Kimi K3
Moonshot's 2.8T flagship — 1M context, tuned for long-horizon agent work.
Reference benchmarks for Kimi K3
These are external benchmarks I pulled from the source comparison guides on agentos.guide — SWE-bench Verified, DRACO, Kilo plan rubric, build-time measurements, vendor-reported coding scores. They are not goldiebench medal scores (those come only from same-prompt one-shot creative coding tasks in the matrix). I surface them here so the spec sheet for Kimi K3 is honest about what's measured.
What is Kimi K3?
Kimi K3 is the Moonshot AI frontier model with a 1,048,576 tokens — a full codebase in working memory context window, released 2026-07-16. Tagline: Moonshot's 2.8T flagship — 1M context, tuned for long-horizon agent work.. Official source: kimi.com.
Pricing detail. Launched July 16, 2026. 2.8T-param MoE (Moonshot's quickstart corrected the circulating 2.5T estimate). $3/M input on OpenRouter at launch; included at no extra cost in the Kimi coding plan (`k3` on the coding endpoint).
How I use it inside the Agent OS. Wired into the Agent OS as the `kimi-k3` Hermes profile and a K3 speed-toggle in the Kimi Code tab — used for long unattended agent runs where a slow-but-right model beats a fast-but-forgetful one.
What I built with Kimi K3
Every model on Goldie Bench gets the same fixed prompt set — one shot, single HTML file out — and I score the result 0–10 inside the Agent Operating System. Here's what Kimi K3 shipped on the bench: 50 one-shot demos across 1,048,576 tokens — a full codebase in working memory of context. Of those, 50 are scored against the field with my honest 0–10 from the source guides at agentos.guide.
Strengths
- Launch-day benchmarks put it around the Fable/Sol tier, with Terminal Bench (agentic terminal-driving) the standout
- 1M-token context verified on this bench's needle test: exact recall from 162k tokens of noise in 18s
- One-shot builds run long but land complete — its first bench game (13.4 min of thinking, 30,880 tokens) playtested with zero JS errors
- Included in the Kimi coding plan — frontier tier without a new bill
Trade-offs
- Slow on hard tasks — early testers report up to ~35 minutes at max reasoning; this bench saw 13+ minute single builds
- Launch-day rate limits on OpenRouter (429s) — the coding-plan endpoint was the reliable route
- Self-reports as K2.7 if you ask it — verify the served model via the API response, not the model's word
Best for
- long-horizon agent runs
- whole-repo context work
- terminal-driving agents
Every benchmark — Kimi K3's full scorecard
All 50 scored tasks, best first — the judge's 0–10 on the same rubric as the whole field. Click any bar for that task's cross-model page, or open this scorecard in the interactive graphs. Full editorial breakdown with judge quotes and sourced outside research: the Kimi K3 deep dive →.
Every demo by Kimi K3
50 live demos, sorted by category. Click any tile to play the actual one-shot result. Verdicts and 0–10 scores are pulled from the source guides where I posted them publicly.
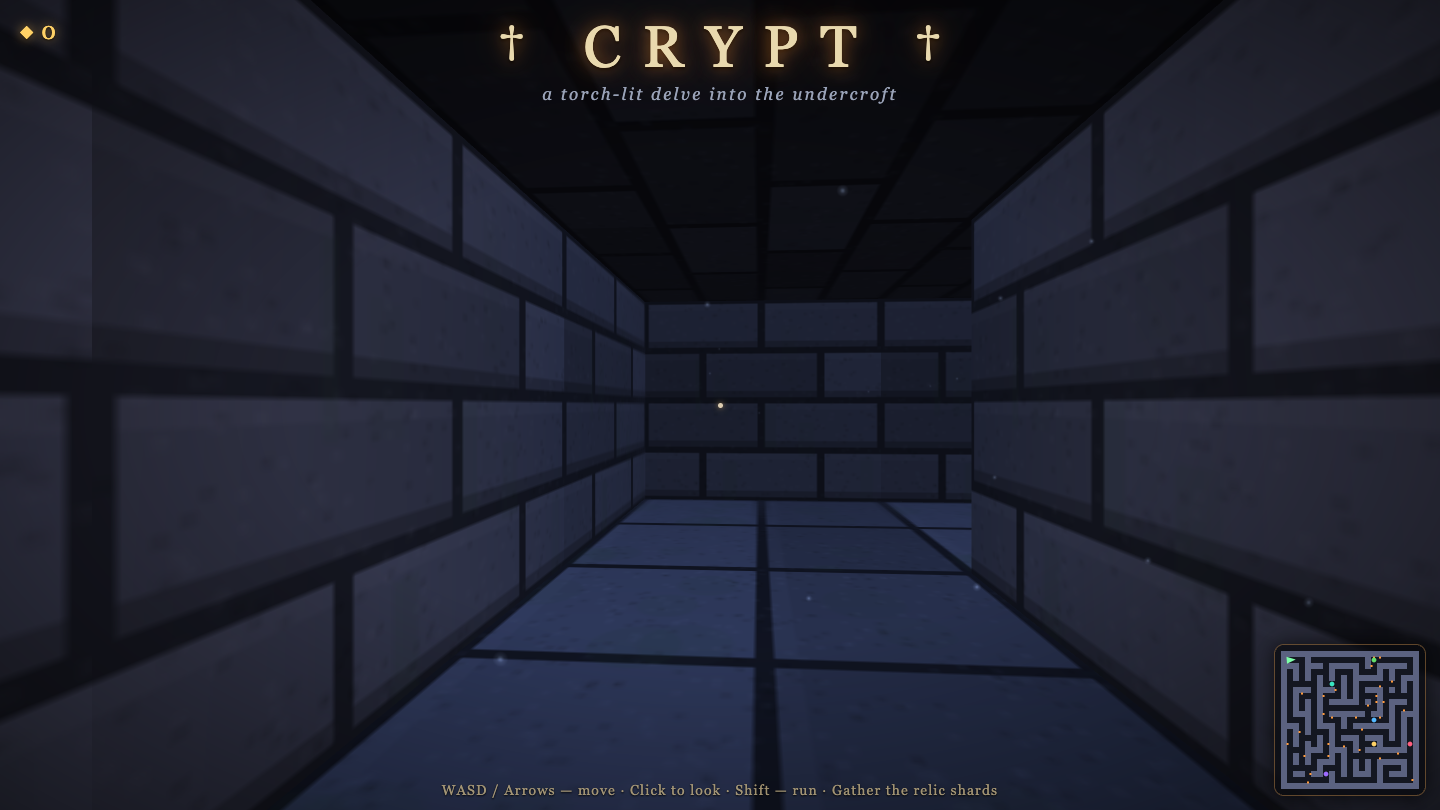 ▶ LIVE
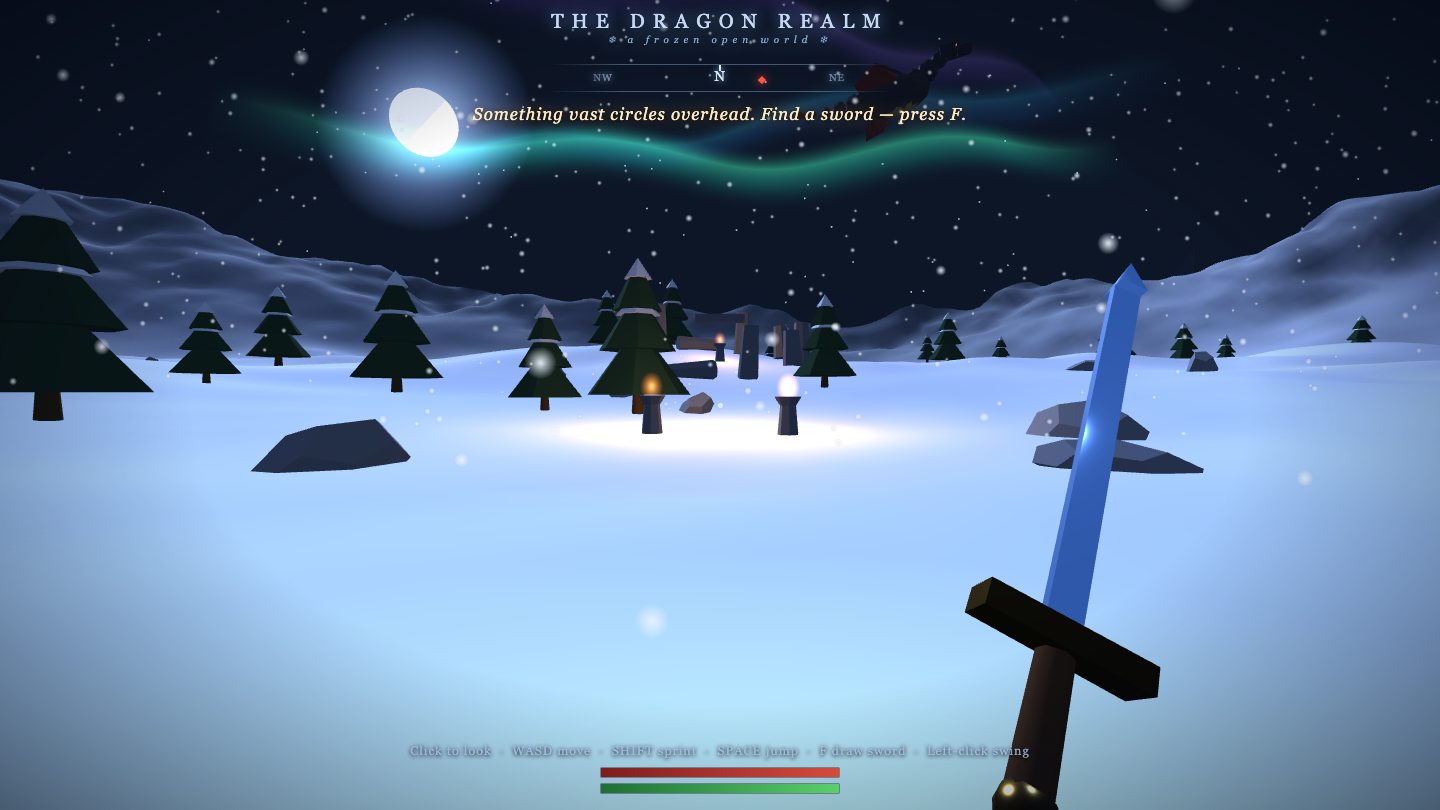 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
 ▶ LIVE
Compare Kimi K3 against every other model
Every head-to-head featuring Kimi K3. Verdicts shown for scored pairs.
See all 66 comparisons across every model →
Quick pill index
Direct comparisons against every other scored model on the bench:
Kimi K3 vs Fusion Kimi K3 vs Claude Opus 5 Kimi K3 vs Hermes MoA Kimi K3 vs GPT-5.6 Sol Kimi K3 vs Claude Fable 5 Kimi K3 vs Qwen 3.8 Kimi K3 vs Grok Kimi K3 vs MiniMax M3 Kimi K3 vs Fugu Ultra Kimi K3 vs GLM-5.2 Kimi K3 vs Fugu Mini Kimi K3 vs Claude Opus 5.5 Kimi K3 vs Muse Spark 1.2 Kimi K3 vs Opus 4.8 Kimi K3 vs Kimi K2.7 Kimi K3 vs Grok 4.7 Kimi K3 vs Qwable 5 27B Coder Kimi K3 vs Gemini 3.6 Flash Kimi K3 vs Claude Sonnet 5 Kimi K3 vs Qwen 3.7 Kimi K3 vs Fugu Ultra 1.1 Kimi K3 vs MiMo-V2.6 Pro Kimi K3 vs Inkling Kimi K3 vs Grok 4.6 Kimi K3 vs Agents-A1 Kimi K3 vs Gemma 4 12B · MLX Kimi K3 vs Laguna XS 2.1 Kimi K3 vs Qwythos 9B Kimi K3 vs LongCat-2.0 Kimi K3 vs Hy3 Kimi K3 vs Gemma-4 12B CoderRead more on agentos.guide: /kimi-k3-machine
Kimi K3 — frequently asked
What is Kimi K3?
Kimi K3 is Moonshot AI's AI model — Moonshot's 2.8T flagship — 1M context, tuned for long-horizon agent work. It has a 1M tokens context window and was released 2026-07-16.
How good is Kimi K3 at coding and one-shot builds?
On the GoldieBench one-shot build benchmark it averages 7.89/10 across 50 scored tasks, with 8 gold, 3 silver and 7 bronze medals.
How much does Kimi K3 cost?
$3 / M in. Launched July 16, 2026. 2.8T-param MoE (Moonshot's quickstart corrected the circulating 2.5T estimate). $3/M input on OpenRouter at launch; included at no extra cost in the Kimi coding plan (`k3` on the coding endpoint).
Where can I see Kimi K3 demos?
Every one-shot build is live and playable on this page and on the GoldieBench compare matrix — same prompt as every other model, no retries.
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 3,400+ founders shipping with it every day all live inside the AI Profit Boardroom.