Real head-to-head · same prompt, one shot
Kimi K3 vs Claude Opus 5.5
Moonshot's 2.8T flagship — 1M context, tuned for long-horizon agent work. vs Anthropic's Opus 5.5 — benched on all 50 one-shot builds, every game playtested.
Head-to-head verdict: Kimi K3 wins 38–11 with 1 tie.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to Kimi K3 and Claude Opus 5.5, side by side, on 50 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
Kimi K3 · Wired into the Agent OS as the `kimi-k3` Hermes profile and a K3 speed-toggle in the Kimi Code tab — used for long unattended agent runs where a slow-but-right model beats a fast-but-forgetful one.
Claude Opus 5.5 · Benched on all 50 GoldieBench tasks via a Claude subscription: one-shot builds, real renders, pixel-diff playtests on every game, then vision-judged.
Side-by-side on 50 shared tasks
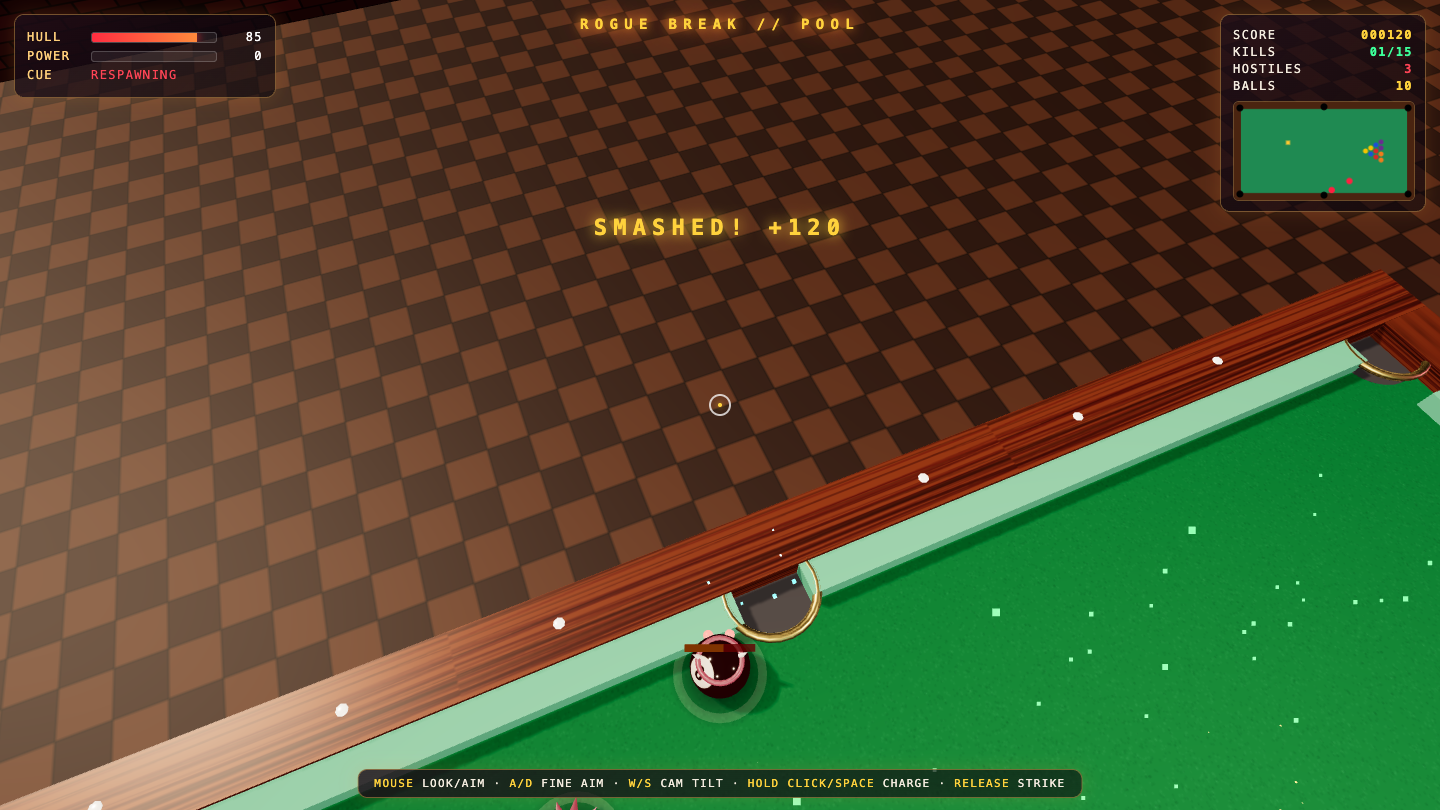
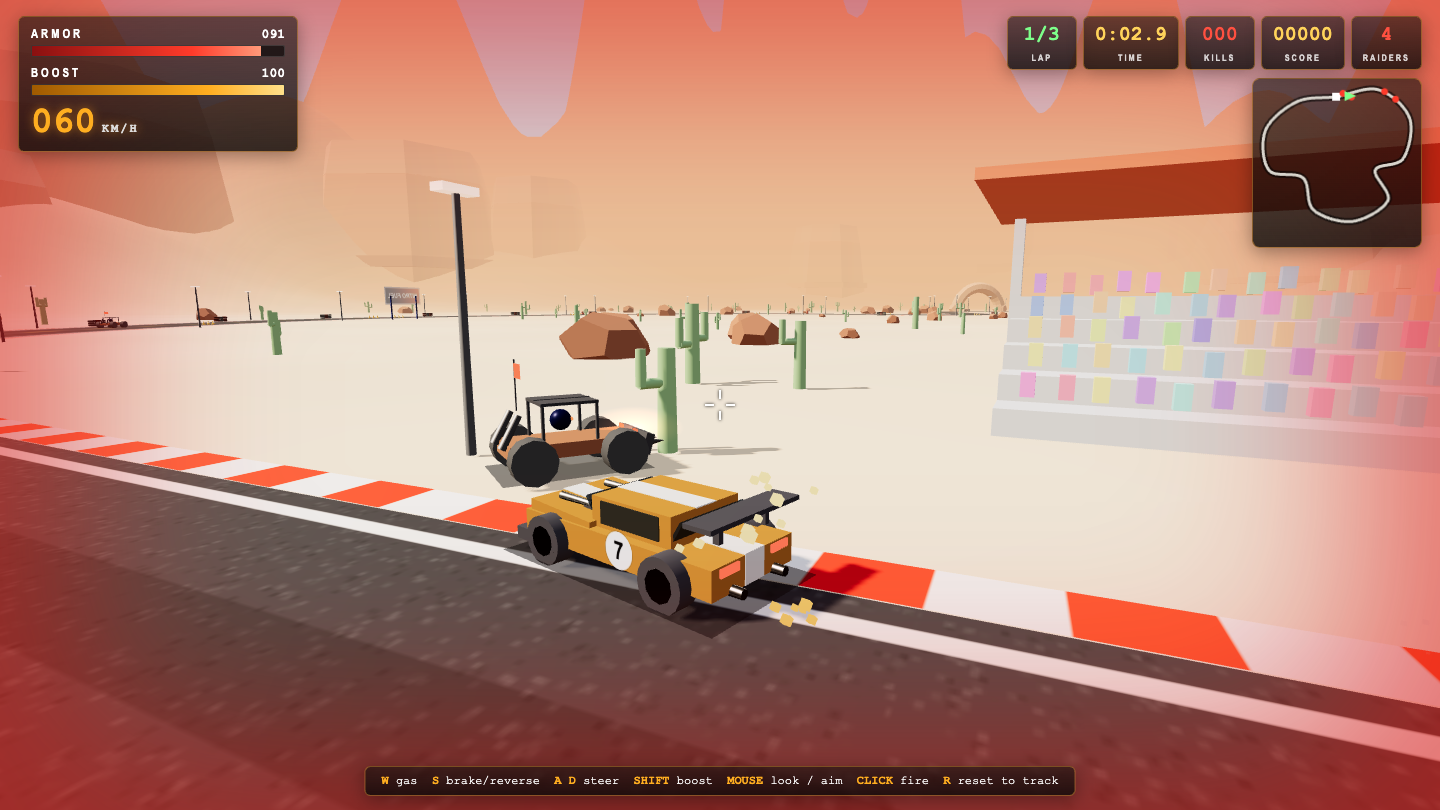
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
Kimi K3
Claude Opus 5.5
Game
Game
Game
Game
Game
Game
Game
Game
Game
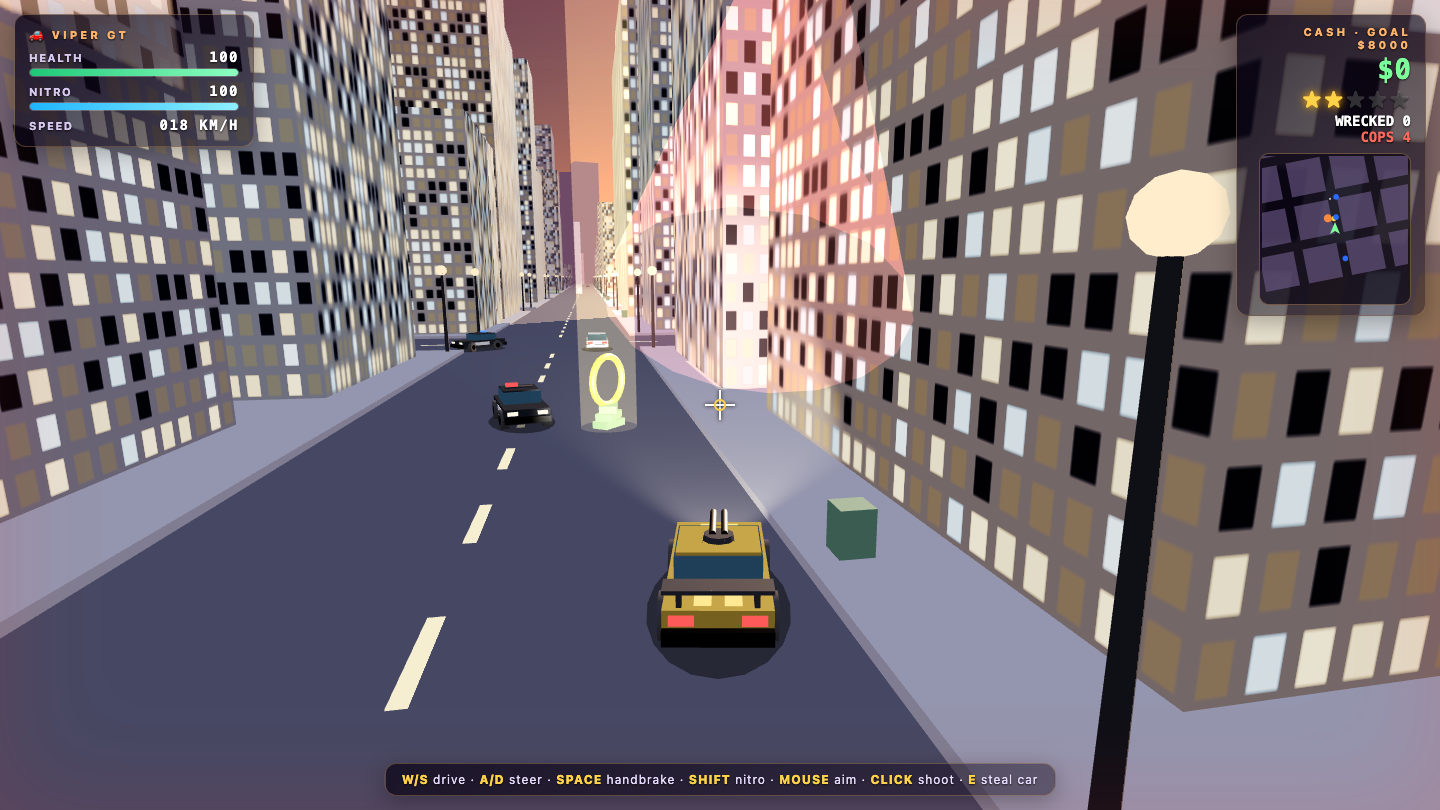
Game
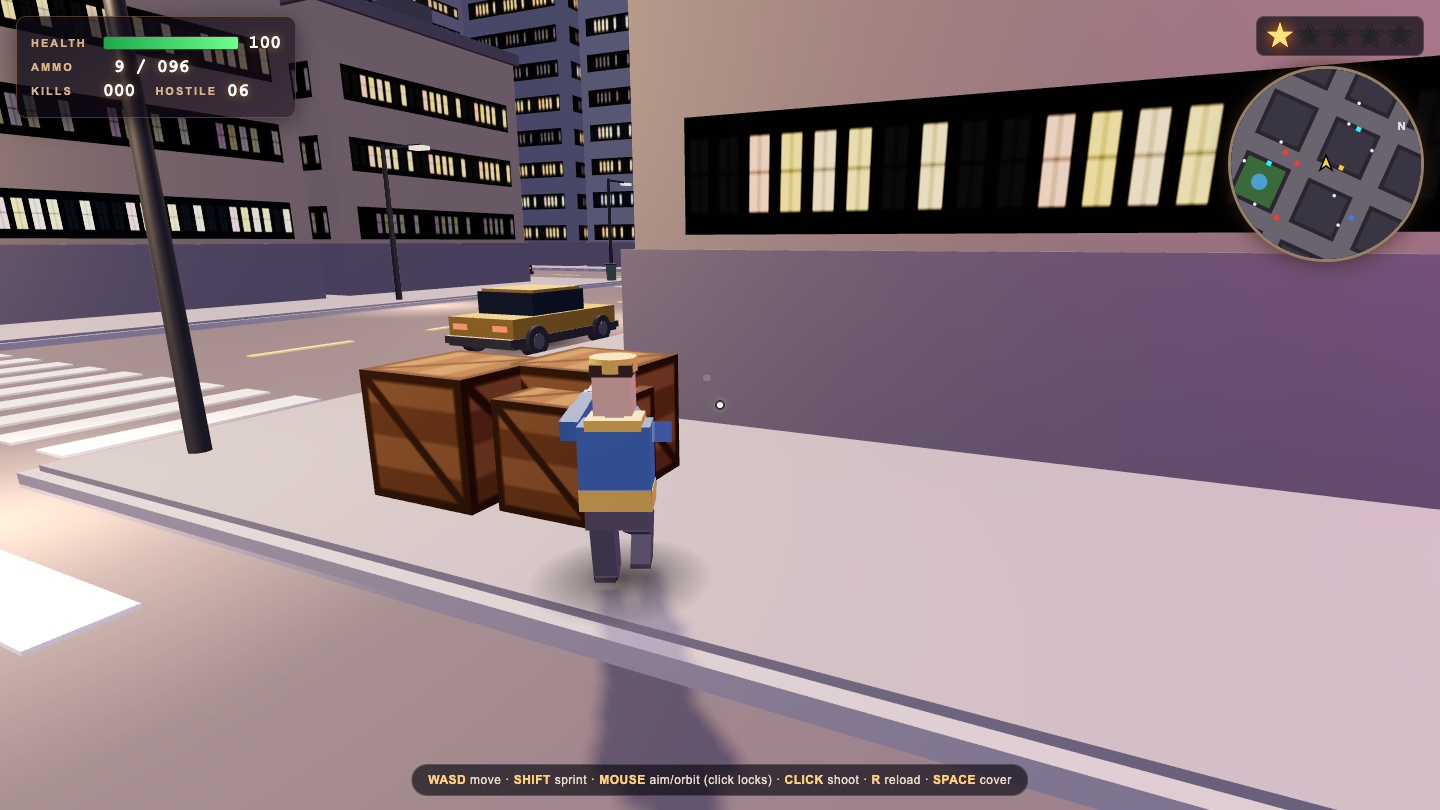
Game
Game
Game
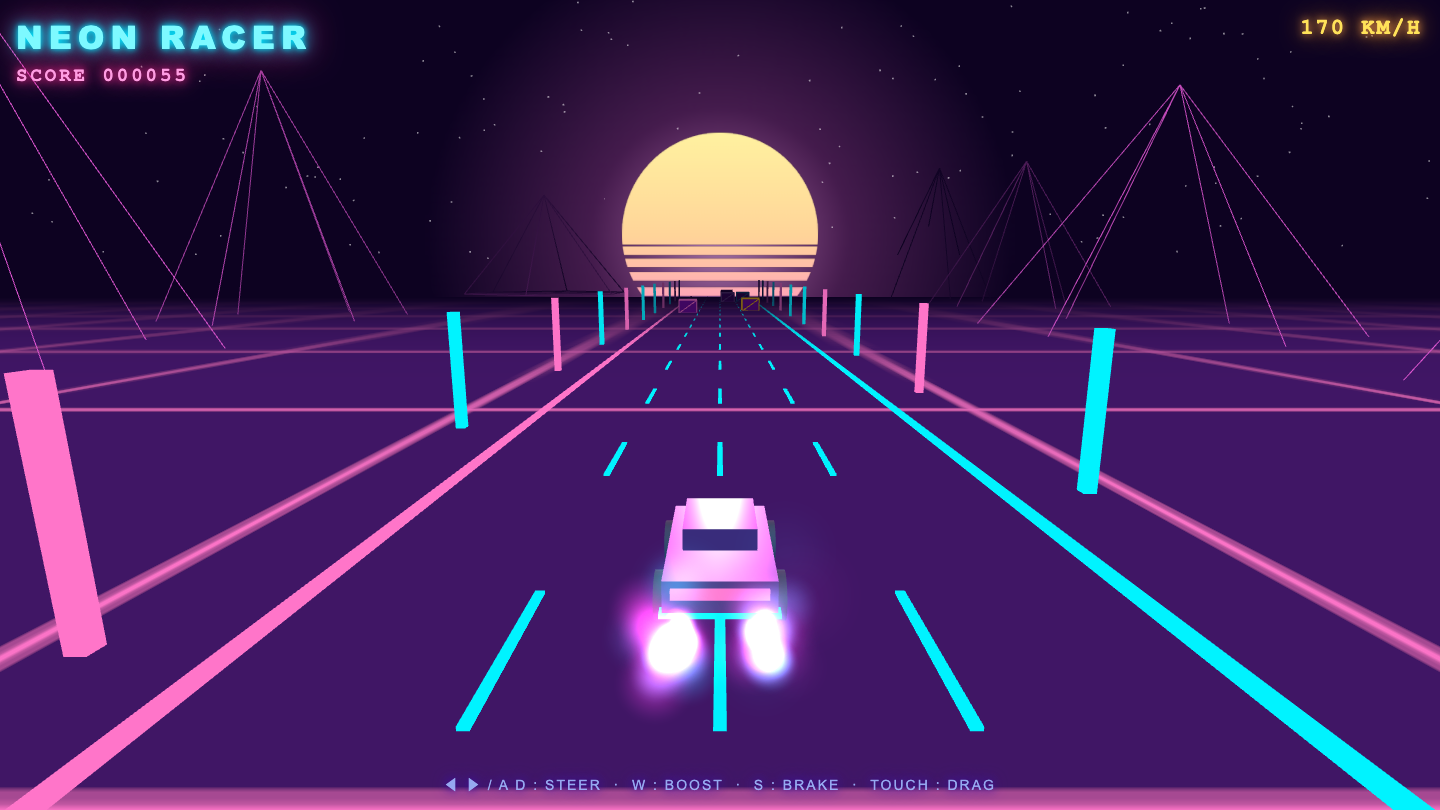
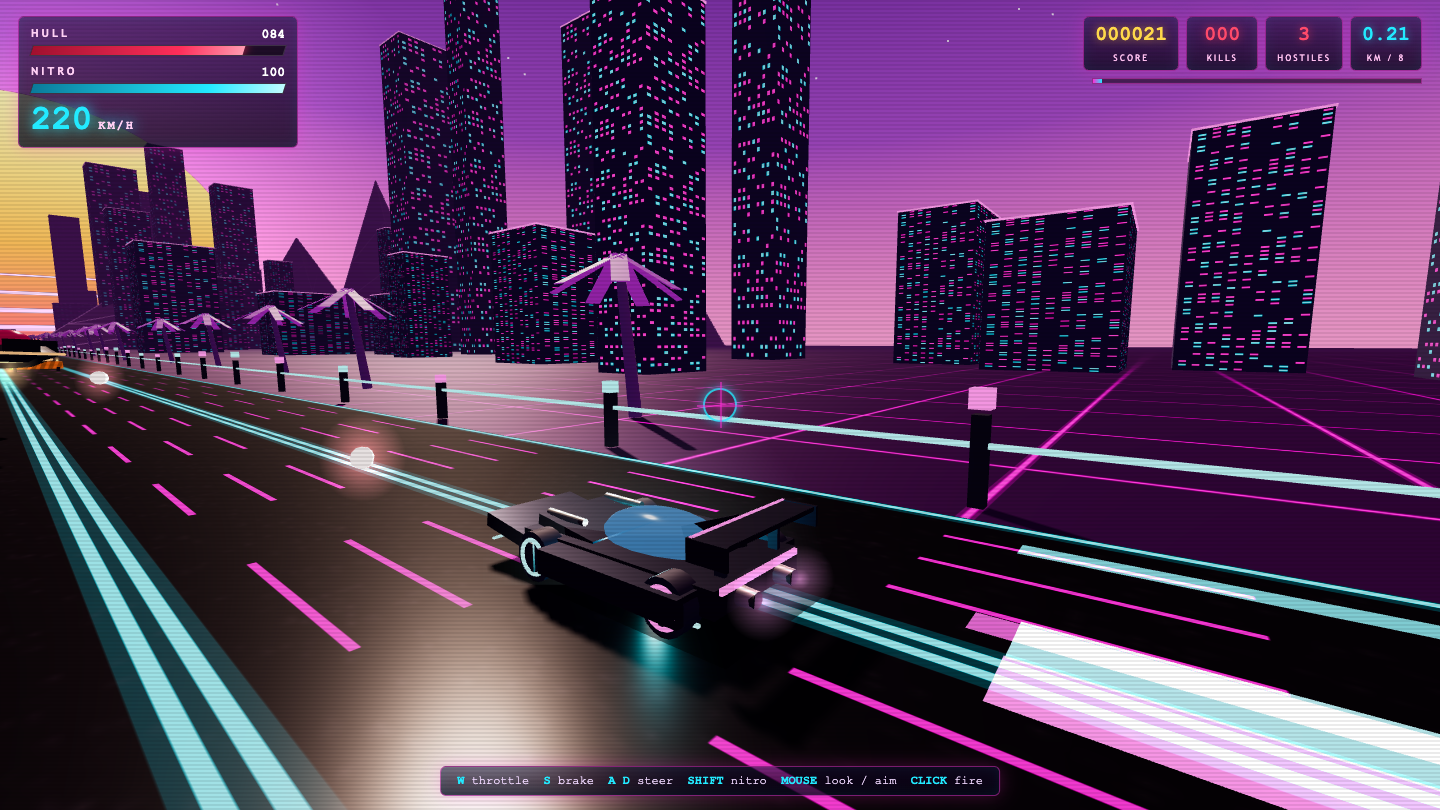
Game
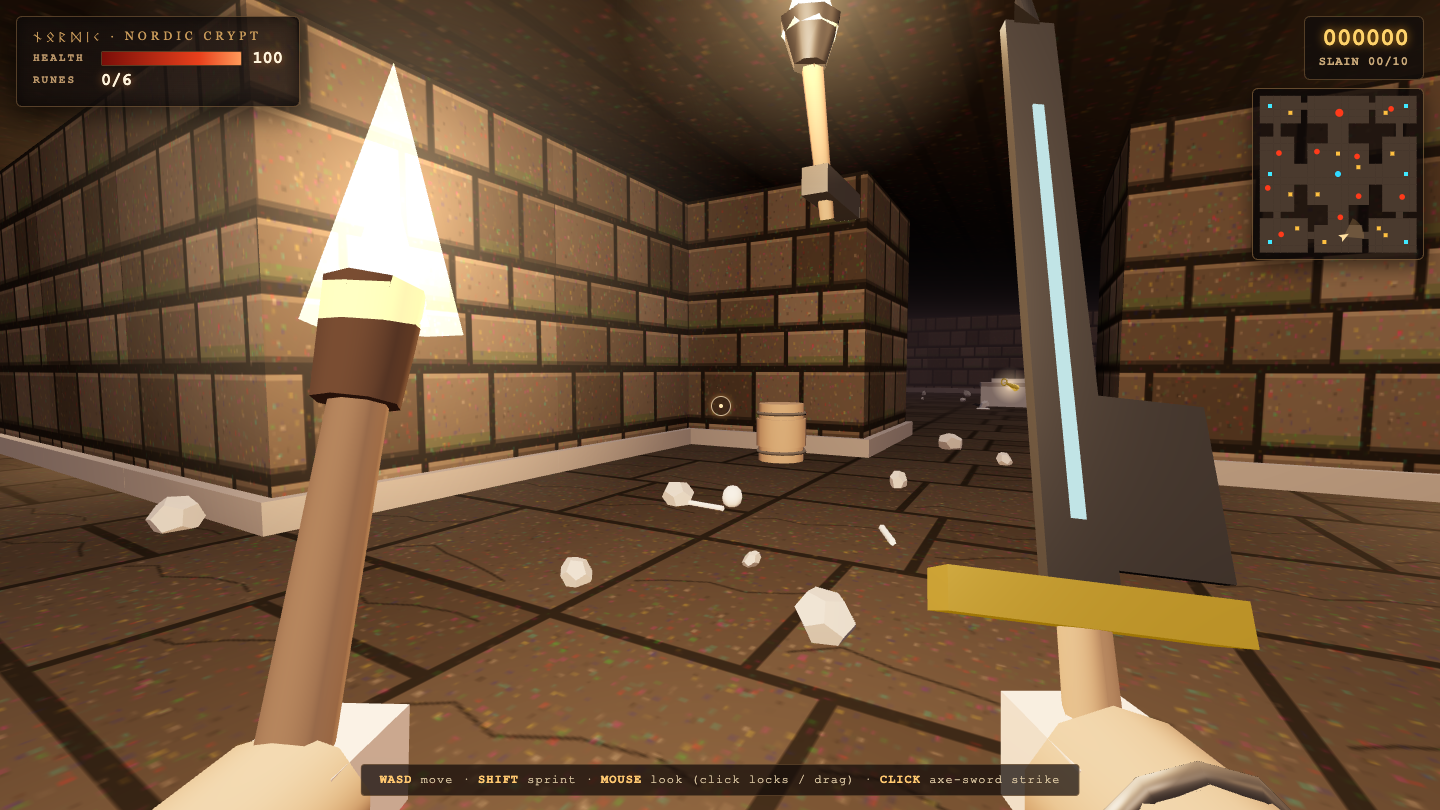
Game
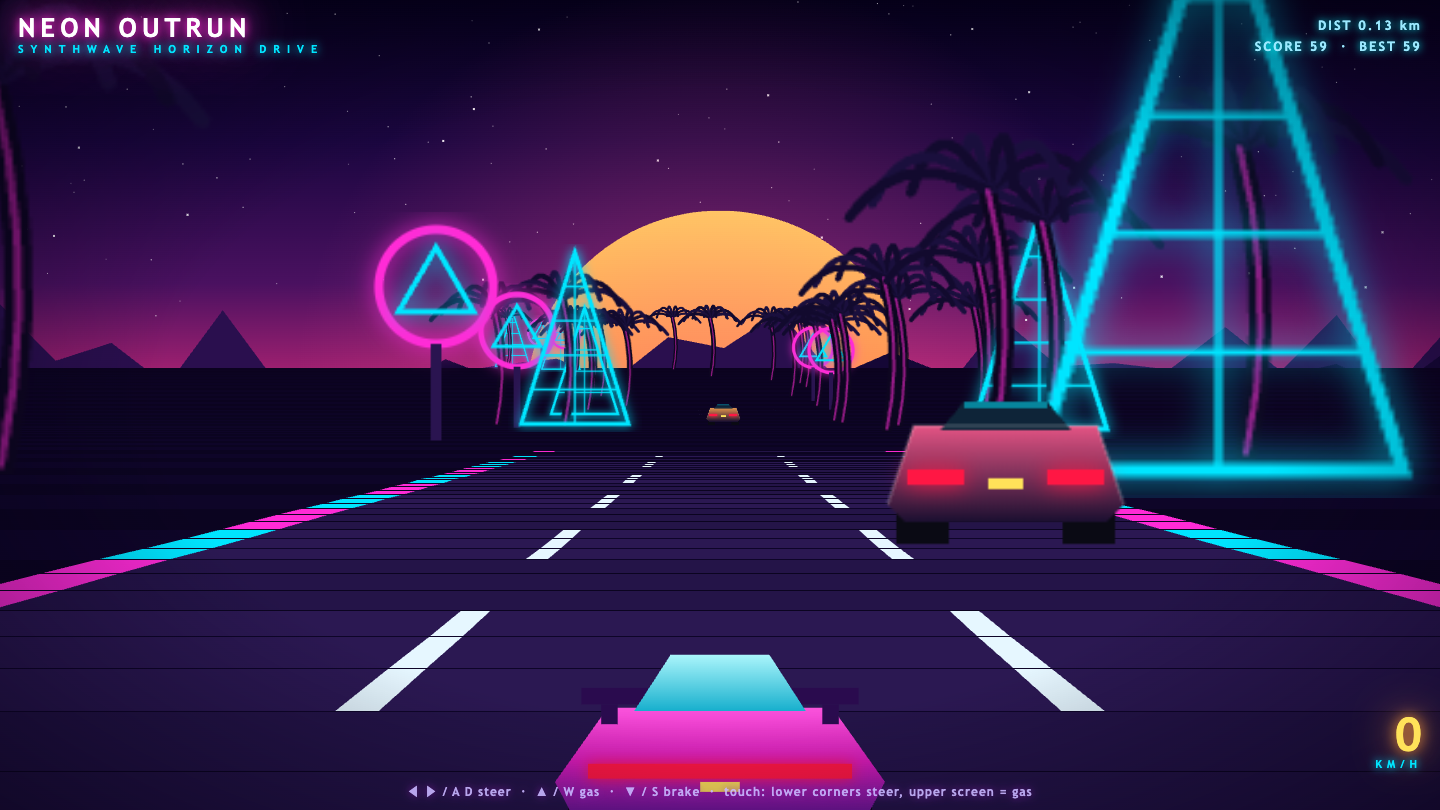
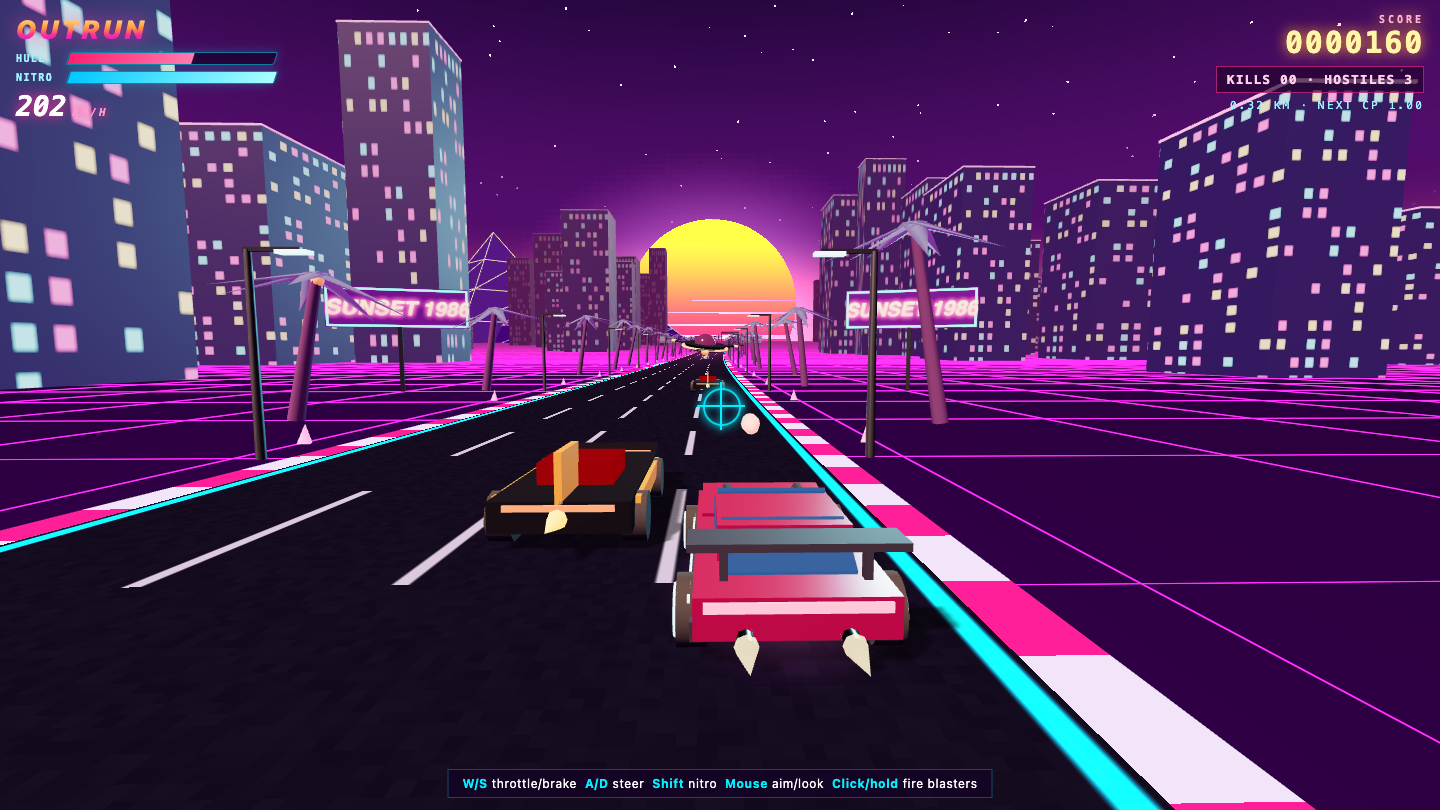
Game
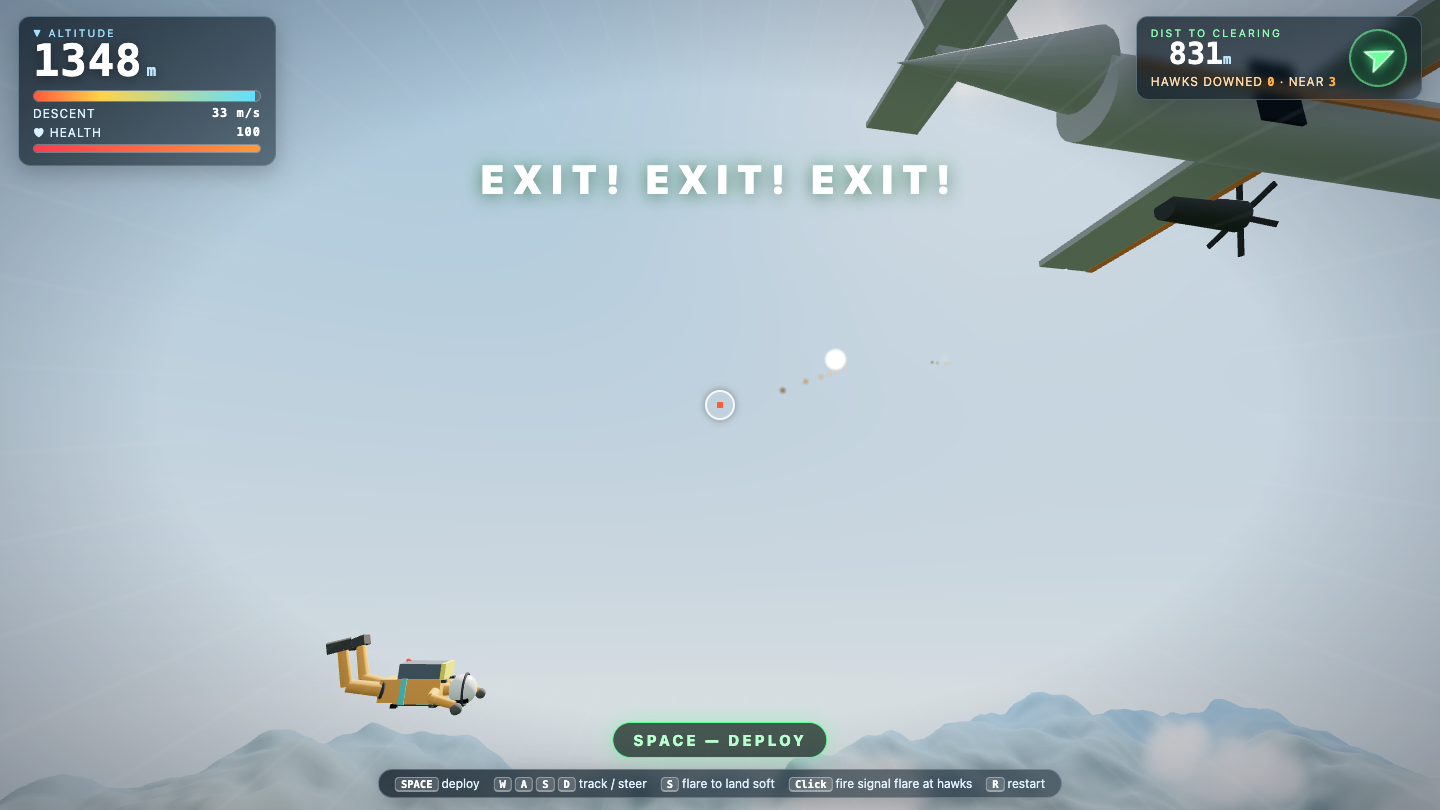
Game
Game
Game
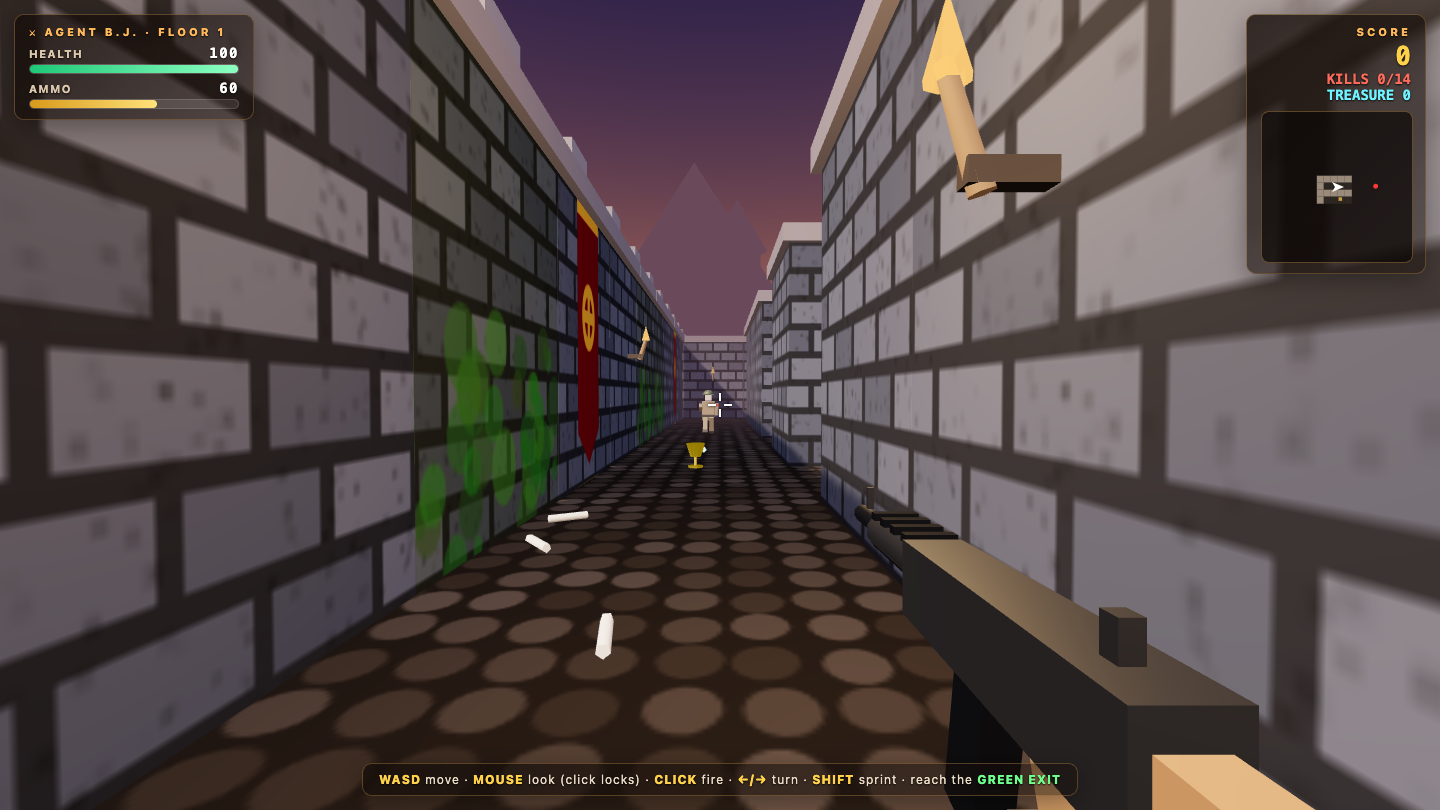
Game
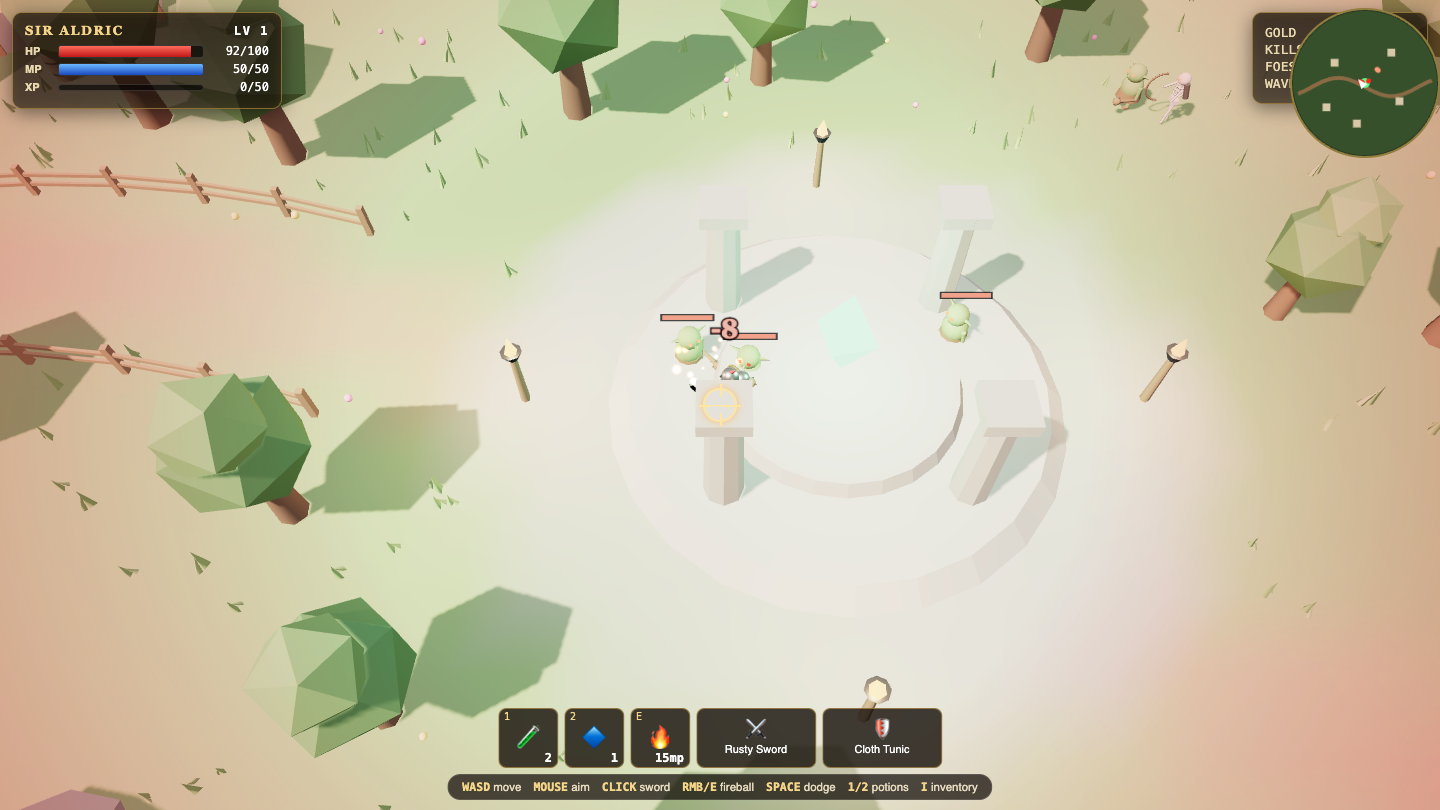
Game
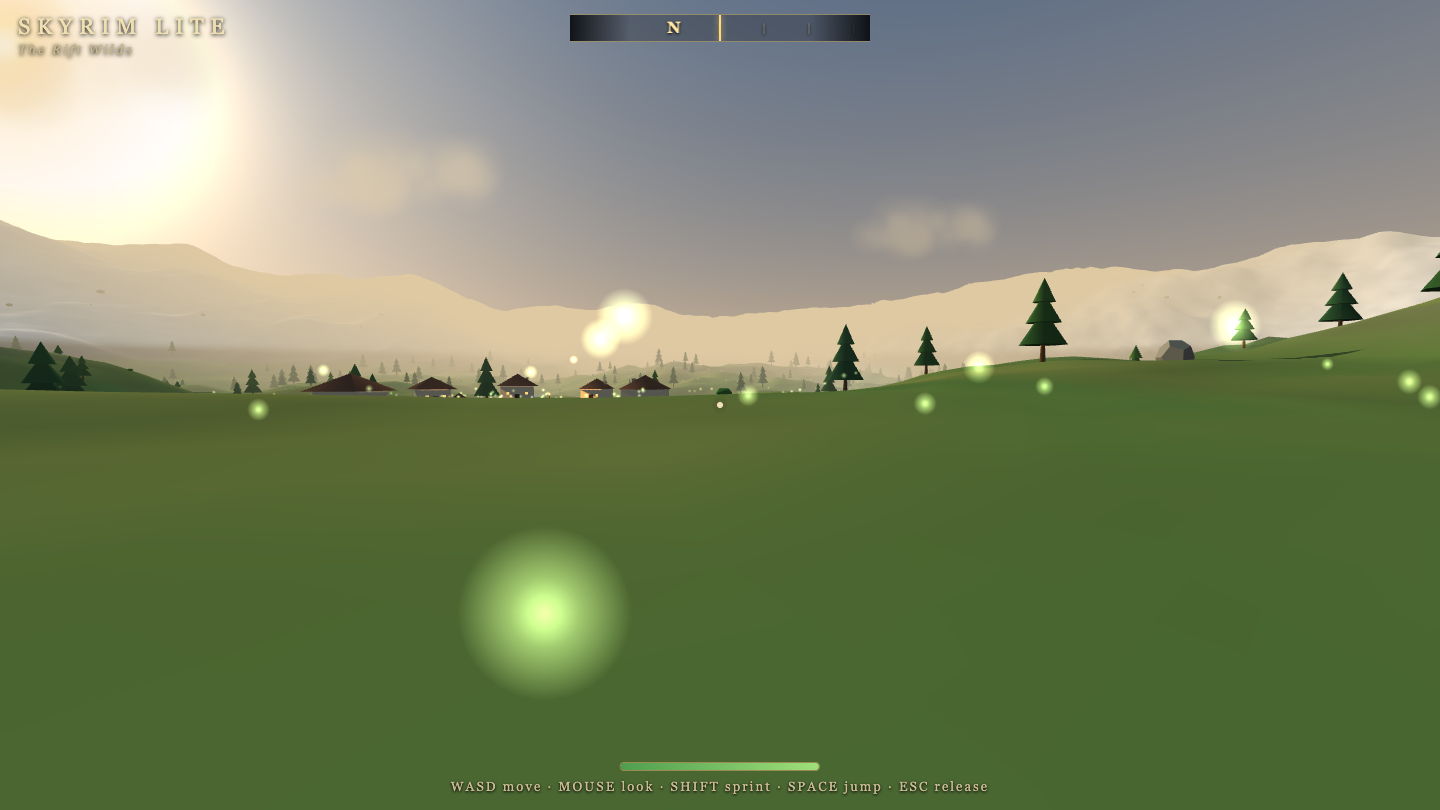
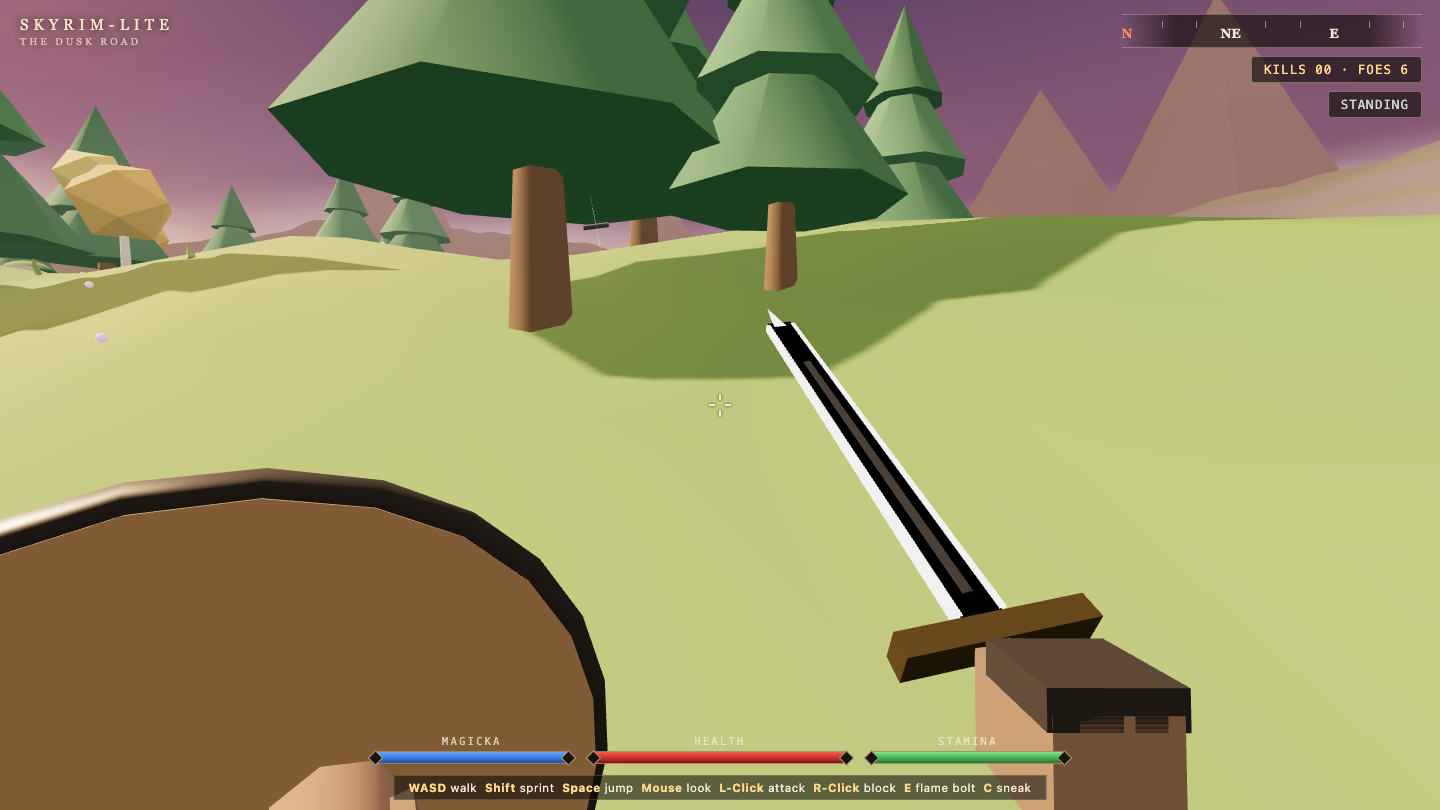
Game
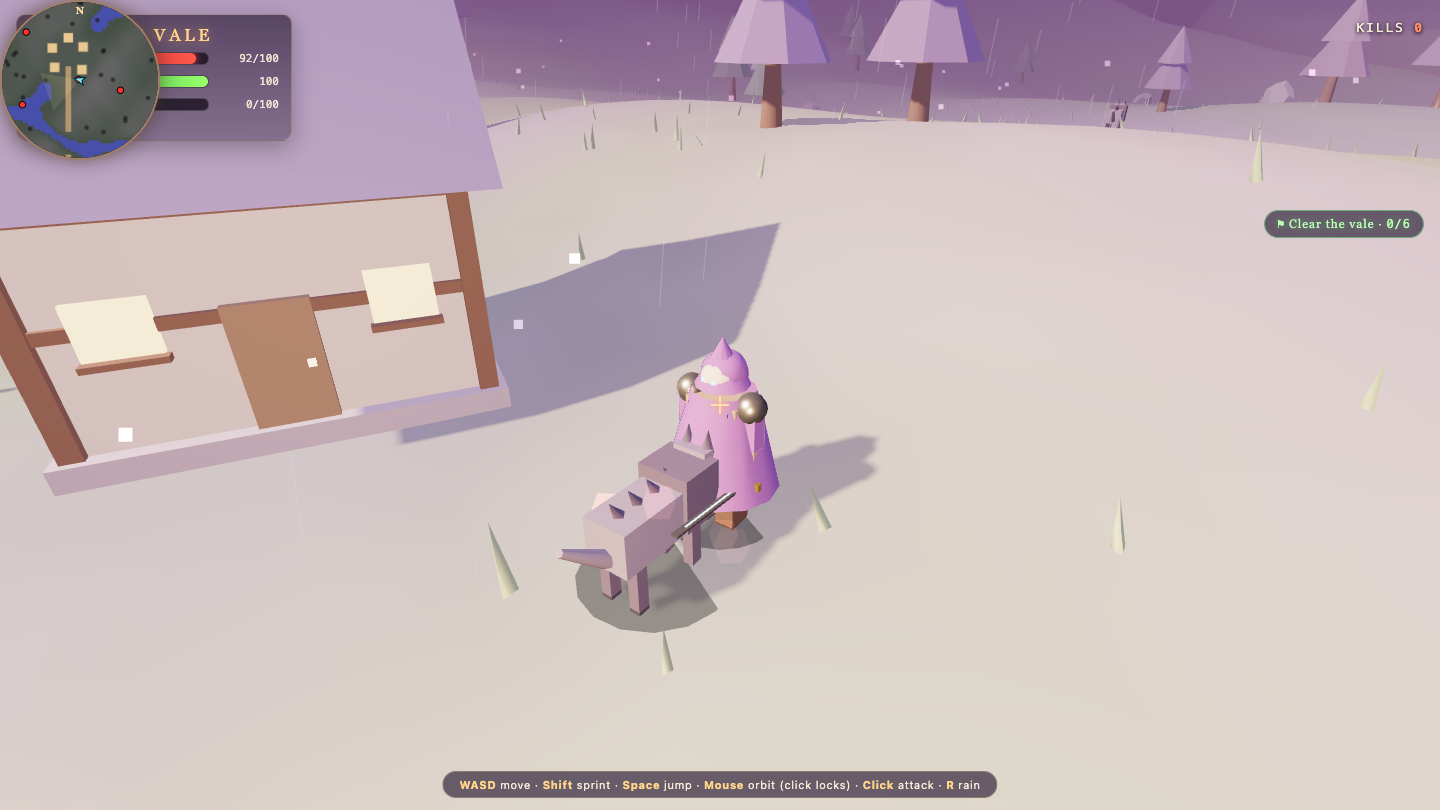
Game
Other
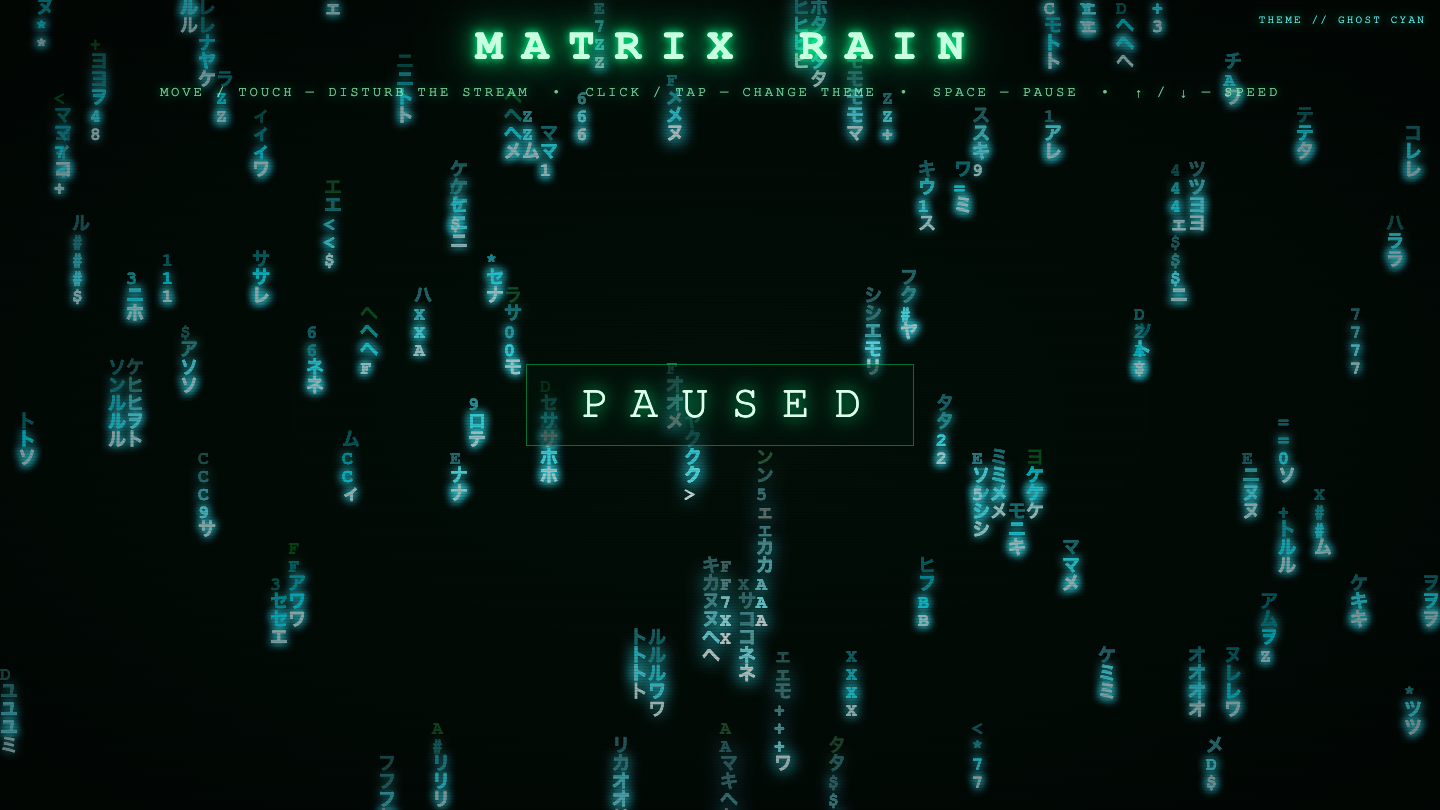
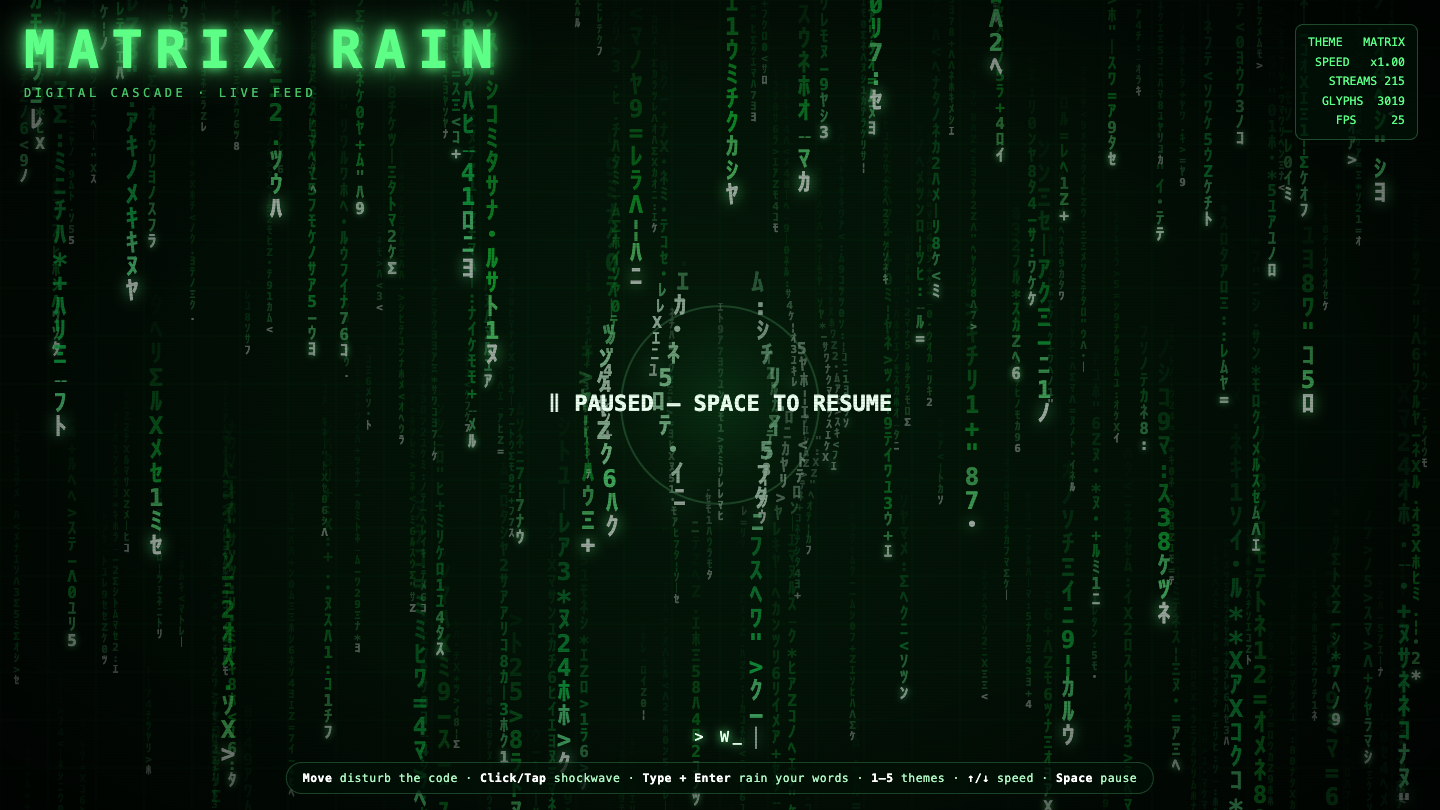
Where Kimi K3 beat Claude Opus 5.5
The tasks where I gave Kimi K3 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
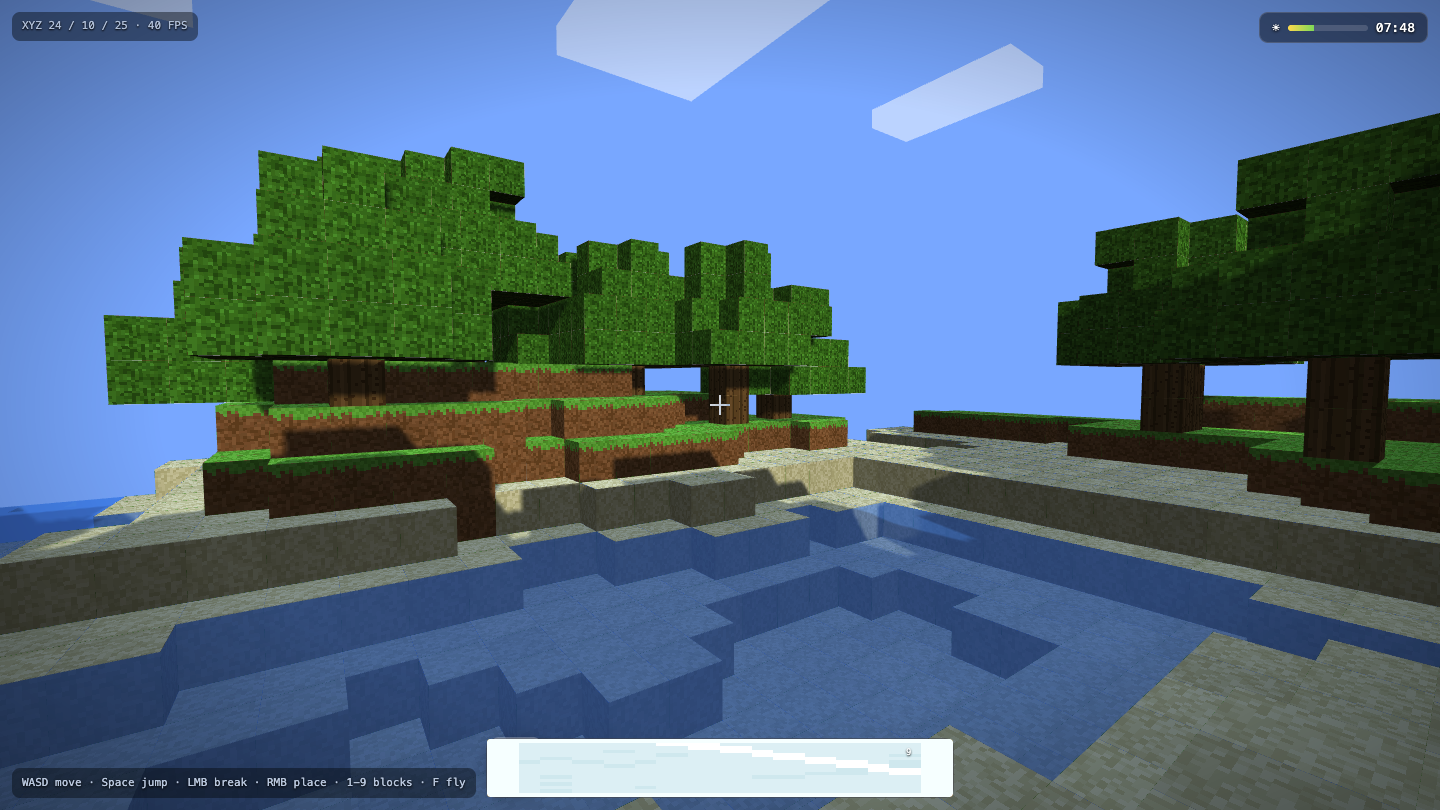
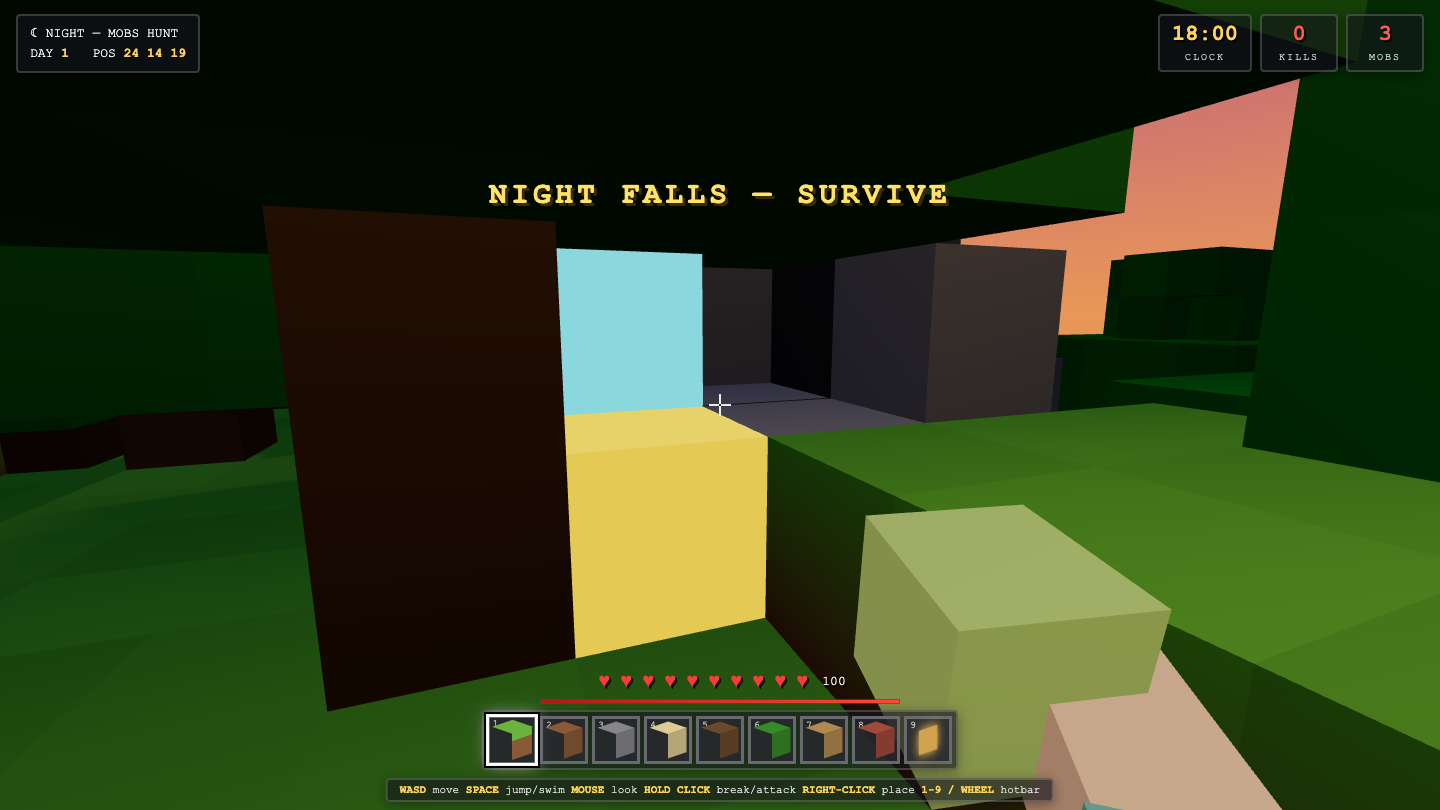
Voxelcraft
Game
Kimi K3 8.7
·
Claude Opus 5.5 5.8
(+2.9)
· polished voxel world
What I saw: Strong: gorgeous procedural terrain with textured grass/dirt/stone/water/trees, real shadows, day/night clock HUD, crosshair and control hints all rendering cleanly and on-brief. Weak: the hotbar area at bottom looks faded/half-rendered in the shot, but the world itself is clearl…
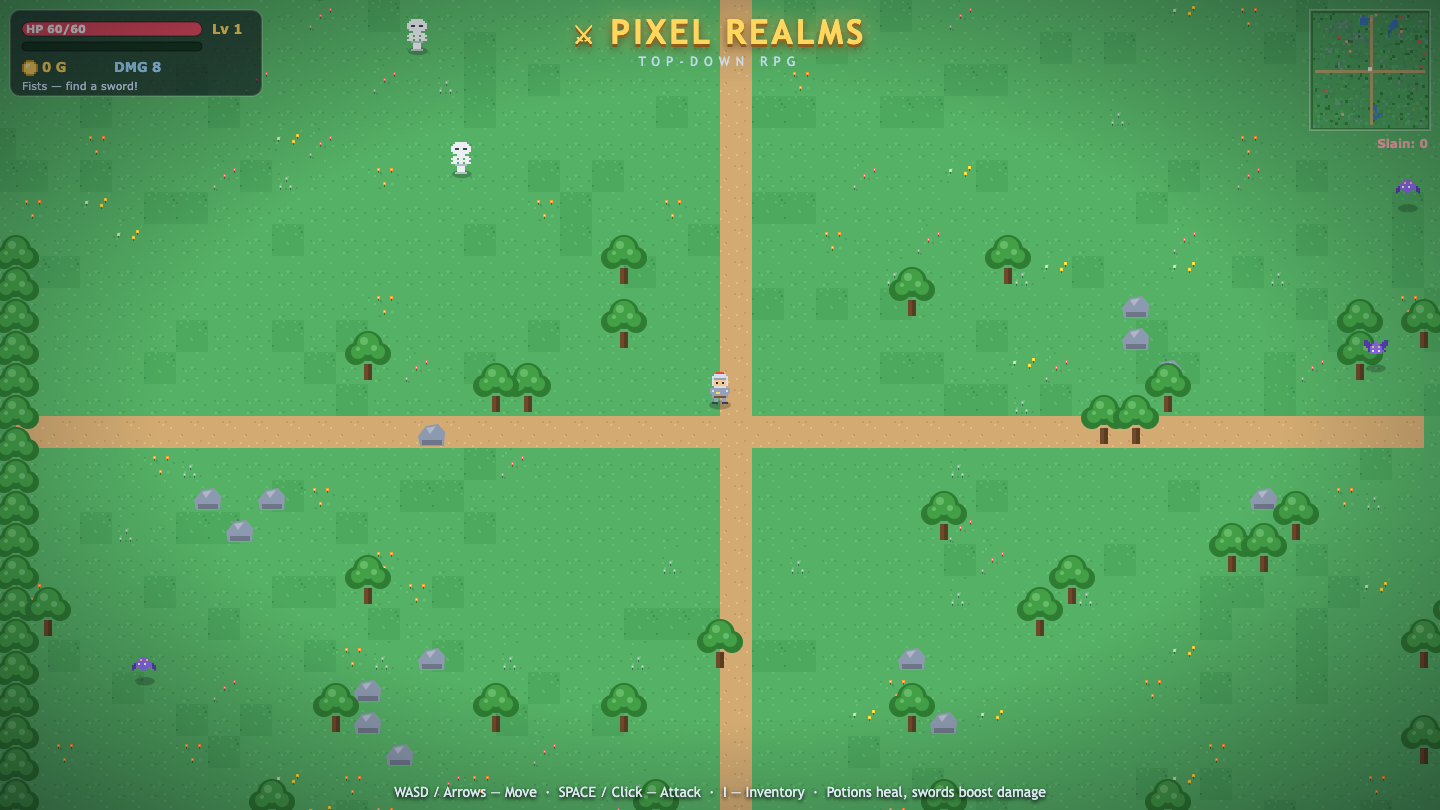
Rpg
Game
Kimi K3 8.3
·
Claude Opus 5.5 5.5
(+2.8)
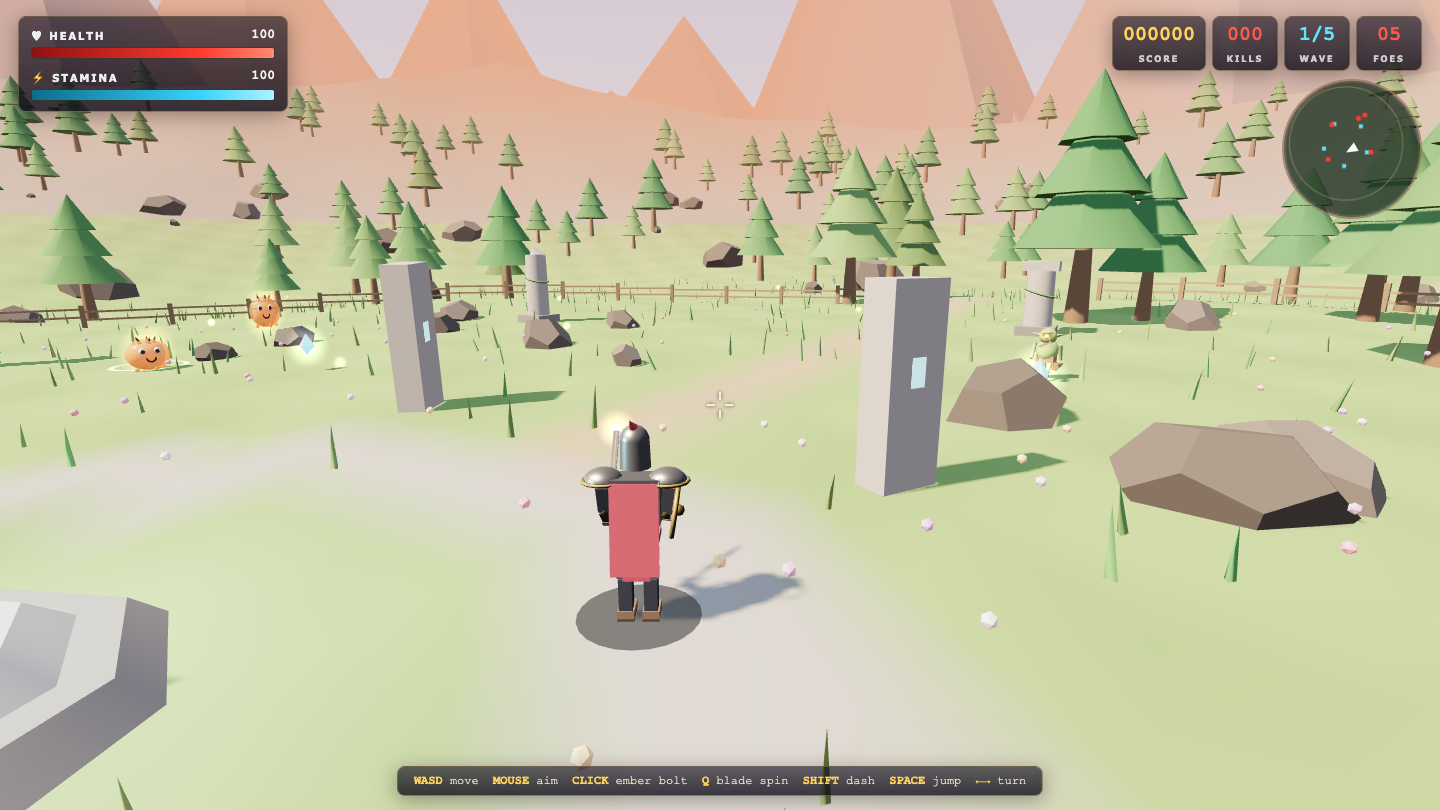
What I saw: Strong, polished render: cohesive pixel-art sprites (knight, skeletons, bats), varied grass/flower/path tiles, trees and rocks, plus a clean HUD with HP/level/gold/DMG, minimap and slain counter — clearly on-brief with combat, inventory and leveling systems in source. Loses a tou…
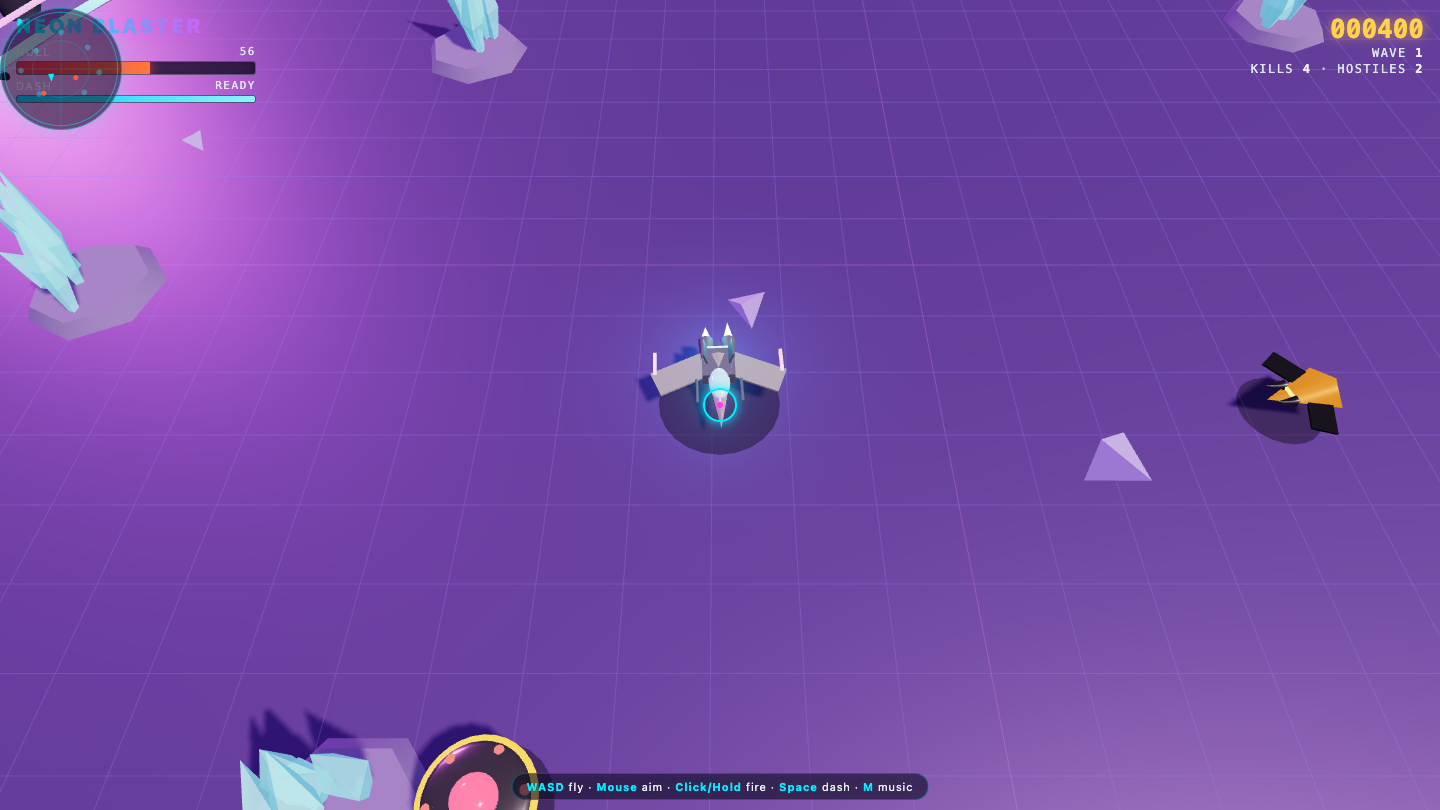
Neonblaster
Game
Kimi K3 8.4
·
Claude Opus 5.5 5.8
(+2.6)
What I saw: Clean neon aesthetic with glowing title, HP diamonds, bomb button, star grid backdrop and a polished 'WAVE 1' banner render; source shows genuinely deep systems — 5 enemy types, bosses with named patterns, power-ups, procedural synth music with delay/compressor, screen-shake — bu…
Arcade
Game
Kimi K3 8.4
·
Claude Opus 5.5 6.0
(+2.4)
· Neon Breakout Polish
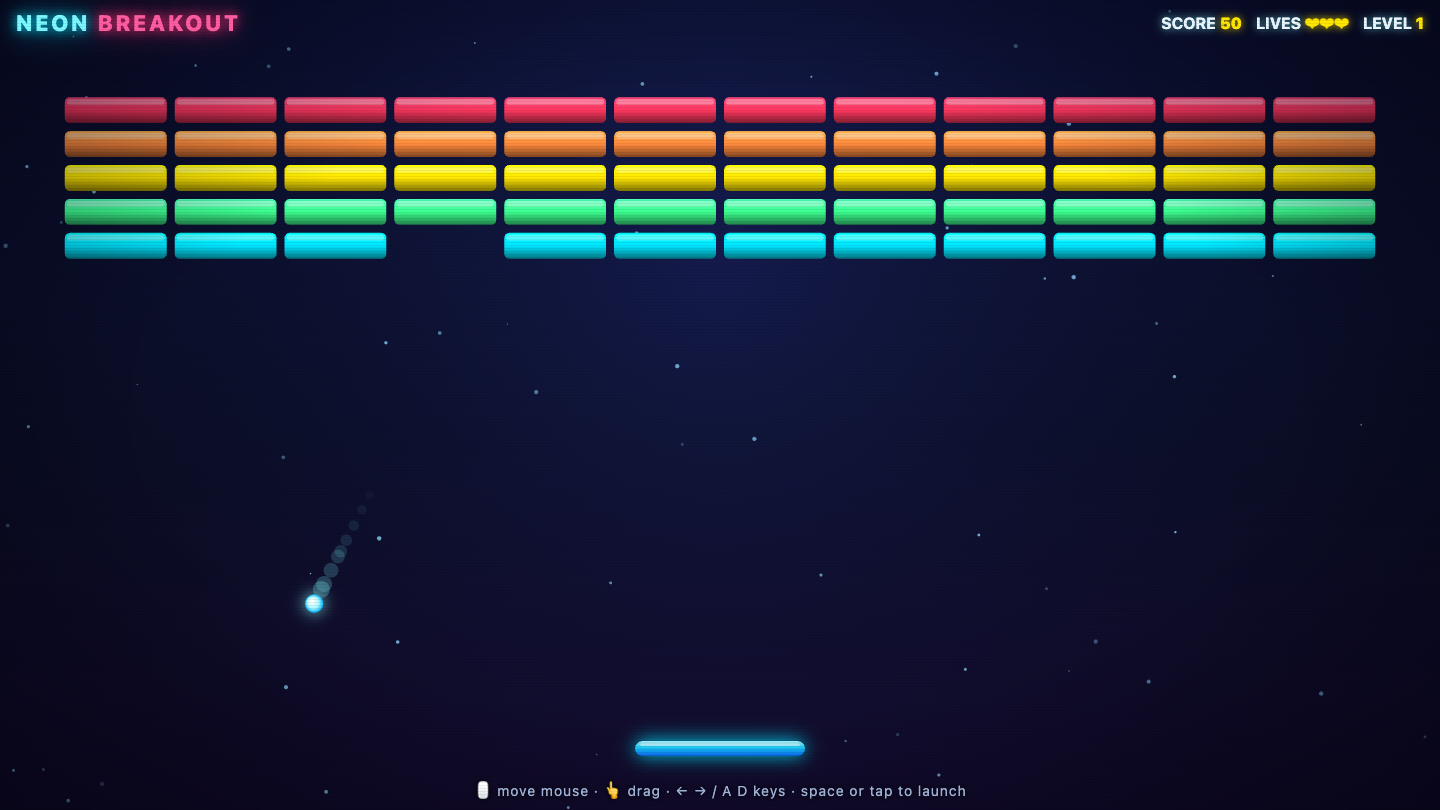
What I saw: Gorgeous neon breakout that rendered cleanly with rainbow bricks, glowing paddle, ball trail, starfield and CRT scanlines, plus a full feature set (powerups, multiball, levels, audio, auto-demo). Very close to the field's best; loses a hair for being a well-trodden brief rather t…
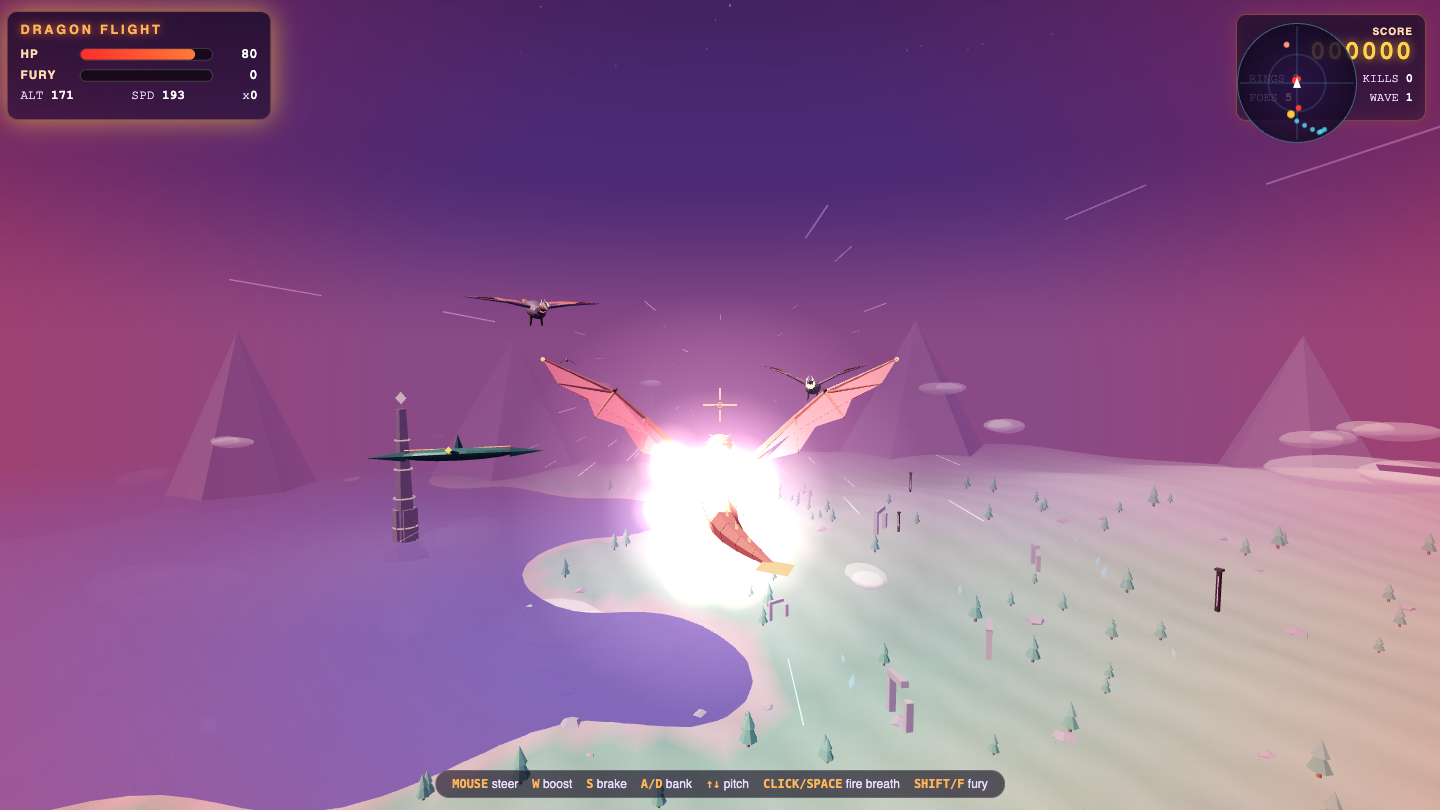
Dragonflight
Game
Kimi K3 8.4
·
Claude Opus 5.5 6.0
(+2.4)
· neon dragon rings
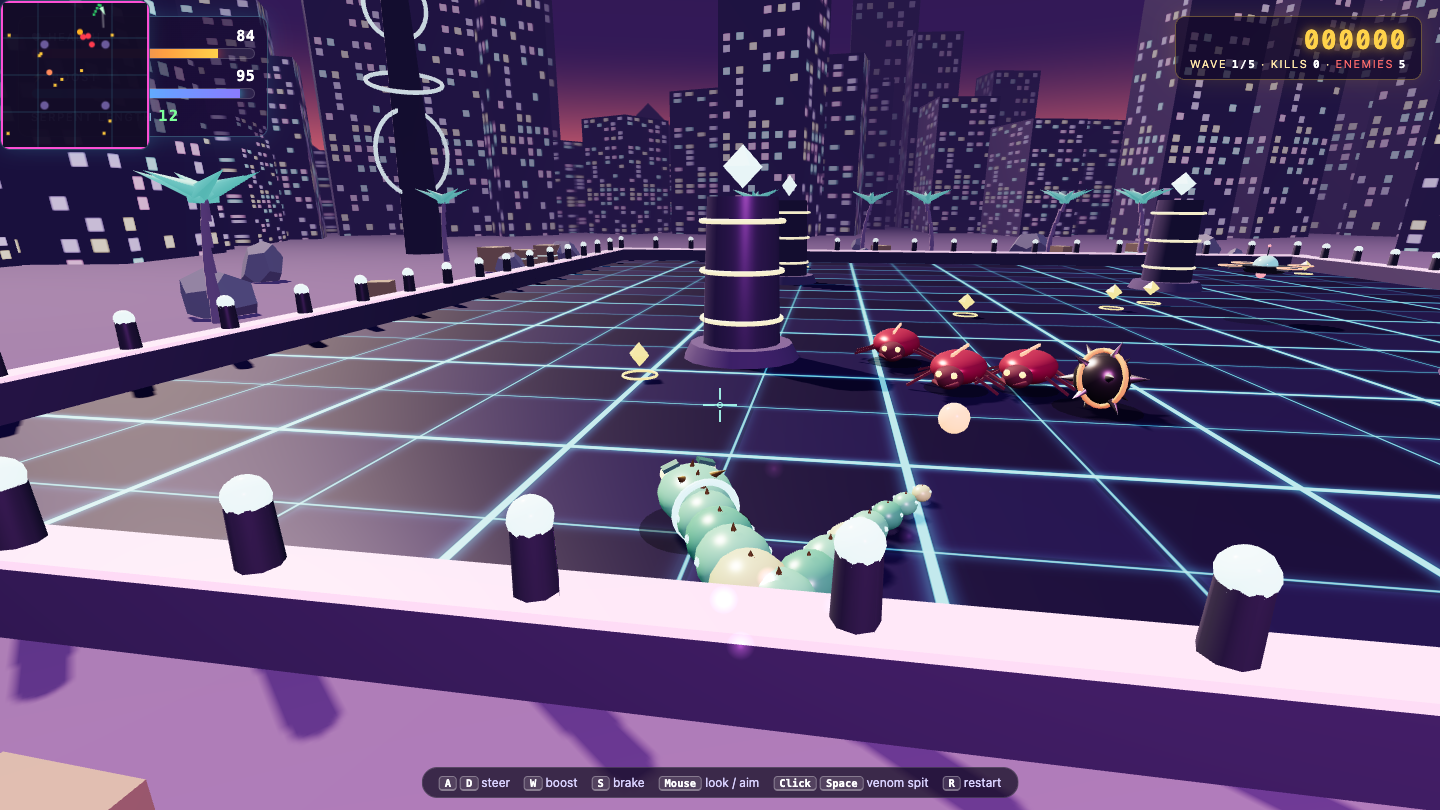
What I saw: Strong 3D scene renders cleanly: a modeled dragon flying through glowing neon rings over a synthwave terrain with full HUD (score, rings, speed, combo, fury meter) all present and on-brief. Slightly loses points—fire-breath isn't visible in the shot and the dragon model reads a b…
Where Claude Opus 5.5 beat Kimi K3
The tasks where I gave Claude Opus 5.5 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Orbit
Sim
Claude Opus 5.5 8.2
·
Kimi K3 3.0
(+5.2)
What I saw: Strong N-body sim: leapfrog integrator, energy-drift readout, 5 scenarios (figure-8, galaxy collision), trails and a click-to-add planet/star, all in a clean cohesive HUD over a glowing polar grid. The scene is a little sparse and dim at this zoom.
Galaxy
Sim
Claude Opus 5.5 8.0
·
Kimi K3 3.0
(+5.0)
What I saw: 90k-star spiral with a glowing core, dust lanes, a mouse vortex, palettes and a clean HUD. It looks gorgeous overall. Visible vertical streak artifacts at the core (particles pulled into columns) mar the centrepiece.
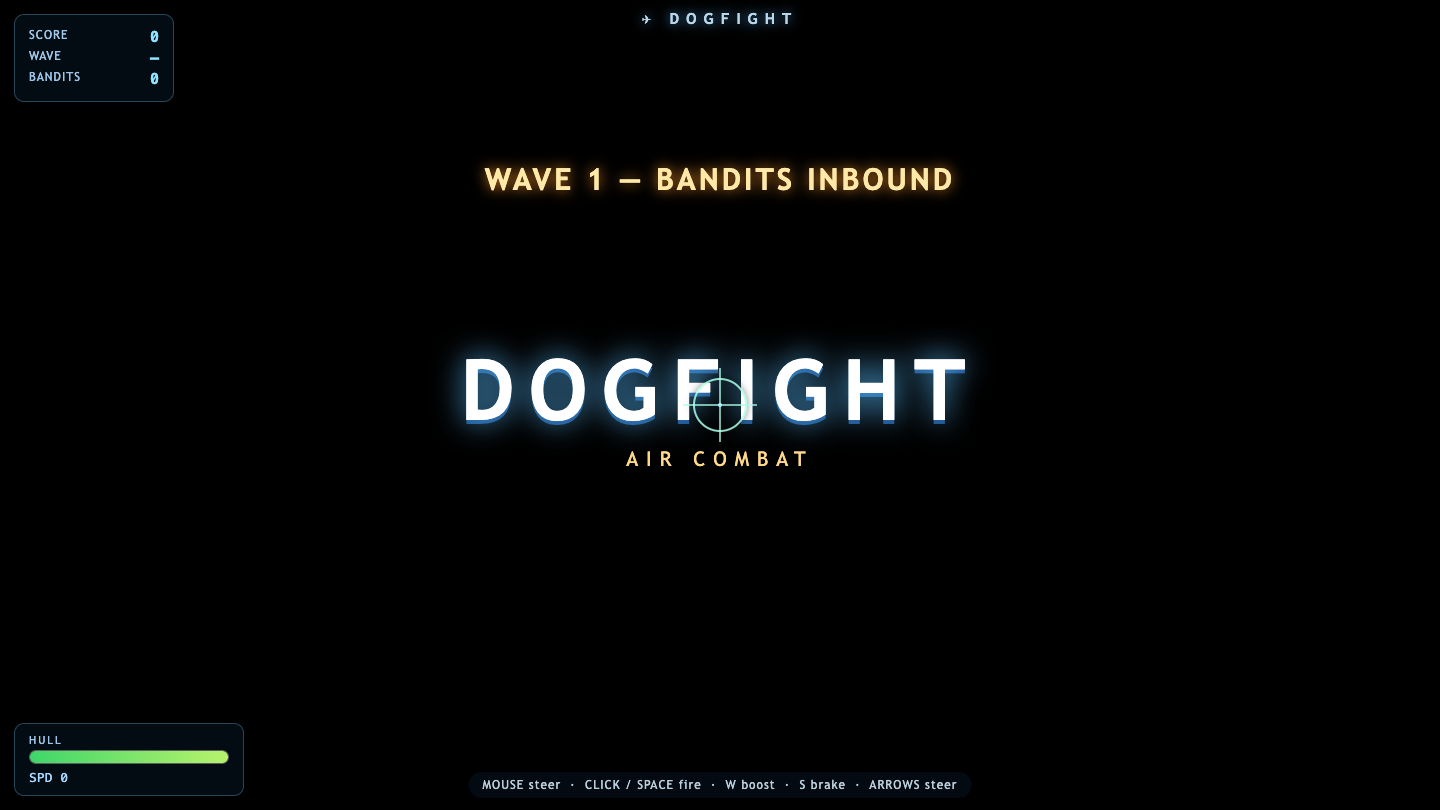
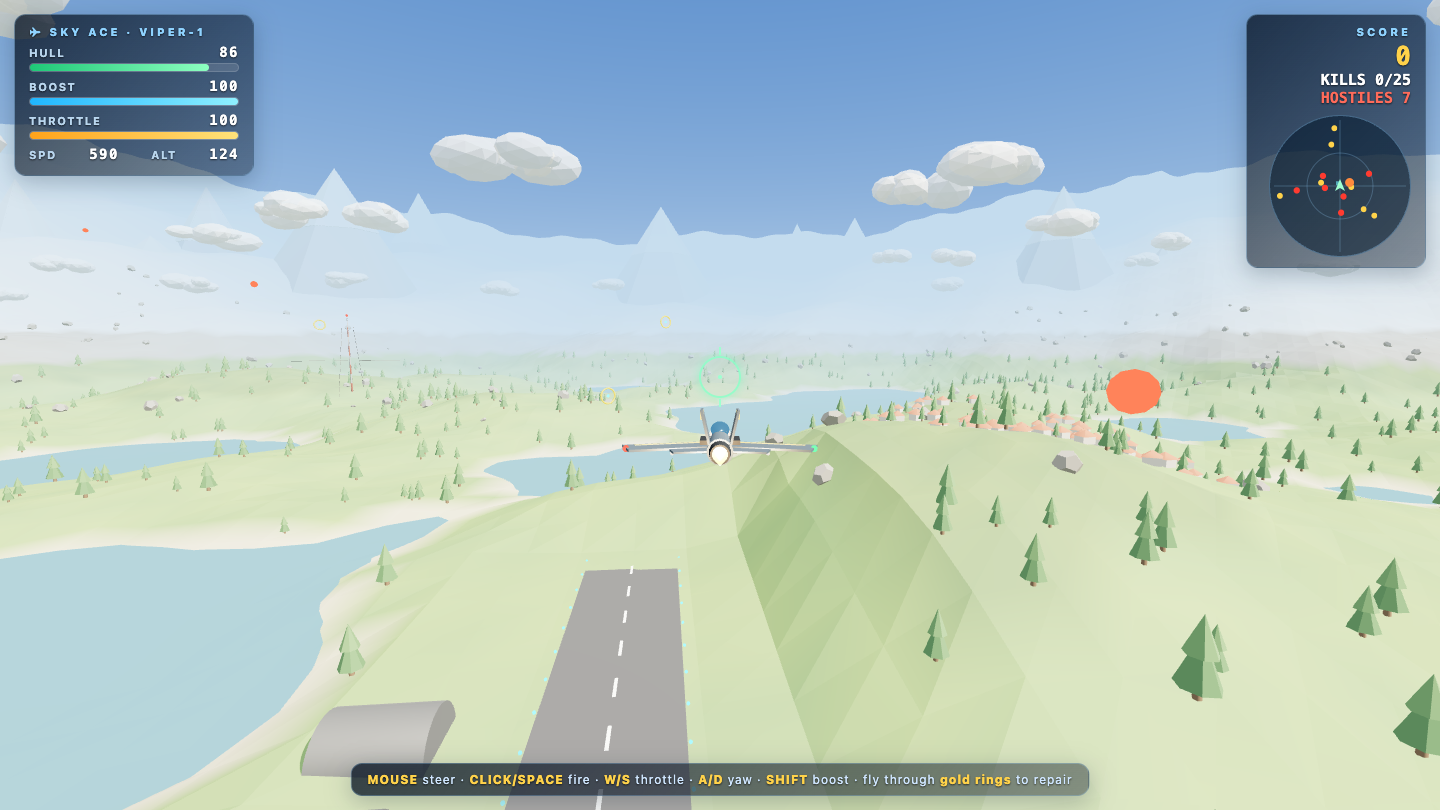
Dogfight
Game
Claude Opus 5.5 7.8
·
Kimi K3 3.5
(+4.3)
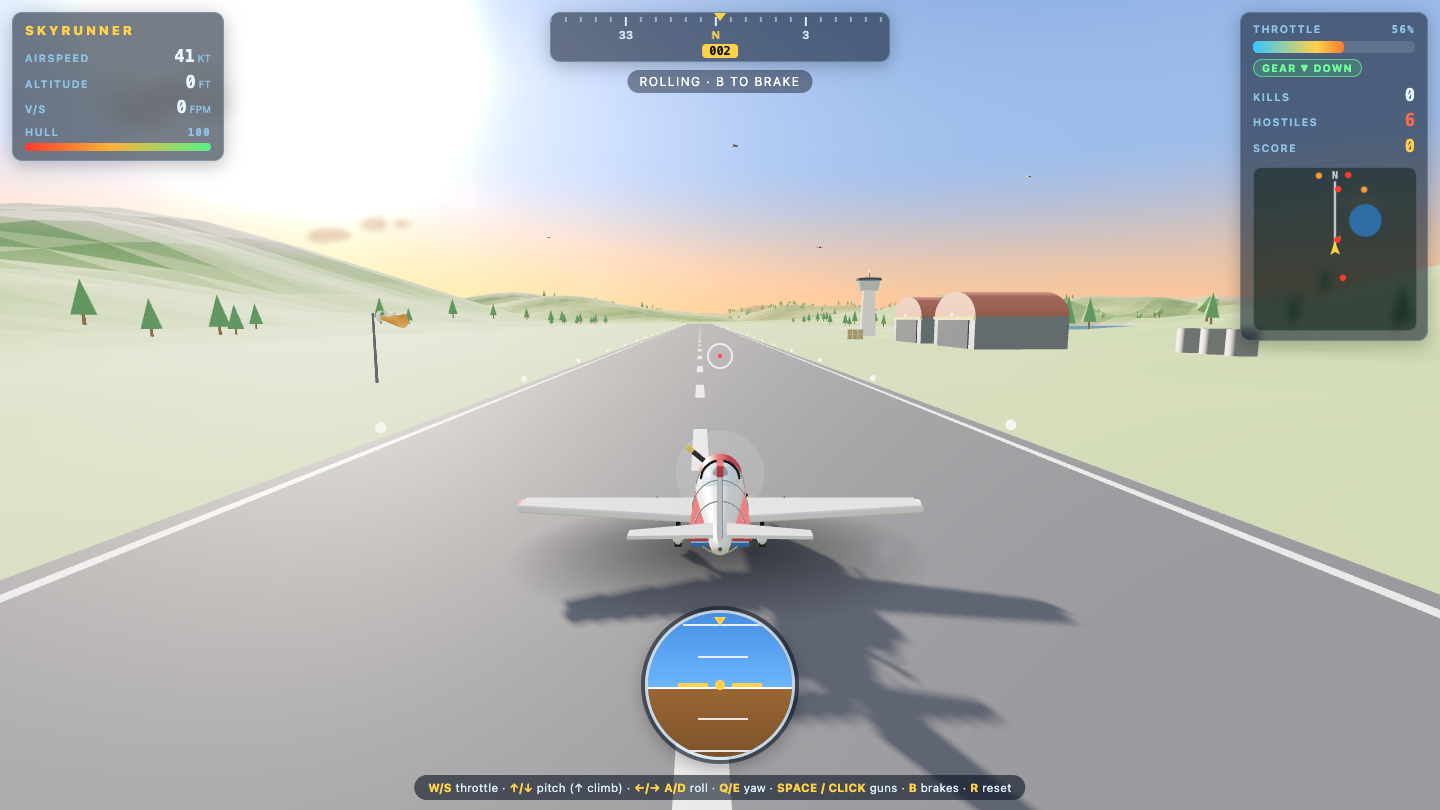
What I saw: Bright, well-lit low-poly world (lakes, forests, village, runway) with a decent jet model and a clean hull/boost/throttle HUD plus radar. The frame reads more like a flight sim than a fight: enemies are specks, the score is 0, and there is an odd flat orange disc in the scene.
Terrain
Visual
Claude Opus 5.5 6.8
·
Kimi K3 4.5
(+2.3)
What I saw: Infinite chunked ridged-fBm terrain with a minimap, day-time cycle, autopilot and stats HUD works. The render is washed out, with milky beige-grey peaks, heavy haze, blurry billboard clouds and sparse cone trees at 20 fps, and the title is barely legible.
Solar
Sim
Claude Opus 5.5 8.4
·
Kimi K3 6.5
(+1.9)
What I saw: Accurate live Keplerian orrery driven by JPL J2000 elements: sqrt/true-distance scale toggle, asteroid belt, ringed Saturn, time controls and a real data panel, all in a polished UI. Planets are tiny at this zoom and the view is a fairly standard top-down orrery.
Strengths & weaknesses I logged
Kimi K3
Strengths
- Launch-day benchmarks put it around the Fable/Sol tier, with Terminal Bench (agentic terminal-driving) the standout
- 1M-token context verified on this bench's needle test: exact recall from 162k tokens of noise in 18s
- One-shot builds run long but land complete — its first bench game (13.4 min of thinking, 30,880 tokens) playtested with zero JS errors
- Included in the Kimi coding plan — frontier tier without a new bill
Trade-offs
- Slow on hard tasks — early testers report up to ~35 minutes at max reasoning; this bench saw 13+ minute single builds
- Launch-day rate limits on OpenRouter (429s) — the coding-plan endpoint was the reliable route
- Self-reports as K2.7 if you ask it — verify the served model via the API response, not the model's word
Claude Opus 5.5
Strengths
- Frontier-class coding + agentic reasoning (Claude 5 family)
- 1M-token context — reads an entire codebase in one call
- All 50 one-shot builds rendered with zero console errors; all 23 games passed the input playtest
Trade-offs
- Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes
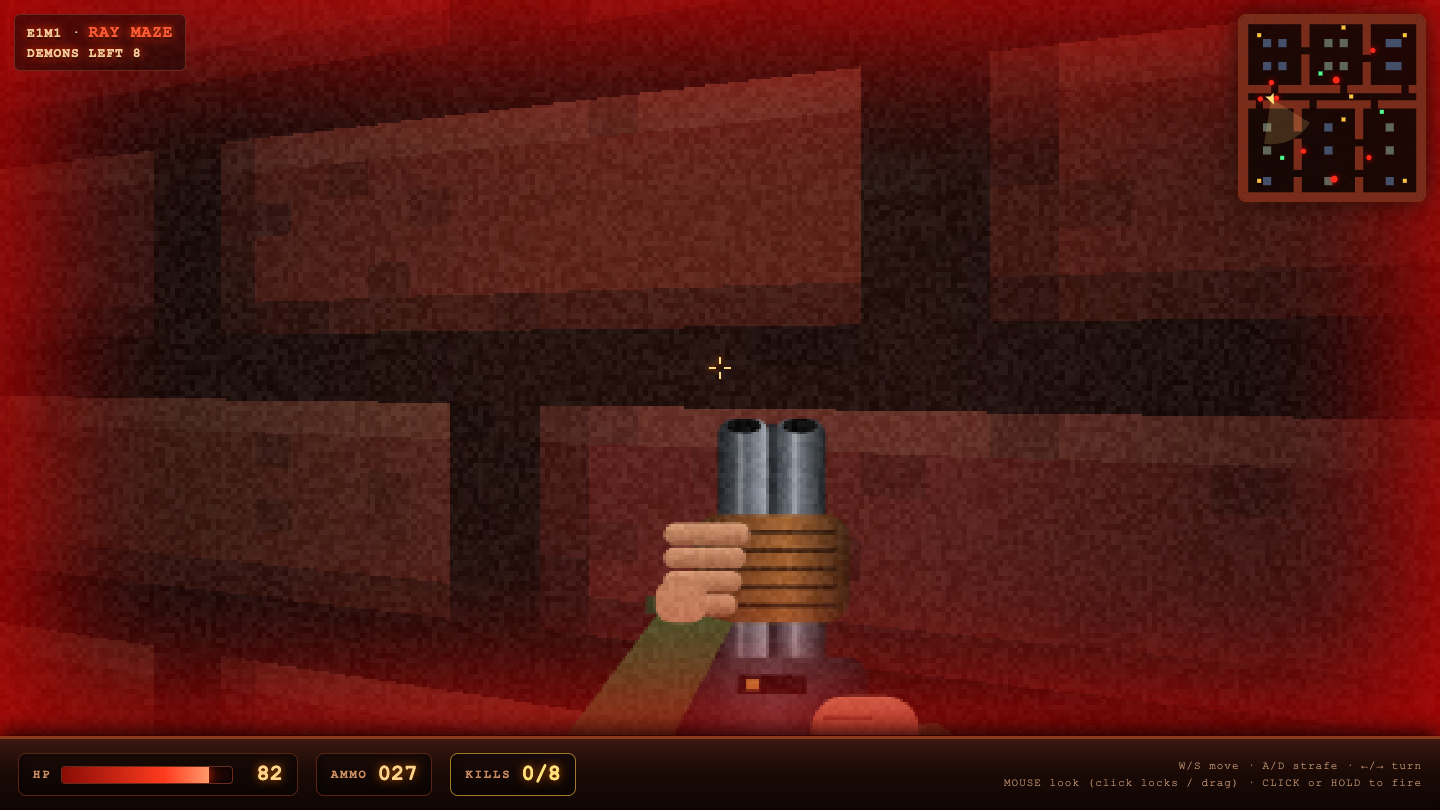
- One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts)
Pricing & context — the spec sheet
| Spec | Kimi K3 | Claude Opus 5.5 |
|---|---|---|
| Vendor | Moonshot AI | Anthropic |
| Context window | 1,048,576 tokens — a full codebase in working memory | 1,000,000 tokens |
| Price | $3 / M in | $4 / $20 per M |
| Pricing detail | Launched July 16, 2026. 2.8T-param MoE (Moonshot's quickstart corrected the circulating 2.5T estimate). $3/M input on OpenRouter at launch; included at no extra cost in the Kimi coding plan (`k3` on the coding endpoint). | Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. |
| Release | 2026-07-16 | 2026-09 |
| Bench coverage | 50/50 scored · avg 7.89/10 | 50/50 scored · avg 7.57/10 |
The verdict — which should you pick?
Across 50 scored shared tasks, Kimi K3 averaged 7.89/10, beating Claude Opus 5.5's 7.57/10 by 0.32 points. Pick Kimi K3 when the build has to ship on the first prompt and you can afford the trade-offs in the comparison below.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire Kimi K3 and Claude Opus 5.5 both into the Agent Operating System and dispatch each from the kanban by task type — long-horizon agent runs → Kimi K3, hardest agentic builds → Claude Opus 5.5. That's the same setup I run for the 4,000+ founders inside the AI Profit Boardroom.
FAQ — Kimi K3 vs Claude Opus 5.5
Which is better, Kimi K3 or Claude Opus 5.5?
On Goldie Bench, Kimi K3 averages 7.89/10 across the shared tasks, with 8 gold, 3 silver, 7 bronze overall. Claude Opus 5.5 averages 7.57/10, with 0 gold, 0 silver, 1 bronze. Kimi K3 wins the head-to-head 38–11.
How much does Kimi K3 cost vs Claude Opus 5.5?
Kimi K3: Launched July 16, 2026. 2.8T-param MoE (Moonshot's quickstart corrected the circulating 2.5T estimate). $3/M input on OpenRouter at launch; included at no extra cost in the Kimi coding plan (`k3` on the coding endpoint). Claude Opus 5.5: Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts.
What's the context window for Kimi K3 vs Claude Opus 5.5?
Kimi K3 has a 1,048,576 tokens — a full codebase in working memory context window. Claude Opus 5.5 has a 1,000,000 tokens context window.
When should I pick Kimi K3 over Claude Opus 5.5?
Pick Kimi K3 for: long-horizon agent runs; whole-repo context work; terminal-driving agents. The trade-off is the weaknesses we logged on the bench: Slow on hard tasks — early testers report up to ~35 minutes at max reasoning; this bench saw 13+ minute single builds; Launch-day rate limits on OpenRouter (429s) — the coding-plan endpoint was the reliable route; Self-reports as K2.7 if you ask it — verify the served model via the API response, not the model's word.
When should I pick Claude Opus 5.5 over Kimi K3?
Pick Claude Opus 5.5 for: Hardest agentic builds; Whole-repo reasoning; Frontier one-shots. The trade-off is the weaknesses we logged on the bench: Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes; One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts).
How does Goldie Bench score Kimi K3 vs Claude Opus 5.5?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
Kimi K3 vs Fusion Claude Opus 5.5 vs Fusion Kimi K3 vs Claude Opus 5 Claude Opus 5.5 vs Claude Opus 5 Kimi K3 vs Hermes MoA Claude Opus 5.5 vs Hermes MoA Kimi K3 vs GPT-5.6 Sol Claude Opus 5.5 vs GPT-5.6 SolFull model pages: Kimi K3 · Claude Opus 5.5 · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.
4,000+founders
258documented wins
38countries
$59/momonthly