Get the Agent OS + join 4,000+ founders inside the AI Profit Boardroom → Join AIPB ($59/mo)
xAI

Grok 4.7

Grok 4.6's price, a bigger base model, and it builds games that hold together.

Context500,000 tokens
Pricing$2 in / $6 out per M tokens
Tasks tested11
Avg score6.86/10 average
Medals🥇0 🥈1 🥉2
Release2026-09
Official vendor source
Grok 4.7 is built by xAI — see the vendor's own product page, pricing, and docs at x.ai/news/grok-4-7.
Visit x.ai/news/grok-4-7 →

Reference benchmarks for Grok 4.7

These are external benchmarks I pulled from the source comparison guides on agentos.guide — SWE-bench Verified, DRACO, Kilo plan rubric, build-time measurements, vendor-reported coding scores. They are not goldiebench medal scores (those come only from same-prompt one-shot creative coding tasks in the matrix). I surface them here so the spec sheet for Grok 4.7 is honest about what's measured.

Artificial Analysis Intelligence Index v4.3.2
46
CursorBench 4.0
46.3%
source: /x.ai
DeepSWE v1.1 (high effort)
71.0%
source: /x.ai
GDPval
1,695 Elo
source: /x.ai
Terminal-Bench 4.0
38.0%
source: /x.ai

What is Grok 4.7?

Grok 4.7 is the xAI frontier model with a 500,000 tokens context window, released 2026-09. Tagline: Grok 4.6's price, a bigger base model, and it builds games that hold together.. Official source: x.ai/news/grok-4-7.

Pricing detail. xAI's September 2026 release, priced exactly like Grok 4.6: $2 per million input tokens and $6 per million output on the standard tier, $4 / $12 on the Fast tier (double the output speed). OpenRouter lists the same model at $1.60 / $4.80.

How I use it inside the Agent OS. Wired into the Agent OS Grok Build tab (4.7 / 4.6 / 4.5 picker, OpenRouter fallback when the CLI is signed out) and benched on twenty skill-infused game builds, each played through its full gameplay arc on a Metal GPU before the vision judge scored the played frame.

What I built with Grok 4.7

Every model on Goldie Bench gets the same fixed prompt set — one shot, single HTML file out — and I score the result 0–10 inside the Agent Operating System. Here's what Grok 4.7 shipped on the bench: 11 one-shot demos across 500,000 tokens of context. Of those, 11 are scored against the field with my honest 0–10 from the source guides at agentos.guide.

Strengths

  • Averaged 6.86/10 on the same twenty skill-infused game briefs where Grok 4.6 averaged 5.63, winning 8 of the 11 head-to-heads
  • Best one-shots on this run: arcade (8.6), dragonrealm (8.6), flightsim (8.5), every one played on a real GPU before scoring
  • Longer reinforcement learning shows: it holds a 40-50KB single-file spec and wires the controls it advertises
  • xAI's own coding numbers moved: CursorBench 4.0 46.3% (from 40.4%) and DeepSWE v1.1 71.0% (from 65.2%)

Trade-offs

  • 2 of 20 builds died on load or never moved when played — crypt: hud is not a function; voxelcraft: mesh.computeBoundingSphere is not a function file:///Users/j
  • Independent Artificial Analysis Intelligence Index v4.3.2 puts it at 46, seven points behind Claude Fable 5.1 and GPT-6 at 53
  • Terminal-Bench 4.0 is the weak spot xAI reports itself: 38.0% at launch

Best for

  • One-shot arcade, driving and shooter builds where the whole game has to arrive in a single file
  • High-volume agent work priced at half what the other frontier models charge
  • Grok Build inside the Agent OS: pick 4.7 in the tab and everything it writes lands in the workspace

Every benchmark — Grok 4.7's full scorecard

All 11 scored tasks, best first — the judge's 0–10 on the same rubric as the whole field. Click any bar for that task's cross-model page, or open this scorecard in the interactive graphs. Full editorial breakdown with judge quotes and sourced outside research: the Grok 4.7 deep dive →.

Every demo by Grok 4.7

11 live demos, sorted by category. Click any tile to play the actual one-shot result. Verdicts and 0–10 scores are pulled from the source guides where I posted them publicly.
Grok 4.7 one-shot build of Crypt — GoldieBench AI benchmark screenshot▶ LIVE
Crypt
Game
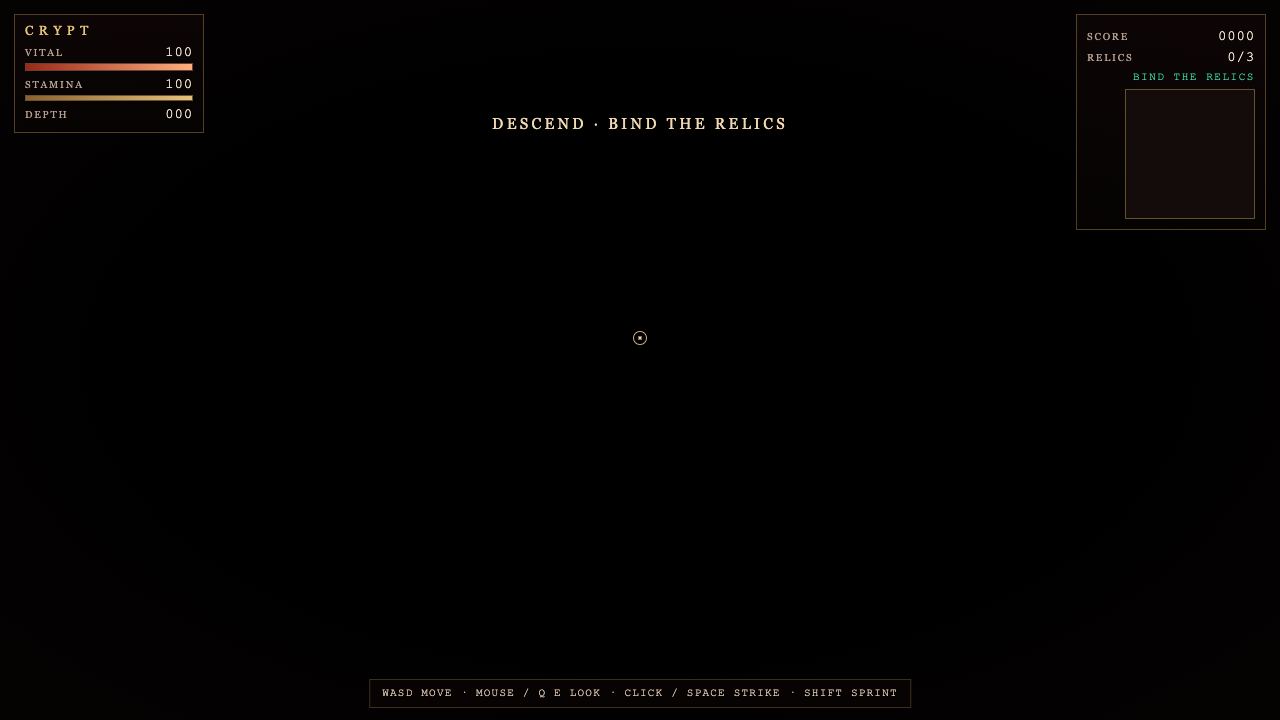
The 3D scene never rendered — screen is pure black (lum mean 2.3, zero pixel change across all playtest moments) with a fatal 'hud is not a function' console error freezing the game at DEPTH 000 / SCORE 0000. Only the polished HUD chrome shows; the actual crypt crawler is non-functional.
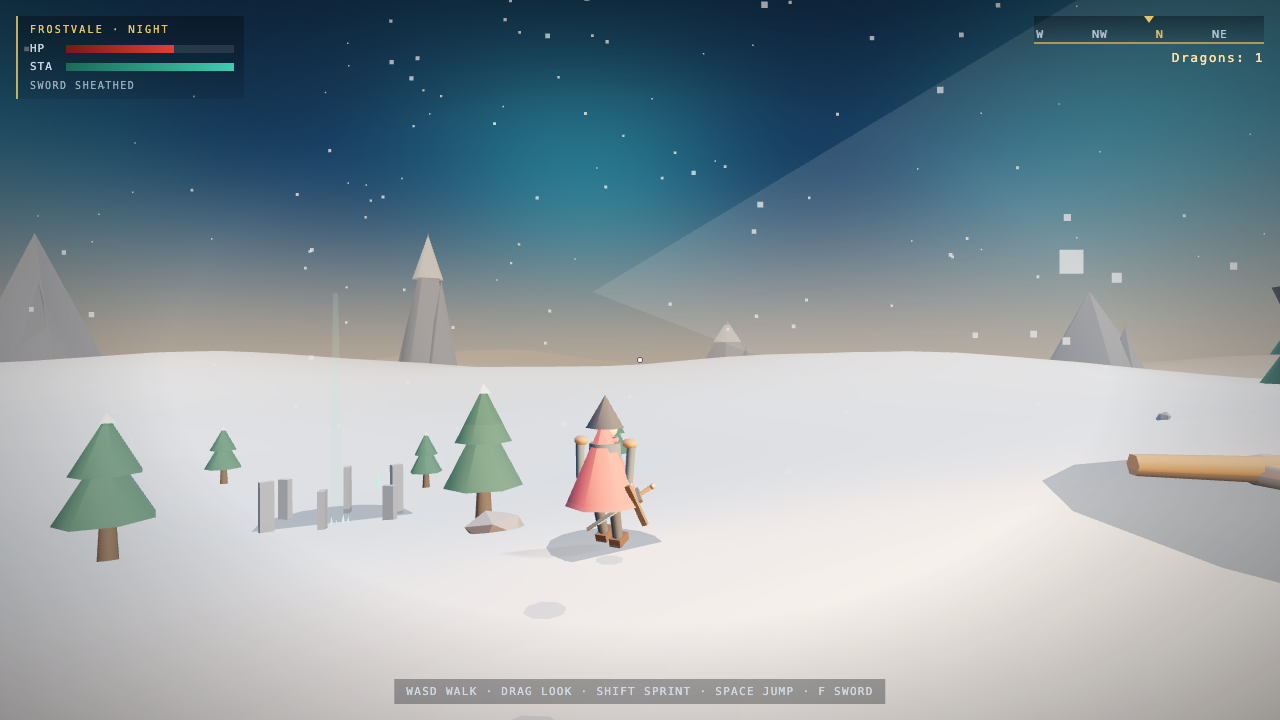
Grok 4.7 one-shot build of Dragonrealm — GoldieBench AI benchmark screenshot▶ LIVE
Dragonrealm 🥉
Game
Gorgeous polished frozen scene — aurora sky, snowy hills, low-poly pines, standing stones, a caped character with sheathed sword, and a working HUD with compass/dragon counter; playtest shows real movement (walkPx 0.58), dragon-dive events, and a STRUCK combat state, hitting the Skyrim brief squarely.
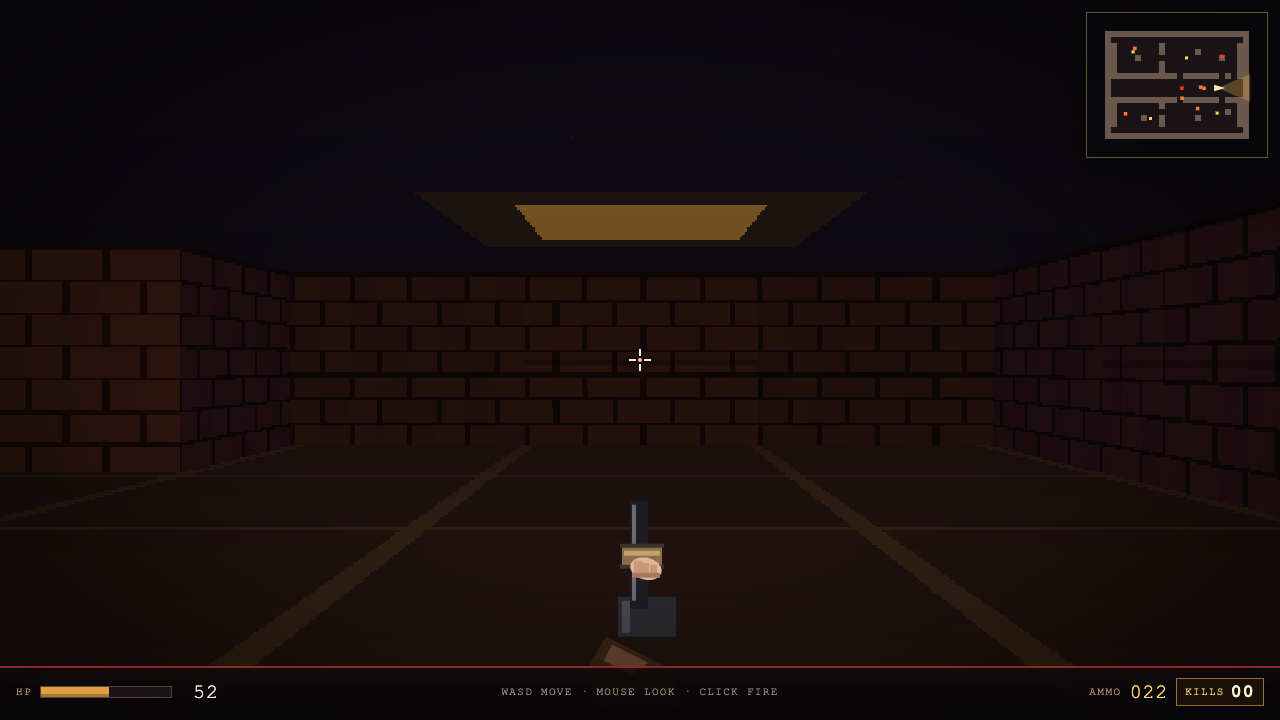
Grok 4.7 one-shot build of Doom — GoldieBench AI benchmark screenshot▶ LIVE
Doom
Game
Strong Doom-flavored raycaster with polished brick walls, weapon sprite, minimap, and detailed demon art in source — the render looks atmospheric and on-brief. But the playtest shows HP draining to 0 (player died) with KILLS stuck at 00 and no monster visible in the frame, so combat against the chasing monsters never actually landed on screen despite the enemies clearly being coded.
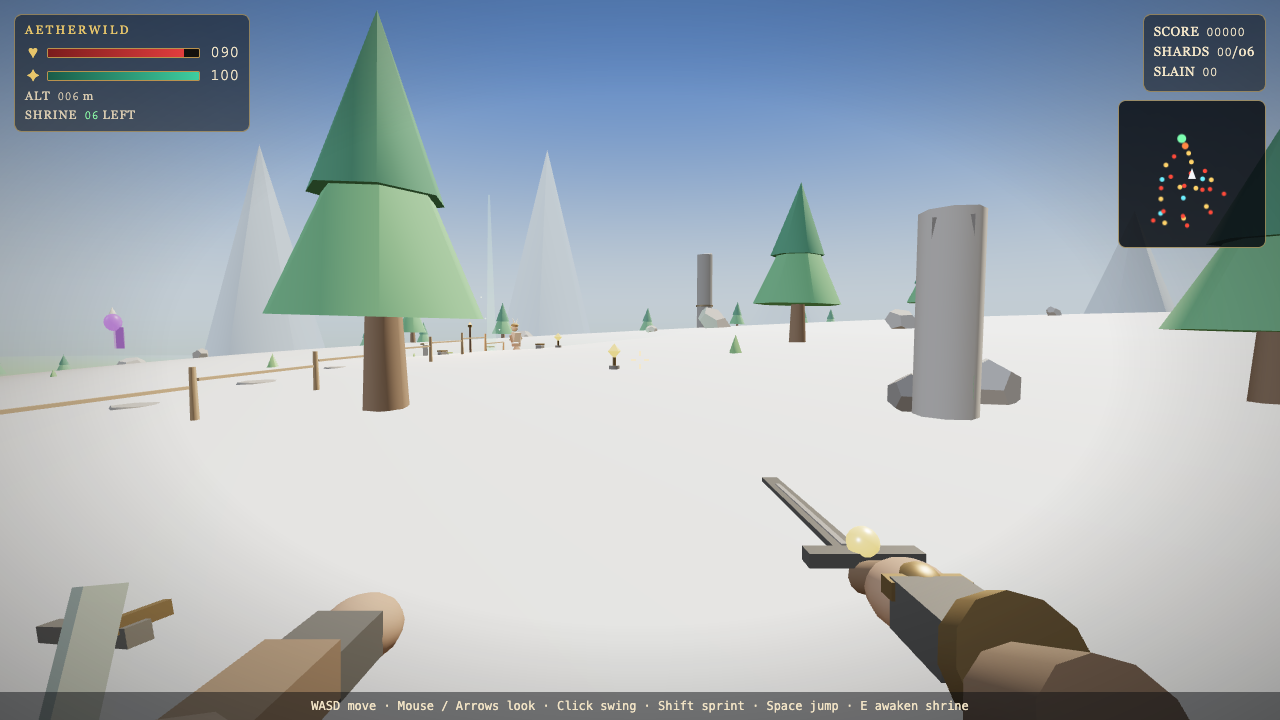
Grok 4.7 one-shot build of Skyrim — GoldieBench AI benchmark screenshot▶ LIVE
Skyrim
Game
Renders a polished, atmospheric first-person Skyrim-lite with soft-shadowed low-poly pines, standing stones, held sword+shield, a working minimap, and a rich RPG HUD (health/stamina/shards/shrines/altitude). Playtest confirms real movement, altitude climbing, and HP dropping from 100→80 (combat/damage working); it's cohesive and on-brief, just slightly generic-snowfield rather than the top's variety.
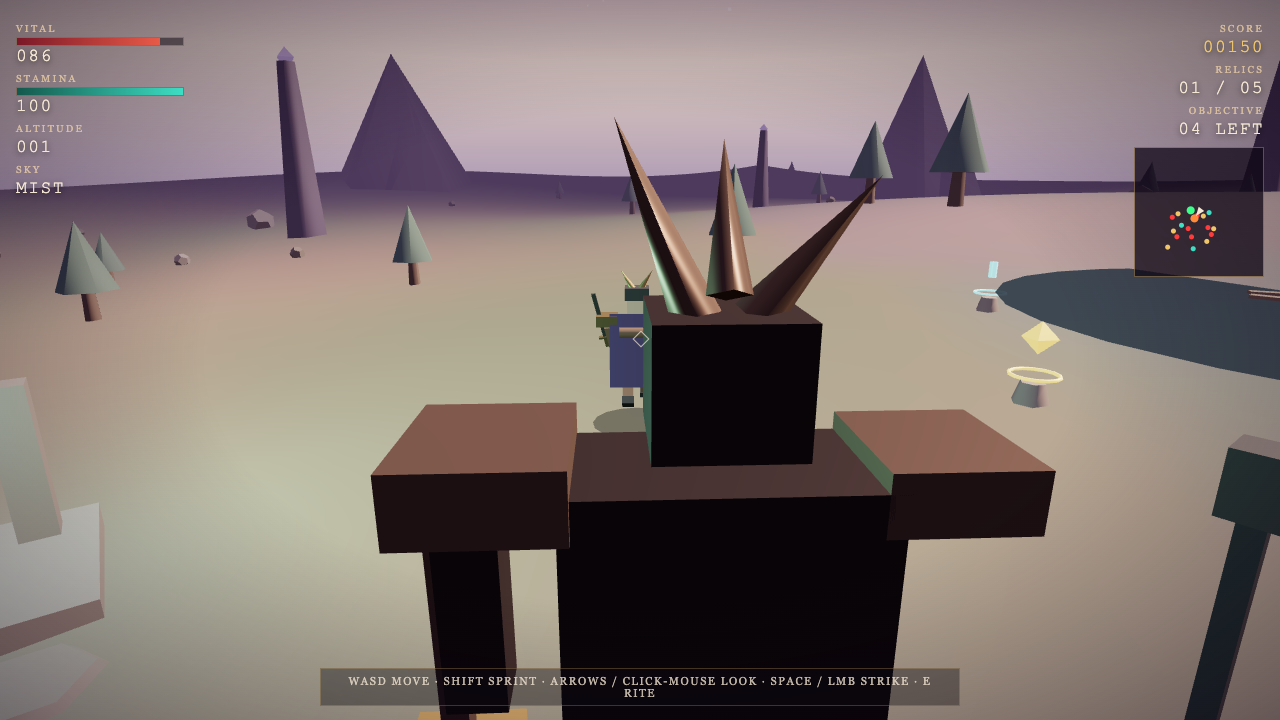
Grok 4.7 one-shot build of Twilightvale — GoldieBench AI benchmark screenshot▶ LIVE
Twilightvale
Game
Renders a polished twilight open-world with terrain, water pool, scattered trees/monoliths, relics, minimap, and a functional combat loop — HUD shows score climbing, a relic collected, VITAL dropping from a WARDEN fight, all confirming real progression. Strong and shippable, but the giant dark foreground obelisks/spikes dominate the frame awkwardly and weather stays static MIST throughout, keeping it just shy of the field's best.
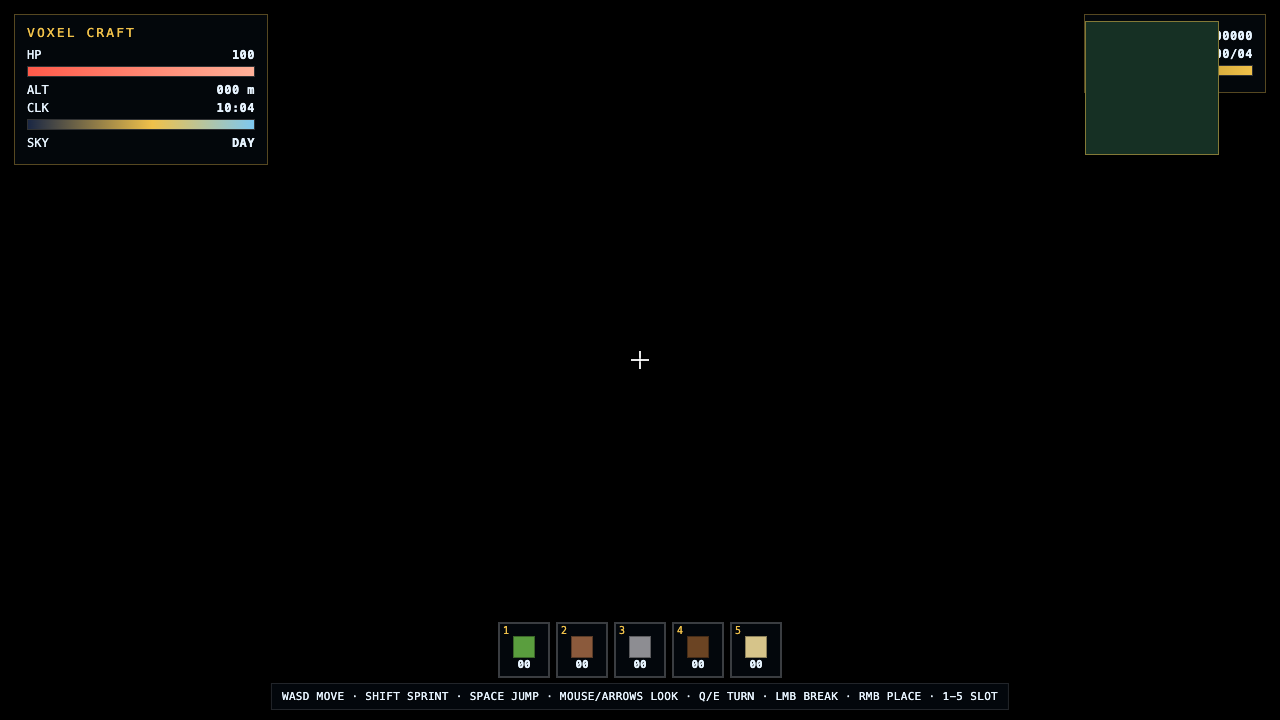
Grok 4.7 one-shot build of Voxelcraft — GoldieBench AI benchmark screenshot▶ LIVE
Voxelcraft
Game
The 3D world never rendered — the canvas stays black with only the HUD/hotbar visible, and a console error (computeBoundingSphere is not a function) plus zero pixel-change and frozen HUD confirm the voxel scene never appeared. Nicely designed HUD, but the actual game is broken/non-rendering.
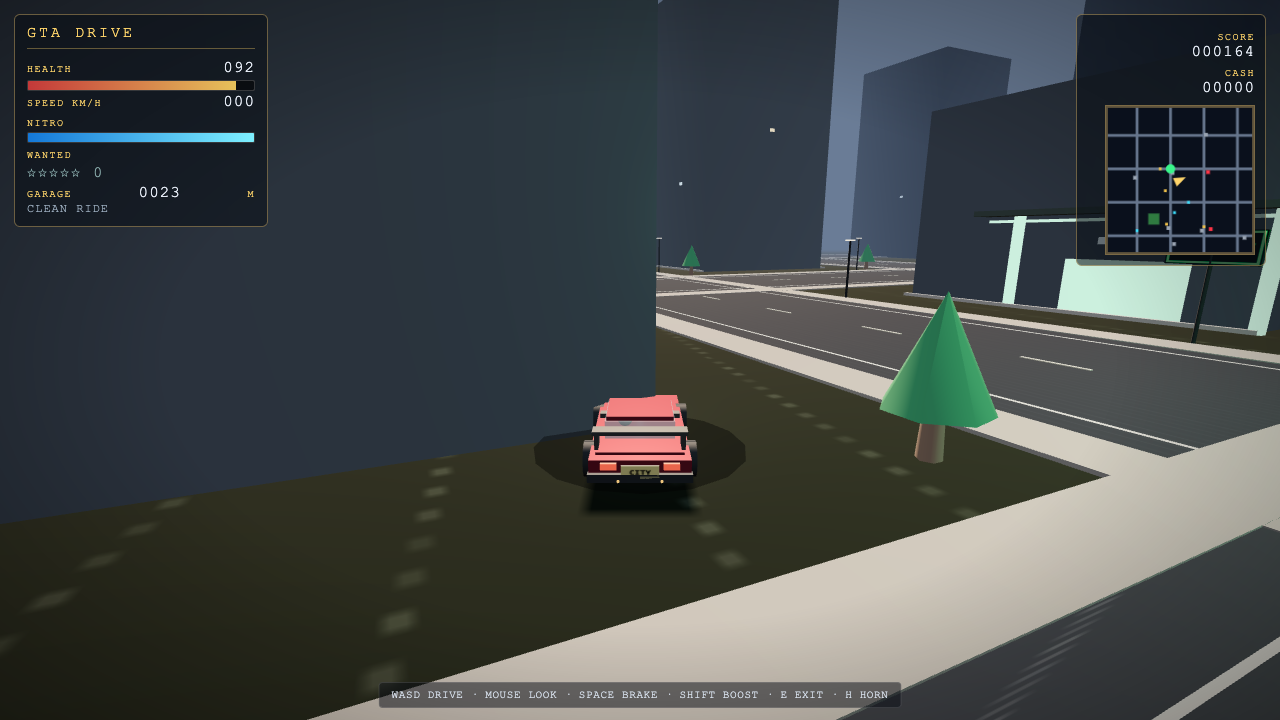
Grok 4.7 one-shot build of Gtadrive — GoldieBench AI benchmark screenshot▶ LIVE
Gtadrive
Game
Renders a polished city sandbox with a detailed HUD (health, nitro, wanted stars, minimap with markers) and a nicely modeled car, and the playtest shows real movement — distance closed from 0104 to 0023, score rose to 164, health dropped on crash. Weak points: speed reads 000 and the car stalled by the end (latePx 0.002), nitro/wanted never engaged, so it works but doesn't fully deliver the outrun-cops/traffic loop.
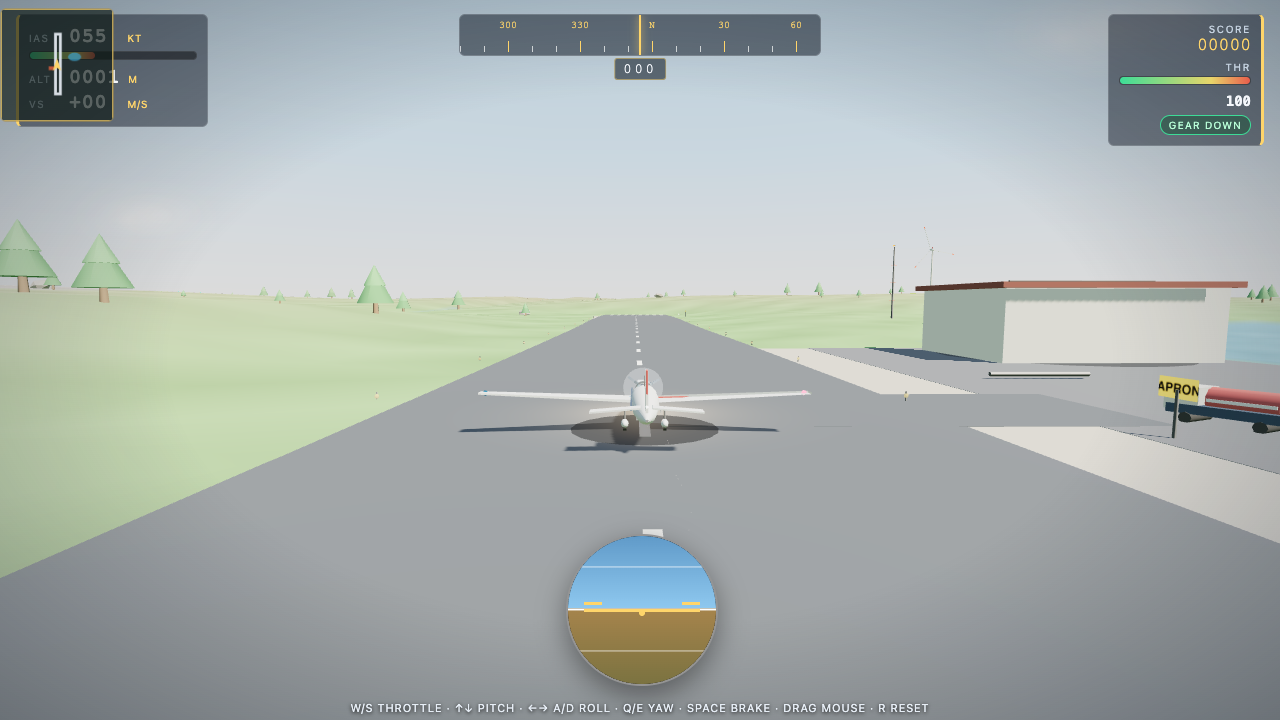
Grok 4.7 one-shot build of Flightsim — GoldieBench AI benchmark screenshot▶ LIVE
Flightsim 🥉
Game
Strong render with a detailed 3D airport (runway, hangar, apron truck), clean chase-cam plane, and a rich professional HUD (heading tape, artificial horizon, IAS/ALT/VS gauges); playtest confirms real takeoff physics — throttle to 100, IAS ramping 55→146kt, ALT climbing 1→236m with VS +60 and heading changes. Minor nit: score stayed 00000 and no explicit landing was demonstrated, but the flight loop clearly works and looks great.
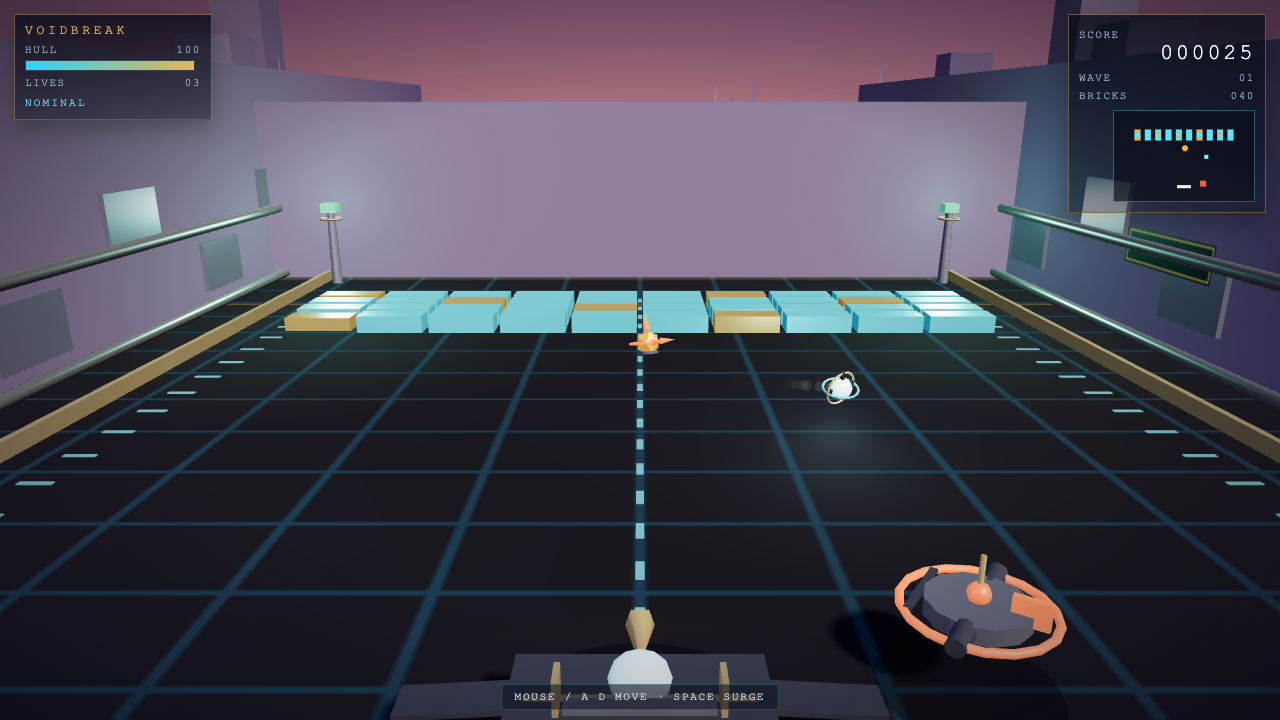
Grok 4.7 one-shot build of Arcade — GoldieBench AI benchmark screenshot▶ LIVE
Arcade 🥈
Game
A gorgeous 3D breakout with rich lighting, gradient sky dome, gridded arena, minimap, and a polished sci-fi HUD; playtest confirms real motion (walkPx 0.23) with hull/lives/score/bricks all changing and no console errors — clearly at or above the field's best.
Grok 4.7 one-shot build of Dogfight — GoldieBench AI benchmark screenshot▶ LIVE
Dogfight
Game
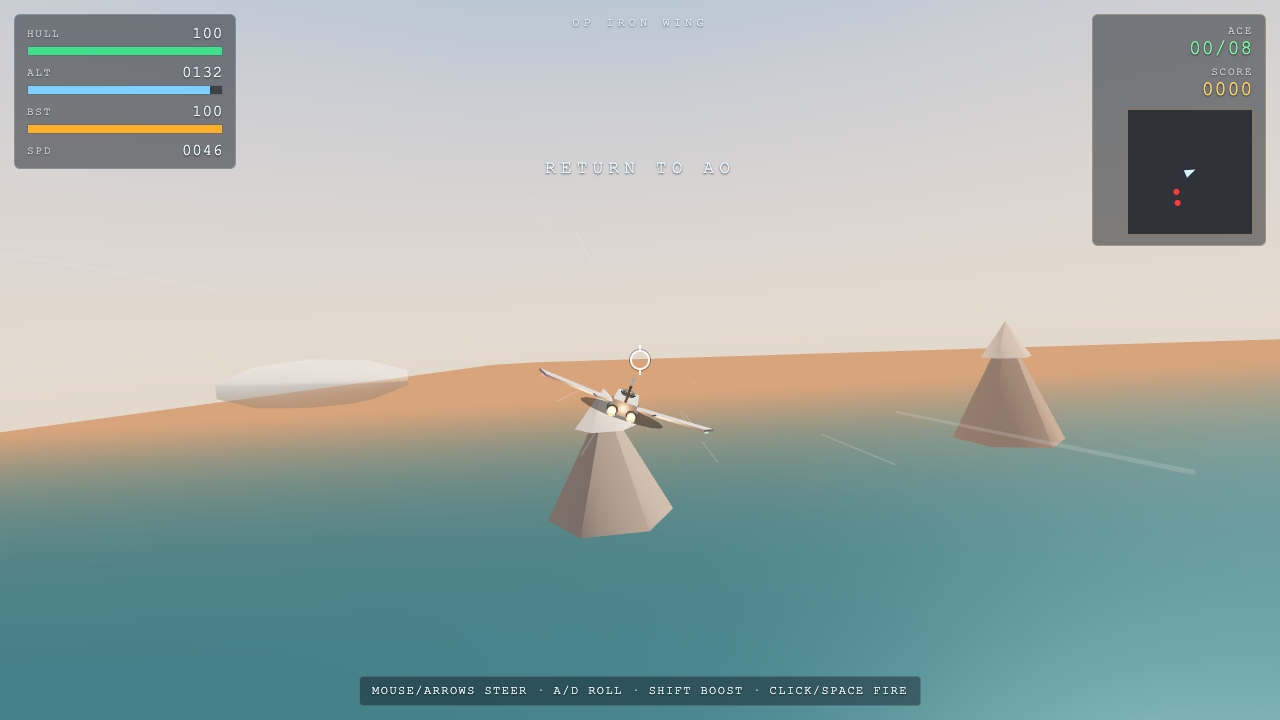
Renders a polished HUD, minimap, and a nicely modeled plane over a warm desert/water world, but playtest shows score/kills frozen at 00/08 and 0000 with the game stuck in 'RETURN TO AO' and near-zero late pixel change — the combat loop never engaged. Strong visual presentation undercut by no demonstrable dogfighting.
Grok 4.7 one-shot build of Rpg — GoldieBench AI benchmark screenshot▶ LIVE
Rpg
Game
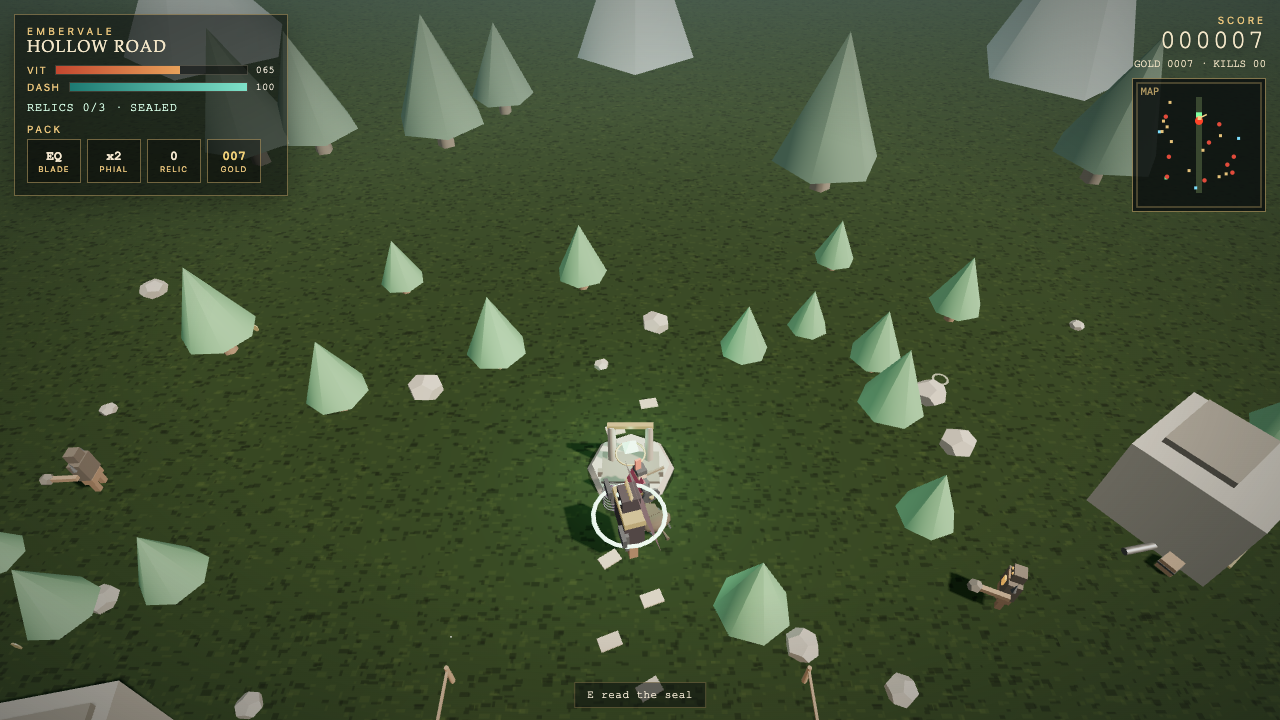
Strong, atmospheric top-down RPG with a polished themed HUD (vit/dash/relics/inventory/minimap), 3D low-poly world, enemies and interactive seals — HUD evidence shows gold/score/vit all progressing and combat context living. Loses some points because VIT dropped steadily toward death with no visible relic/kill progress in the run, suggesting punishing early enemies and thin loop payoff versus the best in field.
every demo, in a grid · click any one to play

Compare Grok 4.7 against every other model

Every head-to-head featuring Grok 4.7. Verdicts shown for scored pairs.

Grok 4.7 vs Fusion
Fusion leads 10–1
Grok 4.7 vs Claude Opus 5
Claude Opus 5 leads 7–4
Grok 4.7 vs Hermes MoA
Hermes MoA leads 6–3
Grok 4.7 vs GPT-5.6 Sol
GPT-5.6 Sol leads 6–2
Grok 4.7 vs Claude Fable 5
Claude Fable 5 leads 7–4
Grok 4.7 vs Qwen 3.8
Qwen 3.8 leads 6–3
Grok 4.7 vs Grok
Grok leads 6–2
Grok 4.7 vs MiniMax M3
MiniMax M3 leads 8–3
Grok 4.7 vs Fugu Ultra
Fugu Ultra leads 5–4
Grok 4.7 vs Kimi K3
Kimi K3 leads 5–4
Grok 4.7 vs GLM-5.2
Grok 4.7 leads 6–5
Grok 4.7 vs Fugu Mini
Grok 4.7 leads 5–1
Grok 4.7 vs Muse Spark 1.2
Grok 4.7 leads 7–4
Grok 4.7 vs Opus 4.8
Grok 4.7 leads 6–5
Grok 4.7 vs Kimi K2.7
Kimi K2.7 leads 3–2
Grok 4.7 vs Qwable 5 27B Coder
Grok 4.7 leads 6–3
Grok 4.7 vs Gemini 3.6 Flash
Grok 4.7 leads 6–5
Grok 4.7 vs Claude Sonnet 5
Grok 4.7 leads 7–4
Grok 4.7 vs Qwen 3.7
Grok 4.7 leads 6–5
Grok 4.7 vs Fugu Ultra 1.1
Fugu Ultra 1.1 leads 5–4
Grok 4.7 vs Inkling
Grok 4.7 leads 8–3
Grok 4.7 vs Grok 4.6
Grok 4.7 leads 8–3
Grok 4.7 vs Agents-A1
Grok 4.7 leads 6–3
Grok 4.7 vs Gemma 4 12B · MLX
Grok 4.7 leads 7–2
Grok 4.7 vs Laguna XS 2.1
Grok 4.7 leads 7–2
Grok 4.7 vs Qwythos 9B
Grok 4.7 leads 8–1
Grok 4.7 vs LongCat-2.0
LongCat-2.0 leads 3–1
Grok 4.7 vs Hy3
Grok 4.7 leads 4–0
Grok 4.7 vs Gemma-4 12B Coder
Grok 4.7 leads 1–0
Grok 4.7 vs DeepSeek V4 Flash
11 shared tasks · unscored
Grok 4.7 vs DeepSeek V4 Pro
11 shared tasks · unscored
Grok 4.7 vs Kimi K2.7 · Fast
11 shared tasks · unscored
Grok 4.7 vs Kimi K2.7 · No-Think
11 shared tasks · unscored
Grok 4.7 vs Kimi K2.7 · Quality
11 shared tasks · unscored
Grok 4.7 vs Ornith 1.0
9 shared tasks · unscored
Grok 4.7 vs Claude Mythos 5
Reference-only
Grok 4.7 vs Kilo Code
Reference-only

See all 66 comparisons across every model →

Quick pill index

Direct comparisons against every other scored model on the bench:

Grok 4.7 vs Fusion Grok 4.7 vs Claude Opus 5 Grok 4.7 vs Hermes MoA Grok 4.7 vs GPT-5.6 Sol Grok 4.7 vs Claude Fable 5 Grok 4.7 vs Qwen 3.8 Grok 4.7 vs Grok Grok 4.7 vs MiniMax M3 Grok 4.7 vs Fugu Ultra Grok 4.7 vs Kimi K3 Grok 4.7 vs GLM-5.2 Grok 4.7 vs Fugu Mini Grok 4.7 vs Muse Spark 1.2 Grok 4.7 vs Opus 4.8 Grok 4.7 vs Kimi K2.7 Grok 4.7 vs Qwable 5 27B Coder Grok 4.7 vs Gemini 3.6 Flash Grok 4.7 vs Claude Sonnet 5 Grok 4.7 vs Qwen 3.7 Grok 4.7 vs Fugu Ultra 1.1 Grok 4.7 vs Inkling Grok 4.7 vs Grok 4.6 Grok 4.7 vs Agents-A1 Grok 4.7 vs Gemma 4 12B · MLX Grok 4.7 vs Laguna XS 2.1 Grok 4.7 vs Qwythos 9B Grok 4.7 vs LongCat-2.0 Grok 4.7 vs Hy3 Grok 4.7 vs Gemma-4 12B Coder

Read more on agentos.guide: /grok-4-7-agent-os

Grok 4.7 — frequently asked

What is Grok 4.7?

Grok 4.7 is xAI's AI model — Grok 4.6's price, a bigger base model, and it builds games that hold together. It has a 500K tokens context window and was released 2026-09.

How good is Grok 4.7 at coding and one-shot builds?

On the GoldieBench one-shot build benchmark it averages 6.86/10 across 11 scored tasks, with 0 gold, 1 silver and 2 bronze medals.

How much does Grok 4.7 cost?

$2 in / $6 out per M tokens. xAI's September 2026 release, priced exactly like Grok 4.6: $2 per million input tokens and $6 per million output on the standard tier, $4 / $12 on the Fast tier (double the output speed). OpenRouter lists the same model

Where can I see Grok 4.7 demos?

Every one-shot build is live and playable on this page and on the GoldieBench compare matrix — same prompt as every other model, no retries.

The same stack Julian uses

Run this stack yourself.

Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.

4,000+founders
258documented wins
38countries
$59/momonthly