Real head-to-head · same prompt, one shot
Fugu Mini vs Grok 4.7
Fugu's fast mini variant — single model, no panel, ~3 min per build. vs Grok 4.6's price, a bigger base model, and it builds games that hold together.
Head-to-head verdict: Grok 4.7 wins 8–4.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to Fugu Mini and Grok 4.7, side by side, on 12 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
Fugu Mini · Dispatched from Agent OS as the fast Sakana lane. Bench scored by Claude judge against the same 42 prompts.
Grok 4.7 · Wired into the Agent OS Grok Build tab (4.7 / 4.6 / 4.5 picker, OpenRouter fallback when the CLI is signed out) and benched on twenty skill-infused game builds, each played through its full gameplay arc on a Metal GPU before the vision judge scored the played frame.
Side-by-side on 45 shared tasks
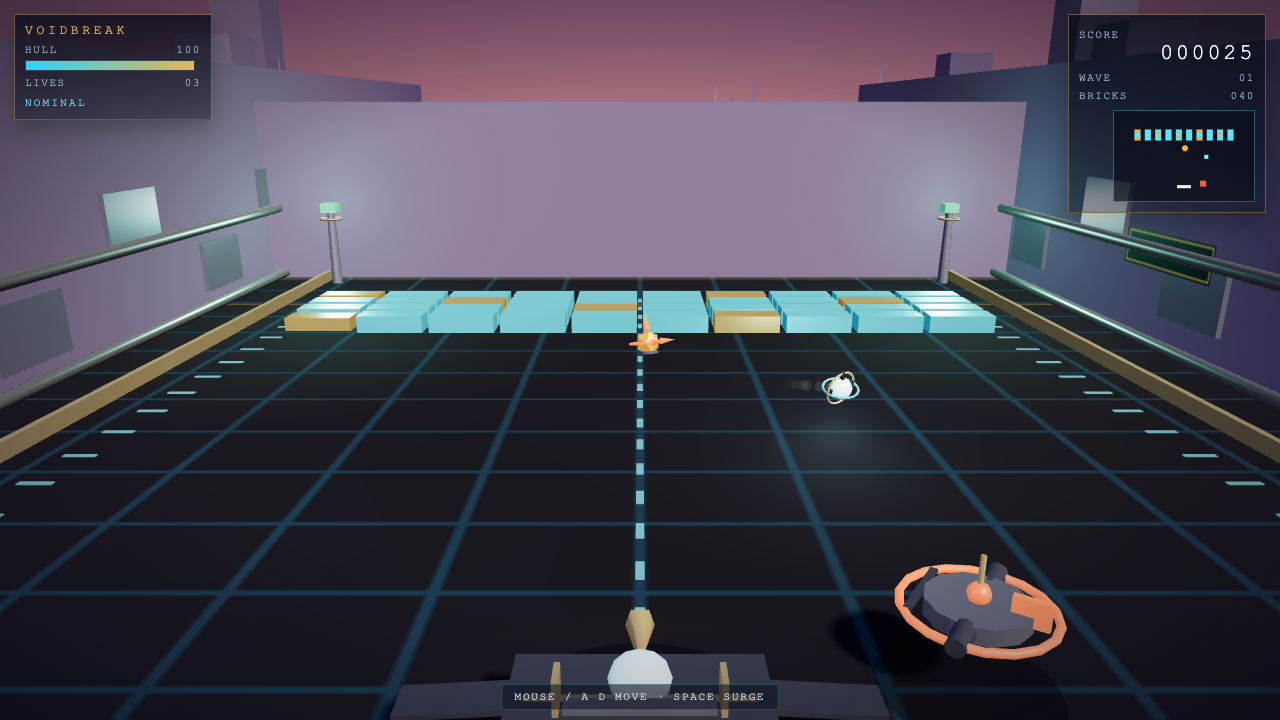
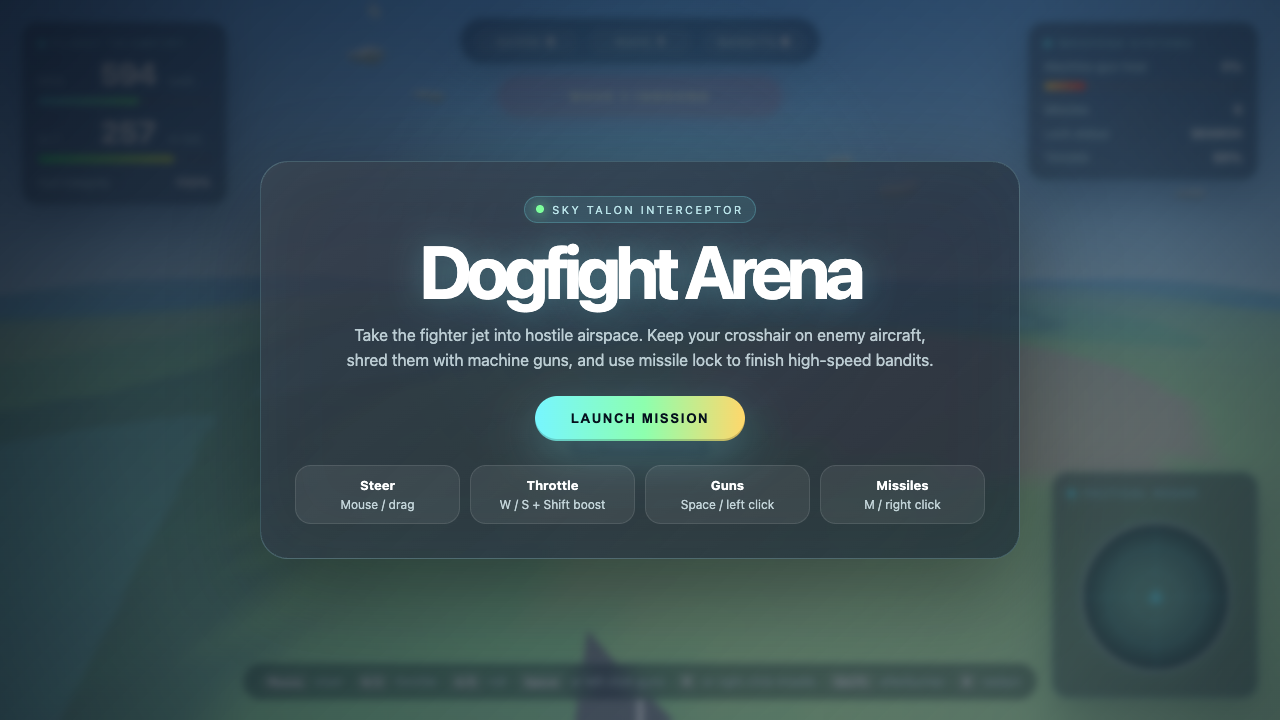
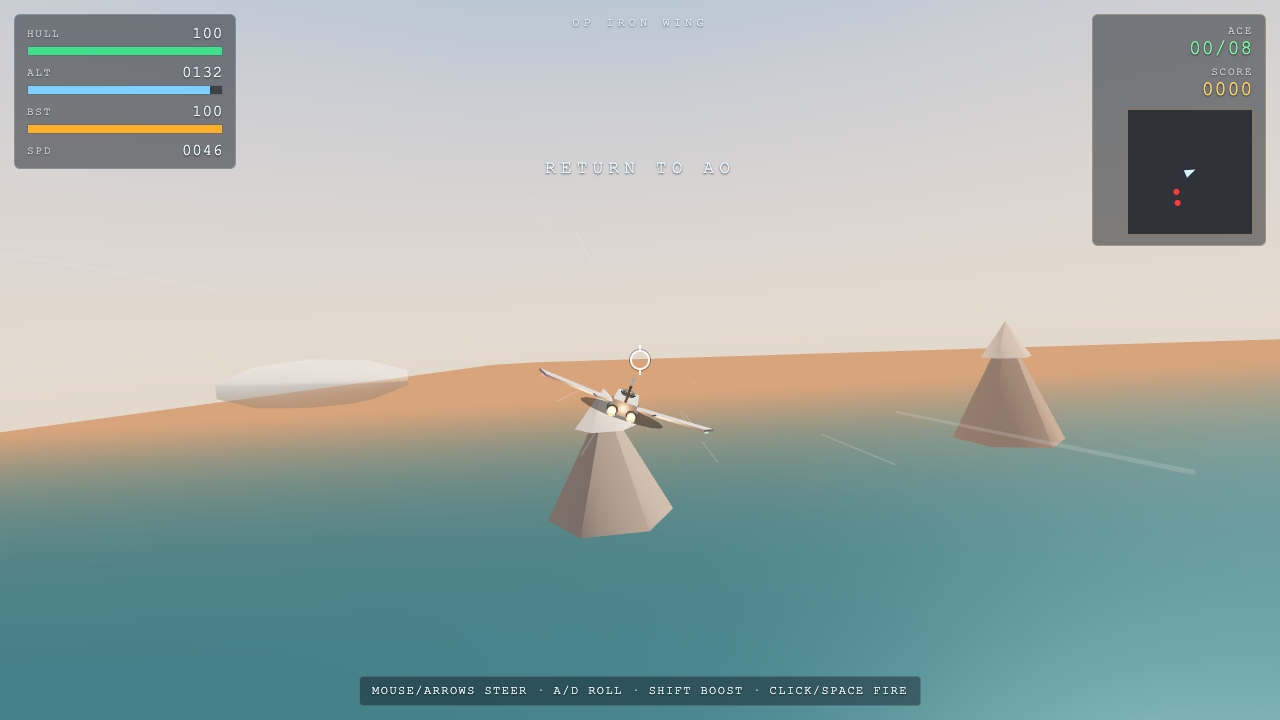
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
Fugu Mini
Grok 4.7
Game
Game
Game
Game
Game
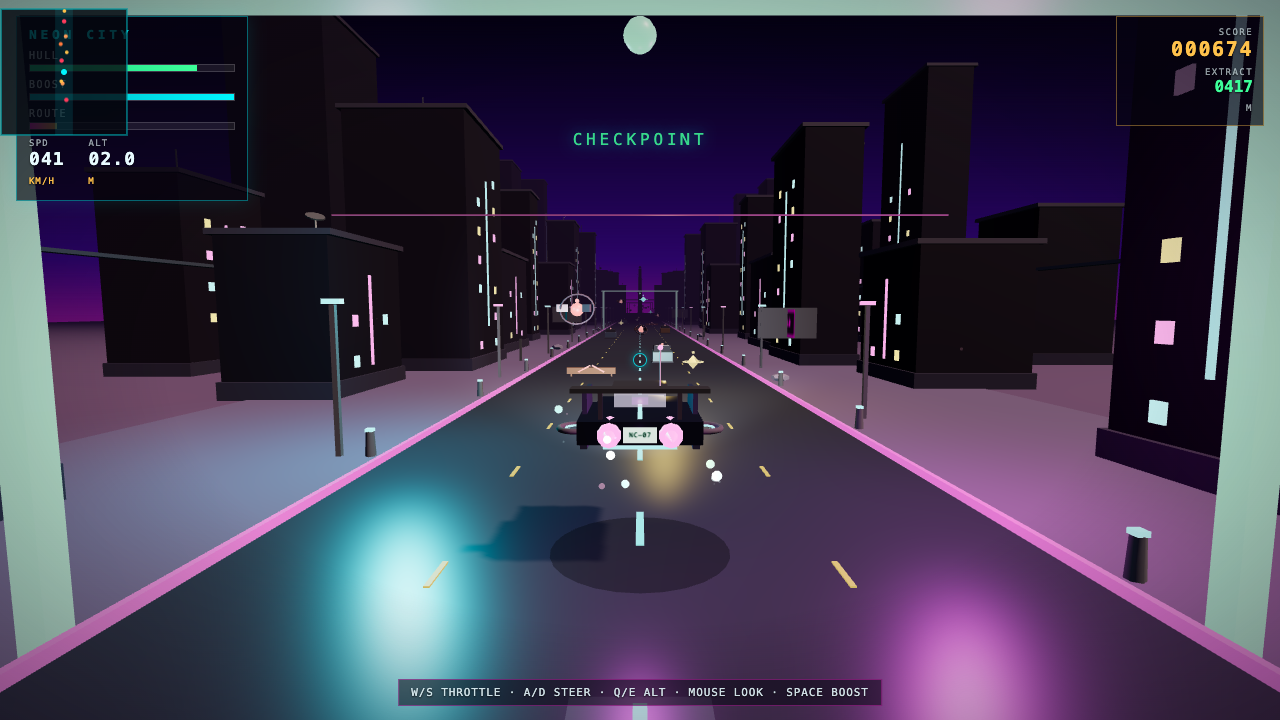
Game
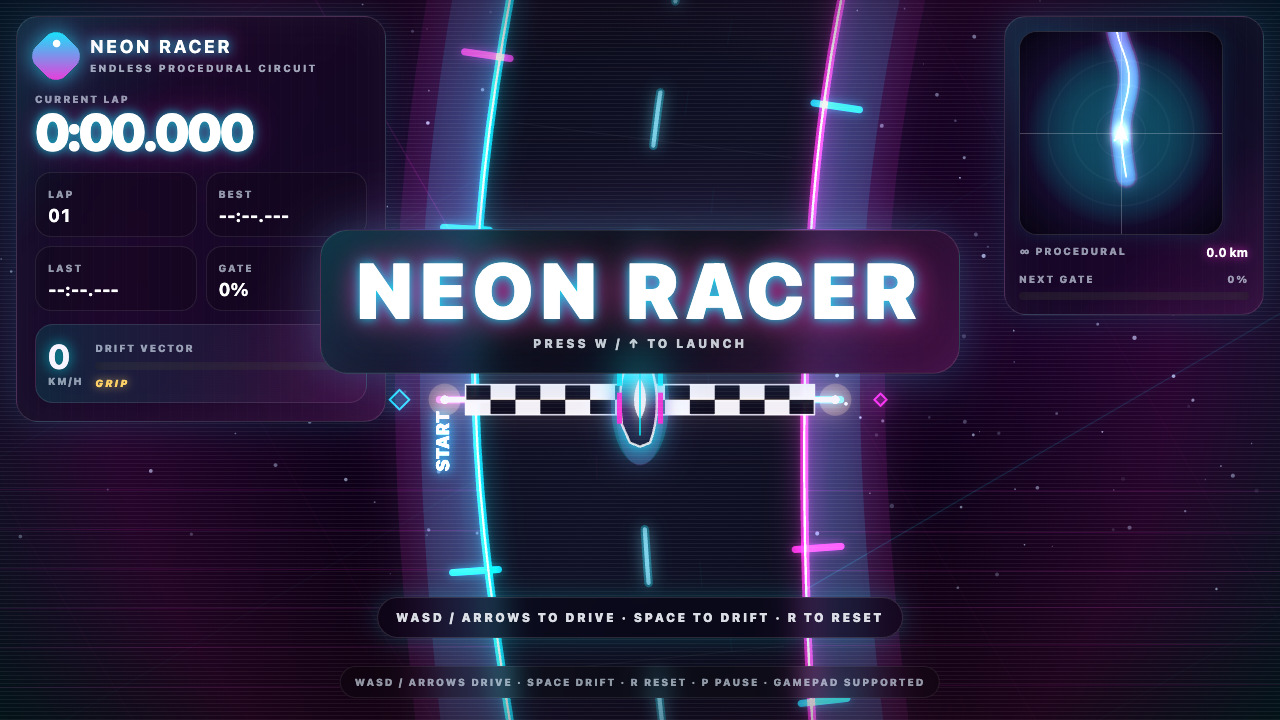
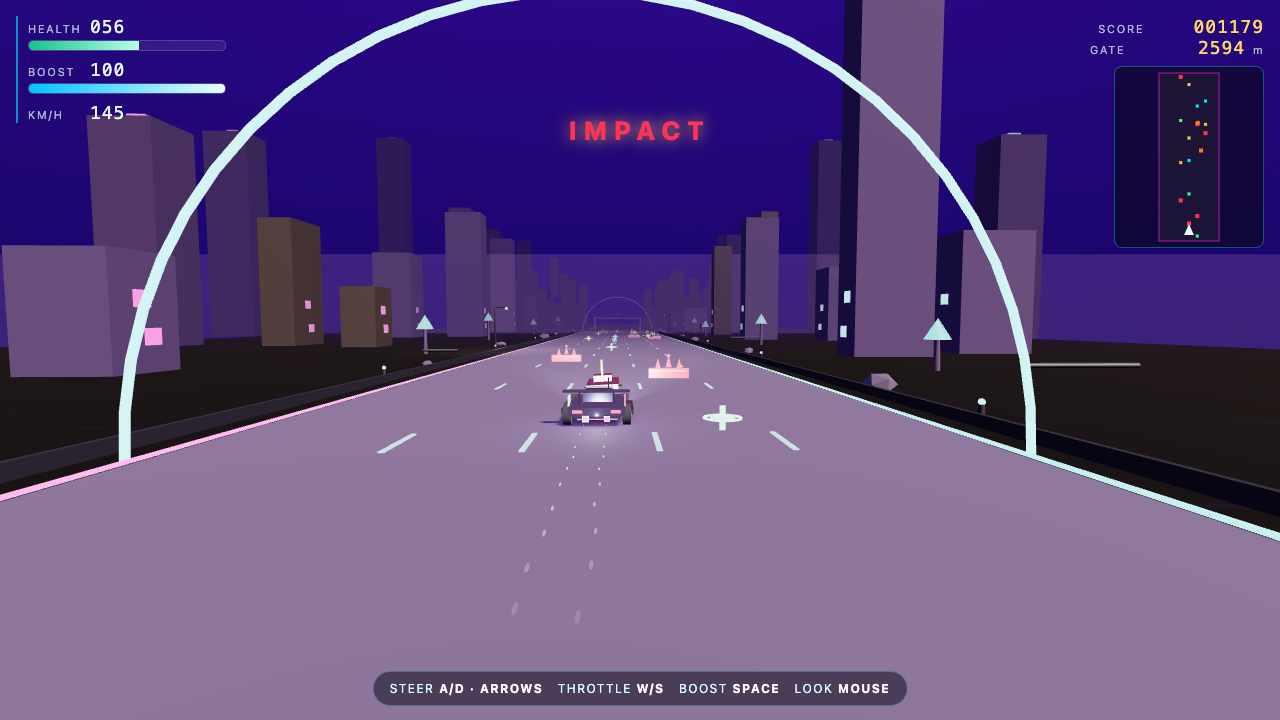
Game
Game
Game
Game
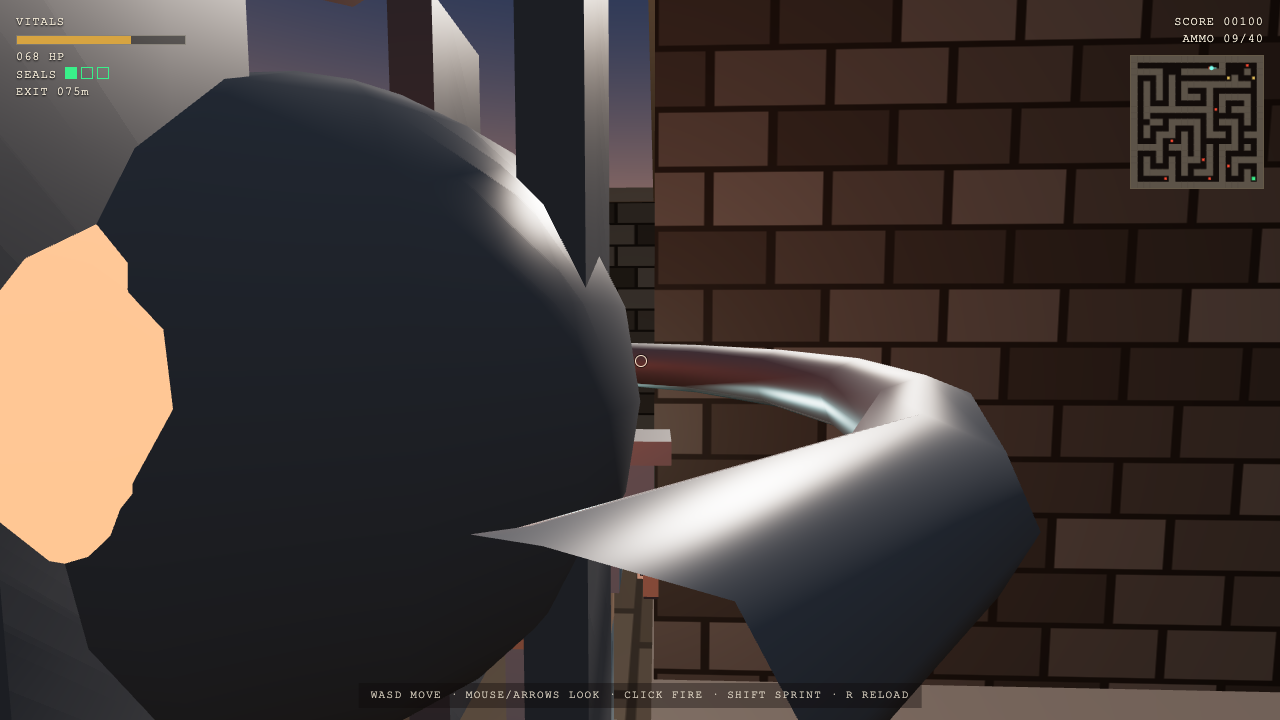
Game
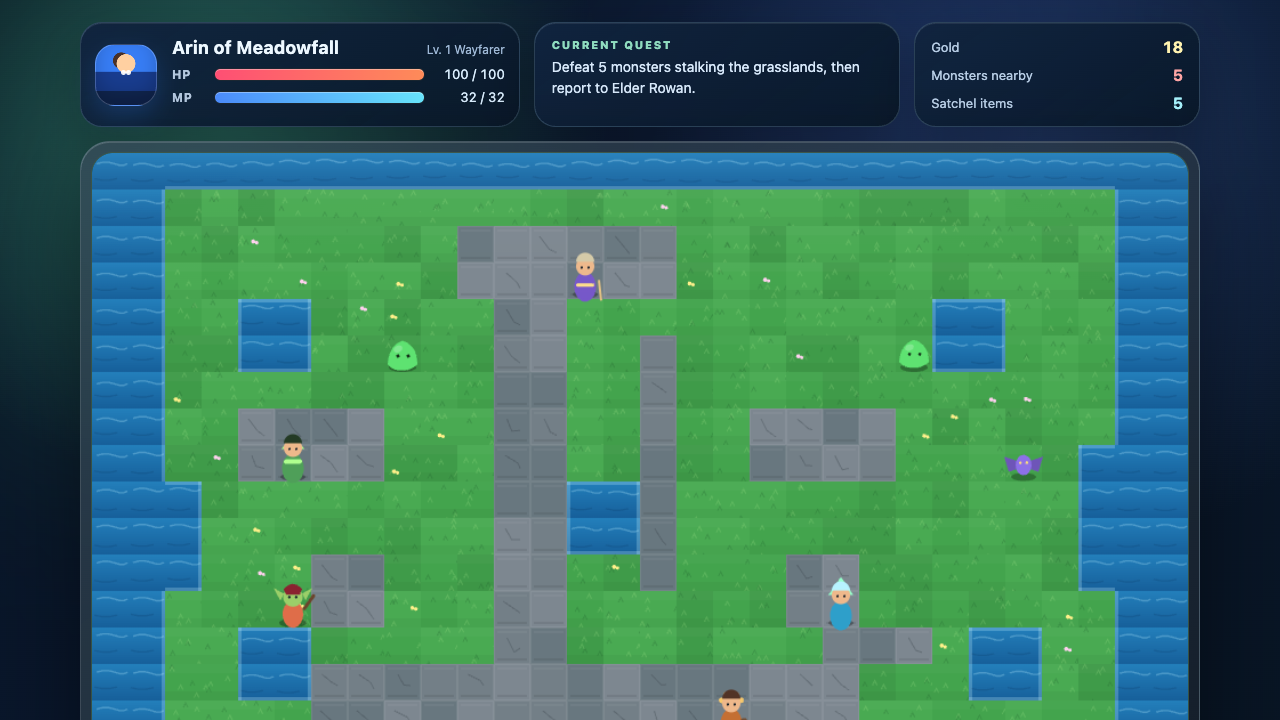
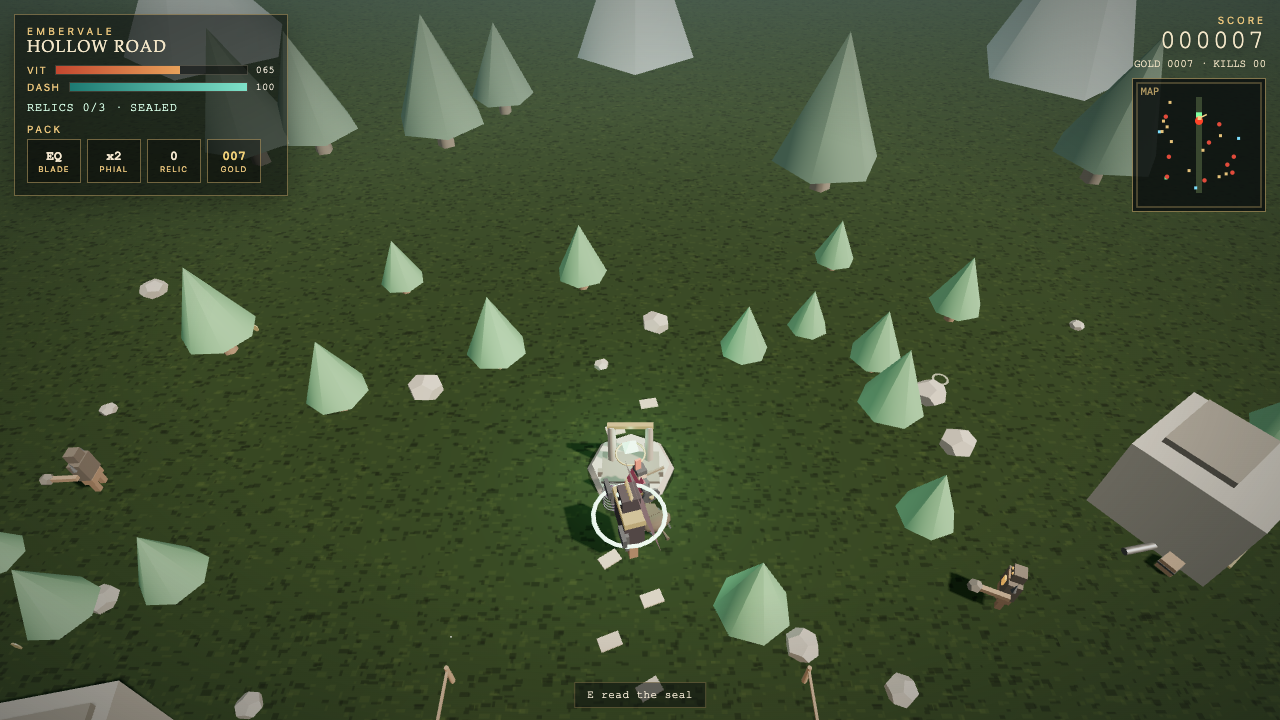
Game
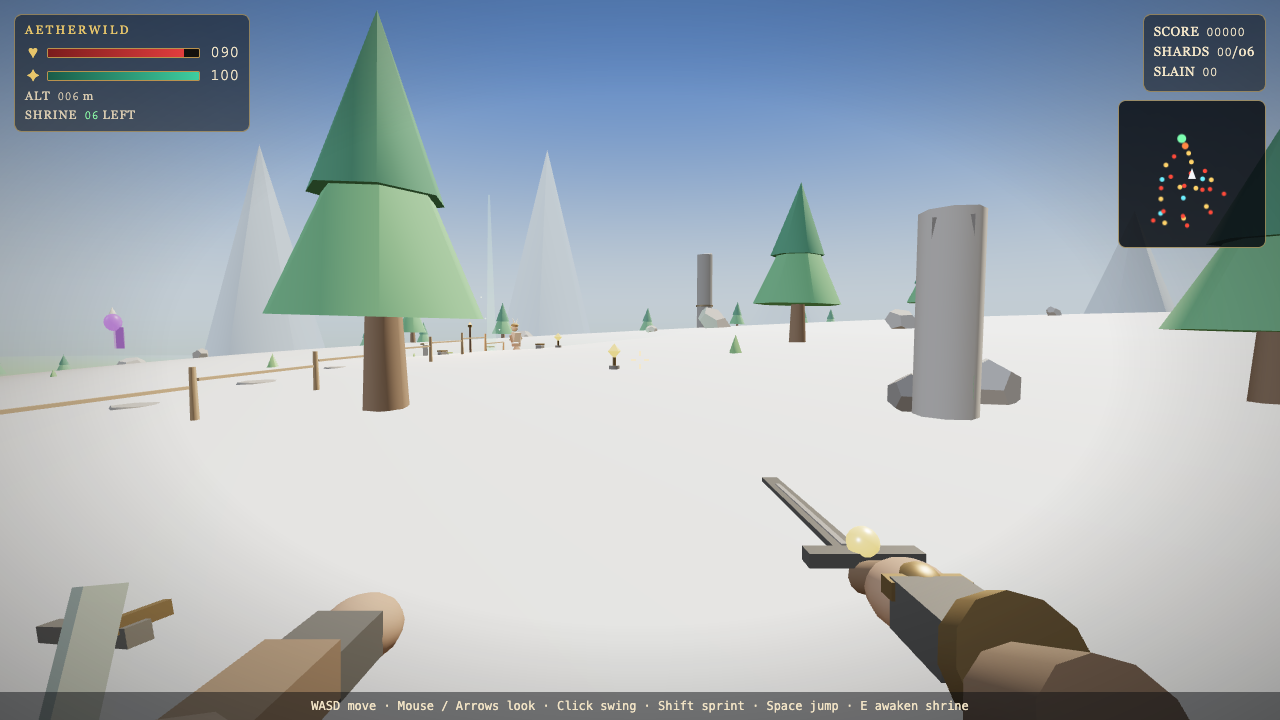
Game
— not attempted —
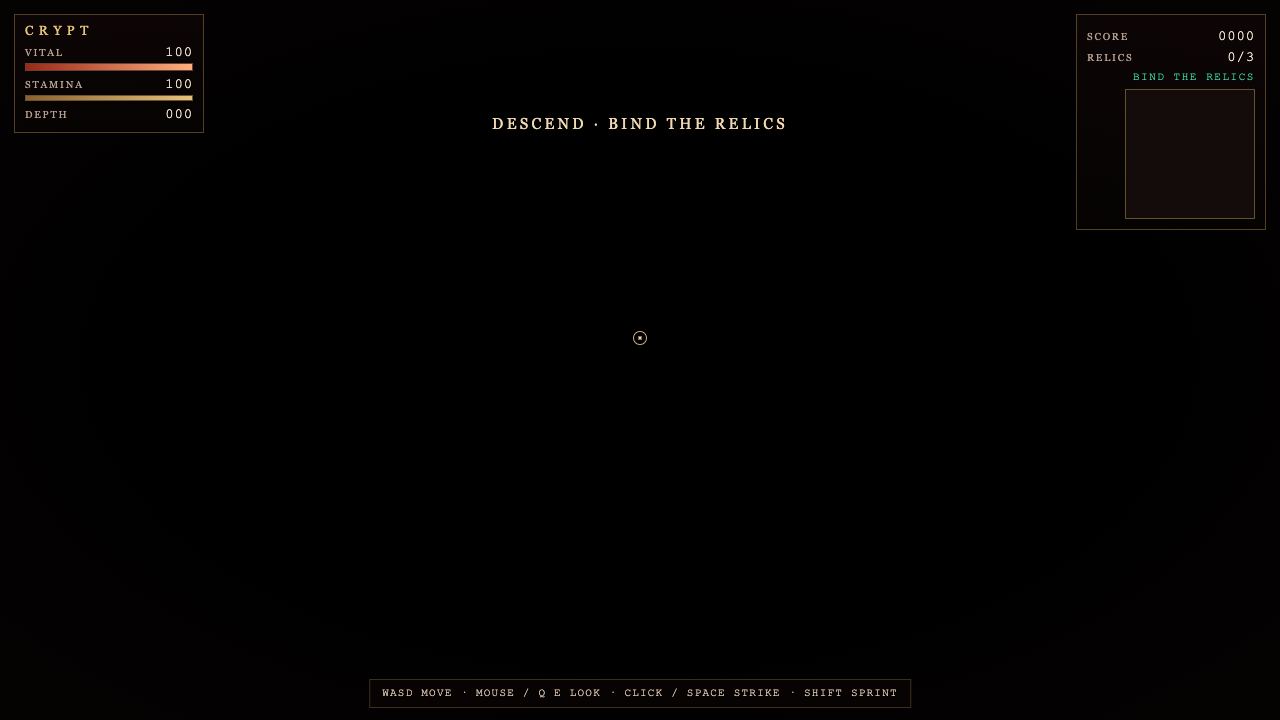
Game
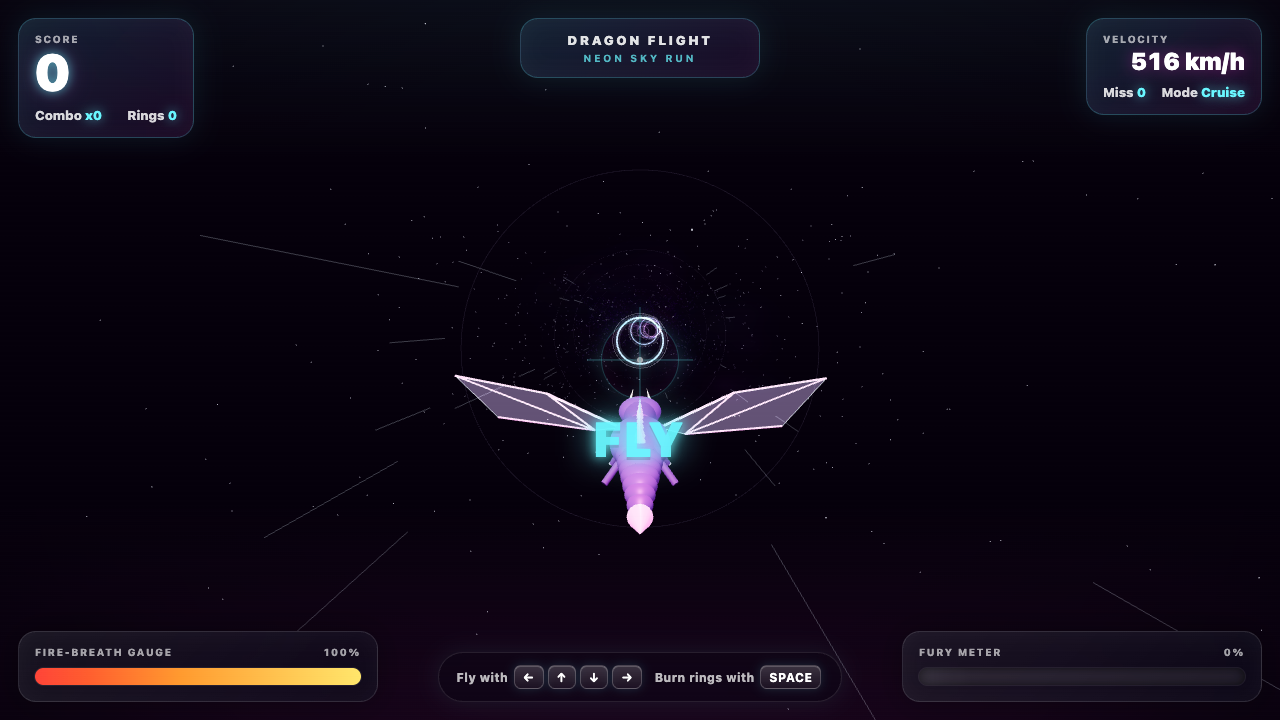
— not attempted —
Game
— not attempted —
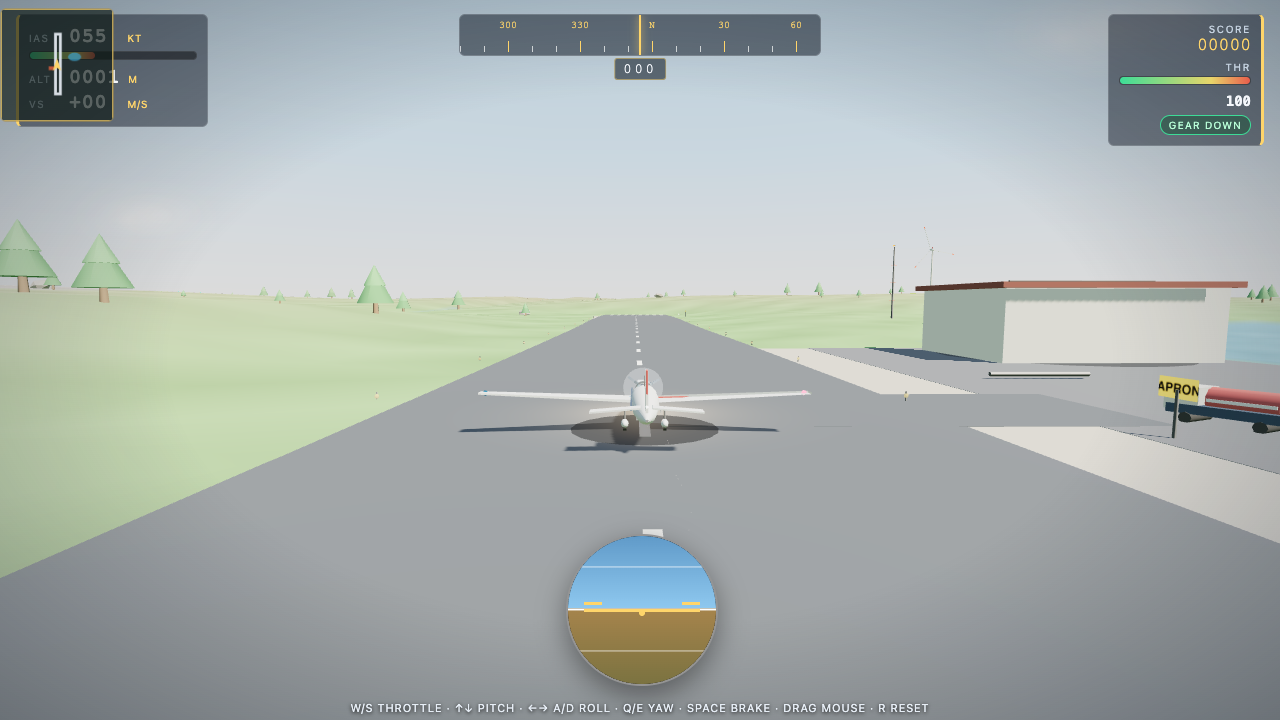
Game
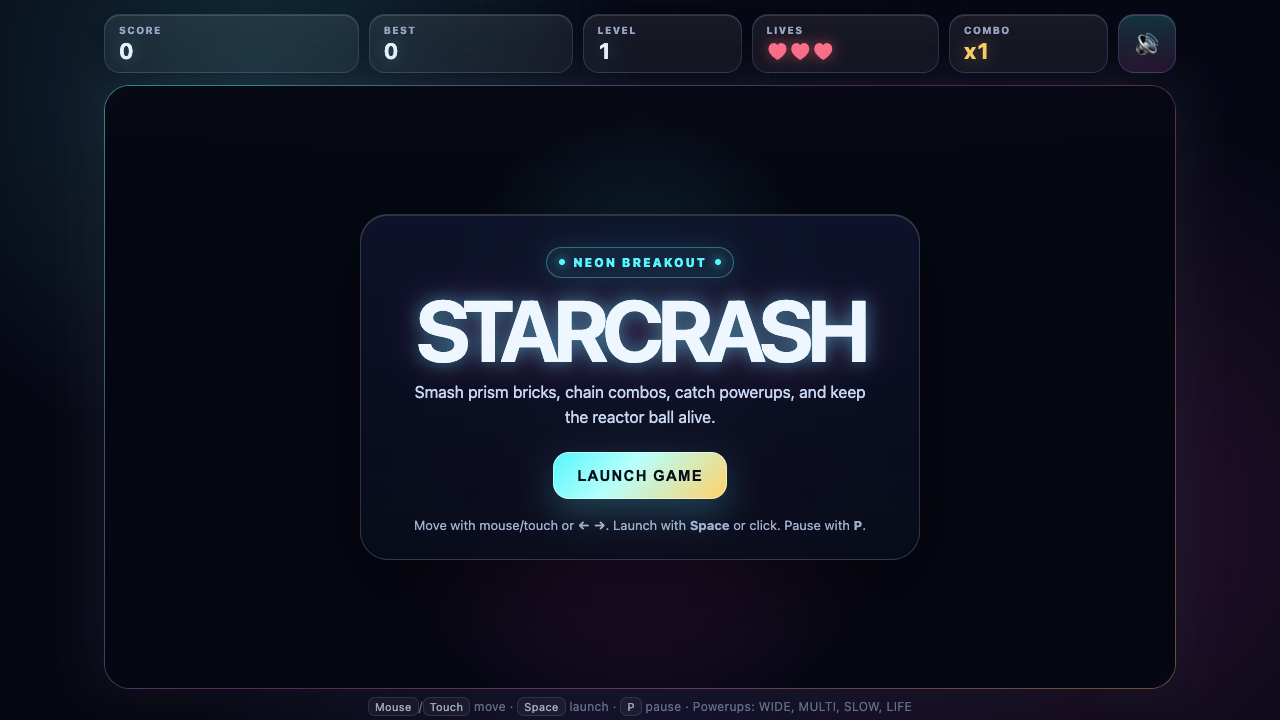
— not attempted —
Game
— not attempted —
Game
— not attempted —
Game
— not attempted —
Game
— not attempted —
Game
— not attempted —
Game
— not attempted —
Page
— not attempted —
Page
— not attempted —
Where Fugu Mini beat Grok 4.7
The tasks where I gave Fugu Mini a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
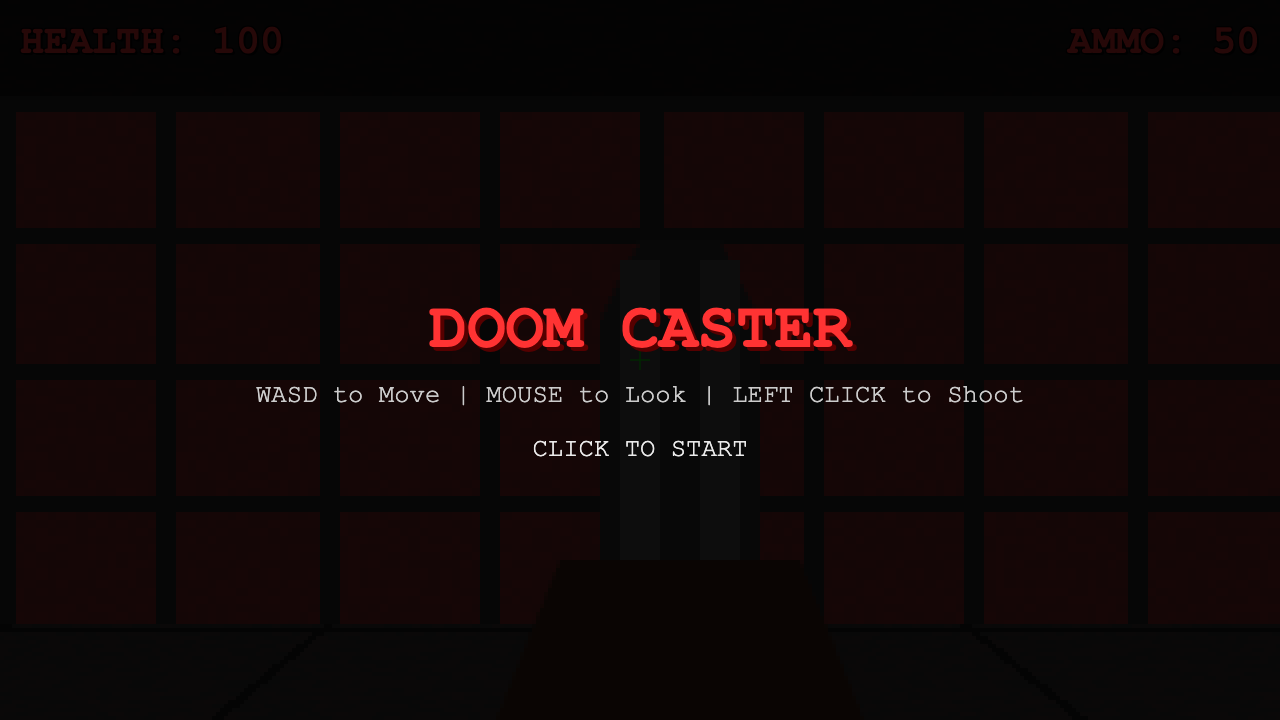
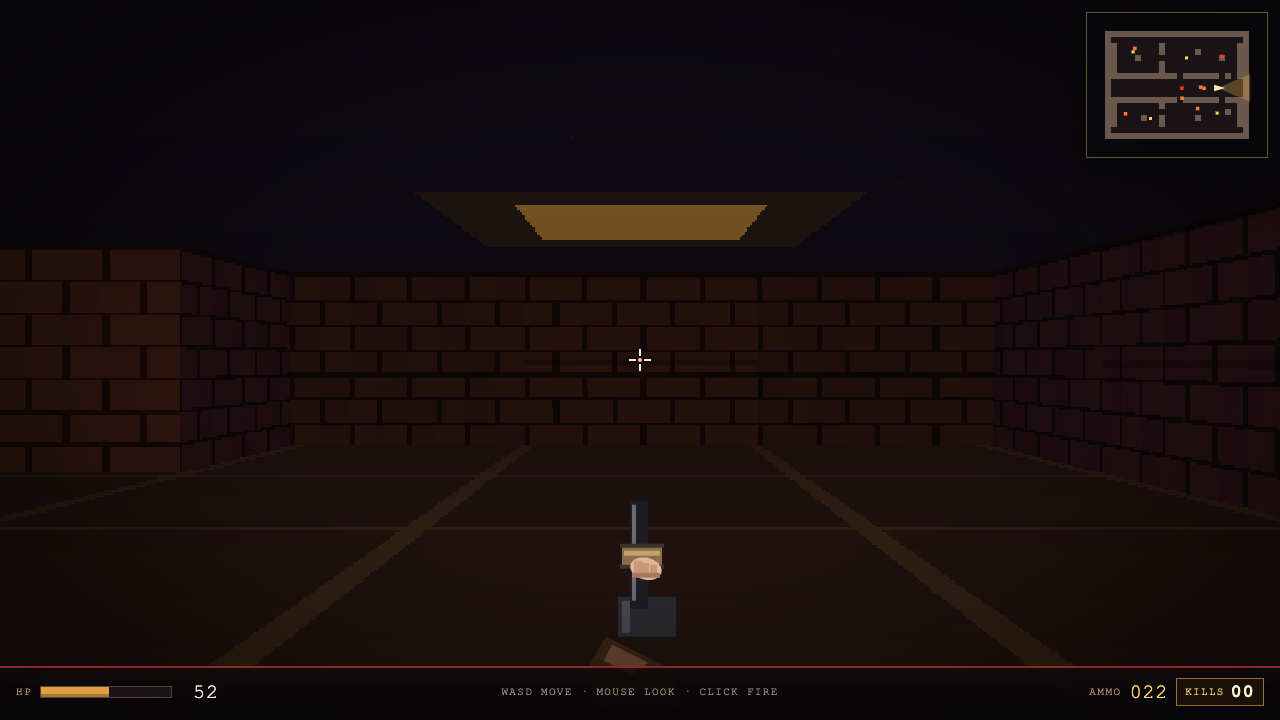
Doom
Game
Fugu Mini 8.0
·
Grok 4.7 6.3
(+1.7)
What I saw: Doom-style raycaster FPS with sprite enemies. Smoke-test PASS (pixel change after click+keys).
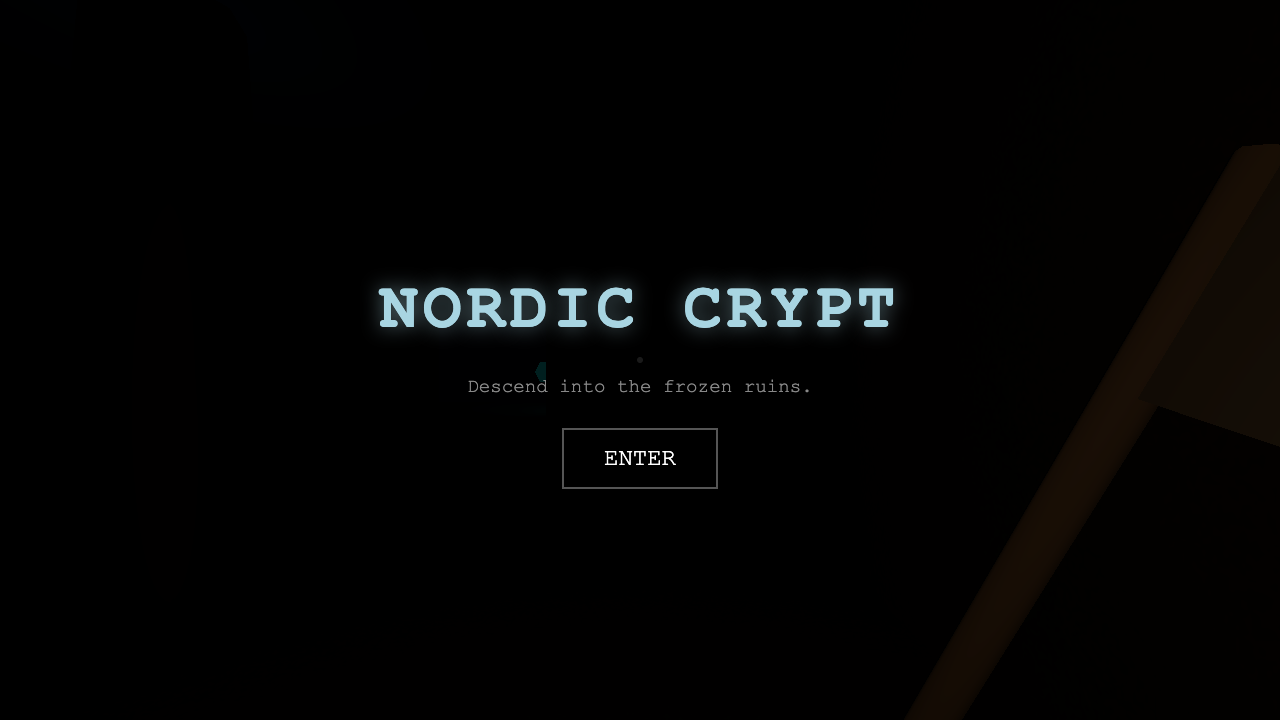
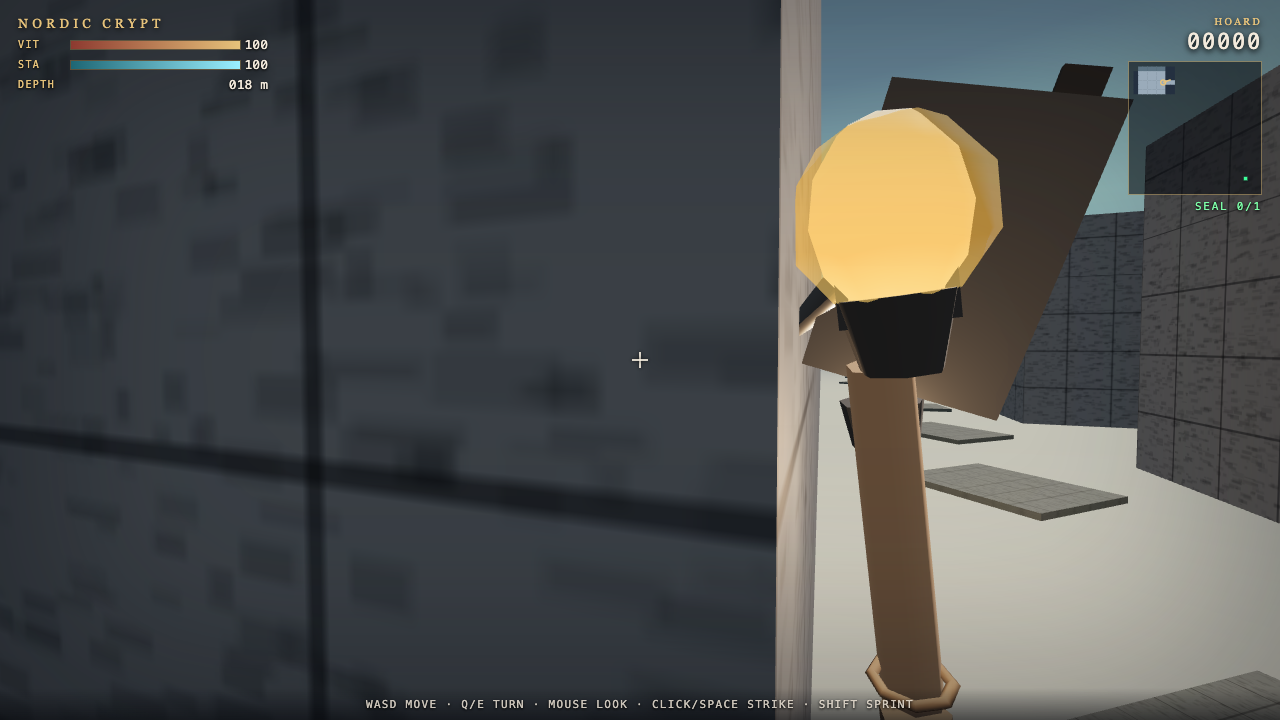
Nordiccrypt
Game
Fugu Mini 7.0
·
Grok 4.7 5.5
(+1.5)
What I saw: Mini gap-fill — 31KB Nordic dungeon. Smoke-test MAYBE (0.5% diff) — pointer-lock FPS; flagged for manual verification.
Raycaster
Game
Fugu Mini 7.0
·
Grok 4.7 6.3
(+0.7)
What I saw: Mini gap-fill — raycaster maze. Smoke-test MAYBE (0.2% diff) — pointer-lock FPS the auto-test can't fully drive; flagged for manual verification.
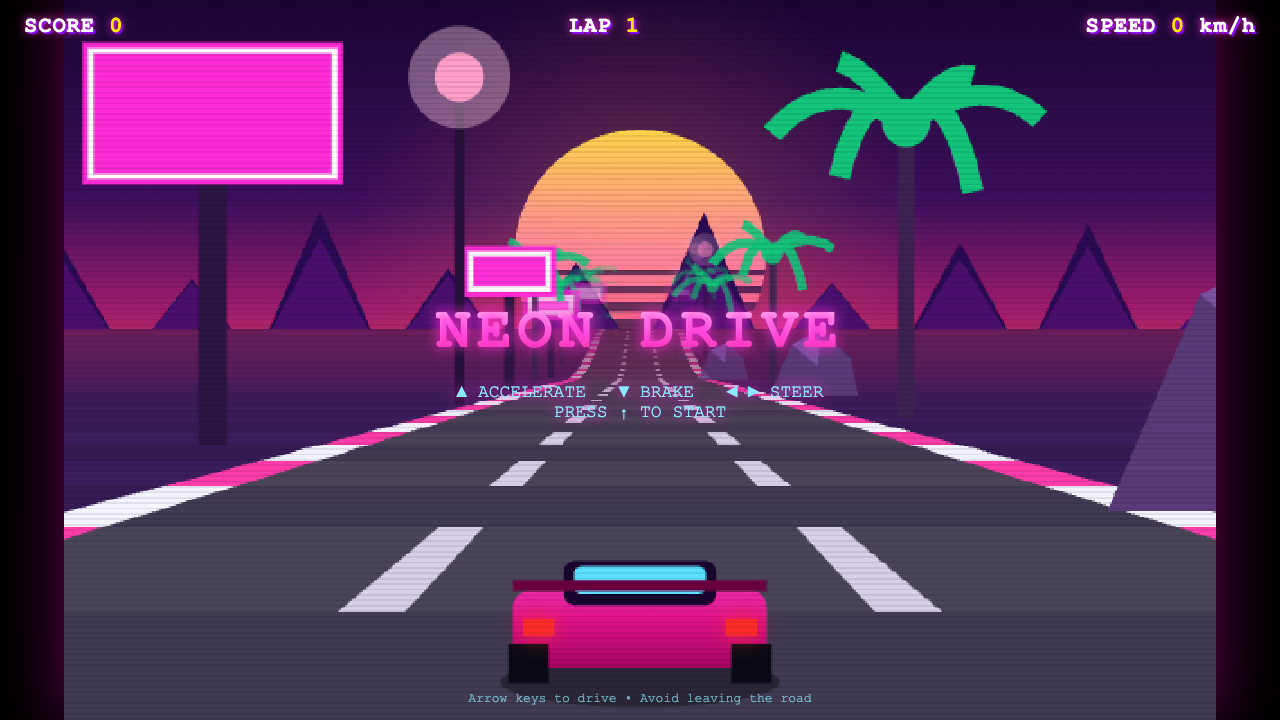
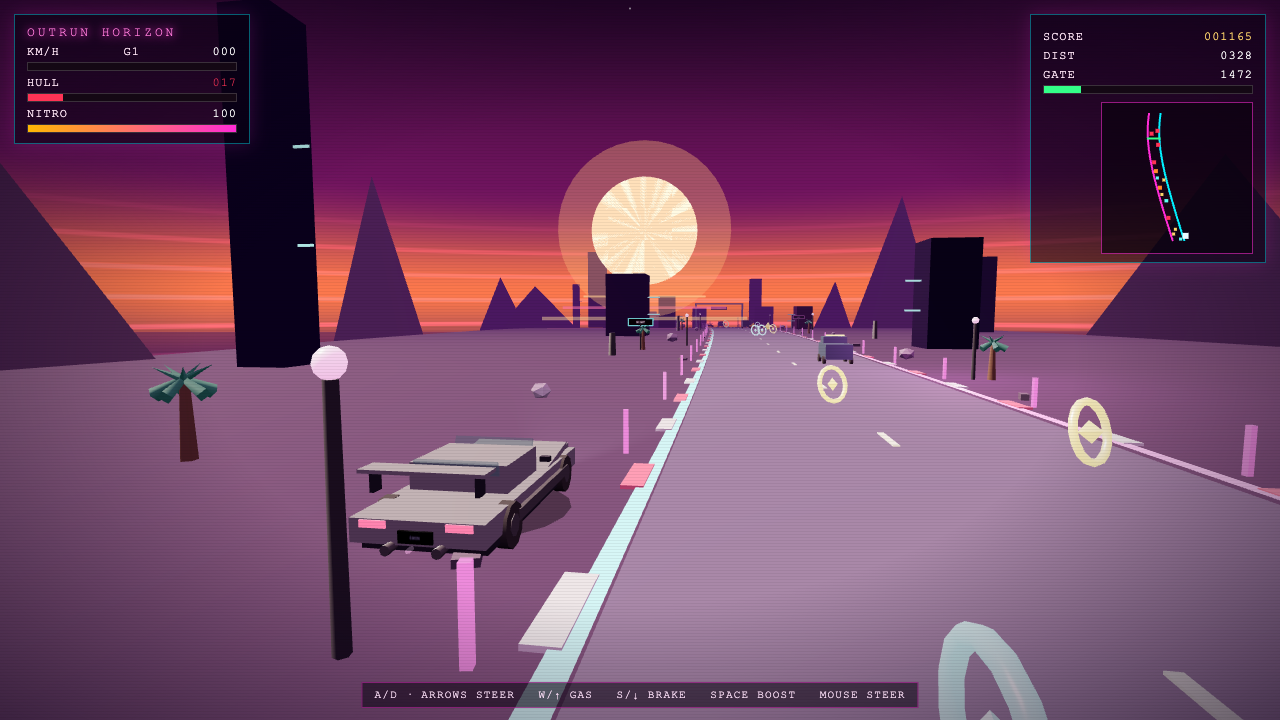
Outrun
Game
Fugu Mini 8.5
·
Grok 4.7 8.4
(+0.1)
What I saw: Pseudo-3D OutRun racer with synthwave horizon. Smoke-test PASS (26% pixel diff after arrow keys).
Where Grok 4.7 beat Fugu Mini
The tasks where I gave Grok 4.7 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Rpg
Game
Grok 4.7 8.2
·
Fugu Mini 6.5
(+1.7)
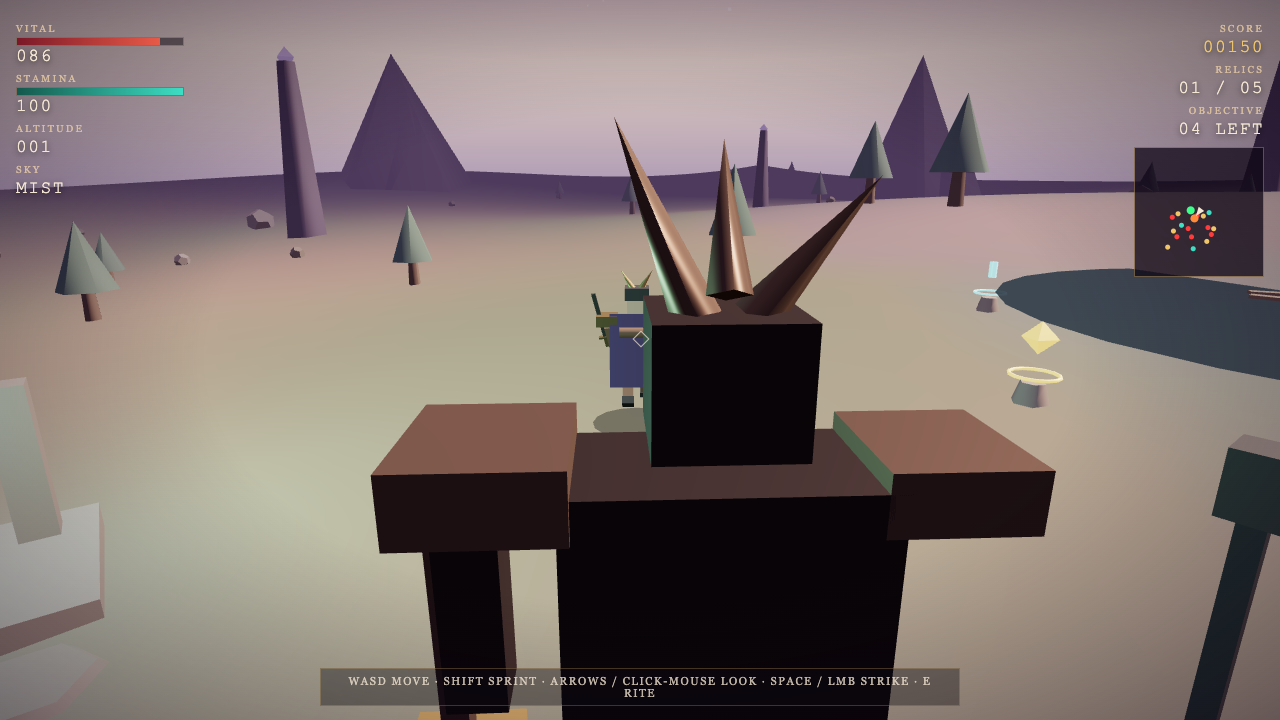
What I saw: Strong, atmospheric top-down RPG with a polished themed HUD (vit/dash/relics/inventory/minimap), 3D low-poly world, enemies and interactive seals — HUD evidence shows gold/score/vit all progressing and combat context living. Loses some points because VIT dropped steadily toward d…
Racing
Game
Grok 4.7 8.7
·
Fugu Mini 8.0
(+0.7)
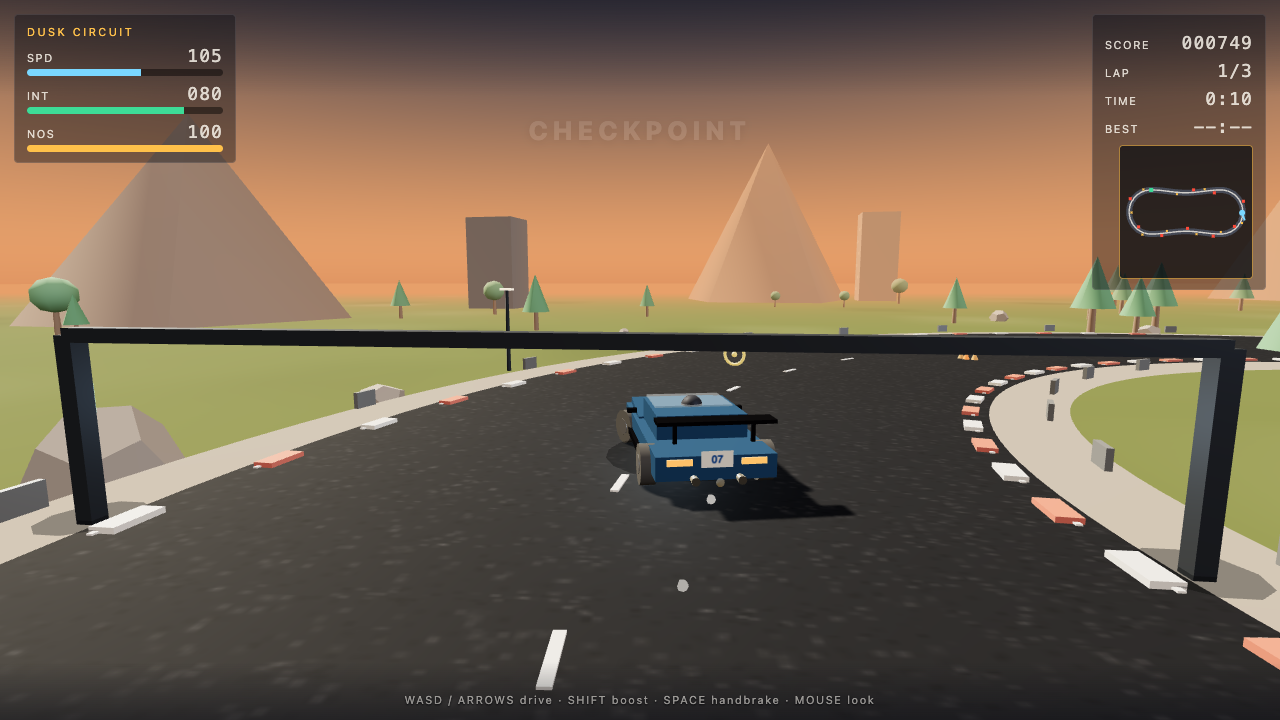
· Polished dusk circuit
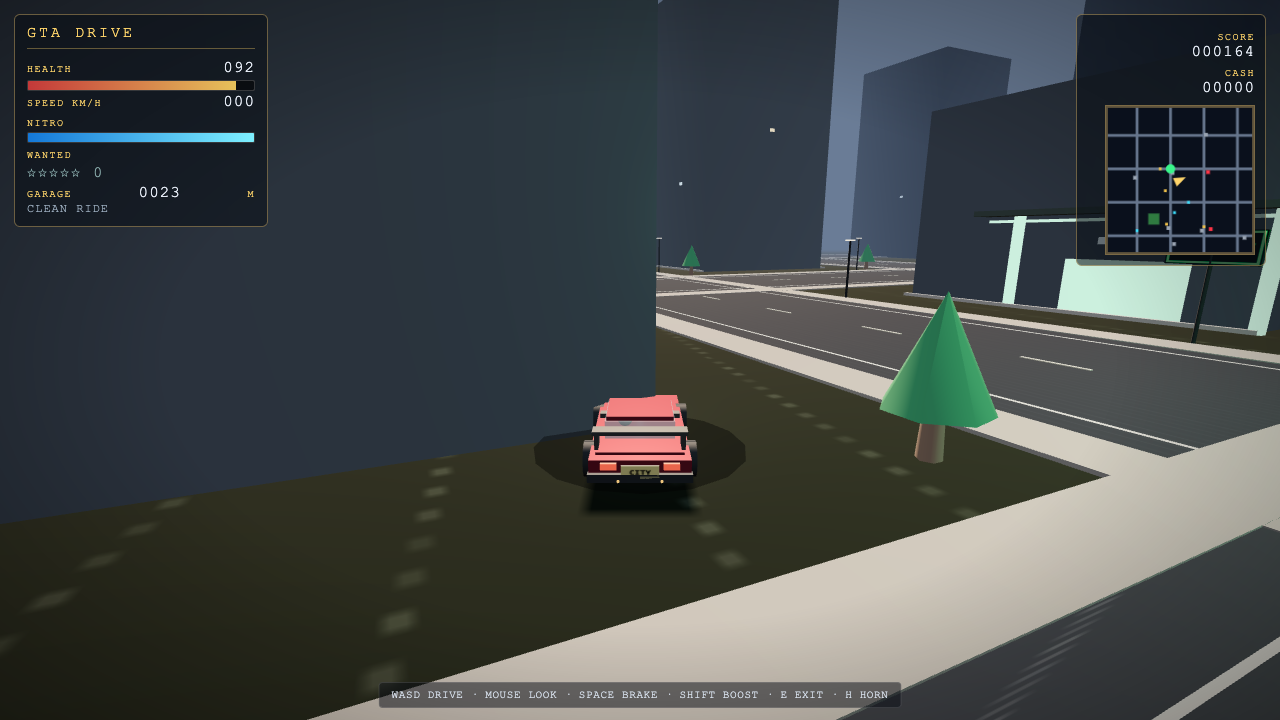
What I saw: Strong: gorgeous dusk-lit third-person racer with a detailed low-poly car, banked track, checkpoint gate, obstacles, working minimap and rich HUD; playtest shows real speed (105), score (000749) and lap progression plus off-track/wreck states. Minor weakness is the car spun off a…
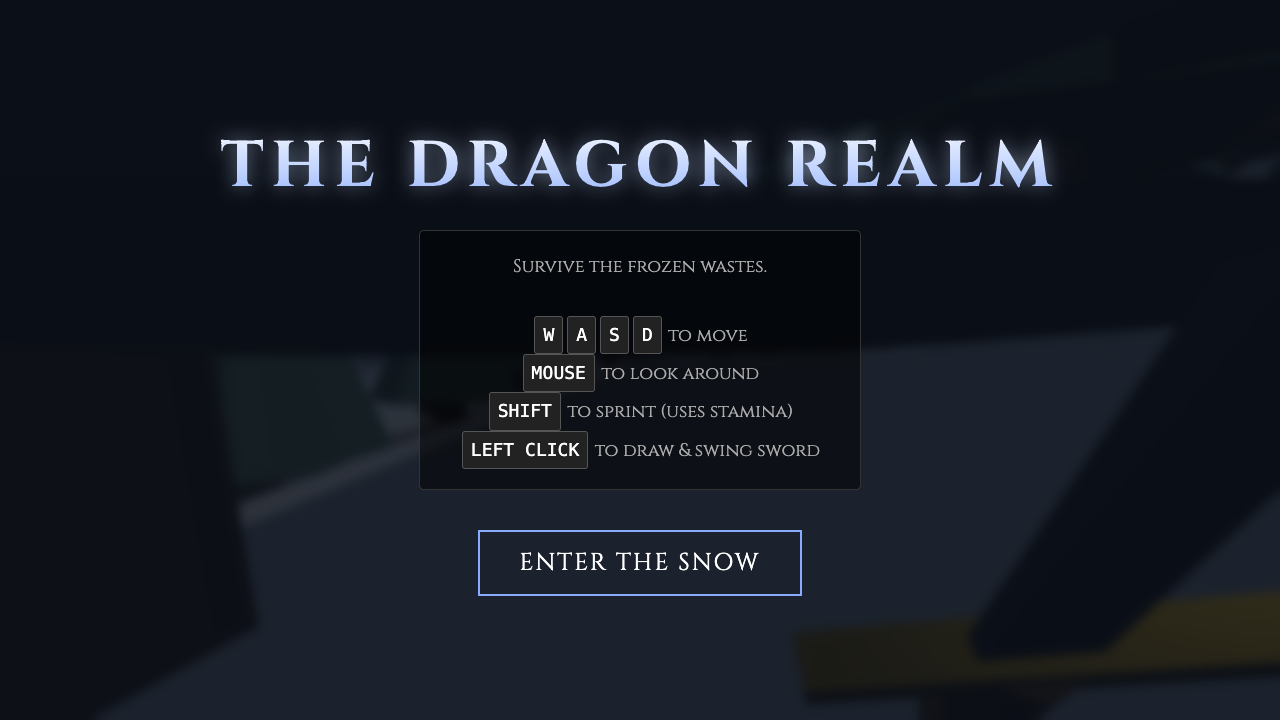
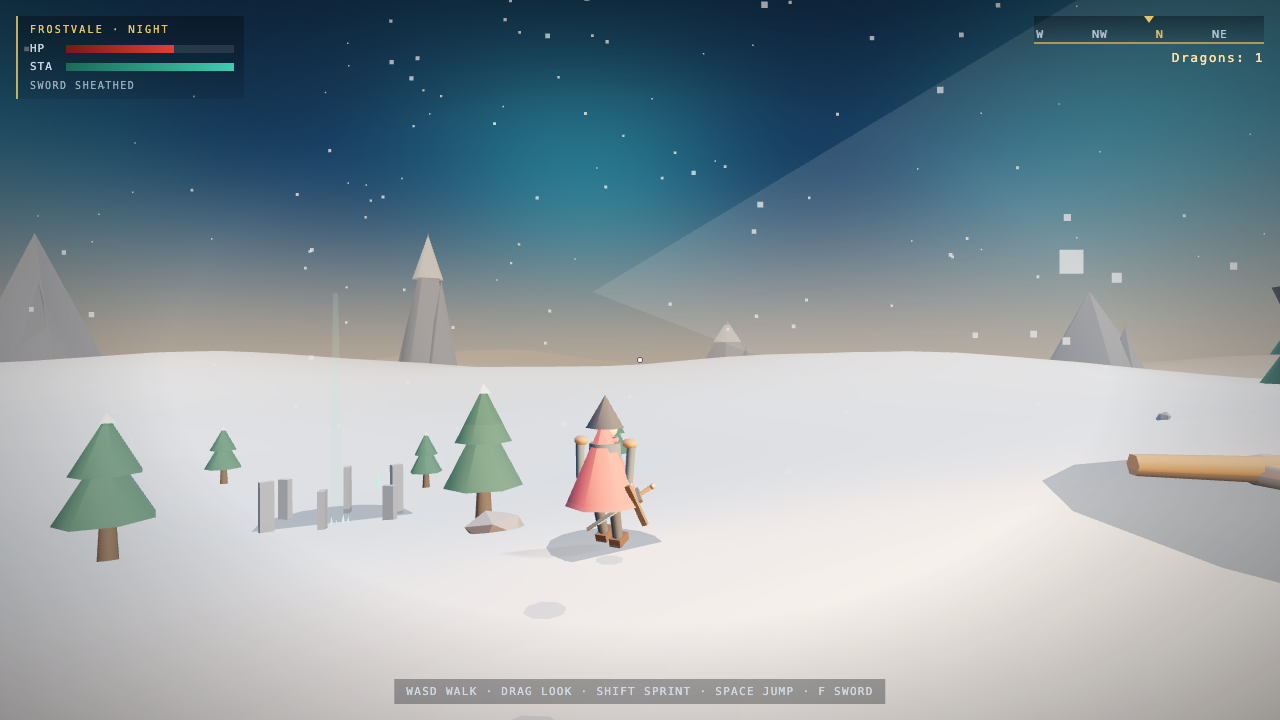
Dragonrealm
Game
Grok 4.7 8.6
·
Fugu Mini 8.0
(+0.6)
· Frozen realm winner
What I saw: Gorgeous polished frozen scene — aurora sky, snowy hills, low-poly pines, standing stones, a caped character with sheathed sword, and a working HUD with compass/dragon counter; playtest shows real movement (walkPx 0.58), dragon-dive events, and a STRUCK combat state, hitting the …
Neonracer
Game
Grok 4.7 8.4
·
Fugu Mini 8.0
(+0.4)
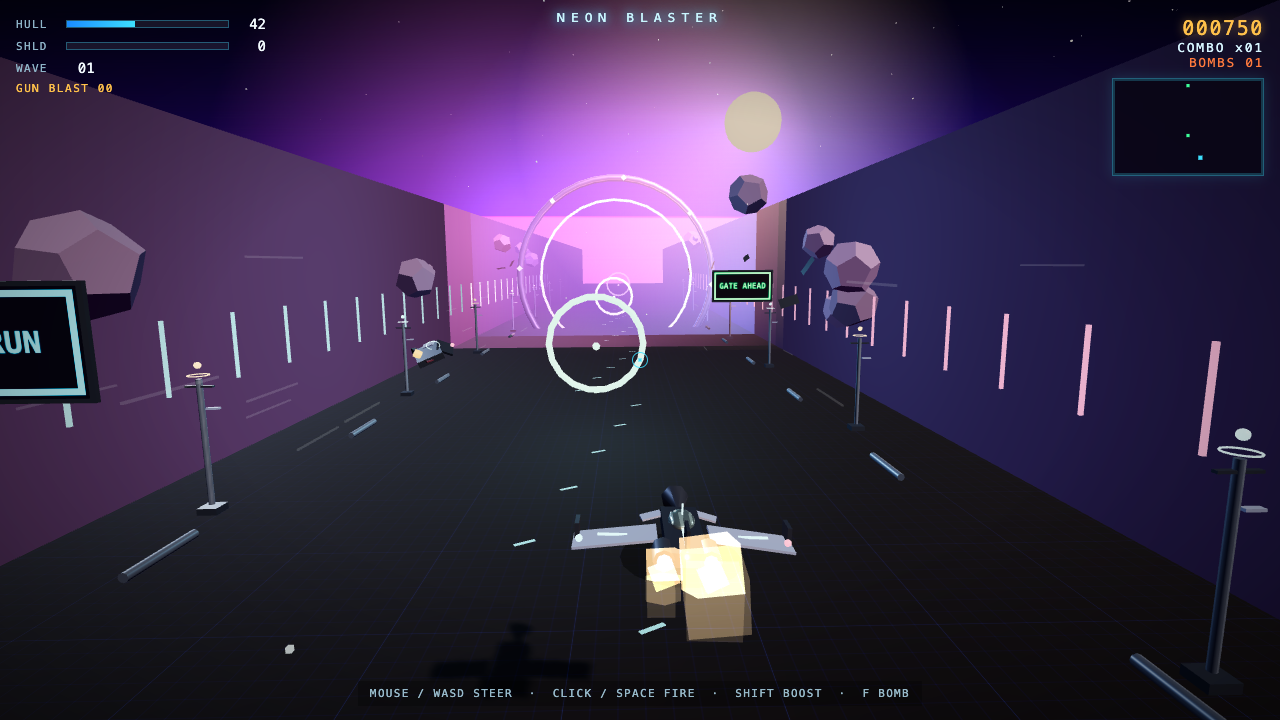
What I saw: Renders a polished 3D neon racer with a clean city skyline, glowing arch, detailed HUD/minimap, and confirmed dynamic play (speed, score climbing, health dropping on IMPACT); strong and shippable but the vapor-trail particle effects are underwhelming/barely visible in the frame, …
Skyrim
Game
Grok 4.7 8.4
·
Fugu Mini 8.0
(+0.4)
· snowy shrine explorer
What I saw: Renders a polished, atmospheric first-person Skyrim-lite with soft-shadowed low-poly pines, standing stones, held sword+shield, a working minimap, and a rich RPG HUD (health/stamina/shards/shrines/altitude). Playtest confirms real movement, altitude climbing, and HP dropping from…
Strengths & weaknesses I logged
Fugu Mini
Strengths
- Zero panel orchestration — much lower latency than Ultra
- Same Sakana subscription, no extra cost
- Doesn't time out on heavy game/3D prompts where Ultra stalls
Trade-offs
- Single model only — no ensemble verdict
- Newer than Ultra — less calibration / verification
Grok 4.7
Strengths
- Averaged 7.15/10 on the same twenty skill-infused game briefs where Grok 4.6 averaged 5.95, winning 14 of the 20 head-to-heads
- Best one-shots on this run: neoncity (8.7), racing (8.7), arcade (8.6), every one played on a real GPU before scoring
- Longer reinforcement learning shows: it holds a 40-50KB single-file spec and wires the controls it advertises
- xAI's own coding numbers moved: CursorBench 4.0 46.3% (from 40.4%) and DeepSWE v1.1 71.0% (from 65.2%)
Trade-offs
- 2 of 20 builds died on load or never moved when played — crypt: hud is not a function; voxelcraft: mesh.computeBoundingSphere is not a function file:///Users/j
- Independent Artificial Analysis Intelligence Index v4.3.2 puts it at 46, seven points behind Claude Fable 5.1 and GPT-6 at 53
- Terminal-Bench 4.0 is the weak spot xAI reports itself: 38.0% at launch
Pricing & context — the spec sheet
| Spec | Fugu Mini | Grok 4.7 |
|---|---|---|
| Vendor | Sakana AI | xAI |
| Context window | Single-model variant of Sakana's Fugu — no panel orchestration. Same API endpoint, much faster per call. | 500,000 tokens |
| Price | Same Sakana subscription pool as Fugu Ultra | $2 in / $6 out per M tokens |
| Pricing detail | The non-Ultra `fugu` model on Sakana's API. Sakana describes it as 'Fast mini model optimized for low latency yet high quality responses.' Crucially: zero orchestration tokens per call (vs Ultra's panel of thousands). Returns in ~3 min instead of 6-15 min and doesn't time out on heavy prompts. | xAI's September 2026 release, priced exactly like Grok 4.6: $2 per million input tokens and $6 per million output on the standard tier, $4 / $12 on the Fast tier (double the output speed). OpenRouter lists the same model at $1.60 / $4.80. |
| Release | 2026-06-15 | 2026-09 |
| Bench coverage | 36/37 scored · avg 7.75/10 | 20/20 scored · avg 7.15/10 |
The verdict — which should you pick?
Across 12 scored shared tasks, the averages are essentially tied — Fugu Mini 7.67 vs Grok 4.7 7.70. This isn't the comparison where one wins; it's the comparison where you pick based on context, pricing, and what you're actually trying to ship.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire Fugu Mini and Grok 4.7 both into the Agent Operating System and dispatch each from the kanban by task type — agent loops where latency matters more than panel consensus → Fugu Mini, one-shot arcade, driving and shooter builds where the whole game has to arrive in a single file → Grok 4.7. That's the same setup I run for the 3,400+ founders inside the AI Profit Boardroom.
FAQ — Fugu Mini vs Grok 4.7
Which is better, Fugu Mini or Grok 4.7?
On Goldie Bench, Fugu Mini averages 7.67/10 across the shared tasks, with 2 gold, 0 silver, 0 bronze overall. Grok 4.7 averages 7.70/10, with 0 gold, 2 silver, 3 bronze. Grok 4.7 wins the head-to-head 8–4.
How much does Fugu Mini cost vs Grok 4.7?
Fugu Mini: The non-Ultra `fugu` model on Sakana's API. Sakana describes it as 'Fast mini model optimized for low latency yet high quality responses.' Crucially: zero orchestration tokens per call (vs Ultra's panel of thousands). Returns in ~3 min instead of 6-15 min and doesn't time out on heavy prompts. Grok 4.7: xAI's September 2026 release, priced exactly like Grok 4.6: $2 per million input tokens and $6 per million output on the standard tier, $4 / $12 on the Fast tier (double the output speed). OpenRouter lists the same model at $1.60 / $4.80.
What's the context window for Fugu Mini vs Grok 4.7?
Fugu Mini has a Single-model variant of Sakana's Fugu — no panel orchestration. Same API endpoint, much faster per call. context window. Grok 4.7 has a 500,000 tokens context window.
When should I pick Fugu Mini over Grok 4.7?
Pick Fugu Mini for: Agent loops where latency matters more than panel consensus; Quick first-drafts you'll refine downstream; Filling out a bench when Ultra is timing out. The trade-off is the weaknesses we logged on the bench: Single model only — no ensemble verdict; Newer than Ultra — less calibration / verification.
When should I pick Grok 4.7 over Fugu Mini?
Pick Grok 4.7 for: One-shot arcade, driving and shooter builds where the whole game has to arrive in a single file; High-volume agent work priced at half what the other frontier models charge; Grok Build inside the Agent OS: pick 4.7 in the tab and everything it writes lands in the workspace. The trade-off is the weaknesses we logged on the bench: 2 of 20 builds died on load or never moved when played — crypt: hud is not a function; voxelcraft: mesh.computeBoundingSphere is not a function file:///Users/j; Independent Artificial Analysis Intelligence Index v4.3.2 puts it at 46, seven points behind Claude Fable 5.1 and GPT-6 at 53; Terminal-Bench 4.0 is the weak spot xAI reports itself: 38.0% at launch.
How does Goldie Bench score Fugu Mini vs Grok 4.7?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
Fugu Mini vs Fusion Grok 4.7 vs Fusion Fugu Mini vs Claude Opus 5 Grok 4.7 vs Claude Opus 5 Fugu Mini vs Hermes MoA Grok 4.7 vs Hermes MoA Fugu Mini vs GPT-5.6 Sol Grok 4.7 vs GPT-5.6 SolFull model pages: Fugu Mini · Grok 4.7 · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 3,400+ founders shipping with it every day all live inside the AI Profit Boardroom.
3,400+founders
258documented wins
38countries
$69/momonthly