Real head-to-head · same prompt, one shot
Fusion vs Grok 4.7
Multi-model panel — Fable 5 + GPT-5.5, ensembled. Beats Fable 5 at half the price. vs Grok 4.6's price, a bigger base model, and it builds games that hold together.
Head-to-head verdict: Fusion wins 17–3.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to Fusion and Grok 4.7, side by side, on 20 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
Fusion · Dispatched from Agent OS for research-heavy prompts where ensemble accuracy outweighs single-model speed.
Grok 4.7 · Wired into the Agent OS Grok Build tab (4.7 / 4.6 / 4.5 picker, OpenRouter fallback when the CLI is signed out) and benched on twenty skill-infused game builds, each played through its full gameplay arc on a Metal GPU before the vision judge scored the played frame.
Side-by-side on 47 shared tasks
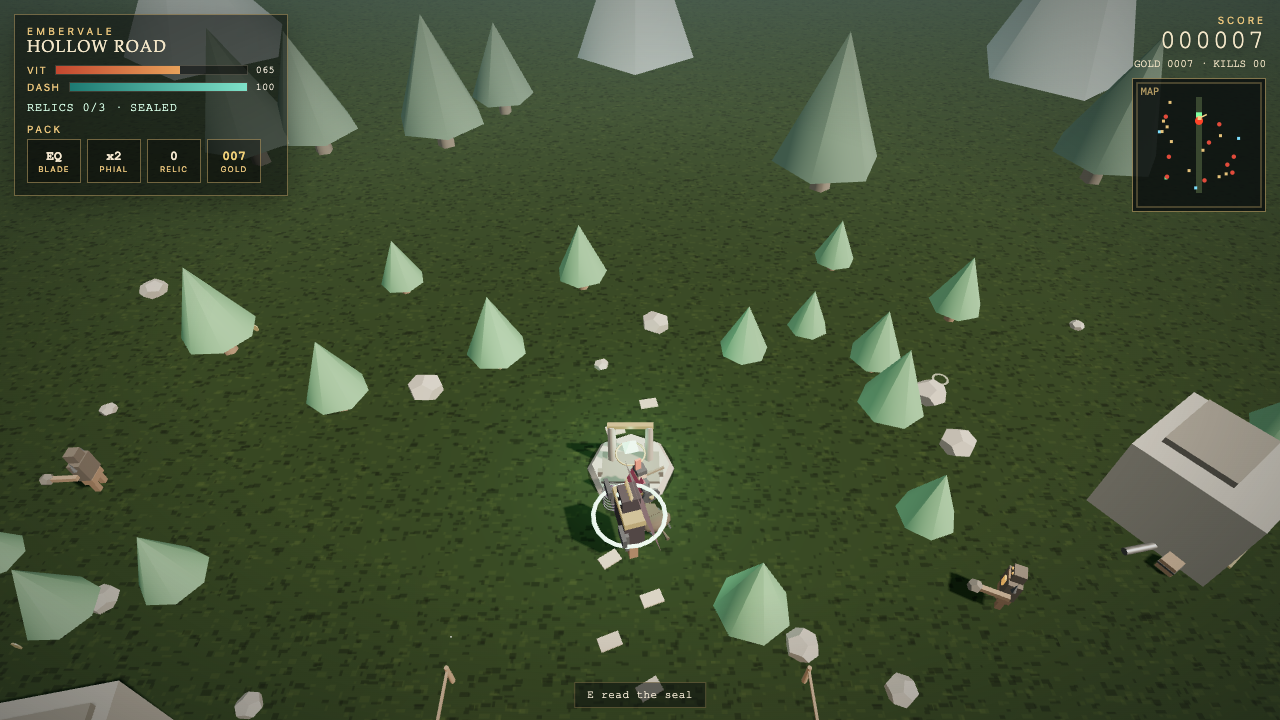
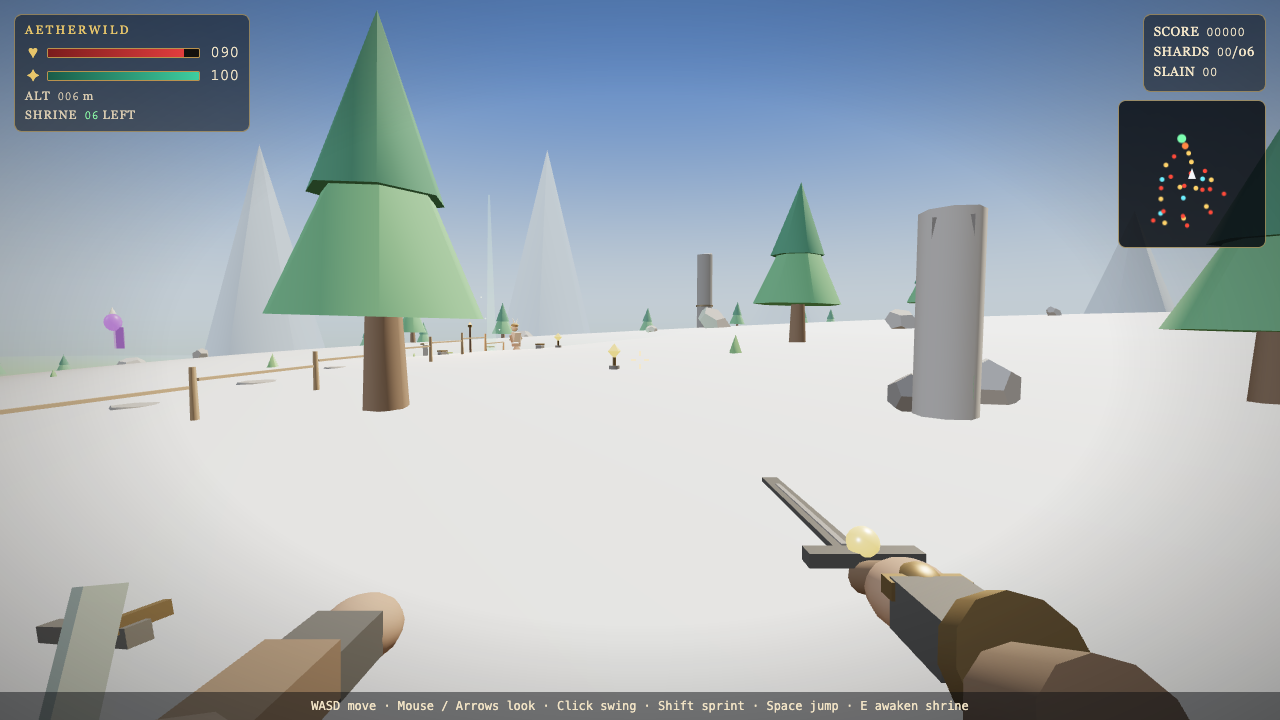
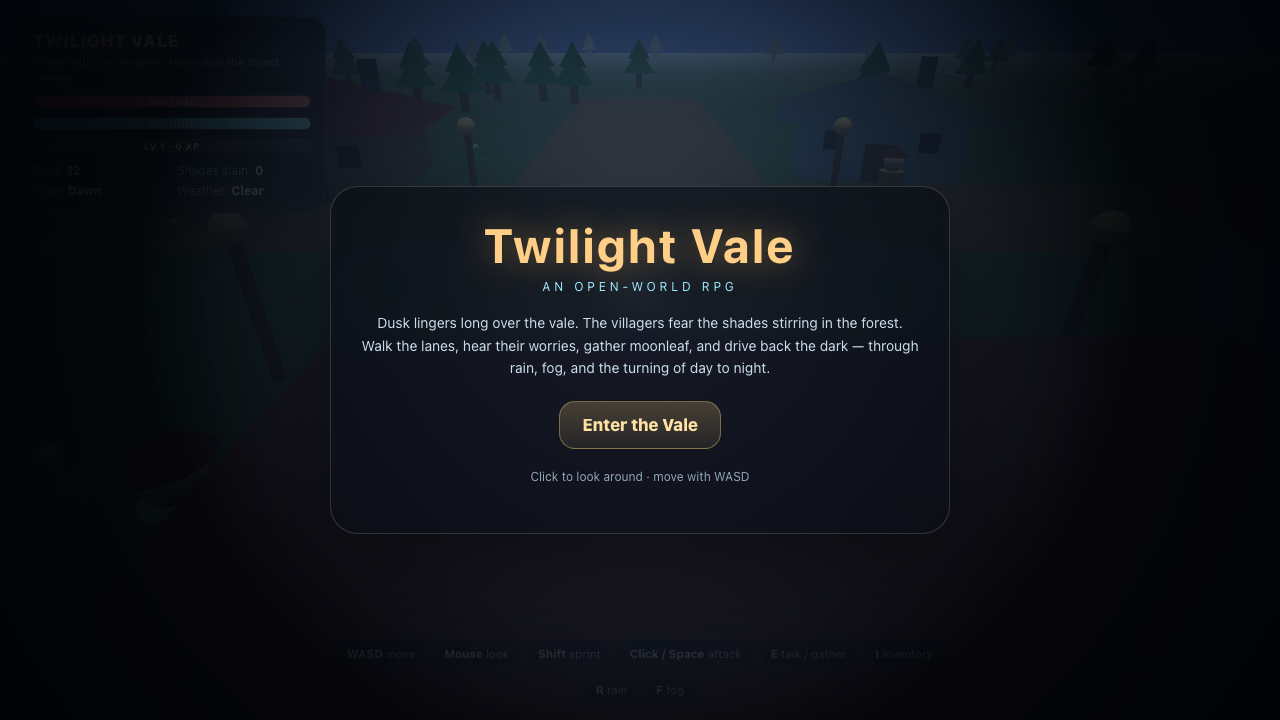
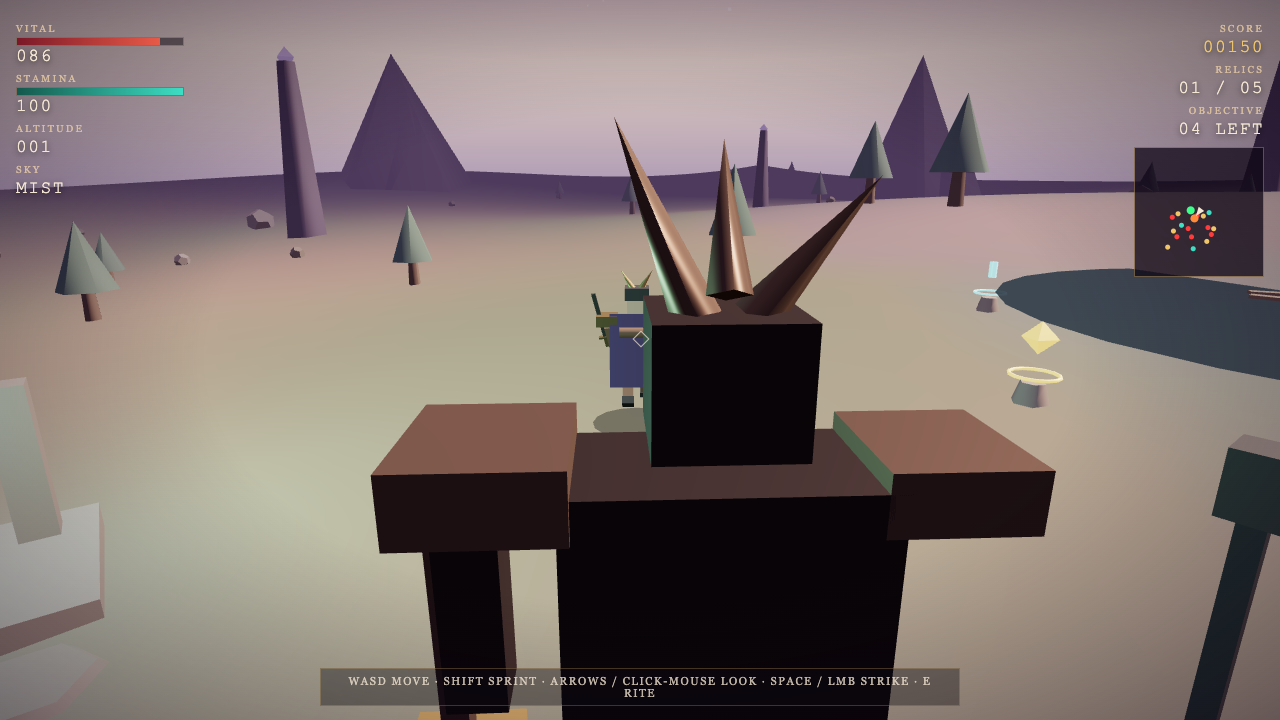
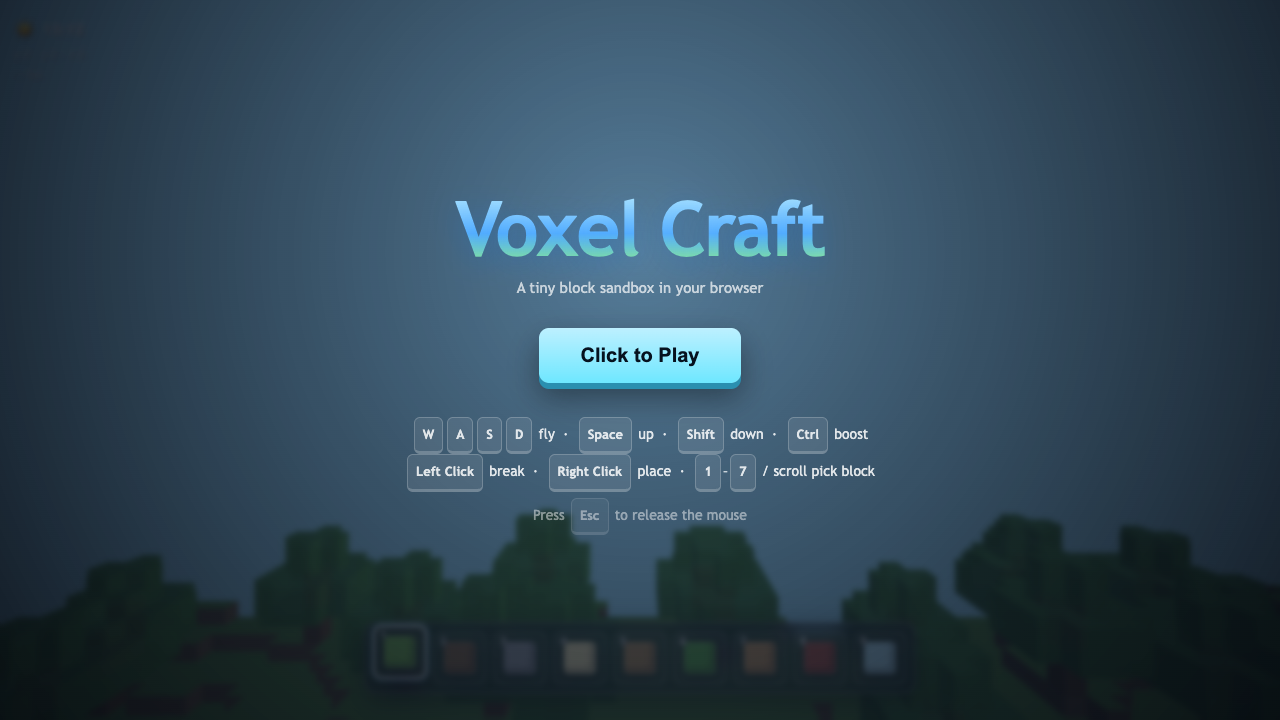
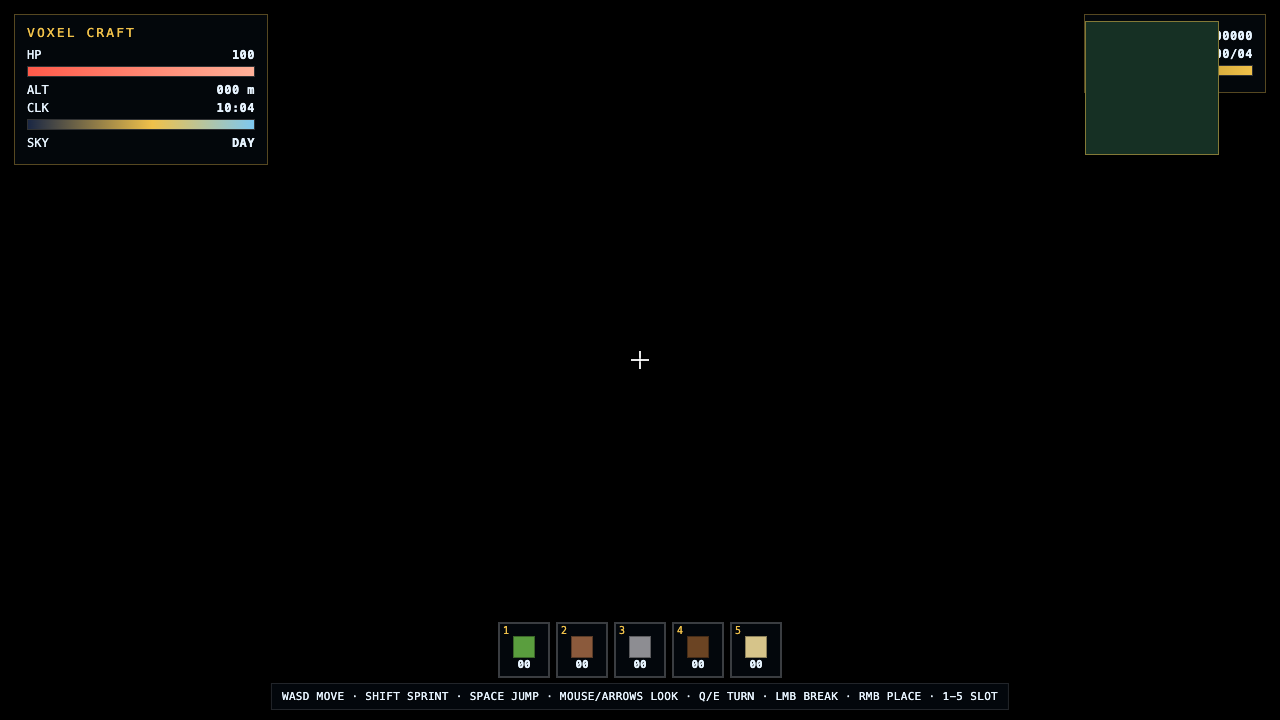
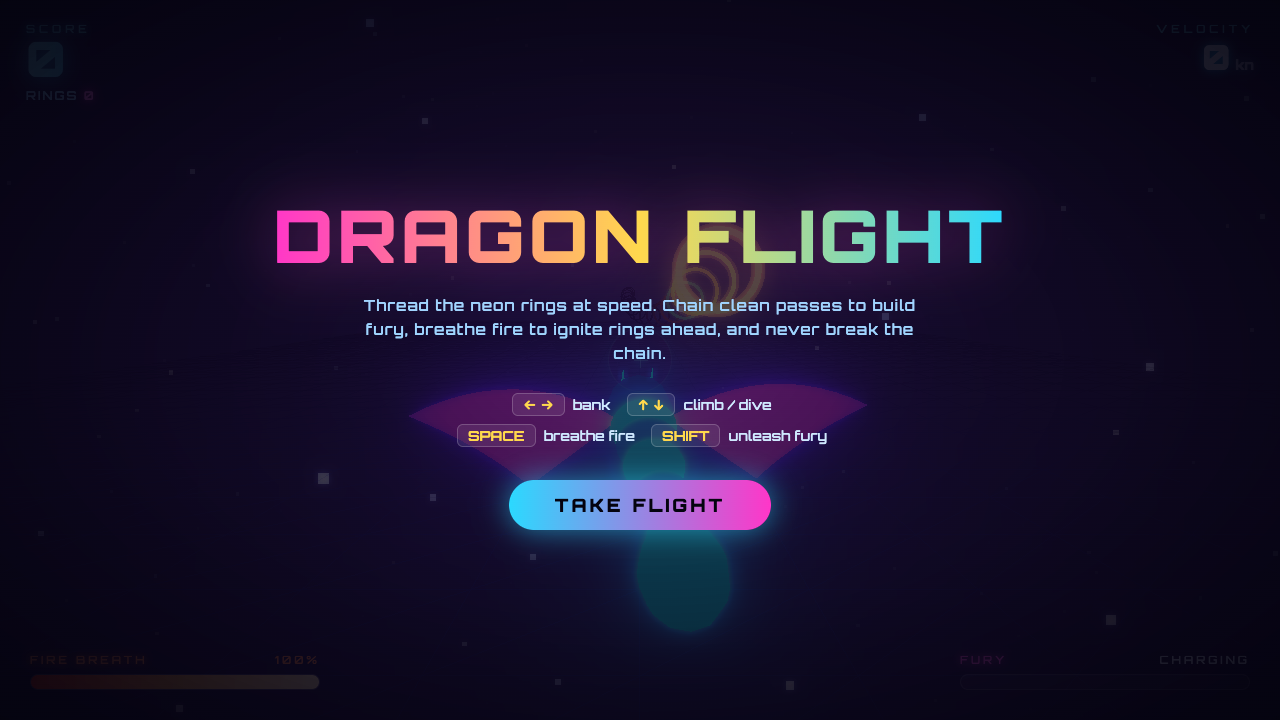
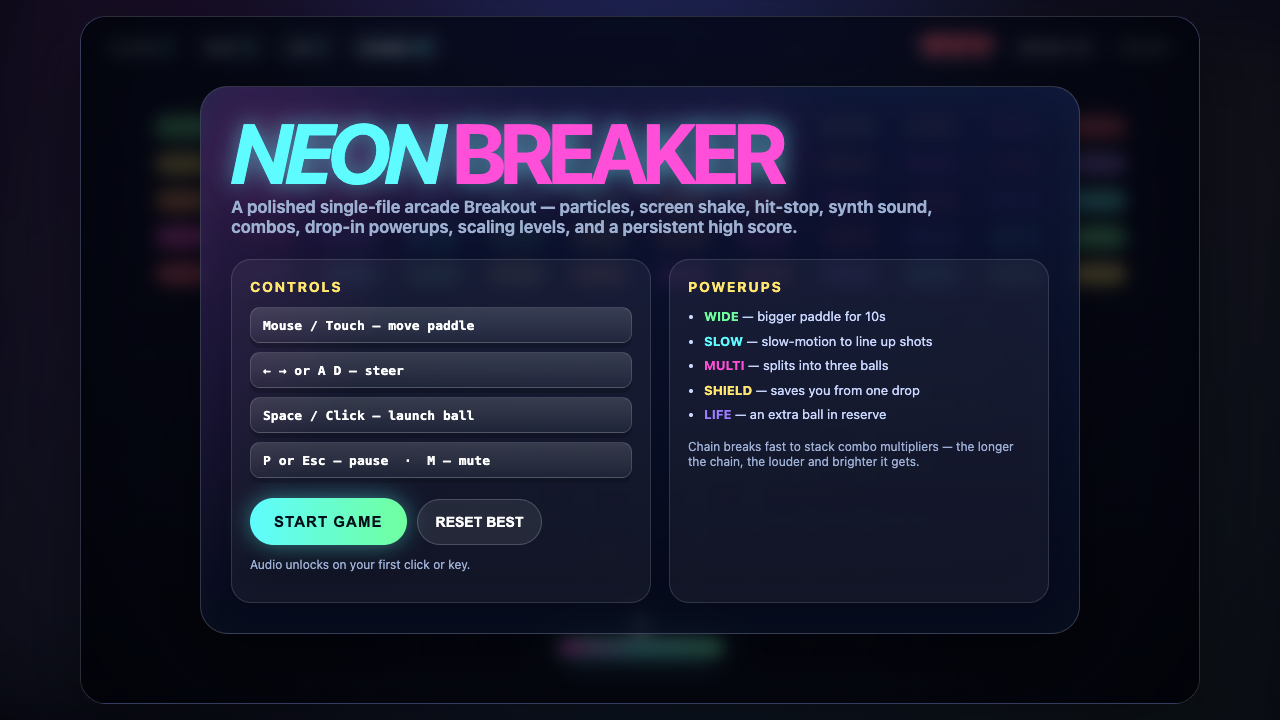
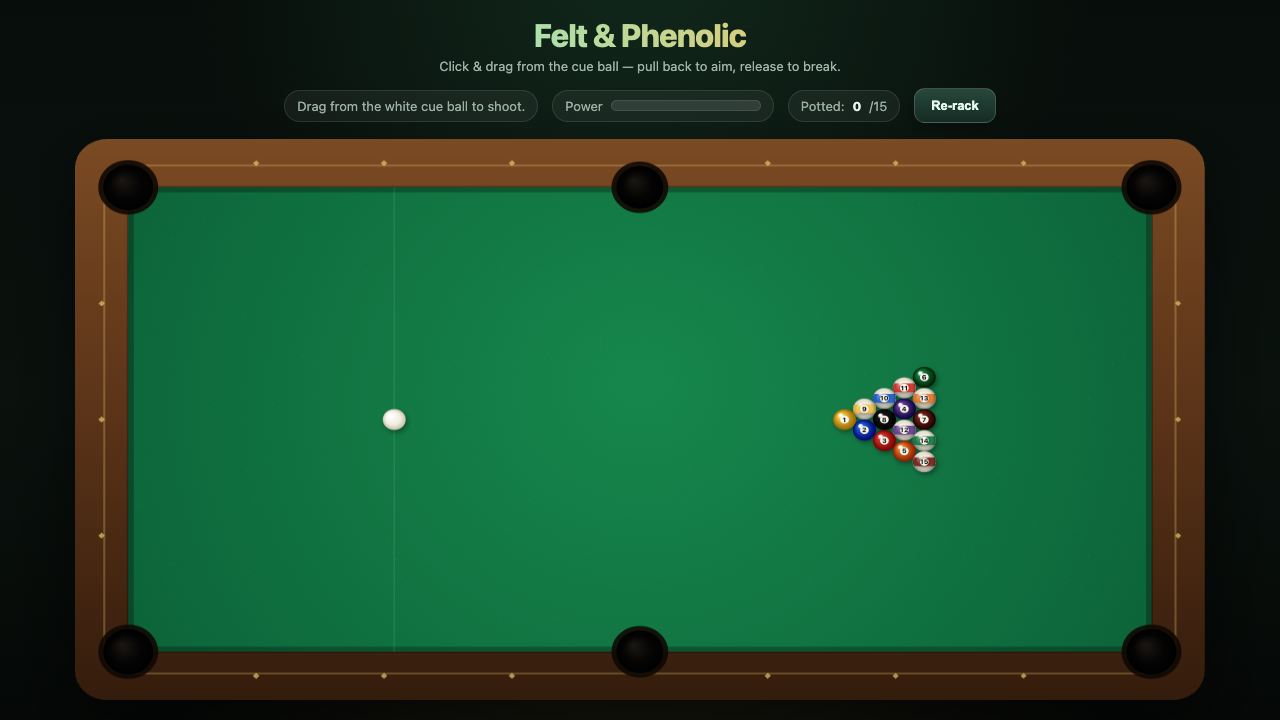
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
Fusion
Grok 4.7
Game
Game
Game
Game
Game
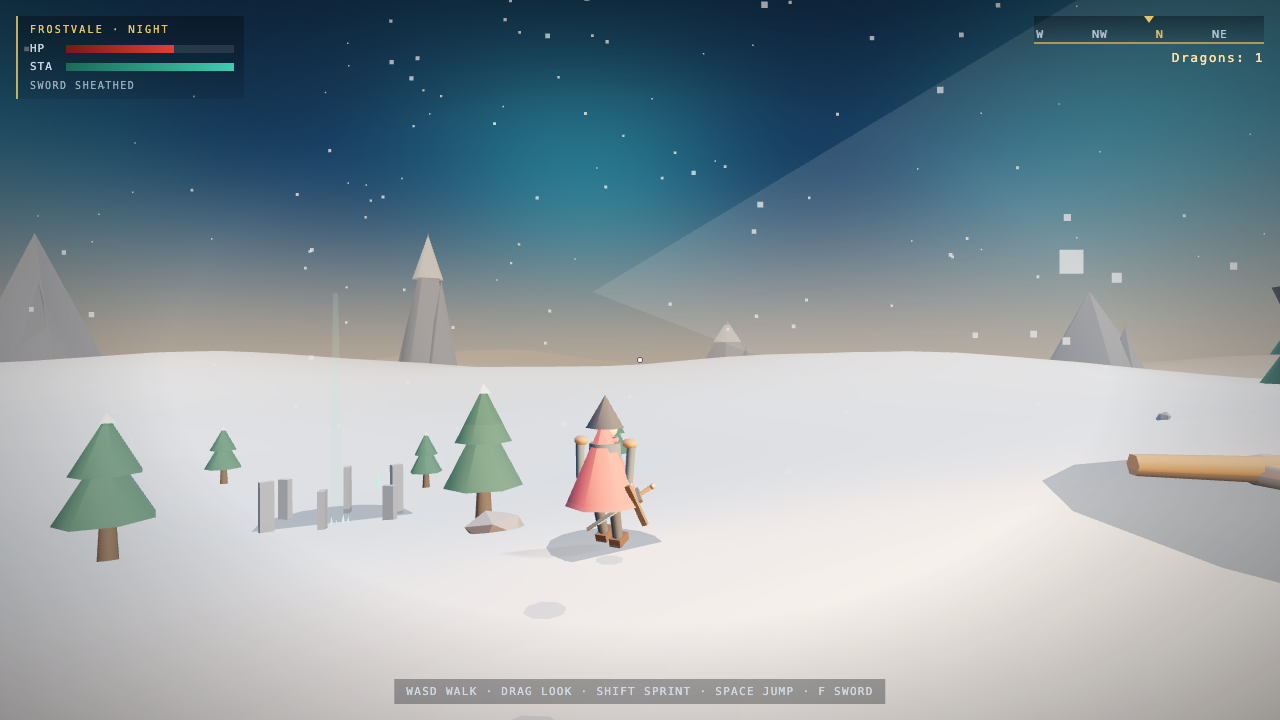
Game
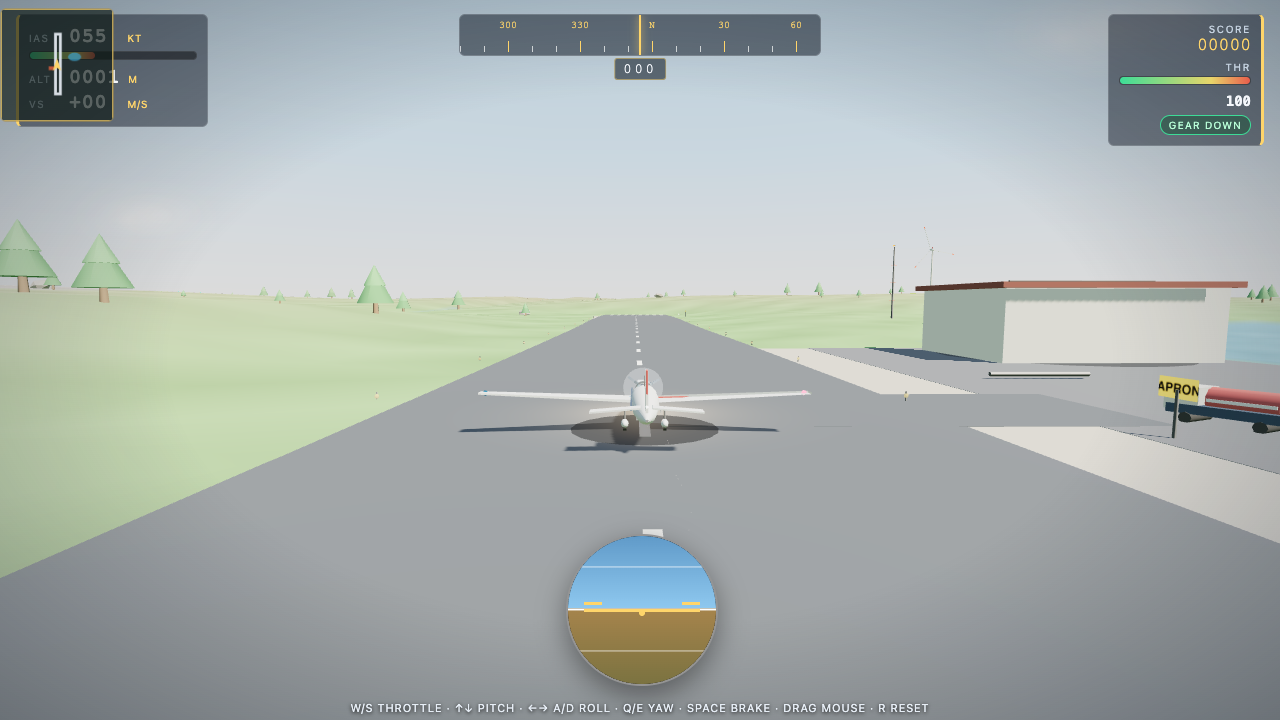
Game
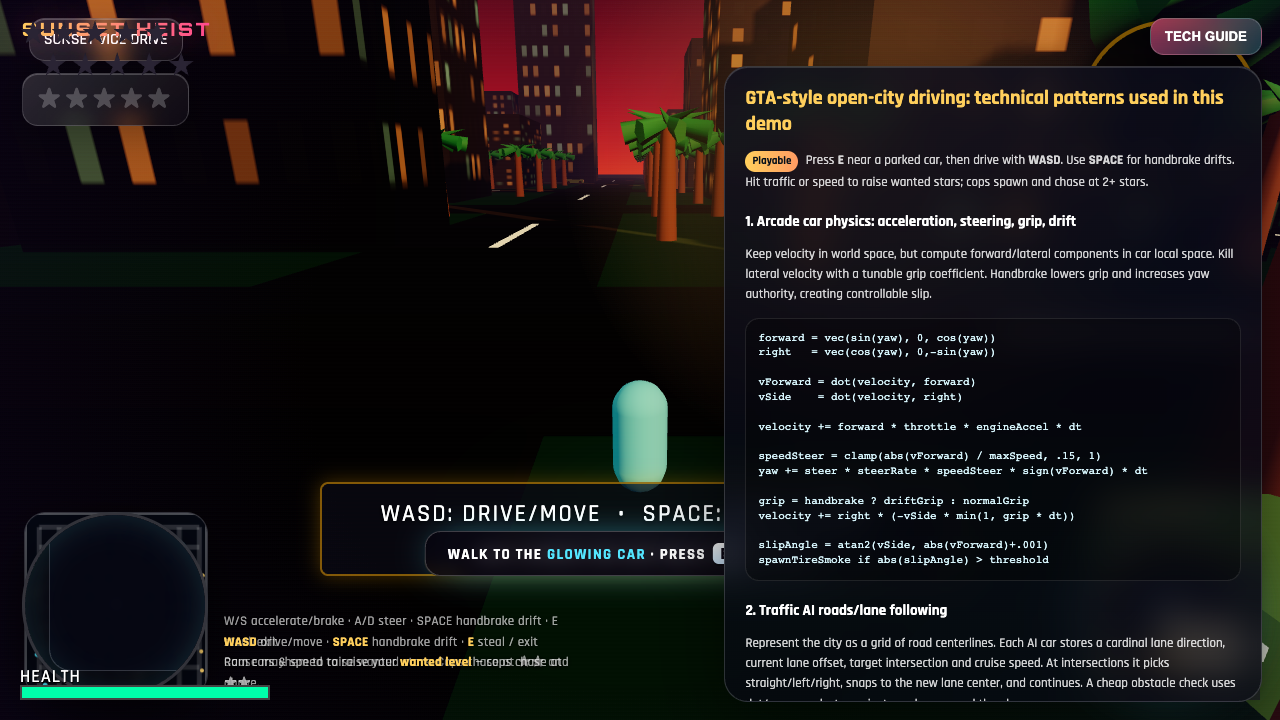
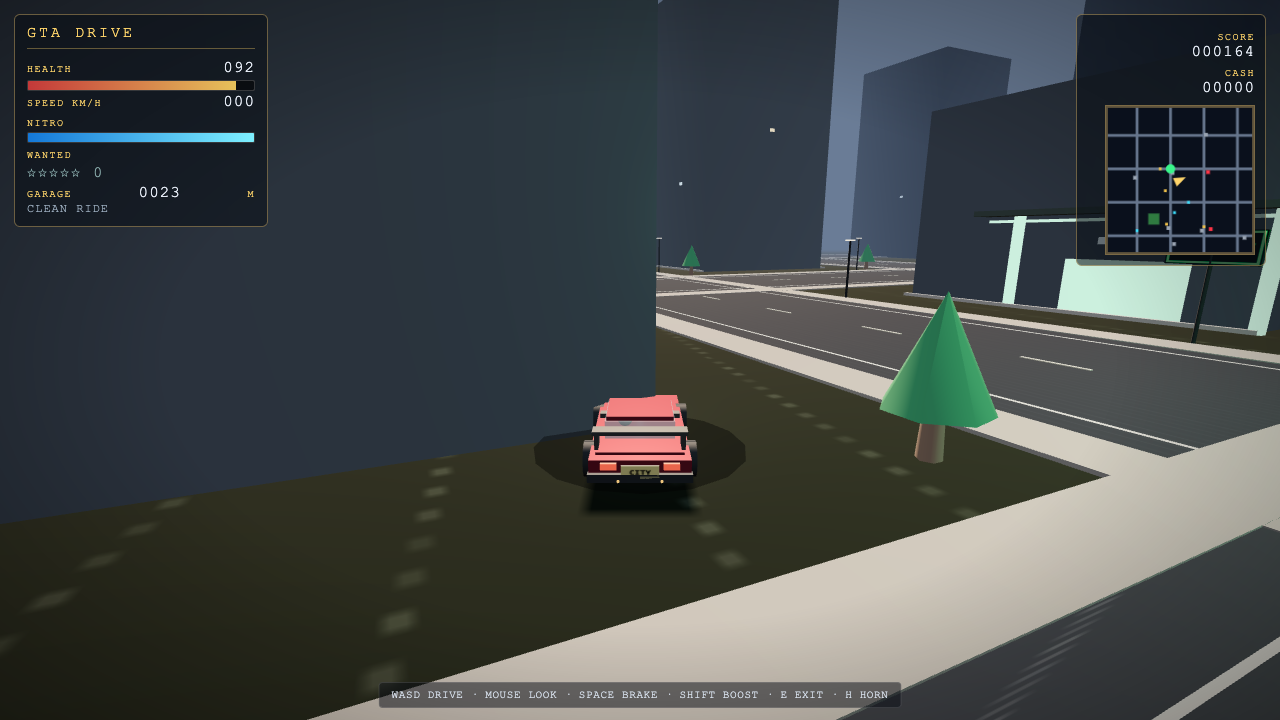
Game
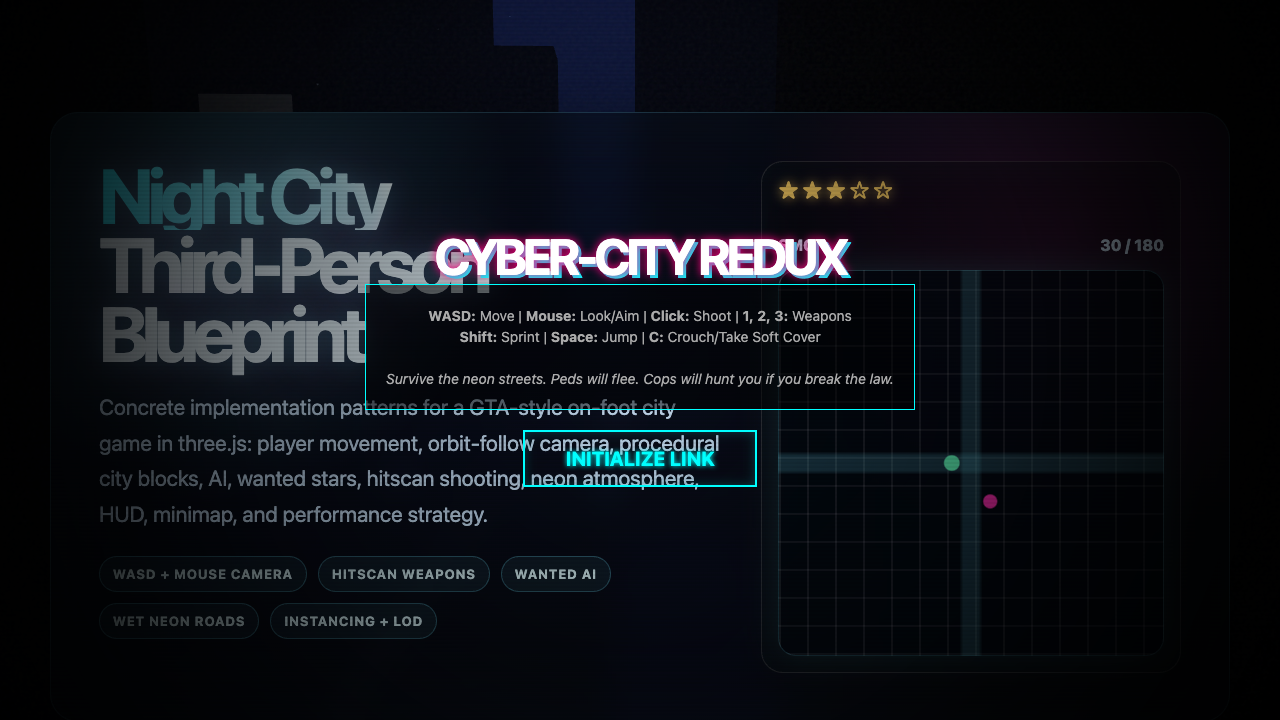
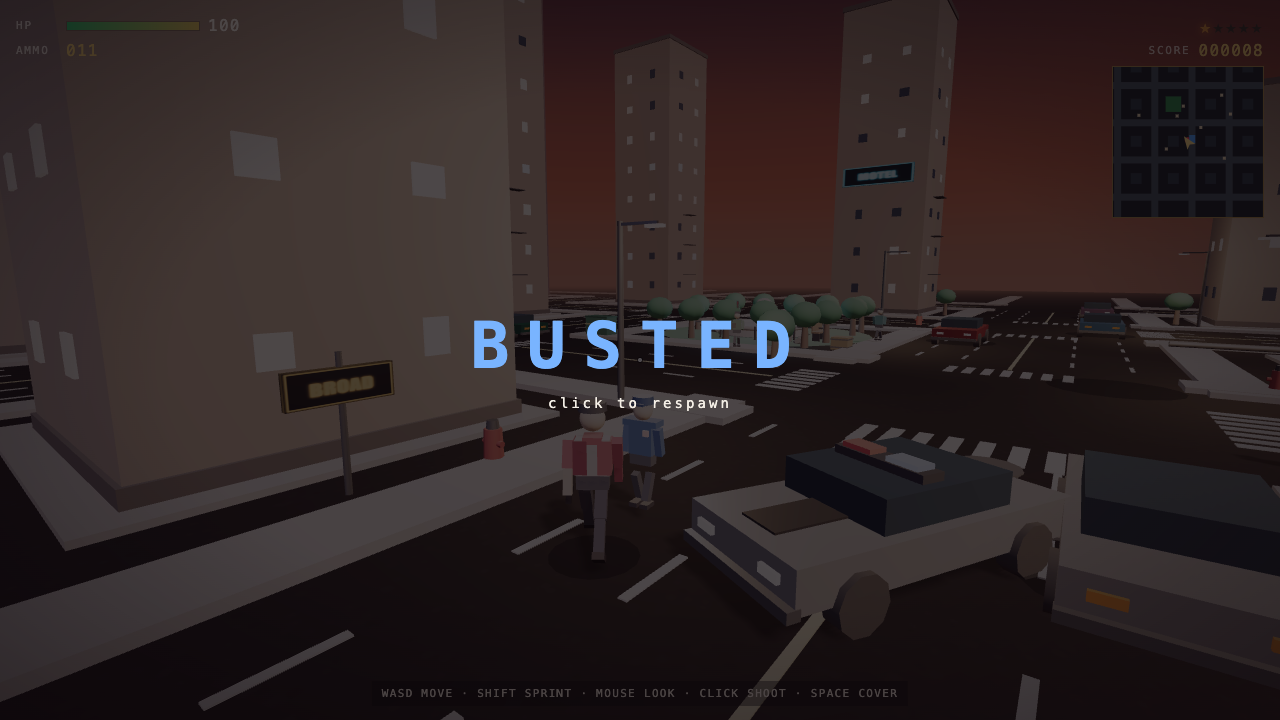
Game
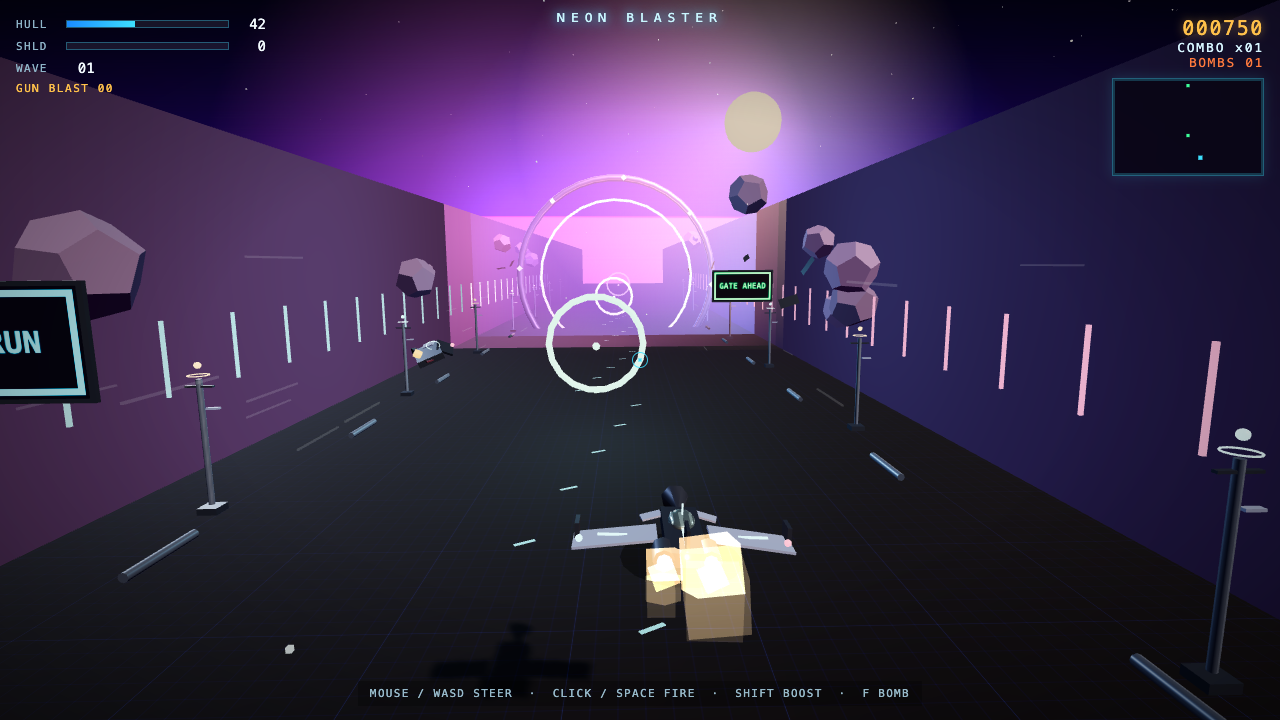
Game
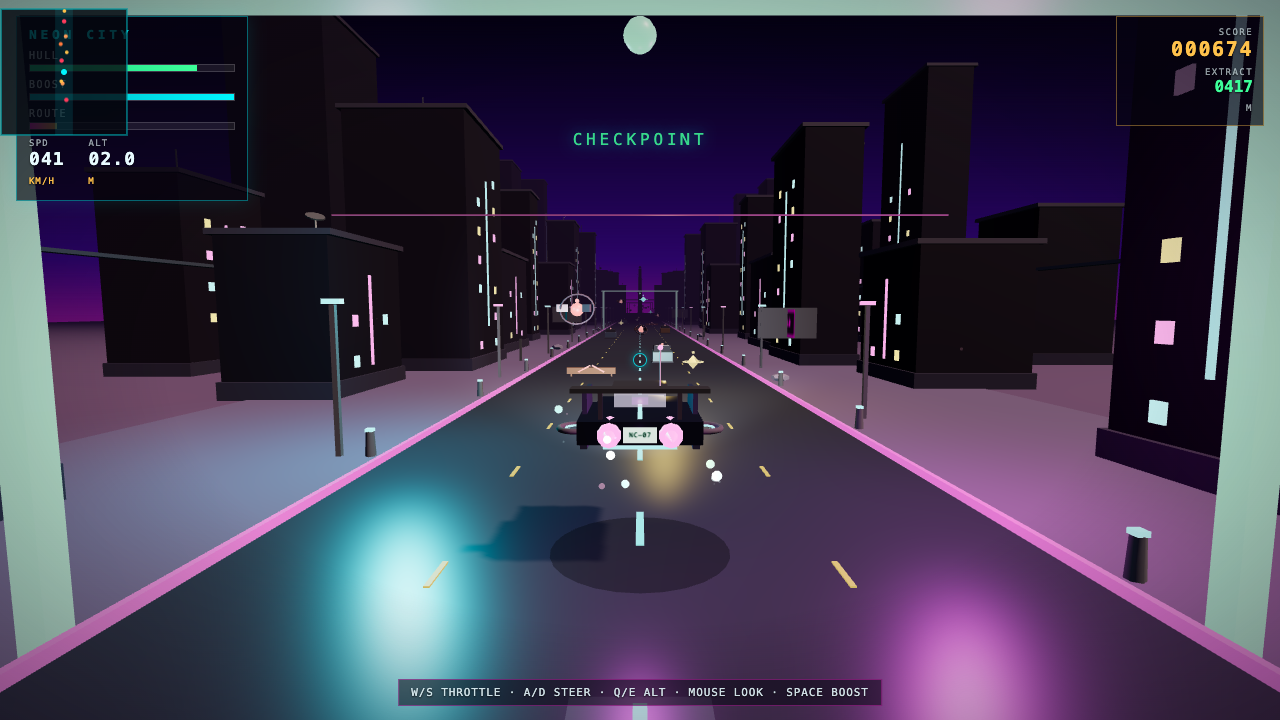
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
— not attempted —
Game
— not attempted —
Game
— not attempted —
Page
— not attempted —
Where Fusion beat Grok 4.7
The tasks where I gave Fusion a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Voxelcraft
Game
Fusion 9.0
·
Grok 4.7 2.2
(+6.8)
· winner · sandbox
What I saw: Minecraft-style voxel sandbox in 23KB. Block-based world, fly around, click-to-break, right-click-to-place, day/night cycle, block-picker hotbar. Closest to a real Minecraft any Fusion build managed.
Crypt
Game
Fusion 9.0
·
Grok 4.7 2.3
(+6.7)
· winner · dungeon crawler
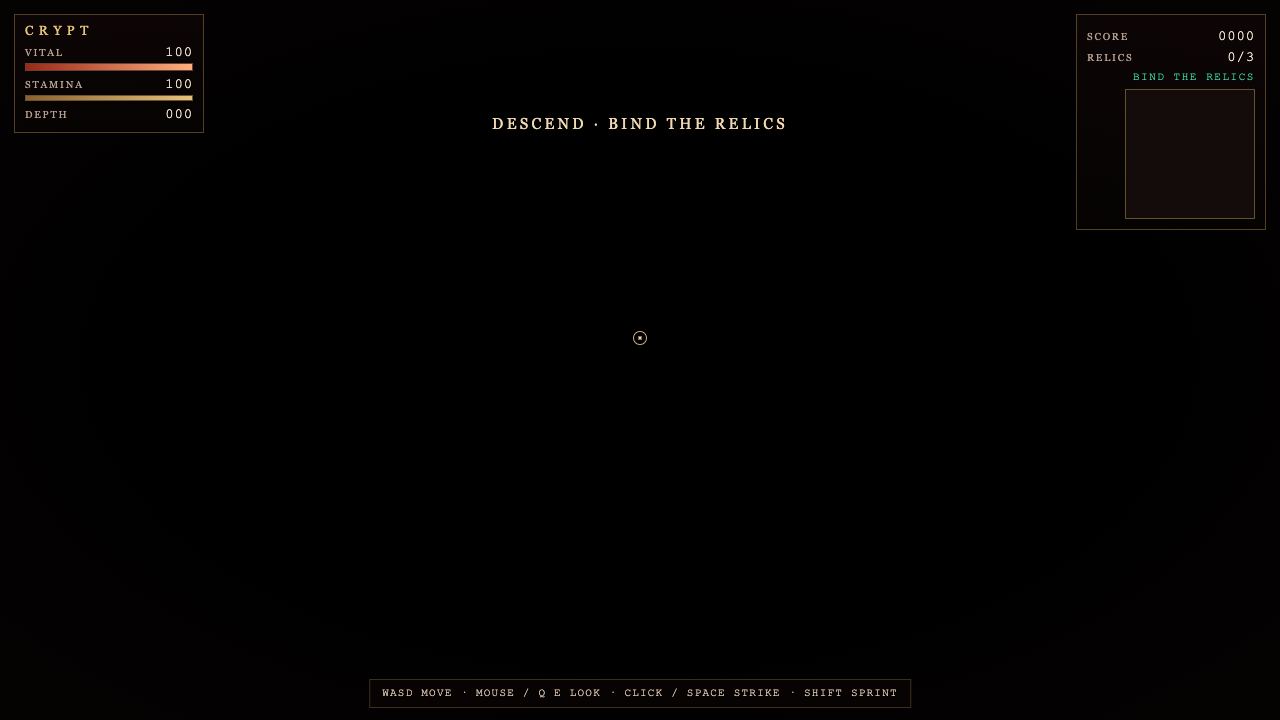
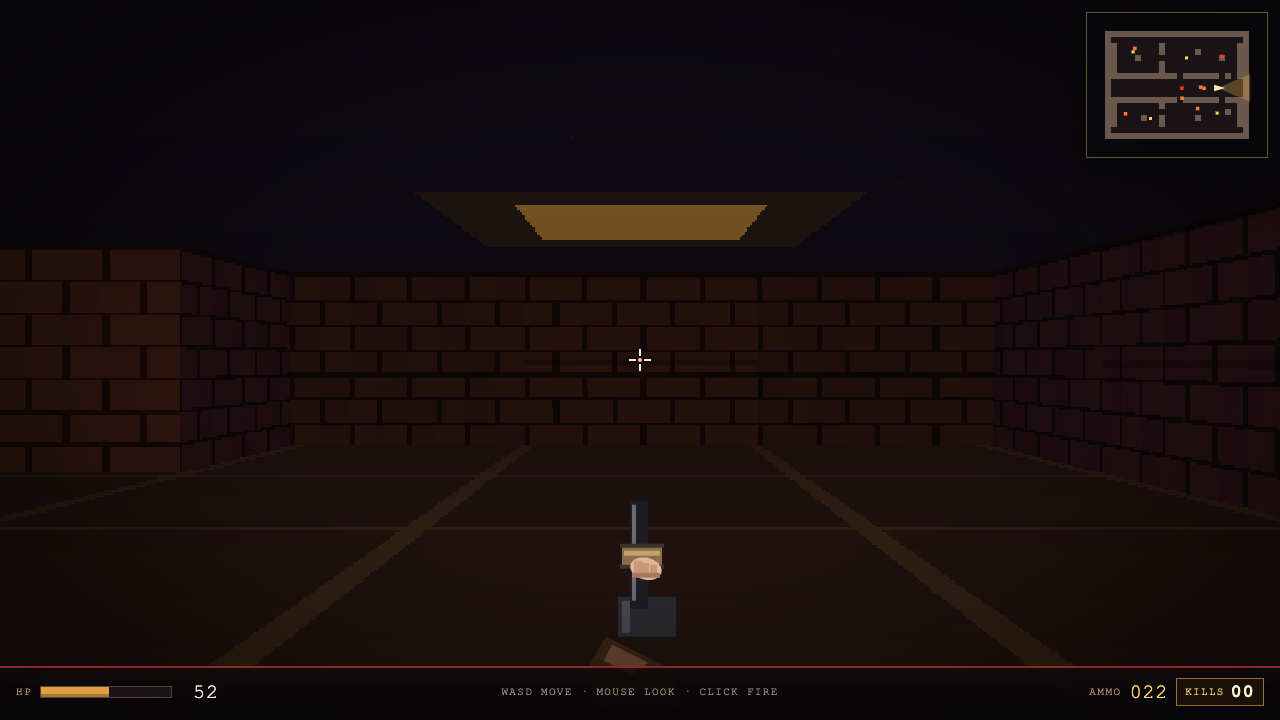
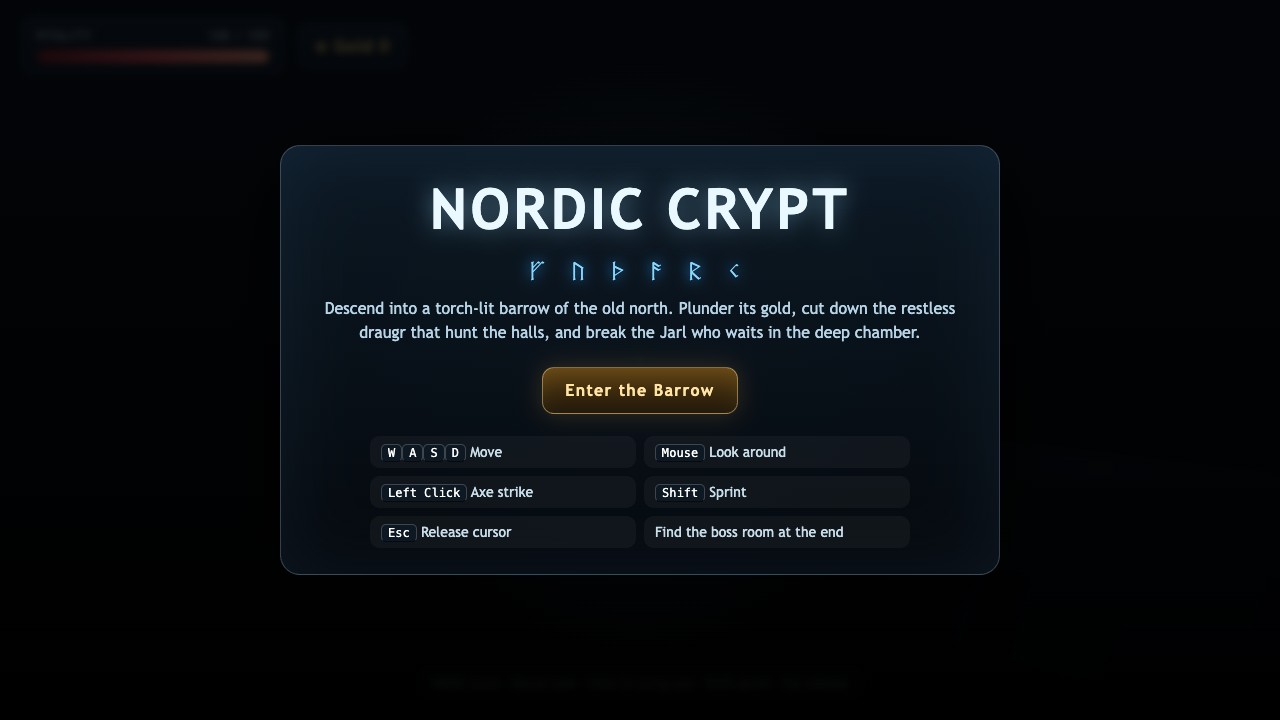
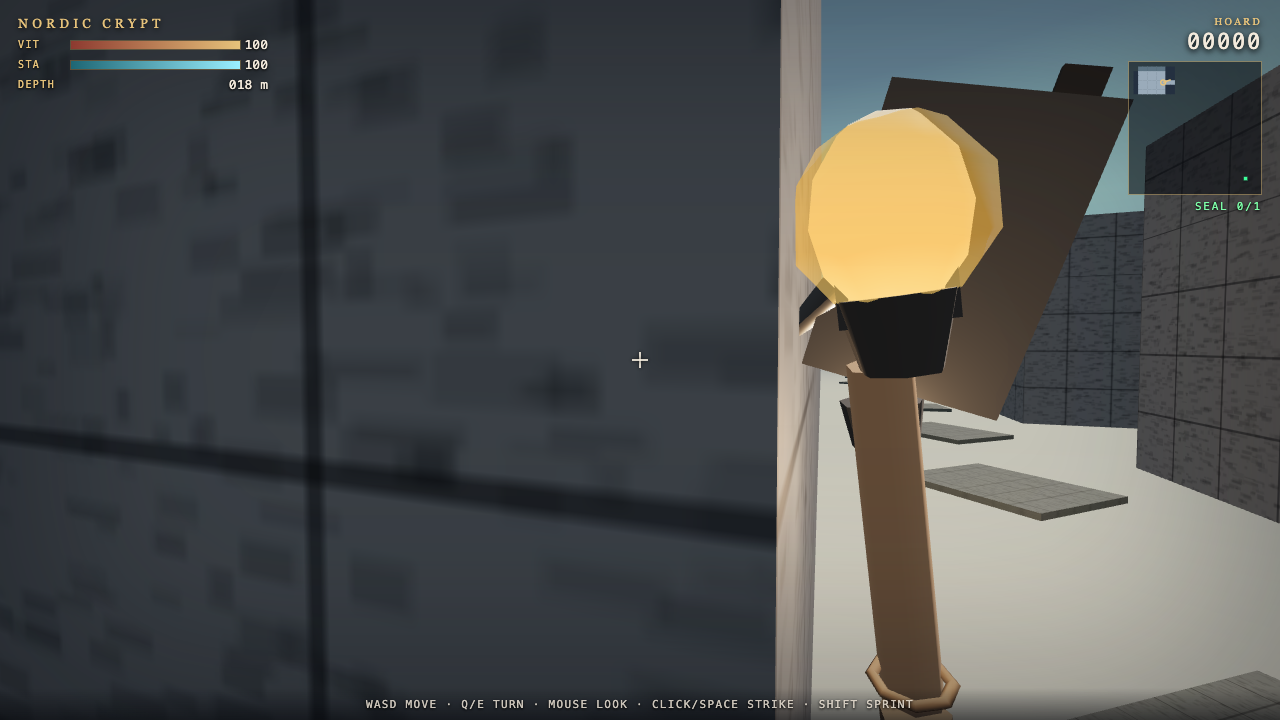
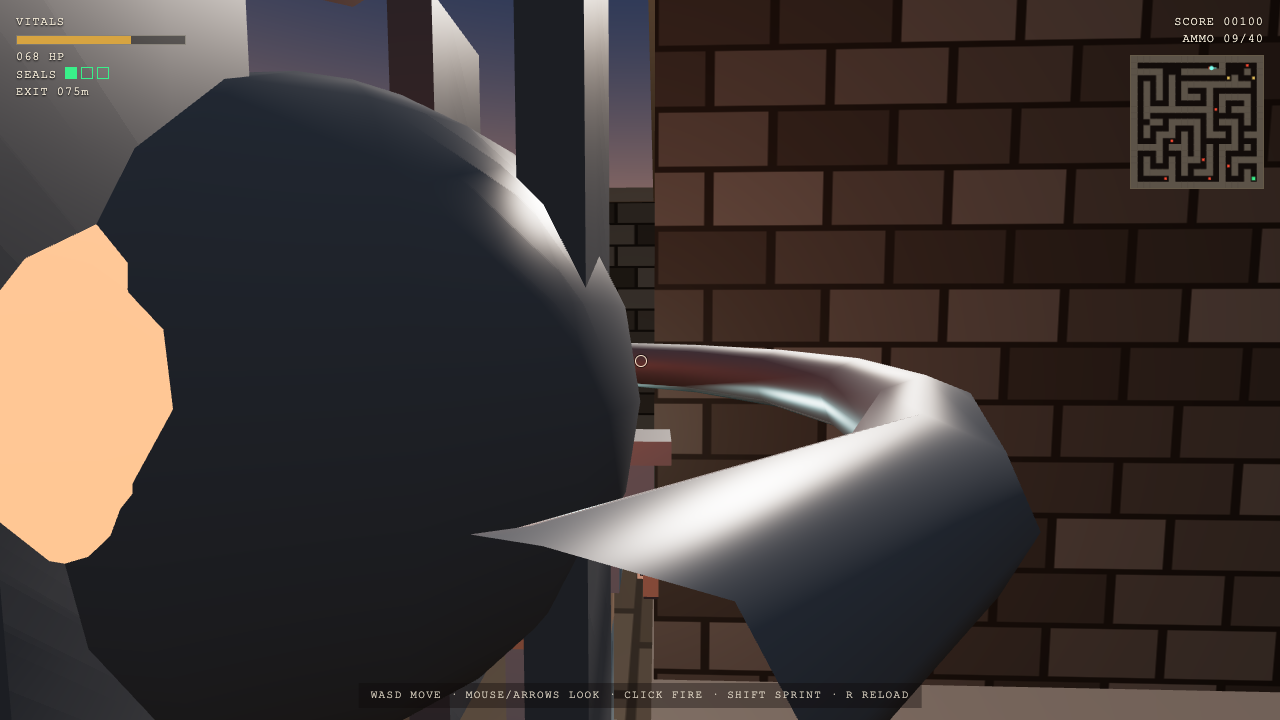
What I saw: First-person Nordic dungeon on three.js with PointerLockControls + WebGL. Torch-lit corridors, held torch, skeletons to strike, health + gold HUD. The crypt Julian wanted.
Nordiccrypt
Game
Fusion 9.5
·
Grok 4.7 5.5
(+4.0)
· winner · best dungeon
What I saw: RETRY @ 24K tokens — now complete: 29KB with rAF + 7 input handlers + closed tags. Torch-lit ancient ruin, PointerLockControls, bloom, chasing enemies, boss room. The original truncated attempt has been replaced with a working build.
Parachute
Game
Fusion 8.8
·
Grok 4.7 6.0
(+2.8)
· showcase · game-director
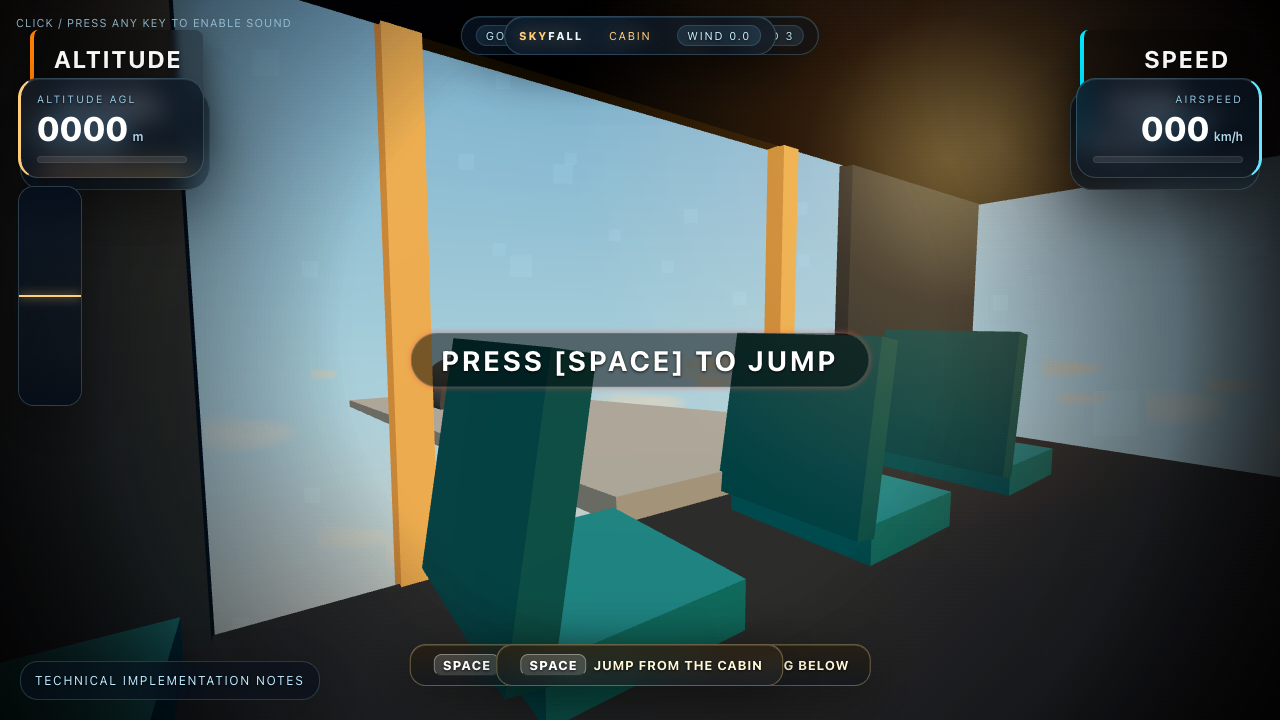
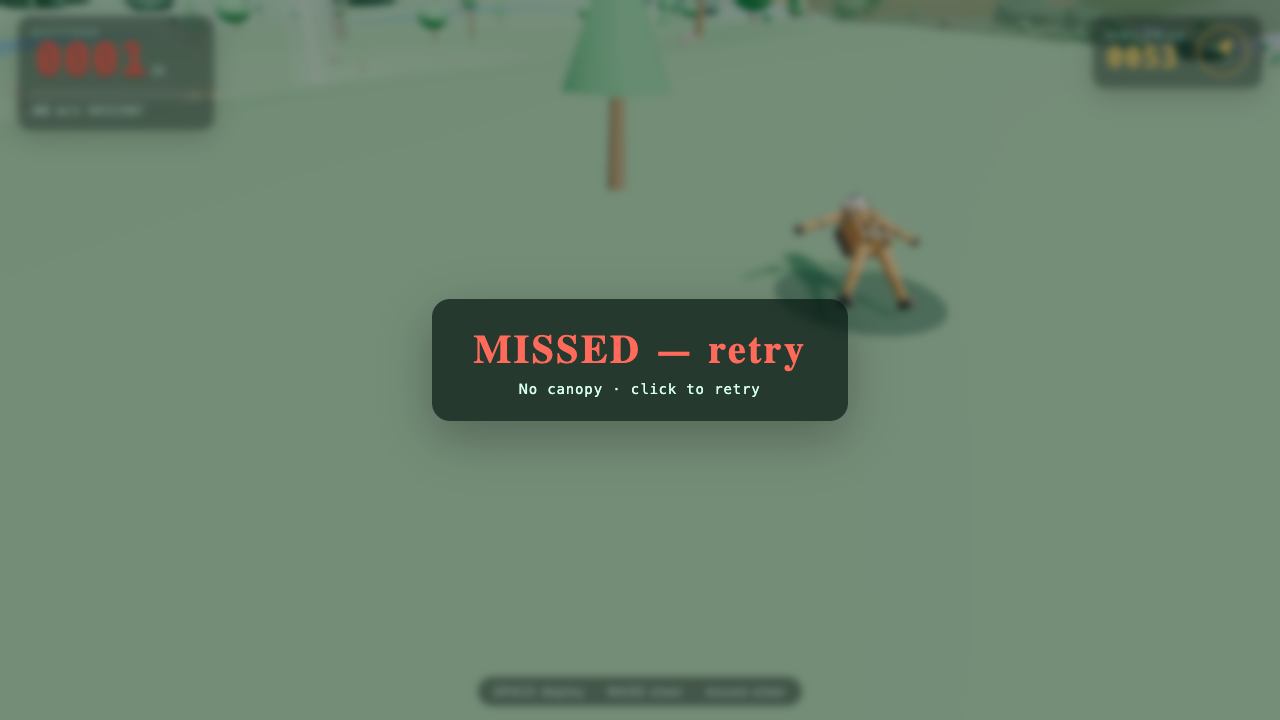
What I saw: SHOWCASE BUILD (threejs-game-director): cargo-bay interior + jump light, articulated skydiver w/ 7 pose sets, 9-cell ram-air canopy w/ lines, 11.5k instanced trees + carved river, ring-target landing scoring, analog altimeter HUD, auto-demo lands inner ring. Eyeball-gate passed.
Dogfight
Game
Fusion 9.0
·
Grok 4.7 6.3
(+2.7)
· winner · air combat
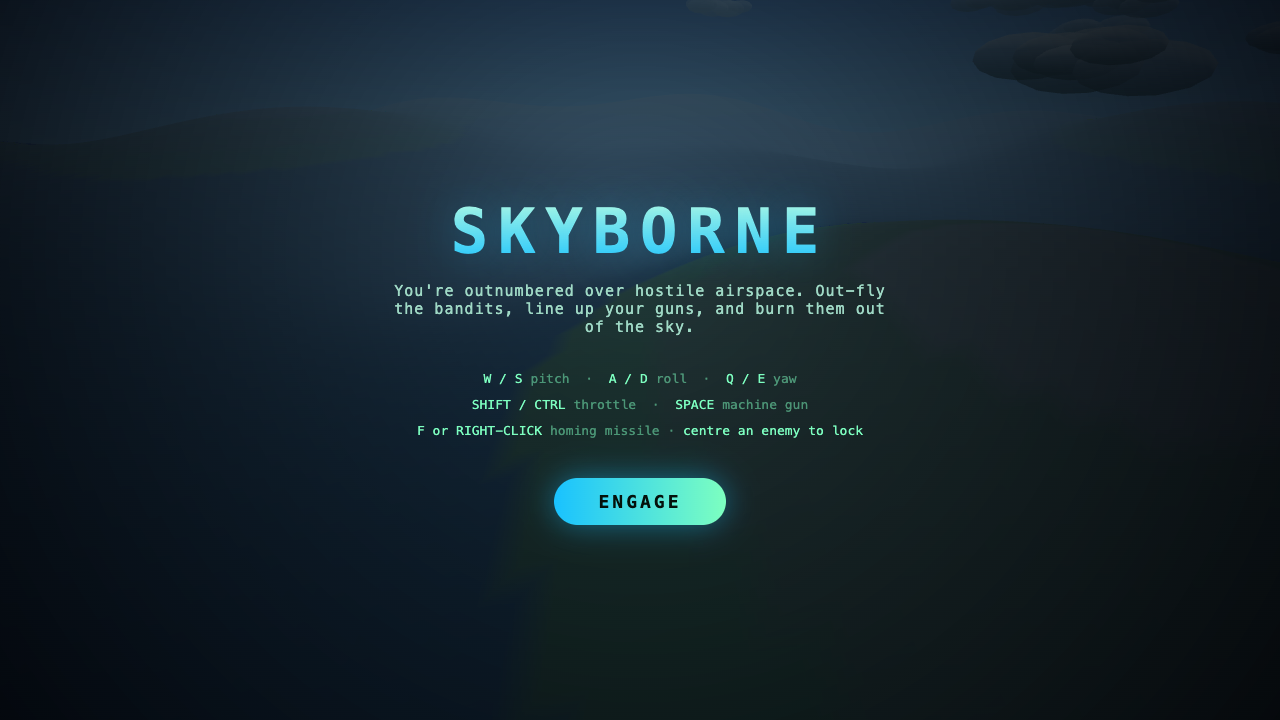
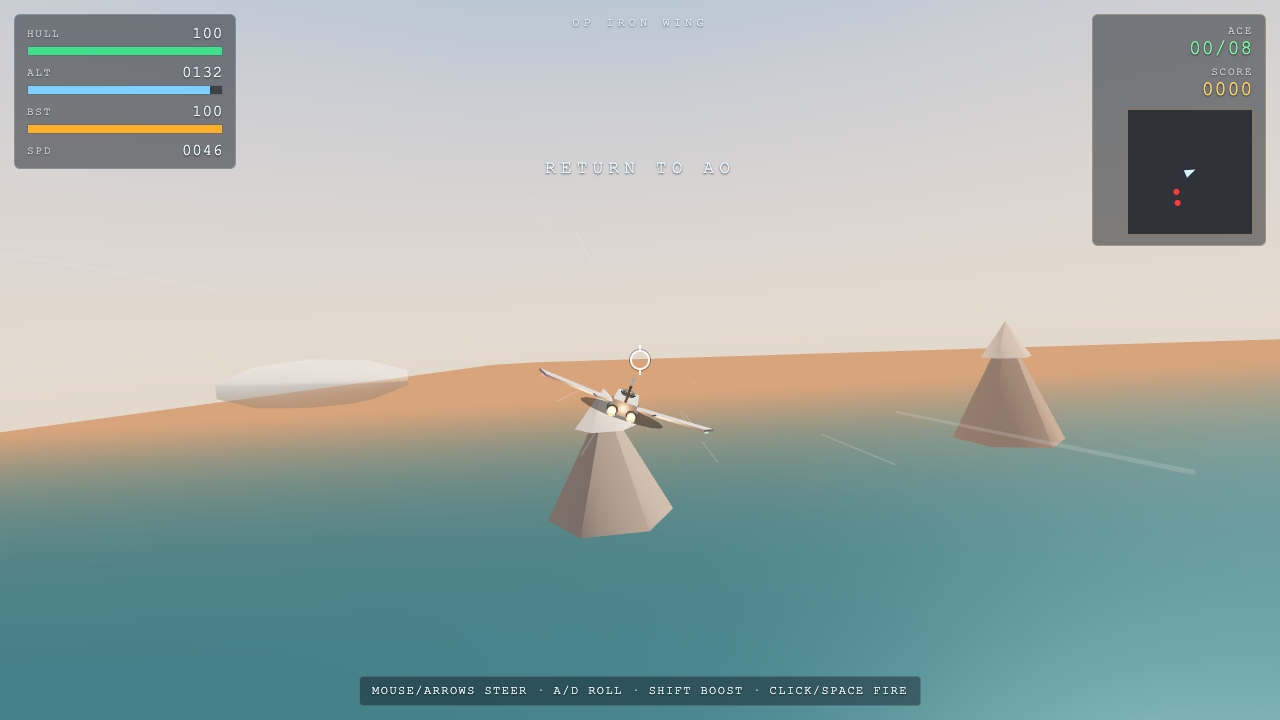
What I saw: RETRY @ 24K tokens — now complete: 36KB three.js + WebGL with 2 rAFs, 6 input handlers, full </html>. Fighter, enemies, missiles, guns, sky + ground, full HUD. The original truncated 32KB attempt has been replaced with a working build.
Where Grok 4.7 beat Fusion
The tasks where I gave Grok 4.7 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Outrun
Game
Grok 4.7 8.4
·
Fusion 8.0
(+0.4)
· synthwave horizon polish
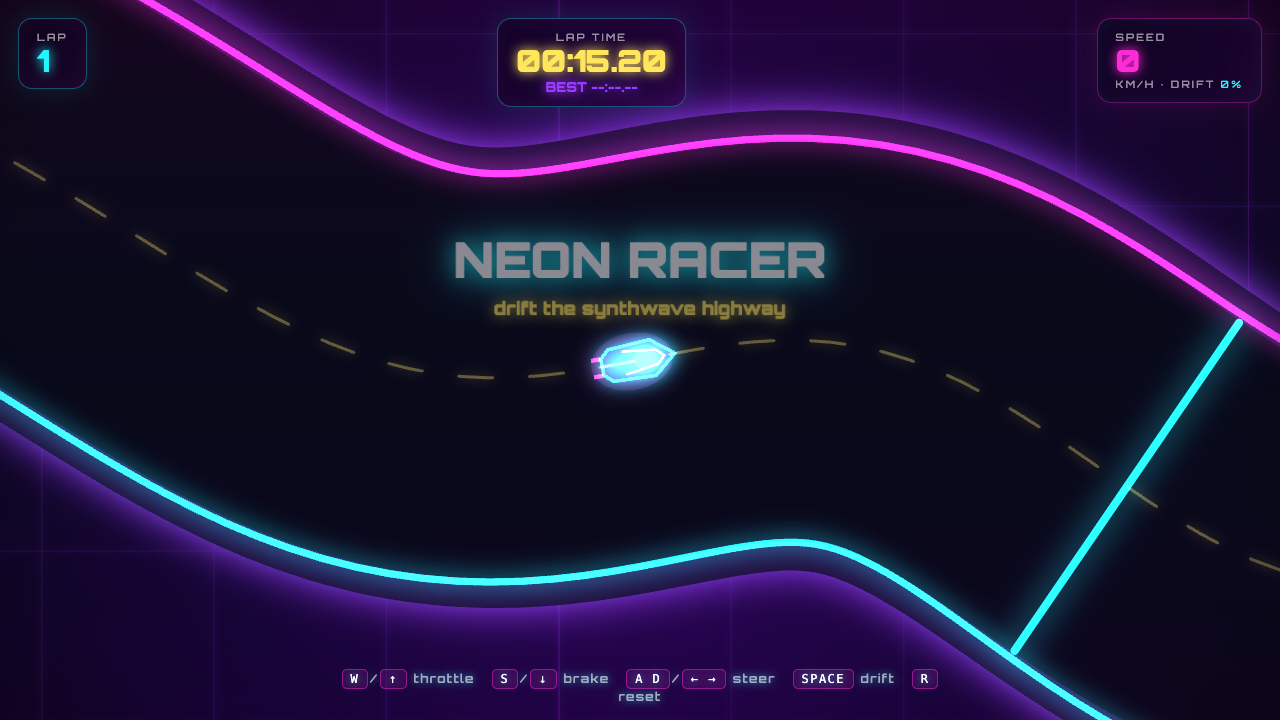
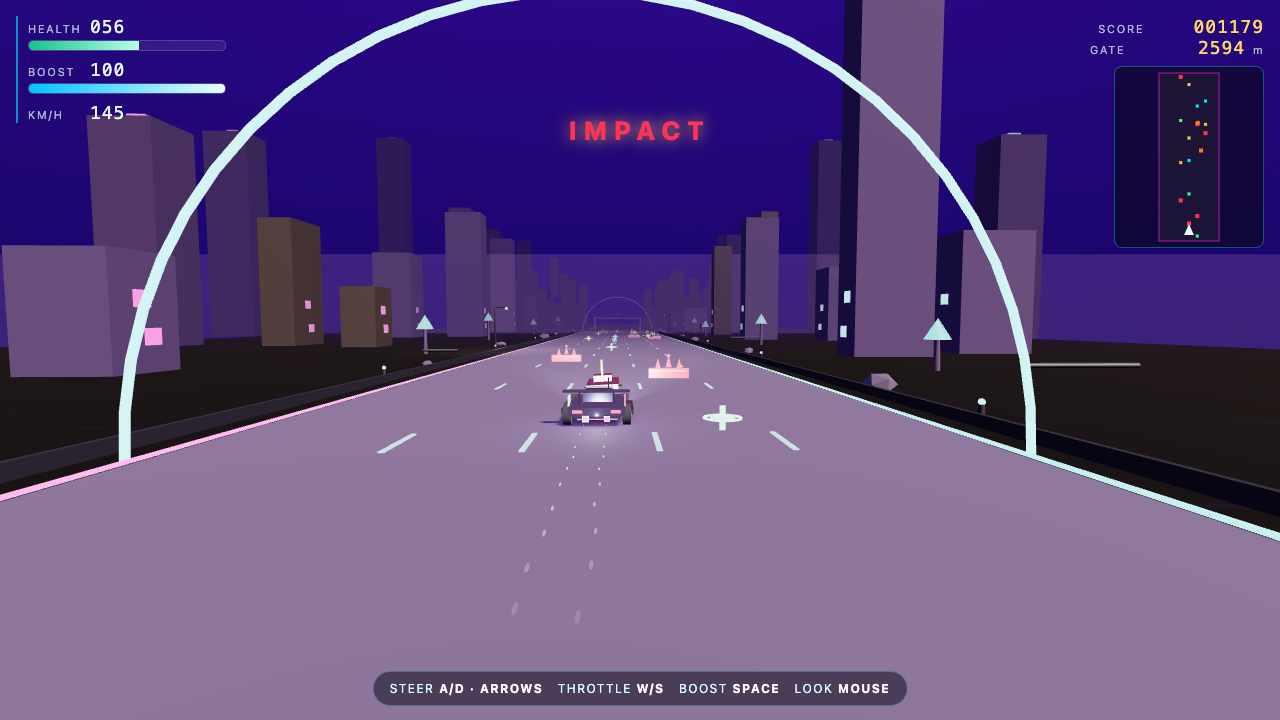
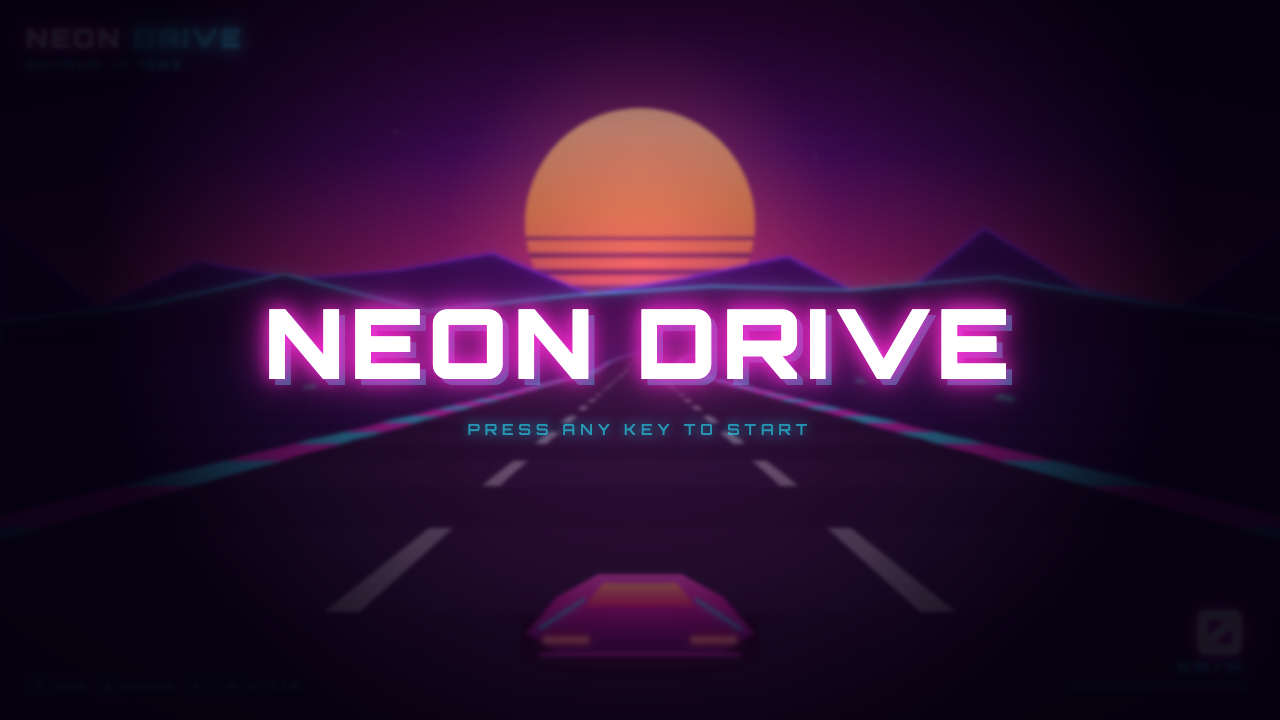
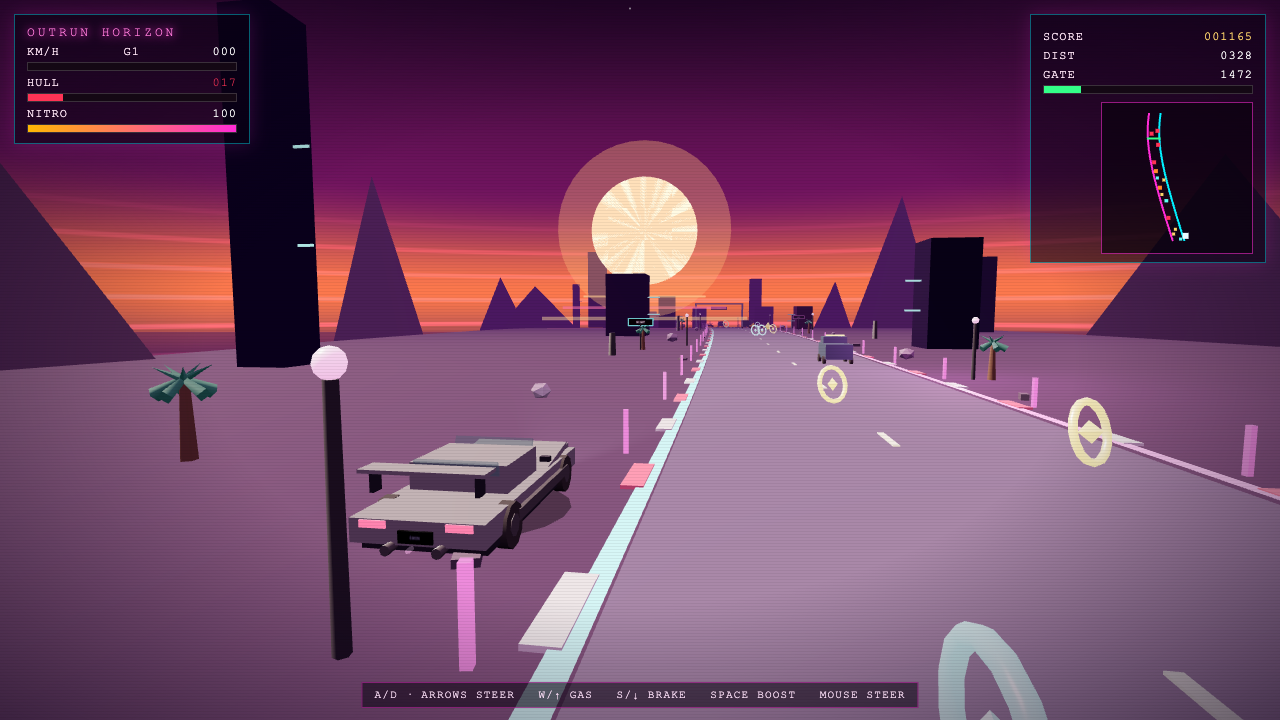
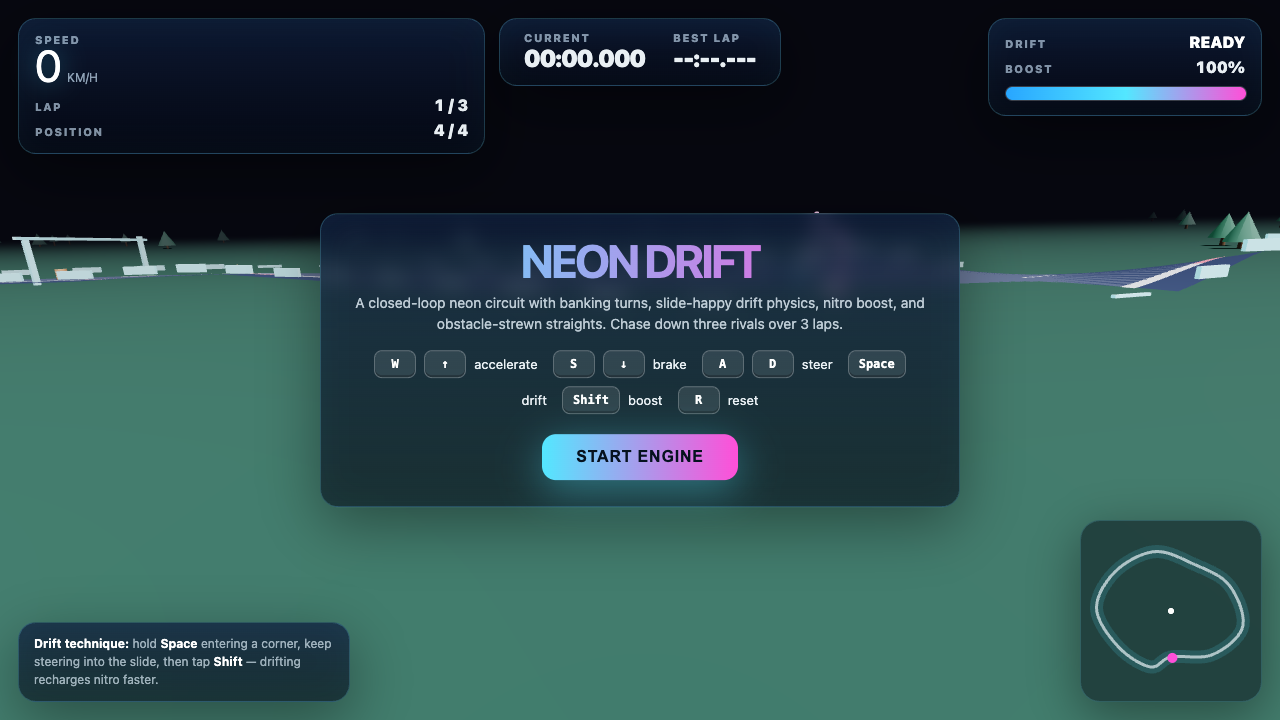
What I saw: Gorgeous full synthwave scene — striped sun, gradient sky, neon grid, palms, pickups, minimap and rich HUD — and playtest shows real progression (dist/score climbed, gears shifted, hull took damage). Loses a touch because the car drifted off-road and stalled at HULL 012 speed 000…
Neoncity
Game
Grok 4.7 8.7
·
Fusion 8.5
(+0.2)
· neon drive polished
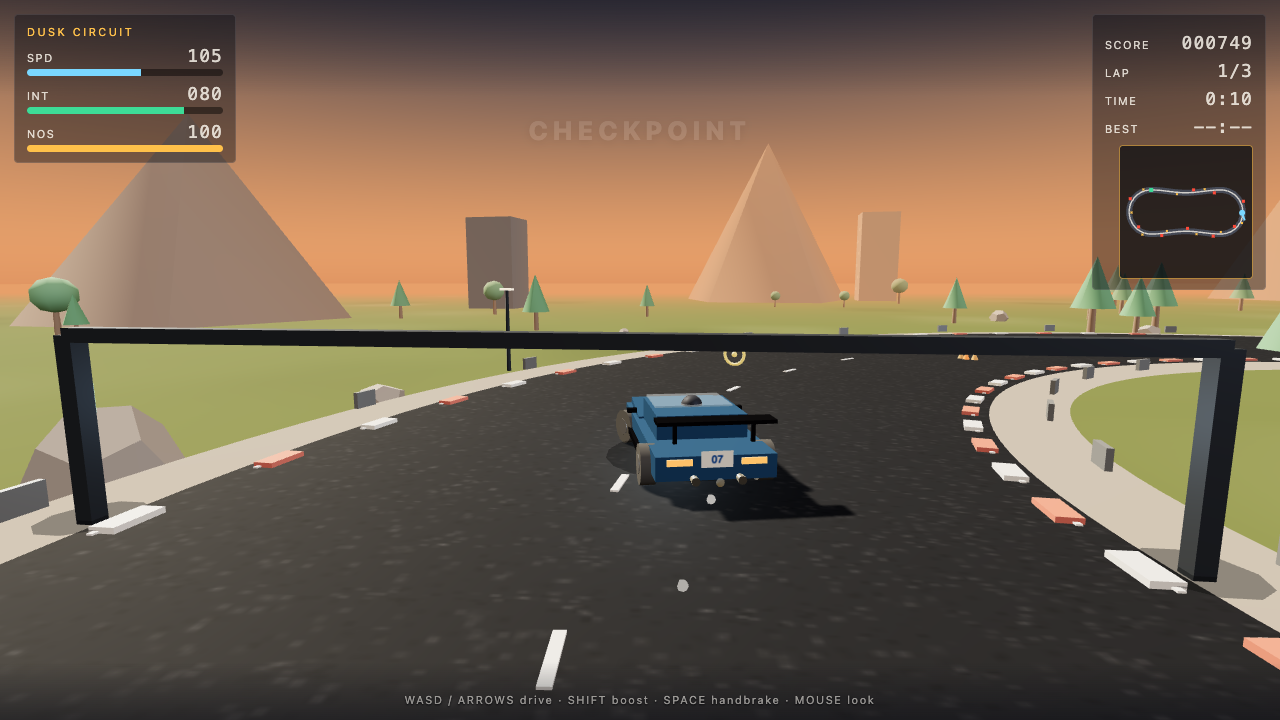
What I saw: Renders a gorgeous cyberpunk street with pink/cyan neon curbs, glowing buildings, a hovercar with reflective plate lights, and a full working HUD (speed, hull/boost/route, score, extract distance, minimap); playtest confirms real motion, progressing score and checkpoint/traffic s…
Arcade
Game
Grok 4.7 8.6
·
Fusion 8.5
(+0.1)
· 3D breakout polish
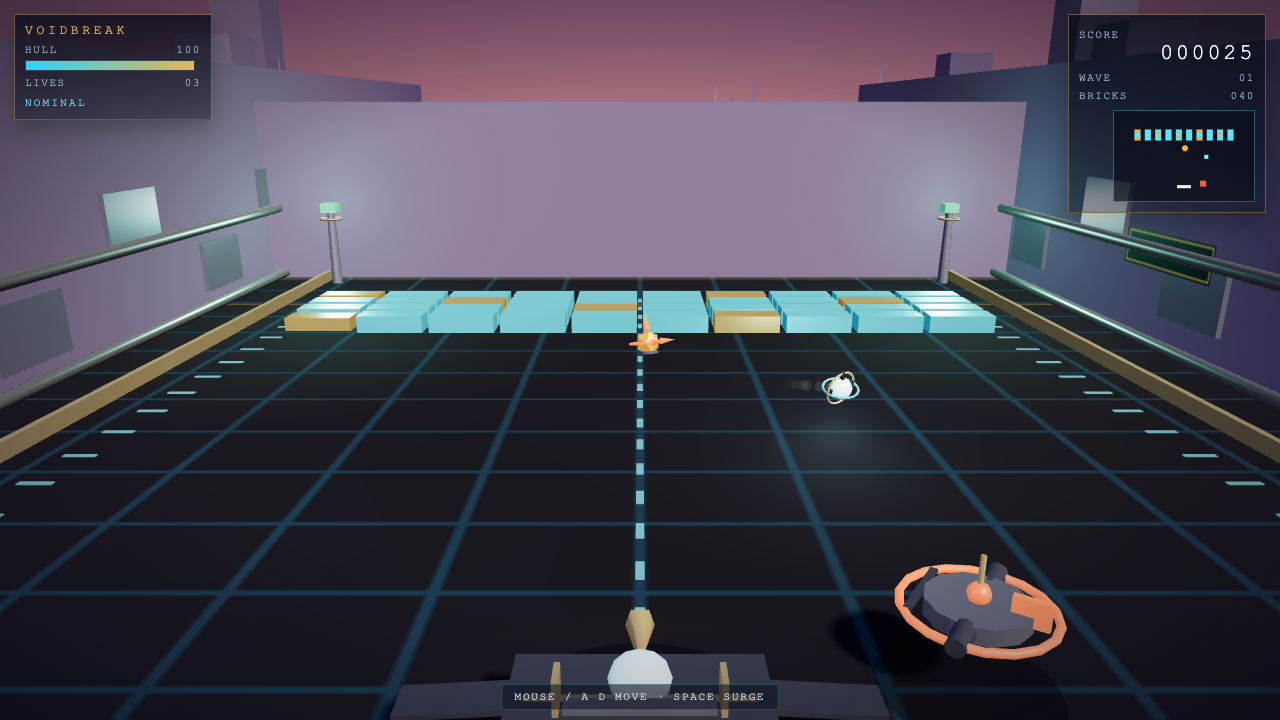
What I saw: A gorgeous 3D breakout with rich lighting, gradient sky dome, gridded arena, minimap, and a polished sci-fi HUD; playtest confirms real motion (walkPx 0.23) with hull/lives/score/bricks all changing and no console errors — clearly at or above the field's best.
Strengths & weaknesses I logged
Fusion
Strengths
- Premium Fusion panel scored 69.0% on DRACO deep-research benchmark — beats solo Fable 5 by +3.7 points
- Budget panel ties Fable 5 at ~64.7% for roughly half the cost
- Vendor-agnostic — model panel can swap as new frontier releases land
Trade-offs
- Ensemble latency higher than any single model (panel calls run in parallel but the slowest still gates the response)
- No per-task goldiebench scoring yet — bench rank pending
Grok 4.7
Strengths
- Averaged 7.15/10 on the same twenty skill-infused game briefs where Grok 4.6 averaged 5.95, winning 14 of the 20 head-to-heads
- Best one-shots on this run: neoncity (8.7), racing (8.7), arcade (8.6), every one played on a real GPU before scoring
- Longer reinforcement learning shows: it holds a 40-50KB single-file spec and wires the controls it advertises
- xAI's own coding numbers moved: CursorBench 4.0 46.3% (from 40.4%) and DeepSWE v1.1 71.0% (from 65.2%)
Trade-offs
- 2 of 20 builds died on load or never moved when played — crypt: hud is not a function; voxelcraft: mesh.computeBoundingSphere is not a function file:///Users/j
- Independent Artificial Analysis Intelligence Index v4.3.2 puts it at 46, seven points behind Claude Fable 5.1 and GPT-6 at 53
- Terminal-Bench 4.0 is the weak spot xAI reports itself: 38.0% at launch
Pricing & context — the spec sheet
| Spec | Fusion | Grok 4.7 |
|---|---|---|
| Vendor | OpenRouter | xAI |
| Context window | Varies — depends on which panel models are dispatched | 500,000 tokens |
| Price | OpenRouter Fusion API pricing | $2 in / $6 out per M tokens |
| Pricing detail | OpenRouter's Fusion API dispatches a single prompt to multiple frontier models and ensembles the answers. Premium panel: Fable 5 + GPT-5.5. Budget panel: cheaper open-weights models. Roughly half the per-token cost of a Fable 5 solo call. | xAI's September 2026 release, priced exactly like Grok 4.6: $2 per million input tokens and $6 per million output on the standard tier, $4 / $12 on the Fast tier (double the output speed). OpenRouter lists the same model at $1.60 / $4.80. |
| Release | 2026-06-14 | 2026-09 |
| Bench coverage | 47/47 scored · avg 8.59/10 | 20/20 scored · avg 7.15/10 |
The verdict — which should you pick?
Across 20 scored shared tasks, Fusion averaged 8.82/10, beating Grok 4.7's 7.15/10 by 1.67 points. Pick Fusion when the build has to ship on the first prompt and you can afford the trade-offs in the comparison below.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire Fusion and Grok 4.7 both into the Agent Operating System and dispatch each from the kanban by task type — deep-research workflows where panel consensus beats single-model answers → Fusion, one-shot arcade, driving and shooter builds where the whole game has to arrive in a single file → Grok 4.7. That's the same setup I run for the 3,400+ founders inside the AI Profit Boardroom.
FAQ — Fusion vs Grok 4.7
Which is better, Fusion or Grok 4.7?
On Goldie Bench, Fusion averages 8.82/10 across the shared tasks, with 21 gold, 3 silver, 1 bronze overall. Grok 4.7 averages 7.15/10, with 0 gold, 2 silver, 3 bronze. Fusion wins the head-to-head 17–3.
How much does Fusion cost vs Grok 4.7?
Fusion: OpenRouter's Fusion API dispatches a single prompt to multiple frontier models and ensembles the answers. Premium panel: Fable 5 + GPT-5.5. Budget panel: cheaper open-weights models. Roughly half the per-token cost of a Fable 5 solo call. Grok 4.7: xAI's September 2026 release, priced exactly like Grok 4.6: $2 per million input tokens and $6 per million output on the standard tier, $4 / $12 on the Fast tier (double the output speed). OpenRouter lists the same model at $1.60 / $4.80.
What's the context window for Fusion vs Grok 4.7?
Fusion has a Varies — depends on which panel models are dispatched context window. Grok 4.7 has a 500,000 tokens context window.
When should I pick Fusion over Grok 4.7?
Pick Fusion for: Deep-research workflows where panel consensus beats single-model answers; Cost-sensitive operators who want Fable-5-class output at ~half the bill; Production agents that benefit from vendor-redundancy on every call. The trade-off is the weaknesses we logged on the bench: Ensemble latency higher than any single model (panel calls run in parallel but the slowest still gates the response); No per-task goldiebench scoring yet — bench rank pending.
When should I pick Grok 4.7 over Fusion?
Pick Grok 4.7 for: One-shot arcade, driving and shooter builds where the whole game has to arrive in a single file; High-volume agent work priced at half what the other frontier models charge; Grok Build inside the Agent OS: pick 4.7 in the tab and everything it writes lands in the workspace. The trade-off is the weaknesses we logged on the bench: 2 of 20 builds died on load or never moved when played — crypt: hud is not a function; voxelcraft: mesh.computeBoundingSphere is not a function file:///Users/j; Independent Artificial Analysis Intelligence Index v4.3.2 puts it at 46, seven points behind Claude Fable 5.1 and GPT-6 at 53; Terminal-Bench 4.0 is the weak spot xAI reports itself: 38.0% at launch.
How does Goldie Bench score Fusion vs Grok 4.7?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
Fusion vs Claude Opus 5 Grok 4.7 vs Claude Opus 5 Fusion vs Hermes MoA Grok 4.7 vs Hermes MoA Fusion vs GPT-5.6 Sol Grok 4.7 vs GPT-5.6 Sol Fusion vs Claude Fable 5 Grok 4.7 vs Claude Fable 5Full model pages: Fusion · Grok 4.7 · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 3,400+ founders shipping with it every day all live inside the AI Profit Boardroom.
3,400+founders
258documented wins
38countries
$69/momonthly