Real head-to-head · same prompt, one shot
Claude Opus 5.5 vs Claude Sonnet 5
Anthropic's Opus 5.5 — benched on all 50 one-shot builds, every game playtested. vs The agentic SWE frontier — 82% SWE-bench Verified, Dev Team mode.
Head-to-head verdict: Claude Opus 5.5 wins 24–23.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to Claude Opus 5.5 and Claude Sonnet 5, side by side, on 47 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
Claude Opus 5.5 · Benched on all 50 GoldieBench tasks via a Claude subscription: one-shot builds, real renders, pixel-diff playtests on every game, then vision-judged.
Claude Sonnet 5 · Reach for it in Agent OS when the job is iterative, tool-using software engineering. For one-shot visual builds, GLM 5.2 (free) beat it 4-1 here.
Side-by-side on 50 shared tasks
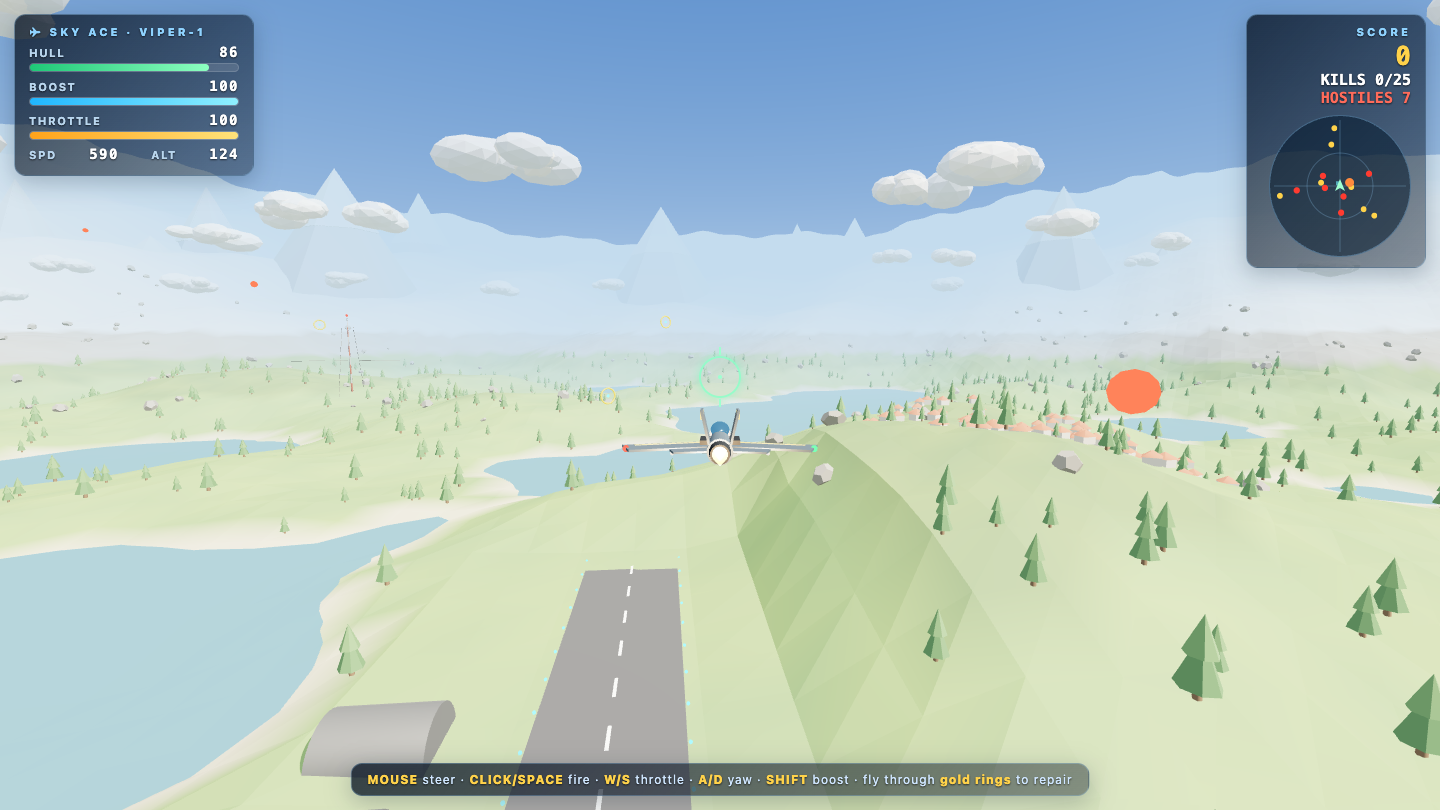
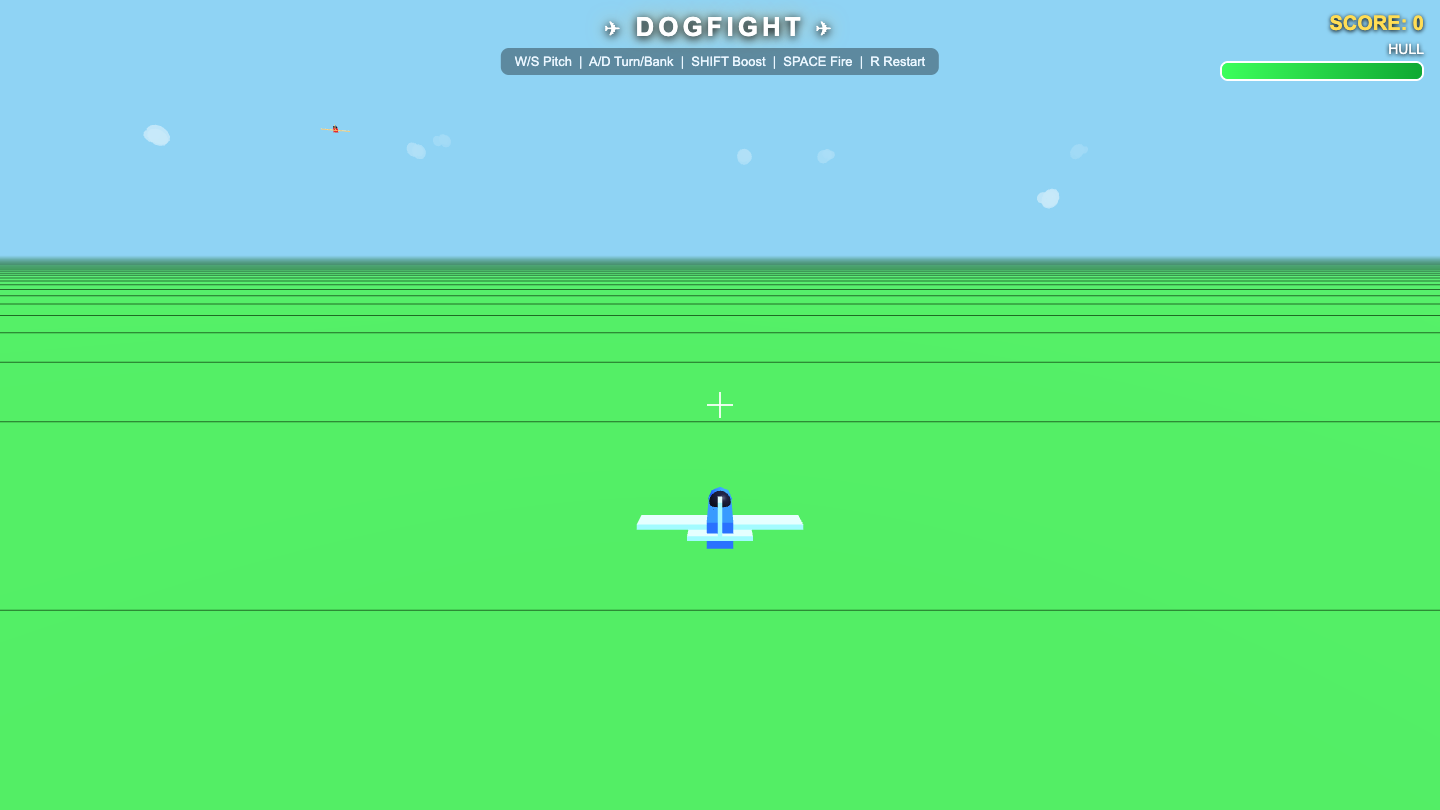
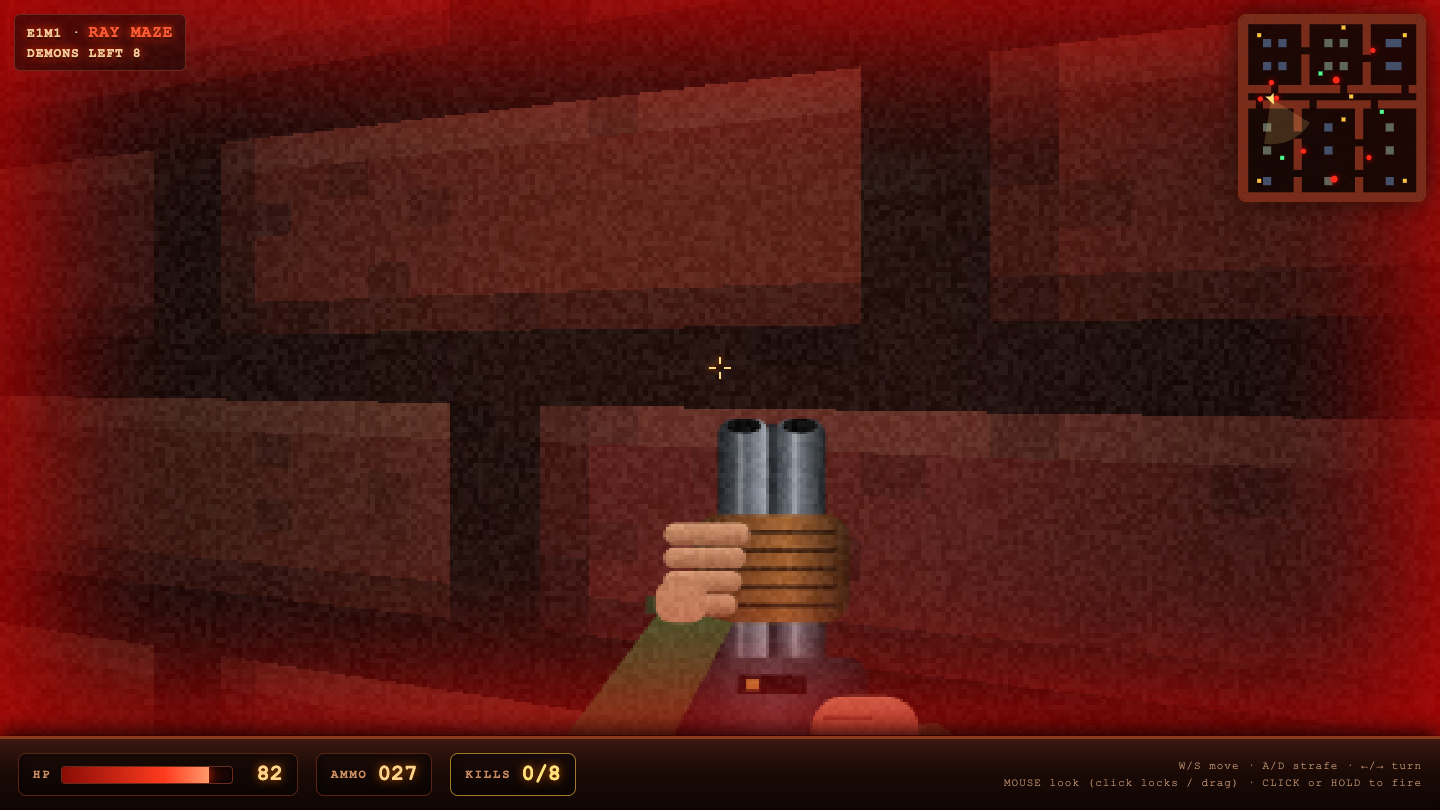
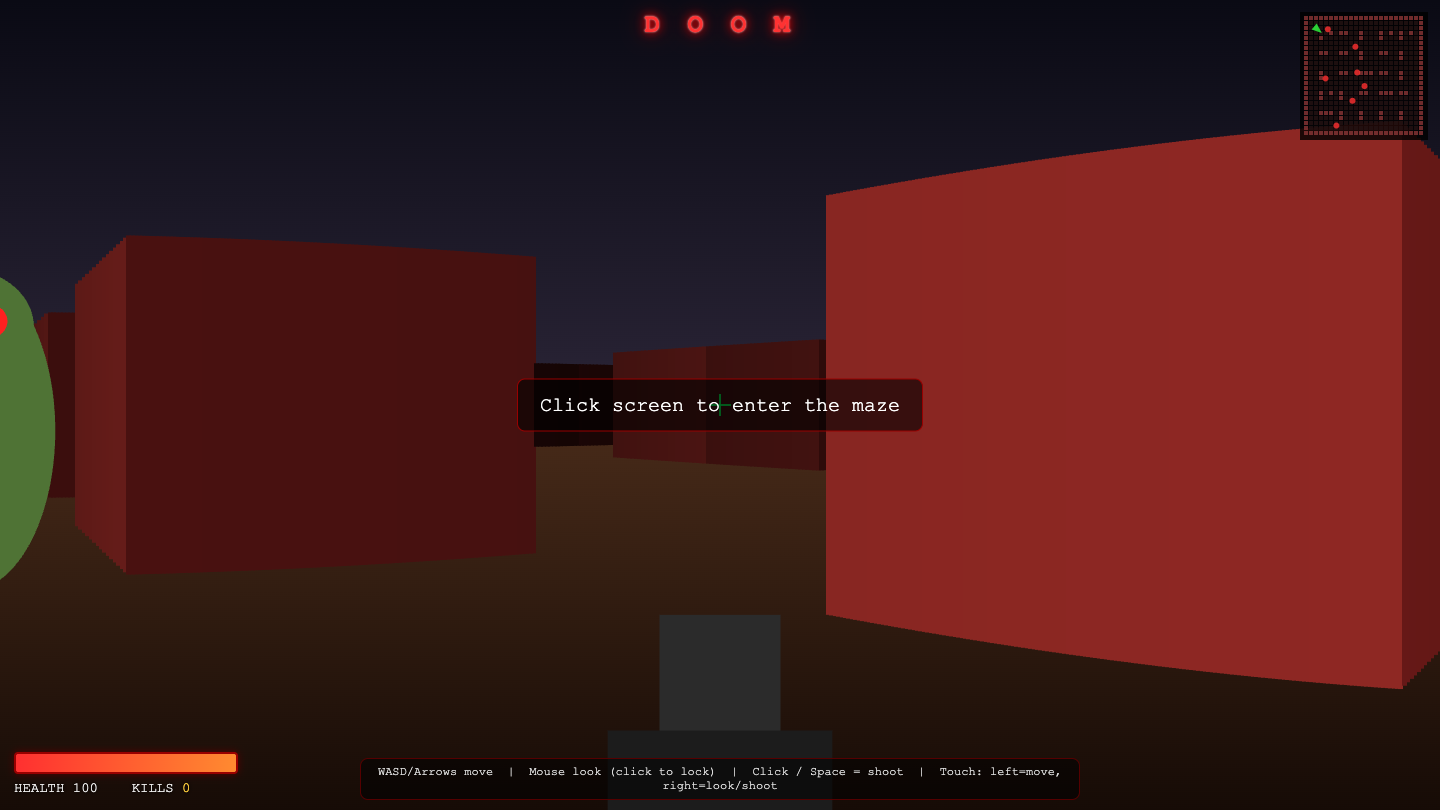
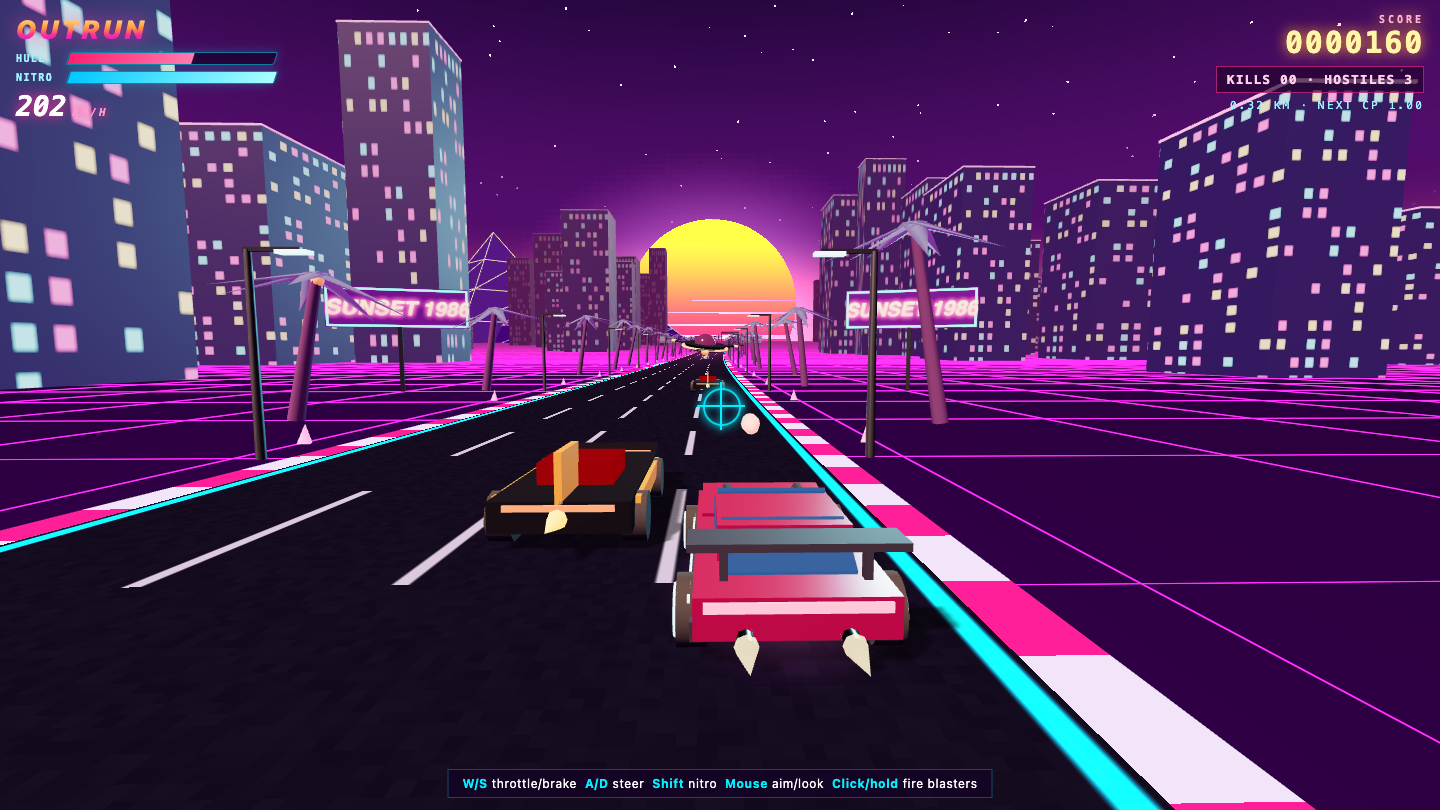
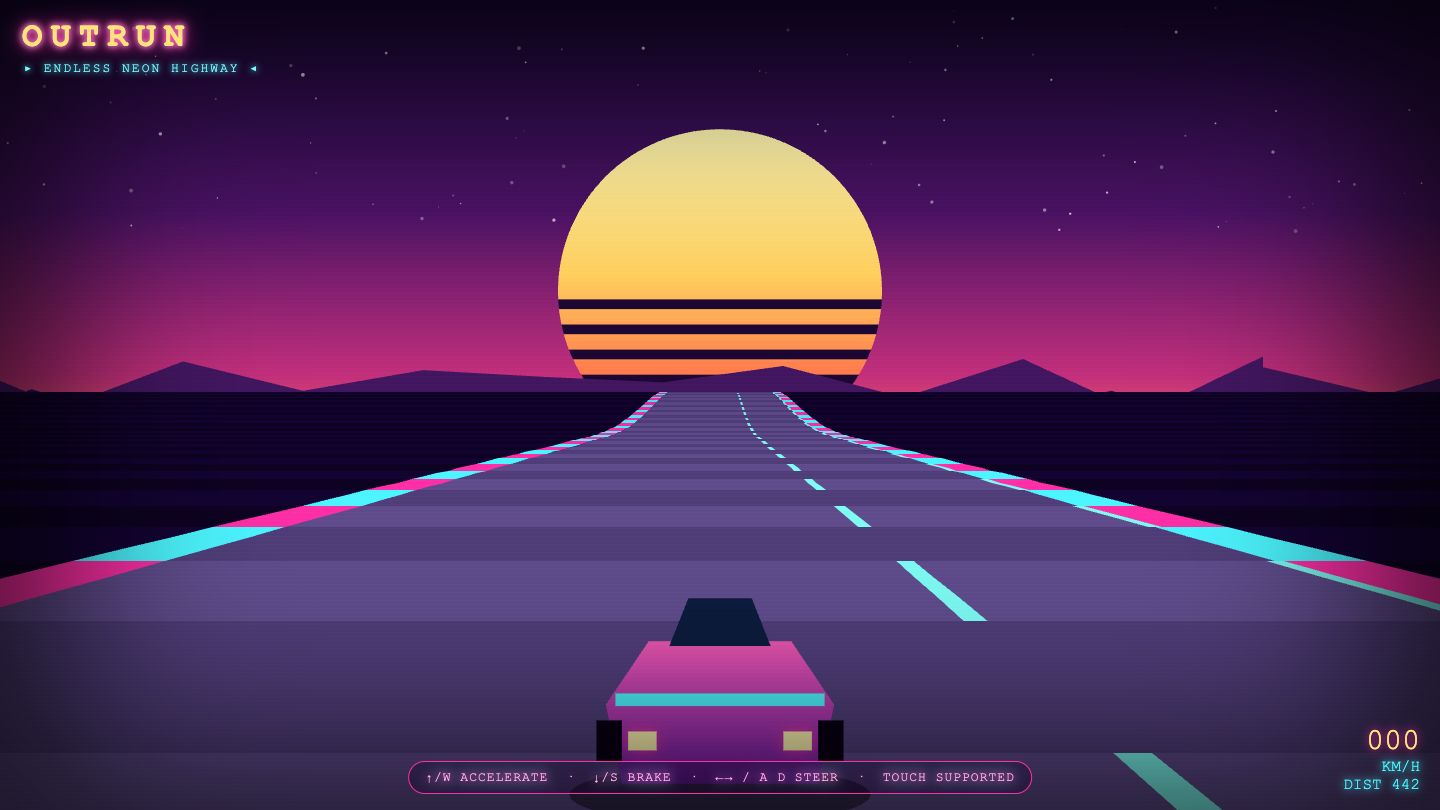
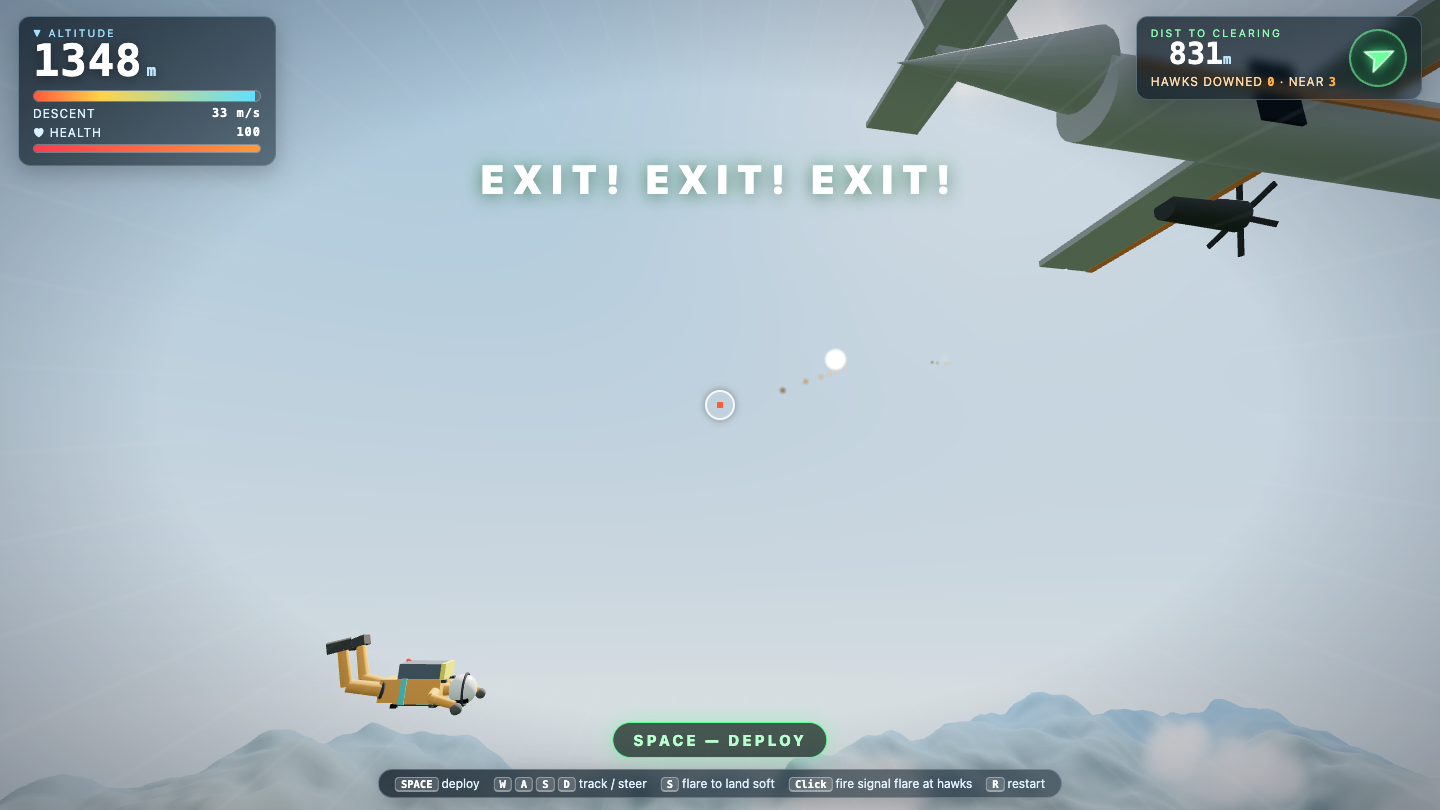
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
Claude Opus 5.5
Claude Sonnet 5
Game
Game
Game
Game
Game
Game
Game
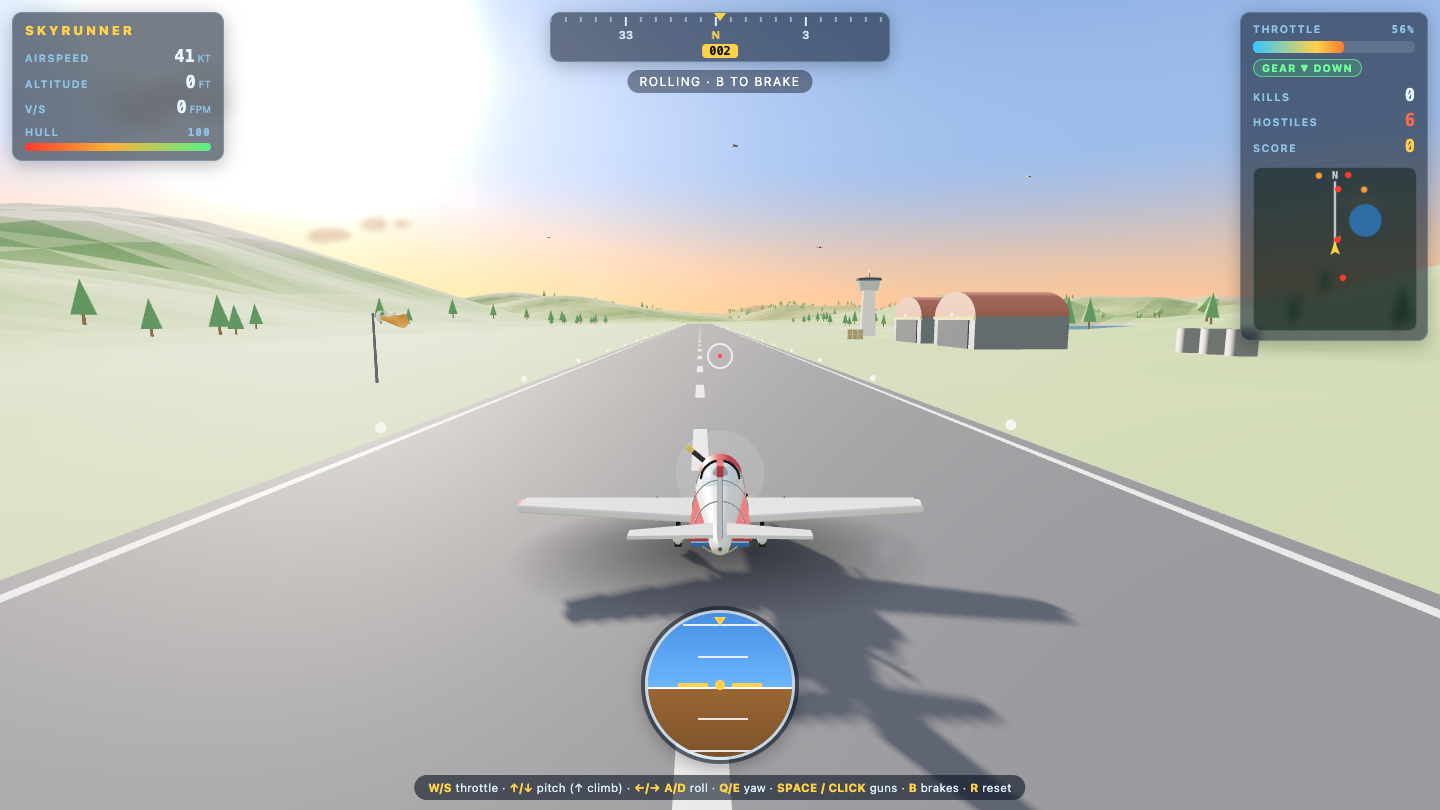
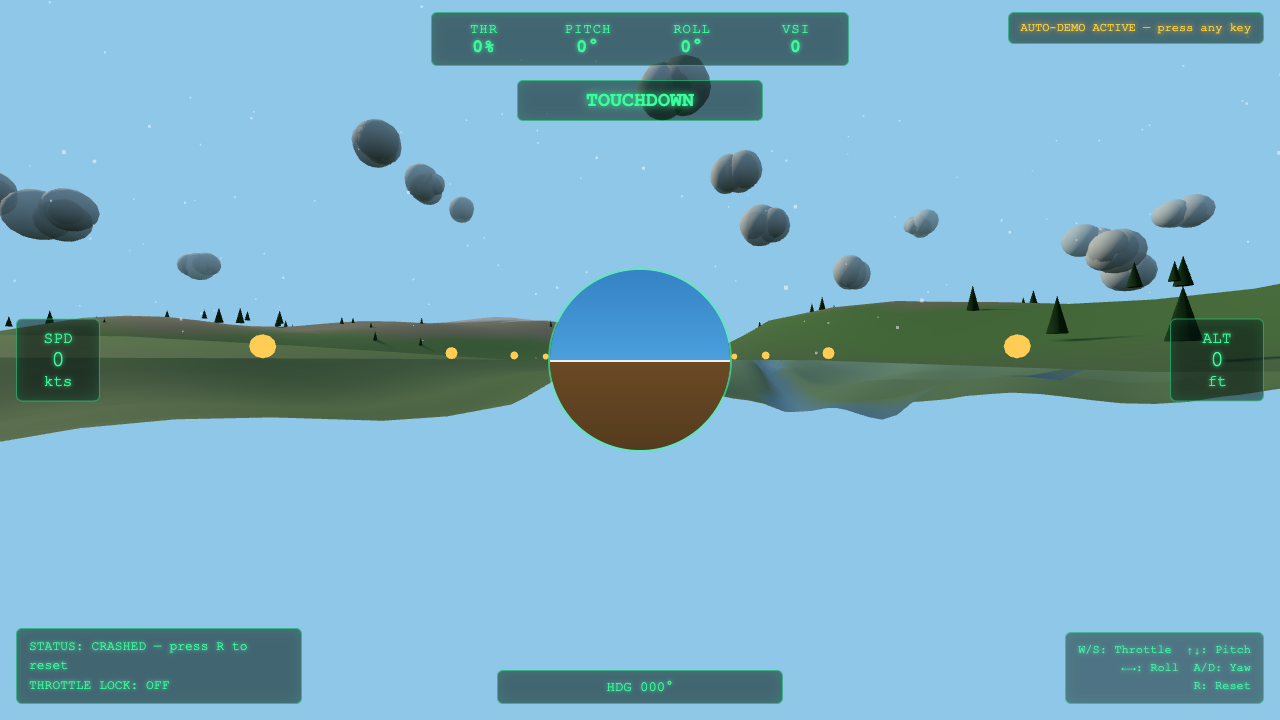
Game
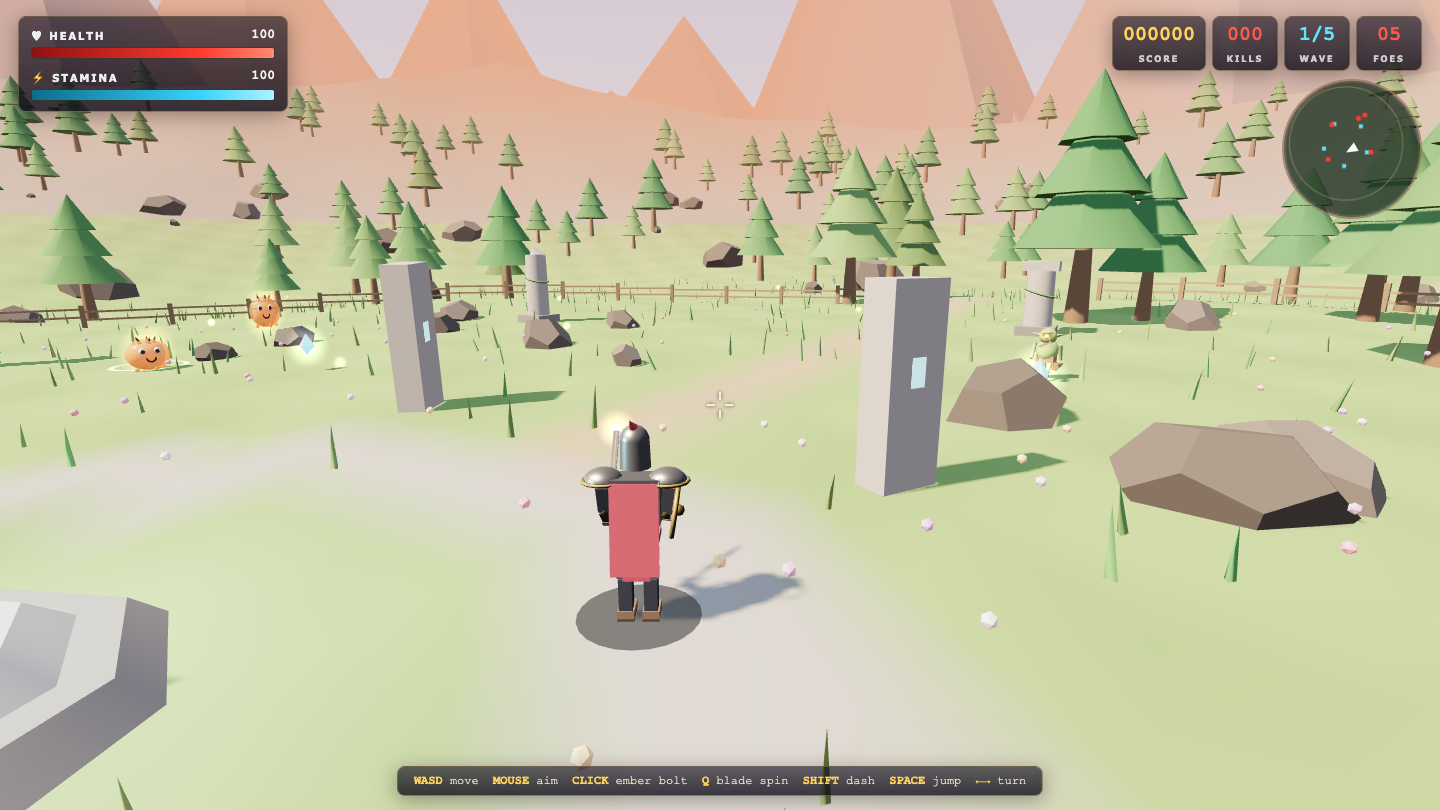
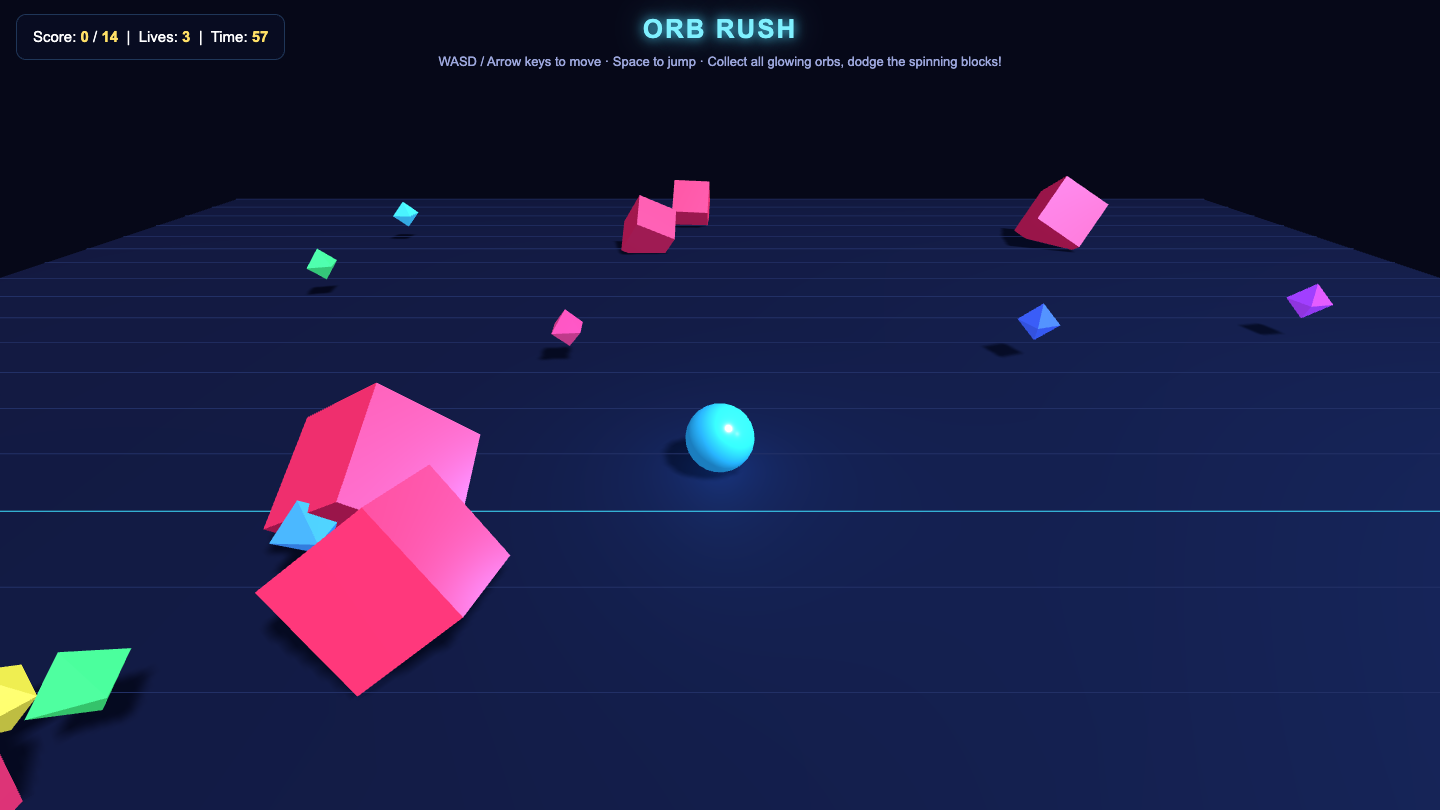
Game
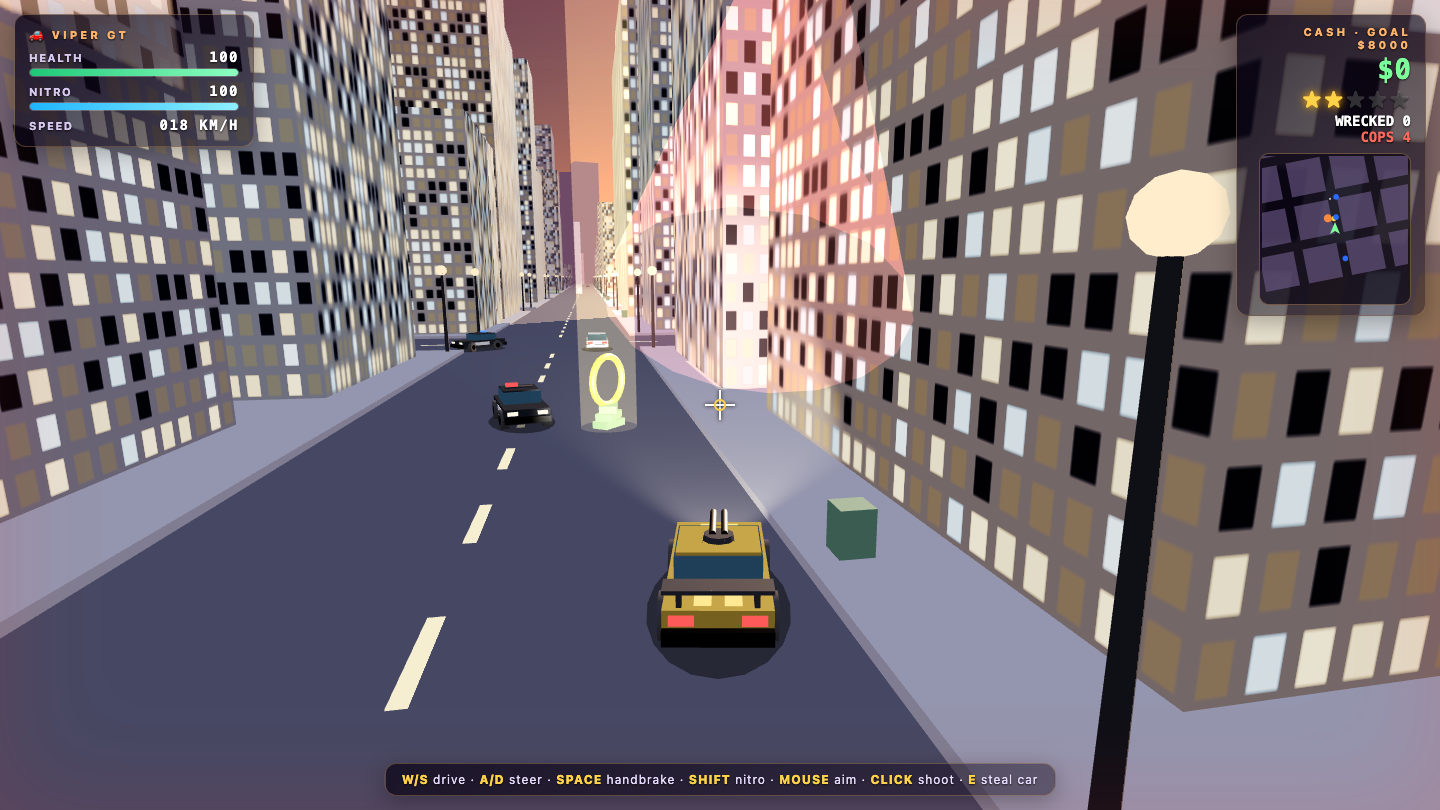
Game
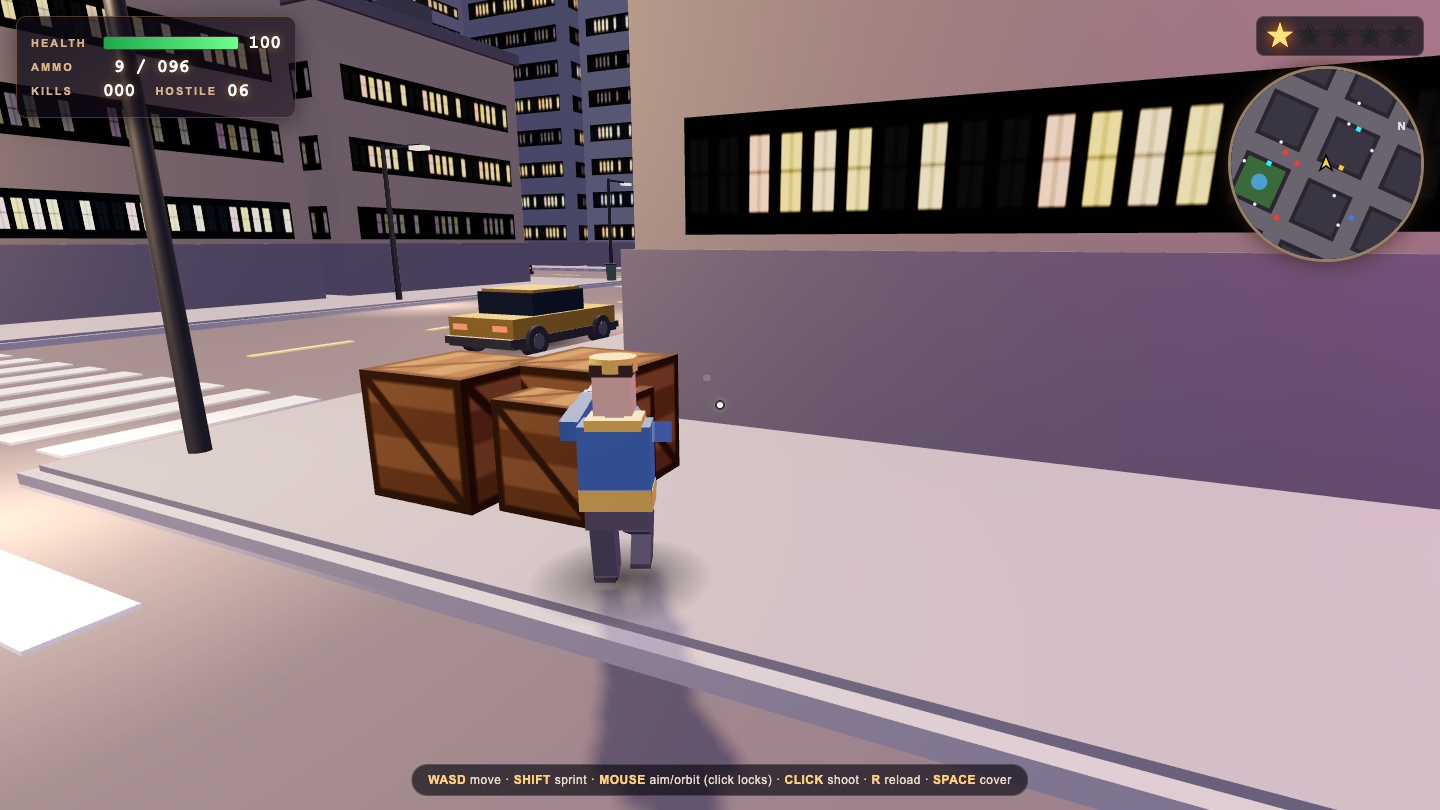
Game
Game
Game
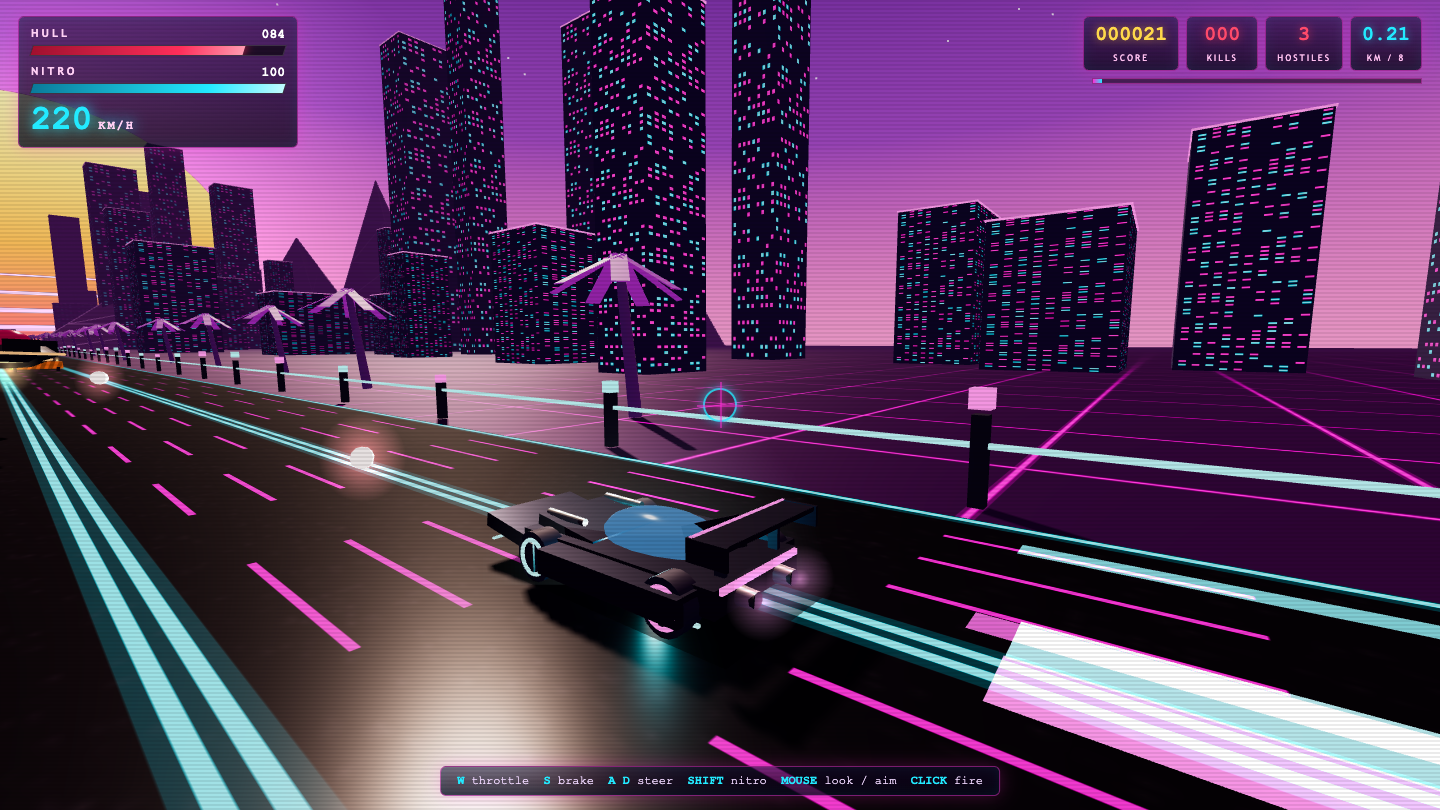
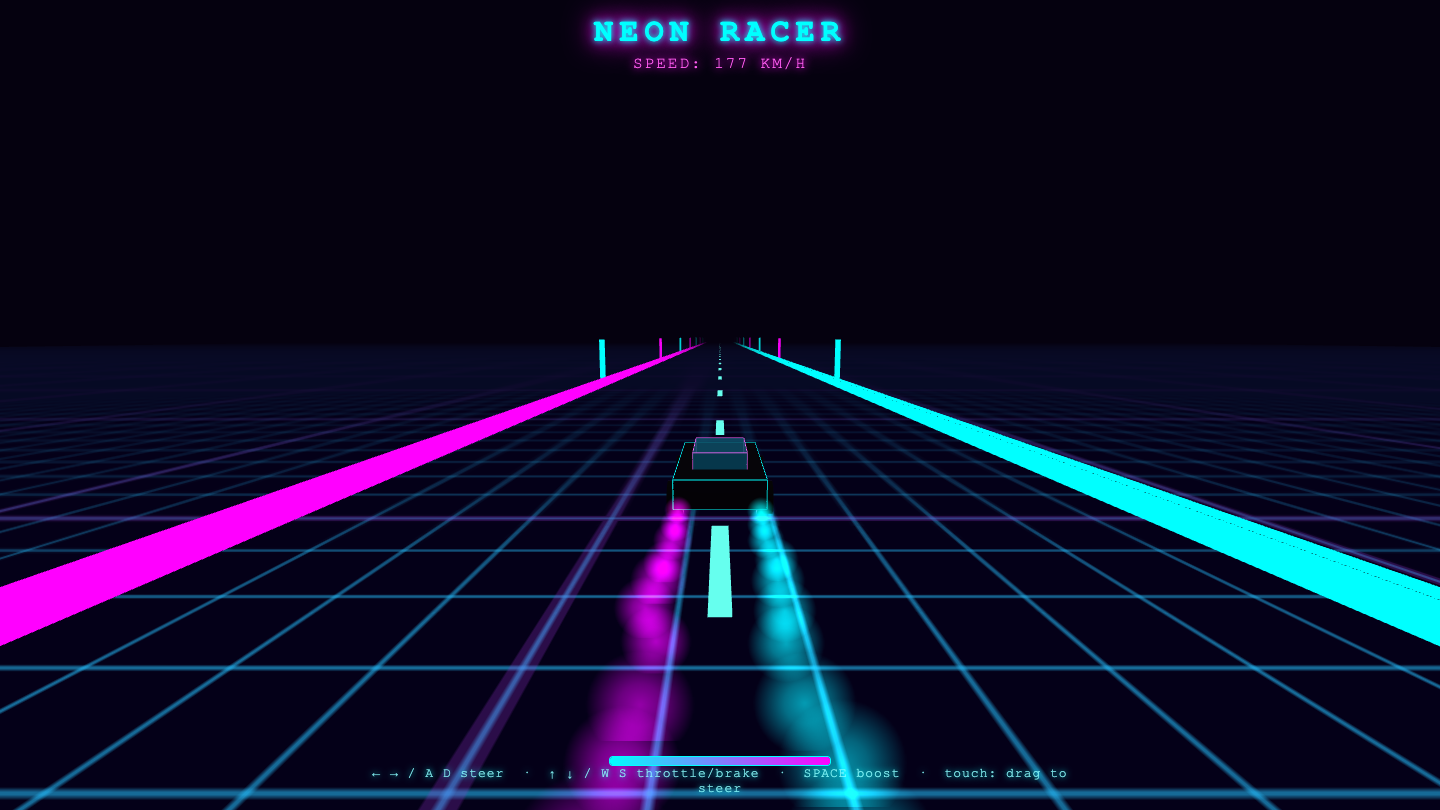
Game
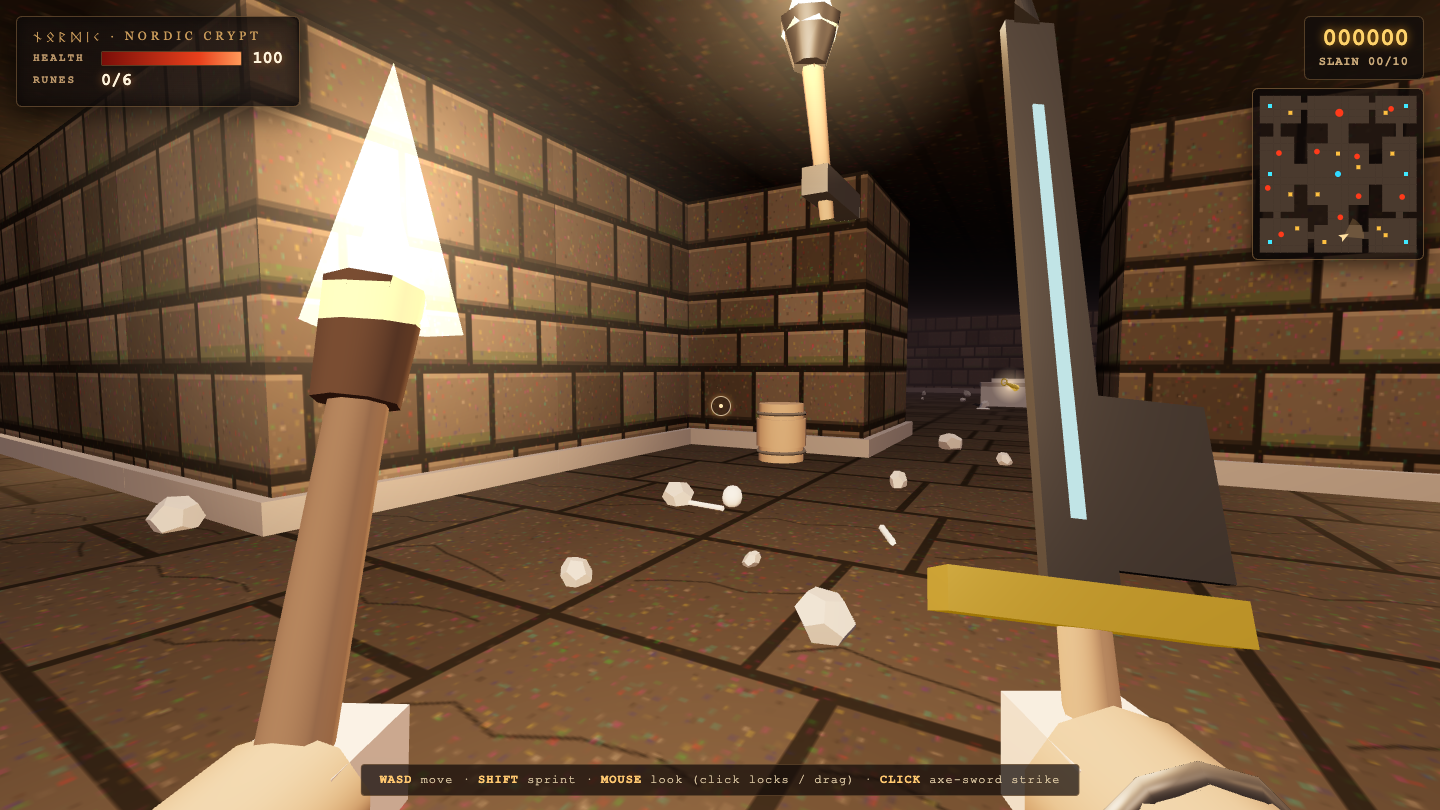
Game
Game
Game
Game
Game
Game
Game
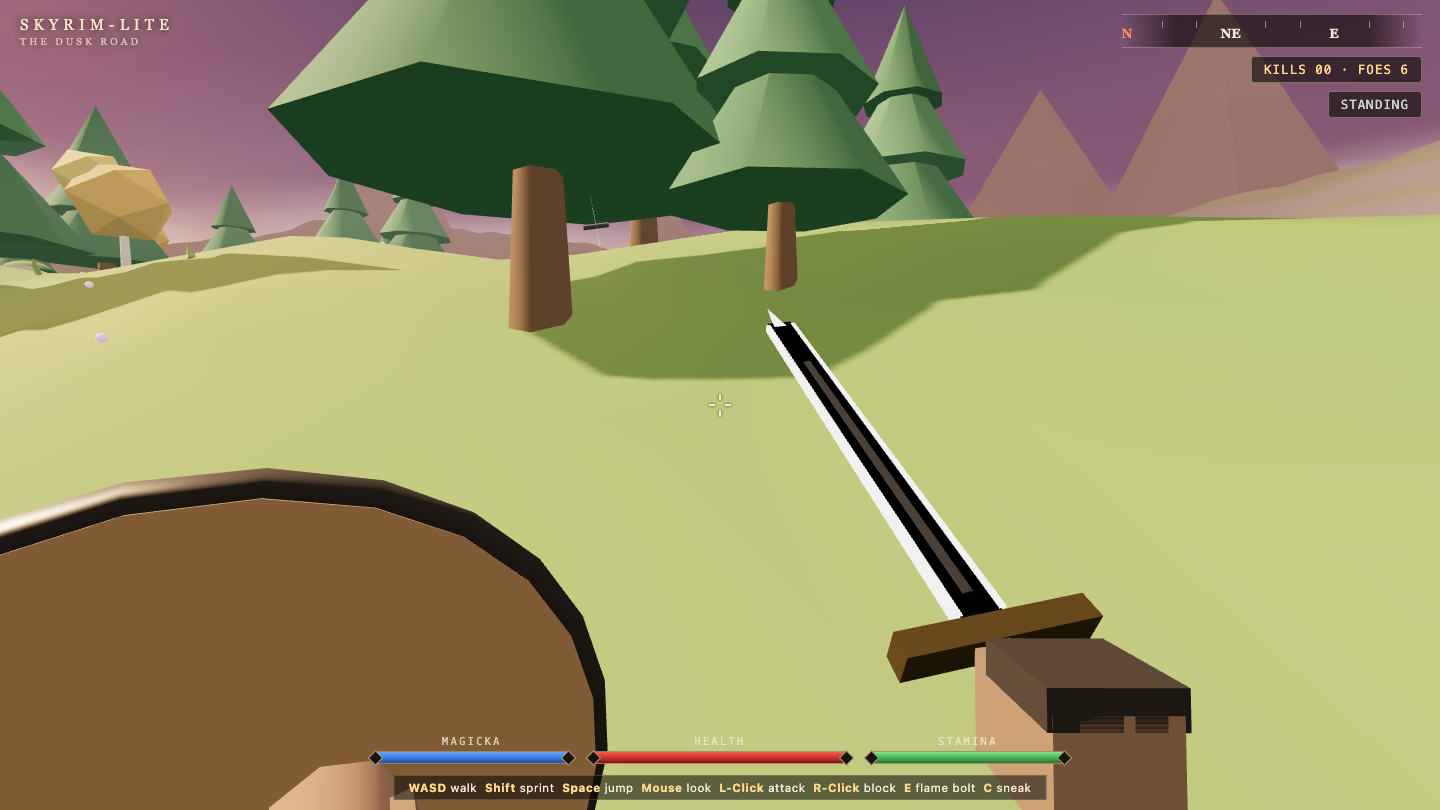
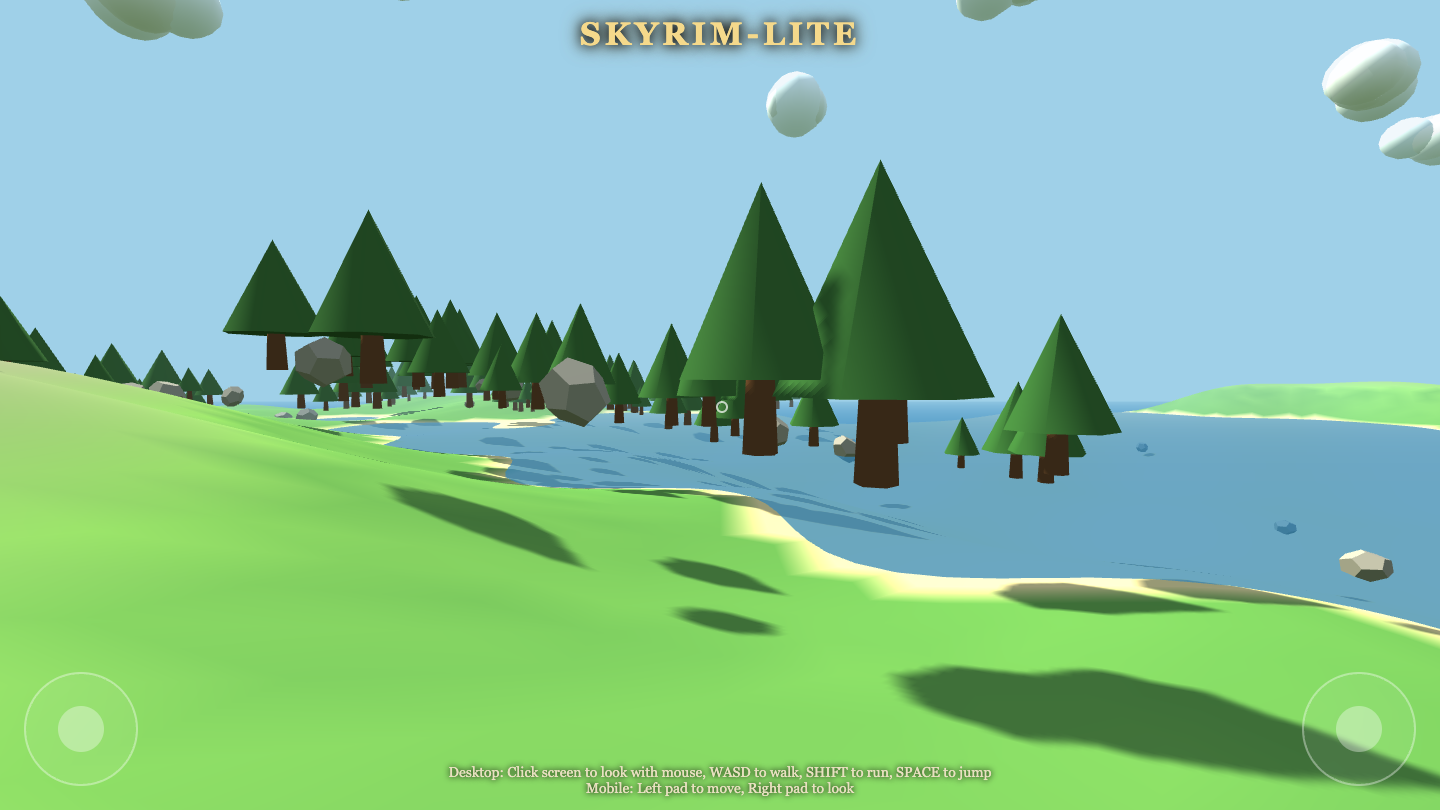
Game
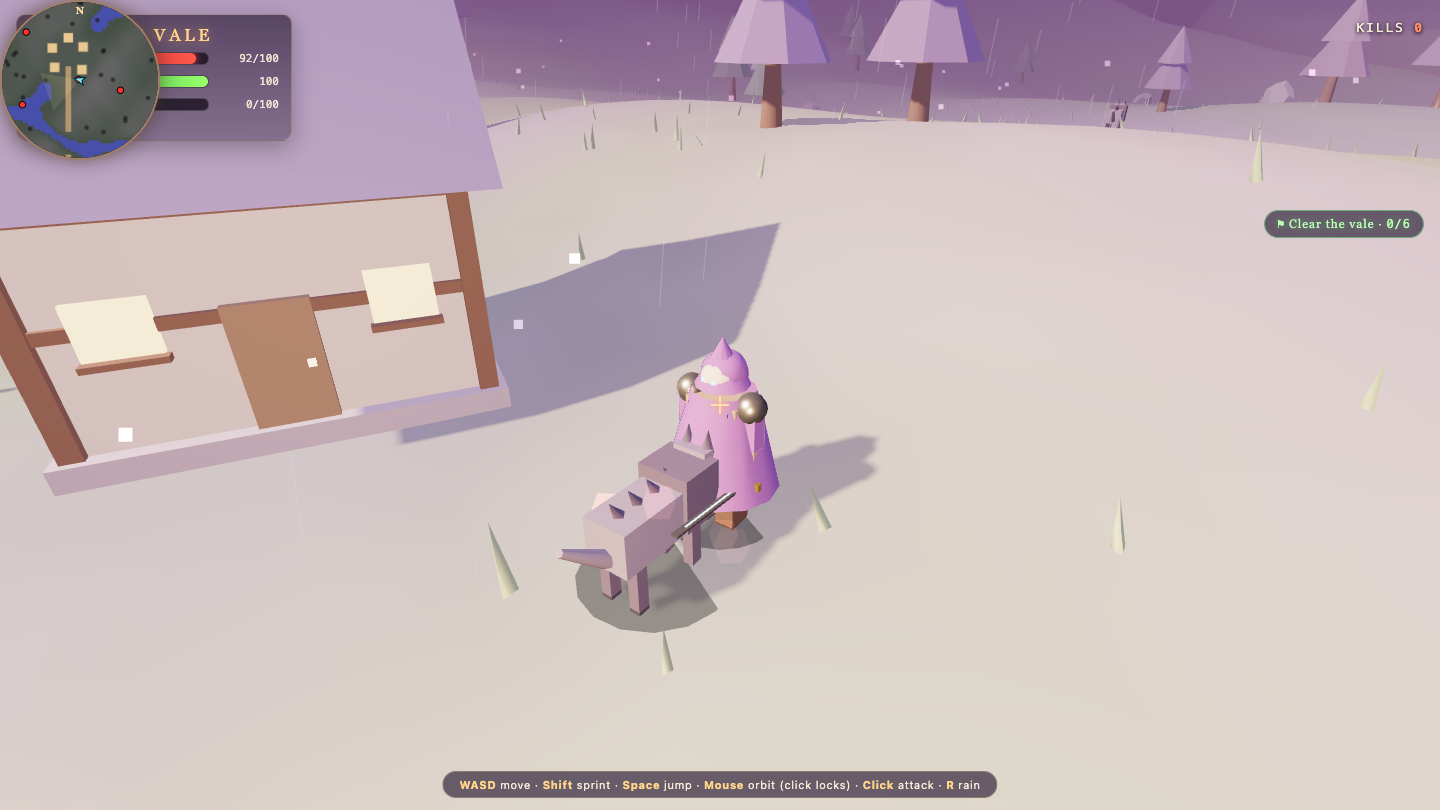
Game
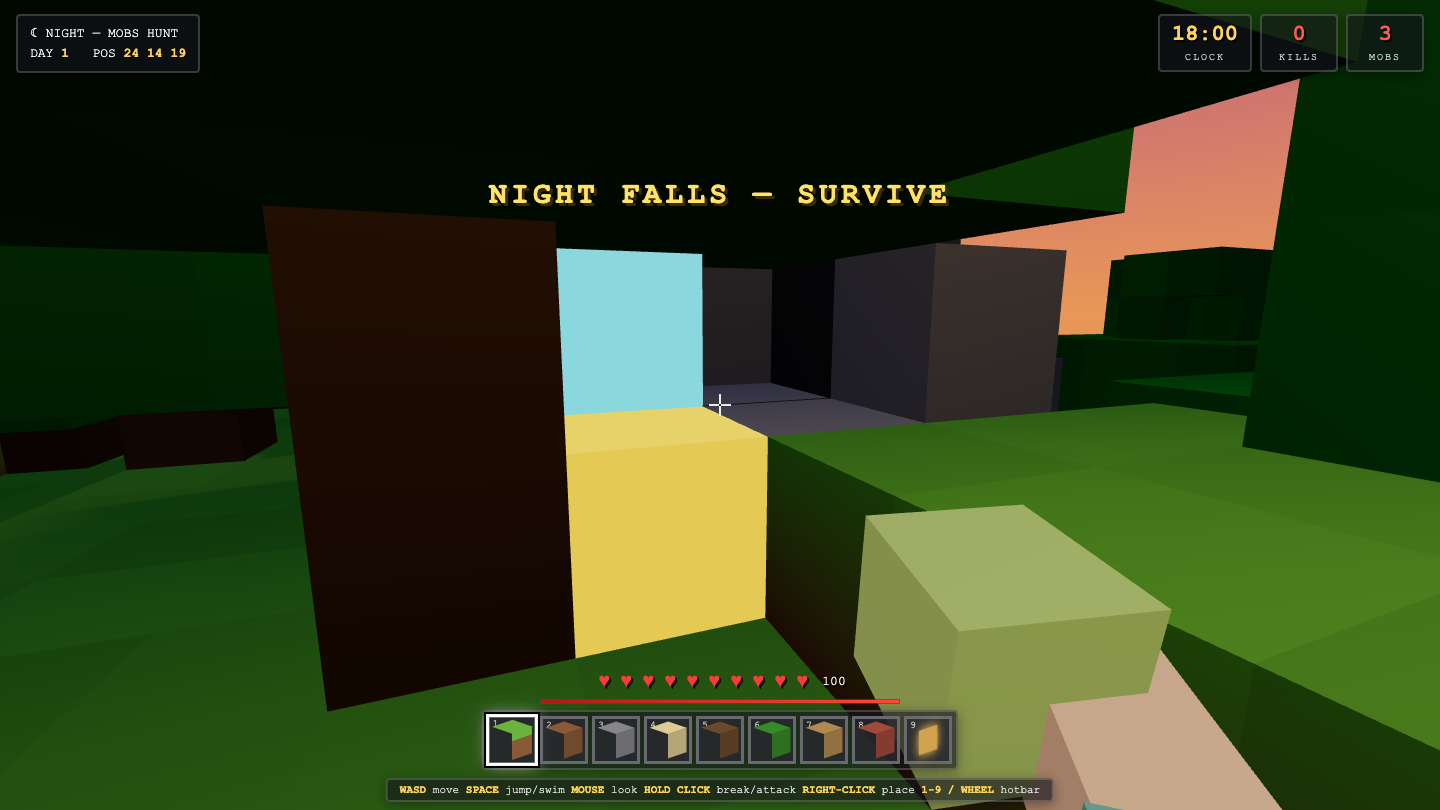
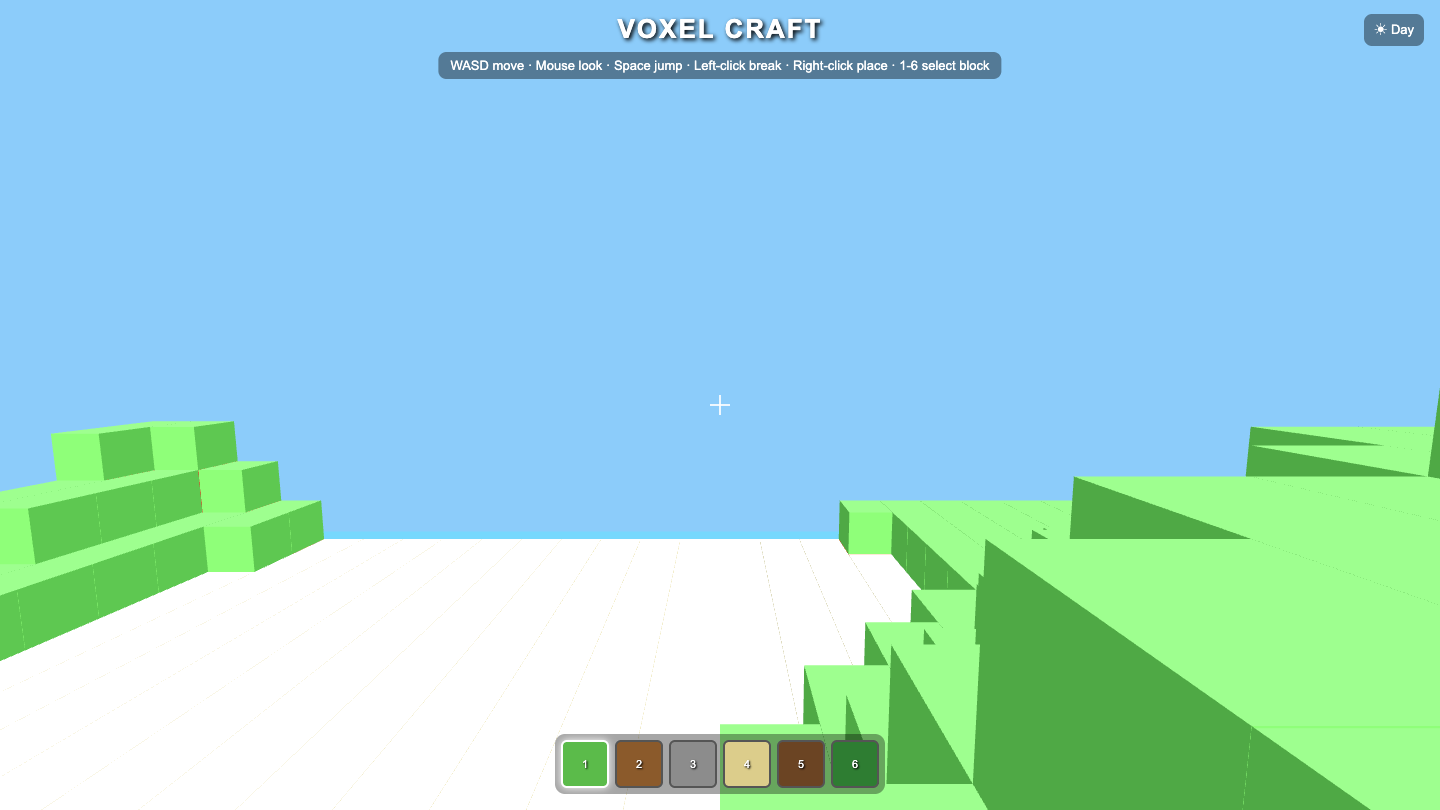
Page
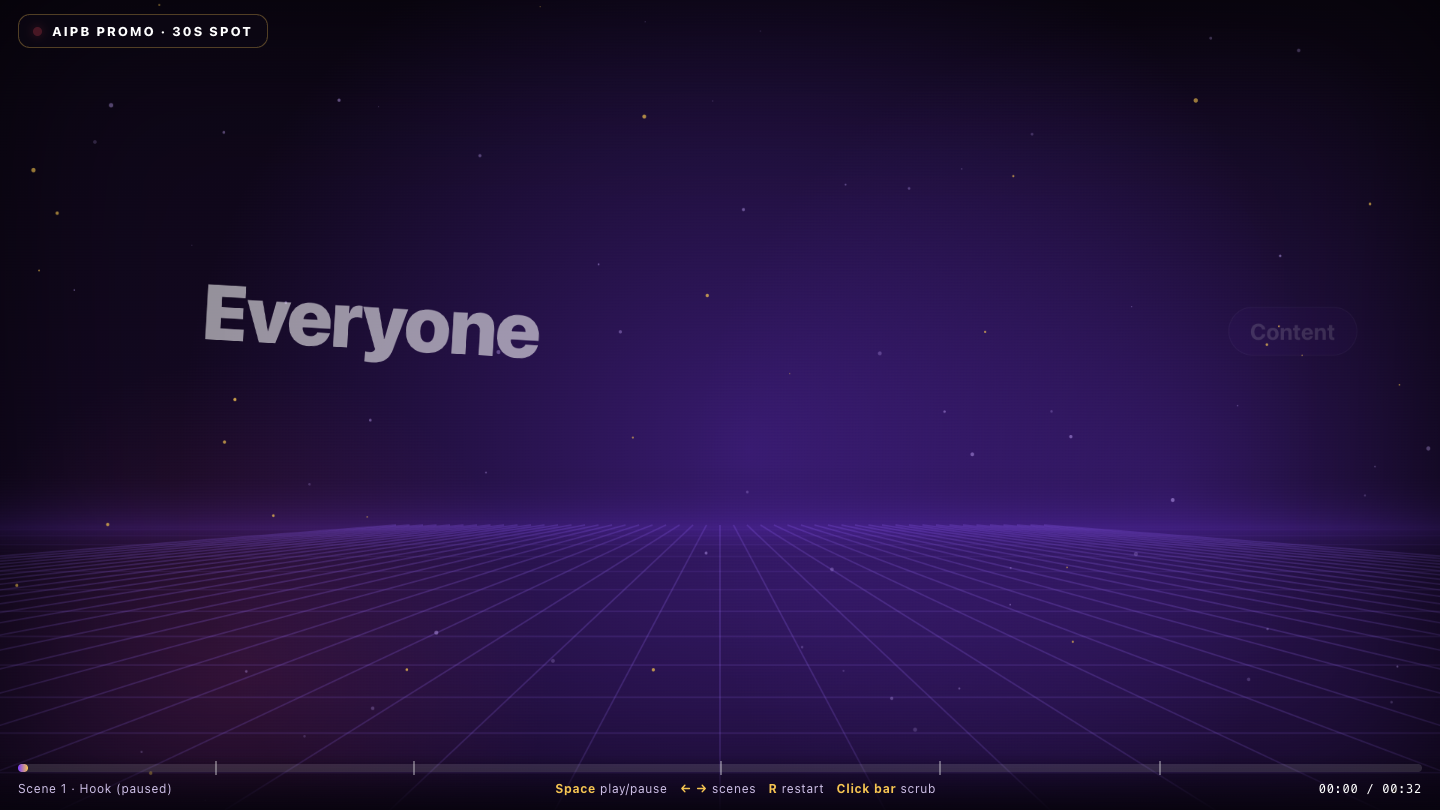
Where Claude Opus 5.5 beat Claude Sonnet 5
The tasks where I gave Claude Opus 5.5 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Aurora
Visual
Claude Opus 5.5 8.4
·
Claude Sonnet 5 2.5
(+5.9)
What I saw: Lovely low-poly valley: layered shader aurora curtains, snowy peaks, a glowing cabin and a mirror lake reflection, plus palette and substorm controls. The foreground snow is a flat, overexposed cyan band that eats the bottom third of the frame.
Solar
Sim
Claude Opus 5.5 8.4
·
Claude Sonnet 5 2.5
(+5.9)
What I saw: Accurate live Keplerian orrery driven by JPL J2000 elements: sqrt/true-distance scale toggle, asteroid belt, ringed Saturn, time controls and a real data panel, all in a polished UI. Planets are tiny at this zoom and the view is a fairly standard top-down orrery.
Wormhole
Sim
Claude Opus 5.5 8.3
·
Claude Sonnet 5 3.0
(+5.3)
What I saw: Striking glowing lattice tunnel with real depth, sector themes, velocity/distance HUD, warp and barrel roll, and it is clean and on-brief. The bloom is heavy enough to blow out the outer frame, and it is just short of the field best.
Orbit
Sim
Claude Opus 5.5 8.2
·
Claude Sonnet 5 3.5
(+4.7)
What I saw: Strong N-body sim: leapfrog integrator, energy-drift readout, 5 scenarios (figure-8, galaxy collision), trails and a click-to-add planet/star, all in a clean cohesive HUD over a glowing polar grid. The scene is a little sparse and dim at this zoom.
Blackhole
Sim
Claude Opus 5.5 8.8
·
Claude Sonnet 5 5.0
(+3.8)
What I saw: Striking real ray-marched Schwarzschild lensing: the Einstein ring bends over the top, the photon ring is thin and bright, the disk is Doppler-beamed and the streaked starfield looks good; controls are clean. Right up with the field's best, though the disk's banded ripple texture…
Where Claude Sonnet 5 beat Claude Opus 5.5
The tasks where I gave Claude Sonnet 5 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Neonblaster
Game
Claude Sonnet 5 8.3
·
Claude Opus 5.5 5.8
(+2.5)
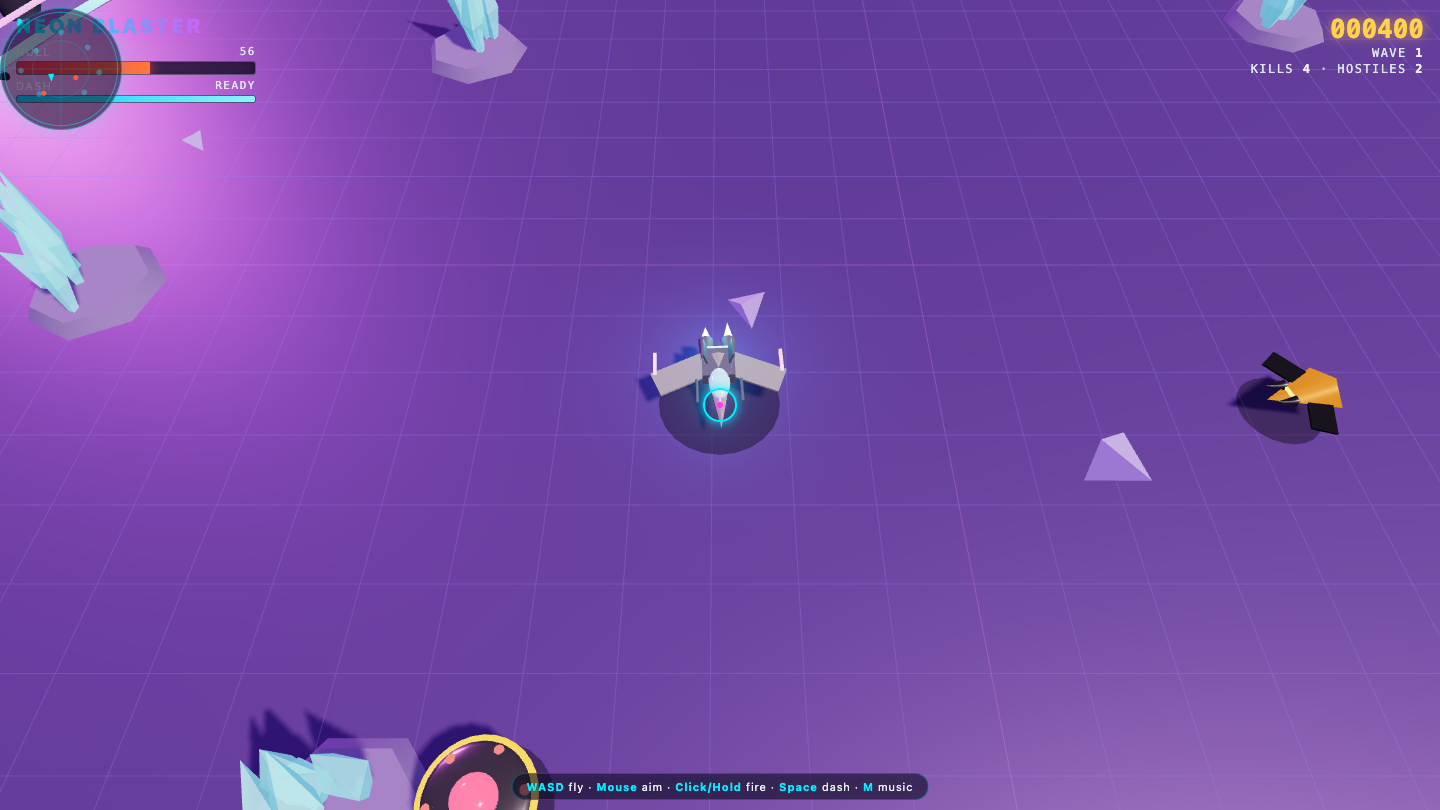
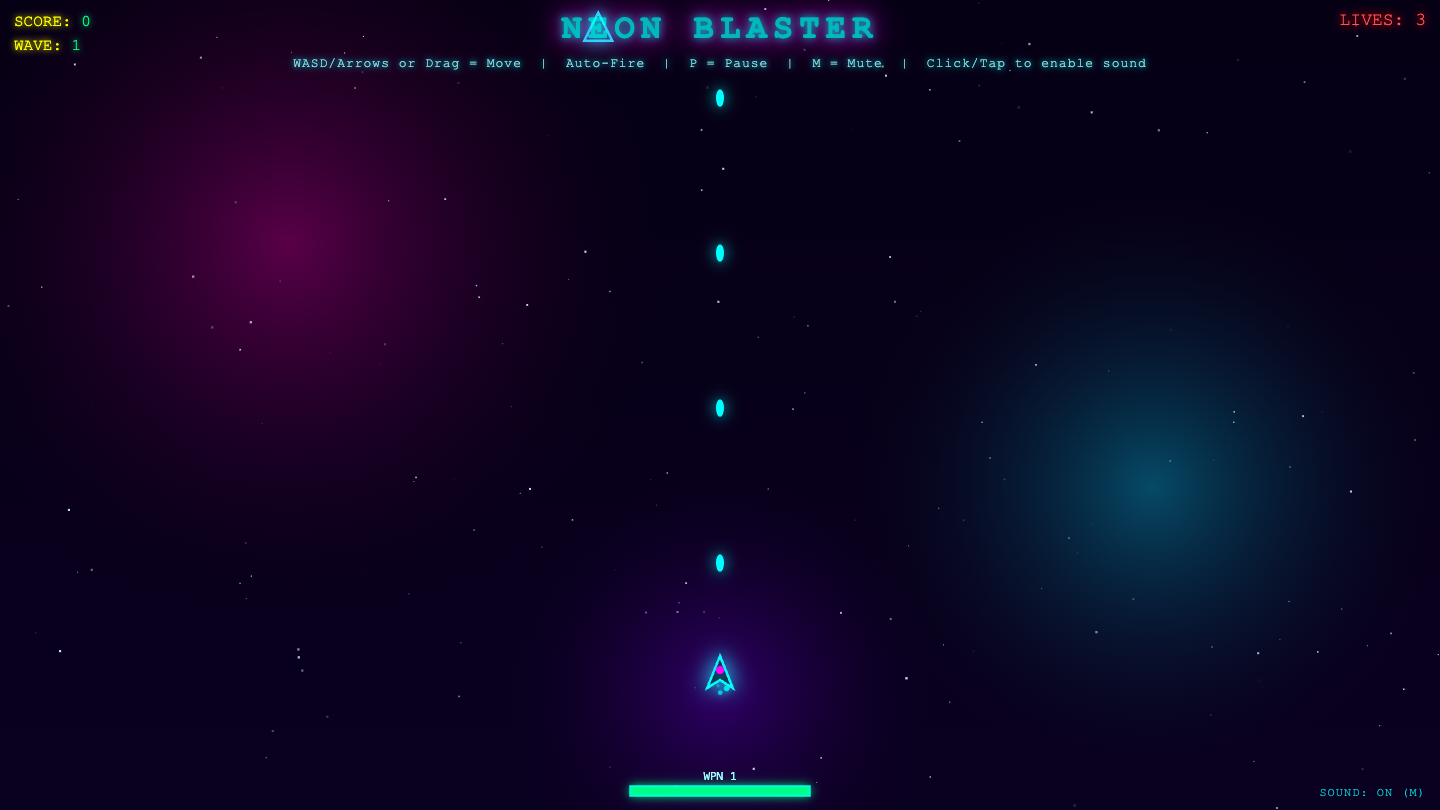
What I saw: Strong neon aesthetic with glowing nebulae, layered starfield, polished ship and auto-fire bullets, plus a full feature set (waves, bosses, power-ups, synth sequencer, screen-shake); the screenshot looks clean and on-brief but reads a touch sparse/quiet early on versus the flashi…
Doom
Game
Claude Sonnet 5 8.0
·
Claude Opus 5.5 5.8
(+2.2)
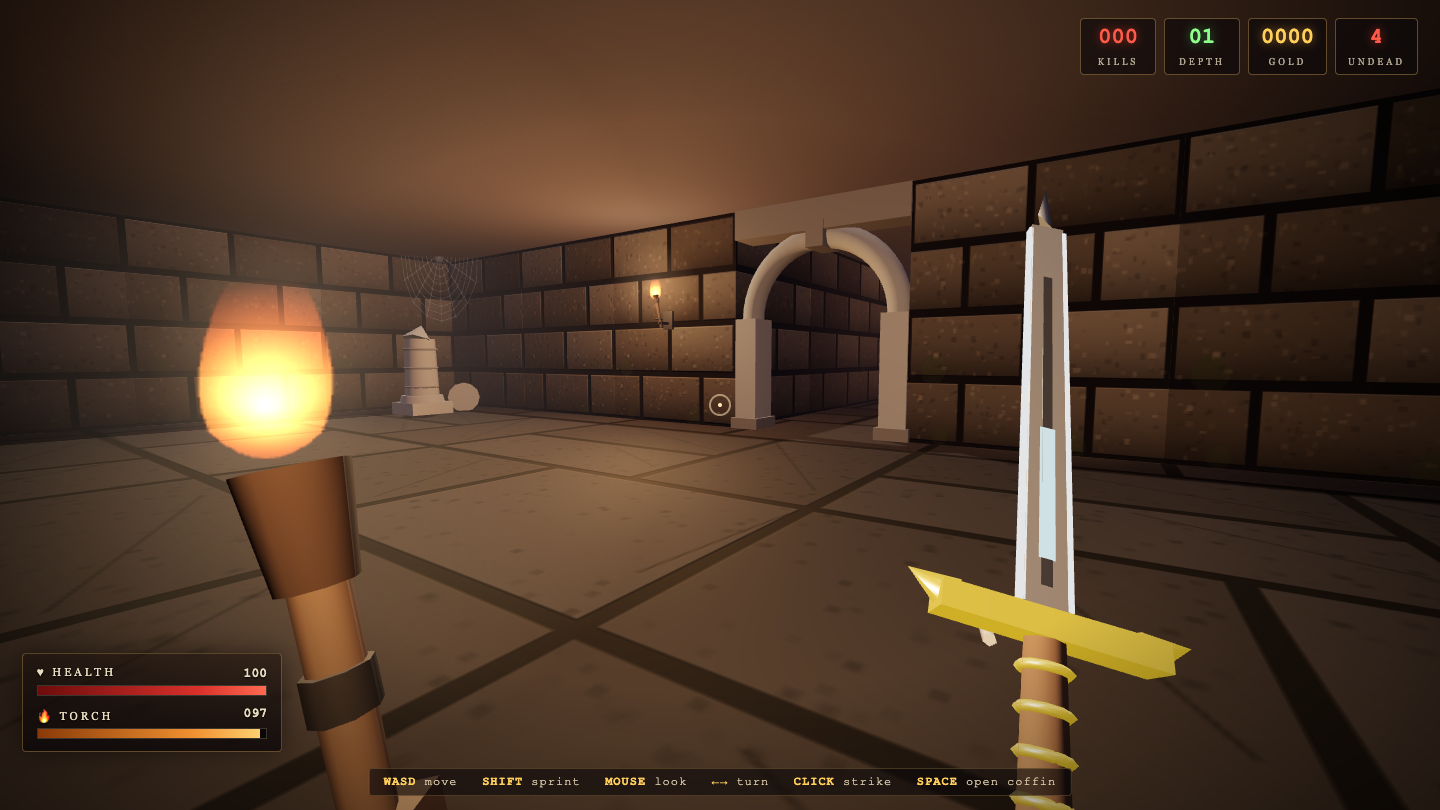
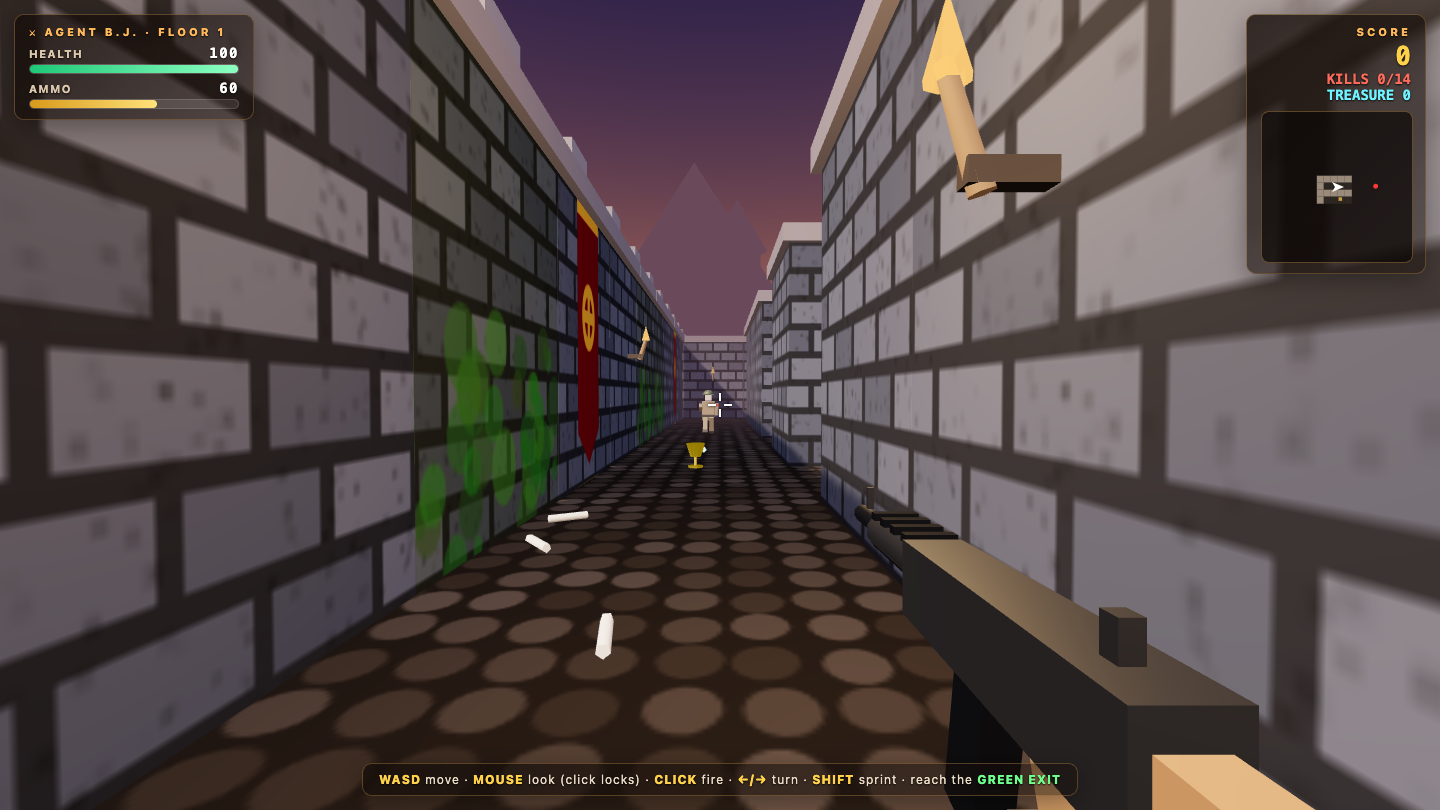
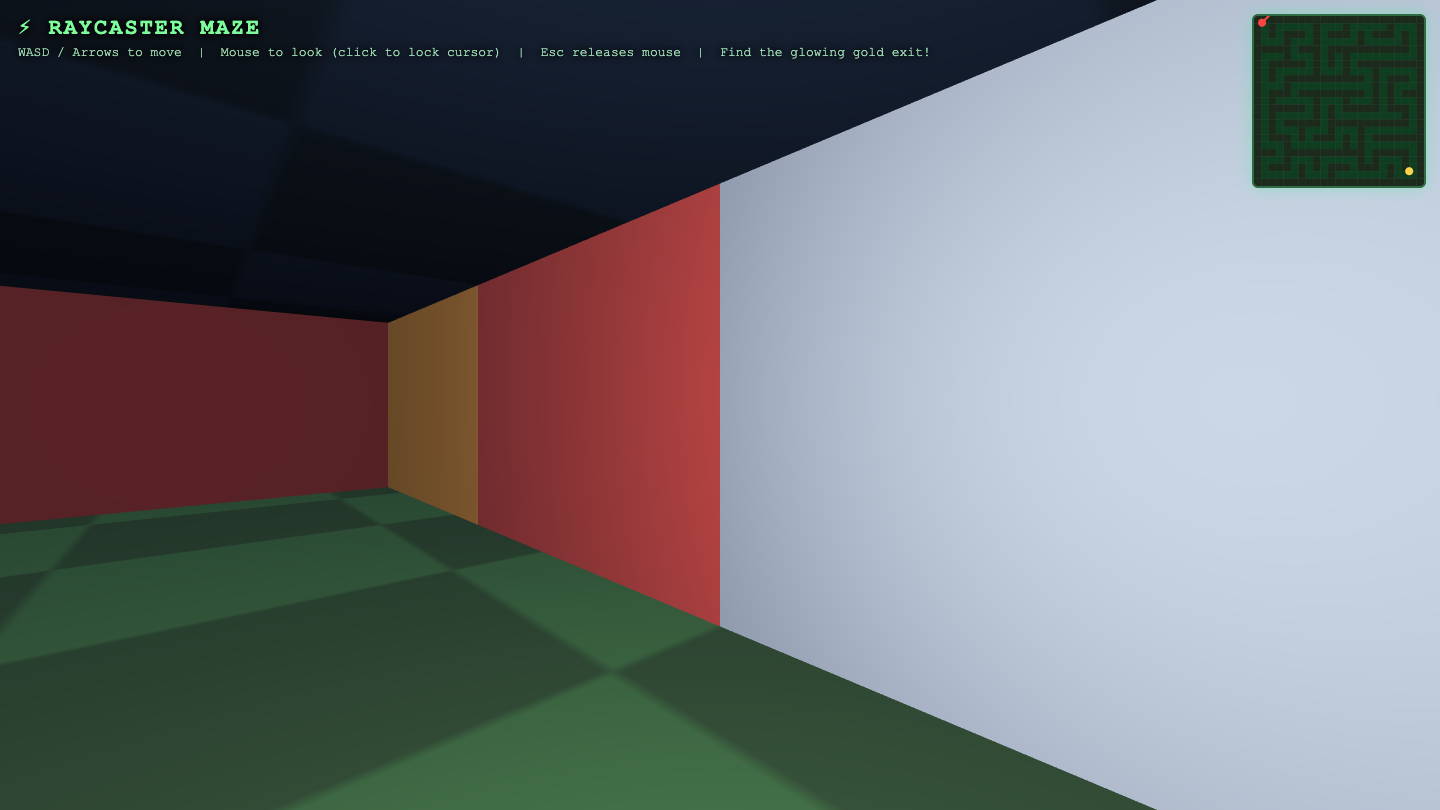
What I saw: Renders a clean raycaster maze with atmospheric red-lit walls, working minimap, HUD health/kills bar, crosshair and a monster visible at screen edge; solid feature set (hitscan shooting, chasing AI, damage flash, touch controls) makes it strong and shippable, though the wall shad…
Arcade
Game
Claude Sonnet 5 8.2
·
Claude Opus 5.5 6.0
(+2.2)
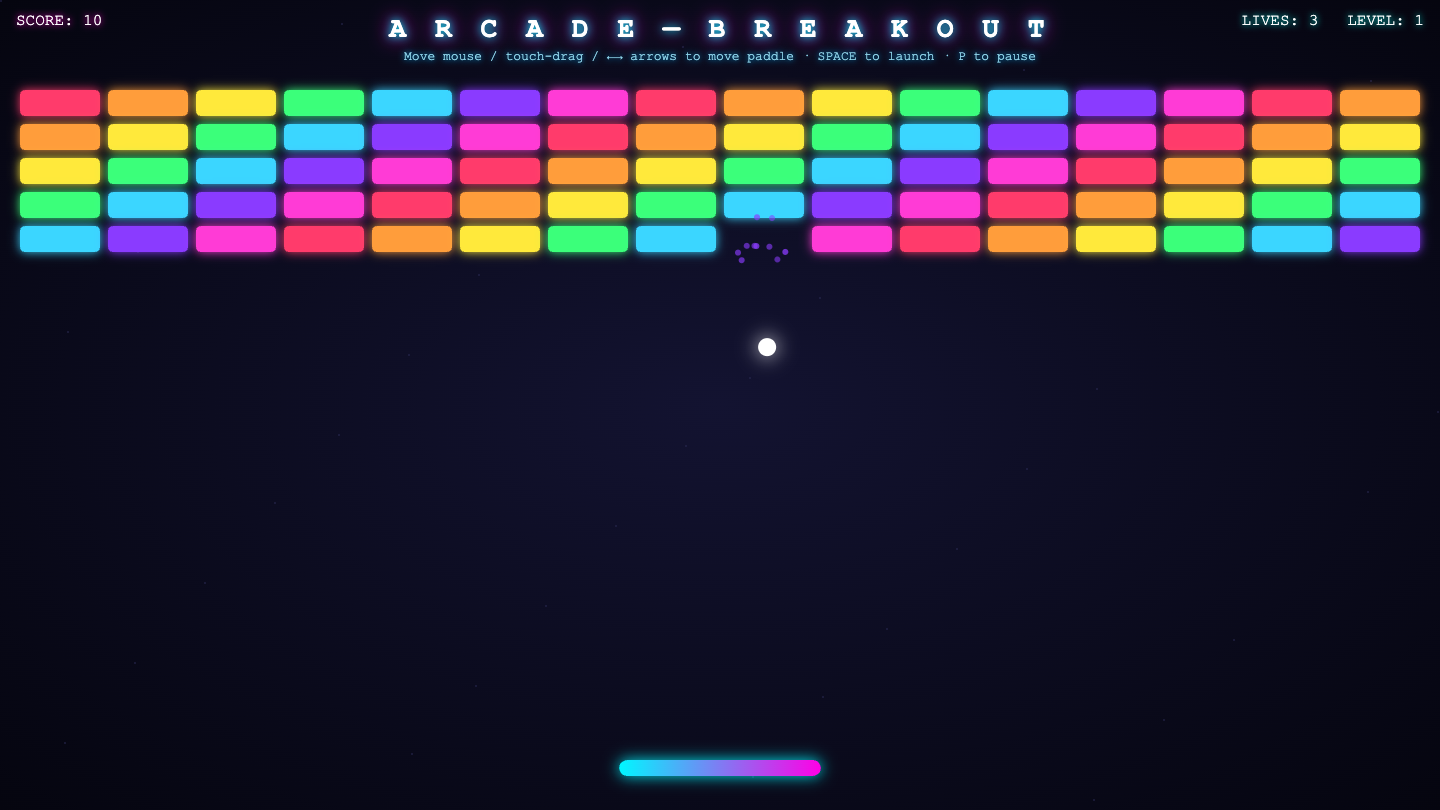
What I saw: Clean, polished neon Breakout that renders perfectly with glowing bricks, gradient paddle, particle bursts, and a live in-progress state (score 10, a brick already cleared). Solid physics with side-aware collisions and level scaling, but it's a well-executed take on the most comm…
Rpg
Game
Claude Sonnet 5 7.4
·
Claude Opus 5.5 5.5
(+1.9)
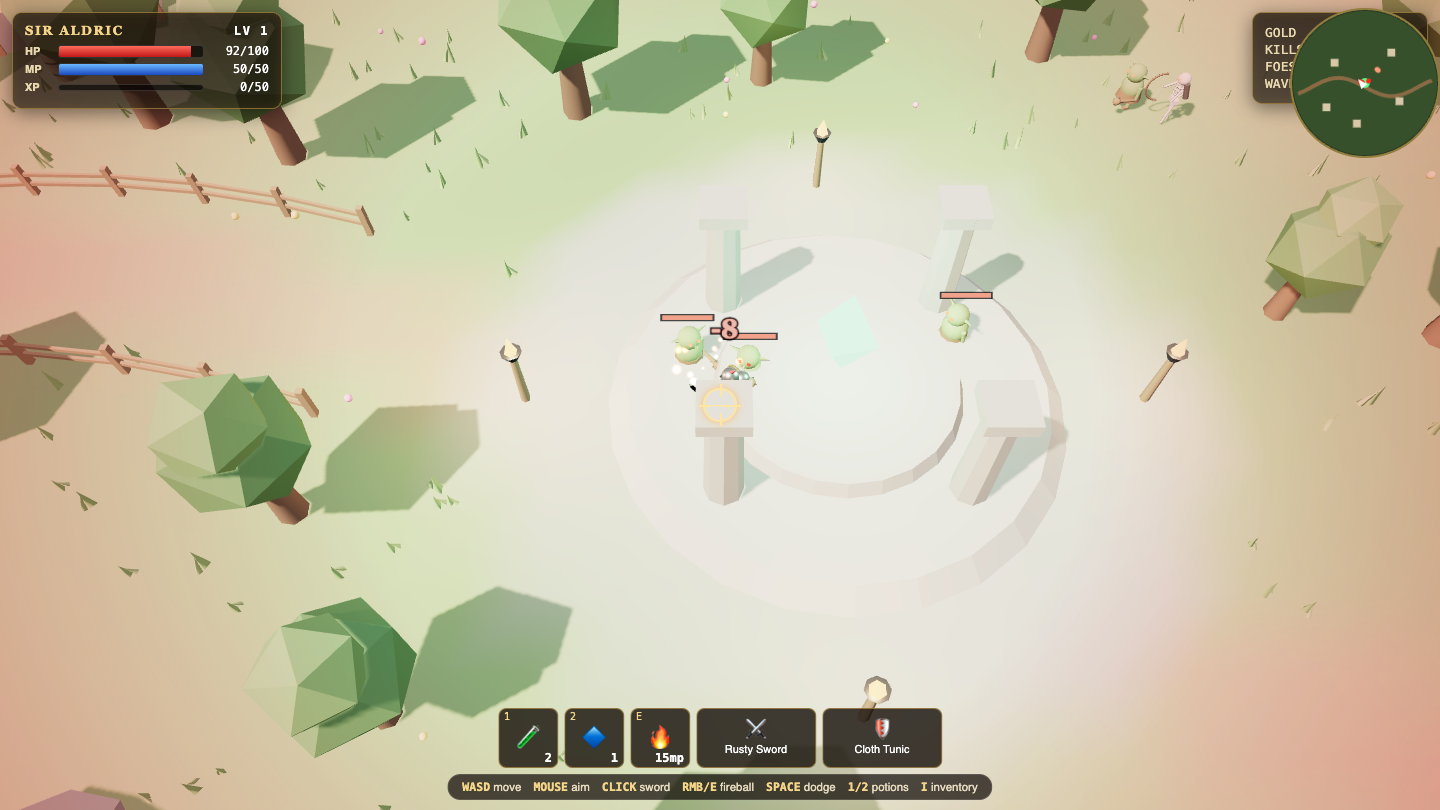
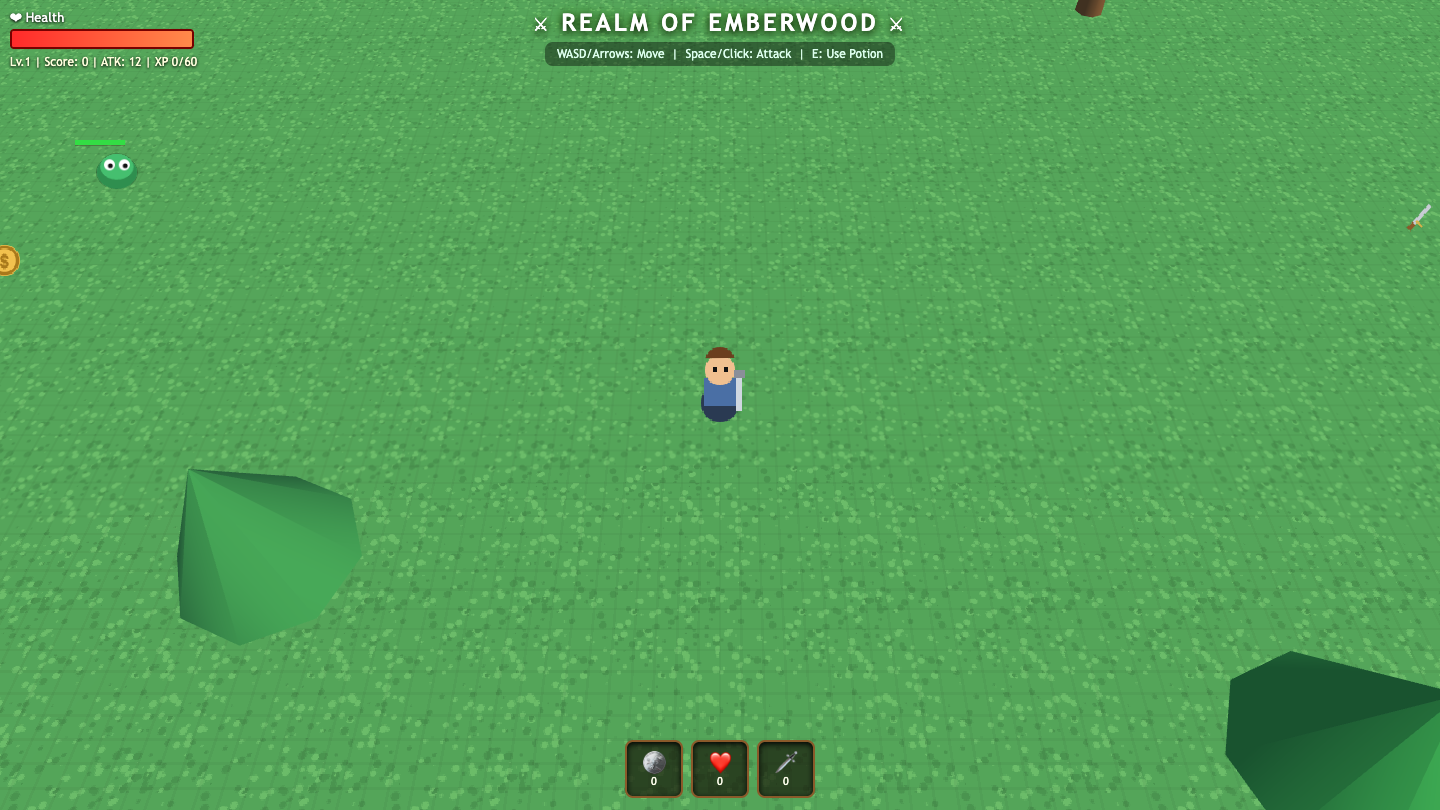
What I saw: Clean render with a readable 3D top-down world—billboard player/slime sprites, HP bar, XP, inventory slots and clear controls all present and on-brief; but the scene feels sparse/empty with sprawling green fields, few obstacles and no visible combat action, keeping it solid-shipp…
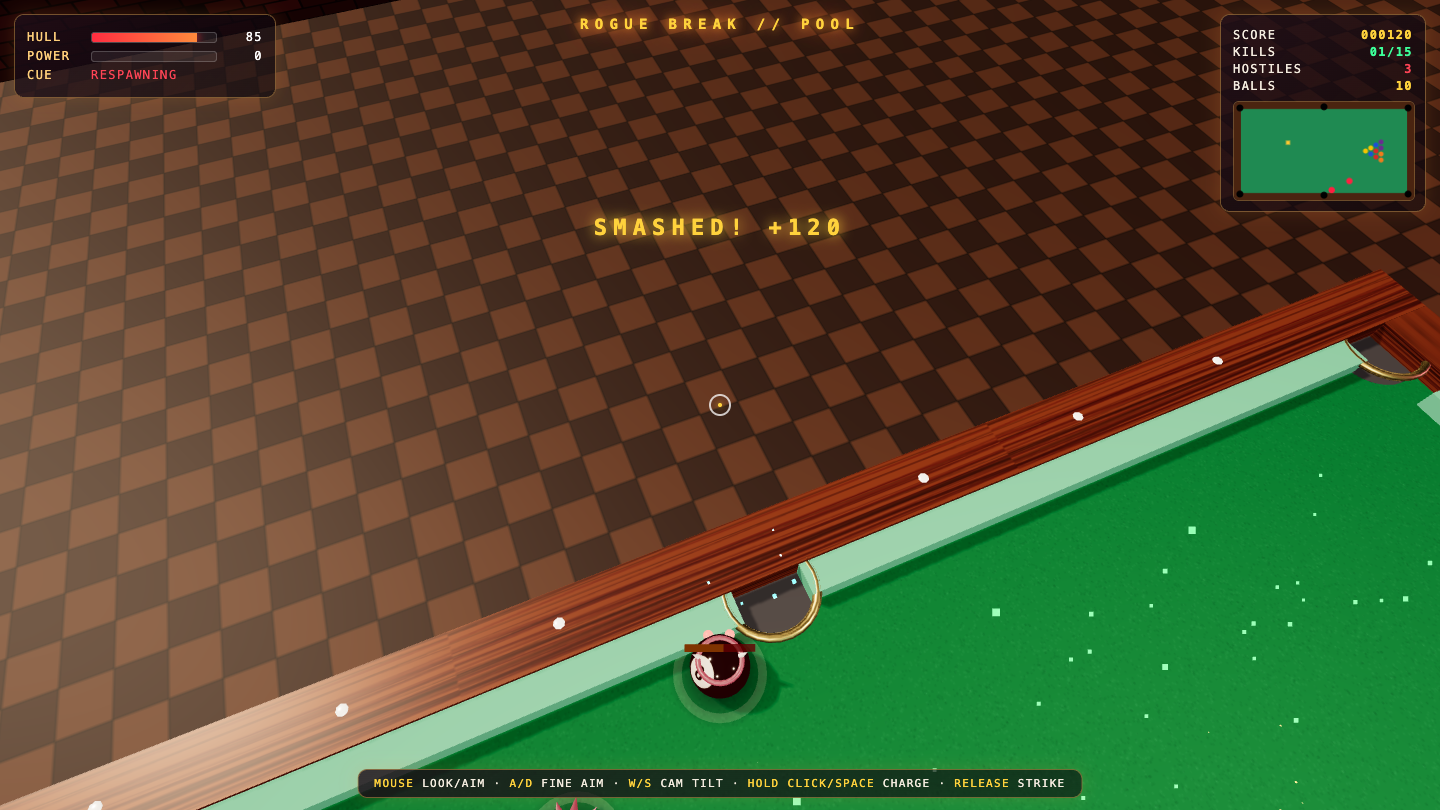
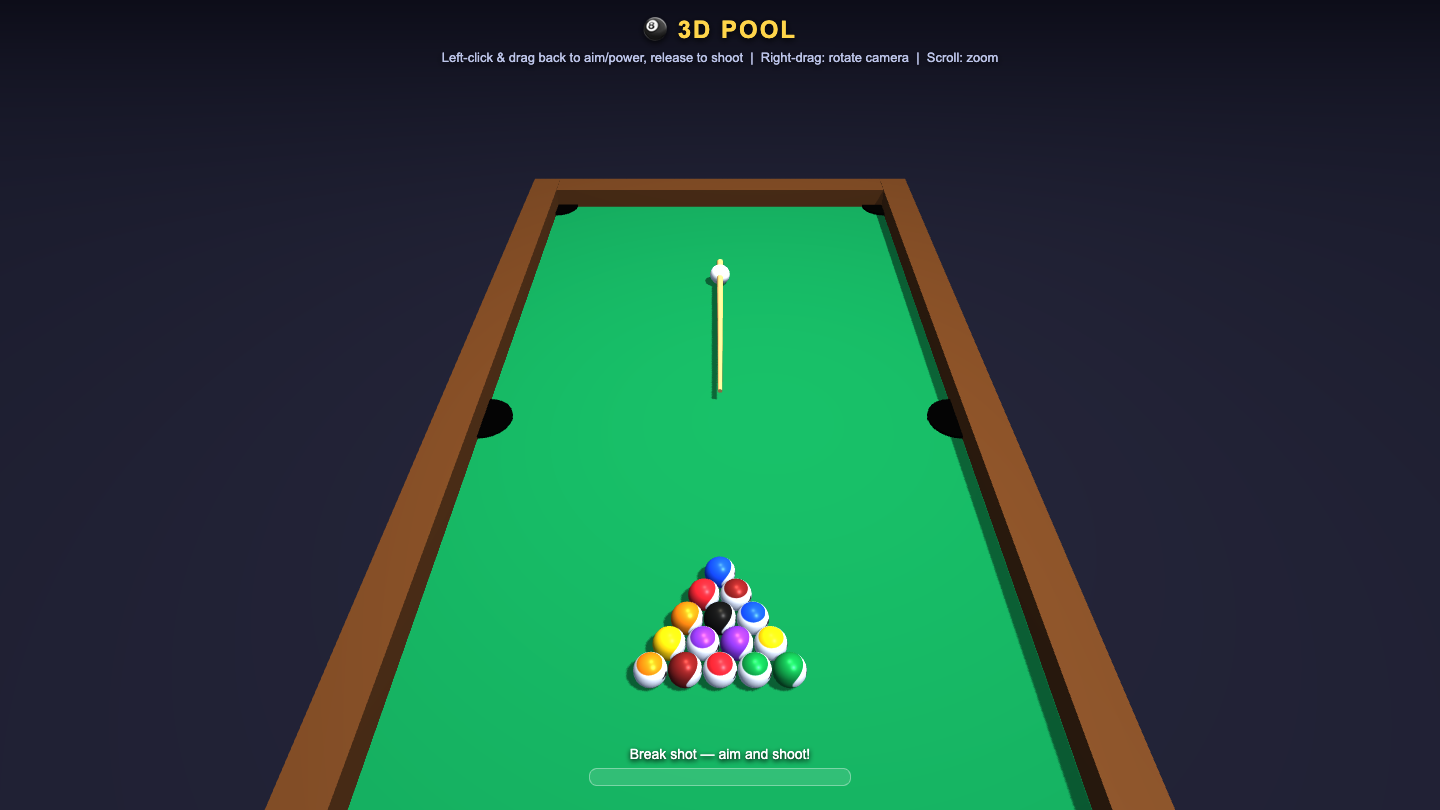
Pool
Game
Claude Sonnet 5 8.2
·
Claude Opus 5.5 6.3
(+1.9)
What I saw: Clean 3D render with proper racked triangle, numbered/striped ball textures, cue stick aiming, pockets and power bar—clearly on-brief and polished. Solid physics-oriented setup but visually generic versus a task winner, and the shadowing under the rack looks a bit off.
Strengths & weaknesses I logged
Claude Opus 5.5
Strengths
- Frontier-class coding + agentic reasoning (Claude 5 family)
- 1M-token context — reads an entire codebase in one call
- All 50 one-shot builds rendered with zero console errors; all 23 games passed the input playtest
Trade-offs
- Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes
- One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts)
Claude Sonnet 5
Strengths
- 82.1% SWE-bench Verified — first model past 80% on real GitHub-issue repair
- Dev Team multi-agent mode + 1M context for repo-level agentic work
- Precision on hard logic — won the raycaster the open-weight field kept botching
Trade-offs
- One-shot creative-visual builds trail GLM 5.2 here (lost 4 of 5) — no iteration to catch its own bugs
- A temporal-dead-zone bug blanked its N-body orbit sim on the first shot
Pricing & context — the spec sheet
| Spec | Claude Opus 5.5 | Claude Sonnet 5 |
|---|---|---|
| Vendor | Anthropic | Anthropic |
| Context window | 1,000,000 tokens | 1,000,000 tokens |
| Price | $4 / $20 per M | $3 / $15 per M ($2/$10 intro) |
| Pricing detail | Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. | $3.00 input / $15.00 output per million tokens; introductory $2.00/$10.00 through 2026-08-31. |
| Release | 2026-09 | 2026-06-30 |
| Bench coverage | 50/50 scored · avg 7.57/10 | 47/47 scored · avg 7.01/10 |
The verdict — which should you pick?
Across 47 scored shared tasks, Claude Opus 5.5 averaged 7.60/10, beating Claude Sonnet 5's 7.01/10 by 0.58 points. Pick Claude Opus 5.5 when the build has to ship on the first prompt and you can afford the trade-offs in the comparison below.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire Claude Opus 5.5 and Claude Sonnet 5 both into the Agent Operating System and dispatch each from the kanban by task type — hardest agentic builds → Claude Opus 5.5, agentic software engineering — write / run / test / fix loops on real repos → Claude Sonnet 5. That's the same setup I run for the 4,000+ founders inside the AI Profit Boardroom.
FAQ — Claude Opus 5.5 vs Claude Sonnet 5
Which is better, Claude Opus 5.5 or Claude Sonnet 5?
On Goldie Bench, Claude Opus 5.5 averages 7.60/10 across the shared tasks, with 0 gold, 0 silver, 1 bronze overall. Claude Sonnet 5 averages 7.01/10, with 0 gold, 0 silver, 4 bronze. Claude Opus 5.5 wins the head-to-head 24–23.
How much does Claude Opus 5.5 cost vs Claude Sonnet 5?
Claude Opus 5.5: Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. Claude Sonnet 5: $3.00 input / $15.00 output per million tokens; introductory $2.00/$10.00 through 2026-08-31.
What's the context window for Claude Opus 5.5 vs Claude Sonnet 5?
Claude Opus 5.5 has a 1,000,000 tokens context window. Claude Sonnet 5 has a 1,000,000 tokens context window.
When should I pick Claude Opus 5.5 over Claude Sonnet 5?
Pick Claude Opus 5.5 for: Hardest agentic builds; Whole-repo reasoning; Frontier one-shots. The trade-off is the weaknesses we logged on the bench: Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes; One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts).
When should I pick Claude Sonnet 5 over Claude Opus 5.5?
Pick Claude Sonnet 5 for: Agentic software engineering — write / run / test / fix loops on real repos; Repo-level reasoning across a 1M-token context (Dev Team multi-agent mode); Precise logic — raycasters, physics — where one-shot open models slip. The trade-off is the weaknesses we logged on the bench: One-shot creative-visual builds trail GLM 5.2 here (lost 4 of 5) — no iteration to catch its own bugs; A temporal-dead-zone bug blanked its N-body orbit sim on the first shot.
How does Goldie Bench score Claude Opus 5.5 vs Claude Sonnet 5?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
Claude Opus 5.5 vs Fusion Claude Sonnet 5 vs Fusion Claude Opus 5.5 vs Claude Opus 5 Claude Sonnet 5 vs Claude Opus 5 Claude Opus 5.5 vs Hermes MoA Claude Sonnet 5 vs Hermes MoA Claude Opus 5.5 vs GPT-5.6 Sol Claude Sonnet 5 vs GPT-5.6 SolFull model pages: Claude Opus 5.5 · Claude Sonnet 5 · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.
4,000+founders
258documented wins
38countries
$59/momonthly