Real head-to-head · same prompt, one shot
Claude Opus 5.5 vs MiMo-V2.6 Pro
Anthropic's Opus 5.5 — benched on all 50 one-shot builds, every game playtested. vs Open weights that score level with Opus 5 on agents, for cents.
Head-to-head verdict: MiMo-V2.6 Pro wins 29–20 with 1 tie.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to Claude Opus 5.5 and MiMo-V2.6 Pro, side by side, on 50 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
Claude Opus 5.5 · Benched on all 50 GoldieBench tasks via a Claude subscription: one-shot builds, real renders, pixel-diff playtests on every game, then vision-judged.
MiMo-V2.6 Pro · Benched on all 50 GoldieBench tasks through OpenRouter at the model's default reasoning effort: one-shot build, real rendered poster, Opus 4.8 vision judge, game tasks skill-infused. No retries, no hand fixes; the broken builds are scored as they shipped.
Side-by-side on 50 shared tasks
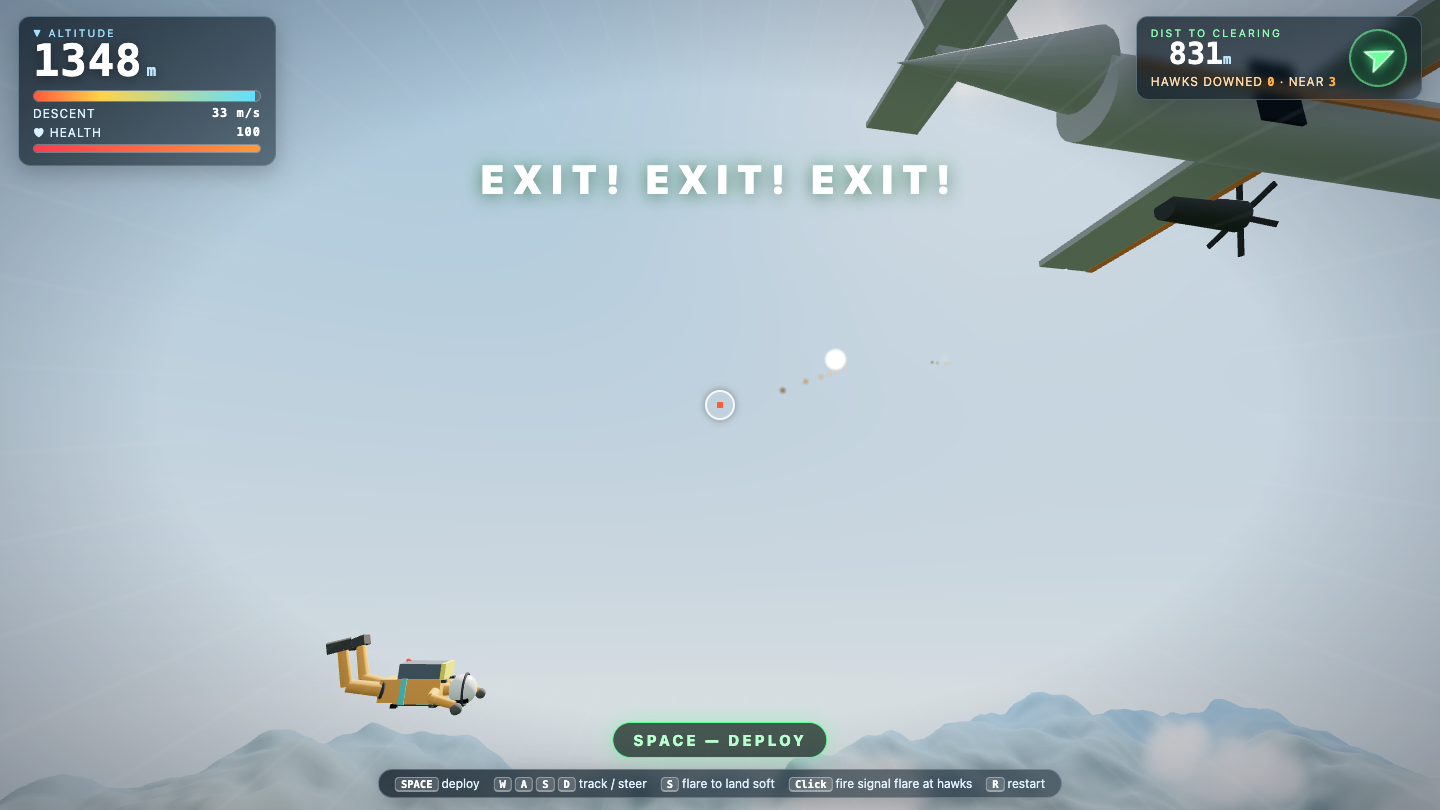
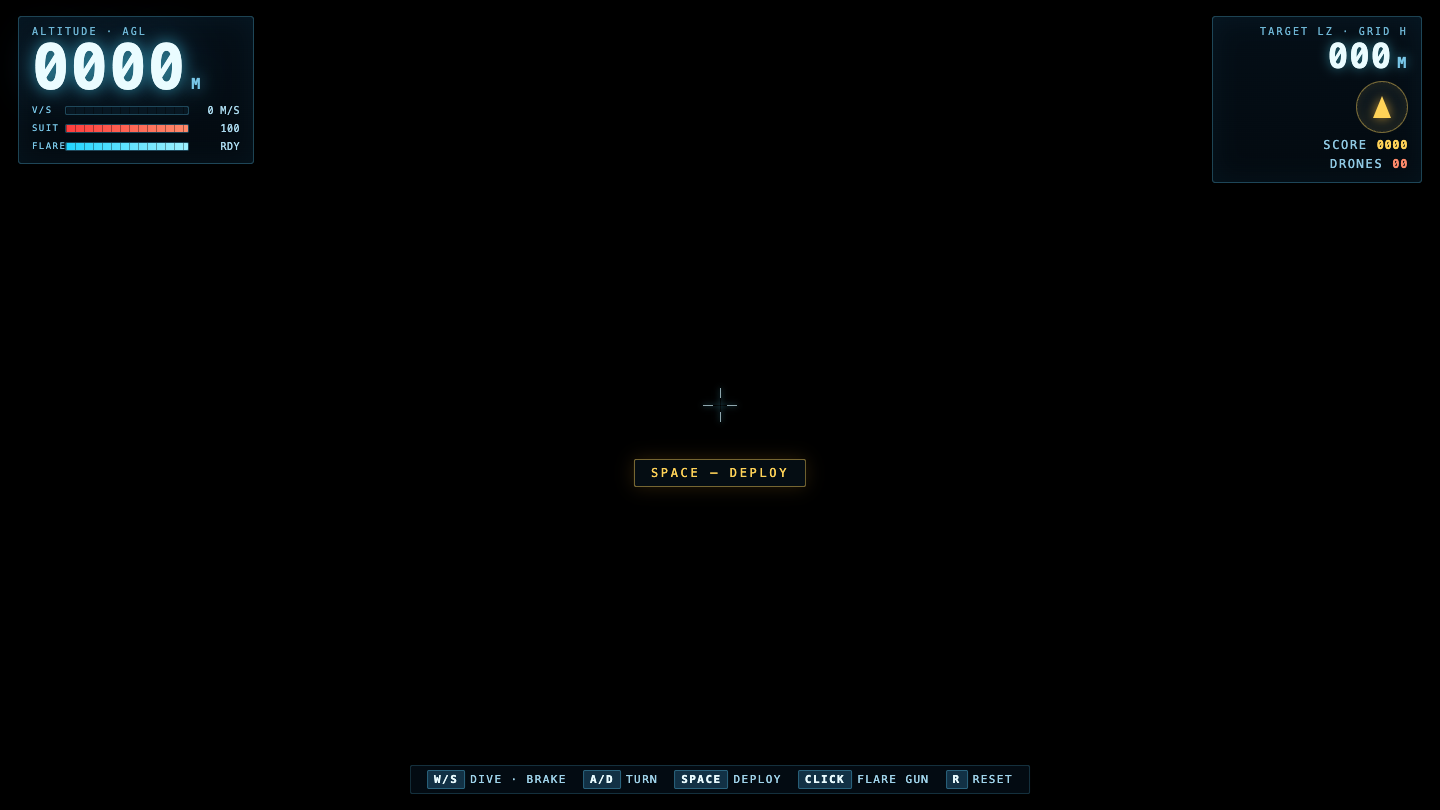
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
Claude Opus 5.5
MiMo-V2.6 Pro
Game
Game
Game
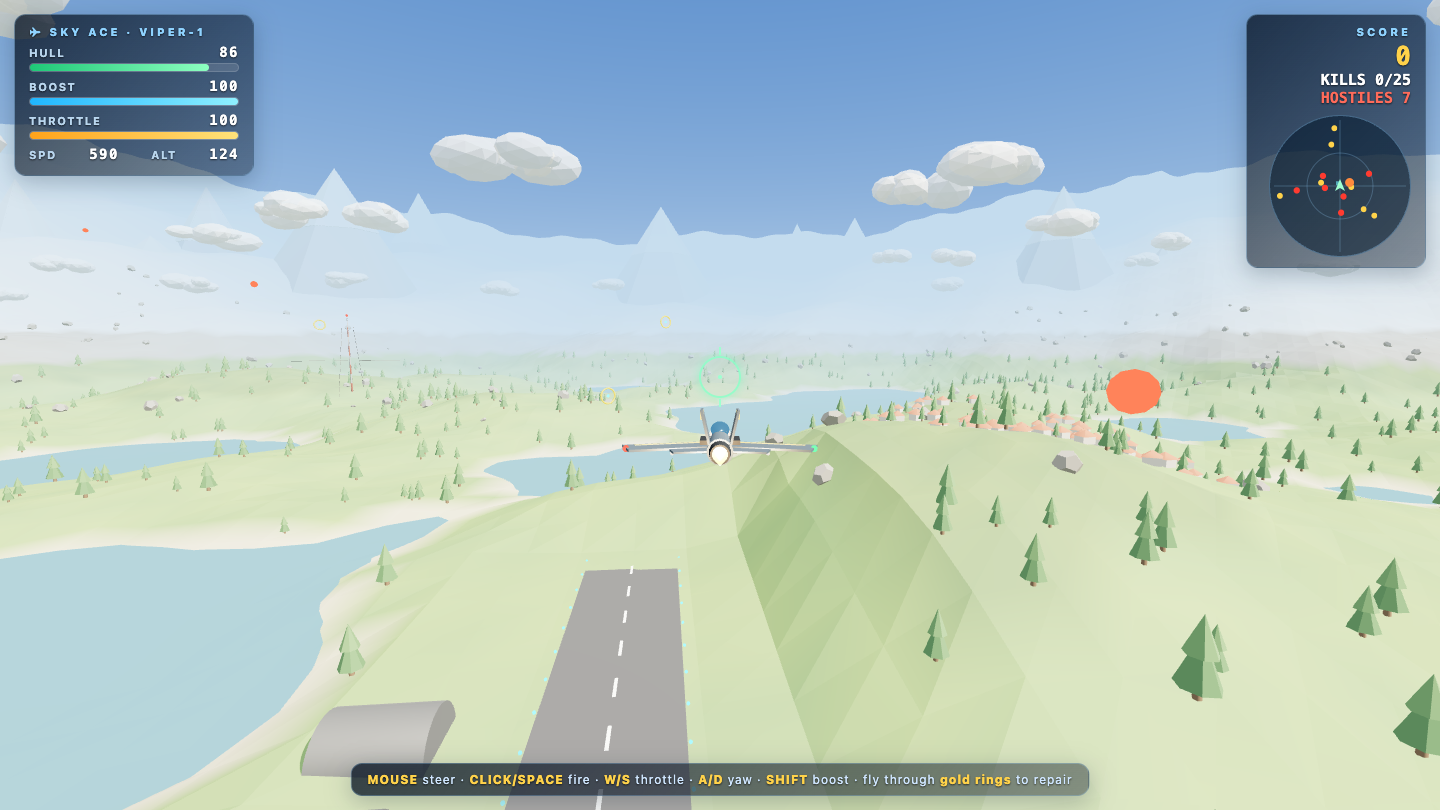
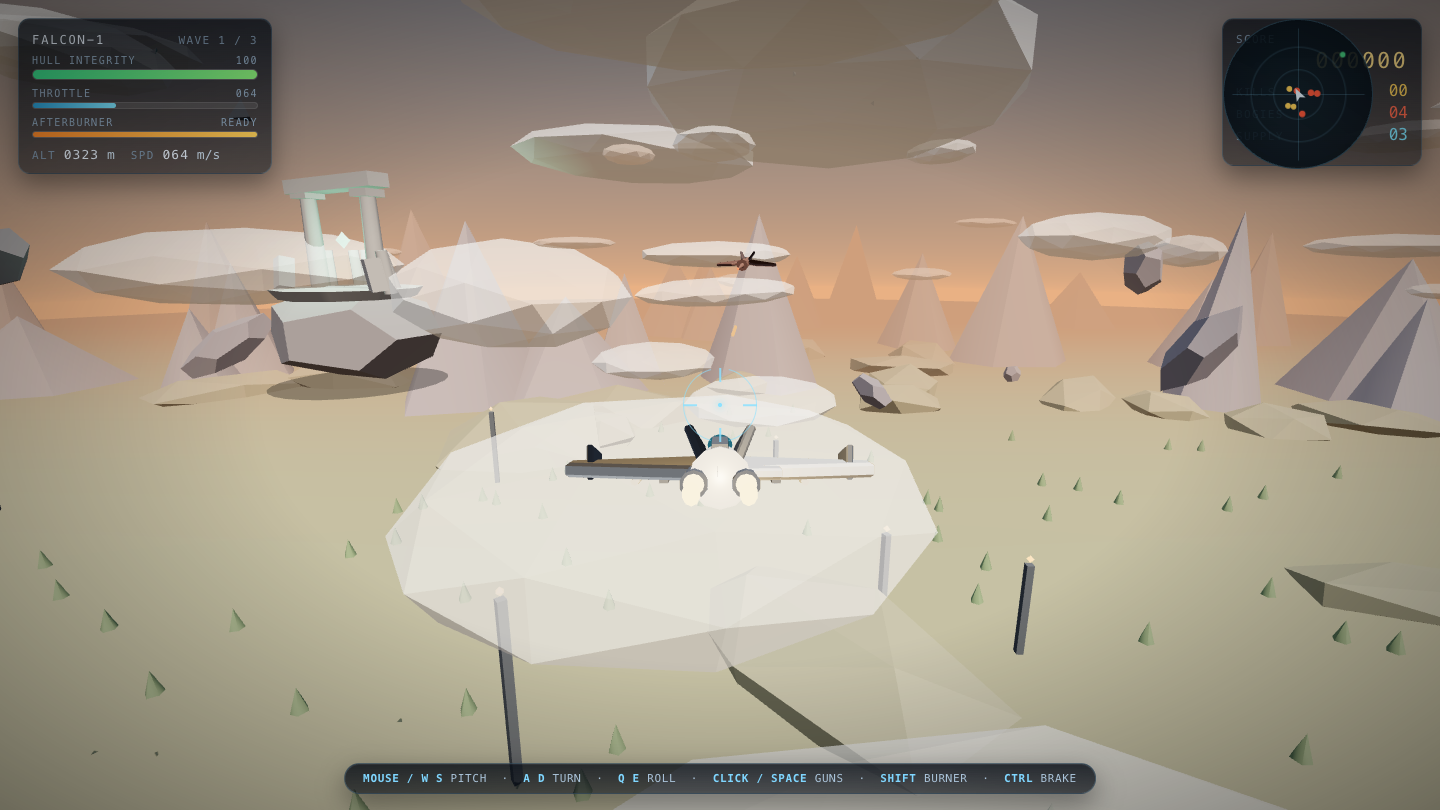
Game
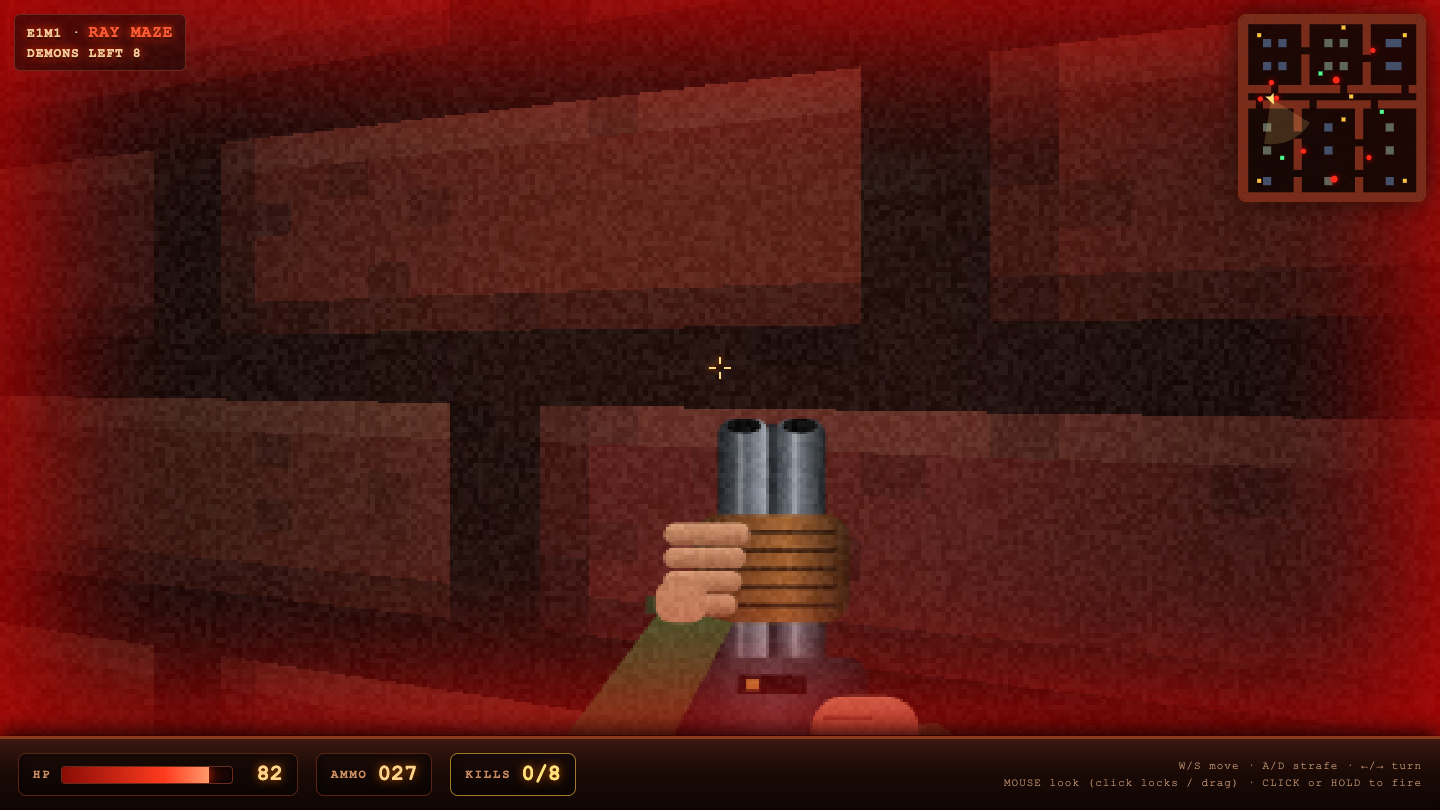
Game
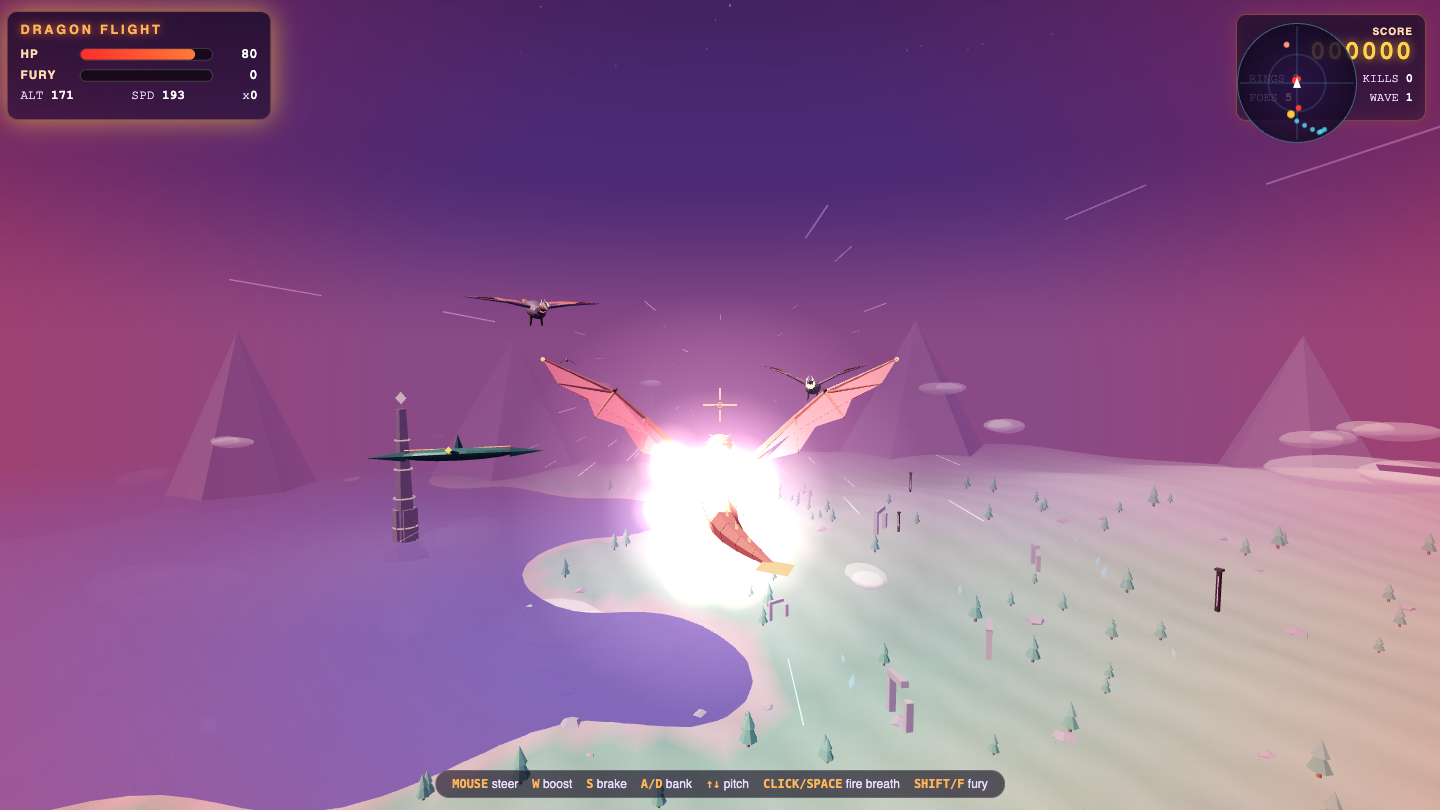
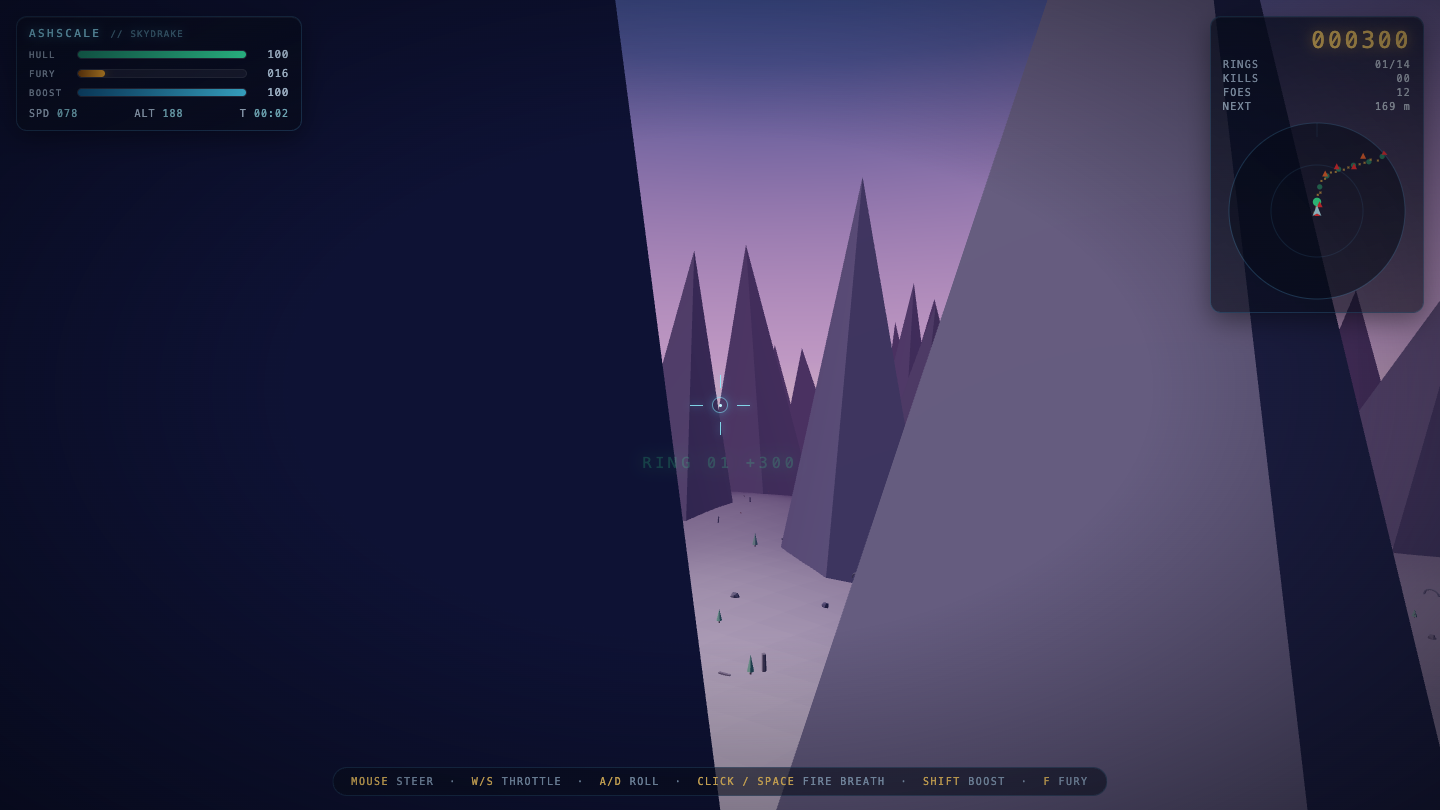
Game
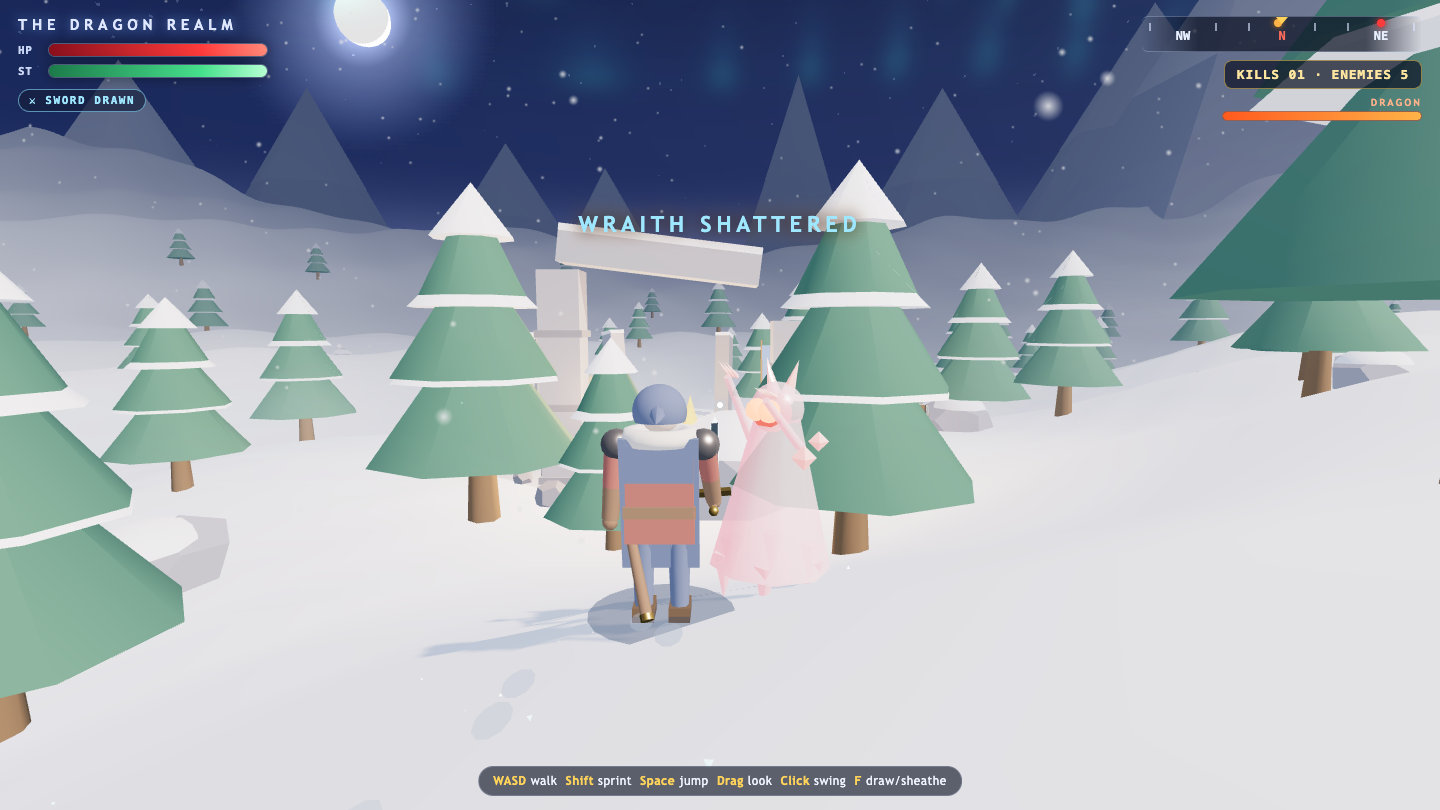
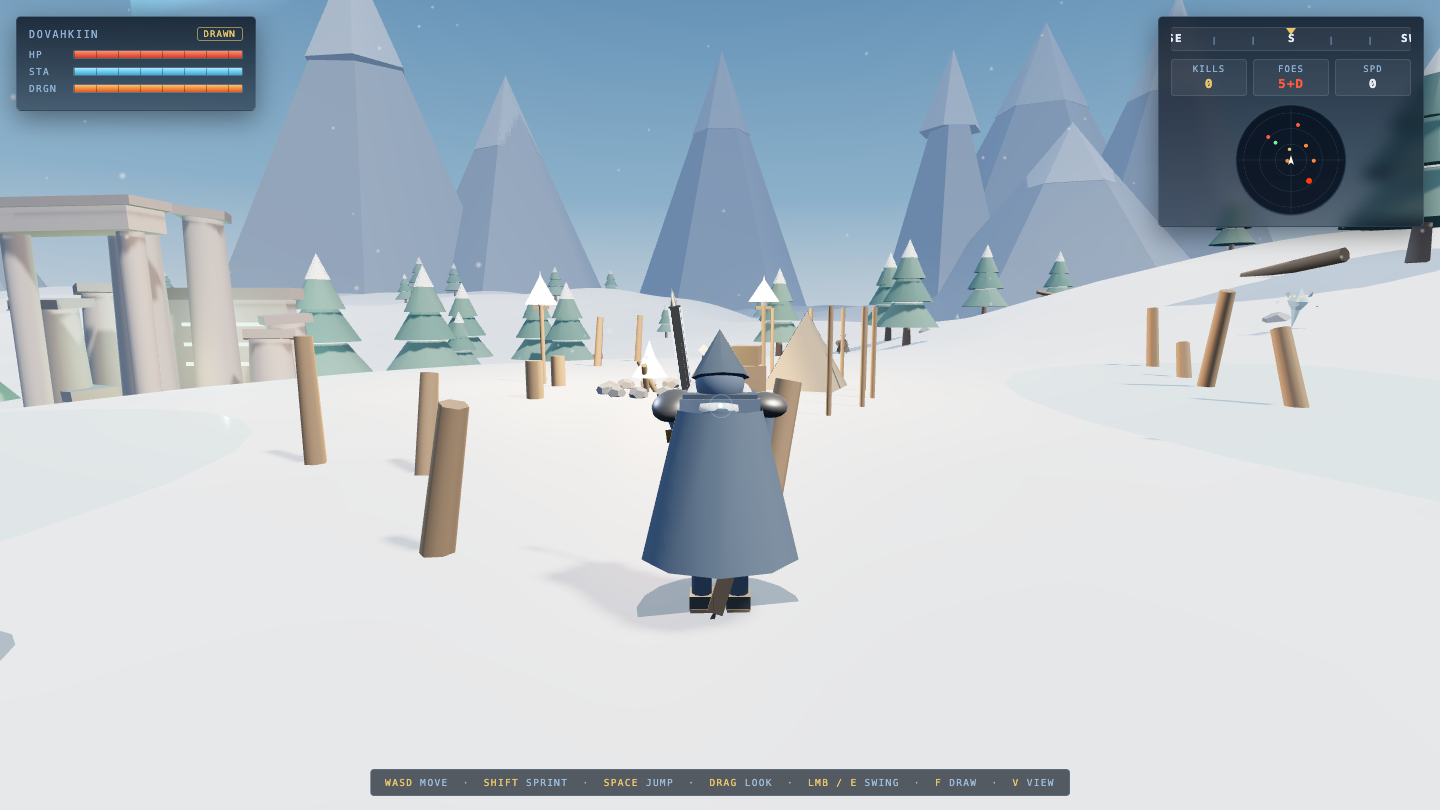
Game
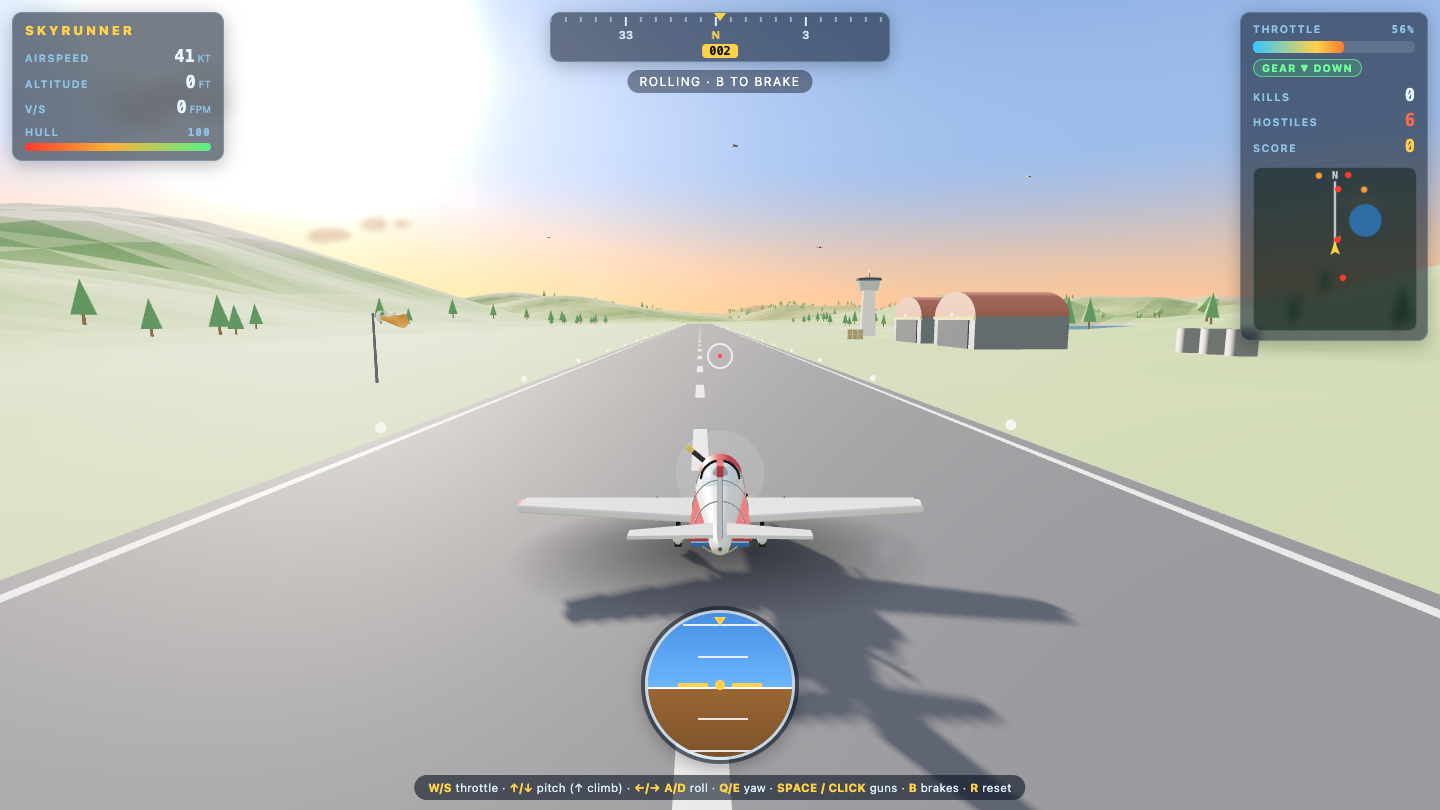
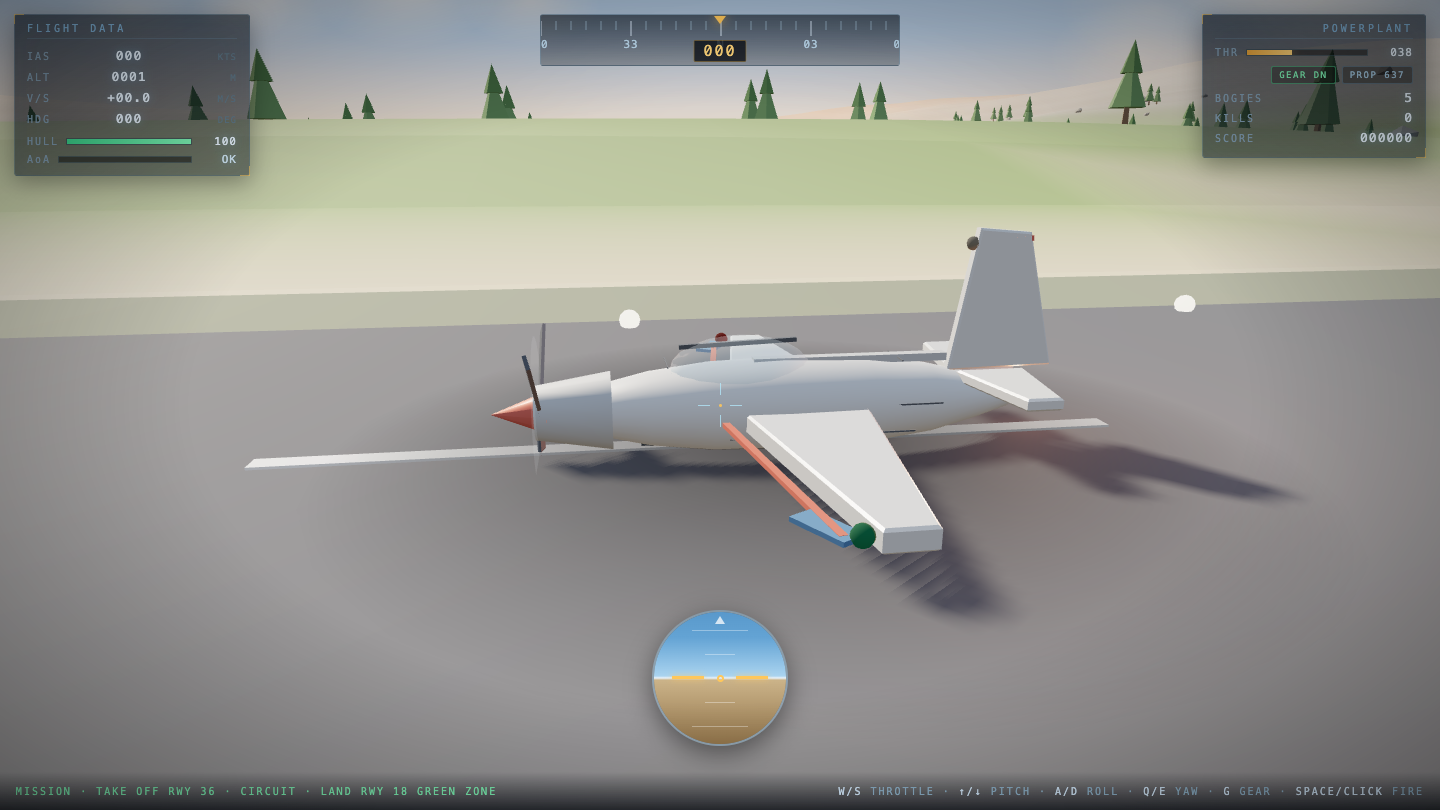
Game
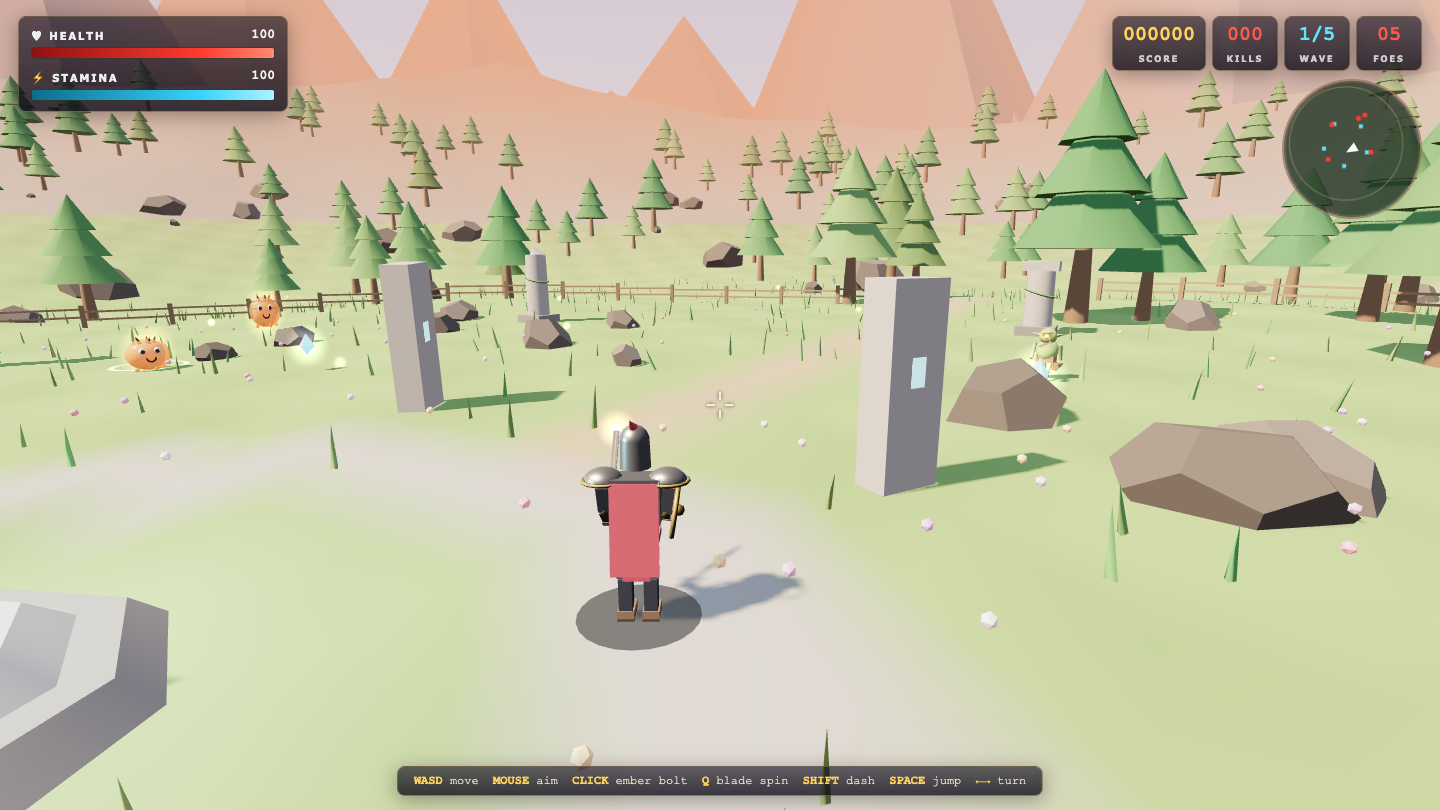
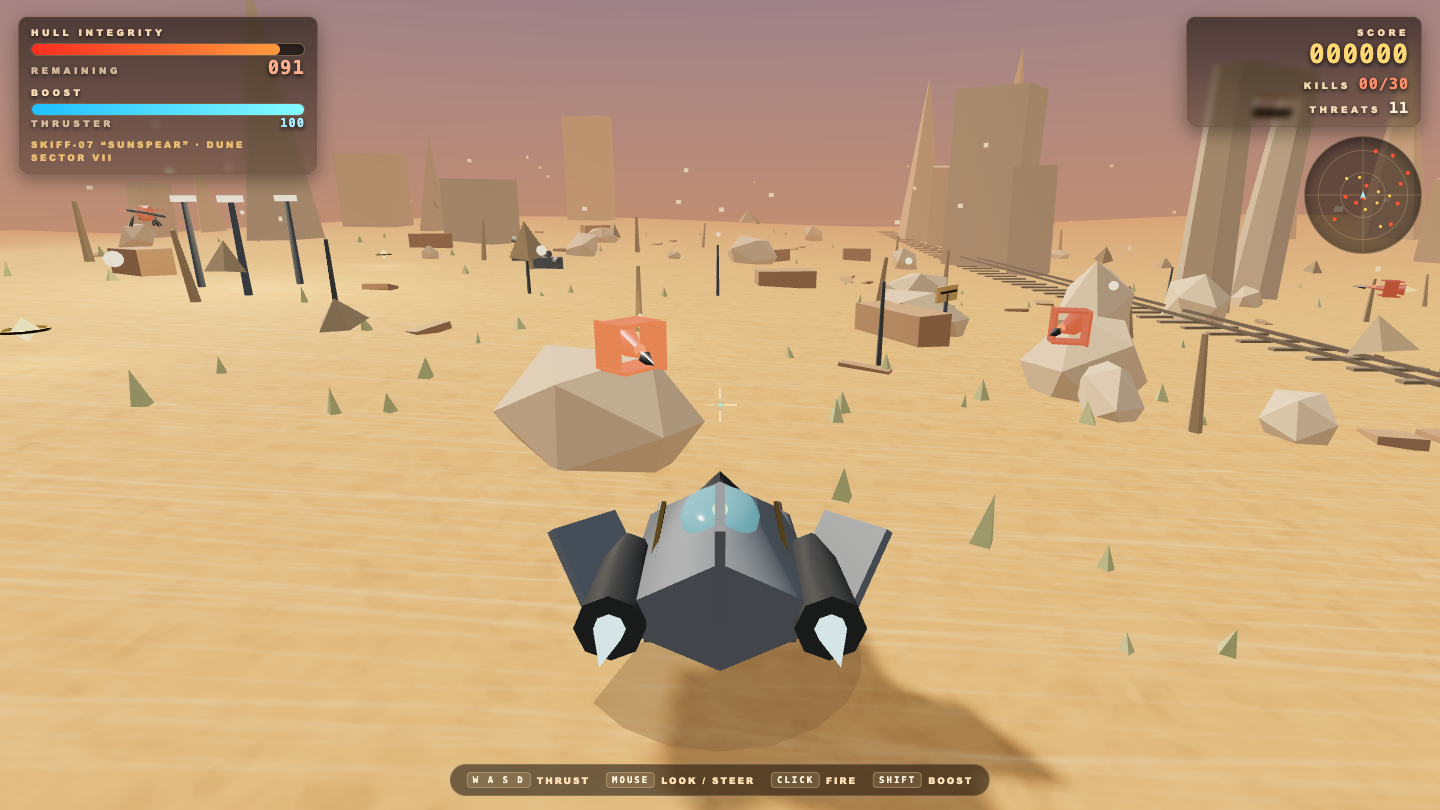
Game
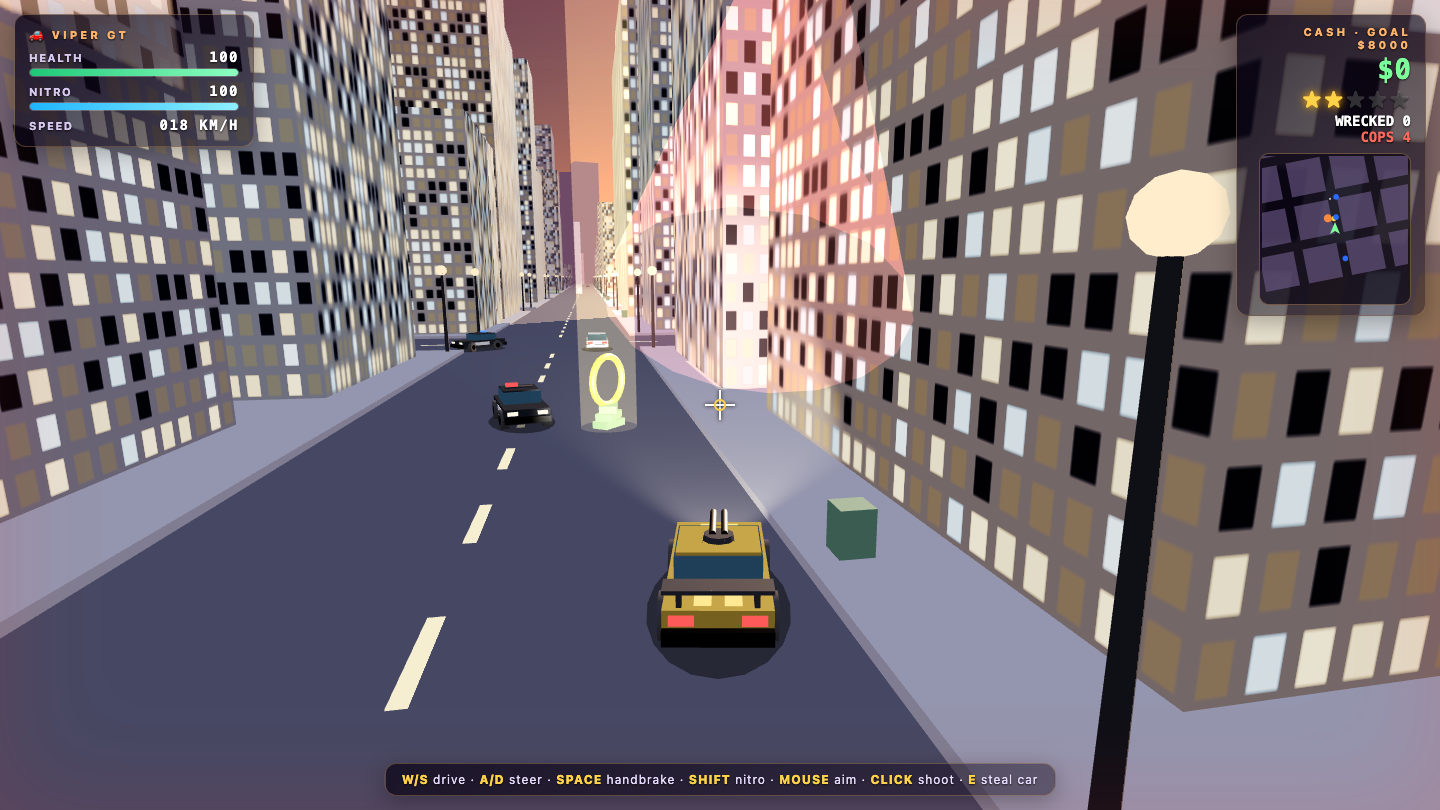
Game
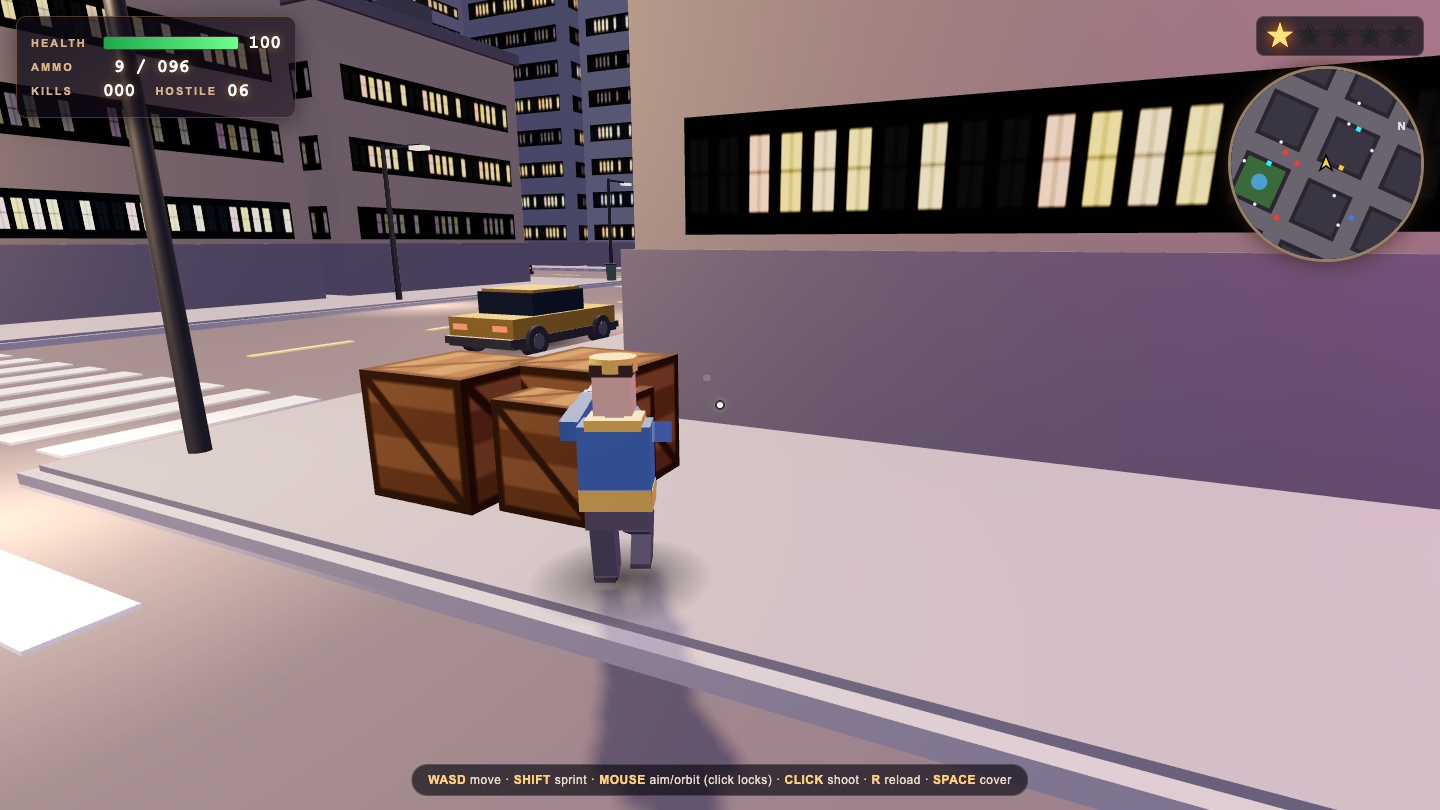
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
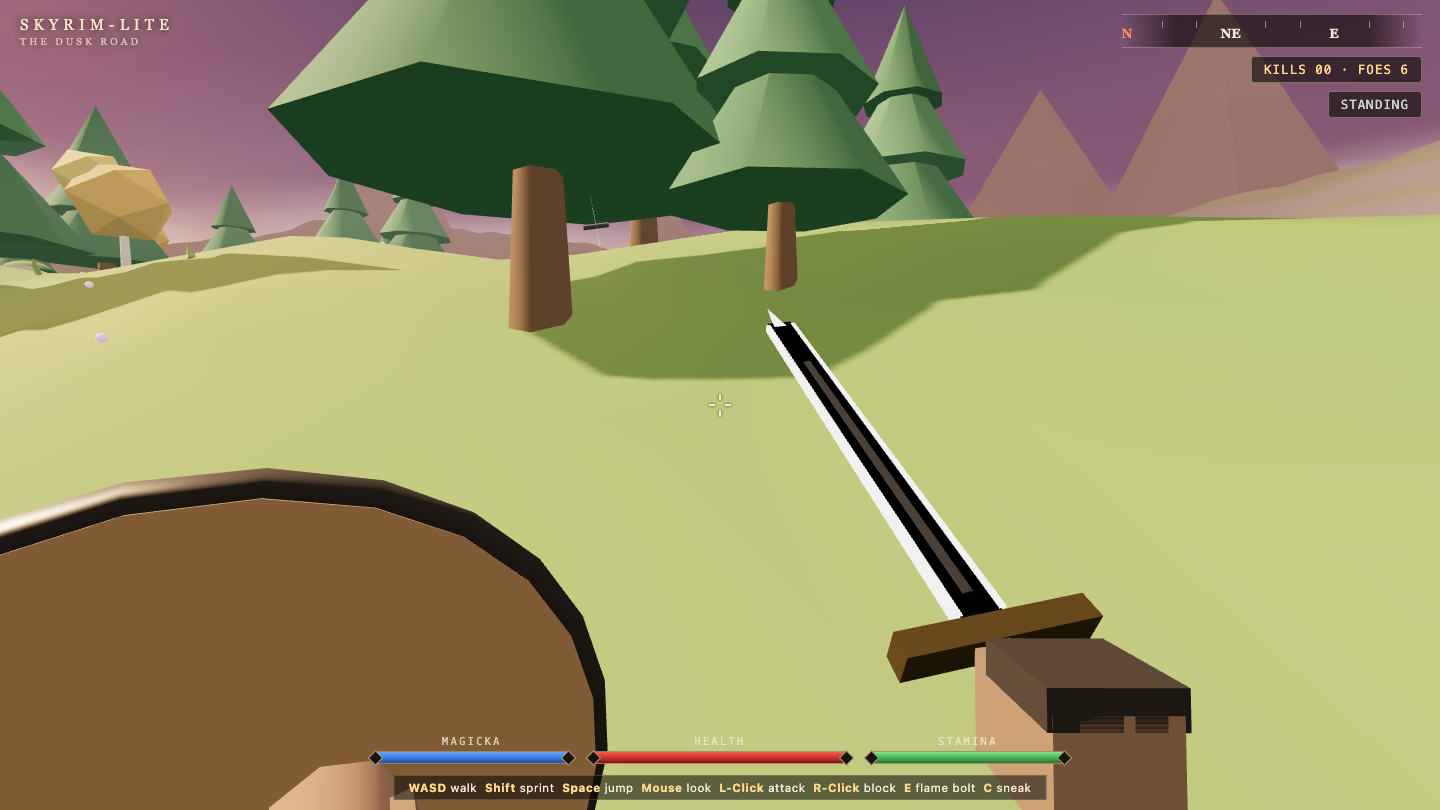
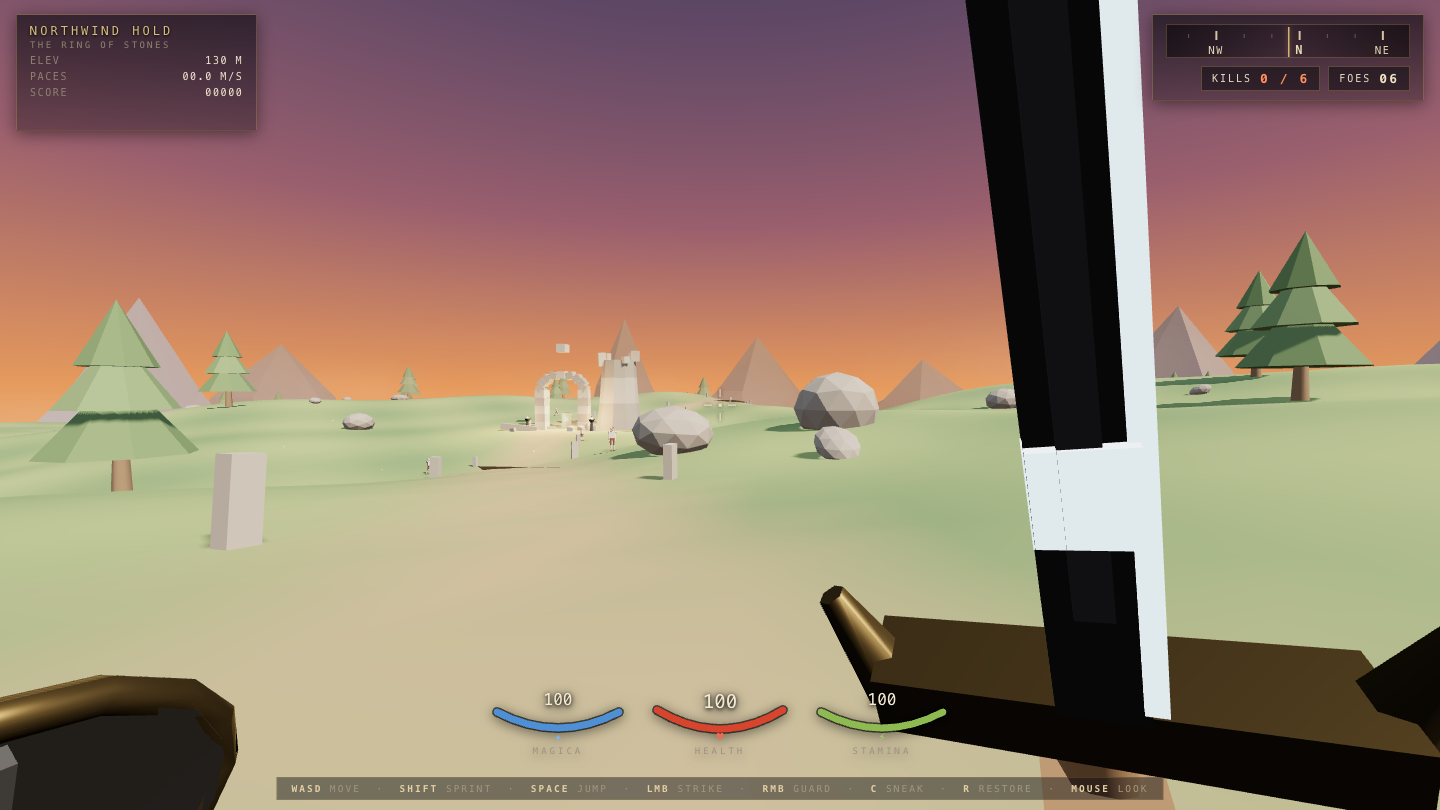
Game
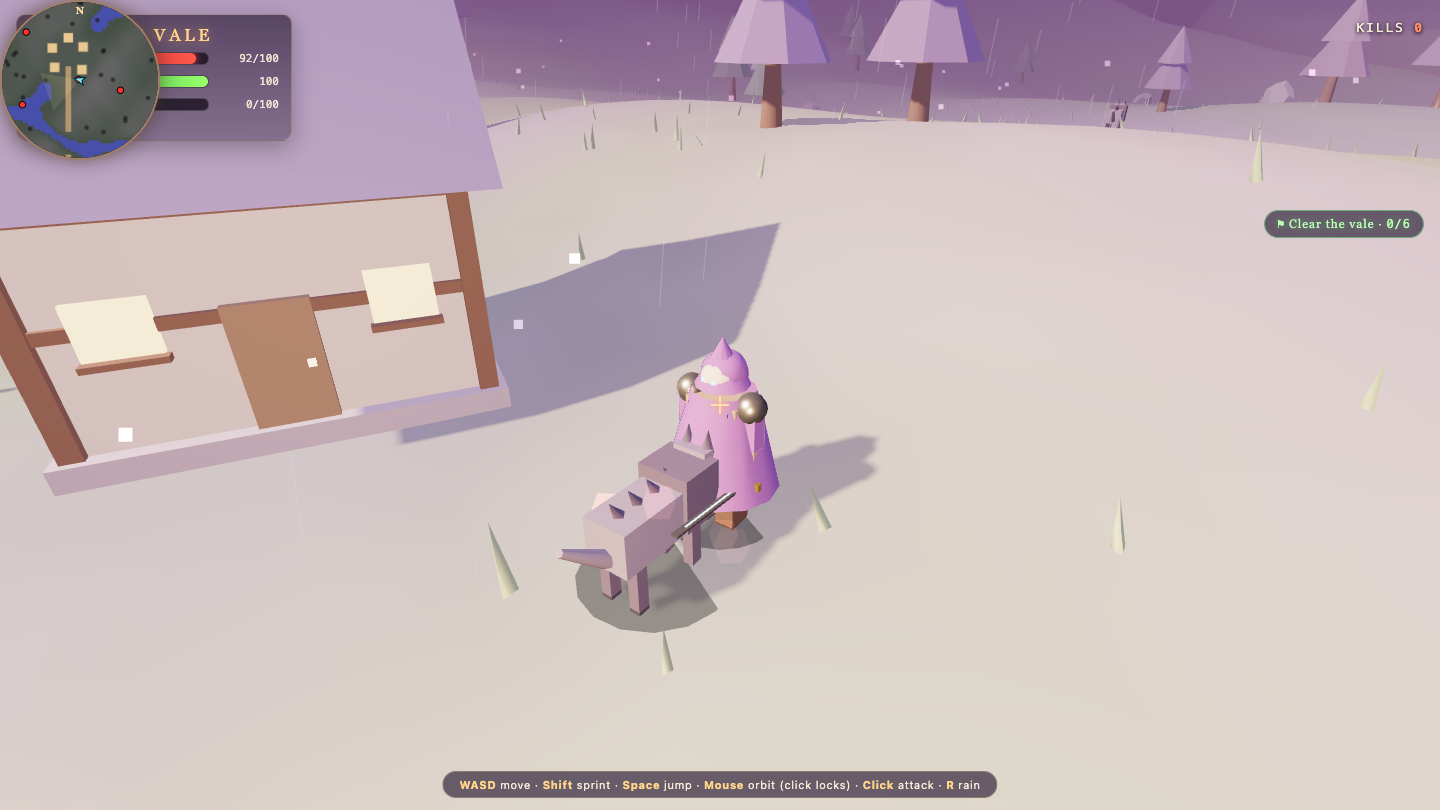
Game
Other
Where Claude Opus 5.5 beat MiMo-V2.6 Pro
The tasks where I gave Claude Opus 5.5 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Solar
Sim
Claude Opus 5.5 8.4
·
MiMo-V2.6 Pro 1.5
(+6.9)
What I saw: Accurate live Keplerian orrery driven by JPL J2000 elements: sqrt/true-distance scale toggle, asteroid belt, ringed Saturn, time controls and a real data panel, all in a polished UI. Planets are tiny at this zoom and the view is a fairly standard top-down orrery.
Synthwave
Visual
Claude Opus 5.5 8.6
·
MiMo-V2.6 Pro 3.0
(+5.6)
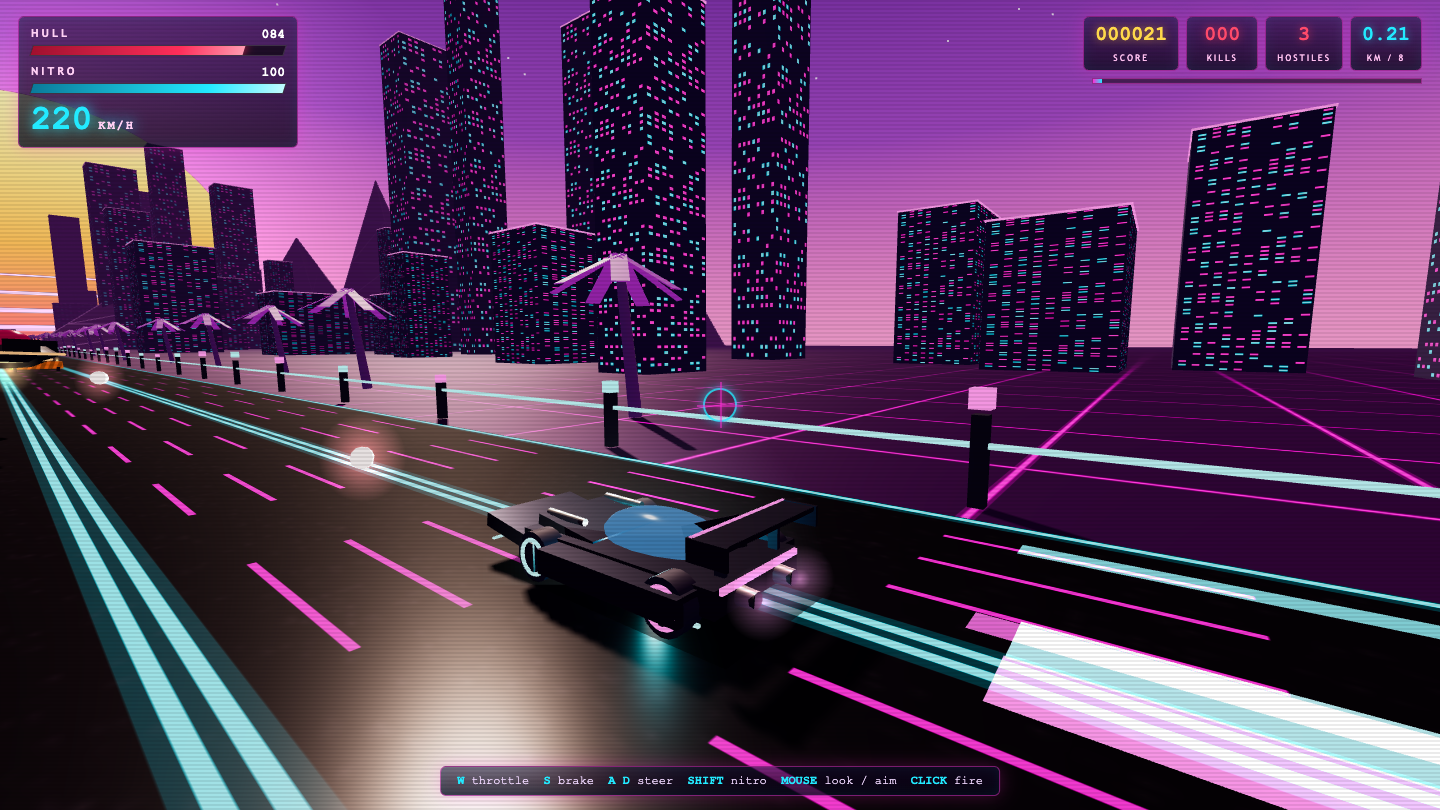
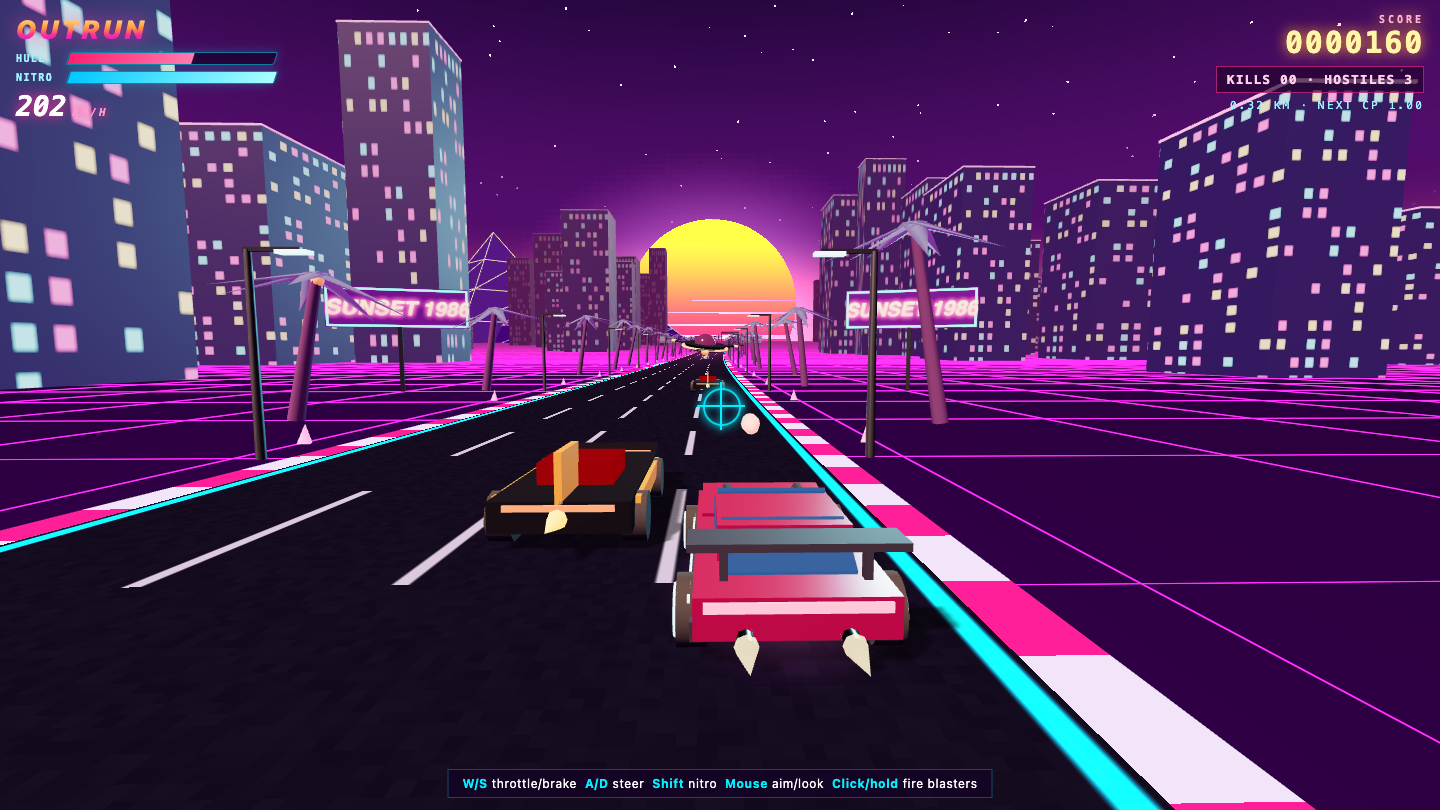
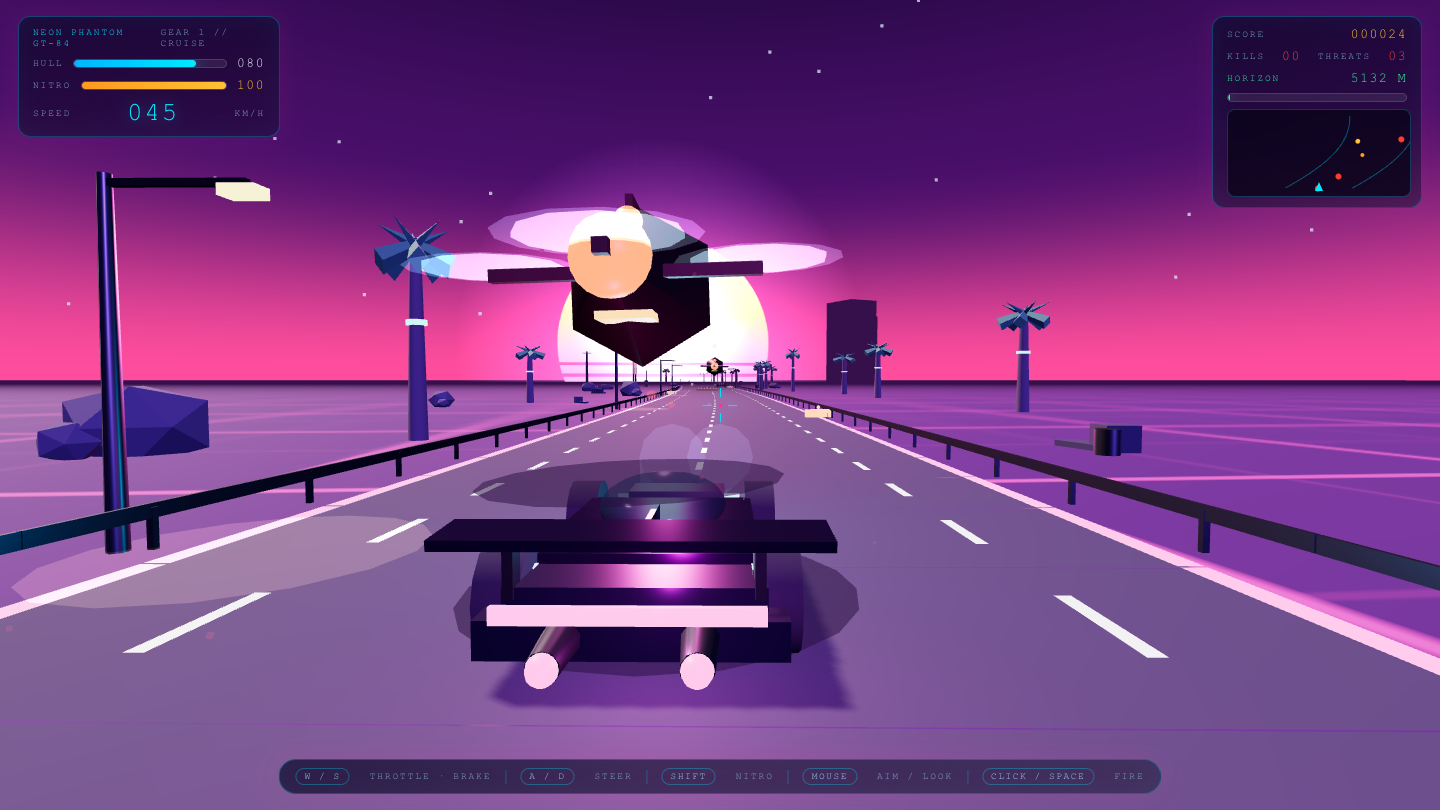
What I saw: Nails the look: a striped setting sun, neon wireframe mountains, palm-lined highway, a car with neon tail-lights, a chrome title and synth music on M. It is close to the field best but not clearly above it. The car is a dark low-detail silhouette.
Fluid
Sim
Claude Opus 5.5 8.5
·
MiMo-V2.6 Pro 3.0
(+5.5)
What I saw: Real GPU Navier-Stokes with vorticity: vivid curling dye plumes and a dense advected particle layer read as a proper swirling fluid, and the control pills are tidy. The stats line still says a stale 'starting…', and the look is a little busy next to the field's 9.0 best.
Pathtracer
Sim
Claude Opus 5.5 8.3
·
MiMo-V2.6 Pro 3.0
(+5.3)
What I saw: A genuine progressive path tracer: a Cornell box with color bleeding, Fresnel glass with caustics, a mirror sphere, soft shadows, samples/paths-per-second telemetry and useful controls. At 17 spp it is still grainy, and the subtitle runs faintly into the render.
Raycaster
Game
Claude Opus 5.5 8.3
·
MiMo-V2.6 Pro 3.0
(+5.3)
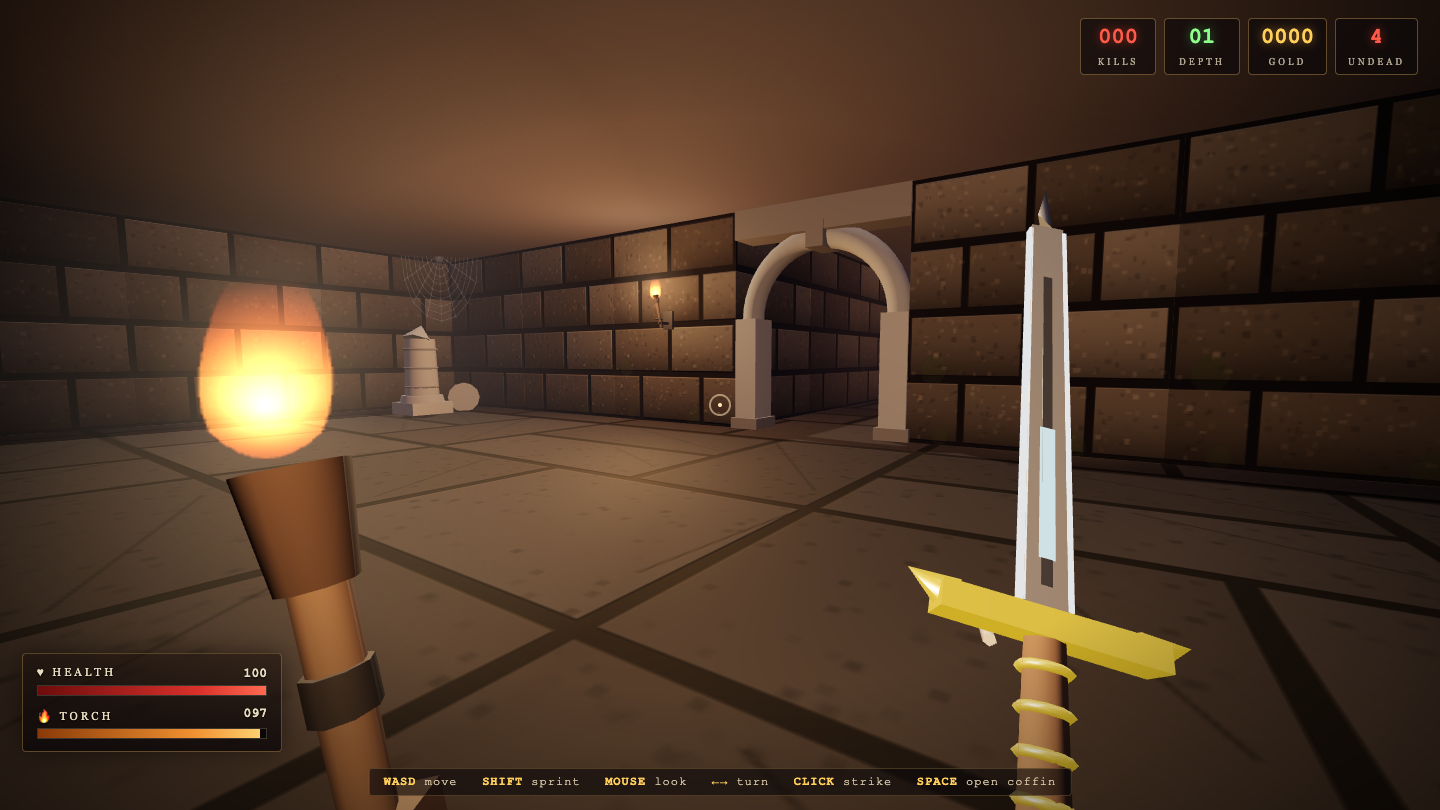
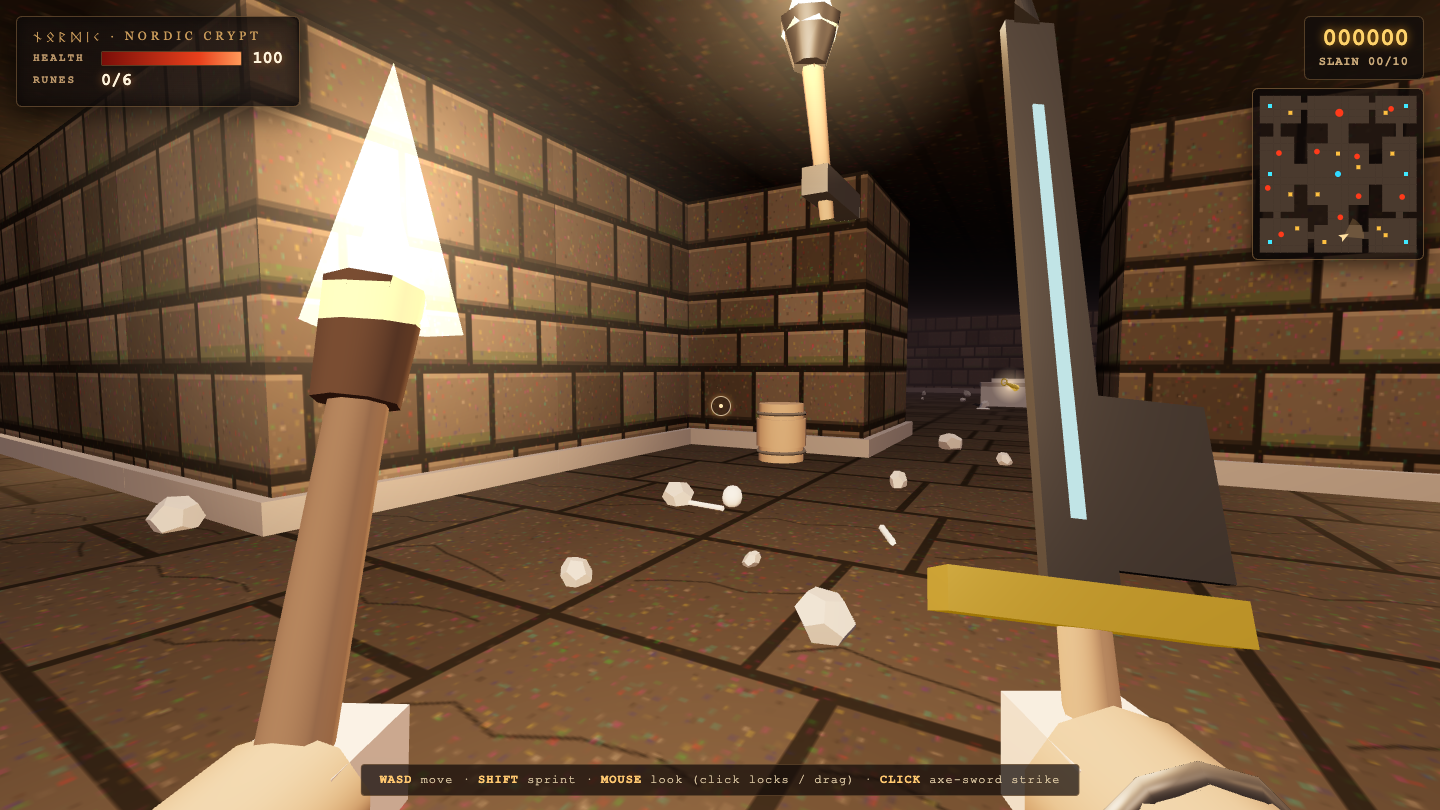
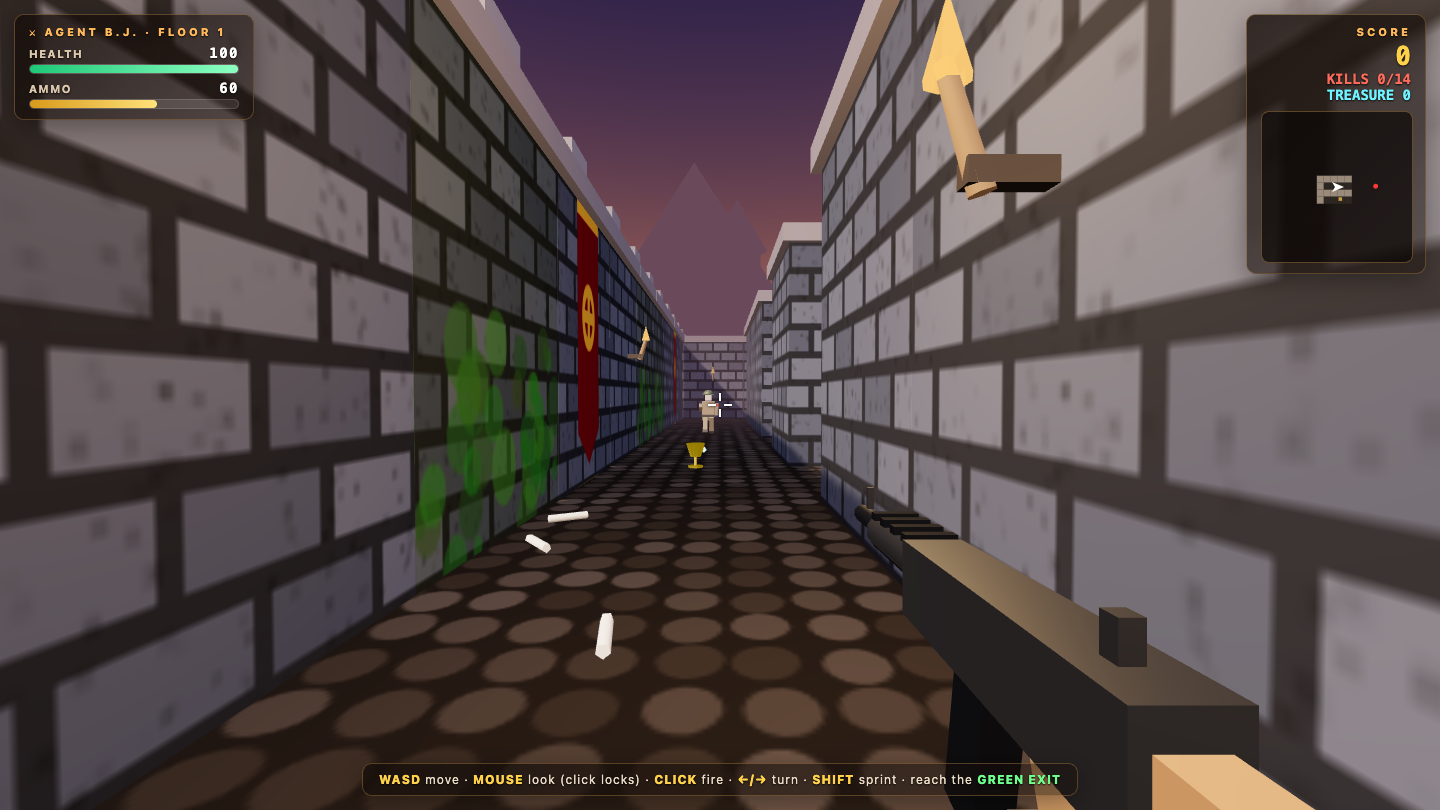
What I saw: Convincing Wolfenstein mood: textured stone corridors, red eagle banners, moss, torches, a cobbled floor, a guard, a treasure chalice and a first-person gun, with a cohesive HUD and minimap. It is a full three.js scene rather than a true raycaster, and the gun and hand are blocky boxes.
Where MiMo-V2.6 Pro beat Claude Opus 5.5
The tasks where I gave MiMo-V2.6 Pro a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
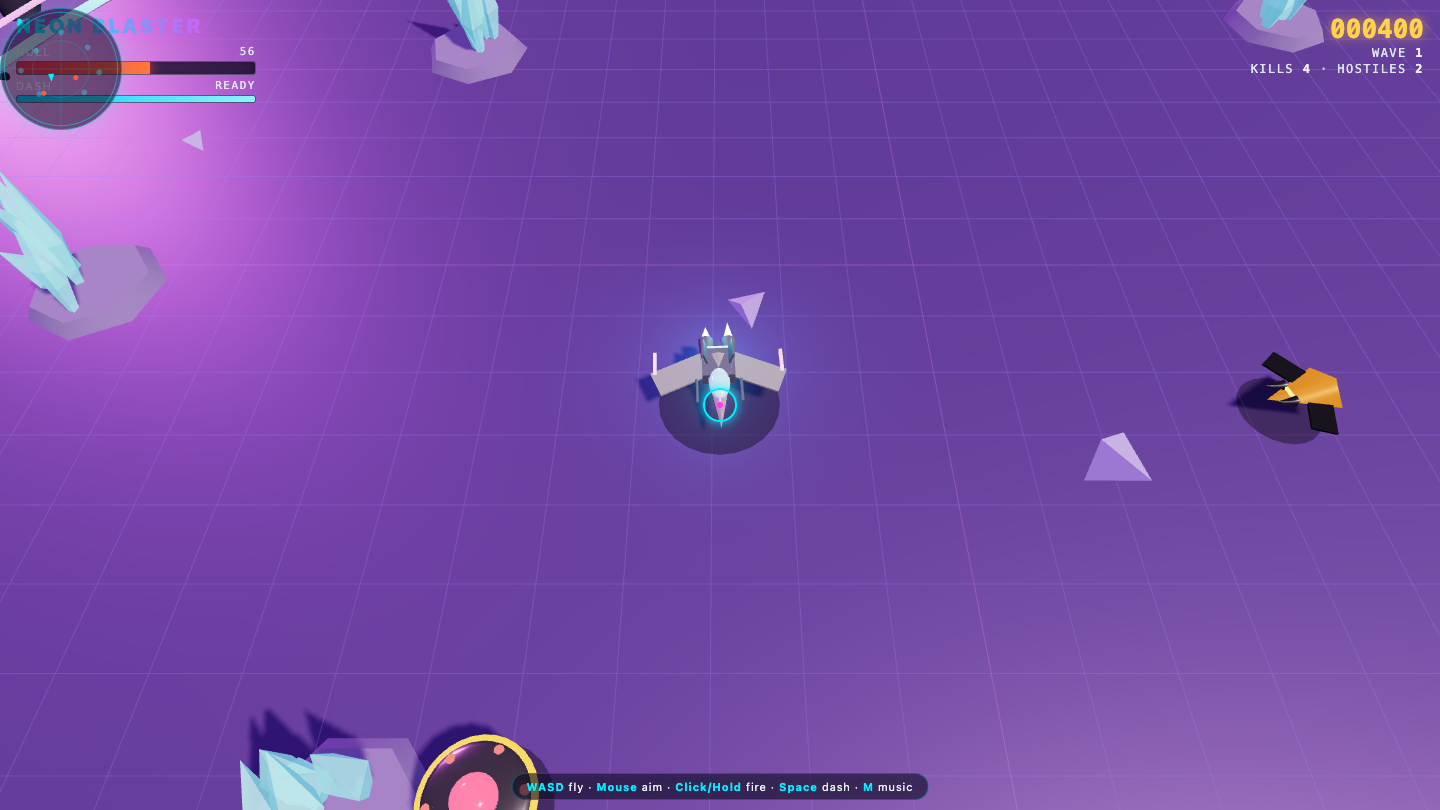
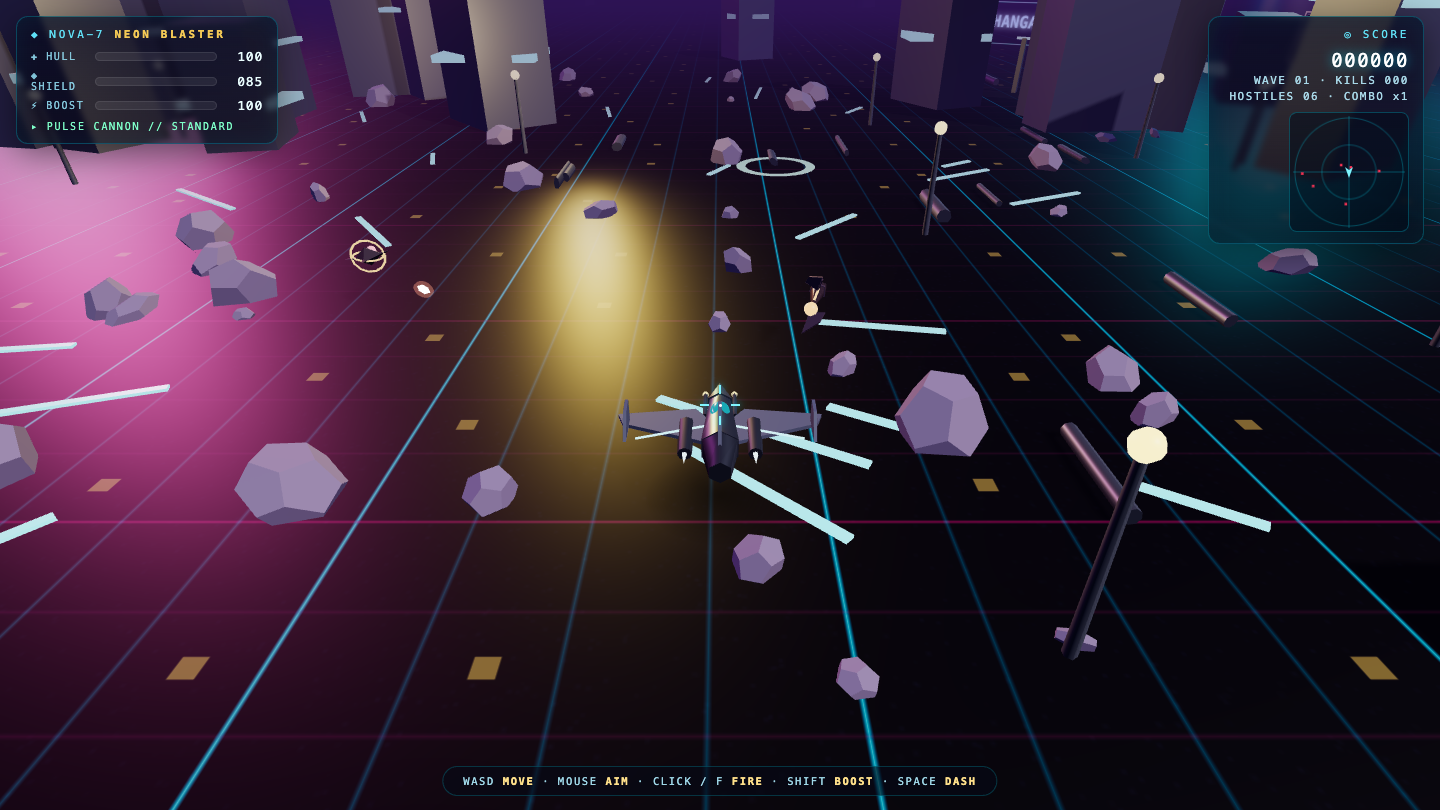
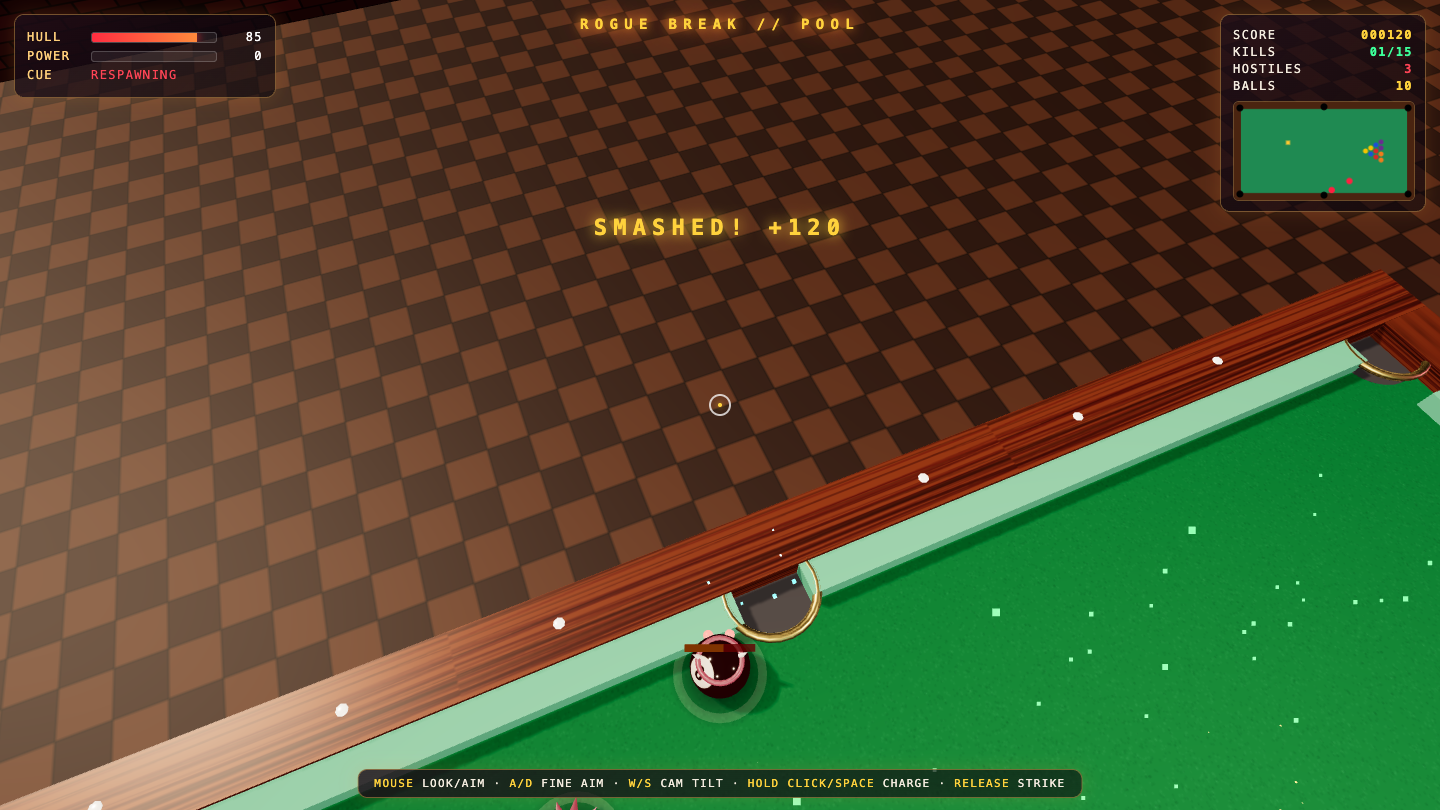
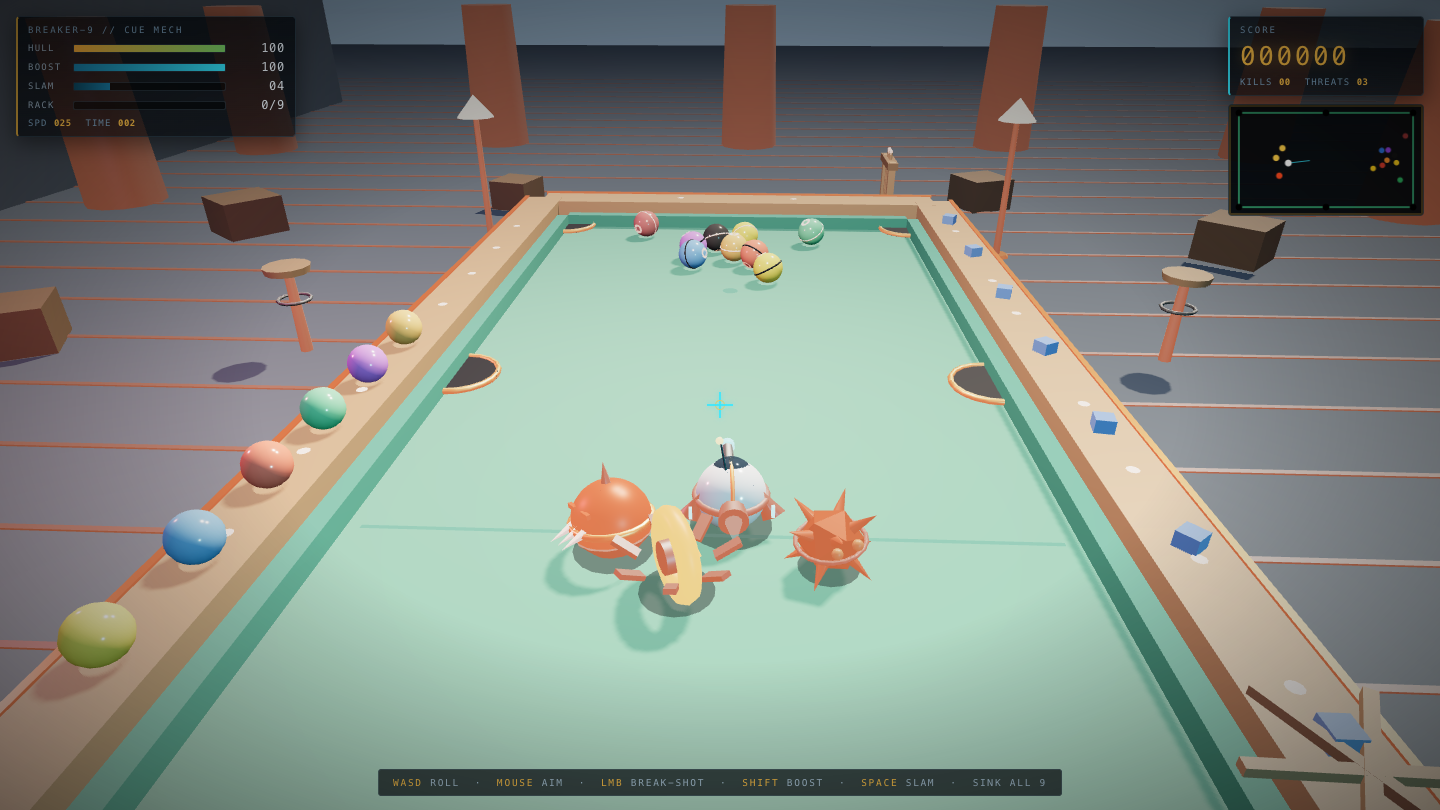
Neonblaster
Game
MiMo-V2.6 Pro 8.7
·
Claude Opus 5.5 5.8
(+2.9)
· 3D neon top-shooter
What I saw: Renders a gorgeous 3D synthwave arena with detailed ship, glowing perspective grid, floating debris, and a fully polished HUD (hull/shield/boost meters, radar, boss bar, combo) backed by scheduled synth music and juicy SFX. Strong on-brief execution that rivals the field best; on…
Voxelcraft
Game
MiMo-V2.6 Pro 8.6
·
Claude Opus 5.5 5.8
(+2.8)
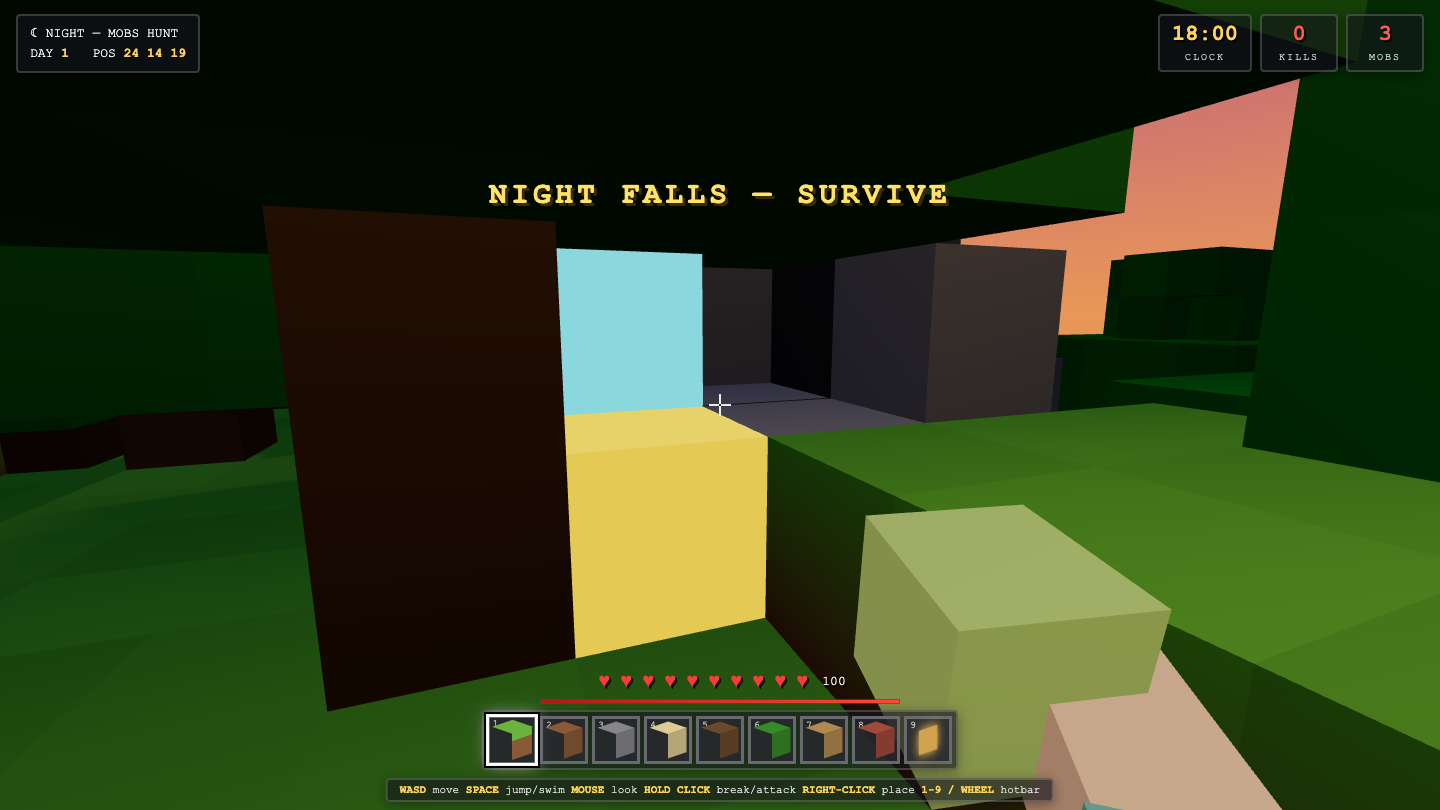
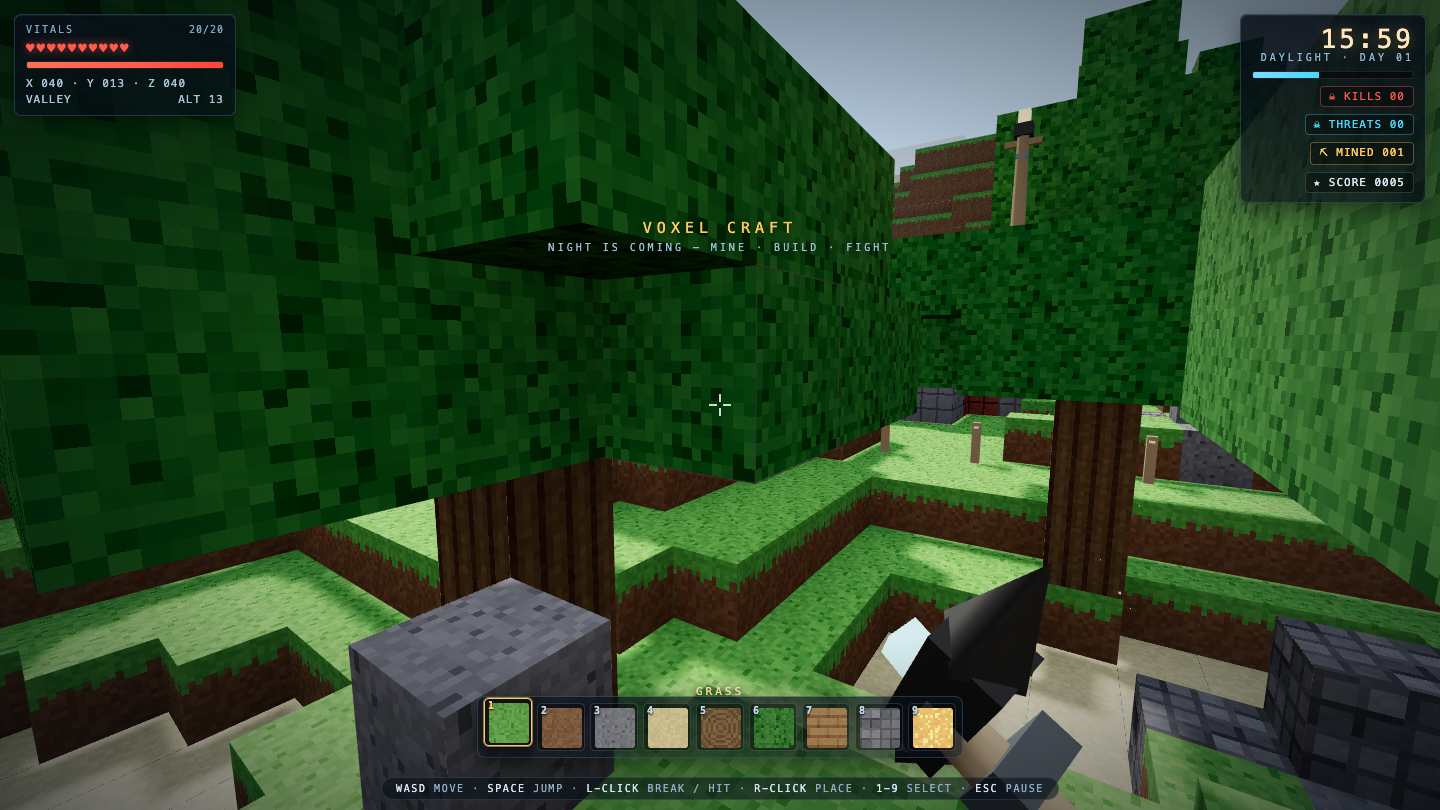
· Polished voxel sandbox
What I saw: Strong render: clean voxel terrain with proper grass/dirt/stone textures, trees, first-person hand, full hotbar with 9 block types, and a polished HUD showing vitals, day/night clock, biome, and score badges. The cohesive dark-cyan monospace UI theme plus visible day/night cycle …
Arcade
Game
MiMo-V2.6 Pro 8.6
·
Claude Opus 5.5 6.0
(+2.6)
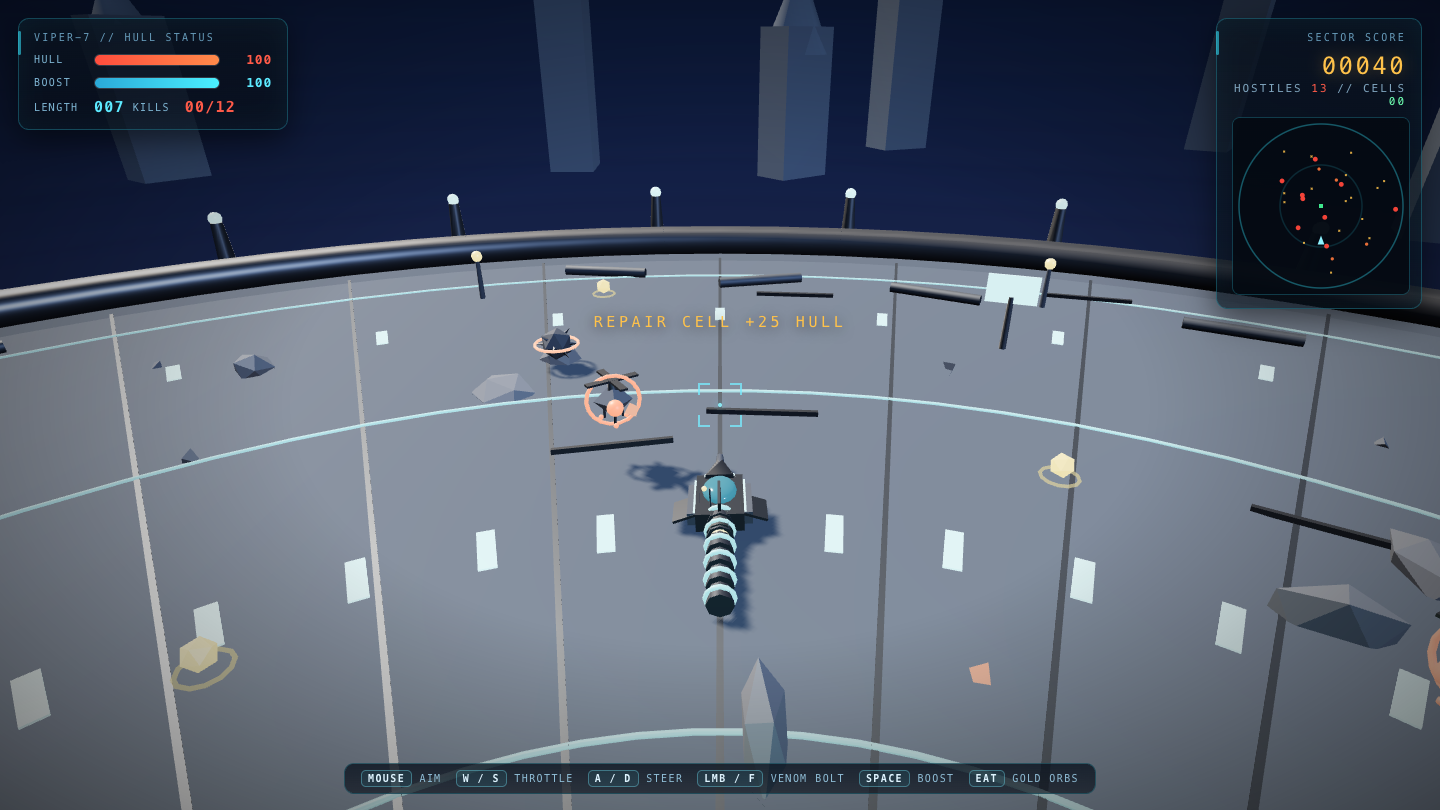
· 3D neon snake
What I saw: Stunning 3D reinterpretation of Snake as a WebGL arena viper — polished lighting, segmented tail, working minimap, pickups, and clean neon HUD all render crisply. Strong on-brief execution that clearly outclasses the flat 2D field; only slight risk is that the elaborate combat fr…
Mlx Speedtest
Other
MiMo-V2.6 Pro 8.3
·
Claude Opus 5.5 6.0
(+2.3)
What I saw: Strong, polished 3D benchmark viz with clean neon-on-dark palette, orbiting bandwidth rings, labeled per-model bars, and a coherent live telemetry panel that all reads as a believable MLX speedtest. Slightly generic bar-chart concept and low 25fps hold it just under the field's b…
Terrain
Visual
MiMo-V2.6 Pro 8.4
·
Claude Opus 5.5 6.8
(+1.6)
· lush forested island
What I saw: Strong on-brief render — a lush low-poly island with snow-capped peaks, dense forests, rocks, and a wireframe overlay, plus a polished glassy HUD with rich parameters and live readouts. The wireframe/mesh showing through the terrain surface looks slightly buggy and the water lily…
Strengths & weaknesses I logged
Claude Opus 5.5
Strengths
- Frontier-class coding + agentic reasoning (Claude 5 family)
- 1M-token context — reads an entire codebase in one call
- All 50 one-shot builds rendered with zero console errors; all 23 games passed the input playtest
Trade-offs
- Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes
- One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts)
MiMo-V2.6 Pro
Strengths
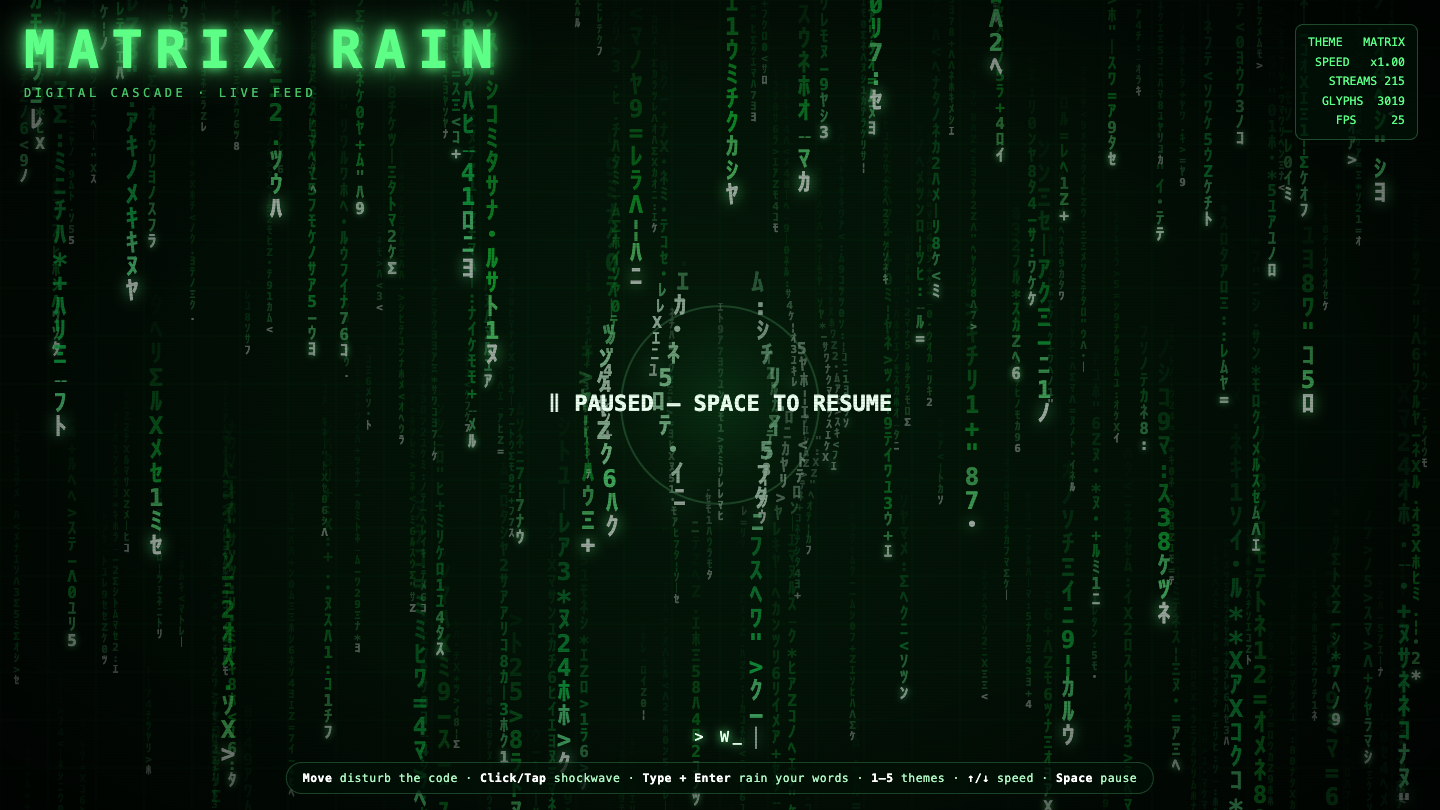
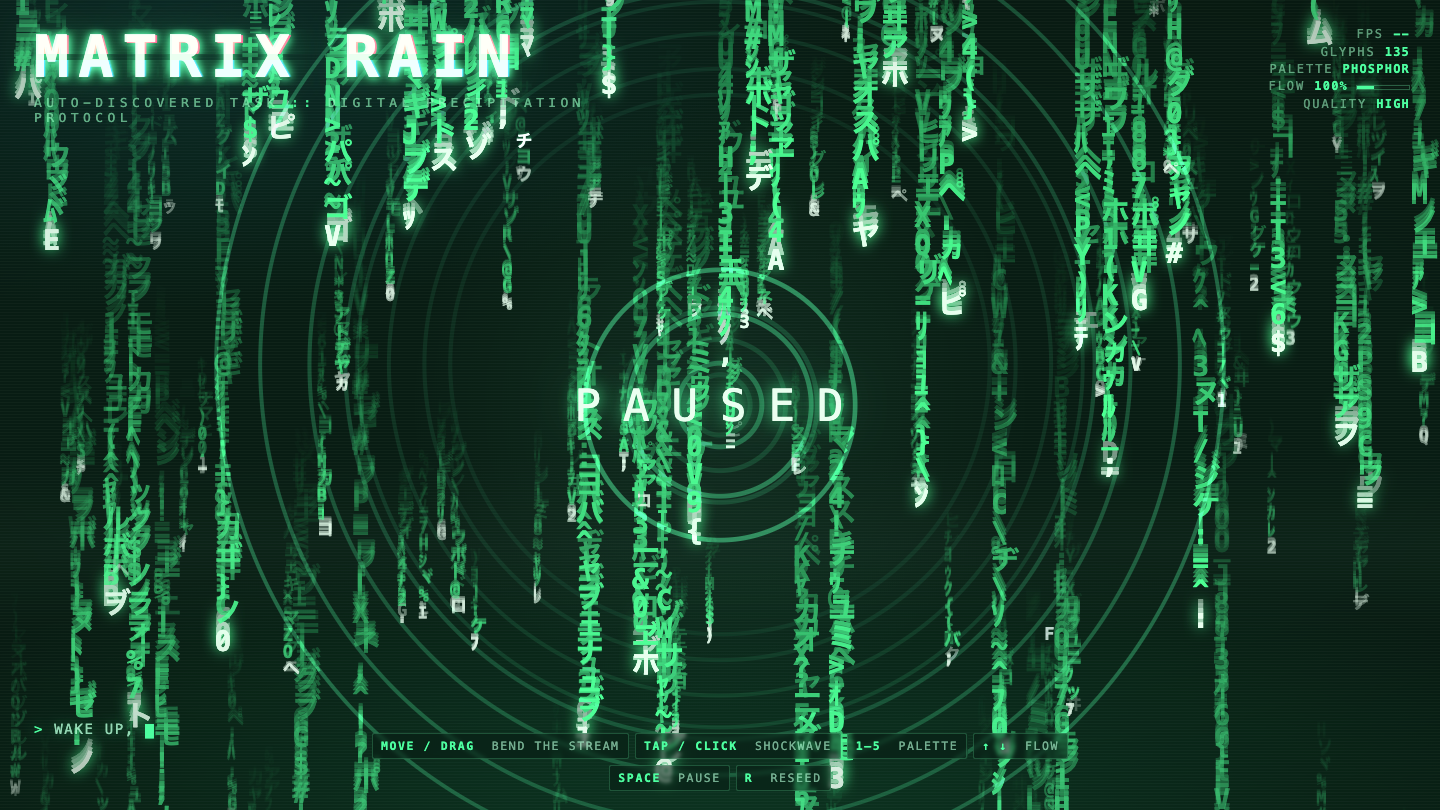
- Simulations and visual pieces are top-tier one-shots: the black hole lensing scored 9.0 and the matrix rain, lava lamp, ocean waves, web desktop, boids and galaxy all landed 8.6 or higher
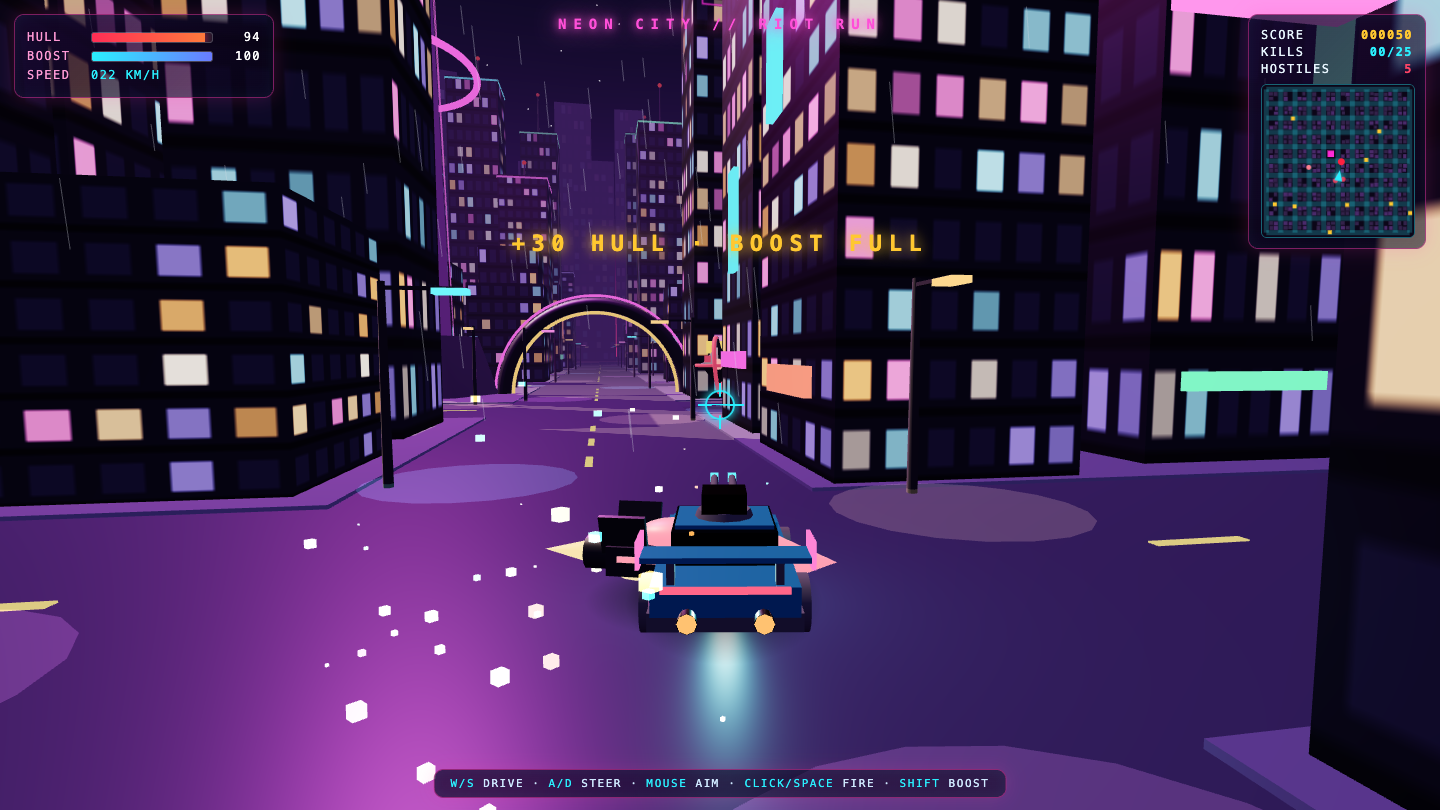
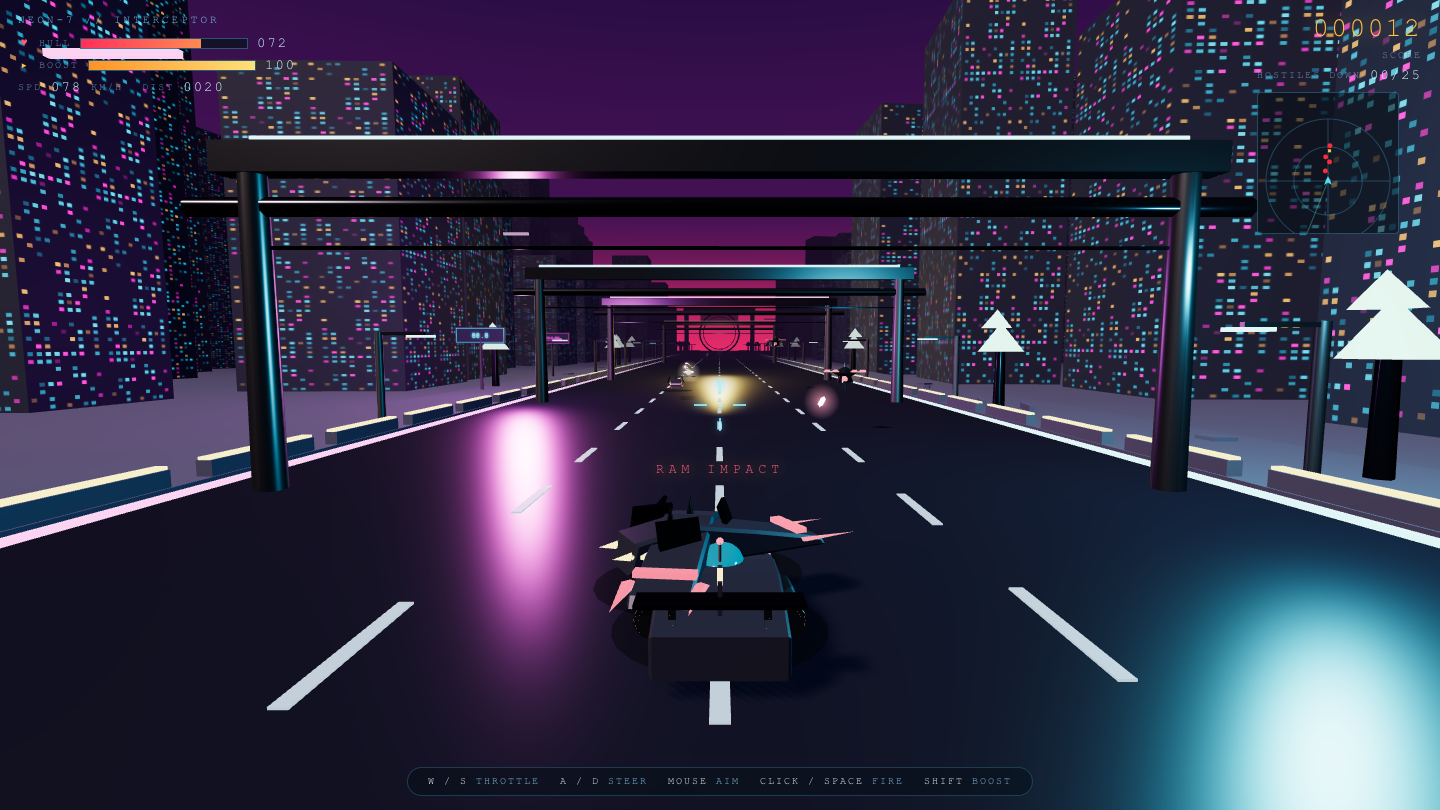
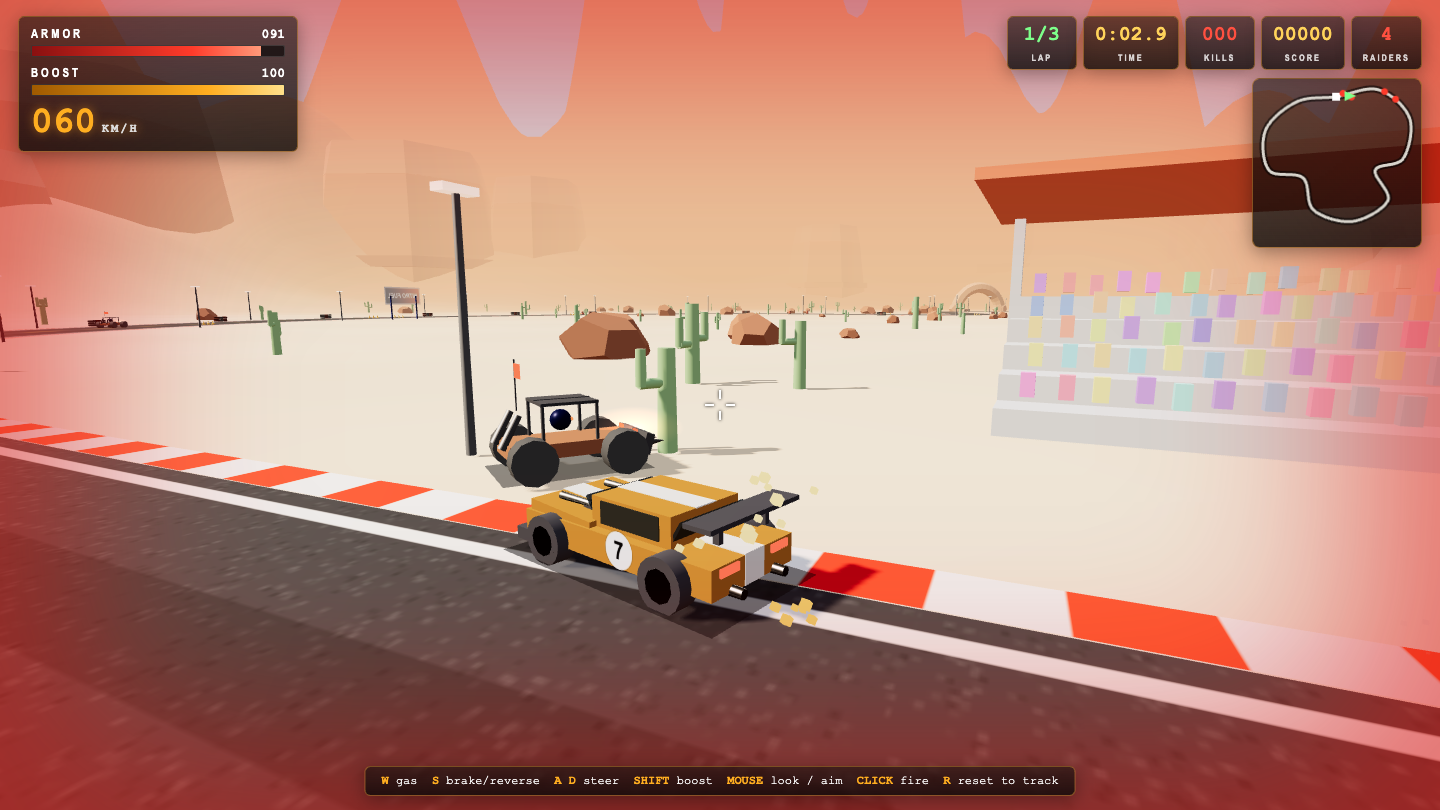
- Strong flight and driving output when the build holds together: a polished 3D dogfight (8.6), a flight sim (8.4) and the synthwave outrun (8.4)
- Big, complete files: builds ran 30 to 70 KB with full HUDs, control hints and settings panels
- The weights are MIT and on Hugging Face, so the same model can run on your own hardware
Trade-offs
- 18 of 50 builds scored under 5: long game files shipped with garbled tokens (a stray 'martin' or 'martial' identifier breaks the whole script), uninitialised references and bad canvas values, so the HUD paints but the 3D scene stays black
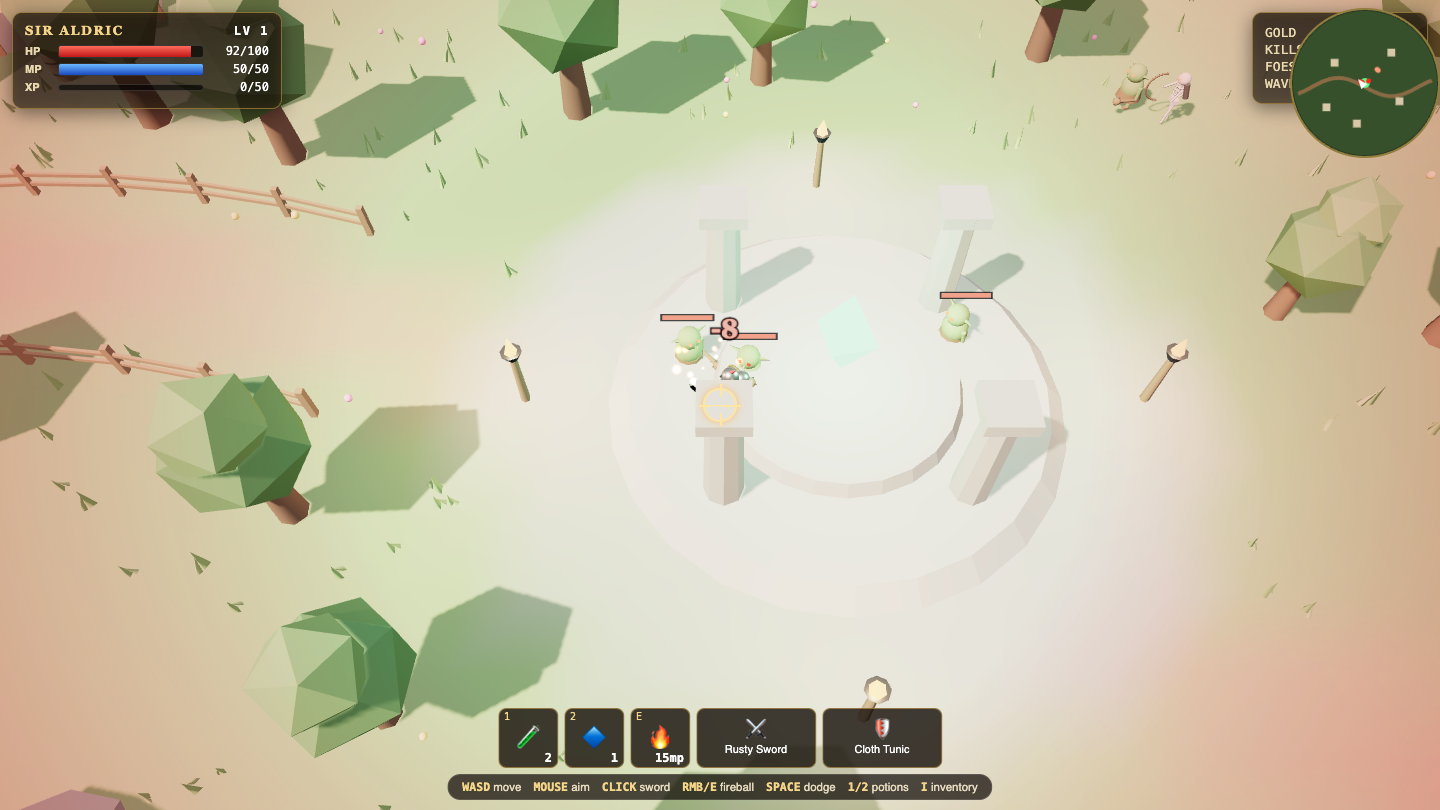
- Two hard crashes: the RPG threw an engine fault on load and the solar system rendered nothing at all
- It reasons for a long time at default effort: builds took 5 to 60 minutes each through OpenRouter
Pricing & context — the spec sheet
| Spec | Claude Opus 5.5 | MiMo-V2.6 Pro |
|---|---|---|
| Vendor | Anthropic | Xiaomi |
| Context window | 1,000,000 tokens | 1,000,000 tokens |
| Price | $4 / $20 per M | $0.435 in / $0.87 out per M tokens |
| Pricing detail | Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. | Xiaomi's September 2026 open-weight flagship (MIT licence, 1.02T total / 42B active parameters). $0.435 per million input tokens and $0.87 per million output on OpenRouter, with cache hits at a fraction of a cent, which is roughly a quarter of Grok 4.7 and a twentieth of the closed frontier models it scores level with on agent benchmarks. |
| Release | 2026-09 | 2026-09 |
| Bench coverage | 50/50 scored · avg 7.57/10 | 50/50 scored · avg 6.35/10 |
The verdict — which should you pick?
Across 50 scored shared tasks, Claude Opus 5.5 averaged 7.57/10, beating MiMo-V2.6 Pro's 6.35/10 by 1.22 points. Pick Claude Opus 5.5 when the build has to ship on the first prompt and you can afford the trade-offs in the comparison below.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire Claude Opus 5.5 and MiMo-V2.6 Pro both into the Agent Operating System and dispatch each from the kanban by task type — hardest agentic builds → Claude Opus 5.5, simulations, shaders and visual scenes in one shot, at a fraction of frontier prices → MiMo-V2.6 Pro. That's the same setup I run for the 4,000+ founders inside the AI Profit Boardroom.
FAQ — Claude Opus 5.5 vs MiMo-V2.6 Pro
Which is better, Claude Opus 5.5 or MiMo-V2.6 Pro?
On Goldie Bench, Claude Opus 5.5 averages 7.57/10 across the shared tasks, with 0 gold, 0 silver, 1 bronze overall. MiMo-V2.6 Pro averages 6.35/10, with 5 gold, 8 silver, 4 bronze. MiMo-V2.6 Pro wins the head-to-head 29–20.
How much does Claude Opus 5.5 cost vs MiMo-V2.6 Pro?
Claude Opus 5.5: Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. MiMo-V2.6 Pro: Xiaomi's September 2026 open-weight flagship (MIT licence, 1.02T total / 42B active parameters). $0.435 per million input tokens and $0.87 per million output on OpenRouter, with cache hits at a fraction of a cent, which is roughly a quarter of Grok 4.7 and a twentieth of the closed frontier models it scores level with on agent benchmarks.
What's the context window for Claude Opus 5.5 vs MiMo-V2.6 Pro?
Claude Opus 5.5 has a 1,000,000 tokens context window. MiMo-V2.6 Pro has a 1,000,000 tokens context window.
When should I pick Claude Opus 5.5 over MiMo-V2.6 Pro?
Pick Claude Opus 5.5 for: Hardest agentic builds; Whole-repo reasoning; Frontier one-shots. The trade-off is the weaknesses we logged on the bench: Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes; One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts).
When should I pick MiMo-V2.6 Pro over Claude Opus 5.5?
Pick MiMo-V2.6 Pro for: Simulations, shaders and visual scenes in one shot, at a fraction of frontier prices; High-volume agent work where an open, MIT-licensed model matters; Pair it with a self-fix loop for games: the failures are single broken tokens, not missing ideas. The trade-off is the weaknesses we logged on the bench: 18 of 50 builds scored under 5: long game files shipped with garbled tokens (a stray 'martin' or 'martial' identifier breaks the whole script), uninitialised references and bad canvas values, so the HUD paints but the 3D scene stays black; Two hard crashes: the RPG threw an engine fault on load and the solar system rendered nothing at all; It reasons for a long time at default effort: builds took 5 to 60 minutes each through OpenRouter.
How does Goldie Bench score Claude Opus 5.5 vs MiMo-V2.6 Pro?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
Claude Opus 5.5 vs Fusion MiMo-V2.6 Pro vs Fusion Claude Opus 5.5 vs Claude Opus 5 MiMo-V2.6 Pro vs Claude Opus 5 Claude Opus 5.5 vs Hermes MoA MiMo-V2.6 Pro vs Hermes MoA Claude Opus 5.5 vs GPT-5.6 Sol MiMo-V2.6 Pro vs GPT-5.6 SolFull model pages: Claude Opus 5.5 · MiMo-V2.6 Pro · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.
4,000+founders
258documented wins
38countries
$59/momonthly