Real head-to-head · same prompt, one shot
Claude Opus 5.5 vs Gemini 3.6 Flash
Anthropic's Opus 5.5 — benched on all 50 one-shot builds, every game playtested. vs Google's launch-day Flash — faster, cheaper, fewer tokens.
Head-to-head verdict: tied 23–23.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to Claude Opus 5.5 and Gemini 3.6 Flash, side by side, on 50 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
Claude Opus 5.5 · Benched on all 50 GoldieBench tasks via a Claude subscription: one-shot builds, real renders, pixel-diff playtests on every game, then vision-judged.
Gemini 3.6 Flash · Benched via the native Gemini API on launch day. Game tasks use the skill-infused threejs-game-director prompt (same as the rest of the field) and are judged on a real mid-play frame by the same Opus vision judge.
Side-by-side on 50 shared tasks
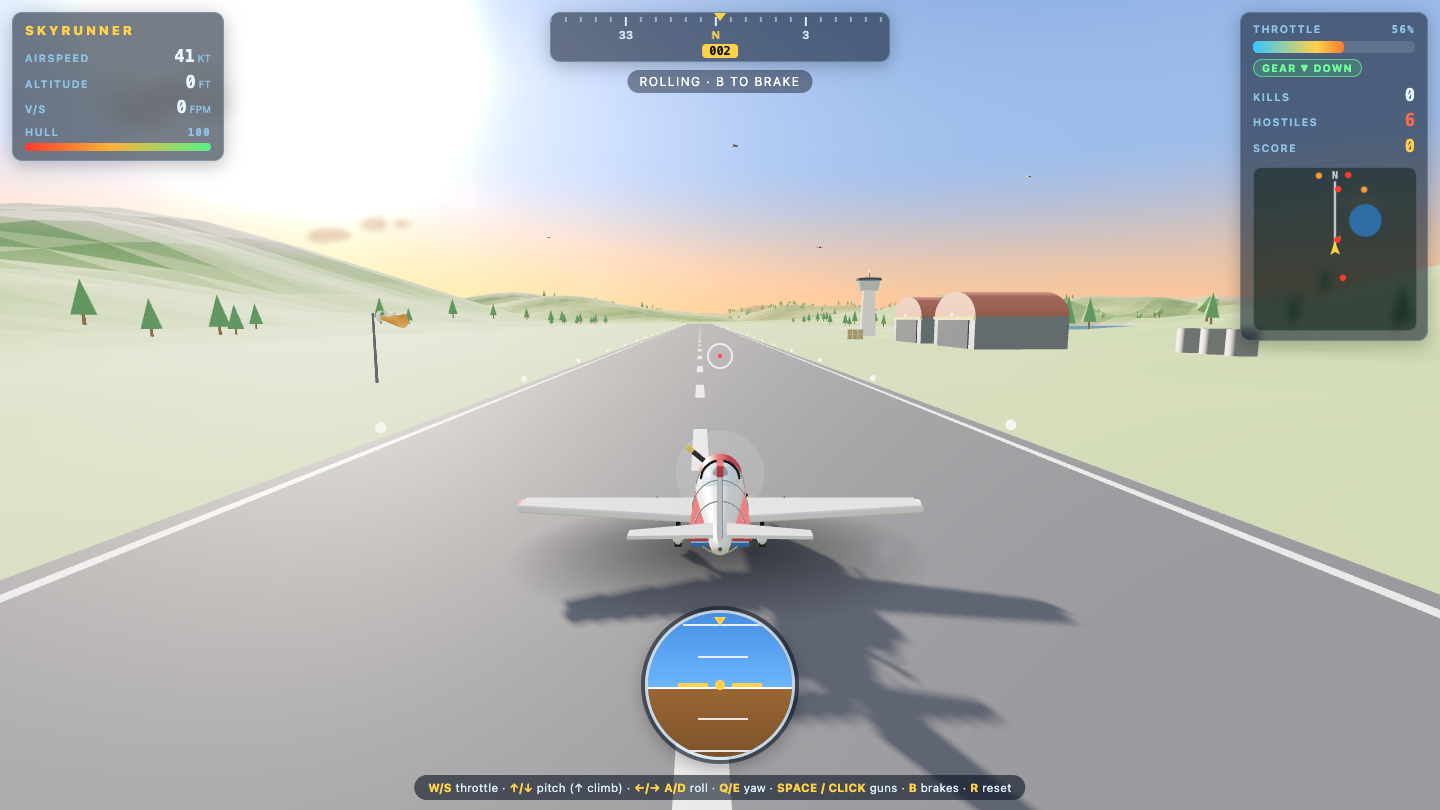
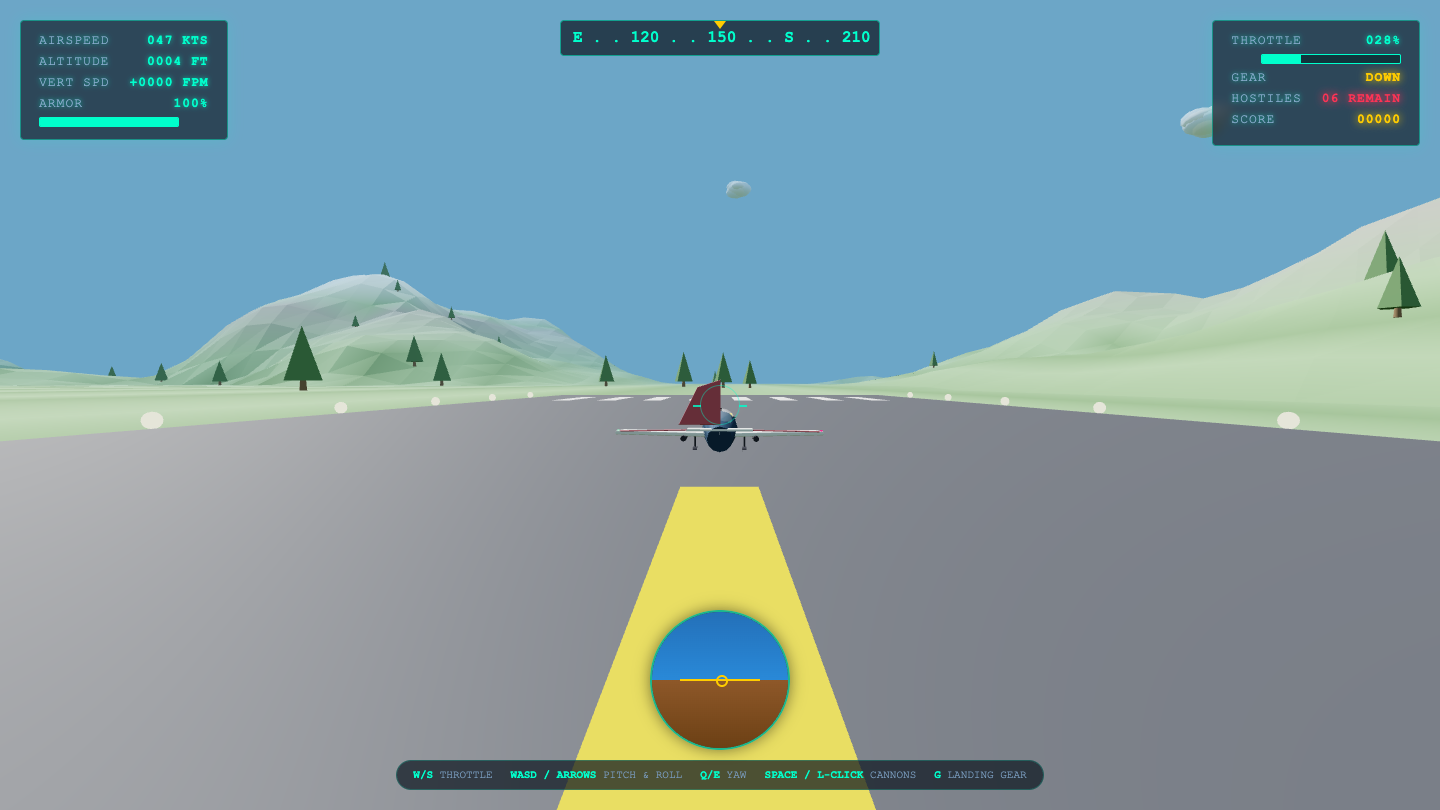
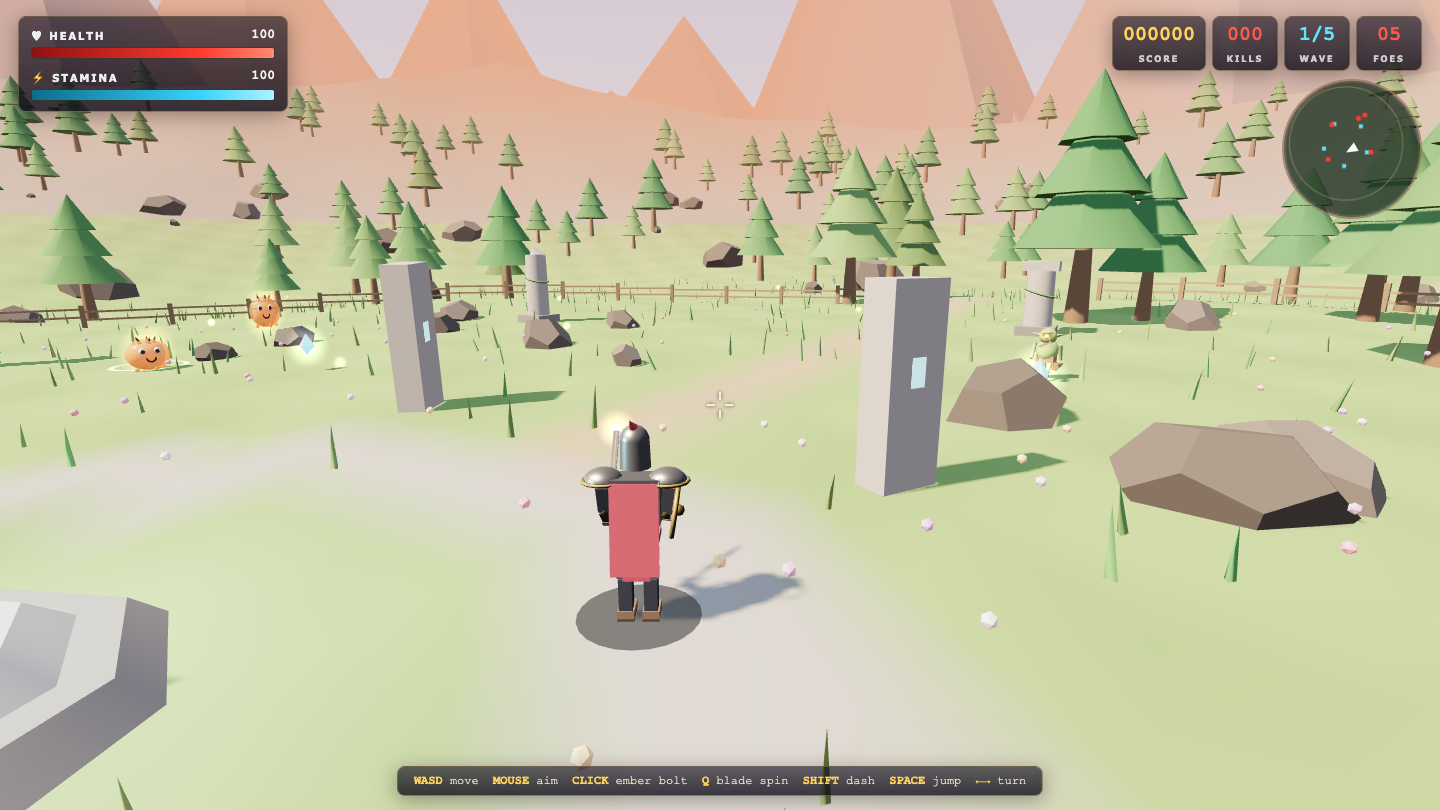
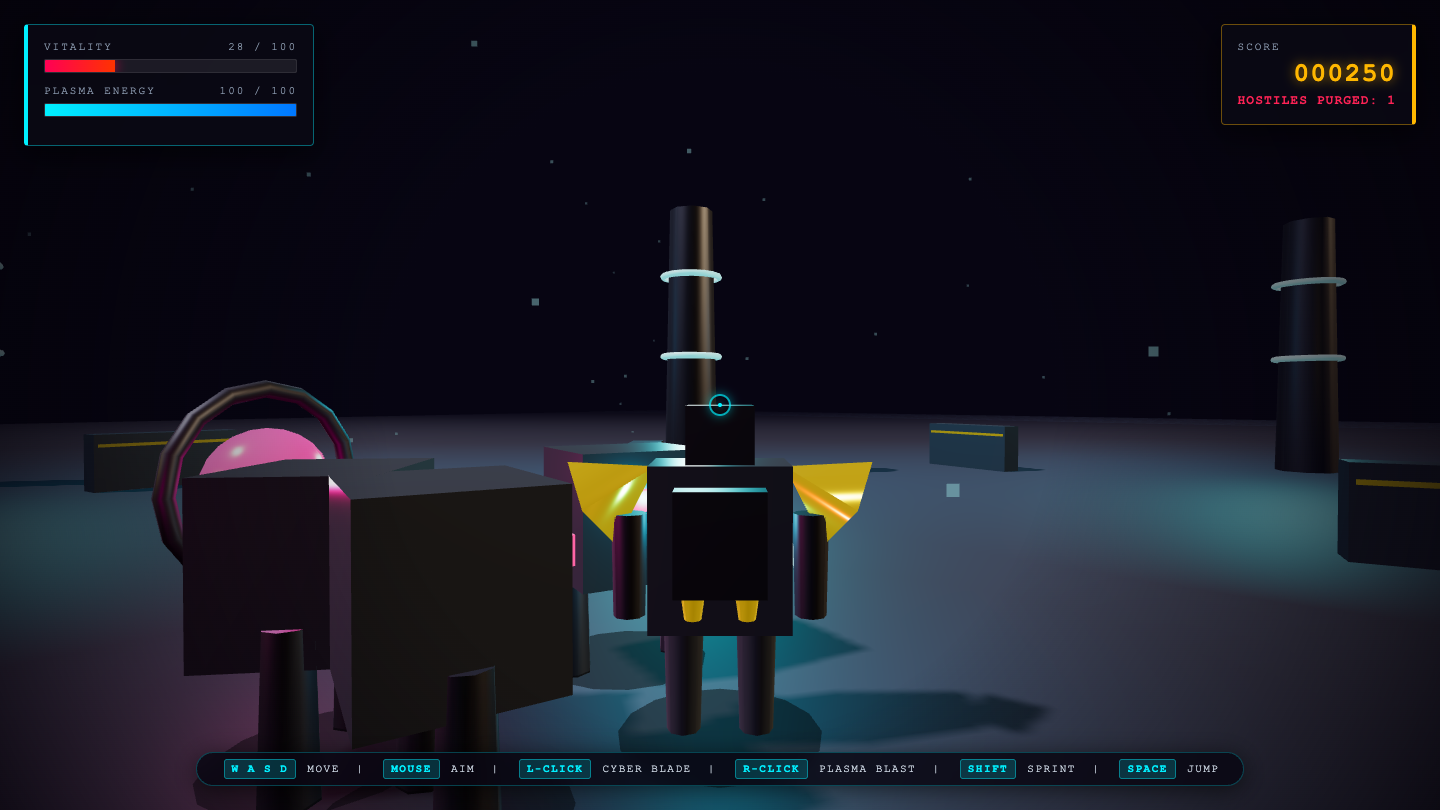
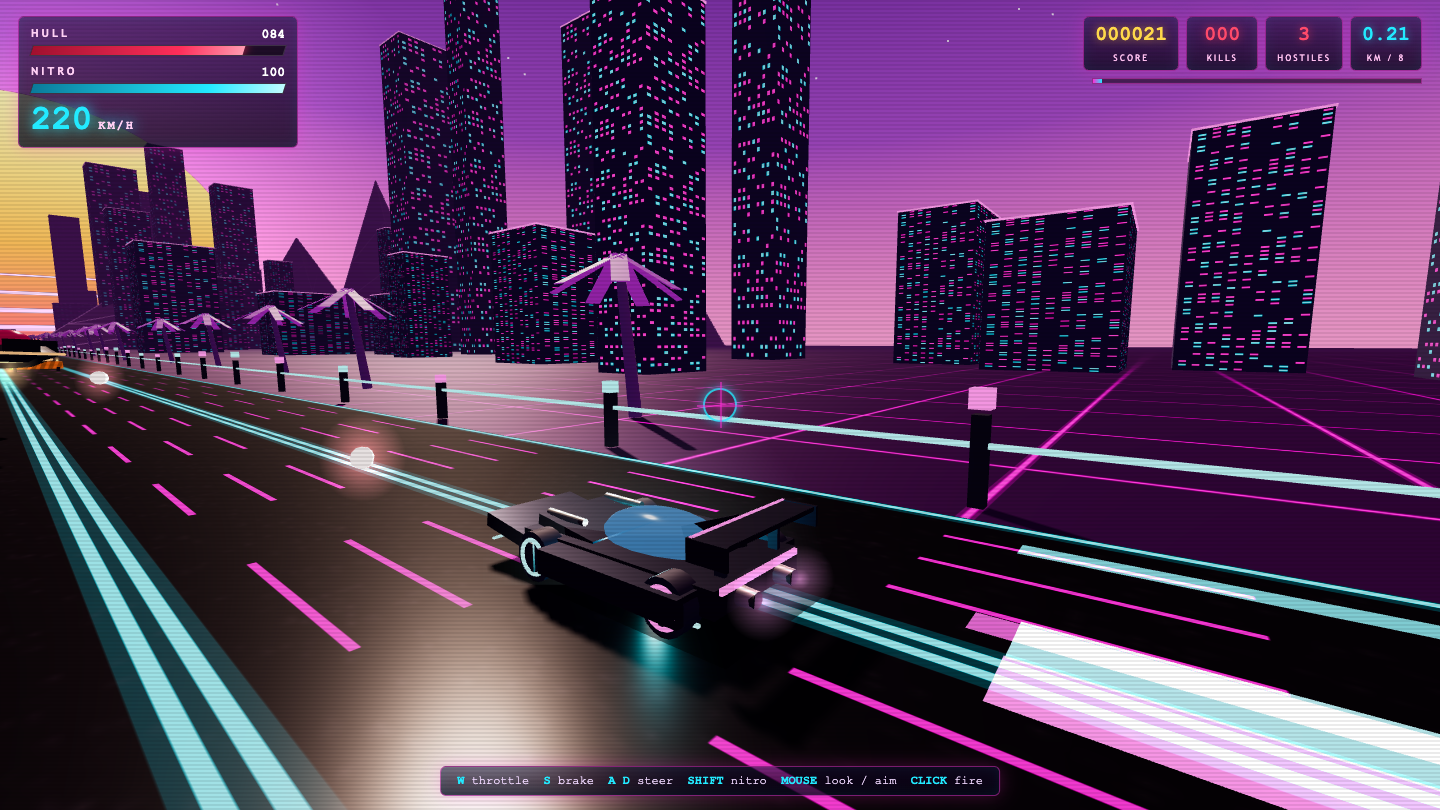
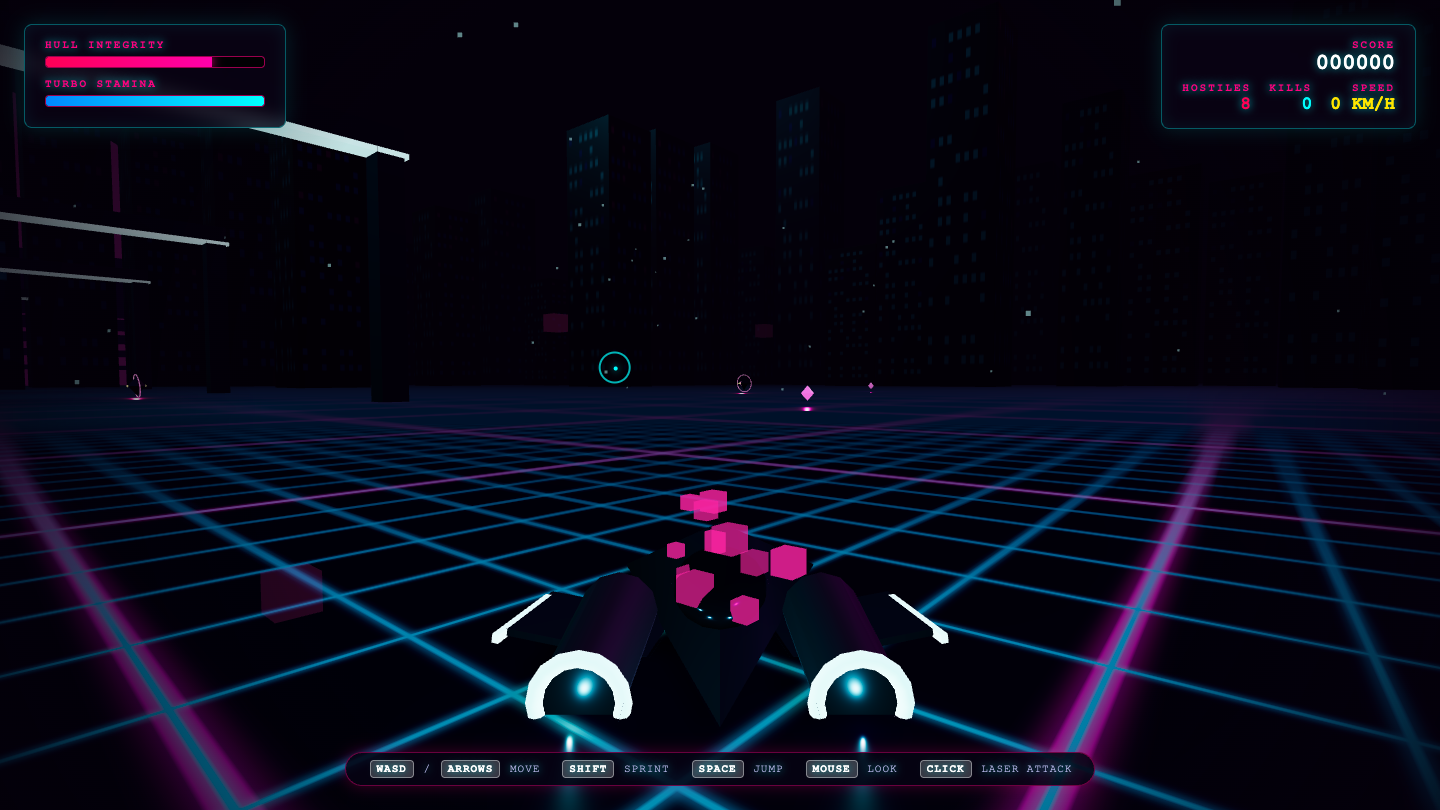
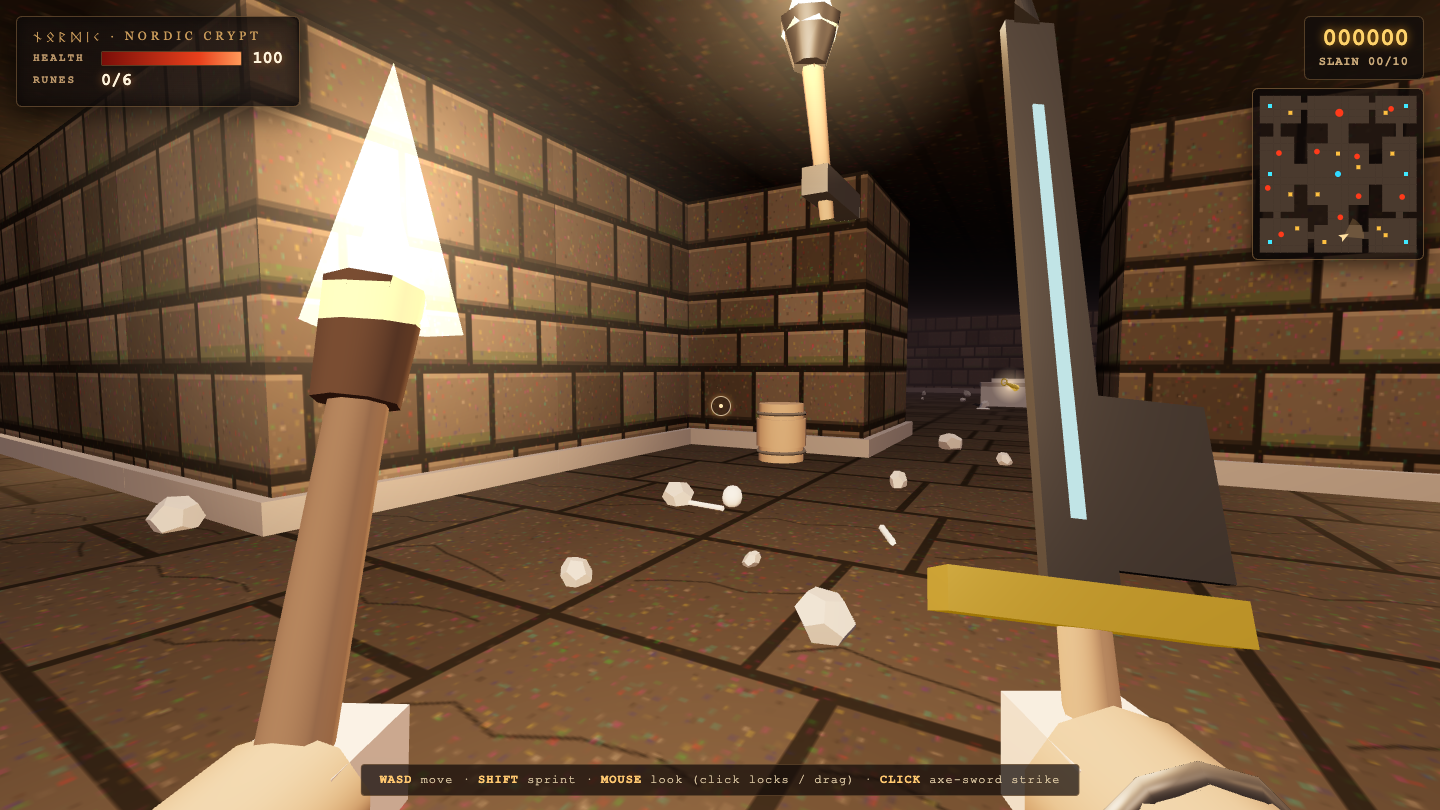
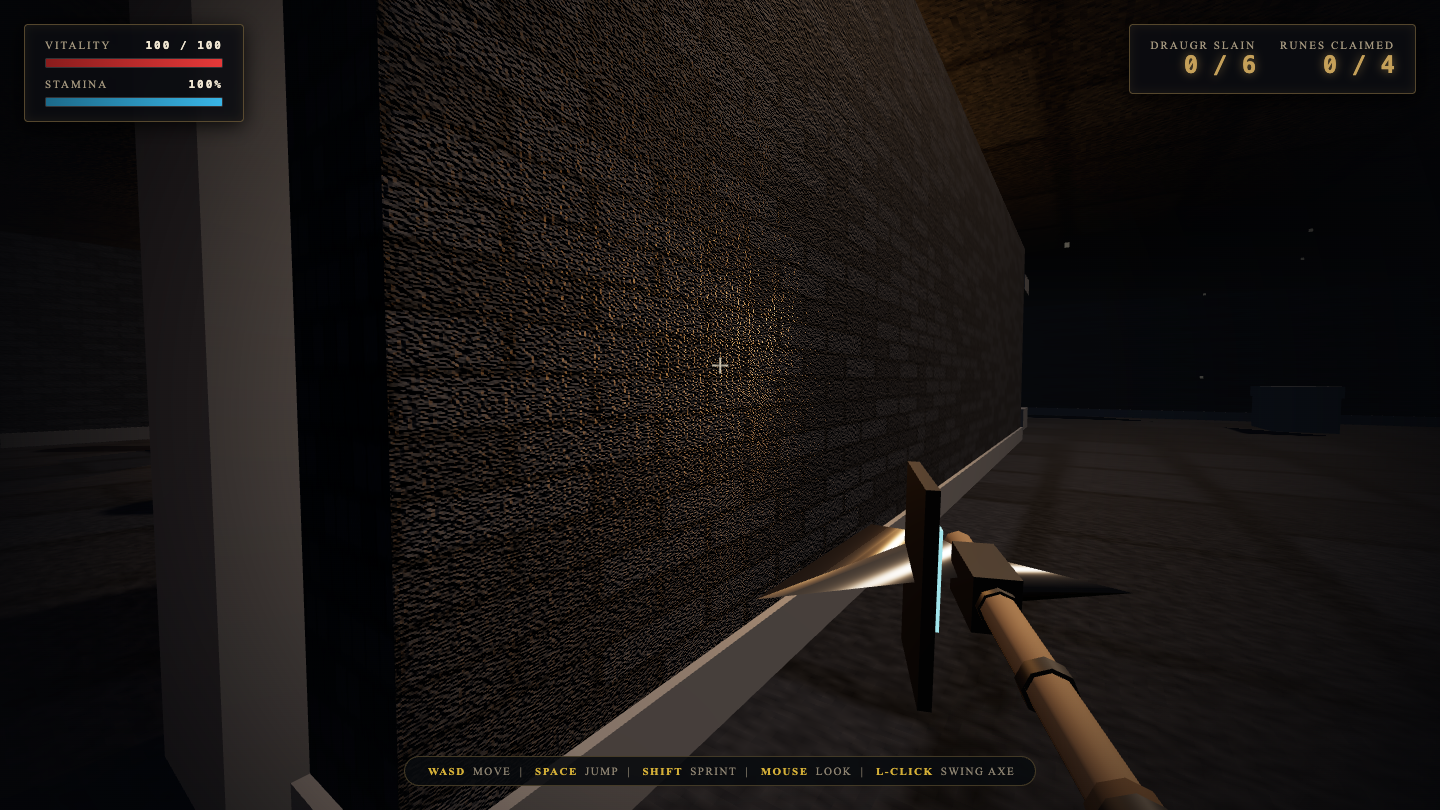
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
Claude Opus 5.5
Gemini 3.6 Flash
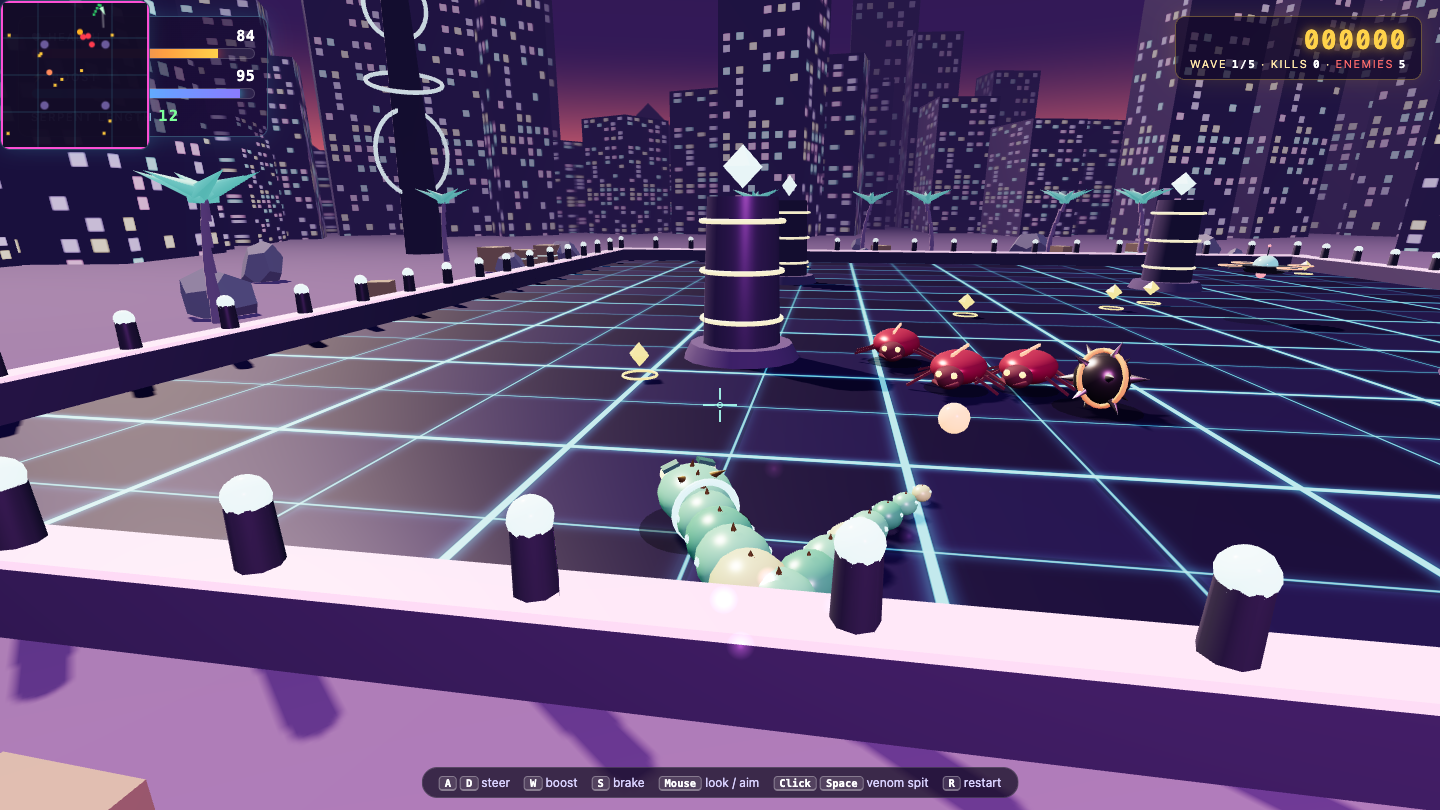
Game
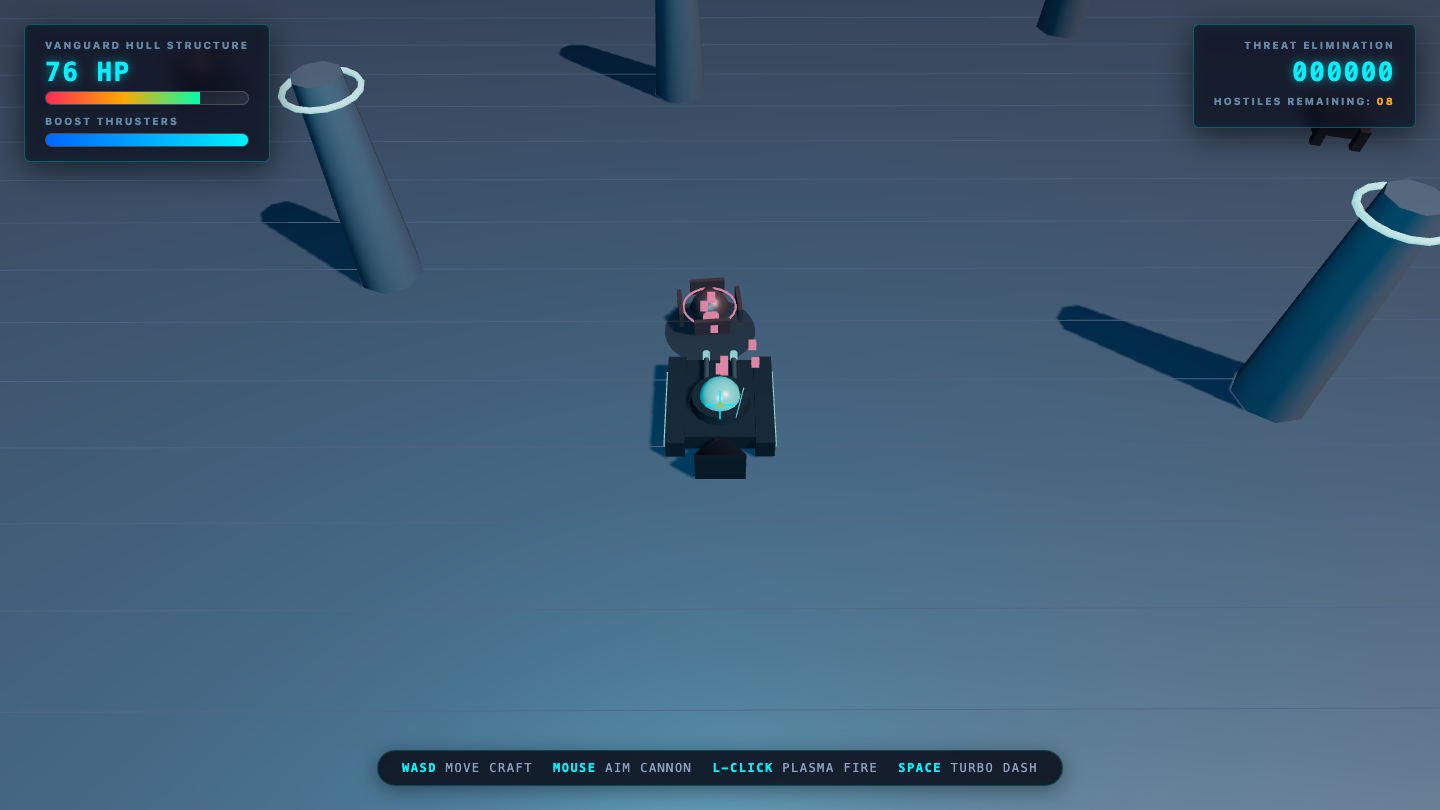
Game
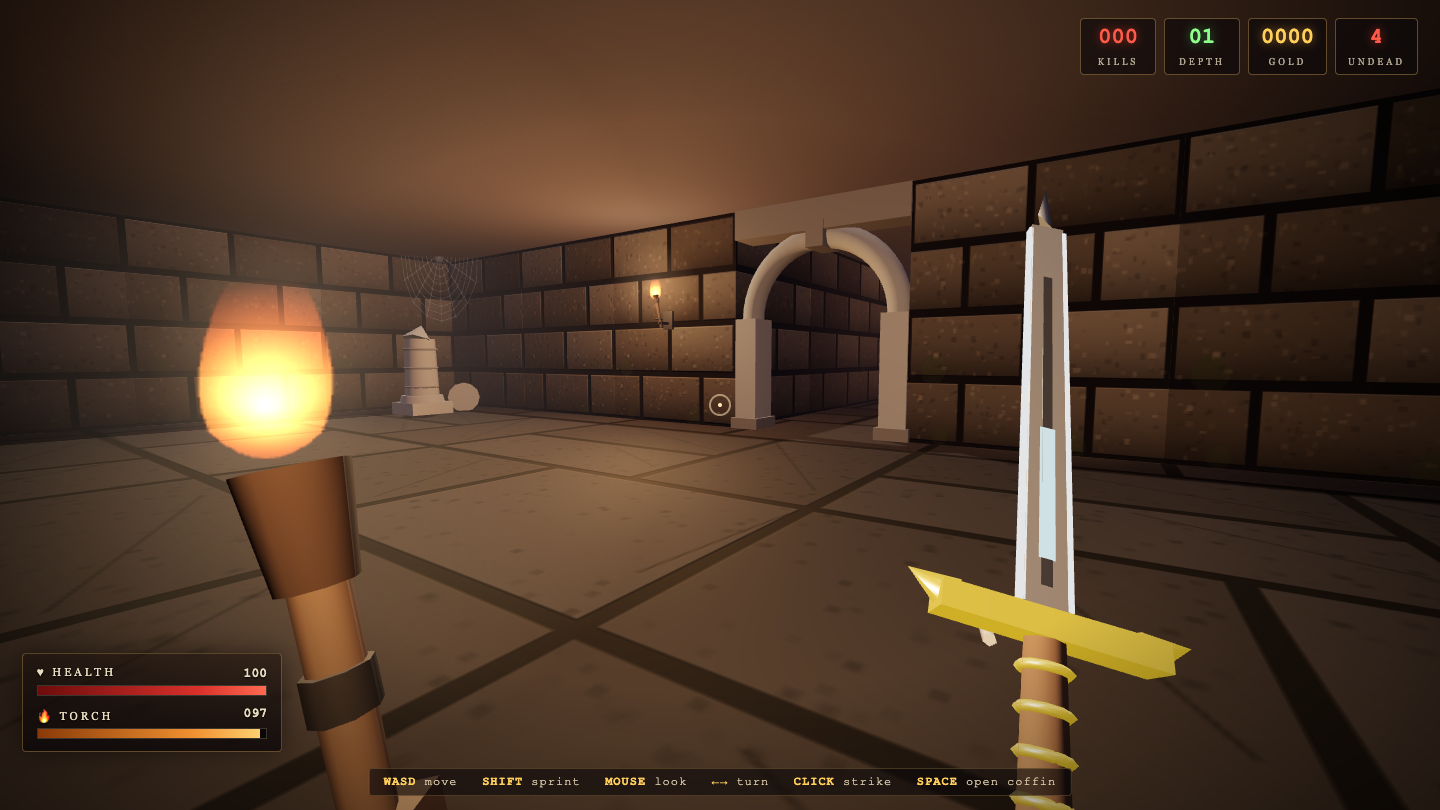
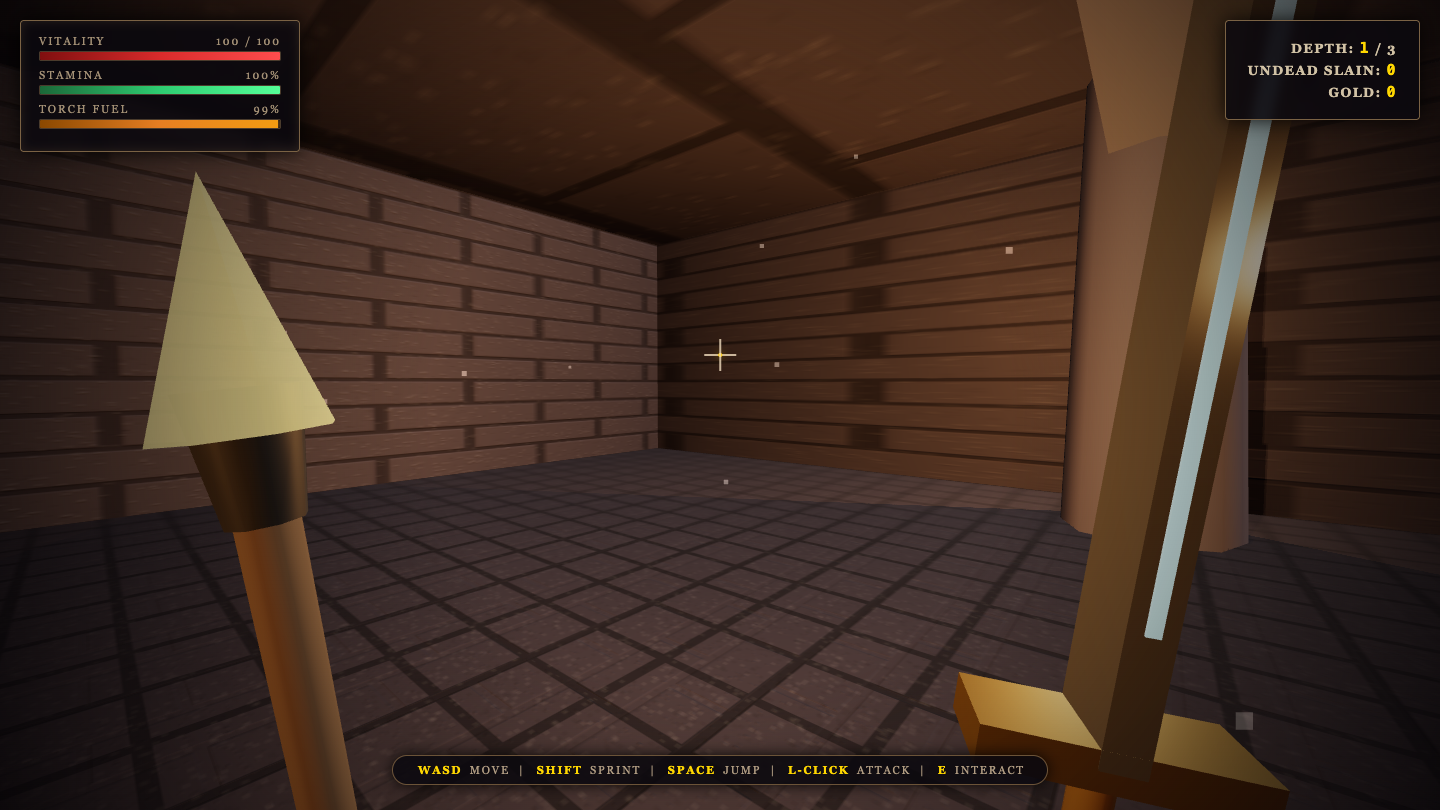
Game
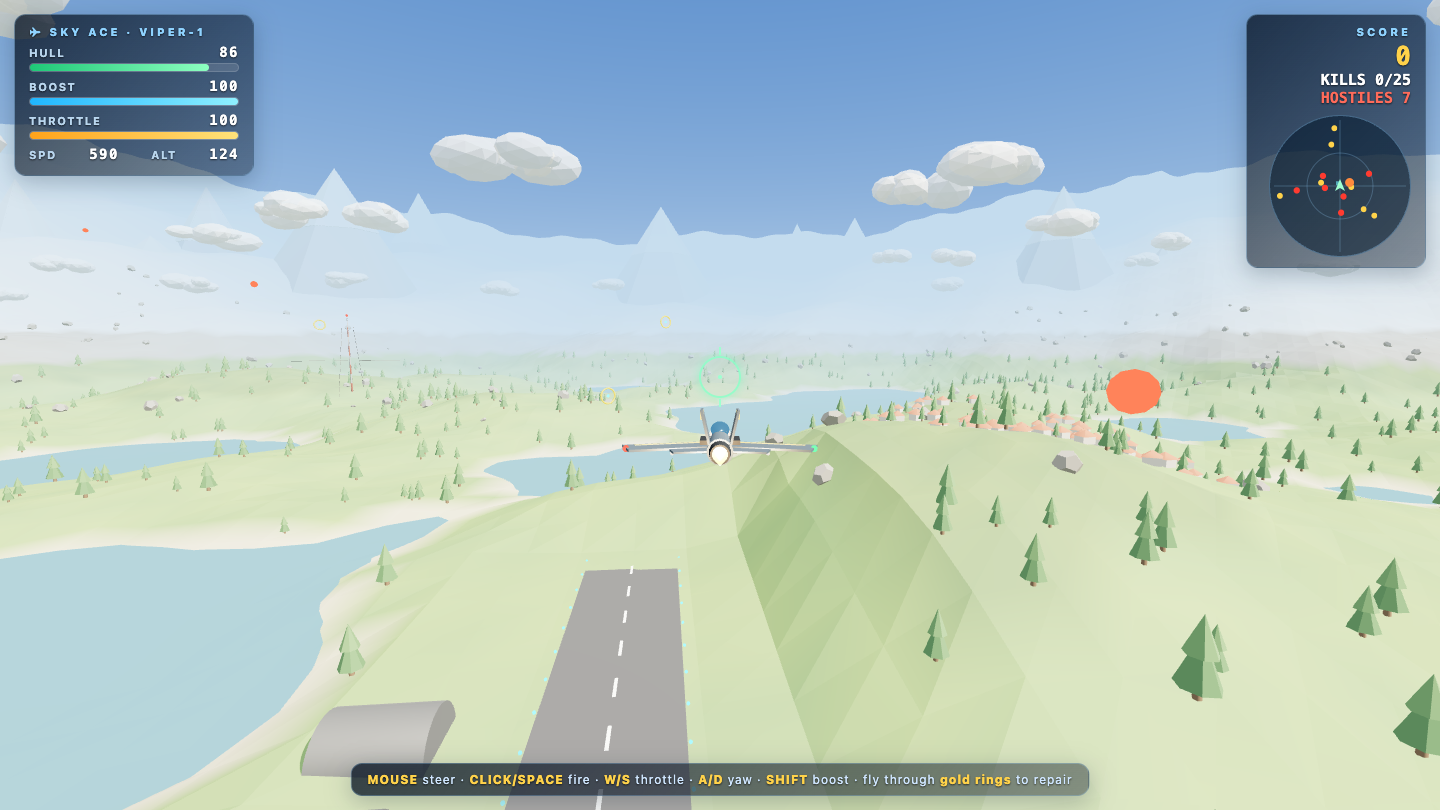
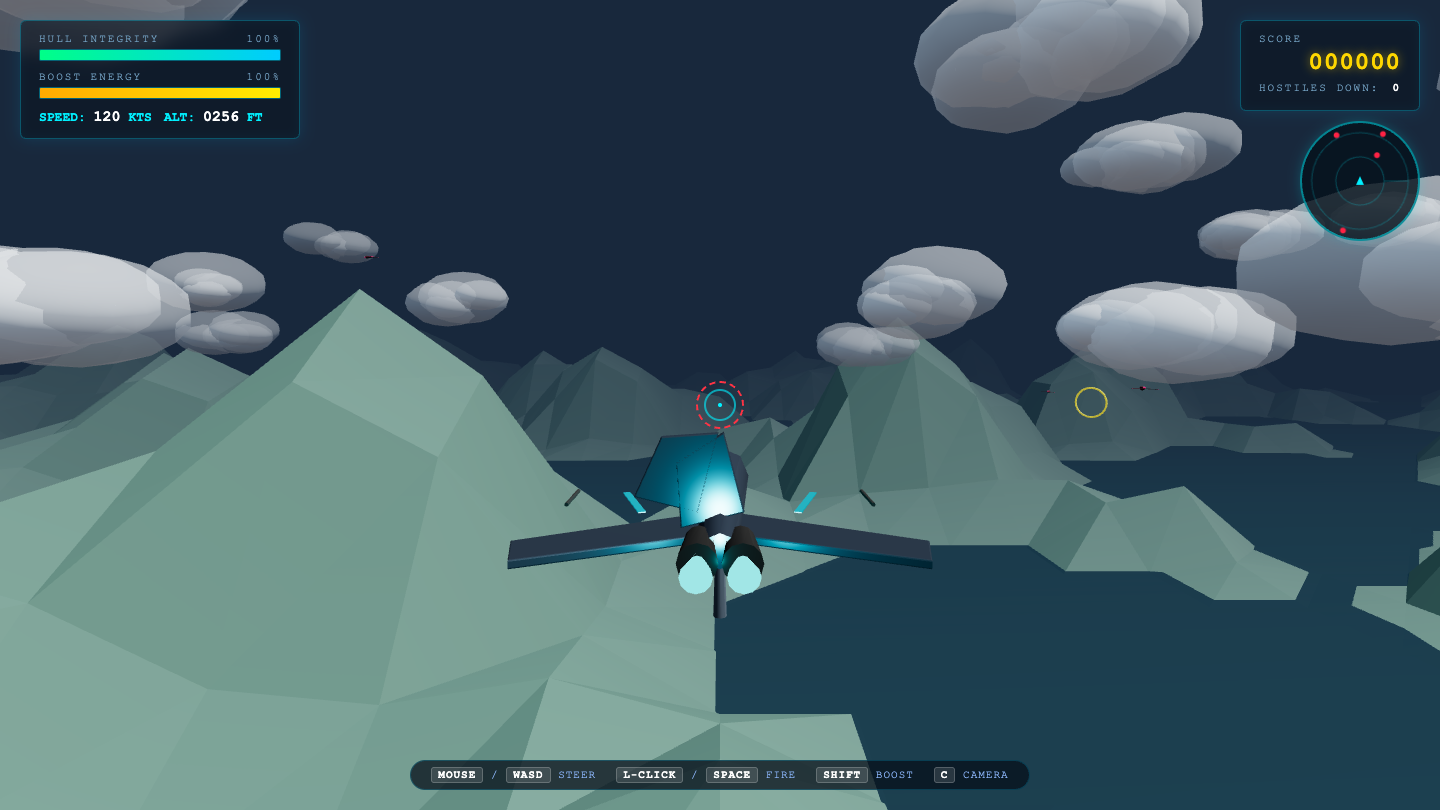
Game
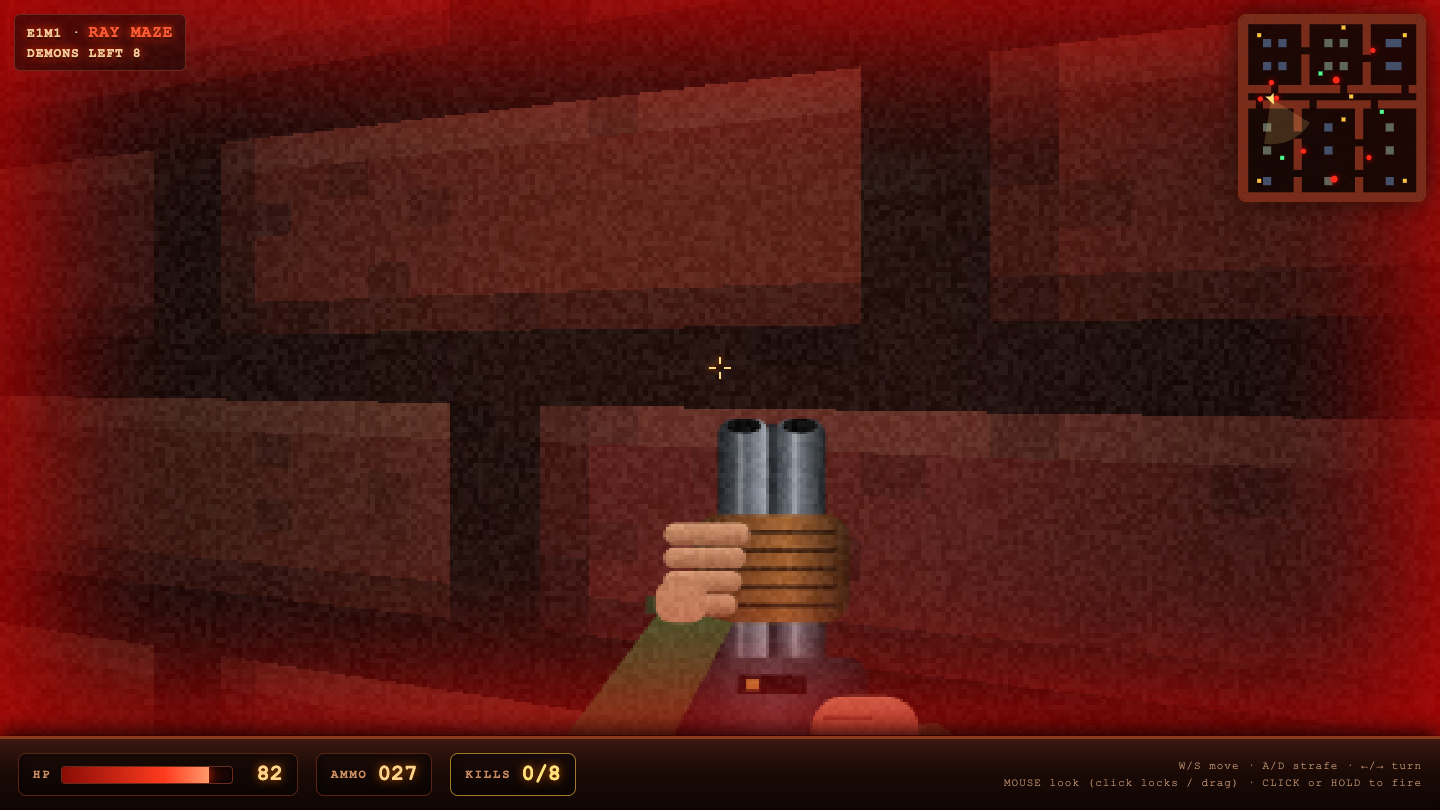
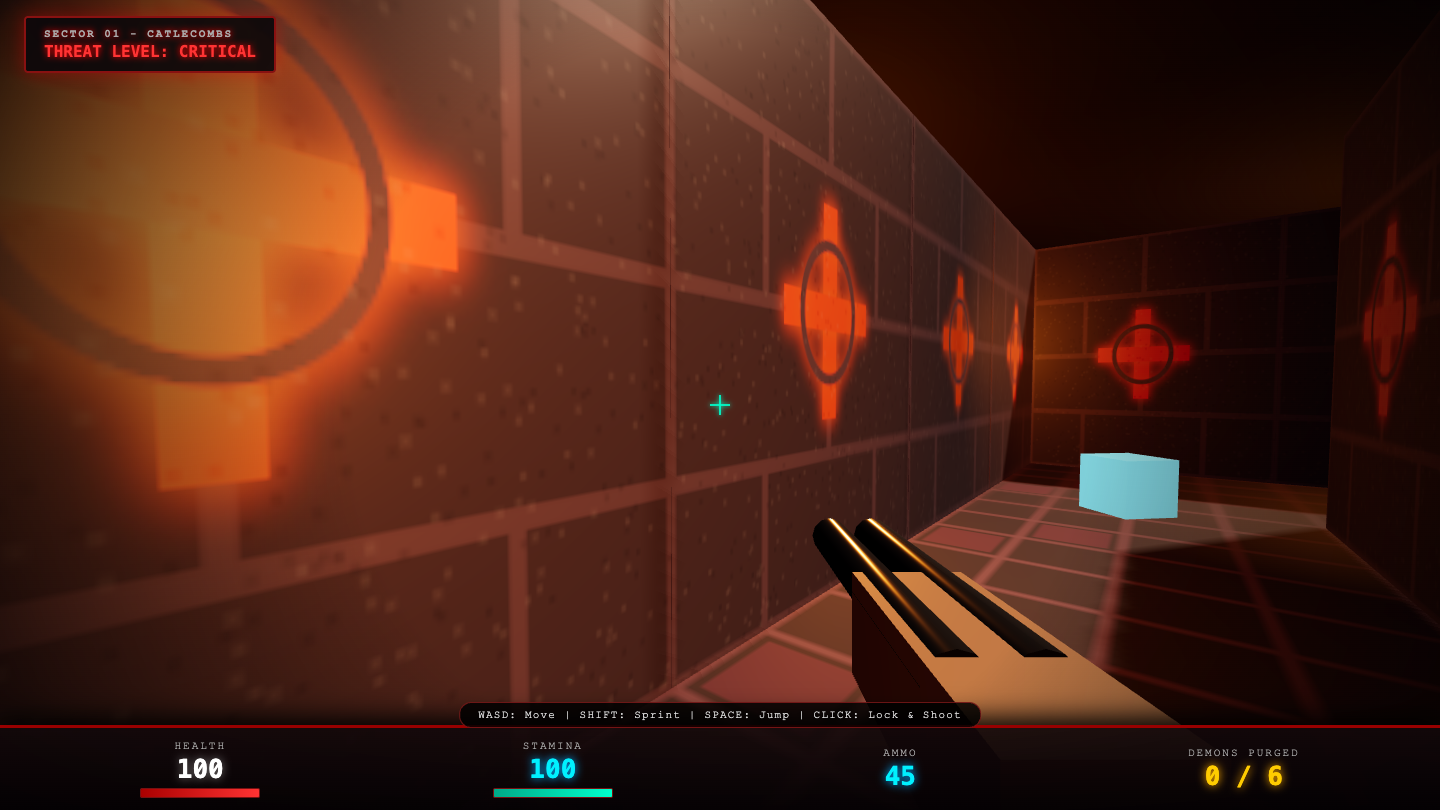
Game
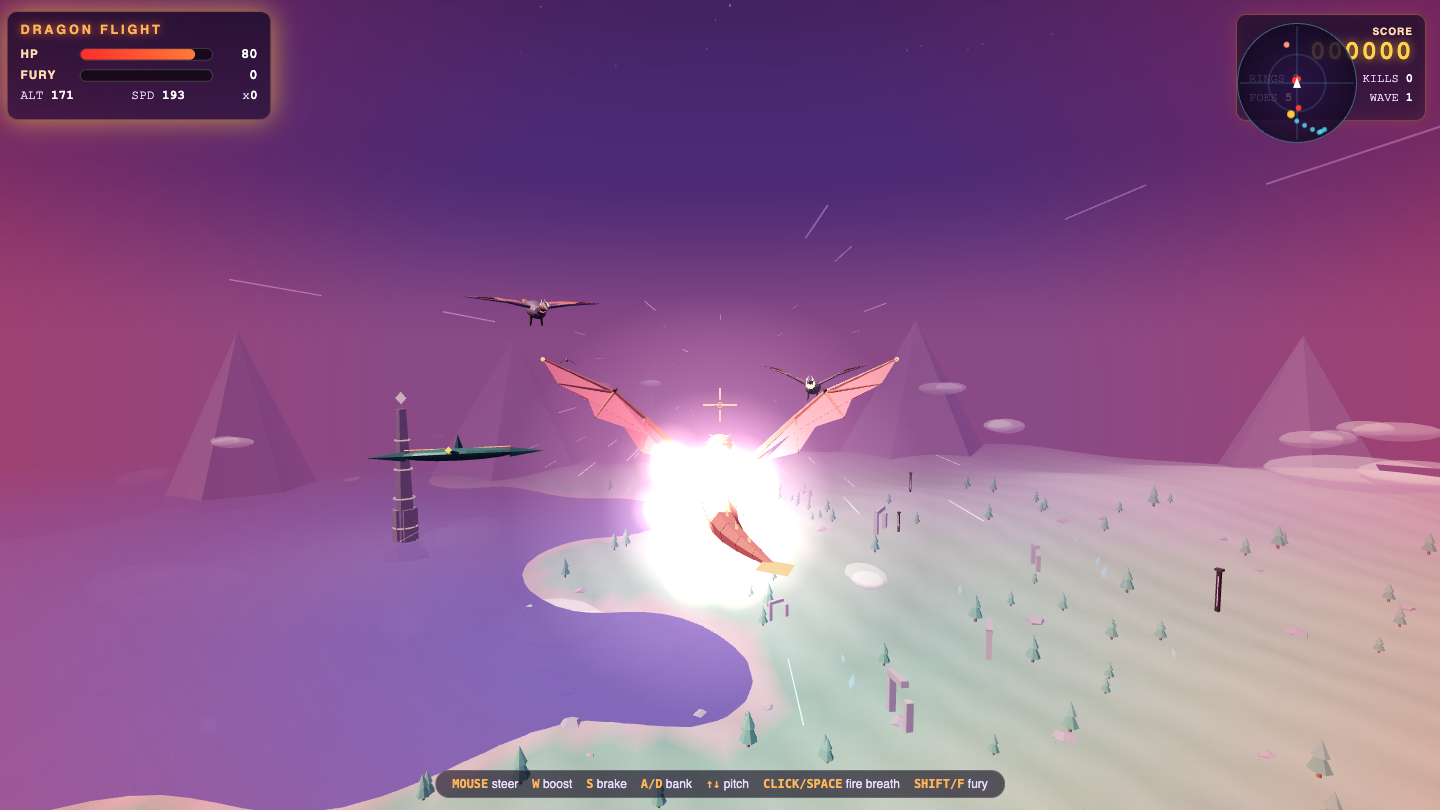
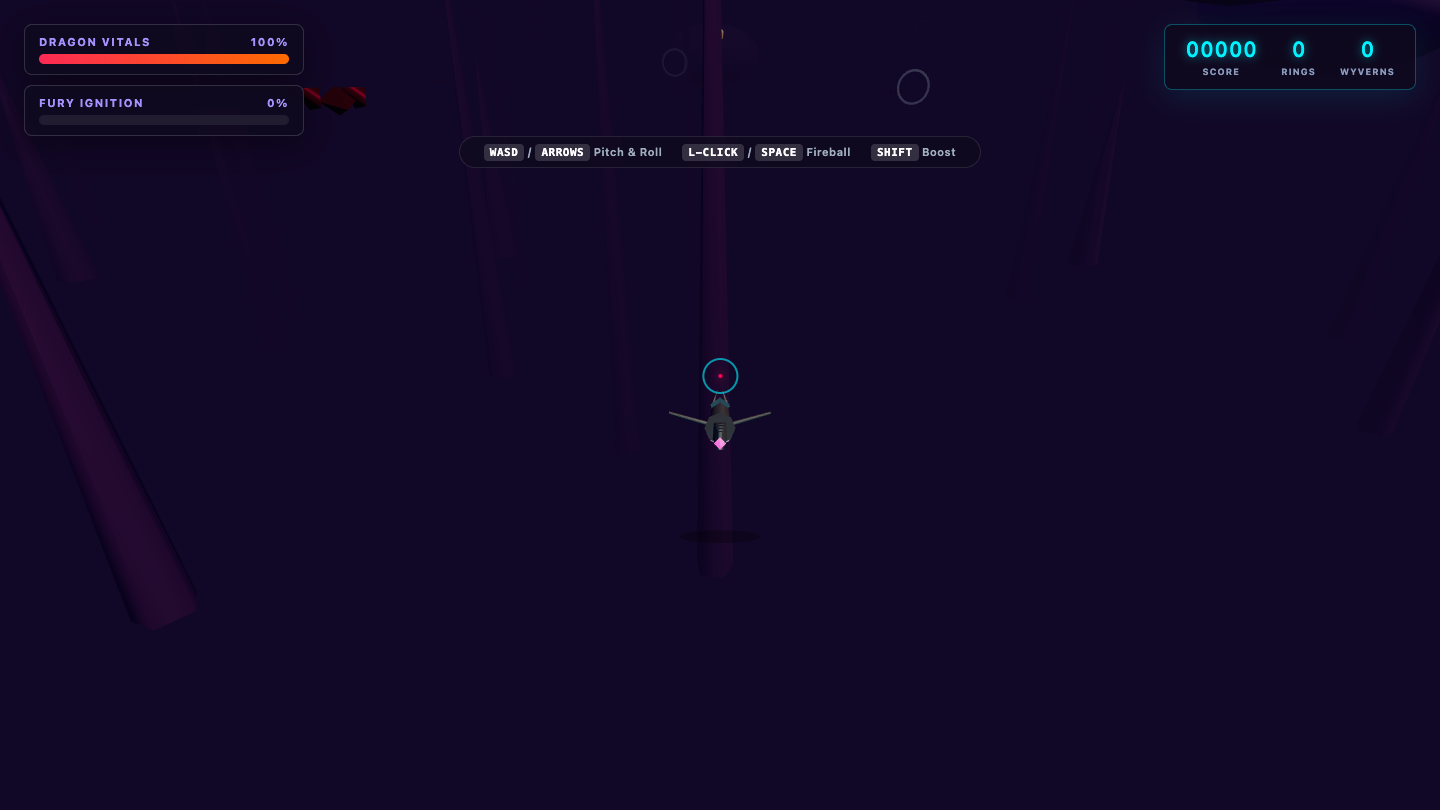
Game
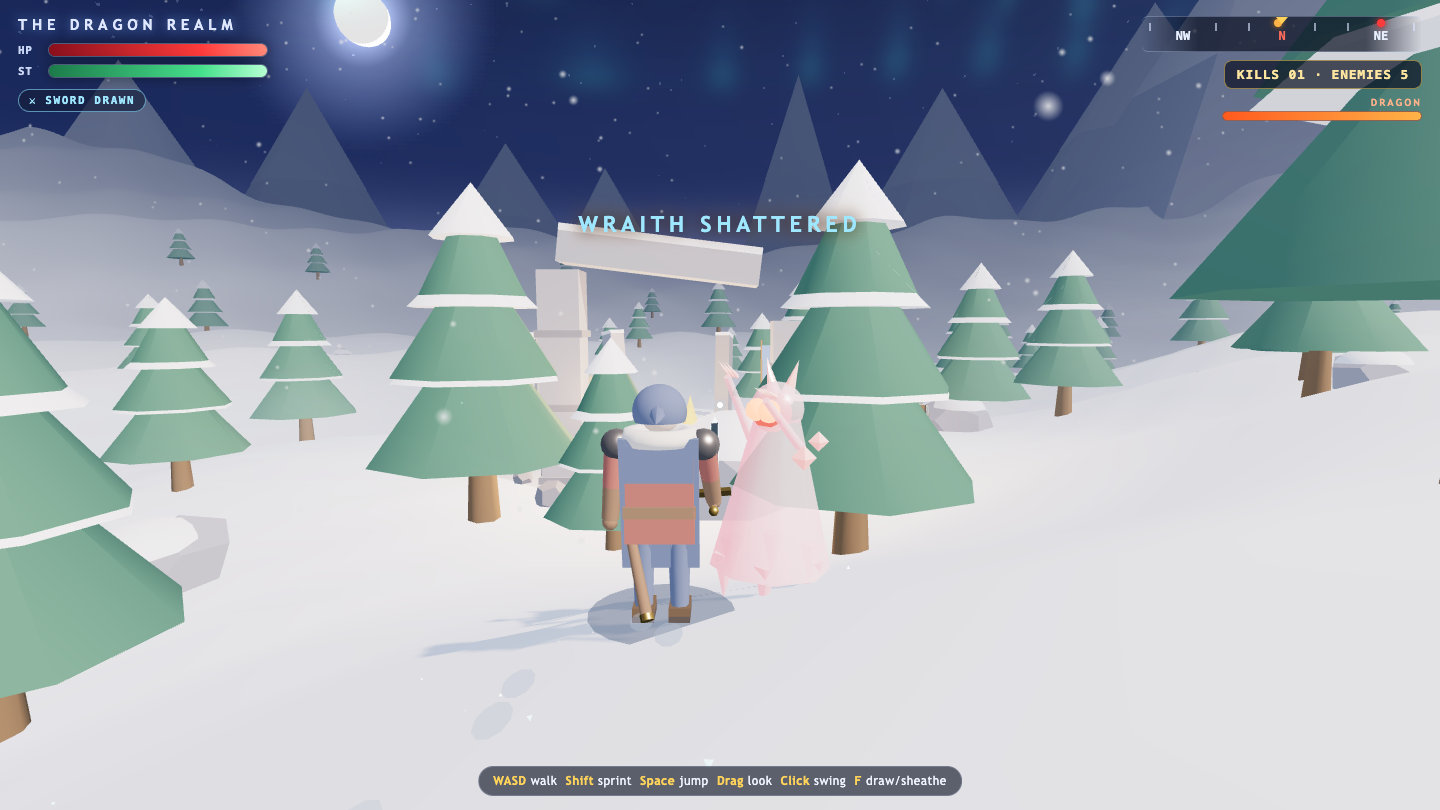
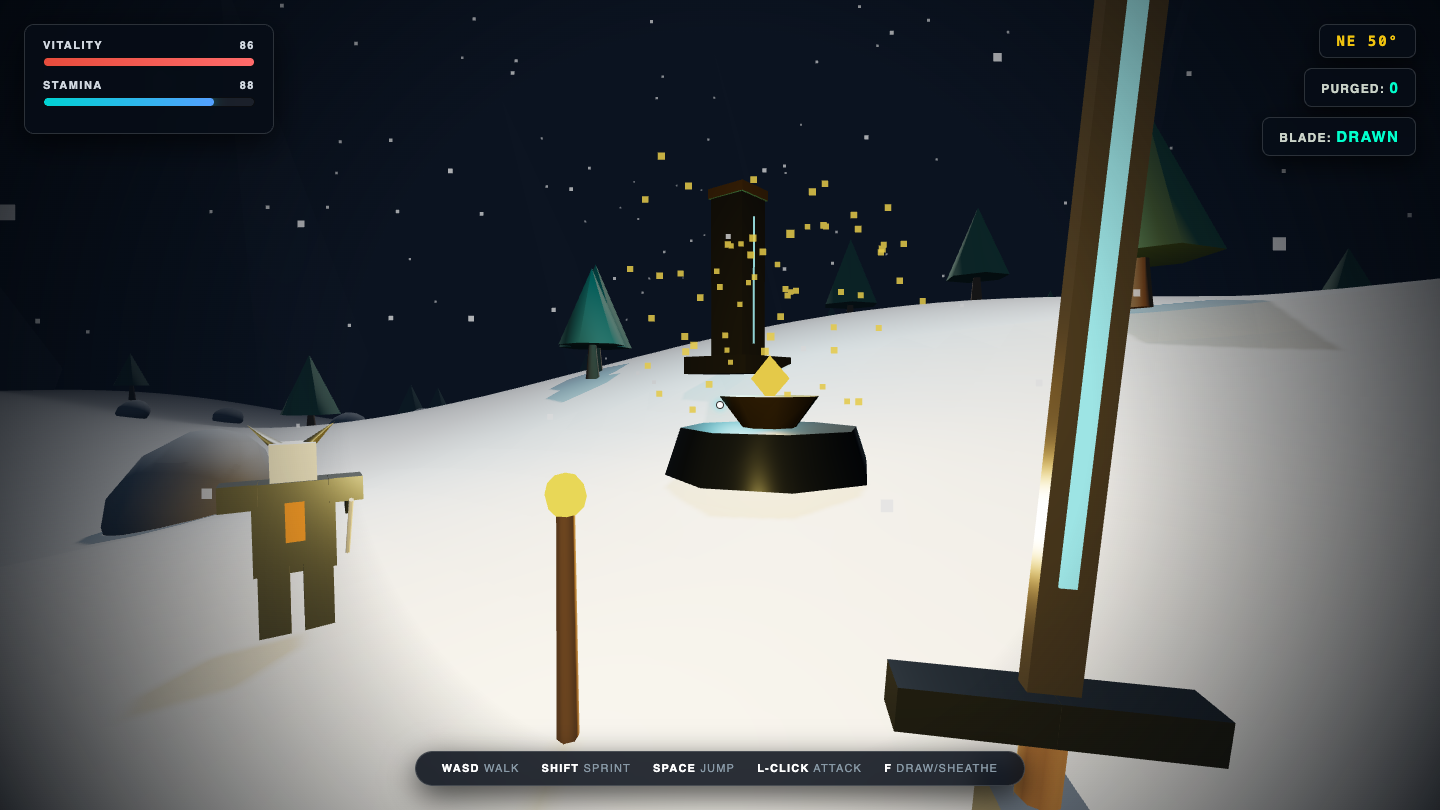
Game
Game
Game
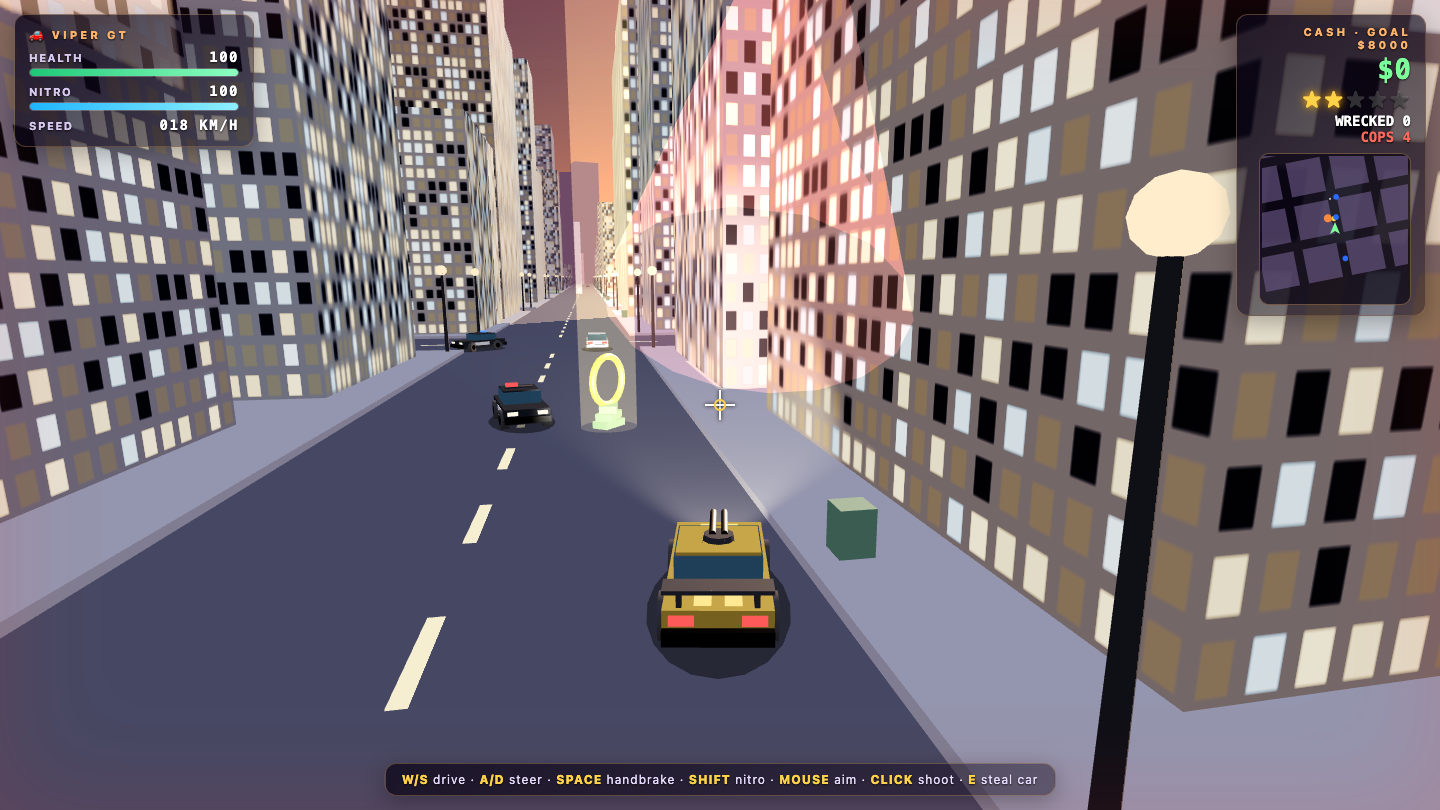
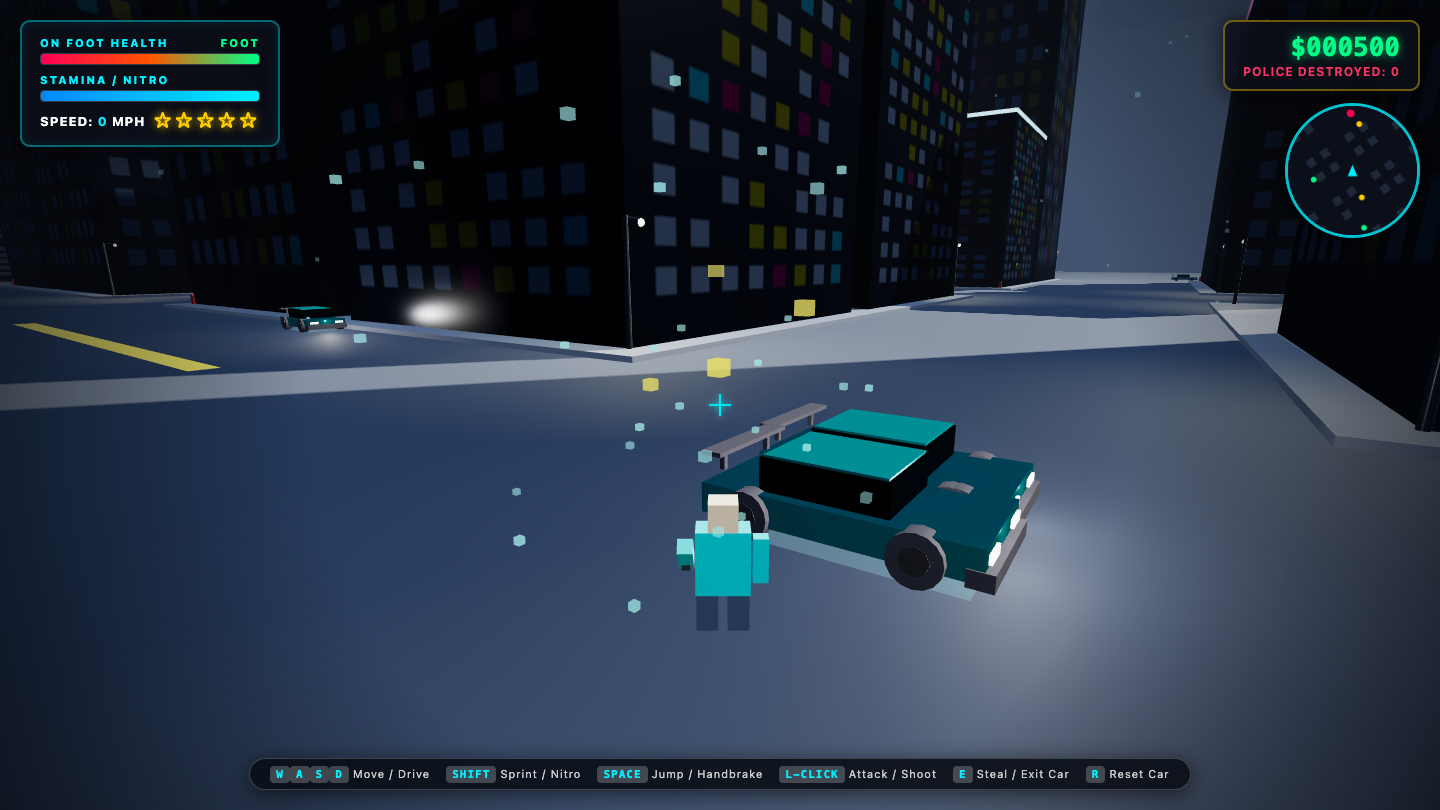
Game
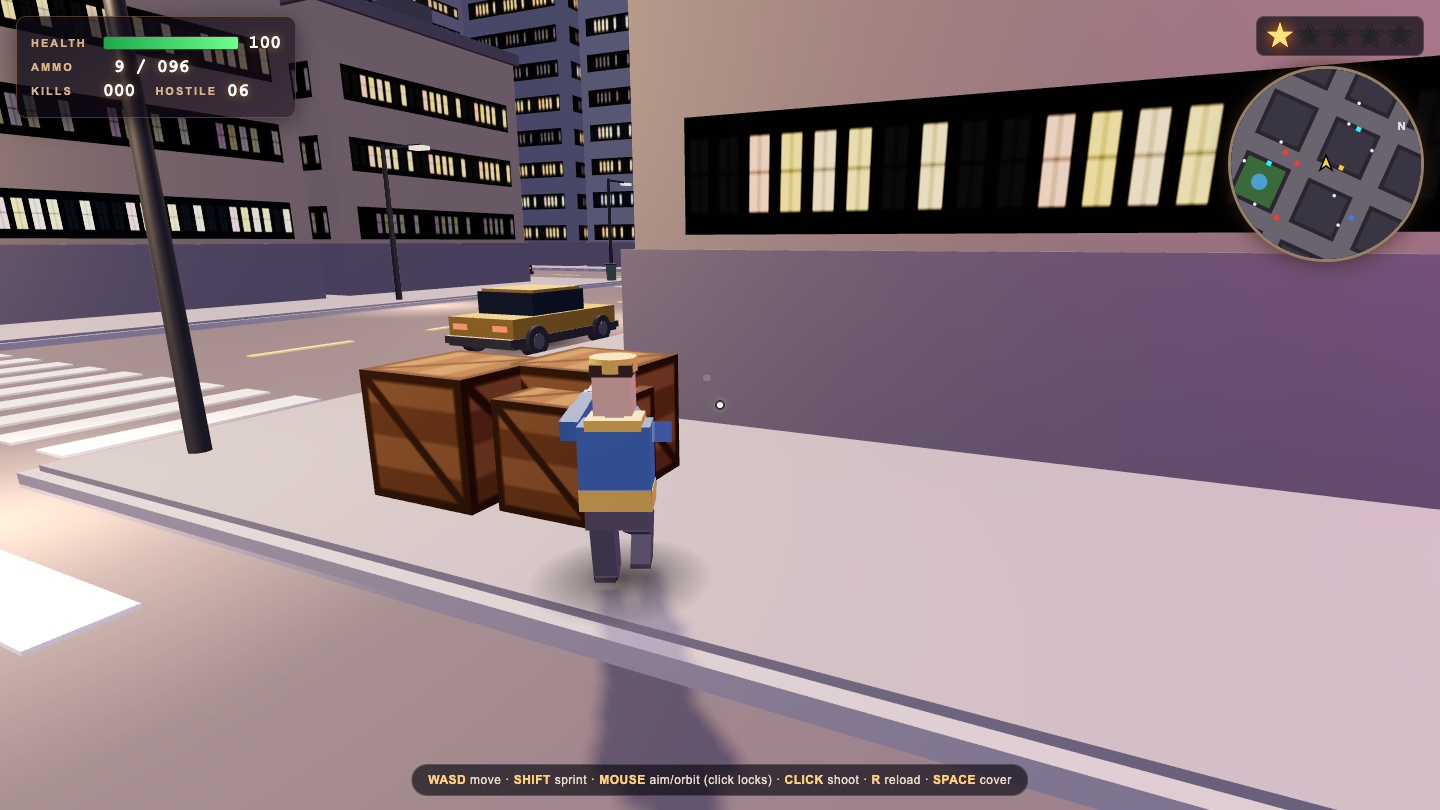
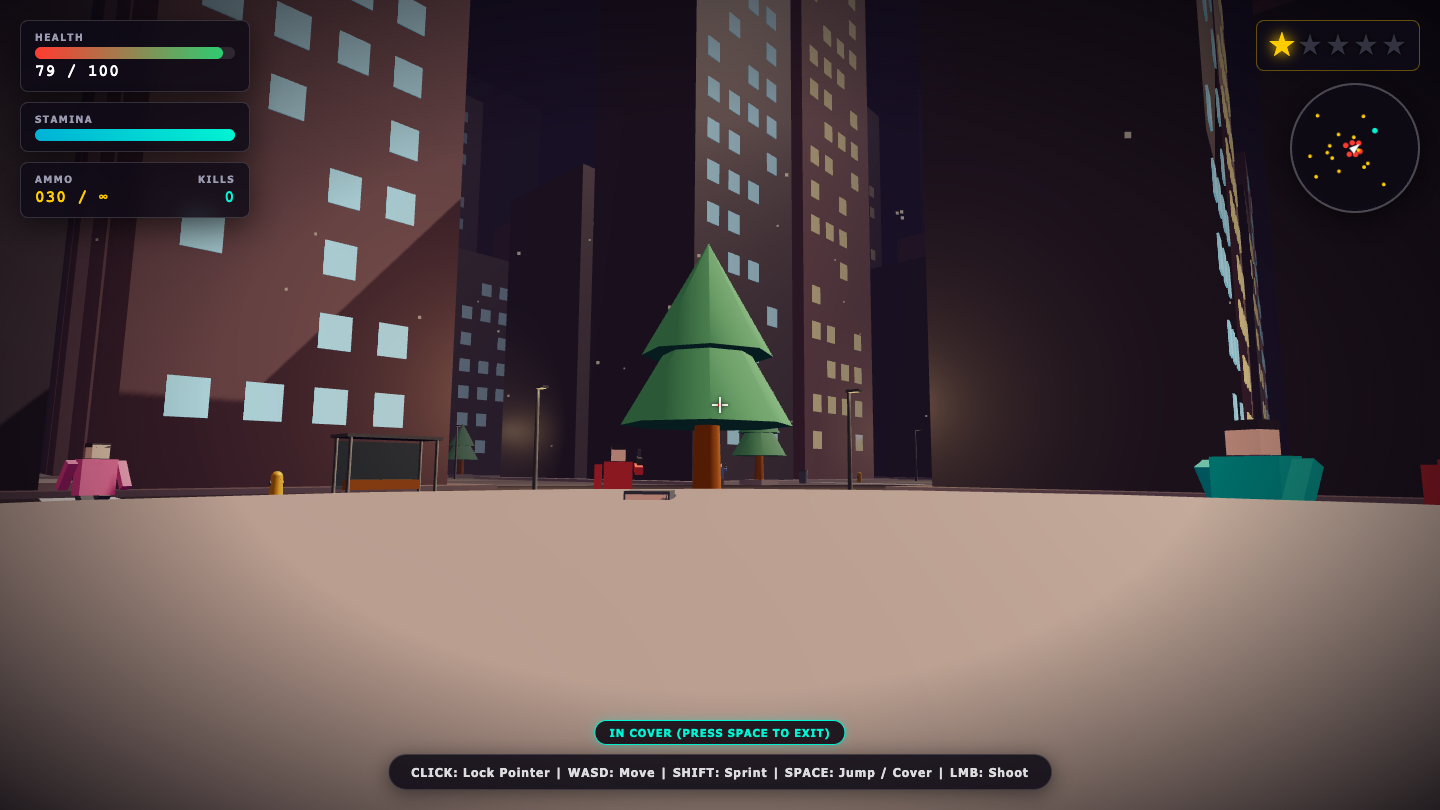
Game
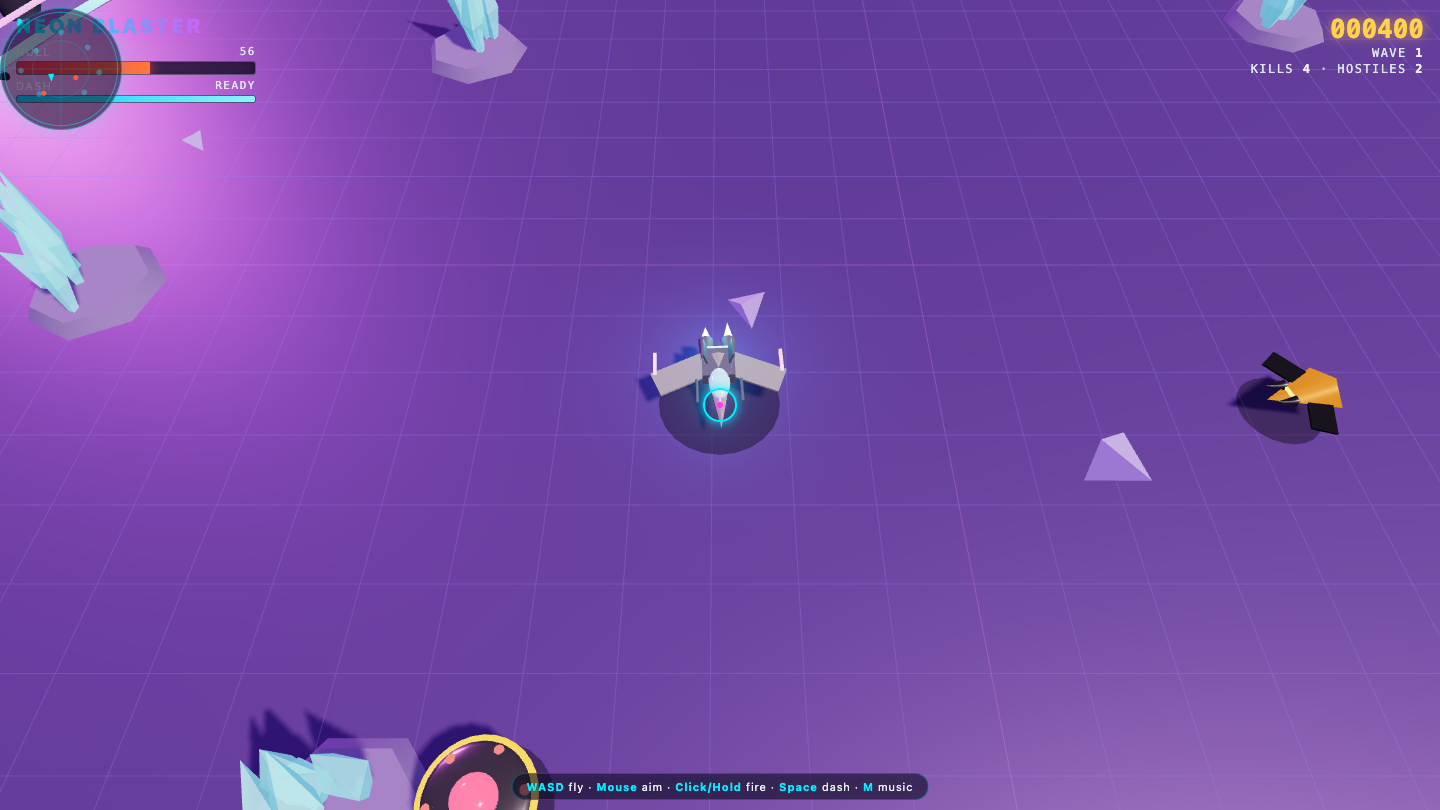
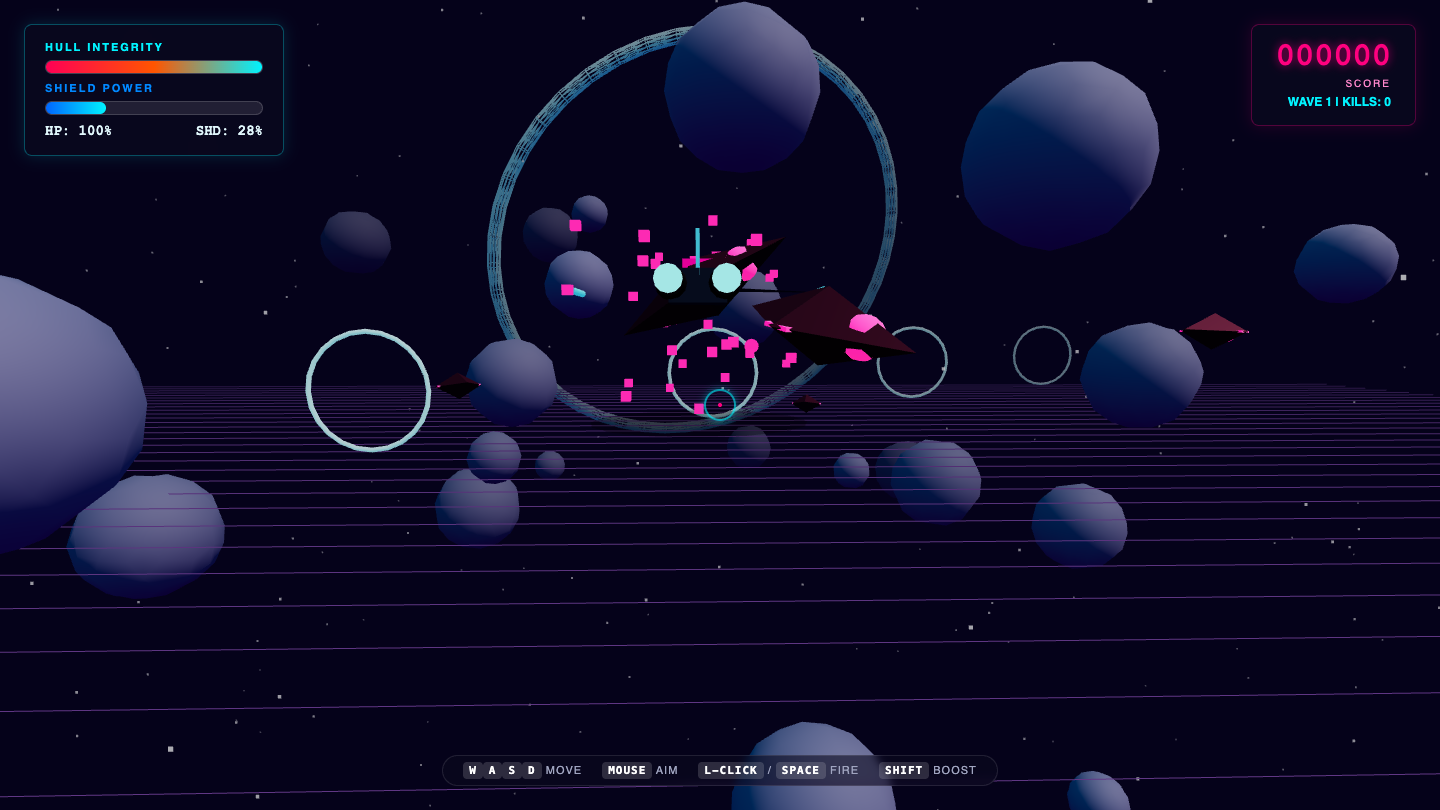
Game
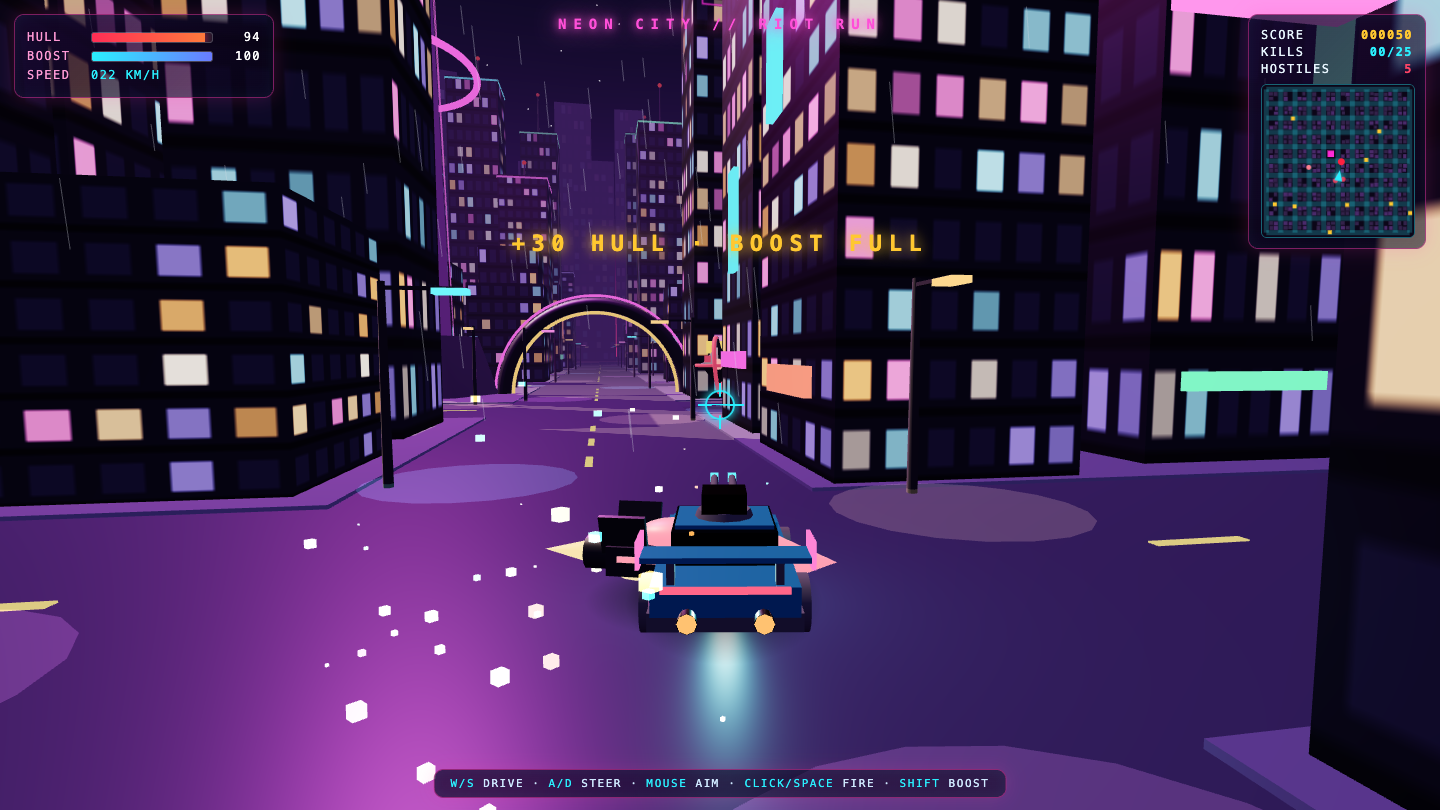
Game
Game
Game
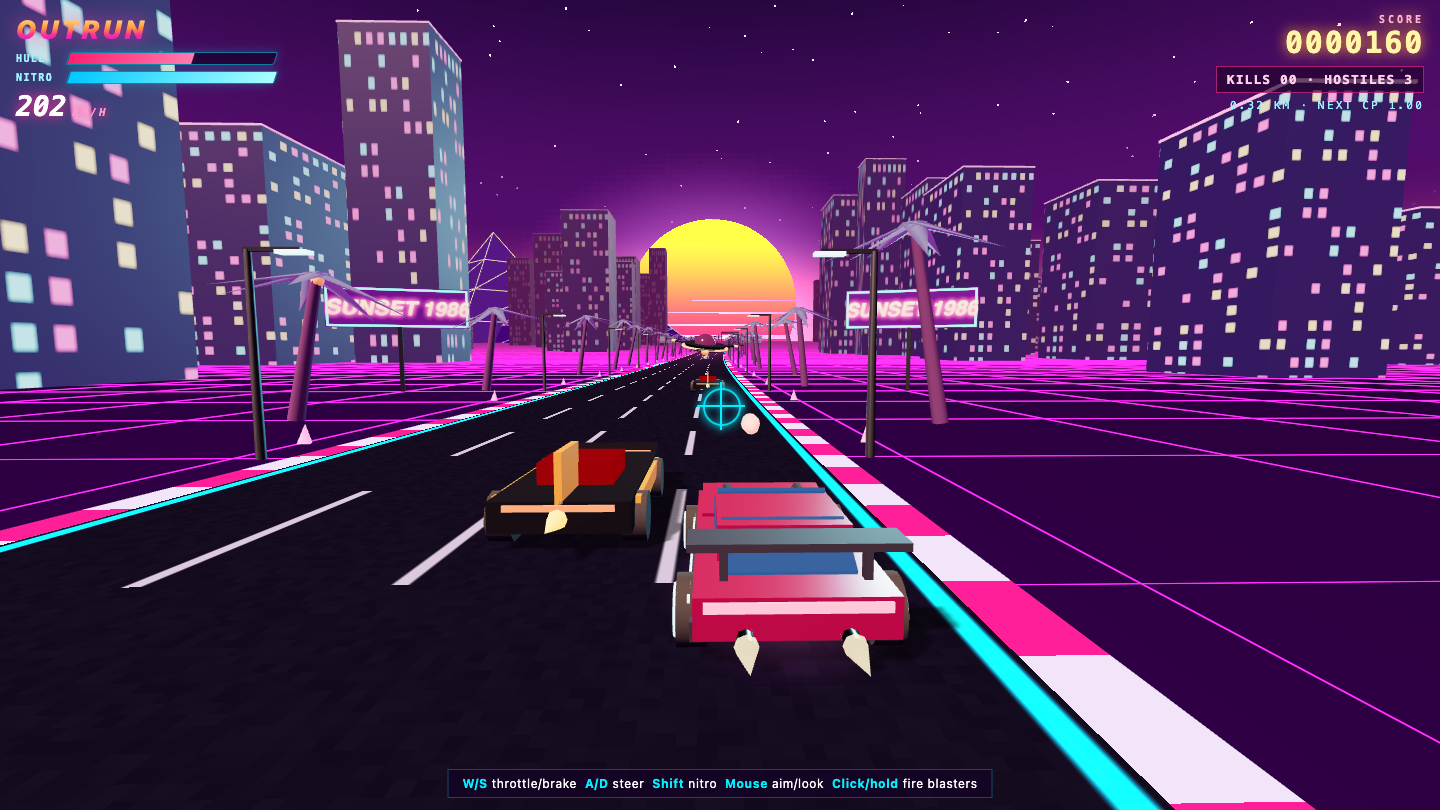
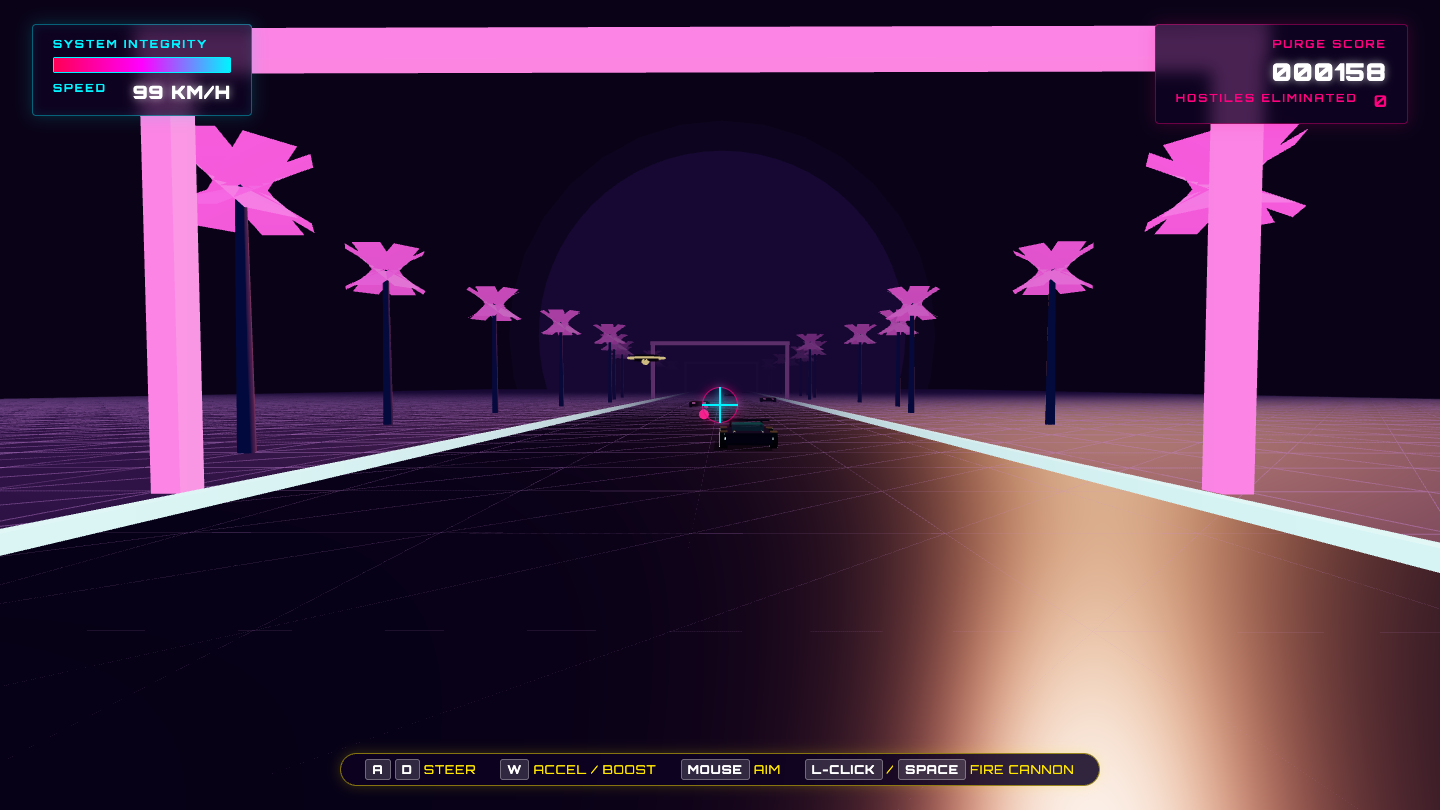
Game
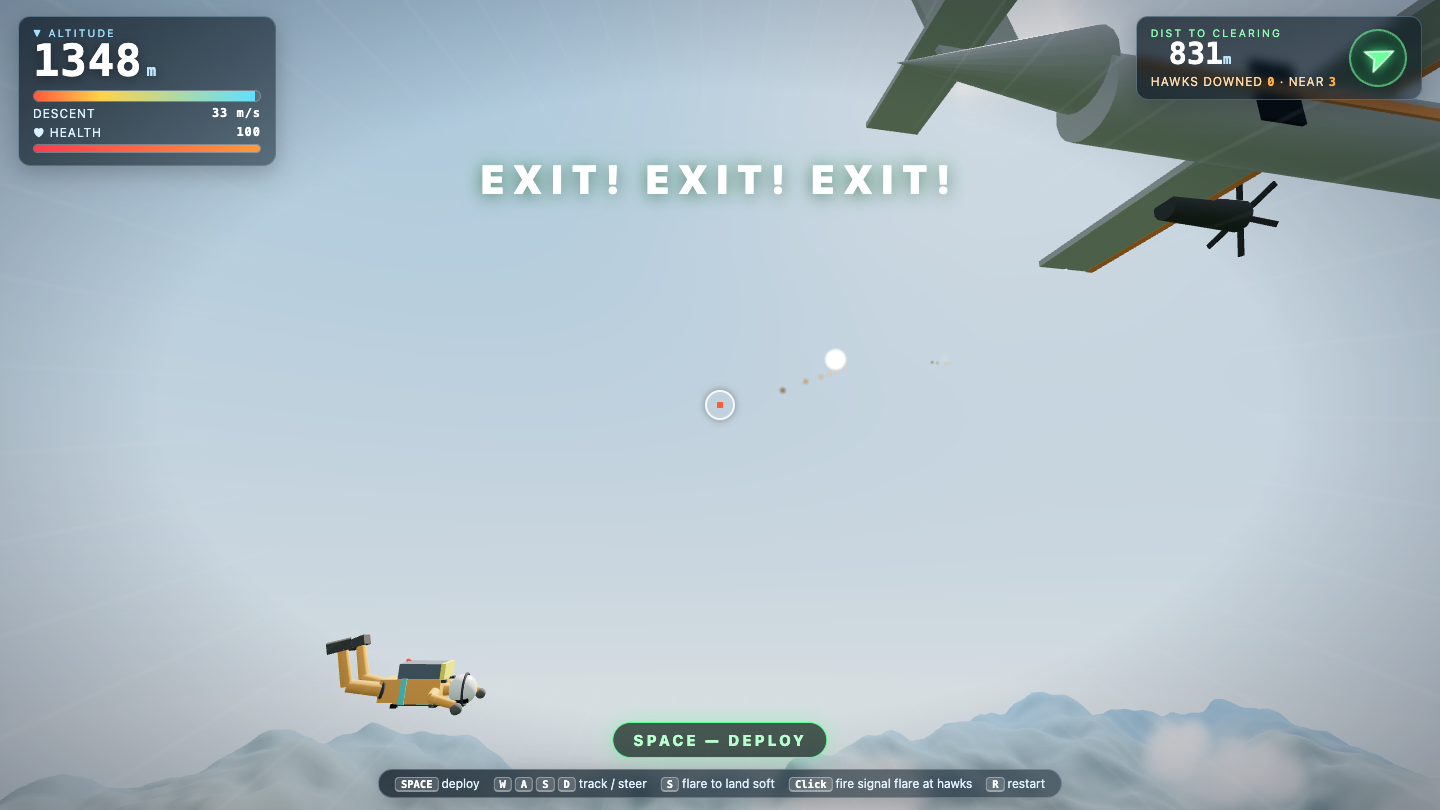
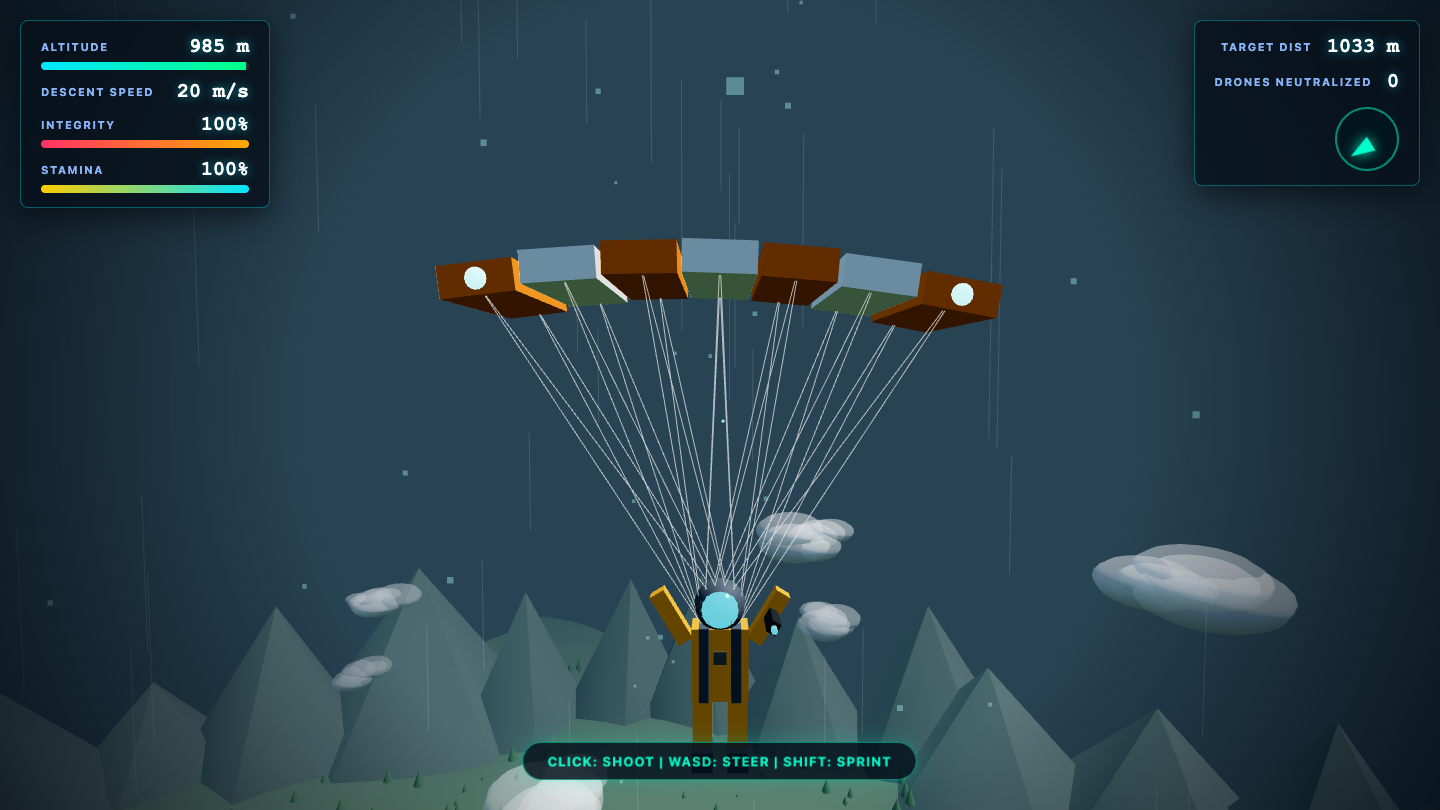
Game
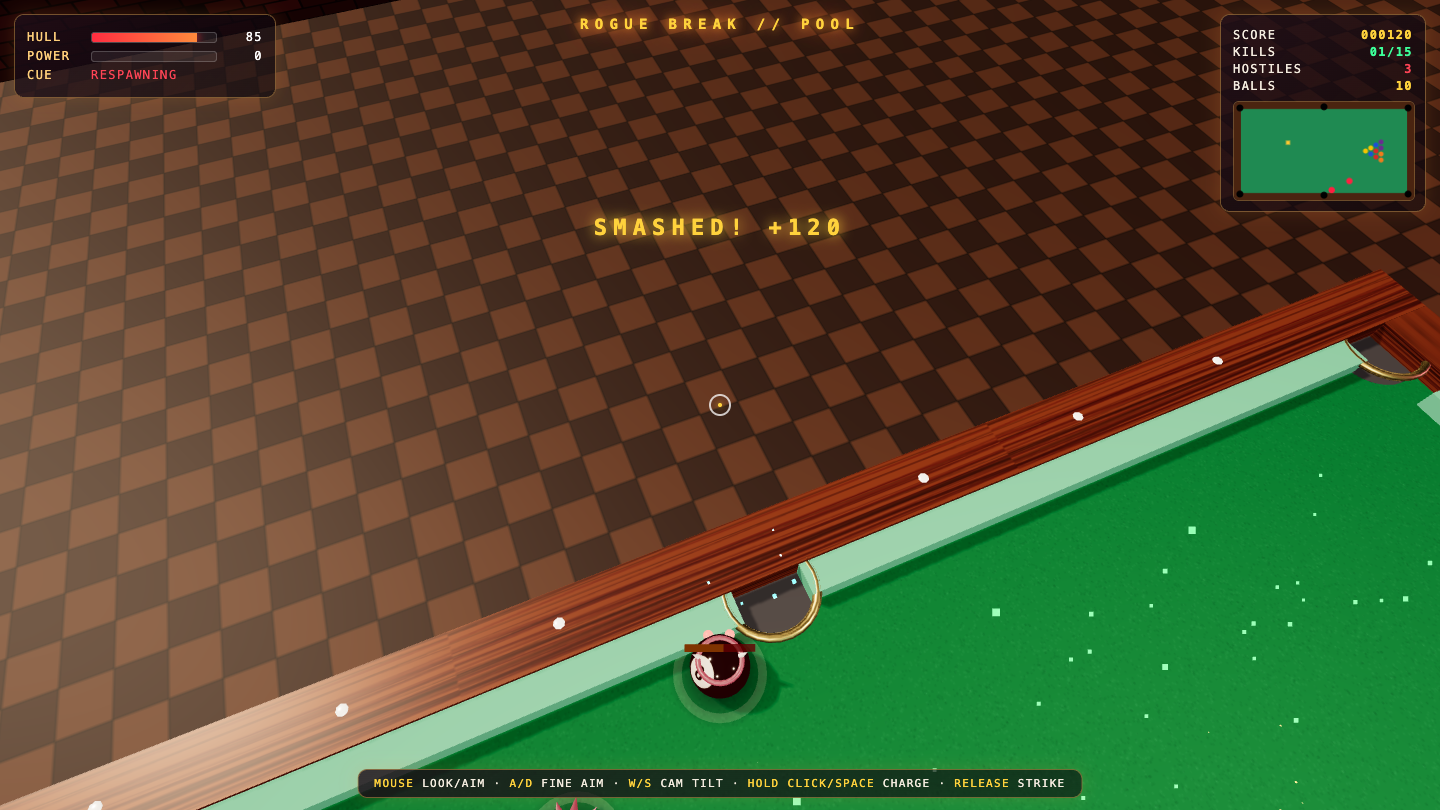
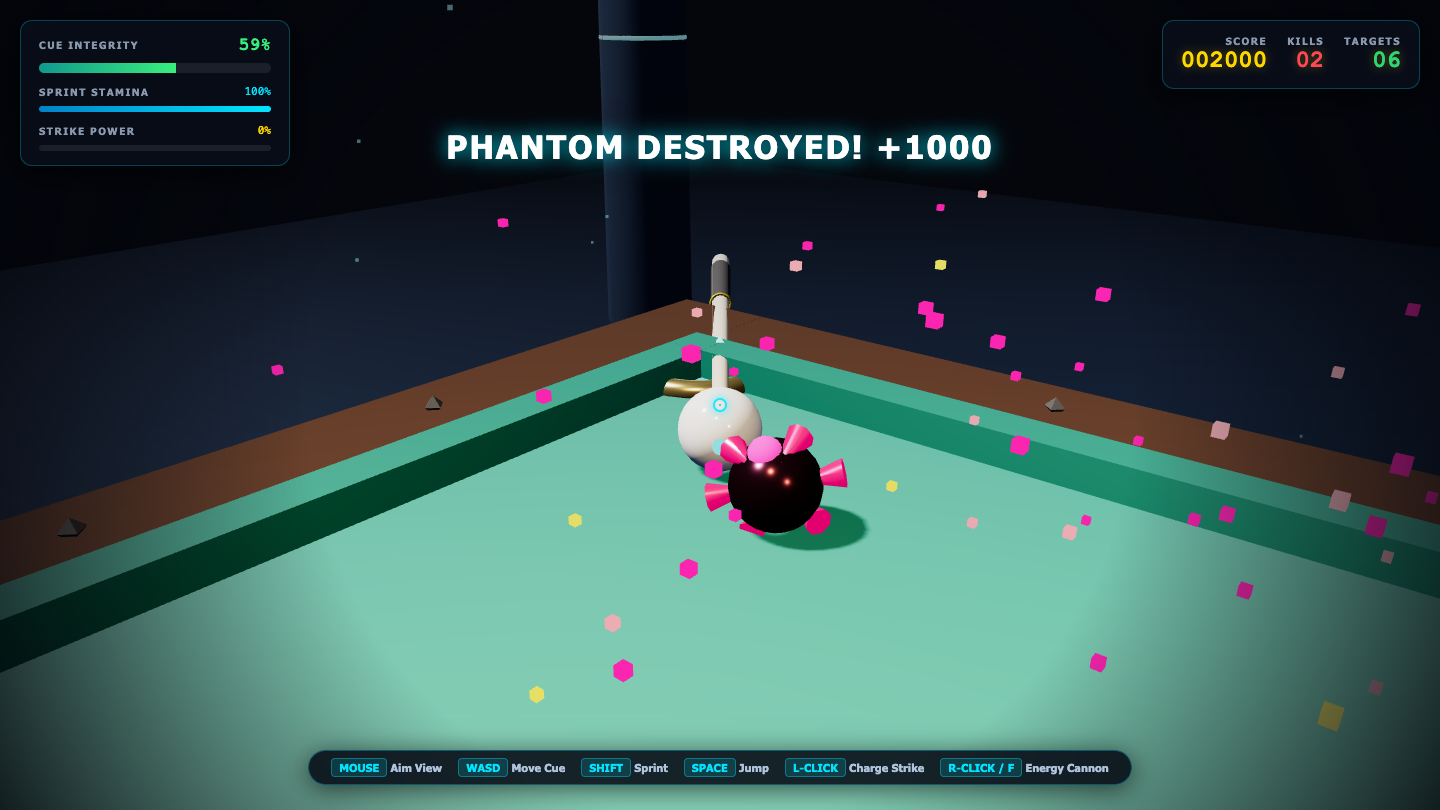
Game
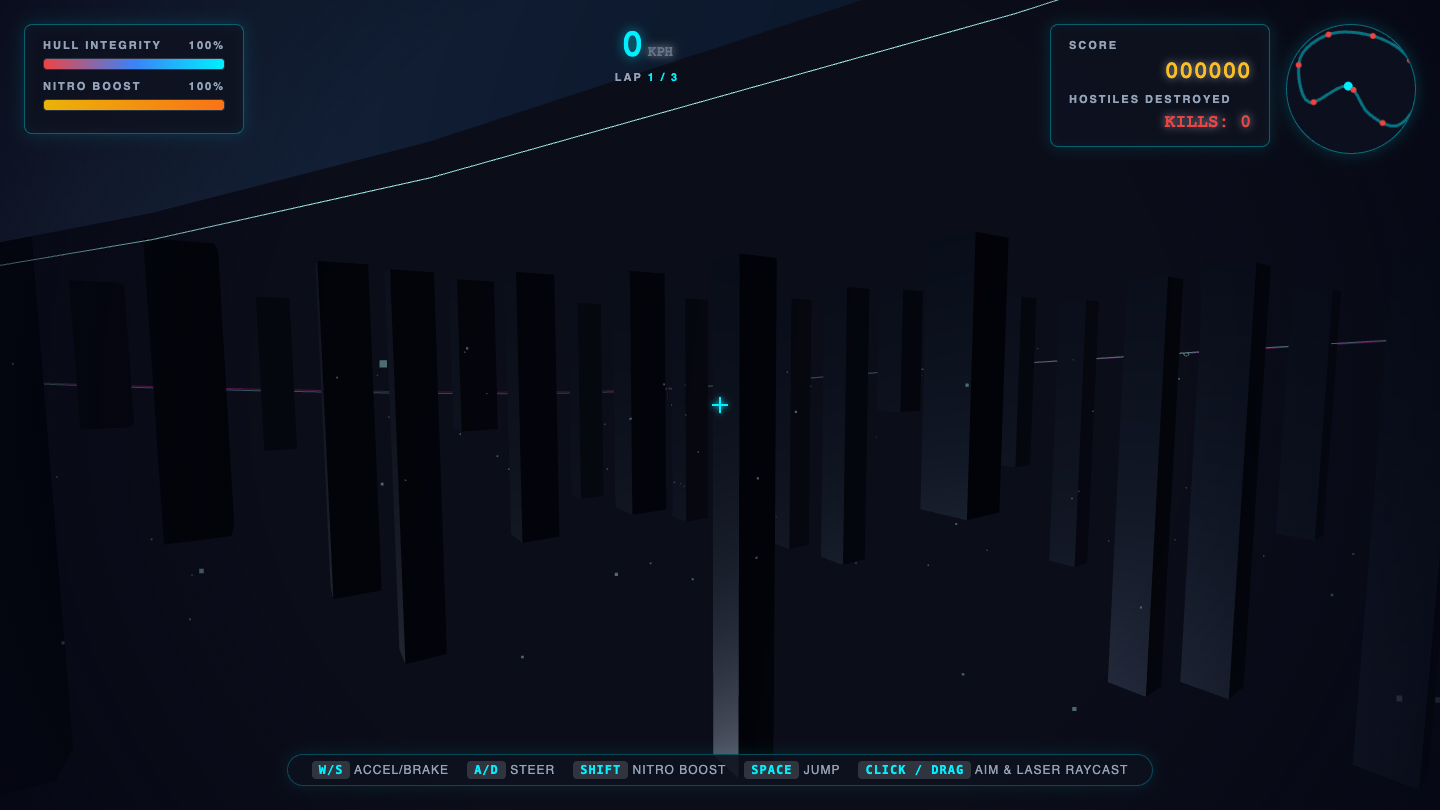
Game
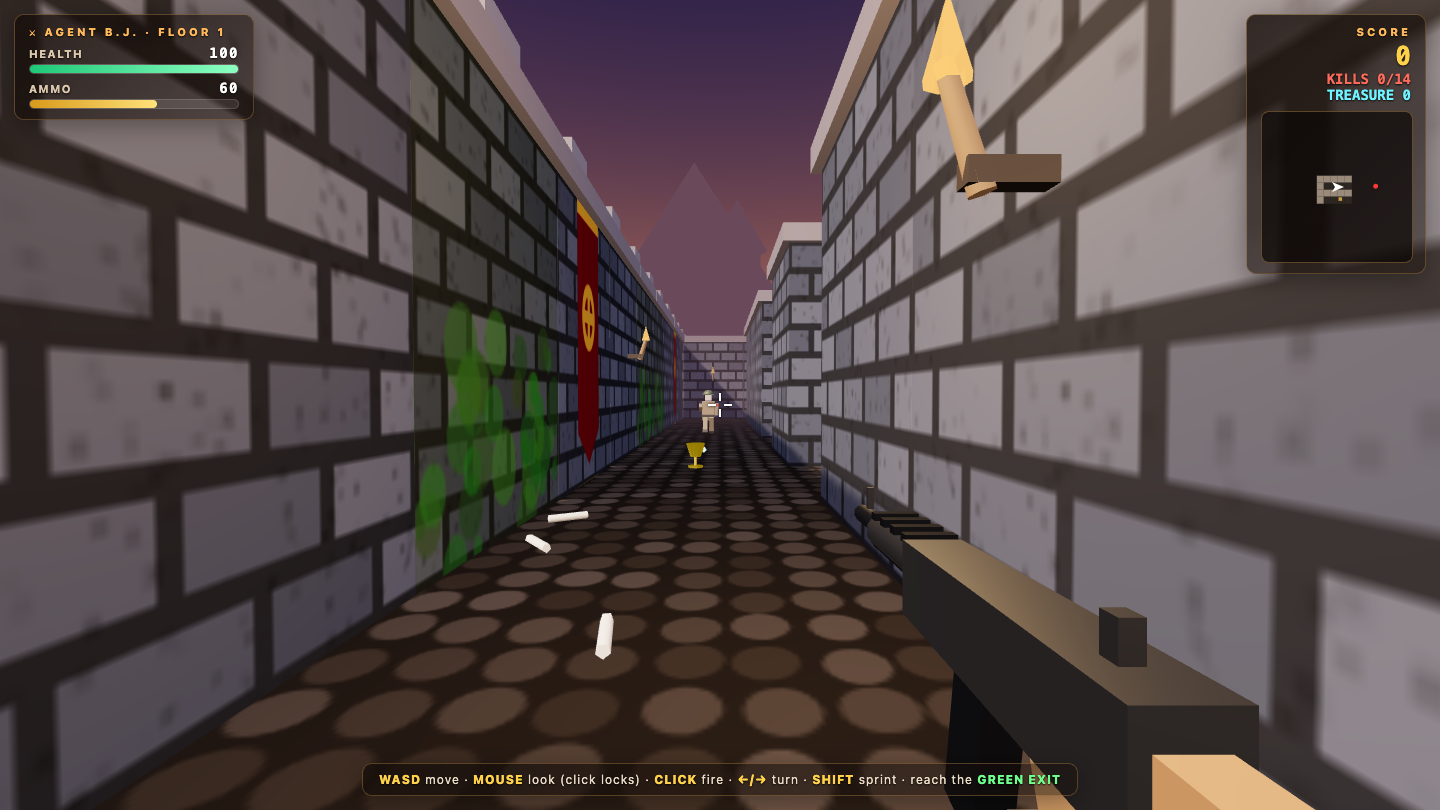
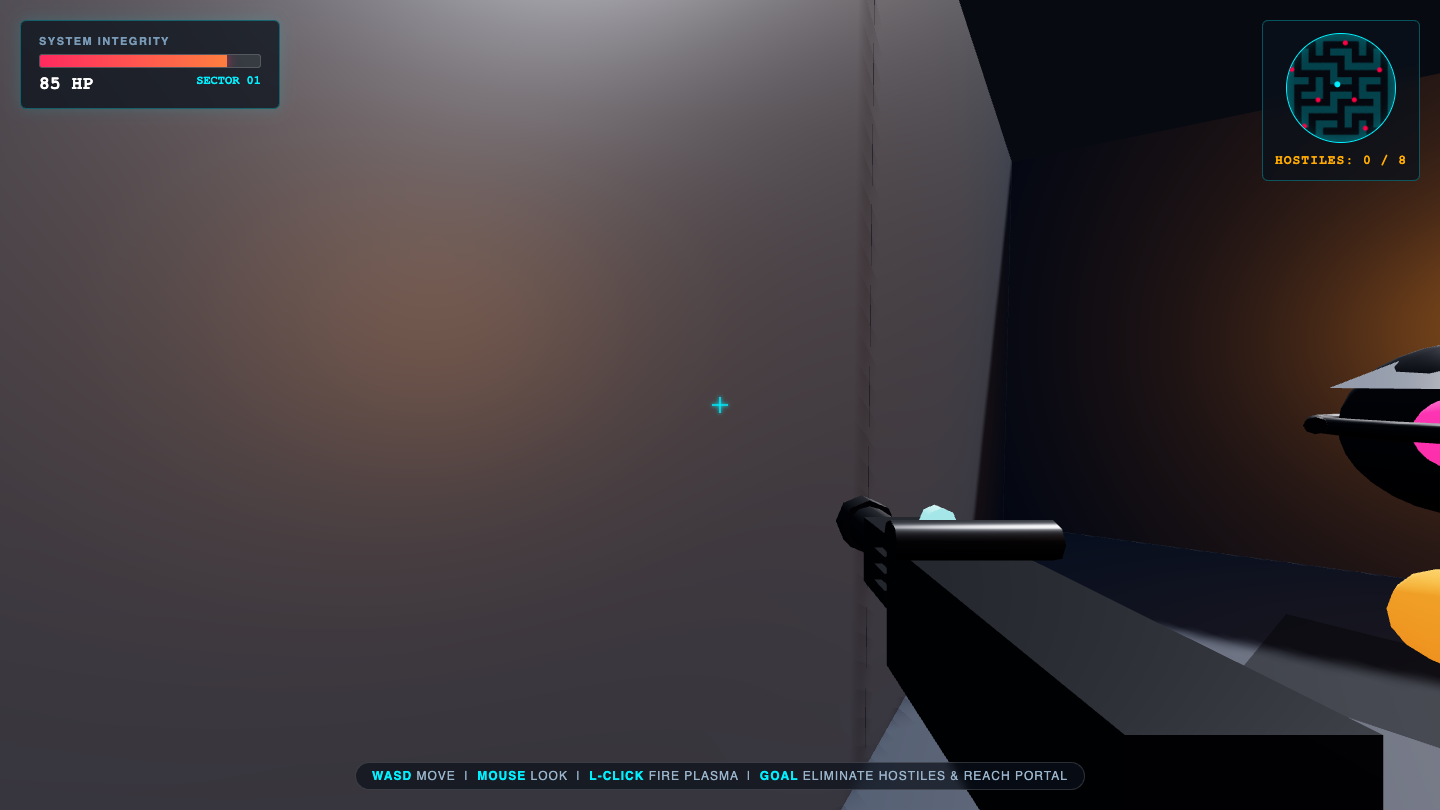
Game
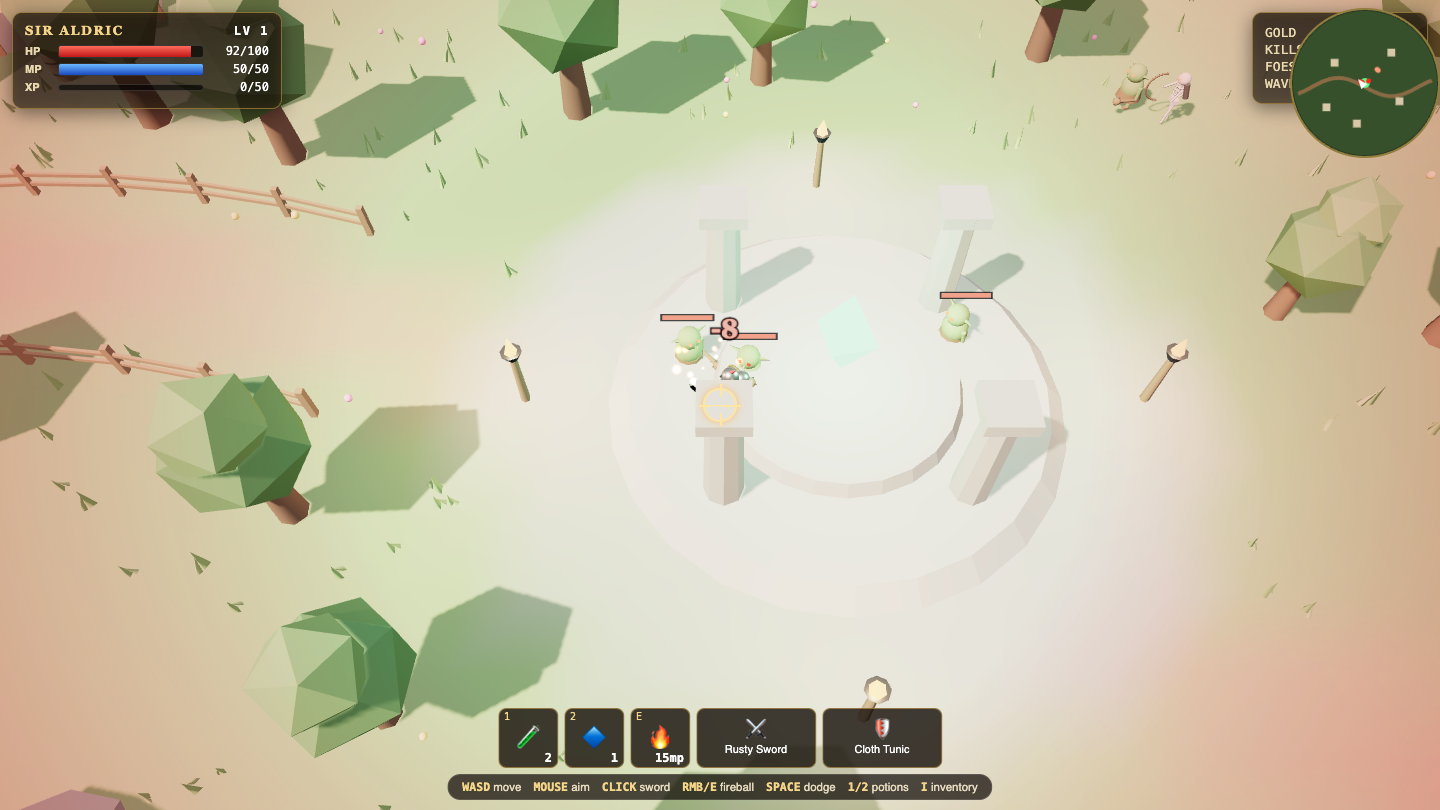
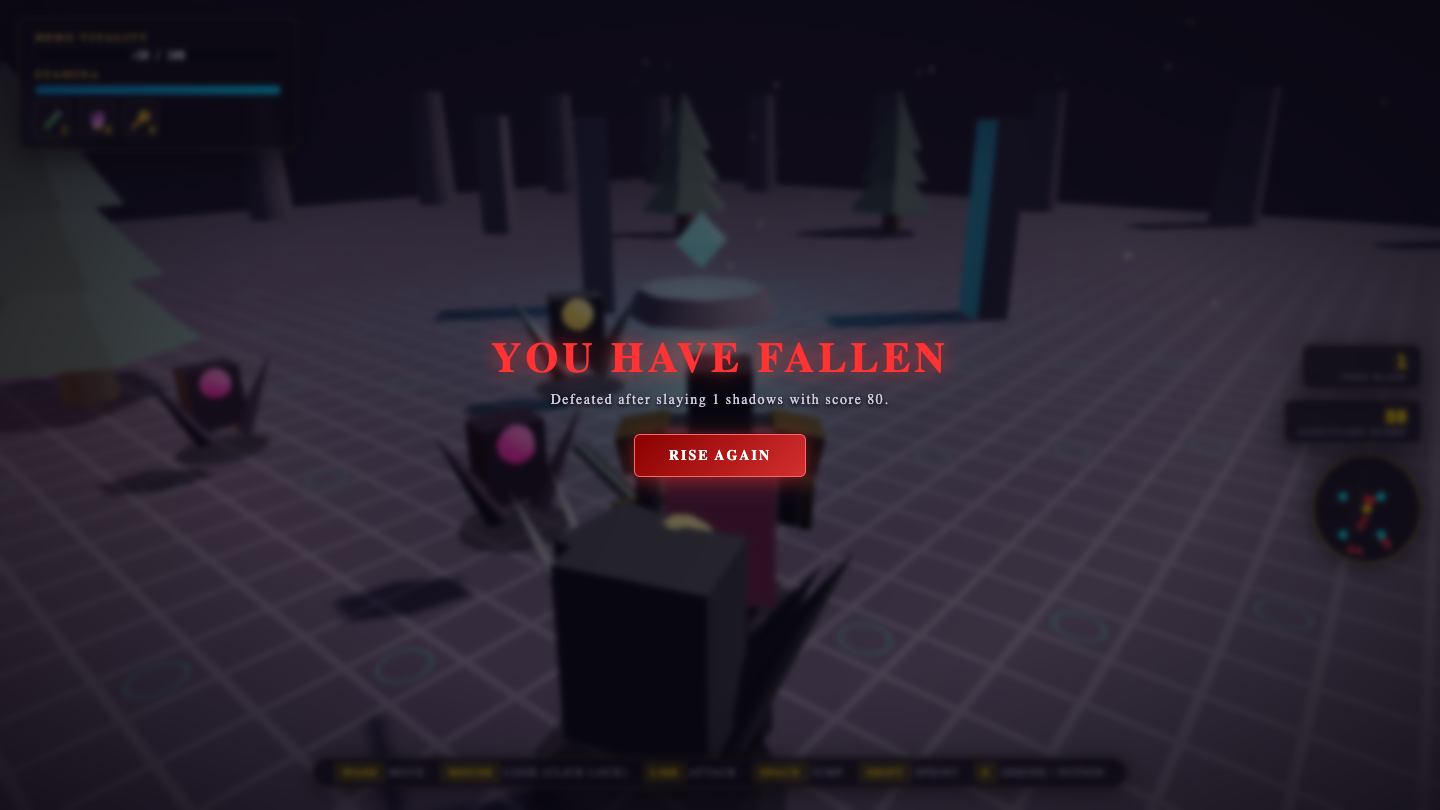
Game
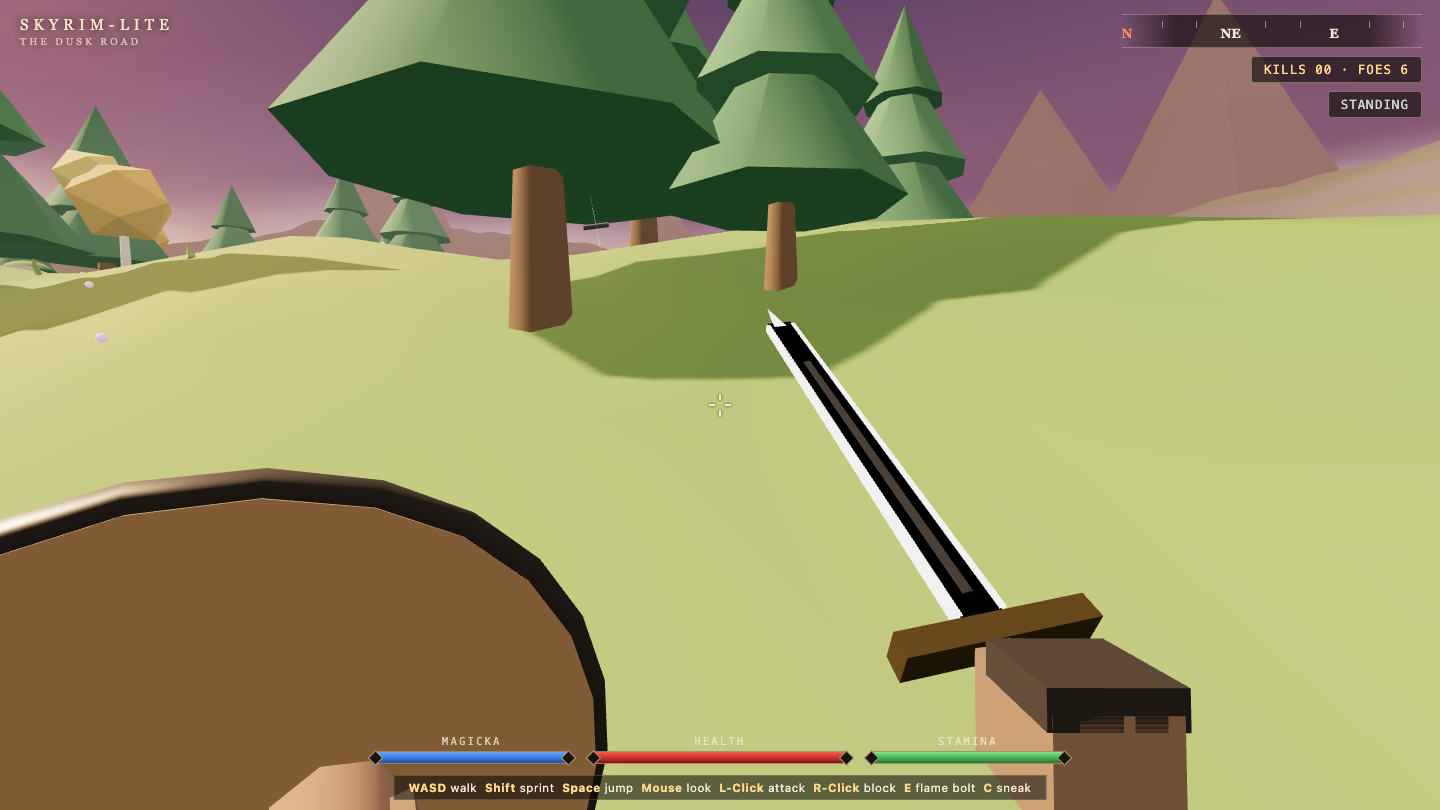
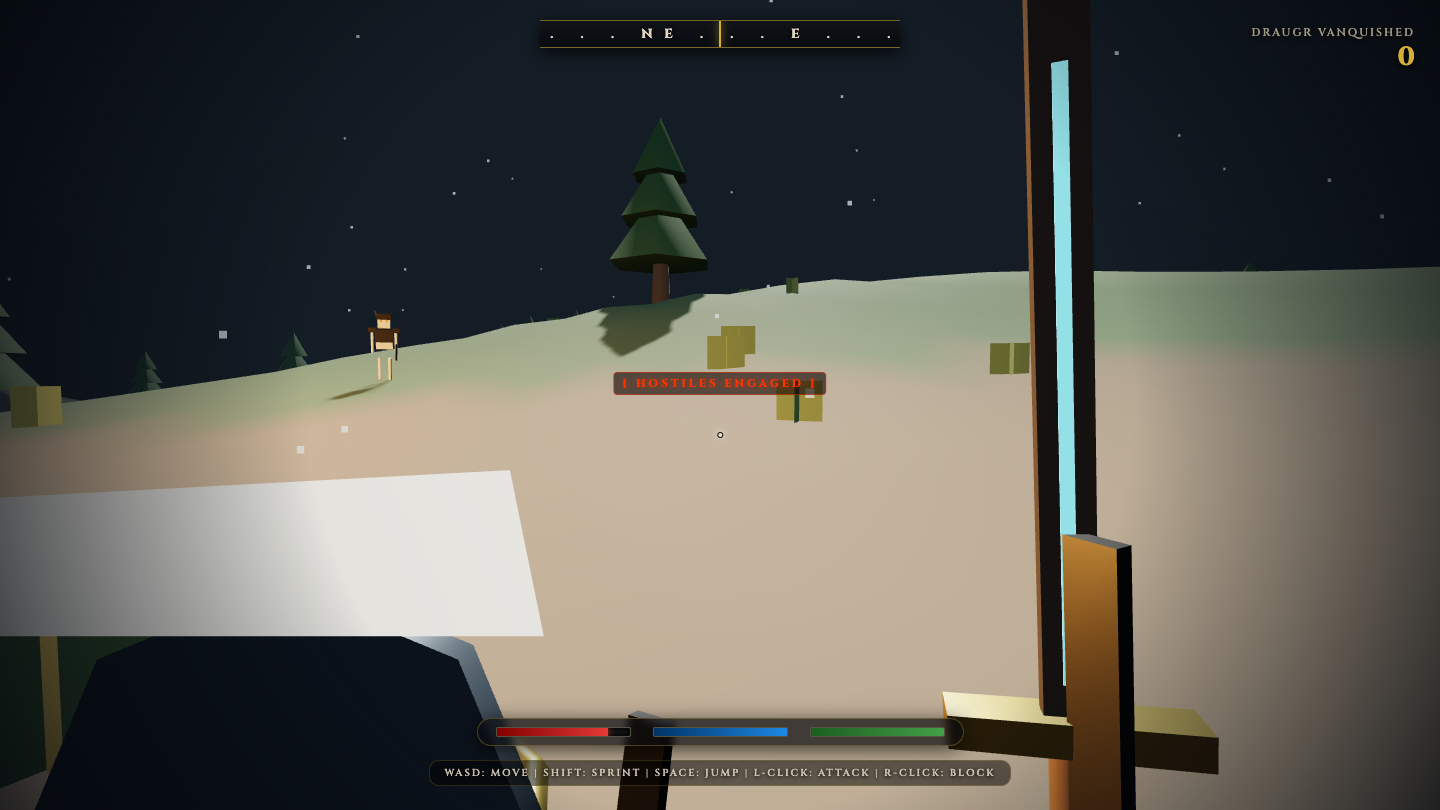
Game
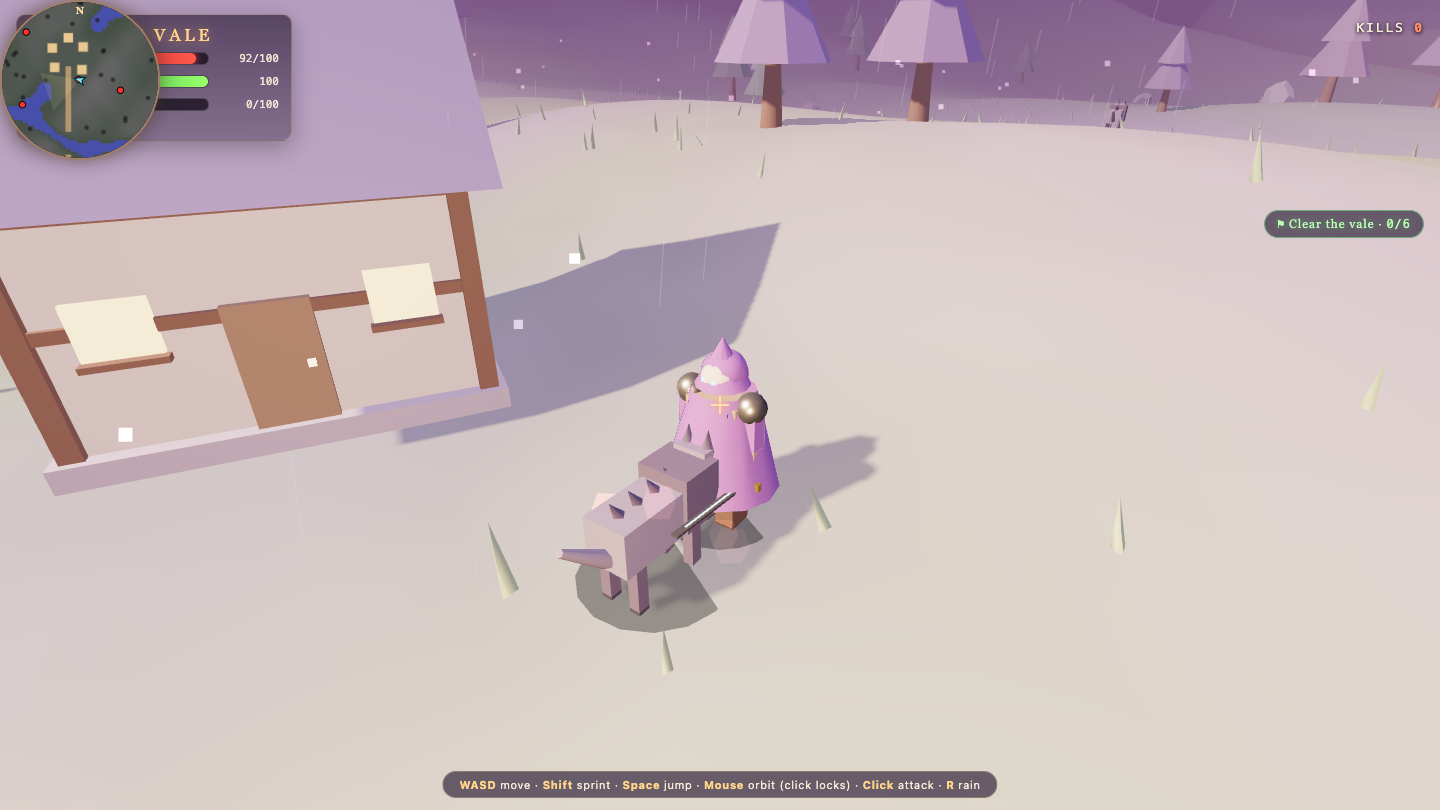
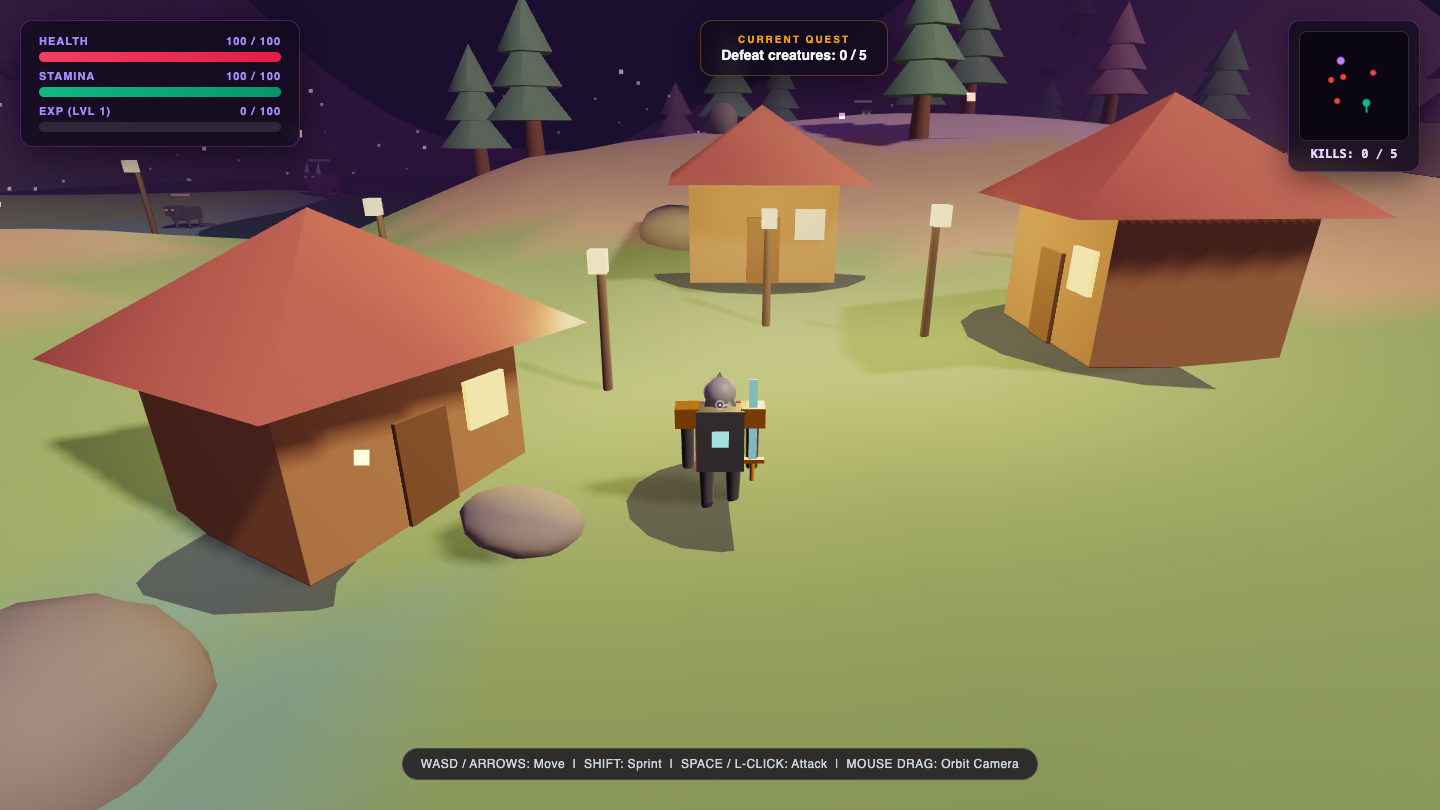
Game
Other
Where Claude Opus 5.5 beat Gemini 3.6 Flash
The tasks where I gave Claude Opus 5.5 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Waves
Visual
Claude Opus 5.5 8.4
·
Gemini 3.6 Flash 3.0
(+5.4)
What I saw: Gerstner ocean with a believable choppy surface, specular sunset glints, a bobbing buoy and sailboat, gulls, and a live sea-state readout. The sliders and presets panel is well built. Wave crests lack foam and the far field flattens into a painted look.
Blackhole
Sim
Claude Opus 5.5 8.8
·
Gemini 3.6 Flash 3.5
(+5.3)
What I saw: Striking real ray-marched Schwarzschild lensing: the Einstein ring bends over the top, the photon ring is thin and bright, the disk is Doppler-beamed and the streaked starfield looks good; controls are clean. Right up with the field's best, though the disk's banded ripple texture…
Pathtracer
Sim
Claude Opus 5.5 8.3
·
Gemini 3.6 Flash 3.5
(+4.8)
What I saw: A genuine progressive path tracer: a Cornell box with color bleeding, Fresnel glass with caustics, a mirror sphere, soft shadows, samples/paths-per-second telemetry and useful controls. At 17 spp it is still grainy, and the subtitle runs faintly into the render.
Particleforge
Sim
Claude Opus 5.5 7.9
·
Gemini 3.6 Flash 3.5
(+4.4)
What I saw: 38k-particle GPU galaxy with gravity wells, repel, swirl, detonate and 4 modes, shown in a tidy stats panel and mode pills. The frame is sparse and almost single-hue purple even though the palette reads EMBER, so it lacks the wow density of the top entries.
Racing
Game
Claude Opus 5.5 7.7
·
Gemini 3.6 Flash 4.2
(+3.5)
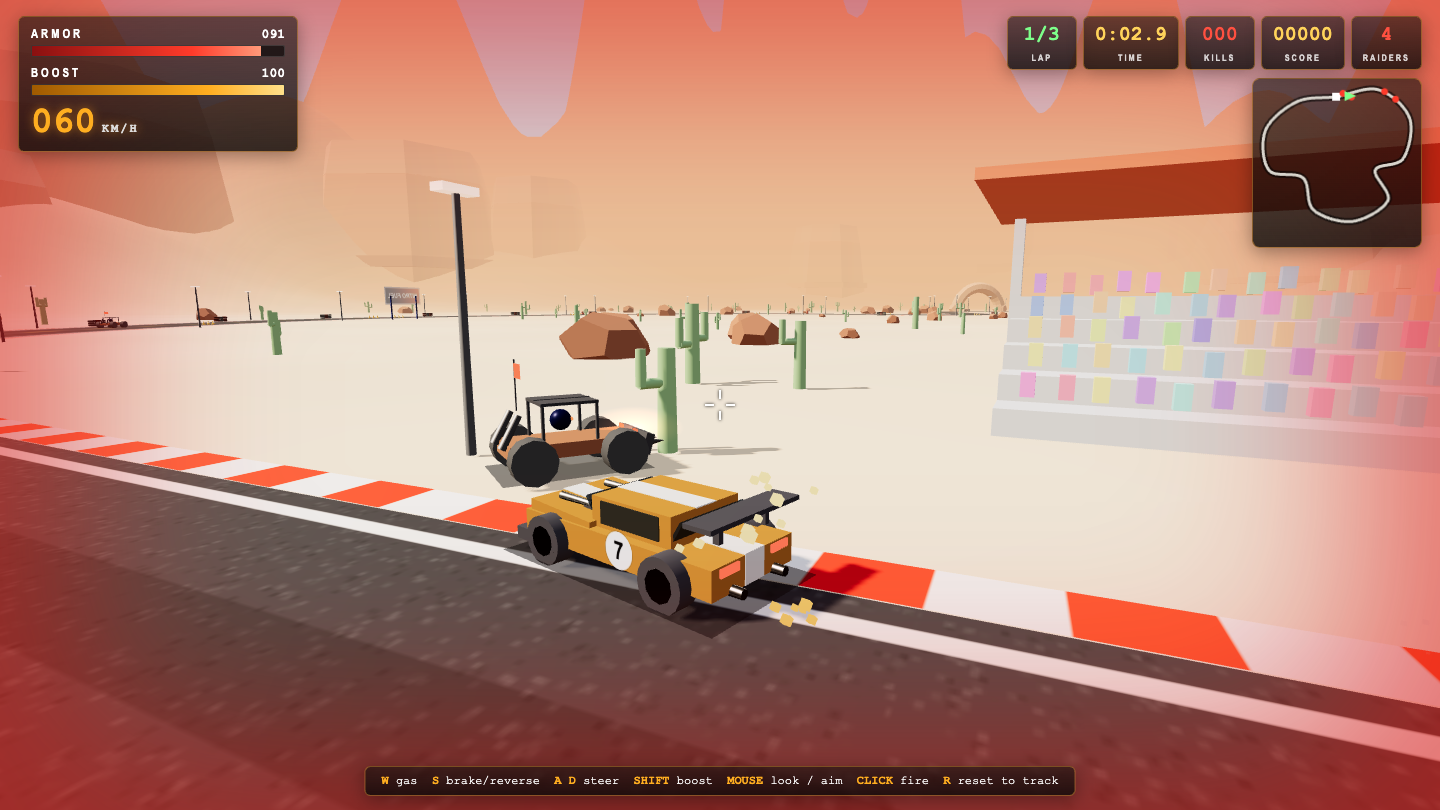
What I saw: Characterful desert circuit with a numbered muscle car, a buggy raider, grandstand, kerbs, cacti and a track minimap in a tidy HUD. A heavy red damage vignette and washed-out haze flatten the frame, so it reads well below the field's best.
Where Gemini 3.6 Flash beat Claude Opus 5.5
The tasks where I gave Gemini 3.6 Flash a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Voxelcraft
Game
Gemini 3.6 Flash 8.6
·
Claude Opus 5.5 5.8
(+2.8)
· combat voxel sandbox
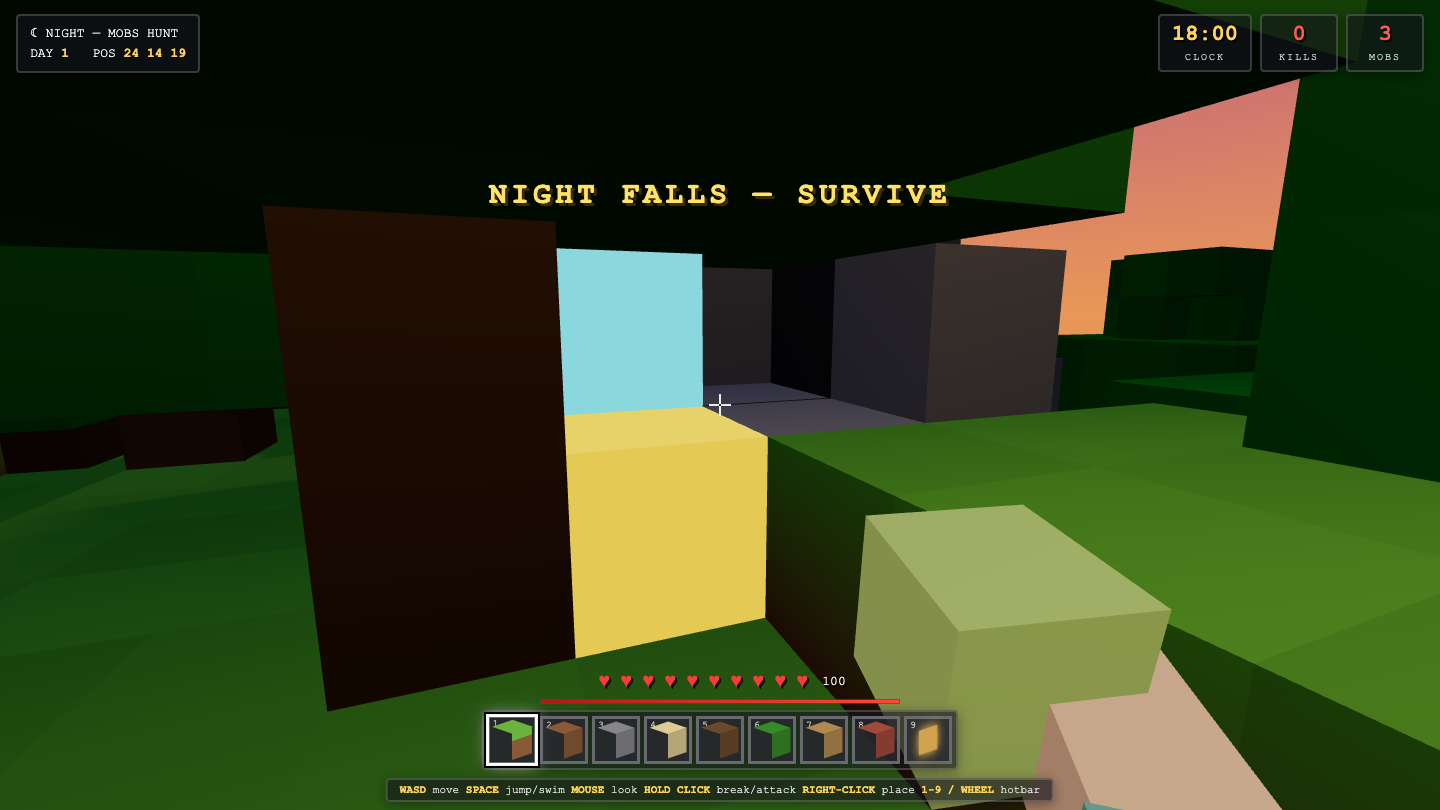
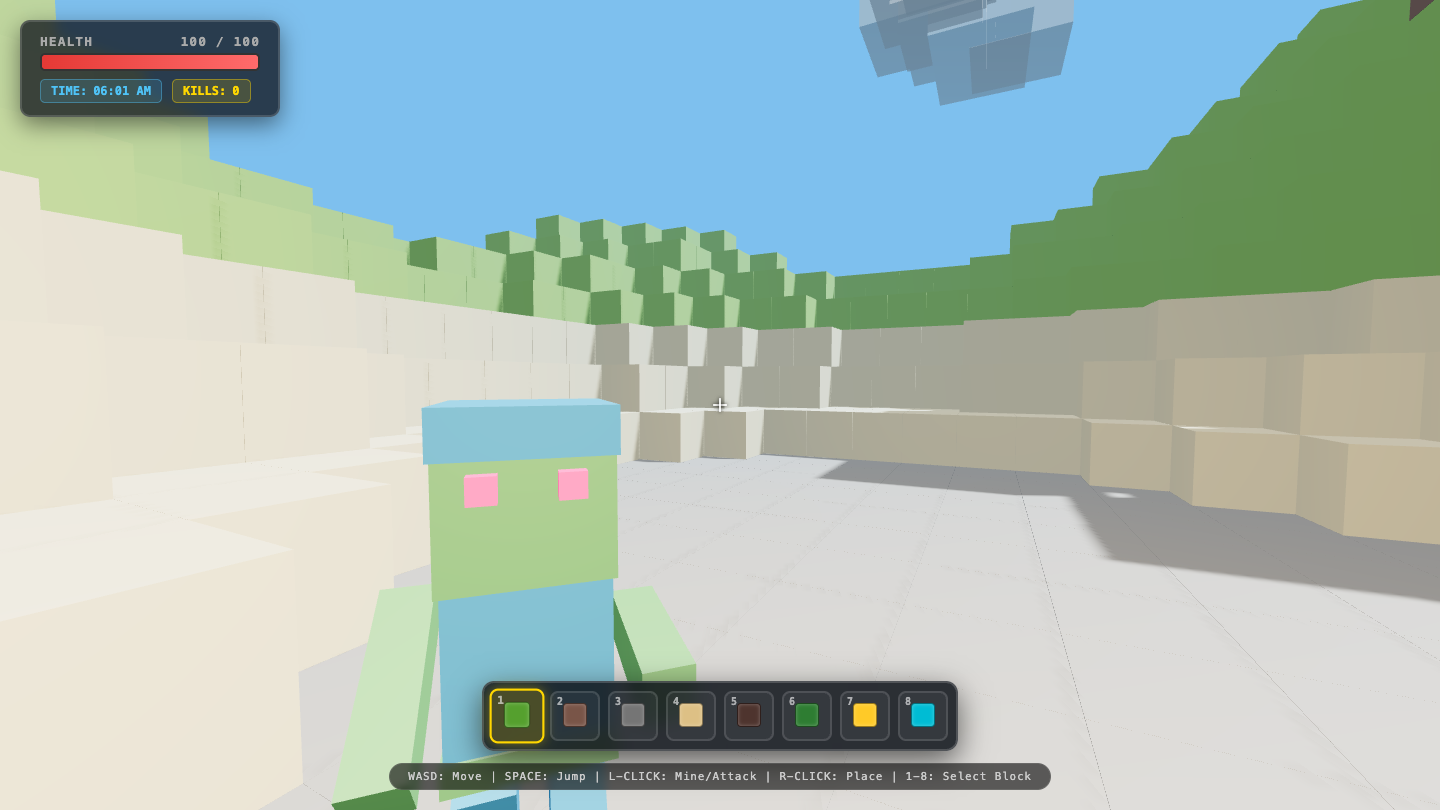
What I saw: Strong voxel world with terrain, a tree, HP/time/kills HUD, an 8-block hotbar and — crucially — a visible zombie-style enemy (plus a red one at right) delivering the combat the brief rewards; place/break plus day/night cycle all present, edging past typical walking-sim entries.
Twilightvale
Game
Gemini 3.6 Flash 7.8
·
Claude Opus 5.5 5.5
(+2.3)
What I saw: Strong atmospheric twilight scene with cohesive village, terrain, fog and a well-armed character plus polished HUD, minimap and quest tracker; however no enemies are visible in the shot (minimap shows red dots but combat isn't demonstrated), keeping it just short of the top tier.
Mlx Speedtest
Other
Gemini 3.6 Flash 8.2
·
Claude Opus 5.5 6.0
(+2.2)
What I saw: Strong, polished MLX benchmark dashboard with a 3D Three.js tensor core, orbital rings, glassmorphic HUD, chip presets and clean metric cards — clearly shippable. Falls just short of the field's best since the screenshot shows an idle state (0 GB/s, 0.0 TFLOPS, 1.0 tok/s) without…
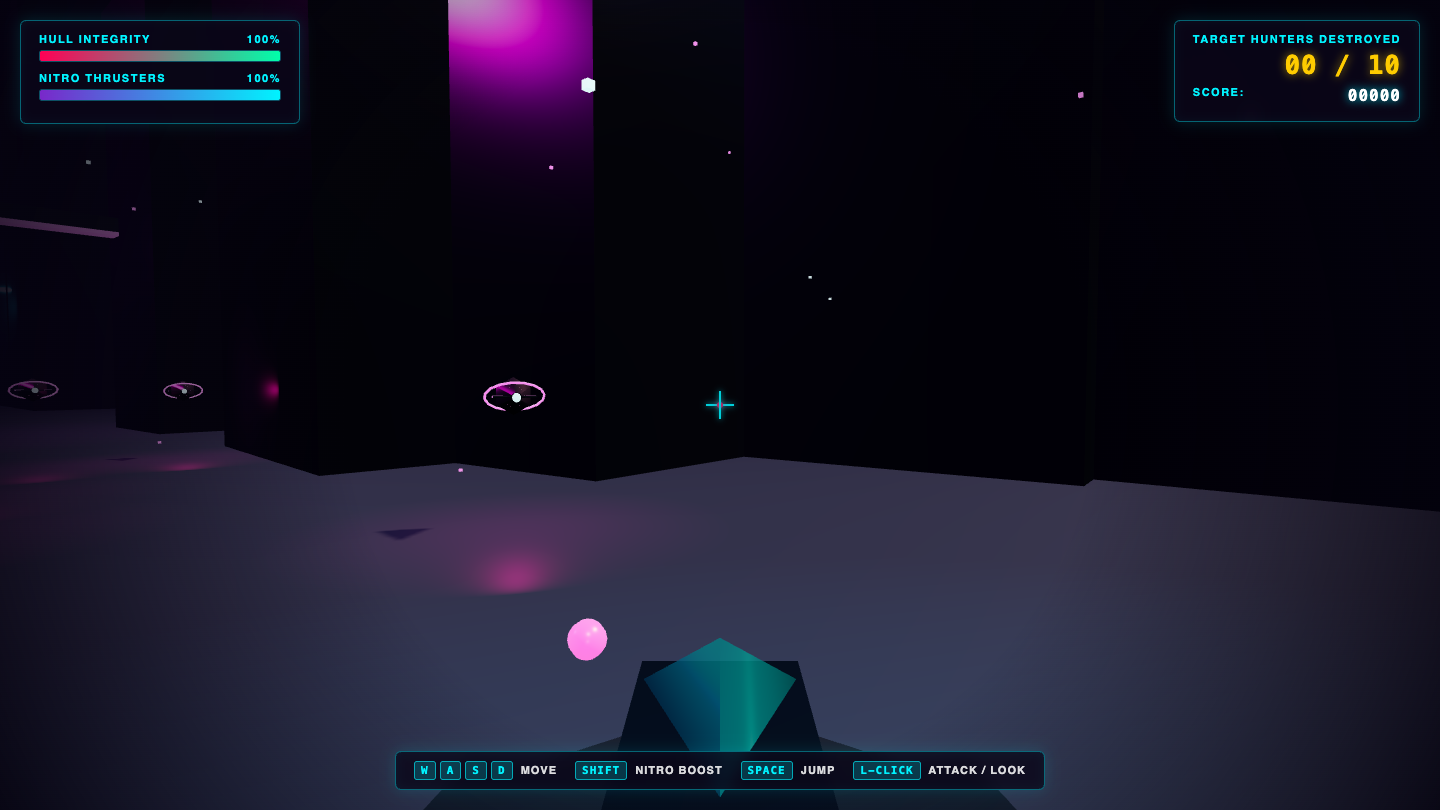
Rpg
Game
Gemini 3.6 Flash 7.4
·
Claude Opus 5.5 5.5
(+1.9)
What I saw: Strong 3D atmospheric arena with visible enemies (glowing-eyed shadow creatures), working combat/kill tracking, minimap, inventory slots and polished HUD — but the task asked for a top-down RPG with sprites, and this delivers a first-person 3D combat scene, so it drifts from the …
Terrain
Visual
Gemini 3.6 Flash 8.4
·
Claude Opus 5.5 6.8
(+1.6)
· biome terrain explorer
What I saw: Strong low-poly terrain with convincing biome coloring (green slopes, sandy shores, snow peaks, blue water), tree instances, stars and polished glassmorphism UI with 5 biome presets plus auto-roam/regenerate; falls just short of the top only for a somewhat flat lighting and gener…
Strengths & weaknesses I logged
Claude Opus 5.5
Strengths
- Frontier-class coding + agentic reasoning (Claude 5 family)
- 1M-token context — reads an entire codebase in one call
- All 50 one-shot builds rendered with zero console errors; all 23 games passed the input playtest
Trade-offs
- Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes
- One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts)
Gemini 3.6 Flash
Strengths
- Fast one-shot builds — full skill-spec 3D games in ~60-120s of generation
- Cheapest frontier-tier entry on the bench at $1.50/M input
- 17% fewer output tokens than 3.5 Flash on the same workflows (Google's launch claim)
Trade-offs
- Benched on launch day — partial run until the full 50-task batch completes
- Flash tier, not a flagship — up against Pro/flagship-class models on this board
Pricing & context — the spec sheet
| Spec | Claude Opus 5.5 | Gemini 3.6 Flash |
|---|---|---|
| Vendor | Anthropic | |
| Context window | 1,000,000 tokens | 1,000,000-token context window |
| Price | $4 / $20 per M | $1.50 / M input |
| Pricing detail | Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. | Launched 2026-07-21 alongside Gemini 3.5 Flash-Lite and 3.5 Flash Cyber. Google's pitch: higher intelligence than its predecessors on coding/ML/knowledge tasks while using 17% fewer output tokens, at a new lower price ($1.50 per million input tokens). Benched here via the native Gemini API on launch day. |
| Release | 2026-09 | 2026-07 |
| Bench coverage | 50/50 scored · avg 7.57/10 | 50/50 scored · avg 7.08/10 |
The verdict — which should you pick?
Across 50 scored shared tasks, Claude Opus 5.5 averaged 7.57/10, beating Gemini 3.6 Flash's 7.08/10 by 0.49 points. Pick Claude Opus 5.5 when the build has to ship on the first prompt and you can afford the trade-offs in the comparison below.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire Claude Opus 5.5 and Gemini 3.6 Flash both into the Agent Operating System and dispatch each from the kanban by task type — hardest agentic builds → Claude Opus 5.5, high-volume agentic work where token cost dominates → Gemini 3.6 Flash. That's the same setup I run for the 4,000+ founders inside the AI Profit Boardroom.
FAQ — Claude Opus 5.5 vs Gemini 3.6 Flash
Which is better, Claude Opus 5.5 or Gemini 3.6 Flash?
On Goldie Bench, Claude Opus 5.5 averages 7.57/10 across the shared tasks, with 0 gold, 0 silver, 1 bronze overall. Gemini 3.6 Flash averages 7.08/10, with 1 gold, 2 silver, 1 bronze. It's a curated tie on the head-to-head.
How much does Claude Opus 5.5 cost vs Gemini 3.6 Flash?
Claude Opus 5.5: Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. Gemini 3.6 Flash: Launched 2026-07-21 alongside Gemini 3.5 Flash-Lite and 3.5 Flash Cyber. Google's pitch: higher intelligence than its predecessors on coding/ML/knowledge tasks while using 17% fewer output tokens, at a new lower price ($1.50 per million input tokens). Benched here via the native Gemini API on launch day.
What's the context window for Claude Opus 5.5 vs Gemini 3.6 Flash?
Claude Opus 5.5 has a 1,000,000 tokens context window. Gemini 3.6 Flash has a 1,000,000-token context window context window.
When should I pick Claude Opus 5.5 over Gemini 3.6 Flash?
Pick Claude Opus 5.5 for: Hardest agentic builds; Whole-repo reasoning; Frontier one-shots. The trade-off is the weaknesses we logged on the bench: Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes; One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts).
When should I pick Gemini 3.6 Flash over Claude Opus 5.5?
Pick Gemini 3.6 Flash for: High-volume agentic work where token cost dominates; Fast prototype builds you iterate on rather than one-shot masterpieces; Routing the everyday 90% while a flagship handles the hard 10%. The trade-off is the weaknesses we logged on the bench: Benched on launch day — partial run until the full 50-task batch completes; Flash tier, not a flagship — up against Pro/flagship-class models on this board.
How does Goldie Bench score Claude Opus 5.5 vs Gemini 3.6 Flash?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
Claude Opus 5.5 vs Fusion Gemini 3.6 Flash vs Fusion Claude Opus 5.5 vs Claude Opus 5 Gemini 3.6 Flash vs Claude Opus 5 Claude Opus 5.5 vs Hermes MoA Gemini 3.6 Flash vs Hermes MoA Claude Opus 5.5 vs GPT-5.6 Sol Gemini 3.6 Flash vs GPT-5.6 SolFull model pages: Claude Opus 5.5 · Gemini 3.6 Flash · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.
4,000+founders
258documented wins
38countries
$59/momonthly