Real head-to-head · same prompt, one shot
Hermes MoA vs Muse Spark 1.2
A panel of frontier models, merged by a chair. The model doesn't matter — the system does. vs Meta's coding reasoning model — co-trained with its own agent, 1M-token window.
Head-to-head verdict: Hermes MoA wins 28–14 with 5 ties.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to Hermes MoA and Muse Spark 1.2, side by side, on 47 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
Hermes MoA · Run from the Mixture tab in the Hermes Agent OS. On this bench the panel built each demo and the aggregator merged the best of every draft.
Muse Spark 1.2 · Cloud coder via OpenRouter; the Muse Code agent (one-command install) is its native harness.
Side-by-side on 50 shared tasks
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
Hermes MoA
Muse Spark 1.2
Game
Game
Game
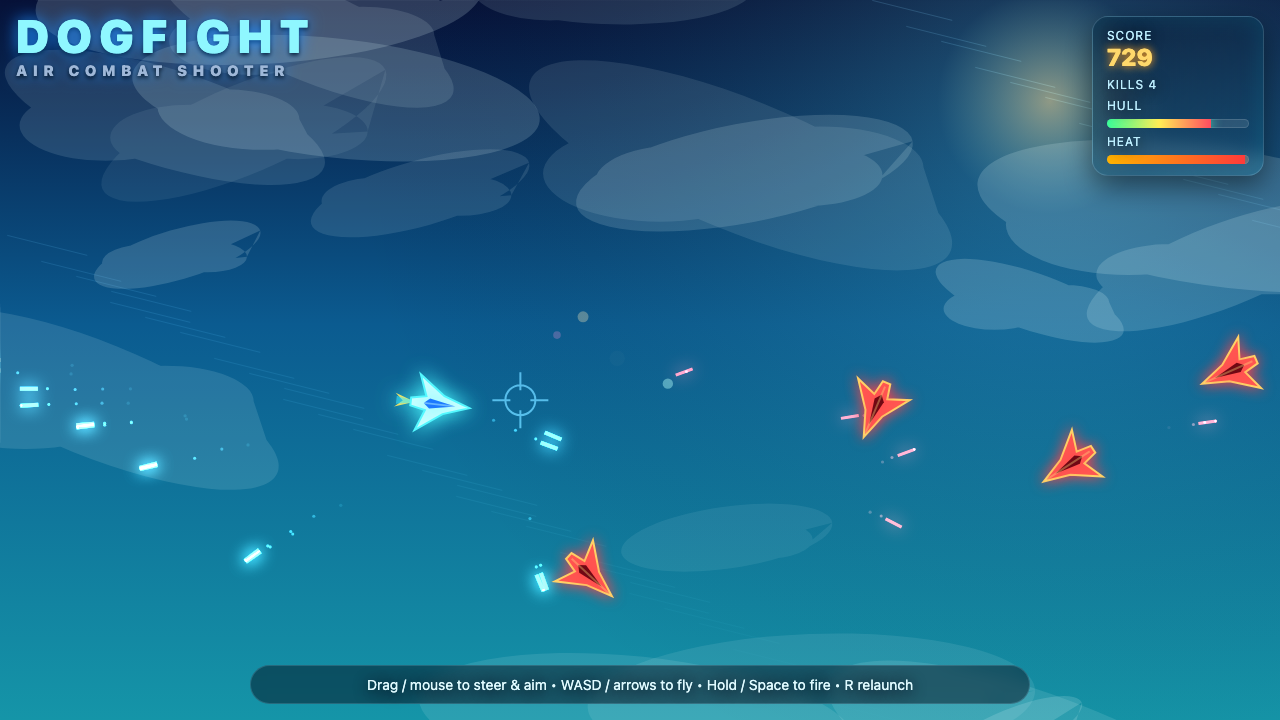
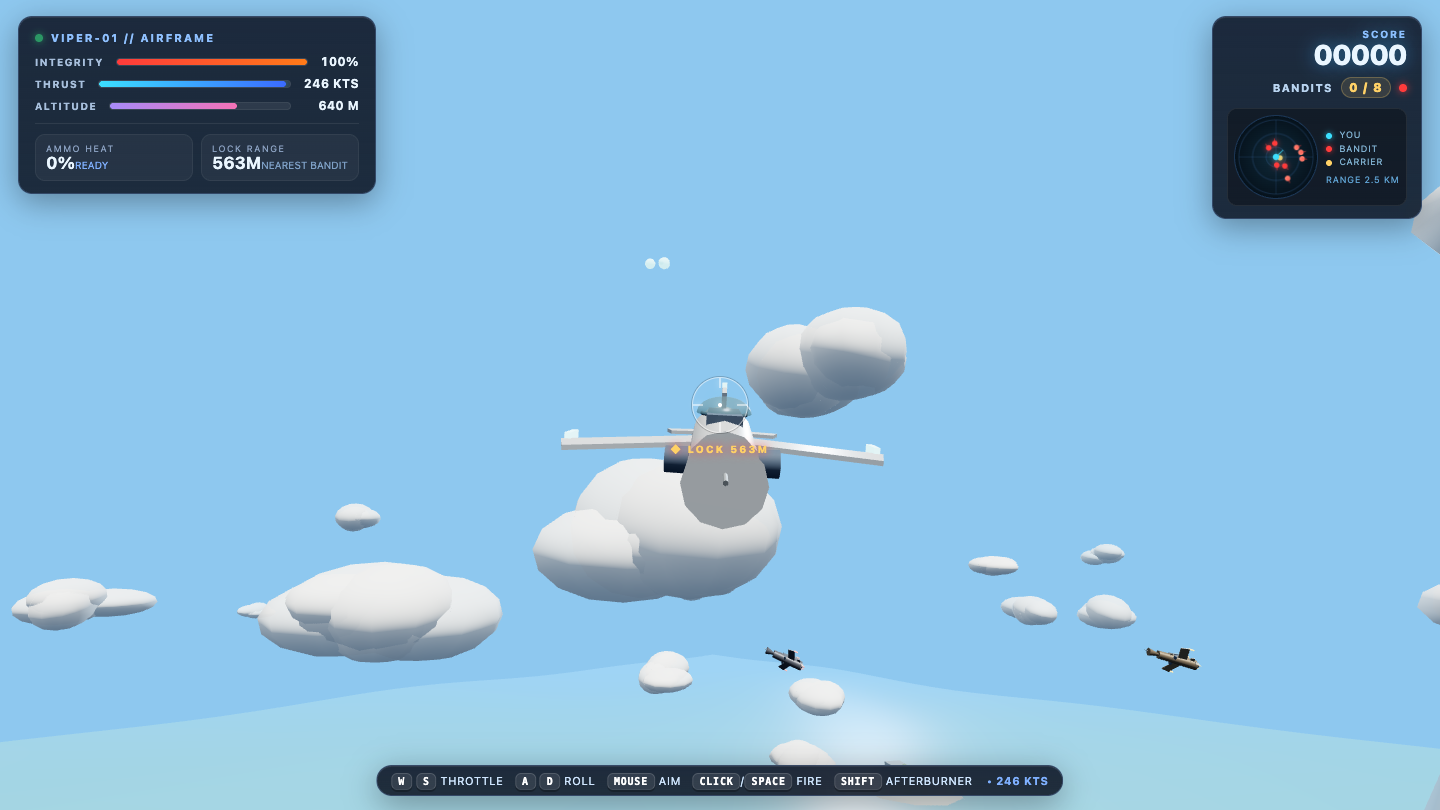
Game
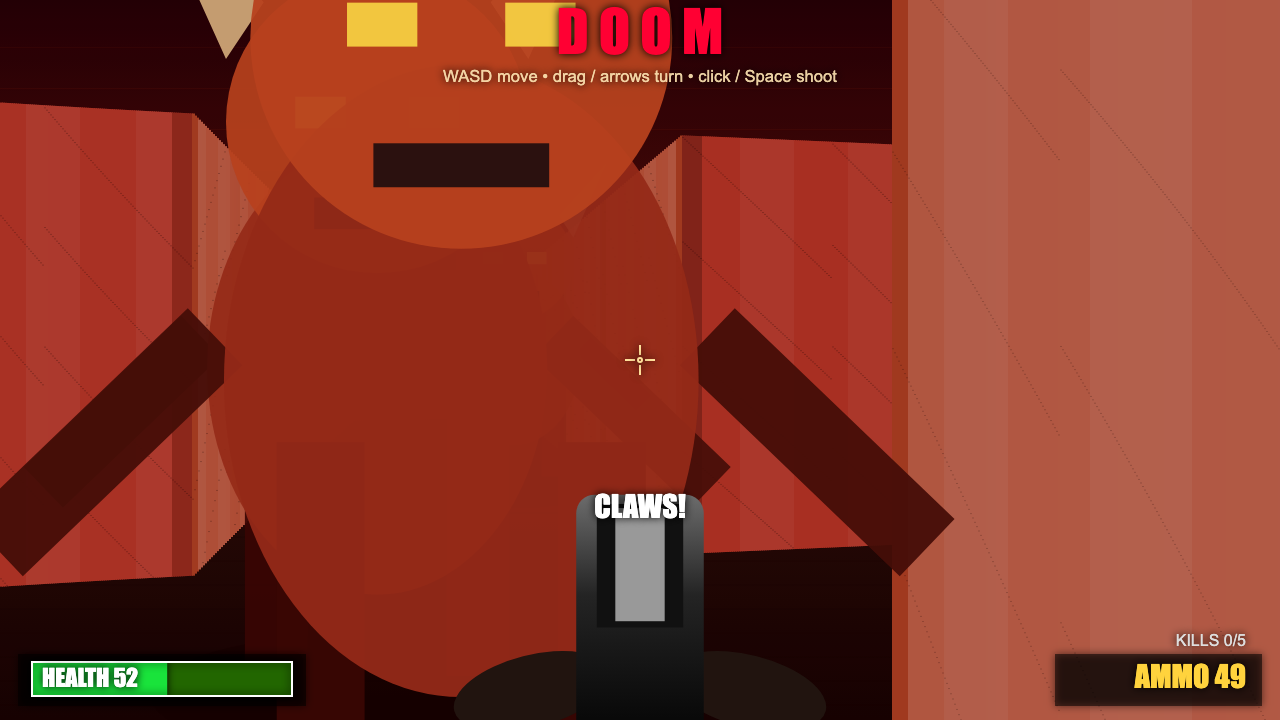
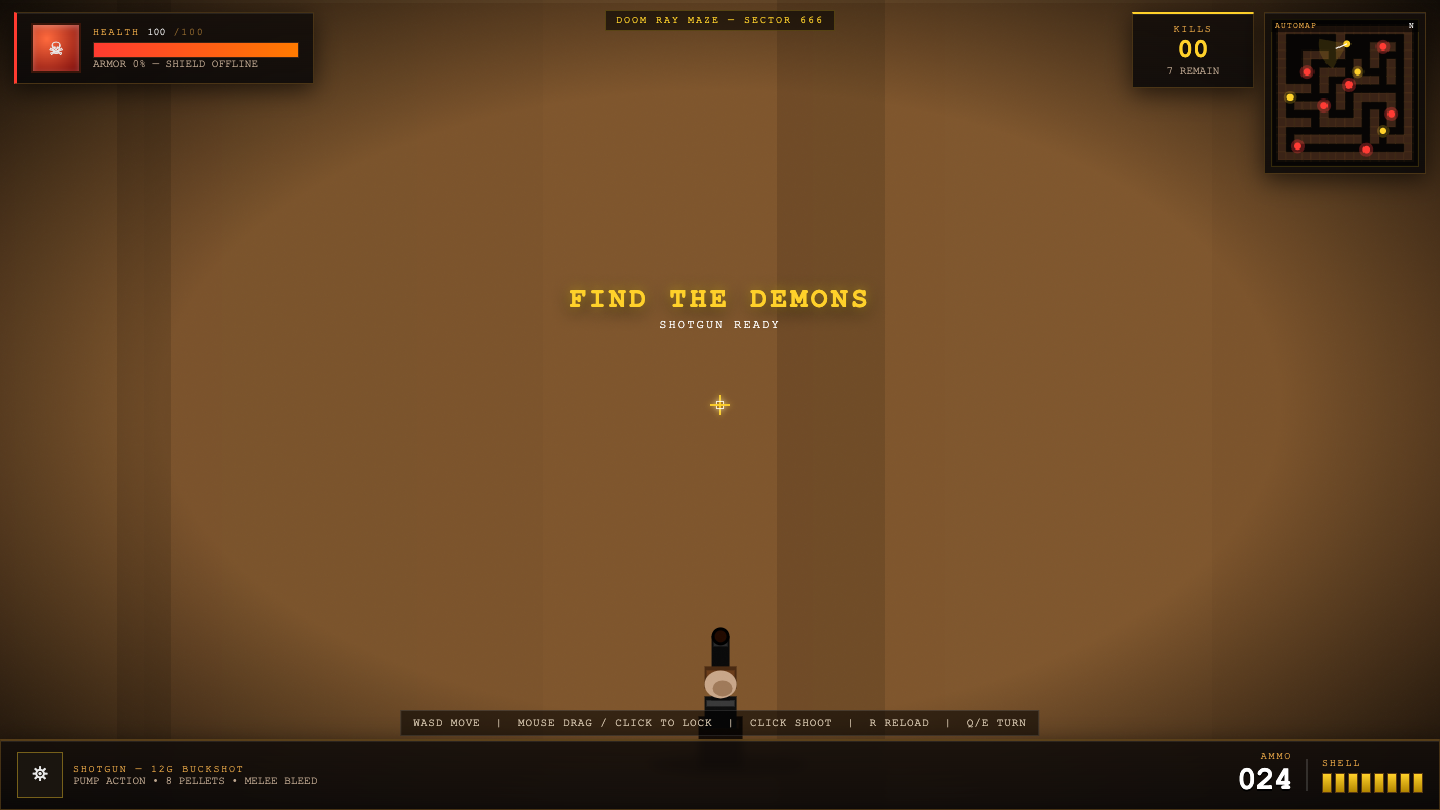
Game
Game
Game
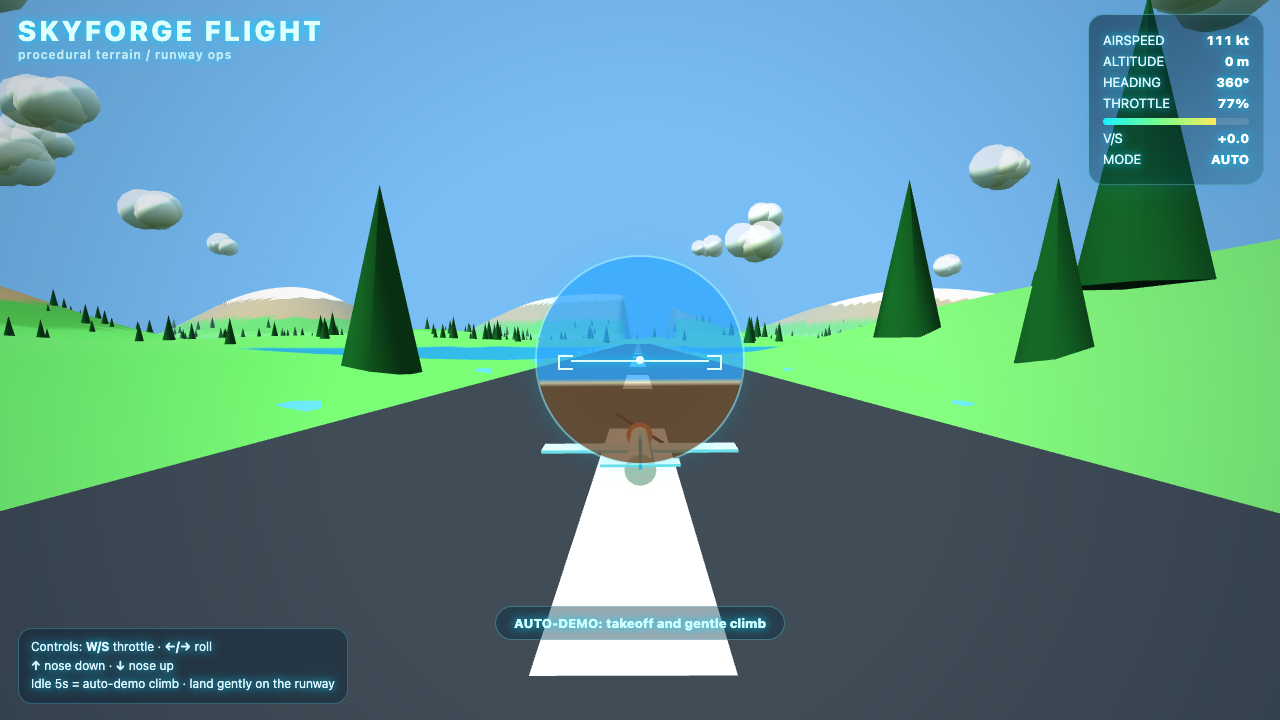
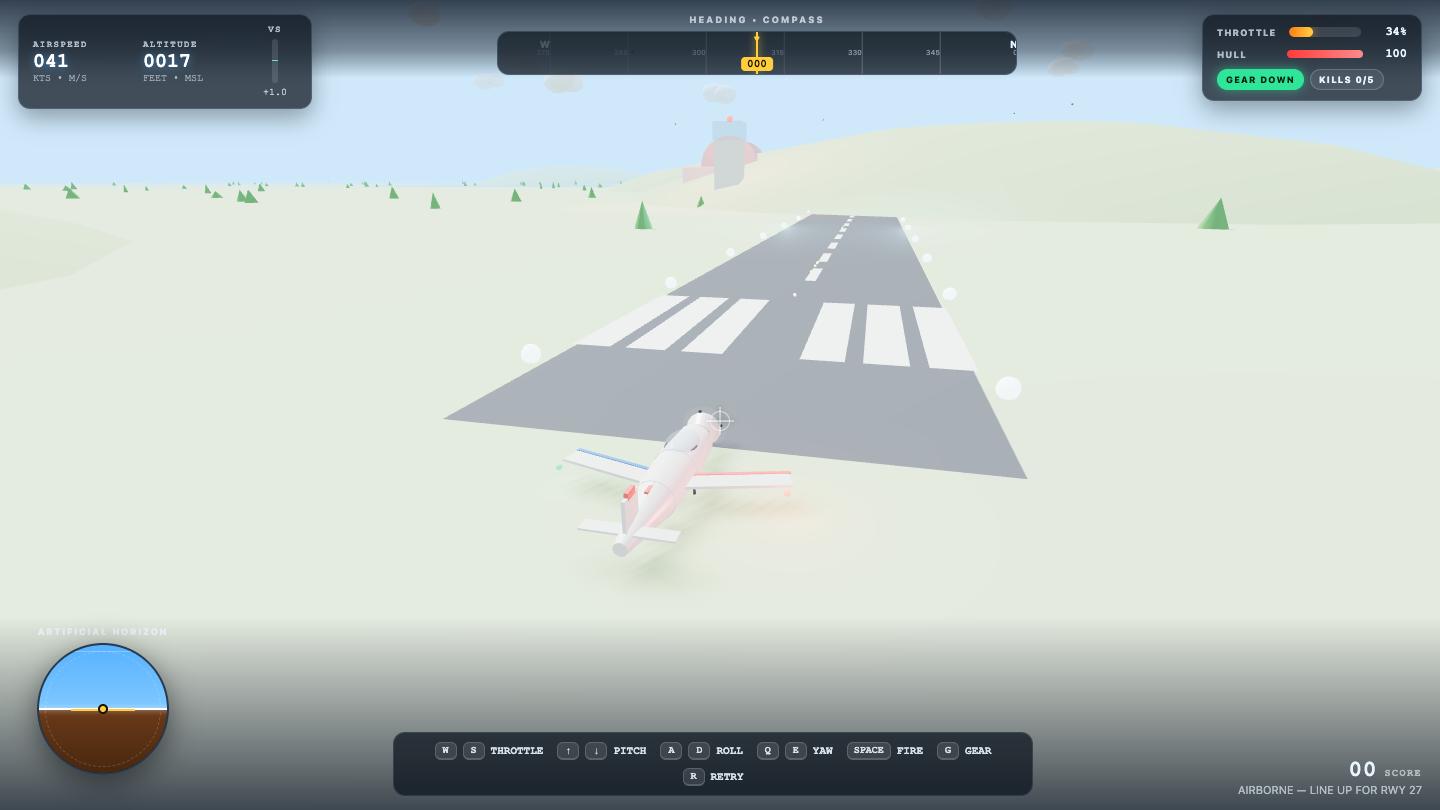
Game
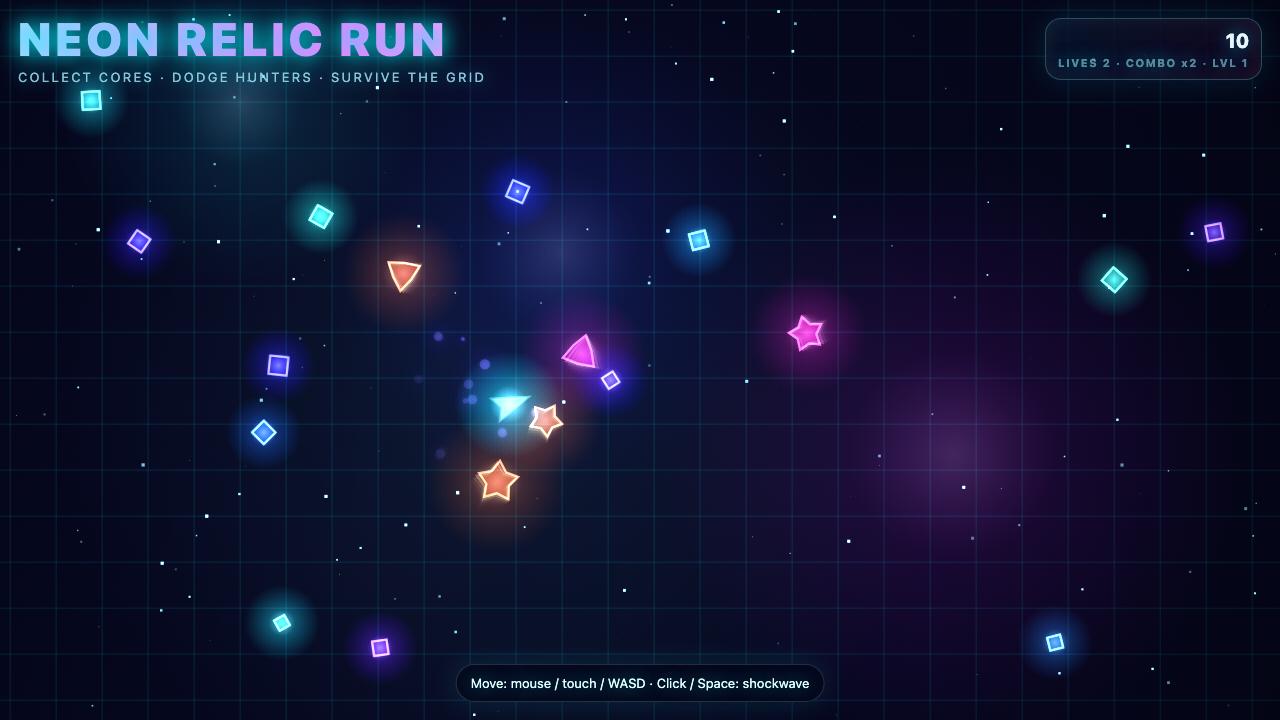
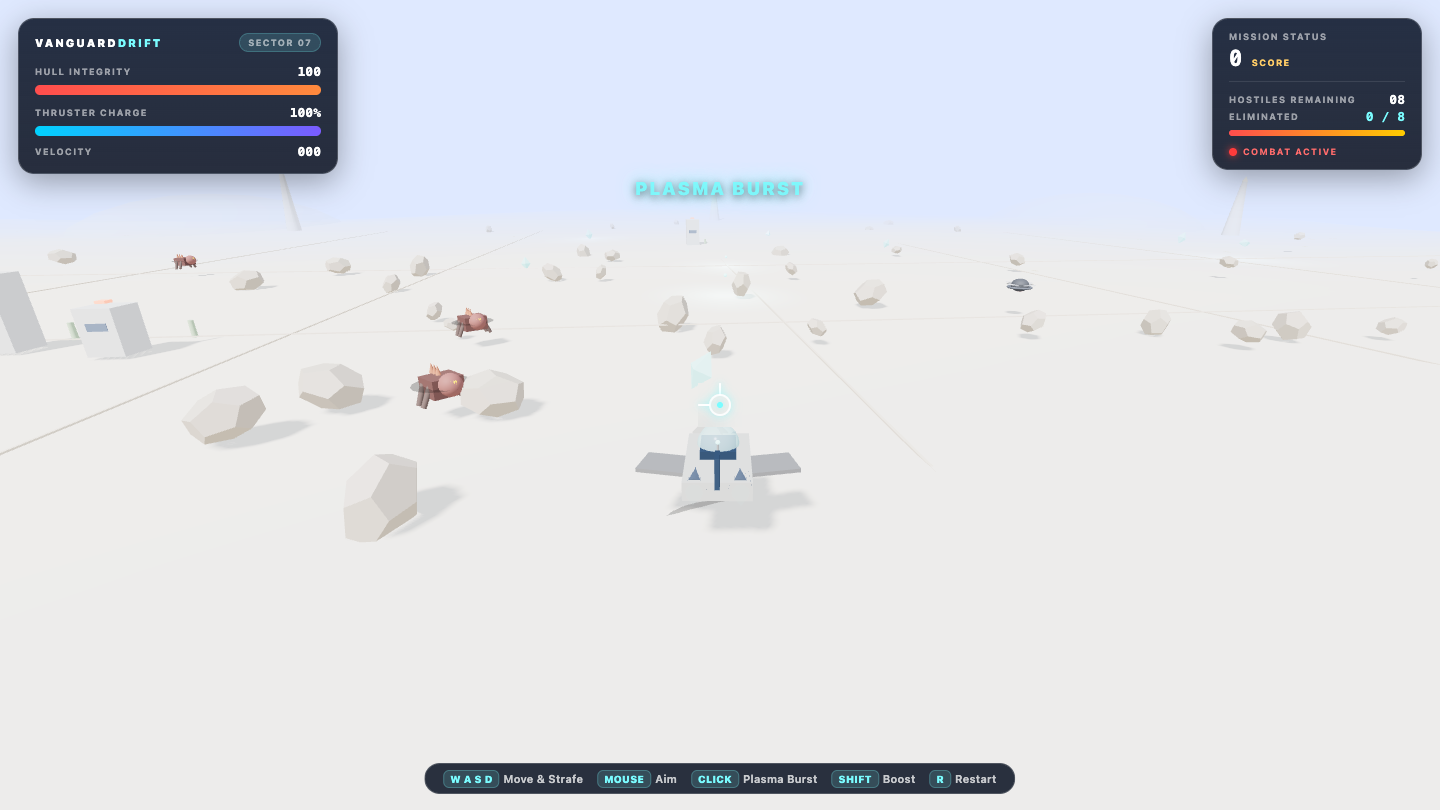
Game
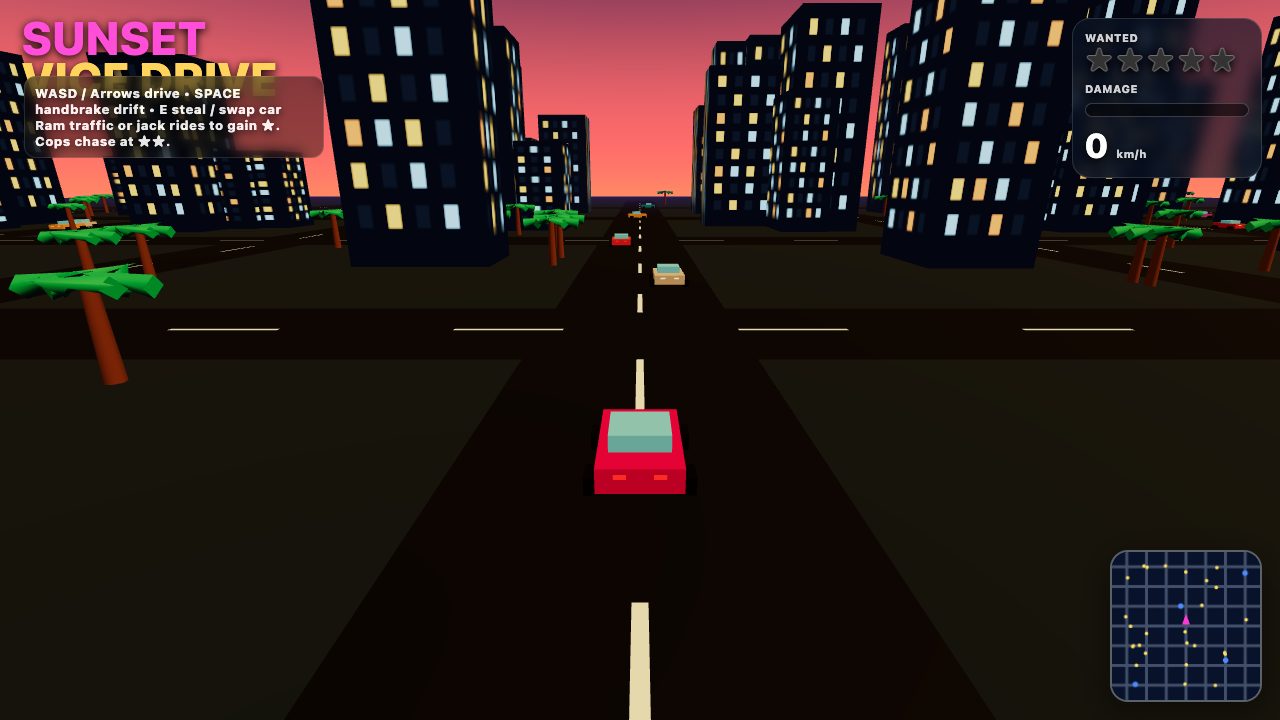
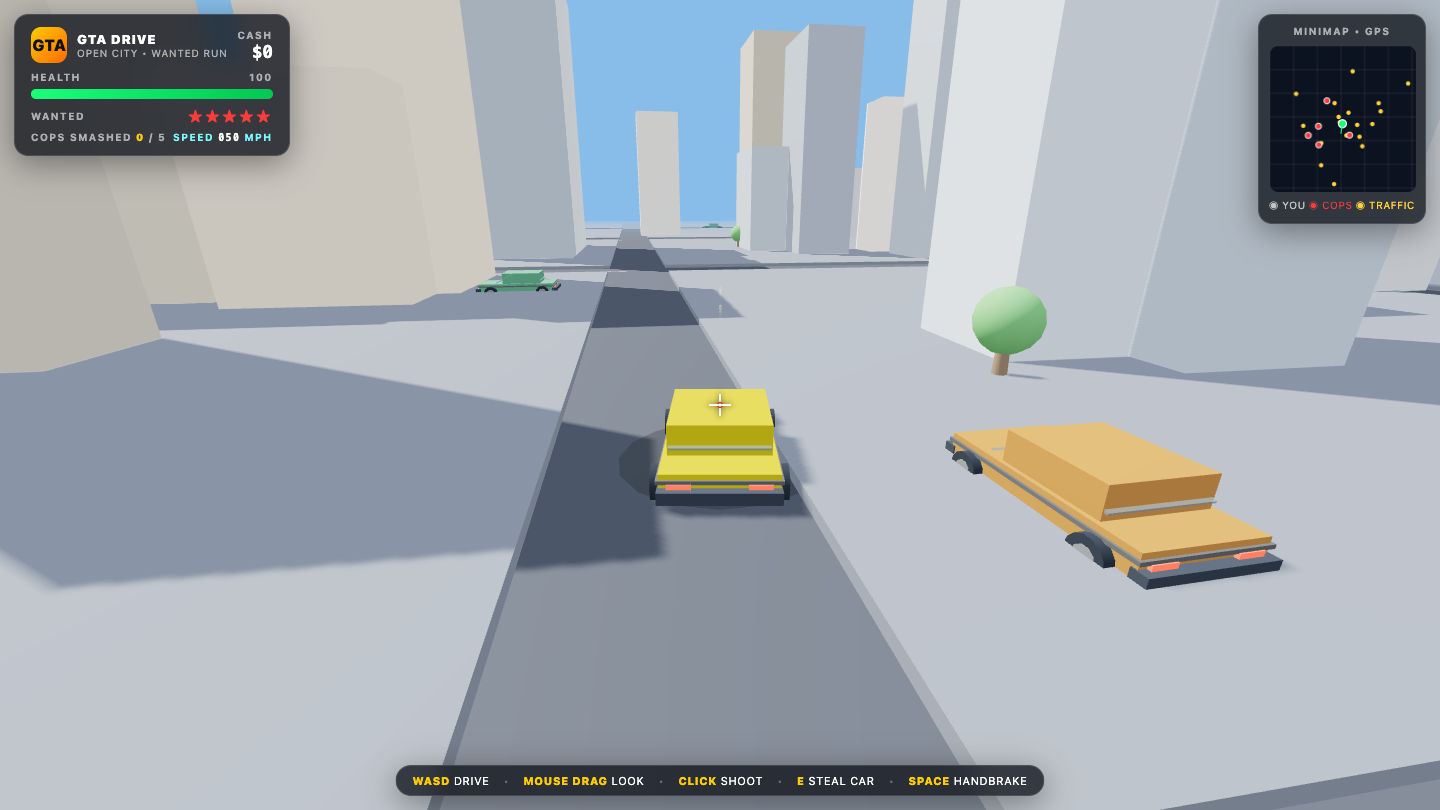
Game
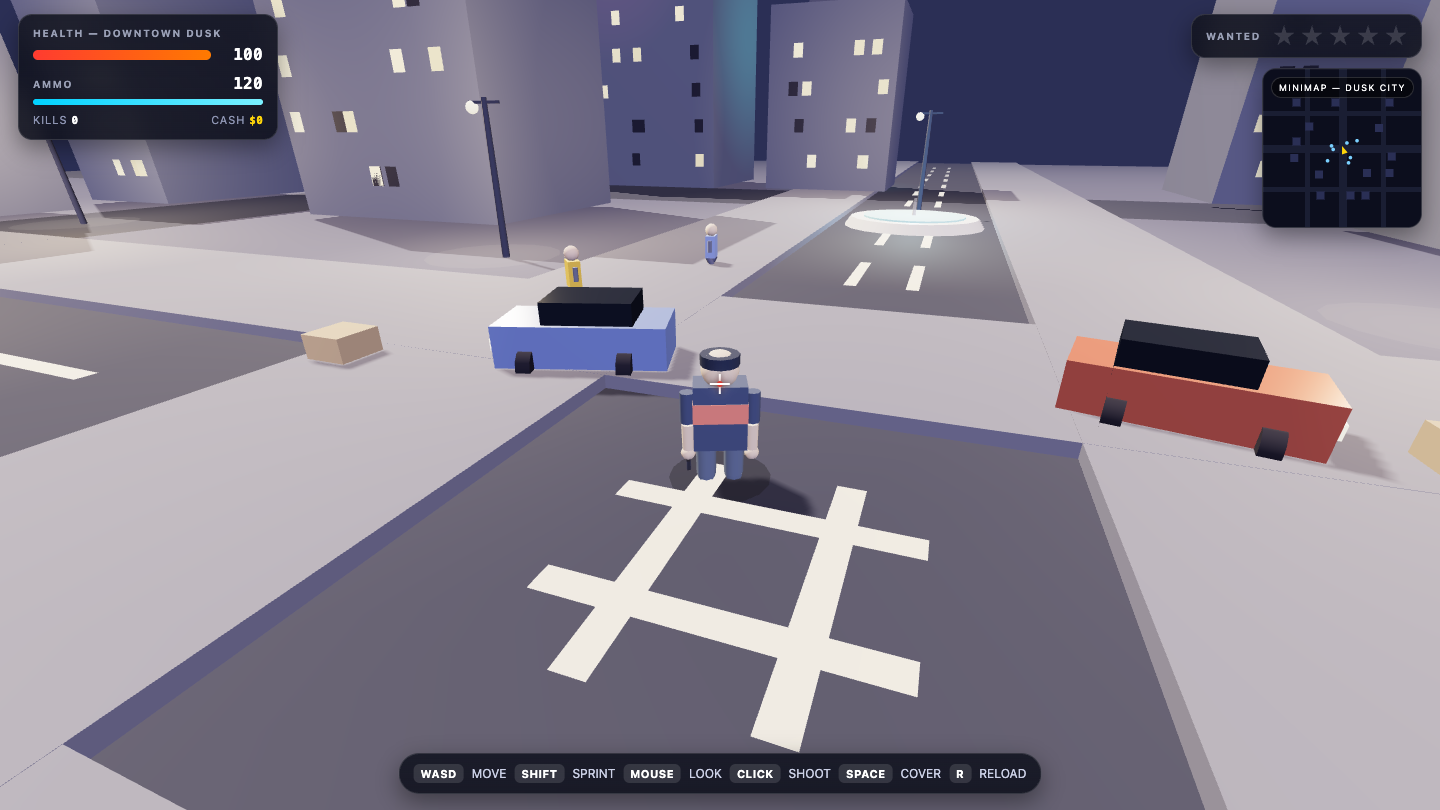
Game
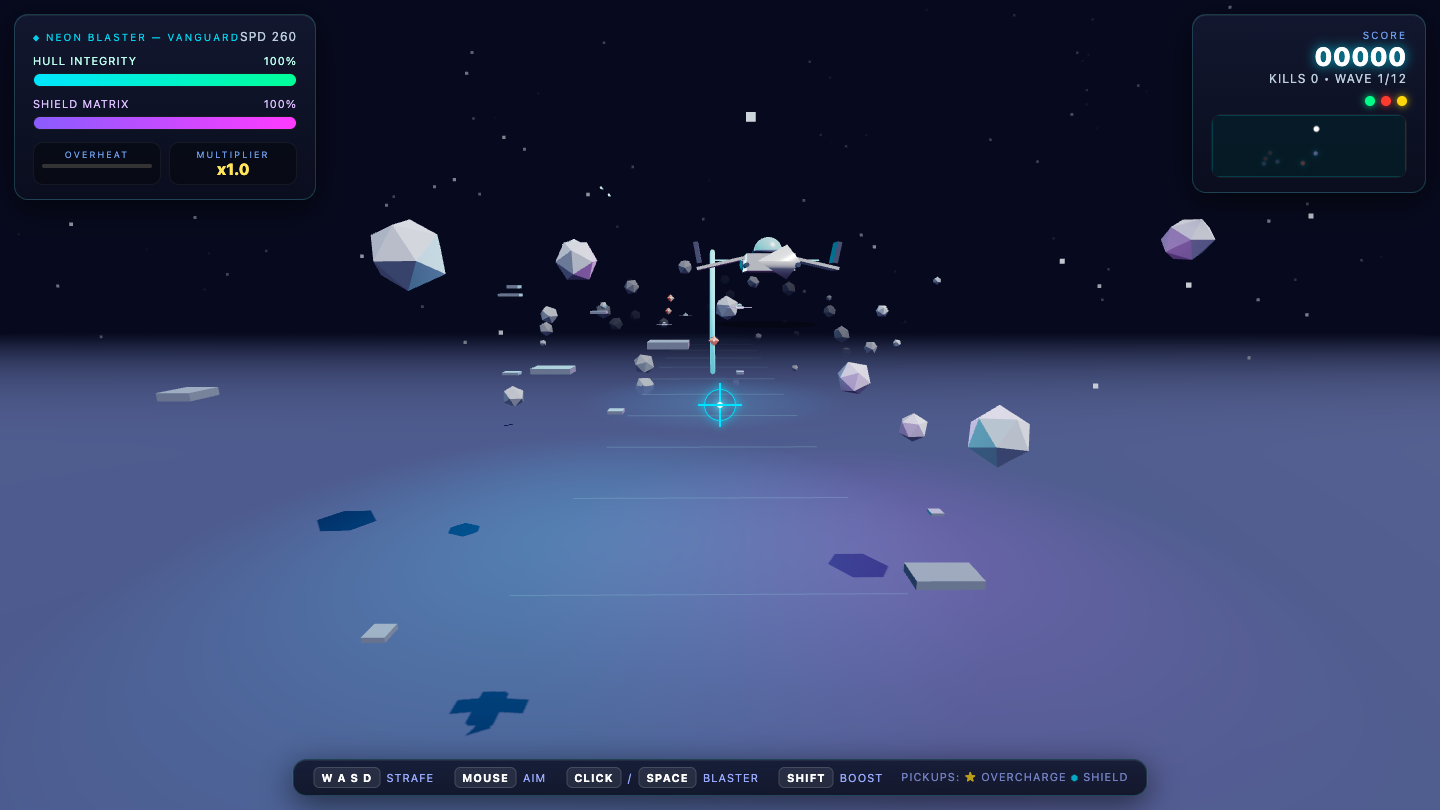
Game
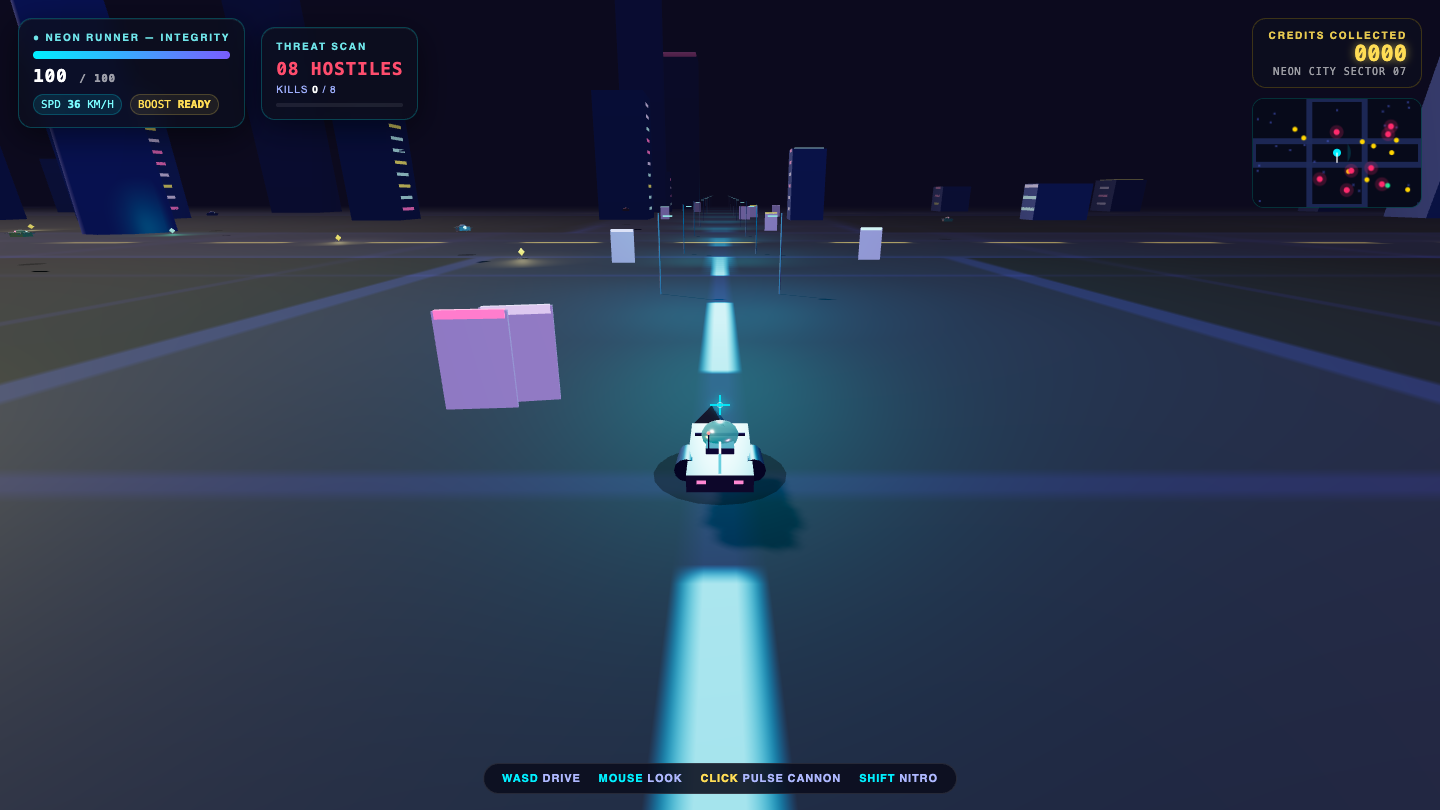
Game
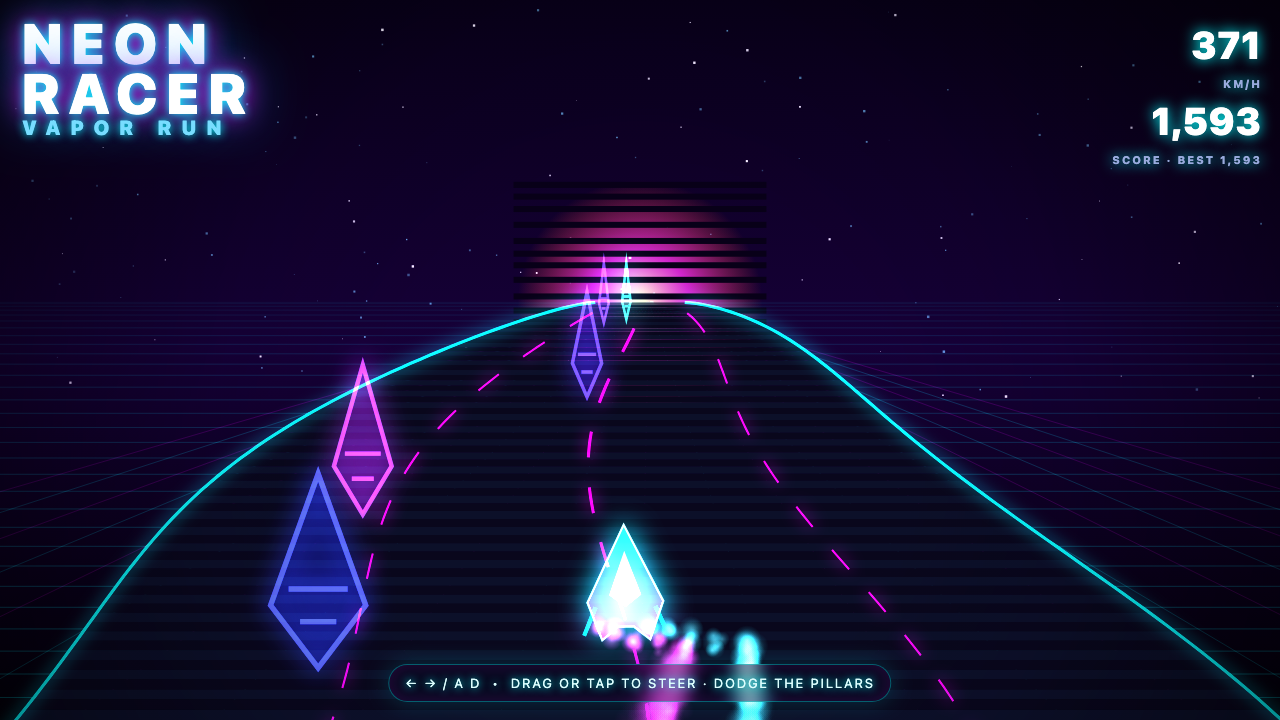
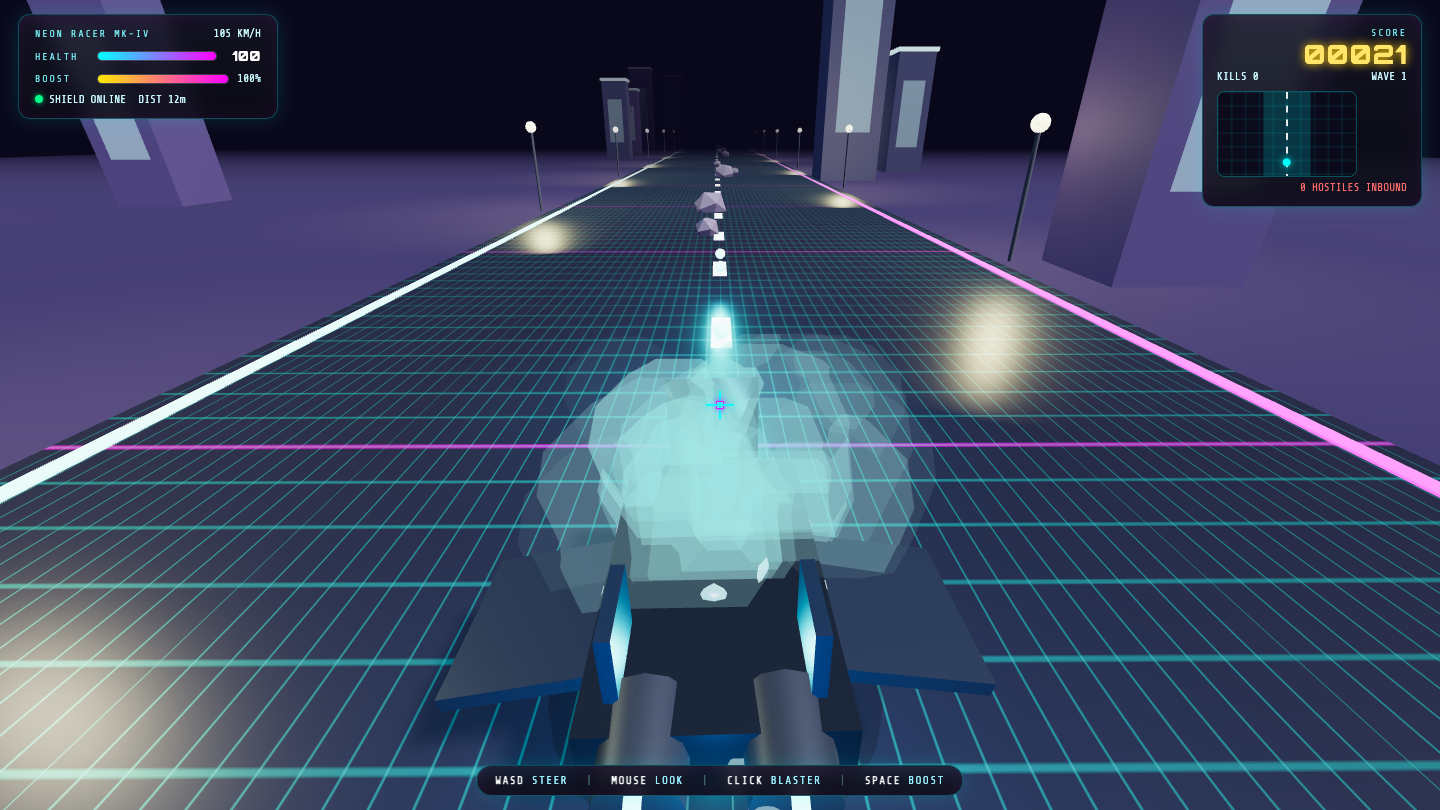
Game
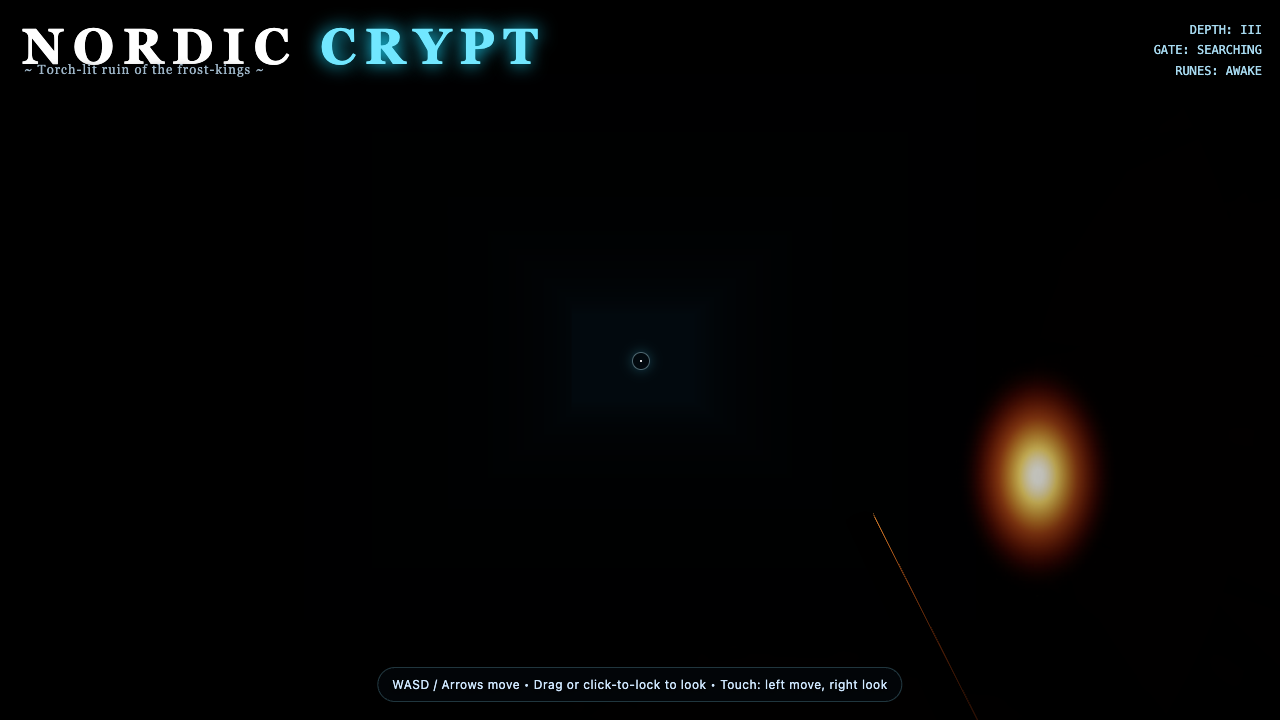
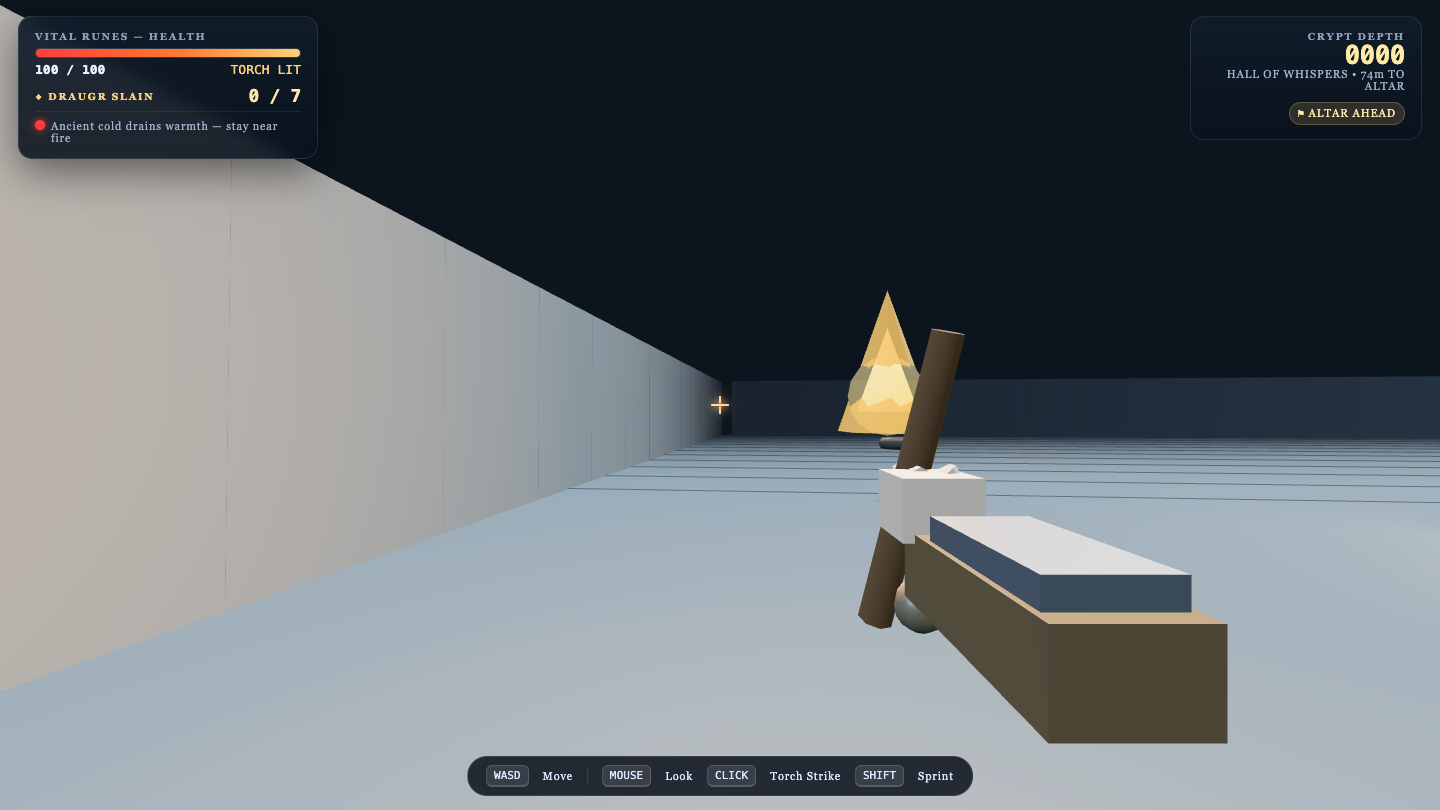
Game
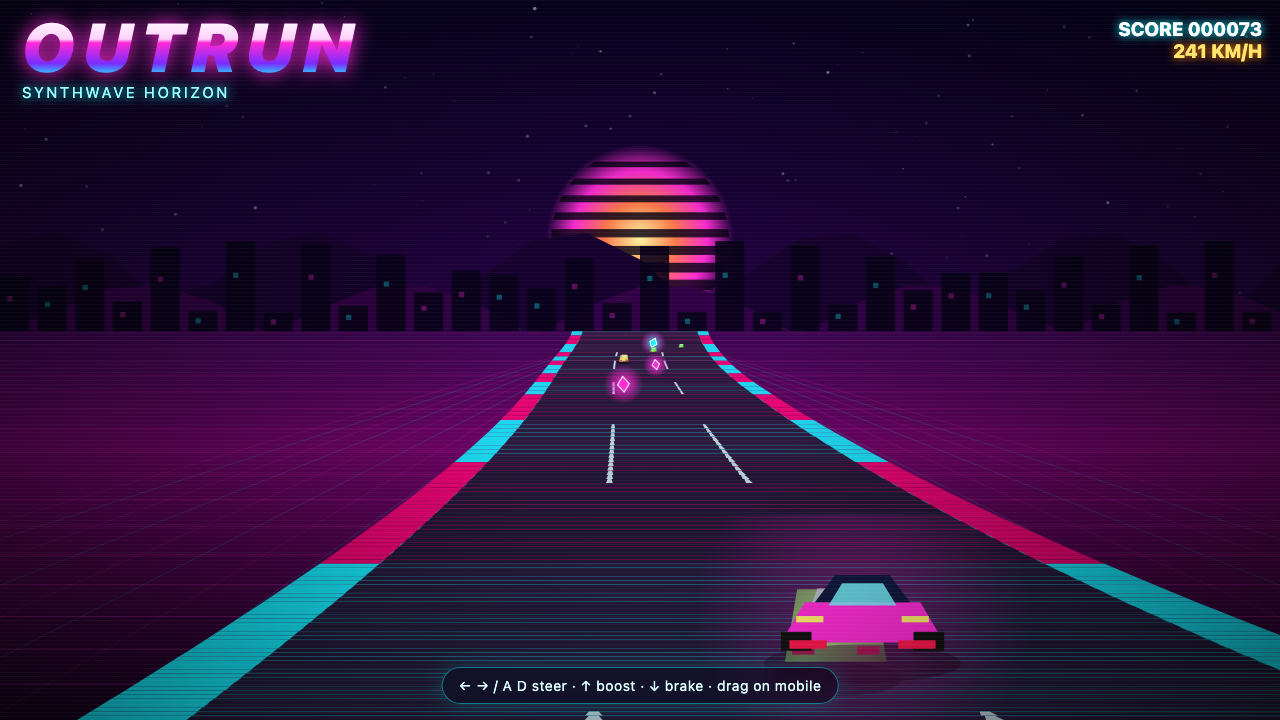
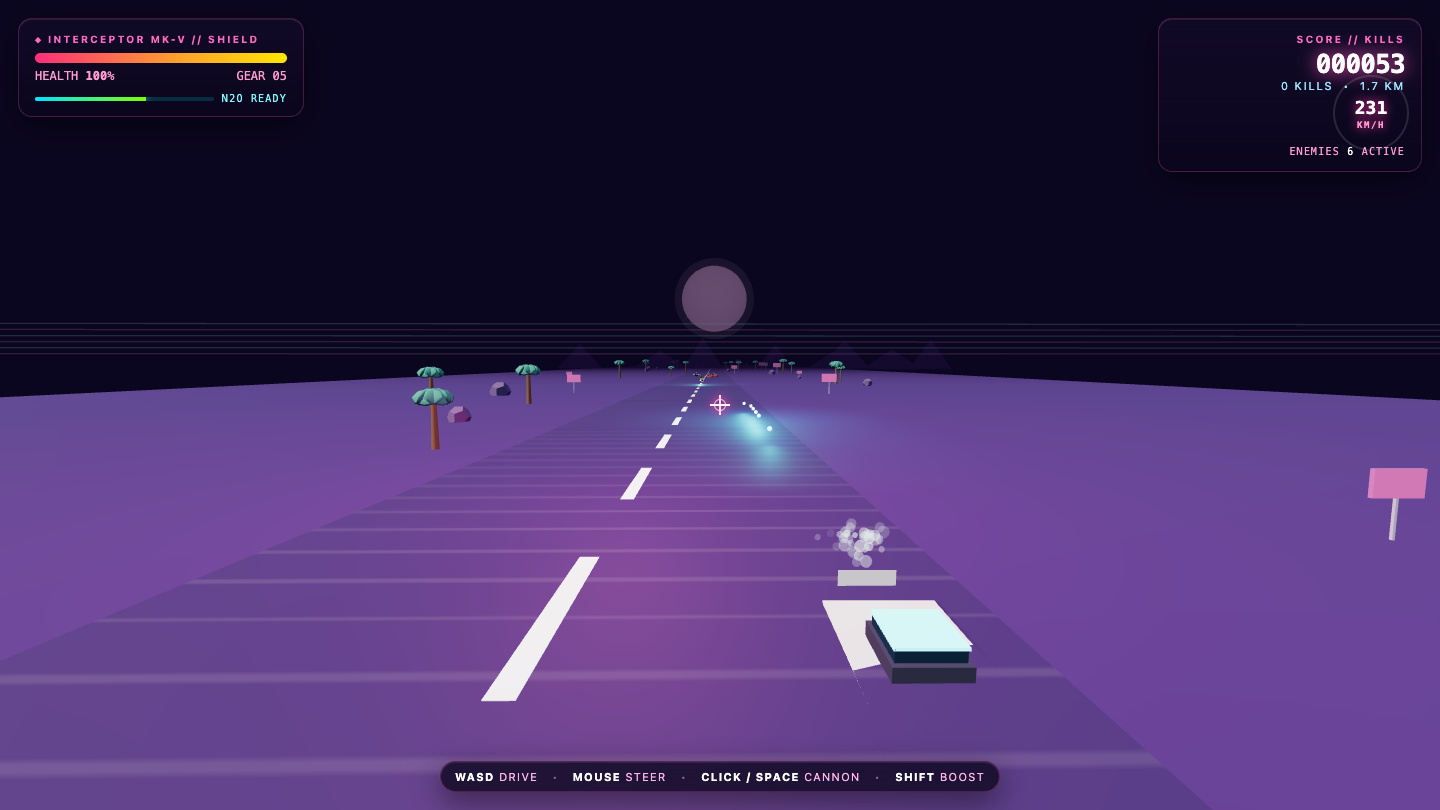
Game
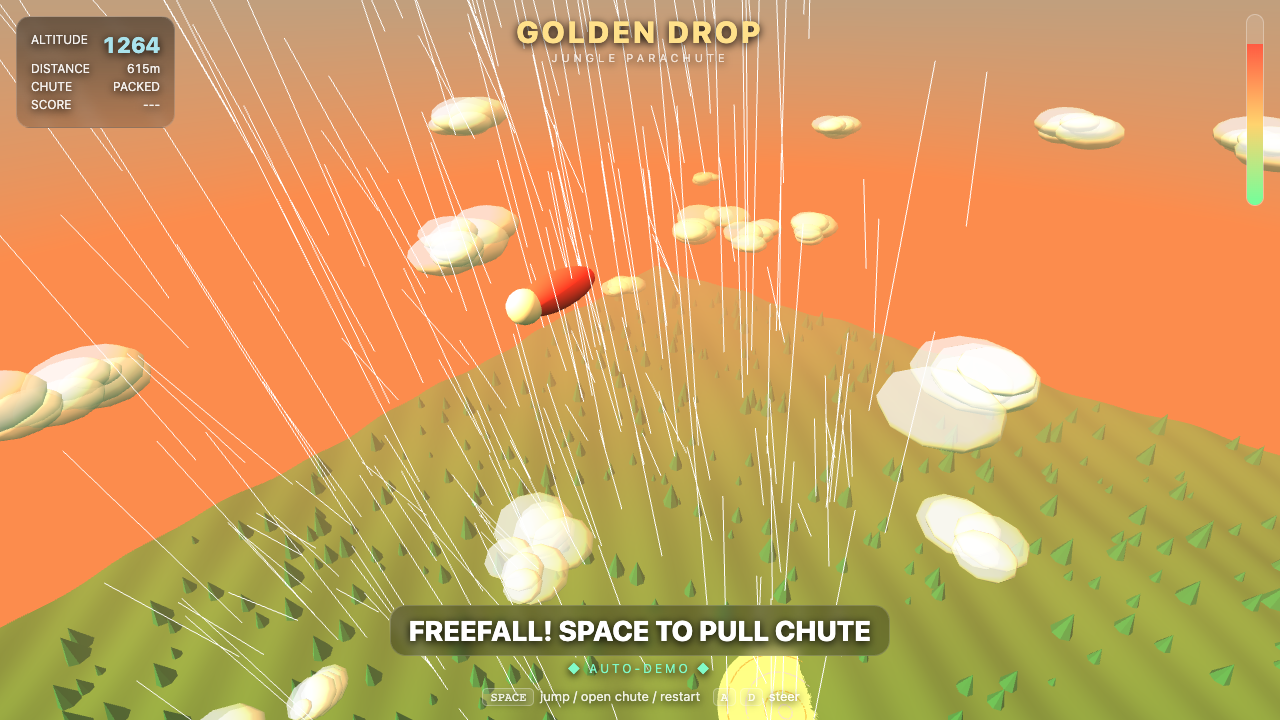
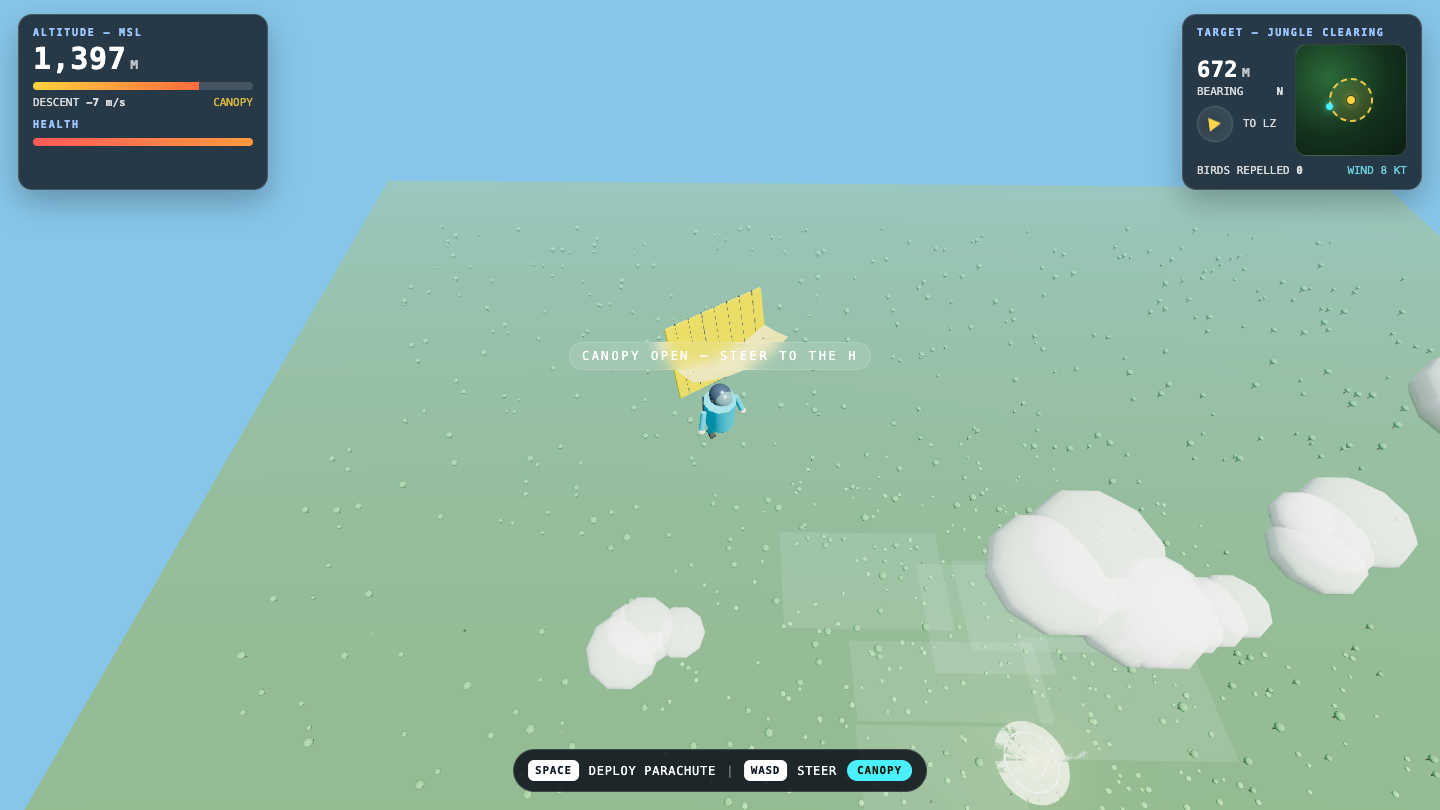
Game
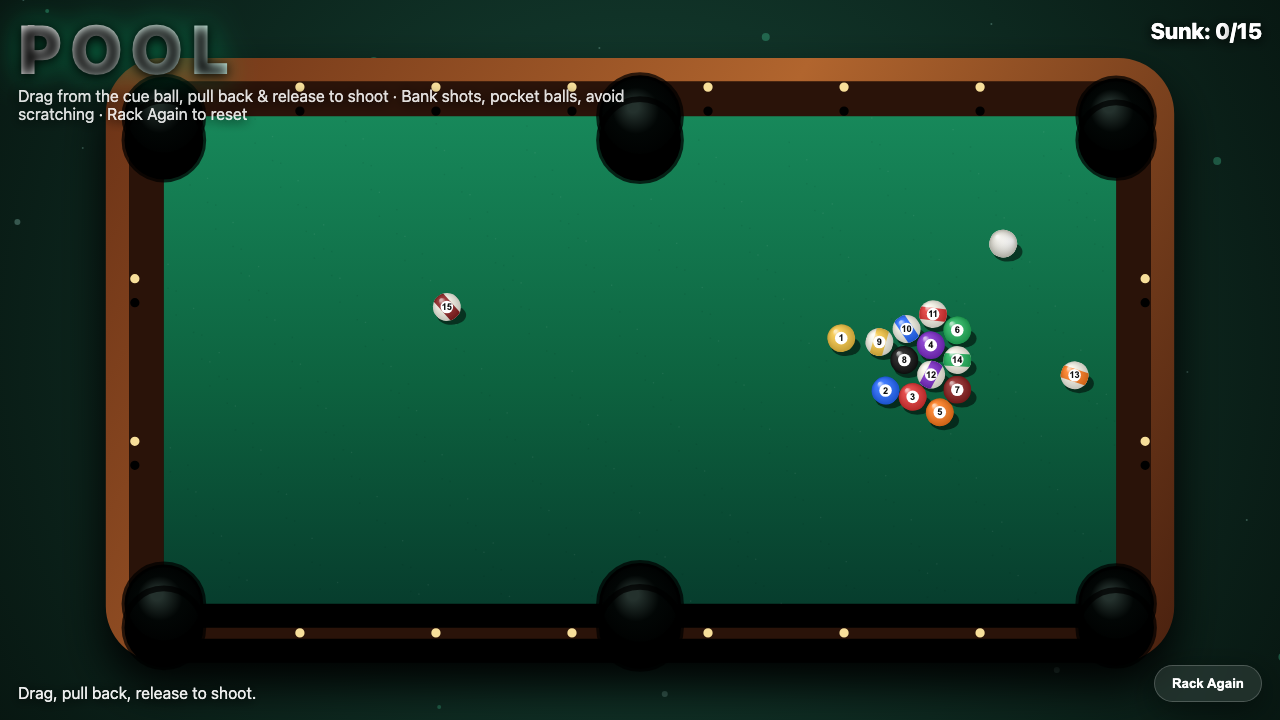
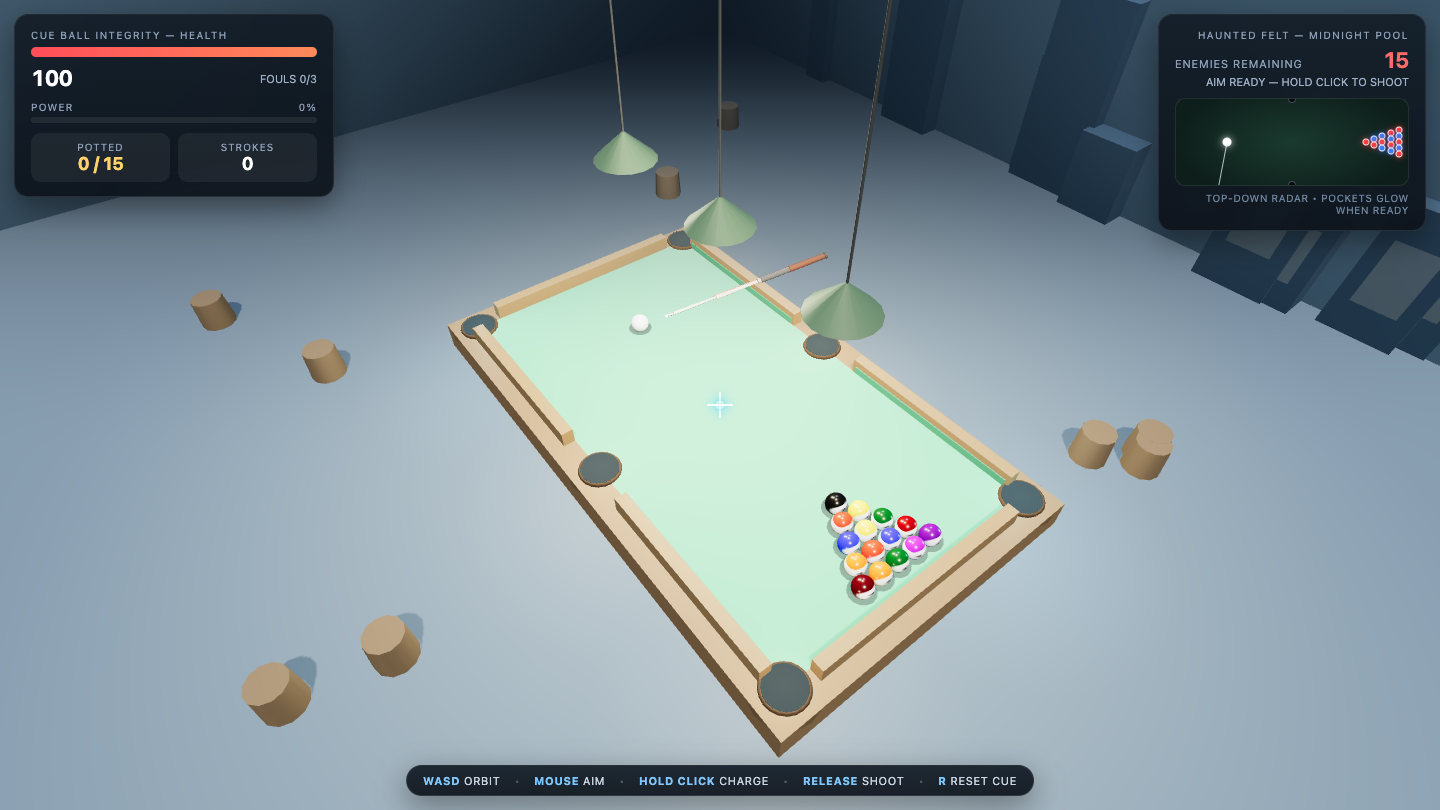
Game
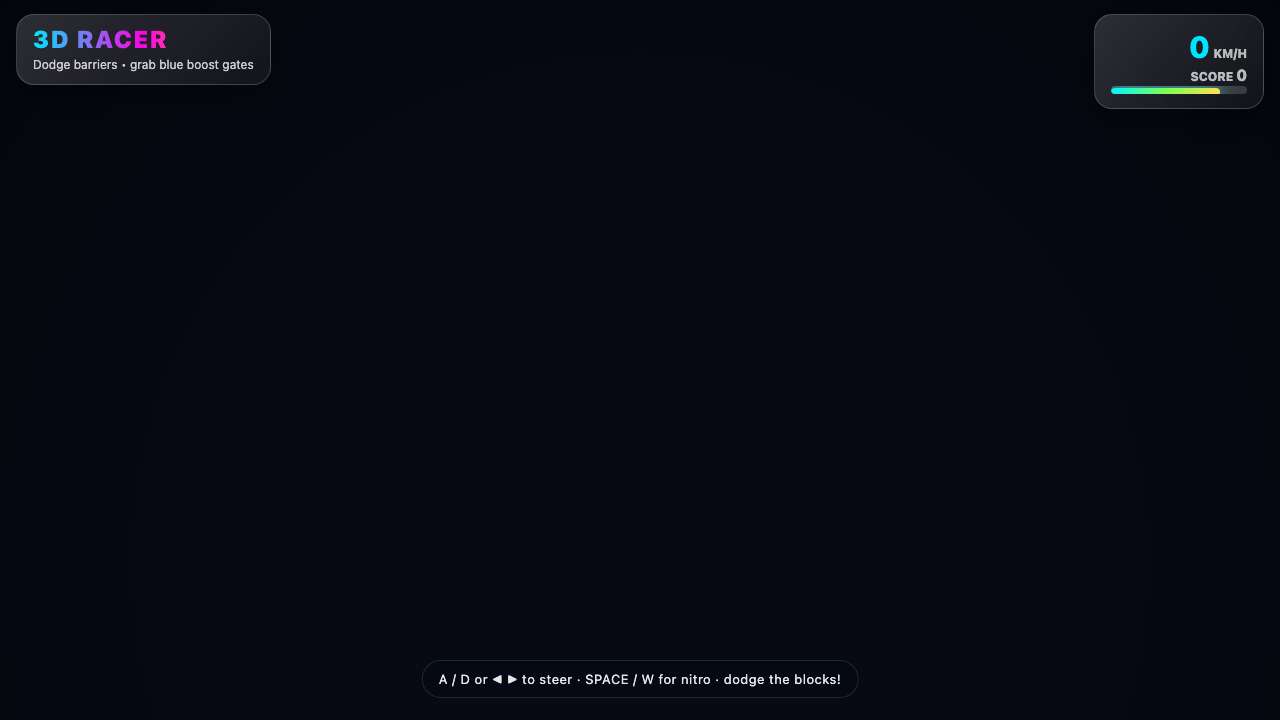
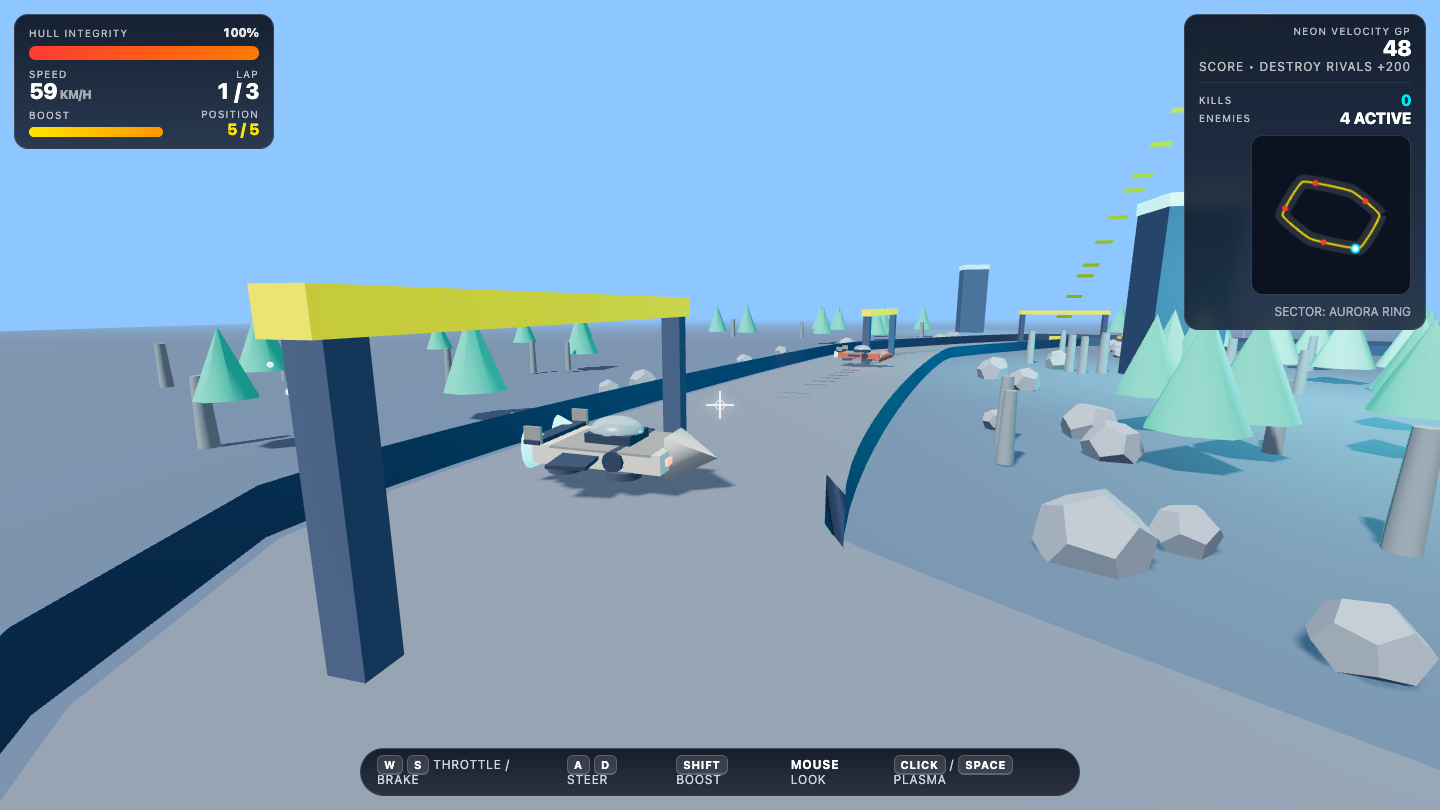
Game
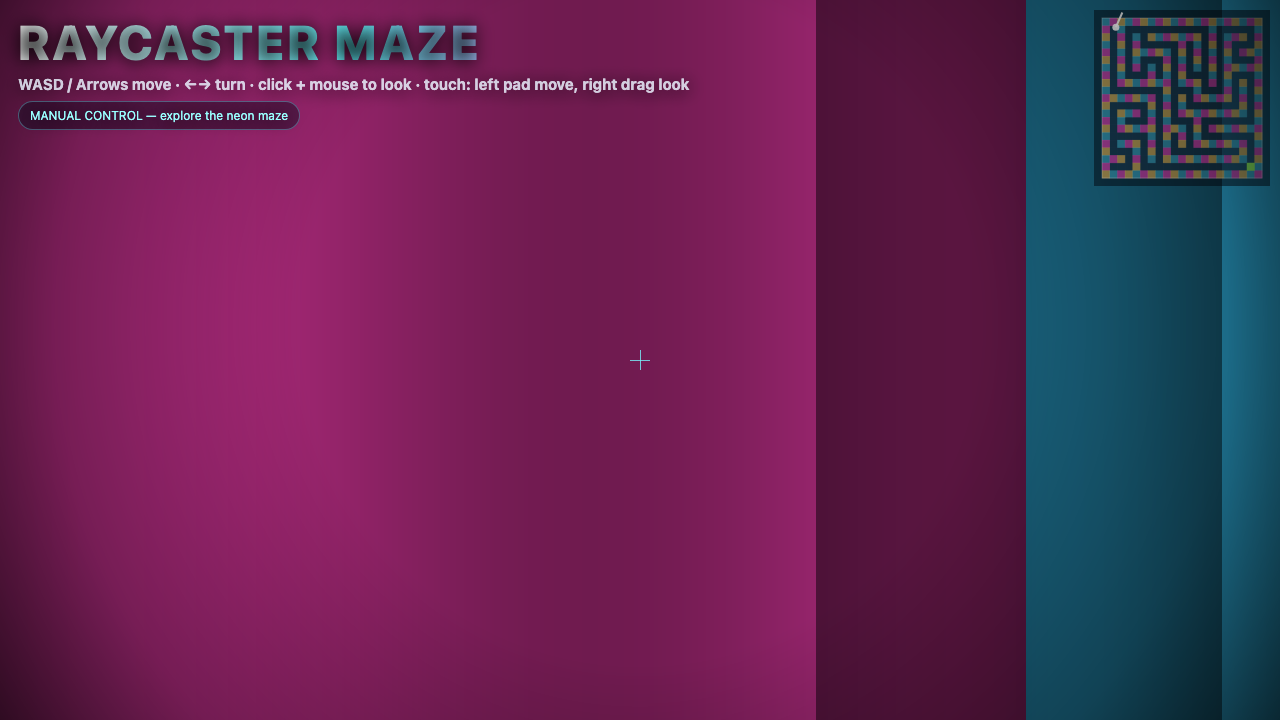
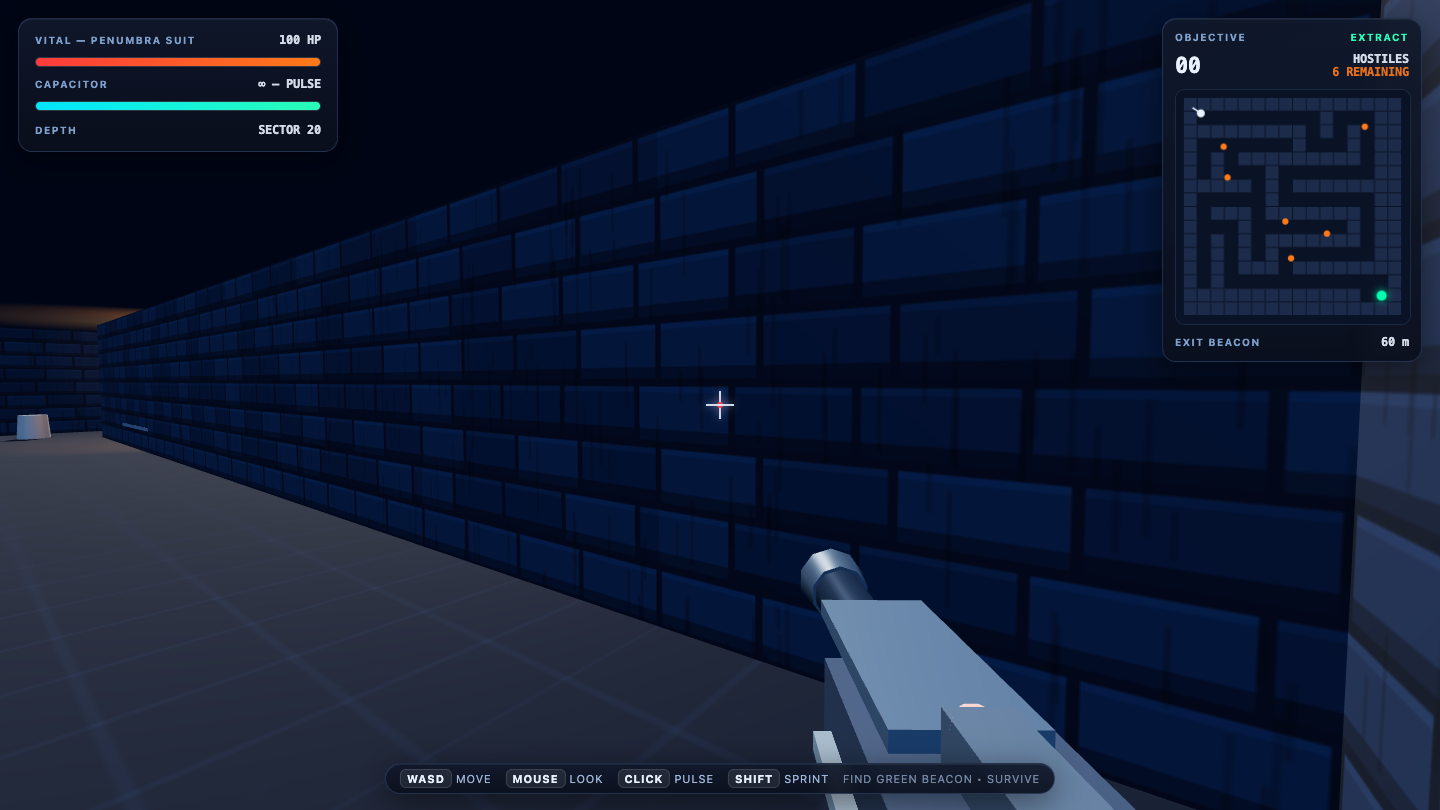
Game
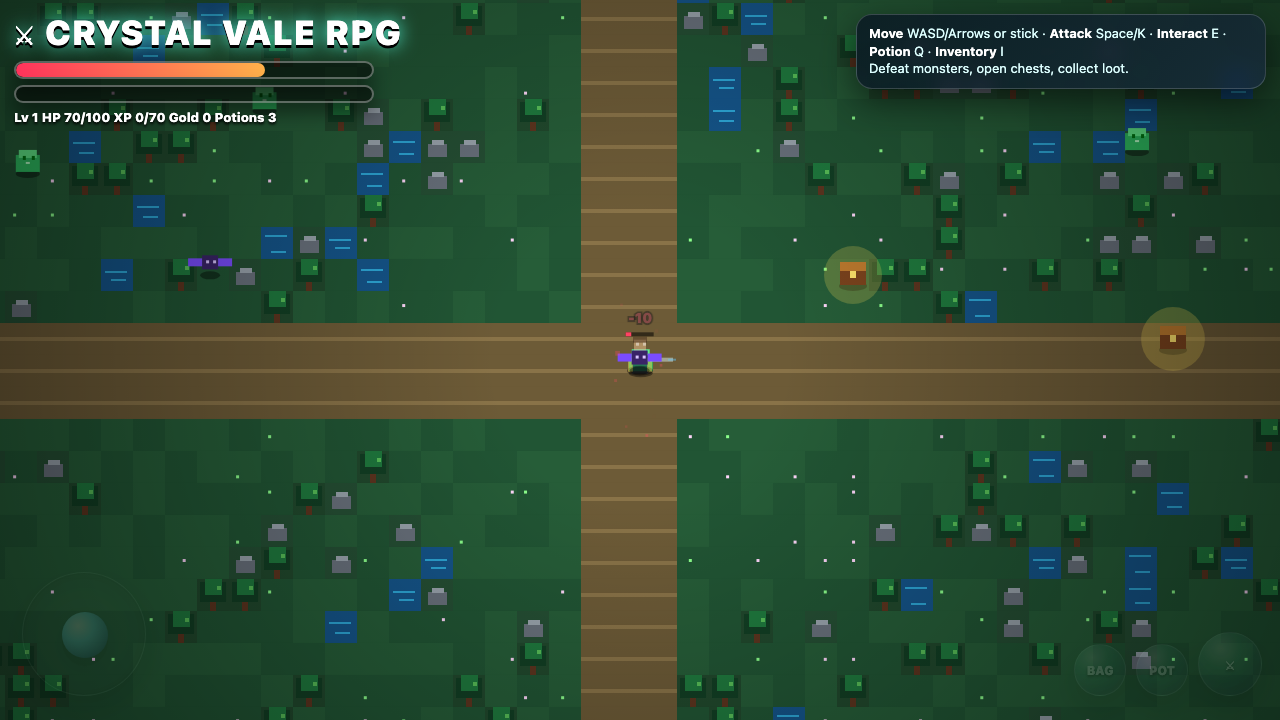
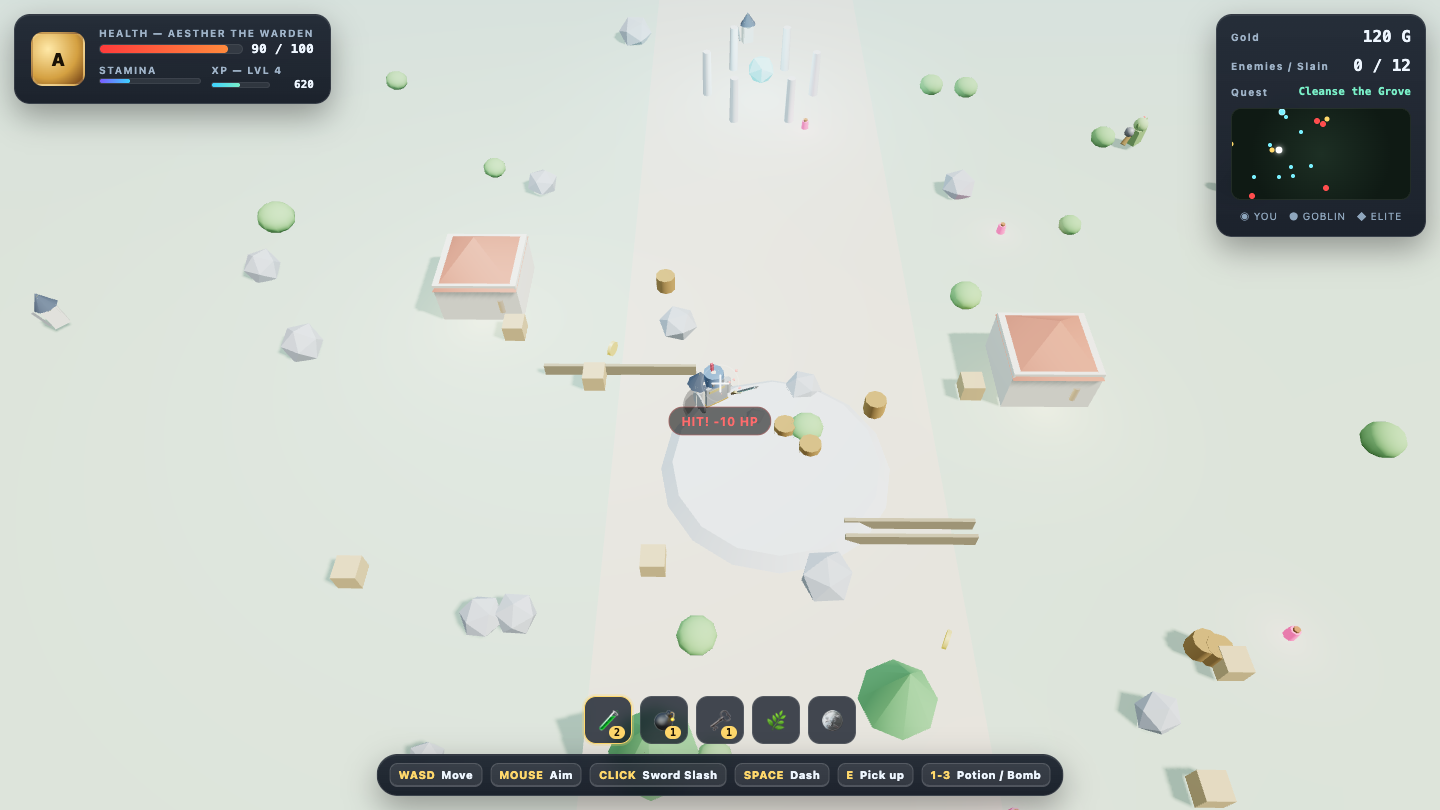
Game
Game
Game
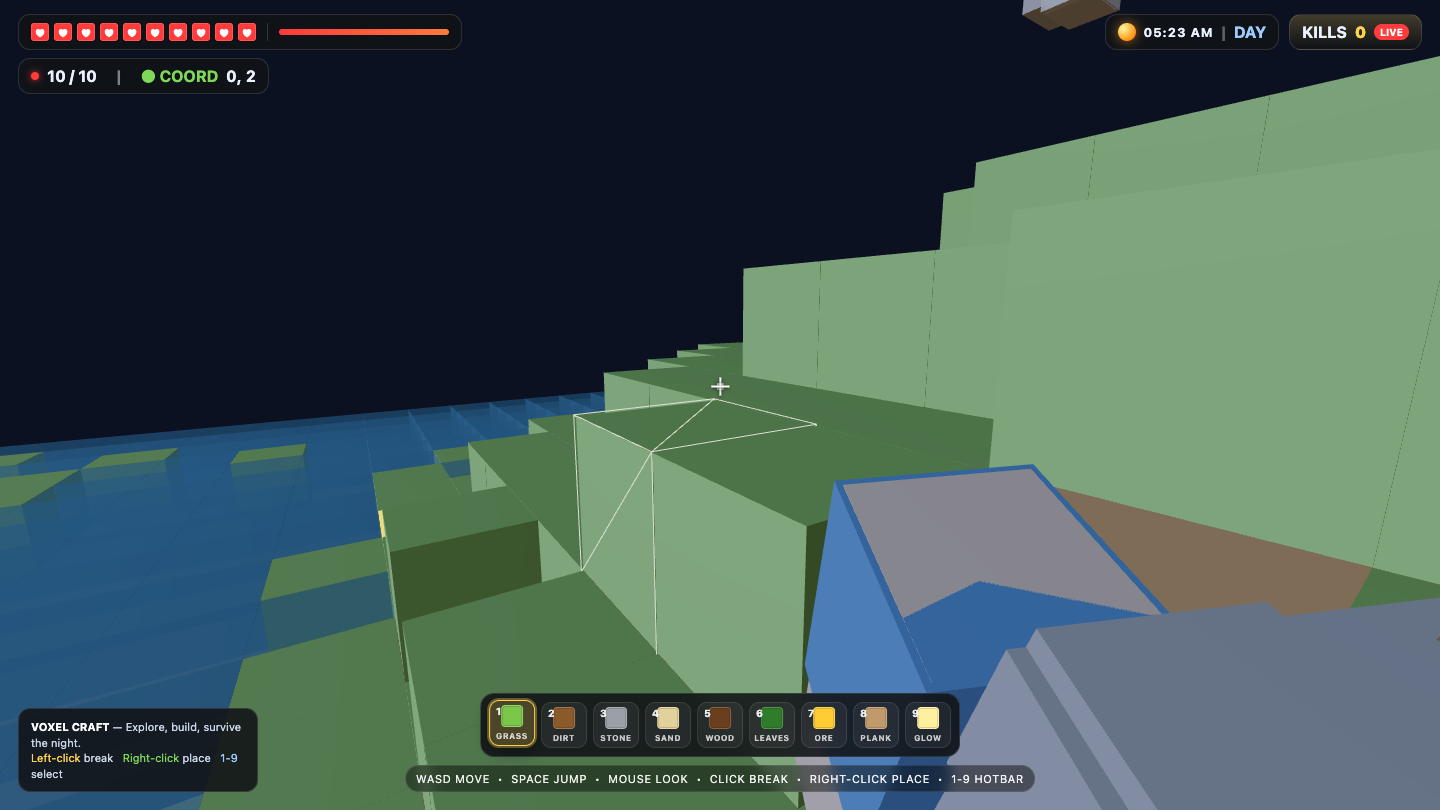
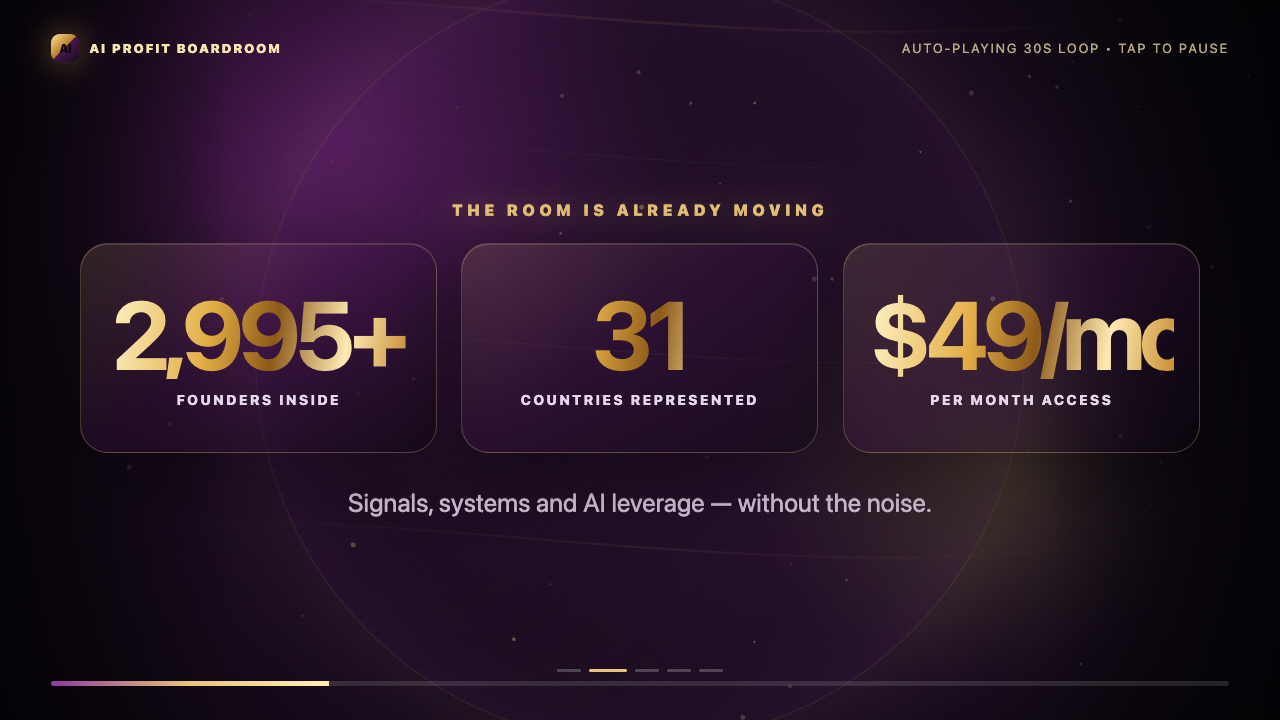
Page
Where Hermes MoA beat Muse Spark 1.2
The tasks where I gave Hermes MoA a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
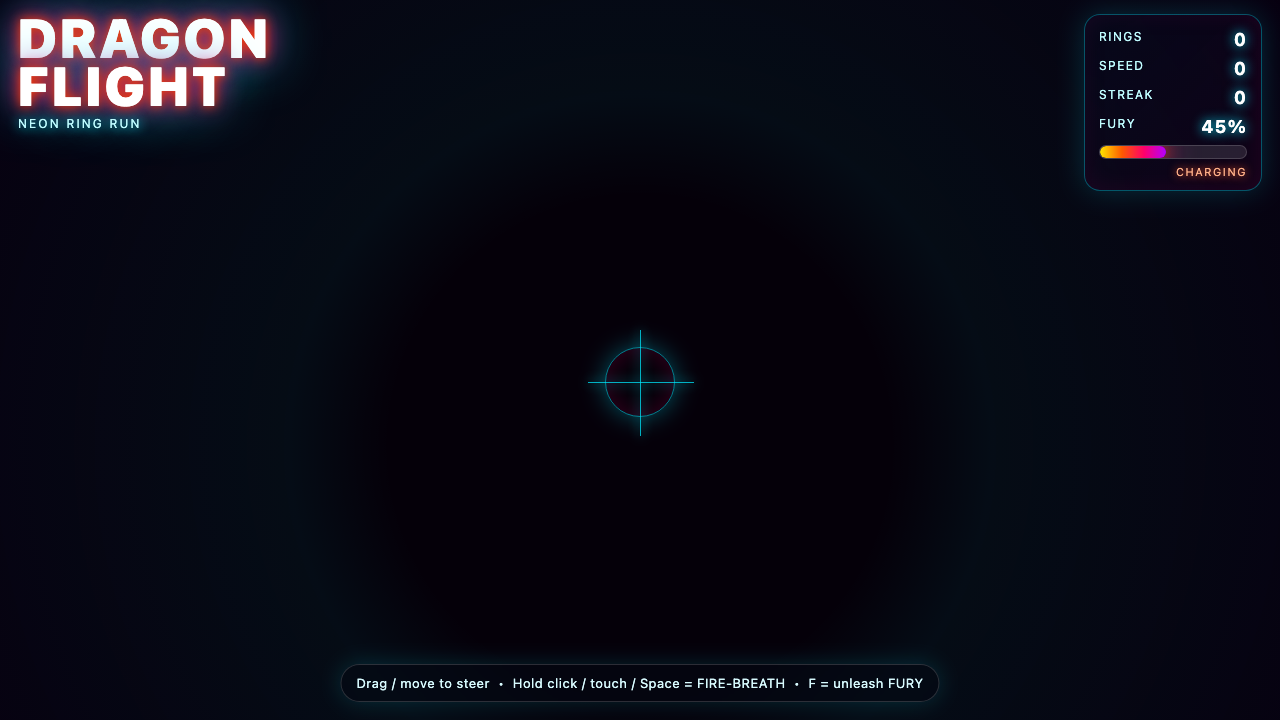
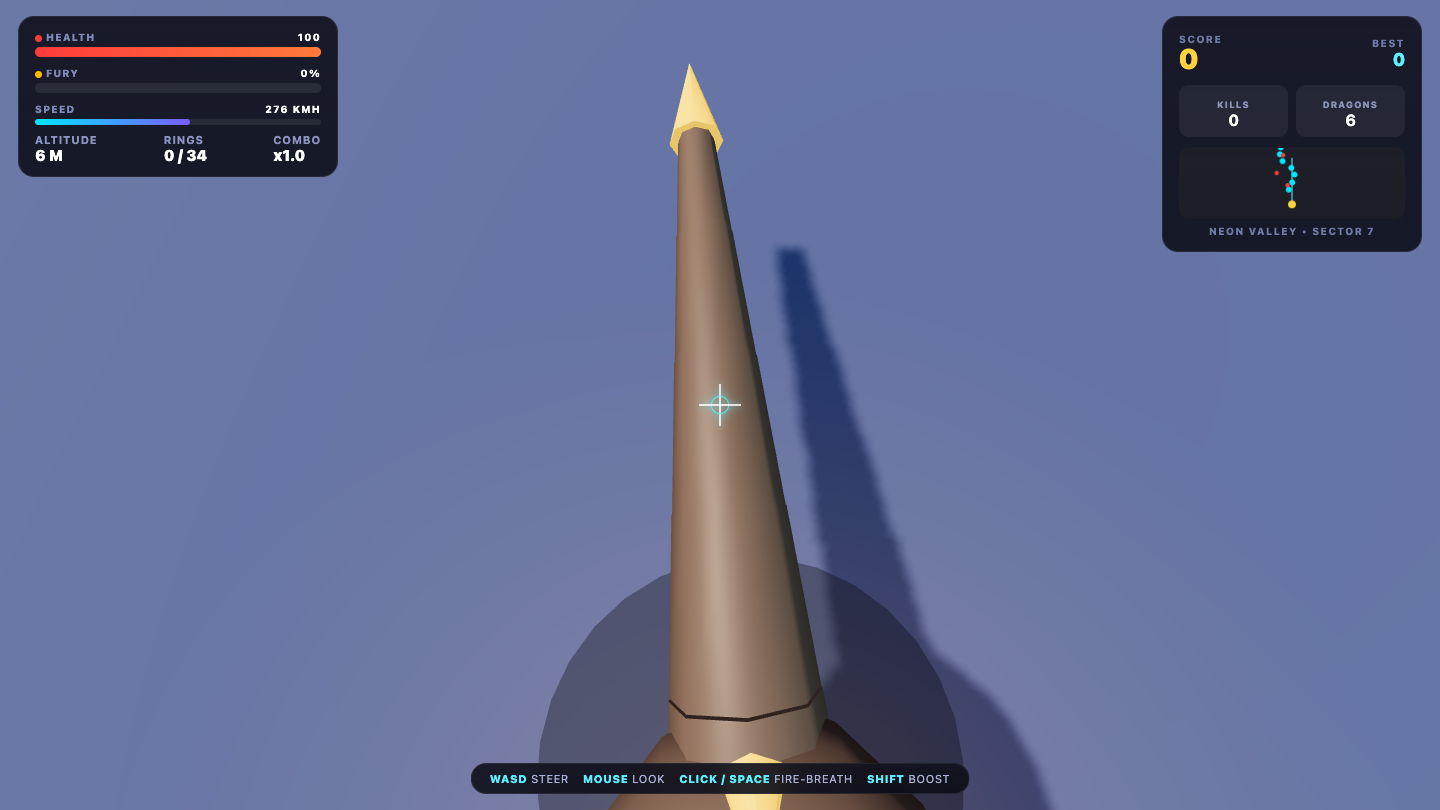
Dragonflight
Game
Hermes MoA 8.6
·
Muse Spark 1.2 4.2
(+4.4)
What I saw: Strong three.js dragon-flight build with a polished neon HUD (rings/speed/streak/fury), a genuinely articulated multi-segment dragon with flapping wings, additive fire-breath particles, fury mode, and three input paths (pointer/keyboard/touch) — visibly richer and more cohesive t…
Skyrim
Game
Hermes MoA 8.4
·
Muse Spark 1.2 4.2
(+4.2)
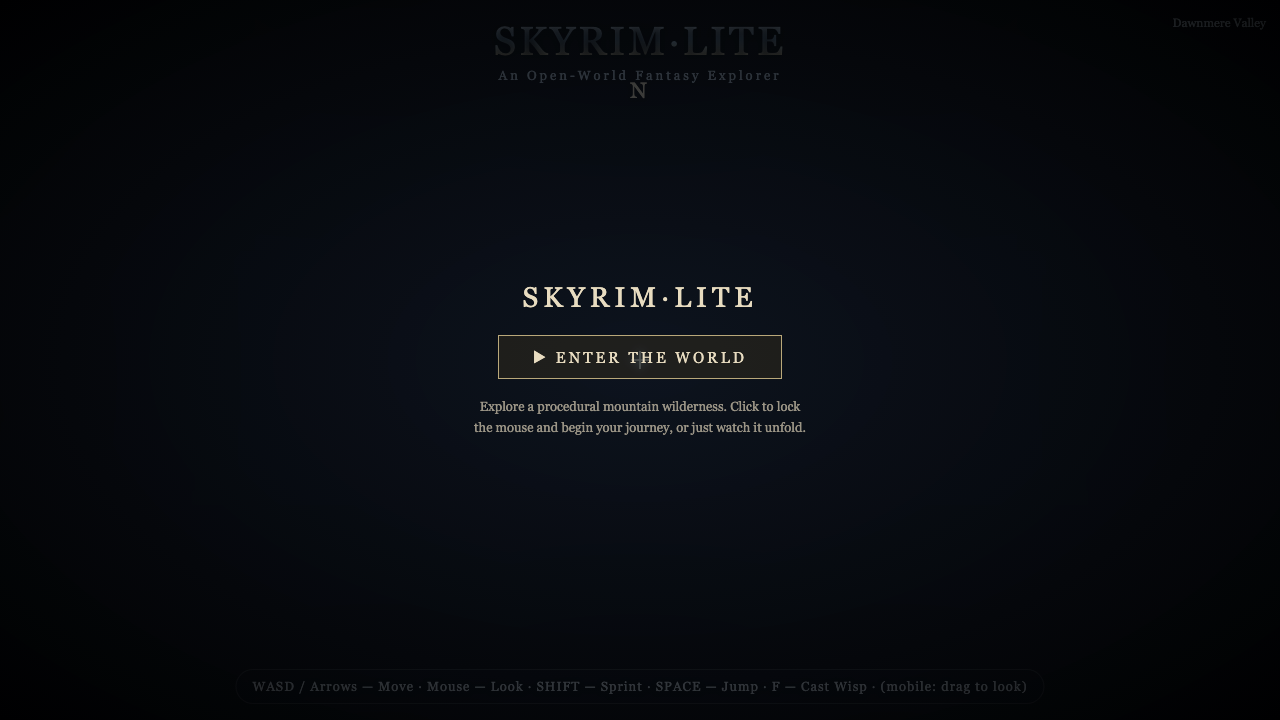
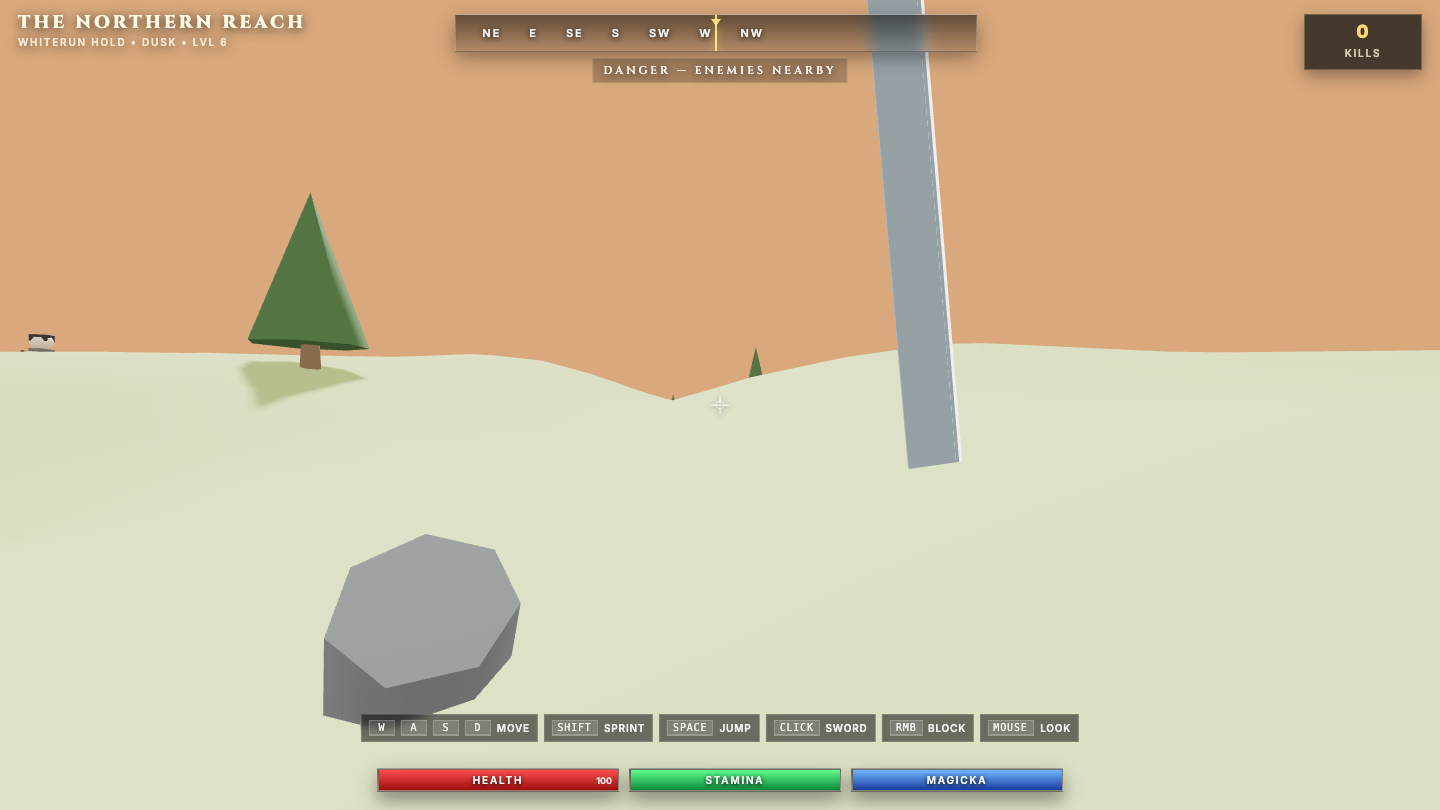
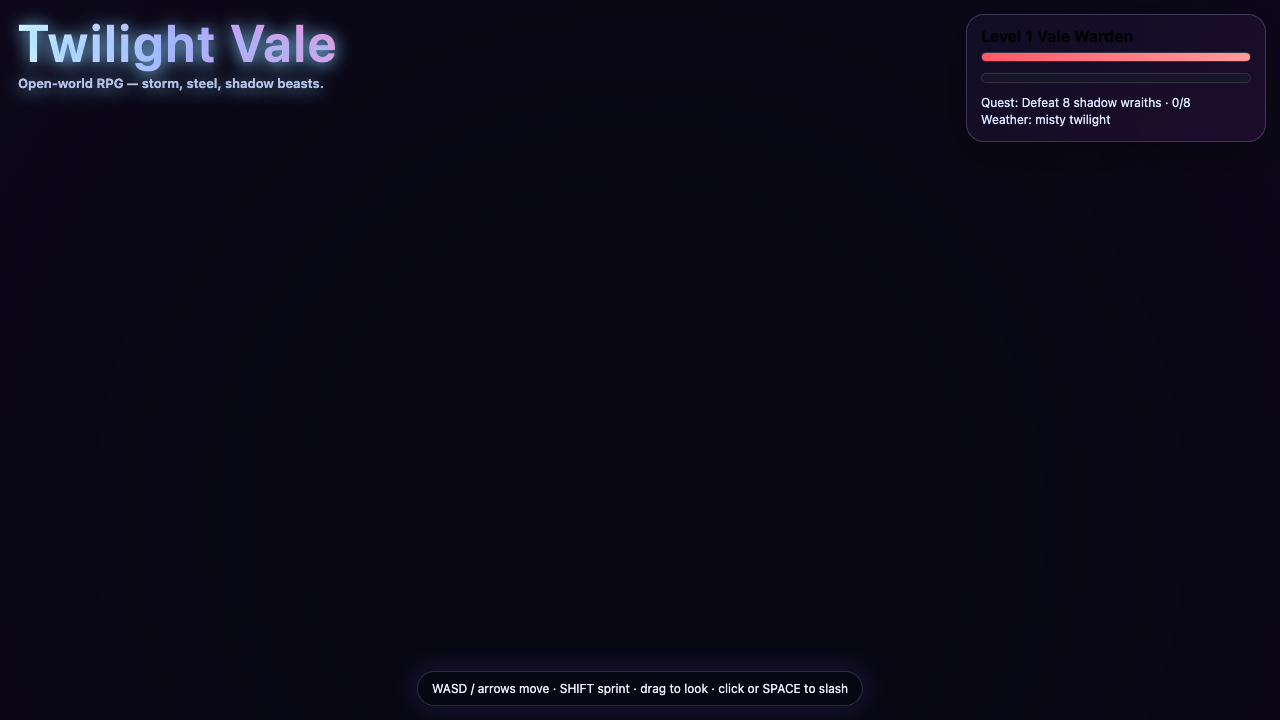
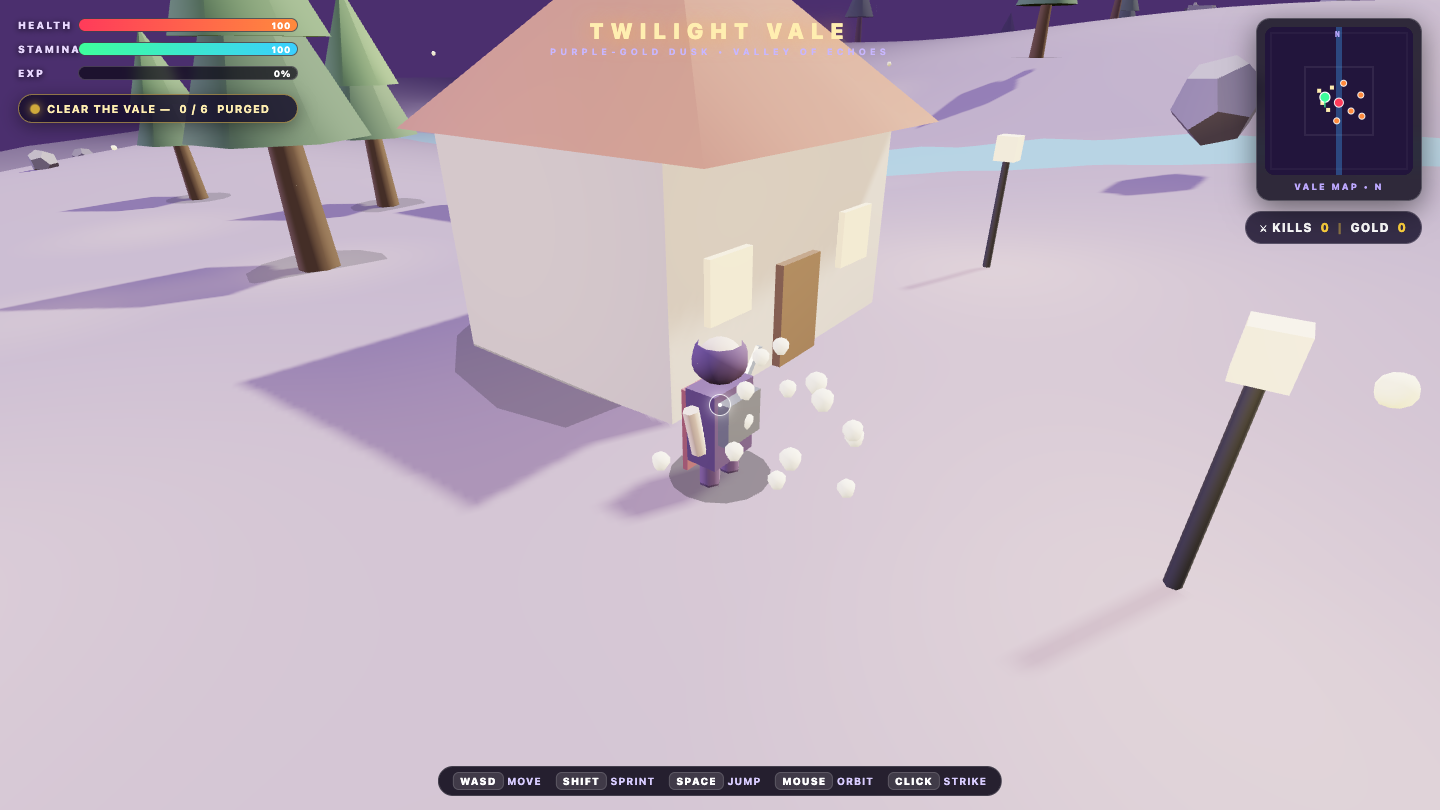
What I saw: Polished single-file three.js Skyrim-lite with vertex-colored terrain, lake basin, instanced pines/rocks, ruins, watchtower, standing-stone ring, custom sky/water shaders, clouds, birds and motes — visually richer than SOLO Opus 4.8 (7.0) and edges out MiniMax (8.5), but the trun…
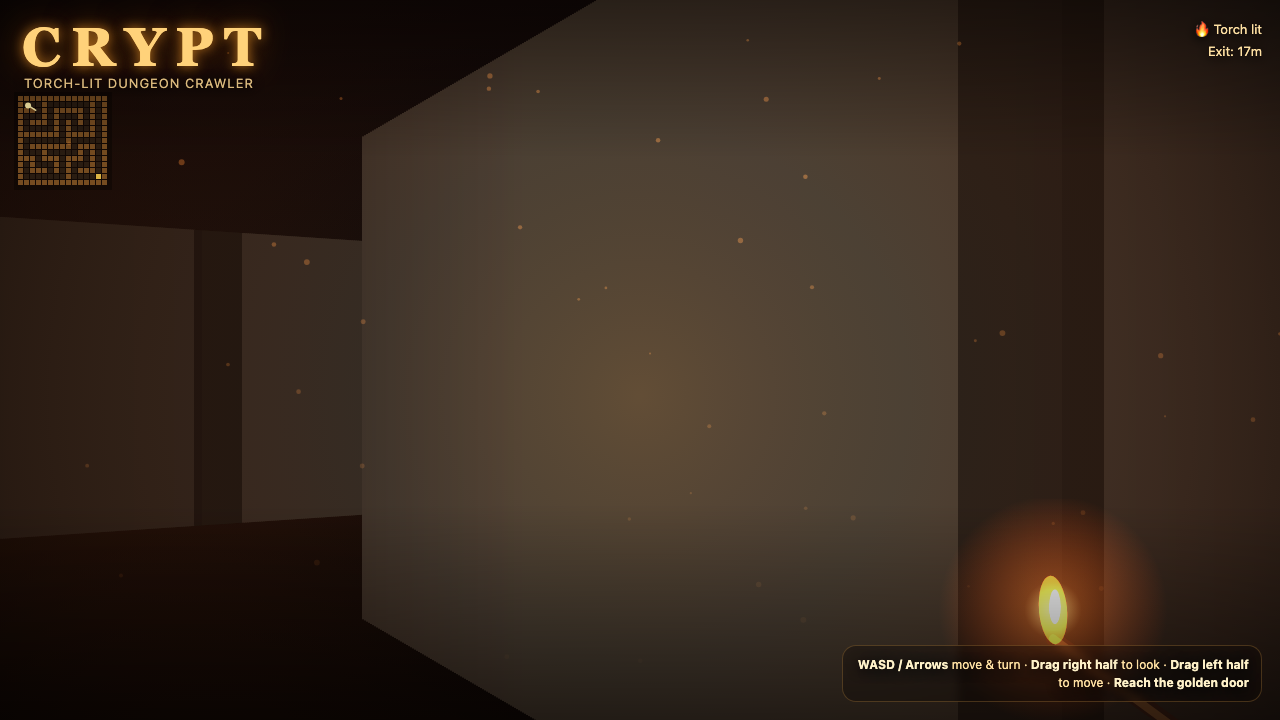
Crypt
Game
Hermes MoA 7.8
·
Muse Spark 1.2 4.5
(+3.3)
What I saw: A clean, self-contained 2.5D raycaster (Wolfenstein-style) crypt with solid mortar/flicker shading, held torch, embers, minimap, and dual touch+keyboard controls — it plays well and is genuinely atmospheric, but it's a flat maze-escape with no enemies or combat, undershooting the…
Doom
Game
Hermes MoA 8.6
·
Muse Spark 1.2 5.5
(+3.1)
What I saw: A complete, polished raycaster that nails the Doom screenshot framing — corridor with imps dead ahead, detailed canvas-drawn imp sprites with bob/flash/death states, muzzle flash, screen-shake kick, hit-scan with line-of-sight checks, and a clean DOOM-branded HUD with health/ammo…
Nordiccrypt
Game
Hermes MoA 7.8
·
Muse Spark 1.2 5.2
(+2.6)
What I saw: Polished Nordic crypt with strong texture/torch/ember/rune atmosphere, instanced walls, mobile joysticks and pointer-lock — clearly beats SOLO Opus 4.8 (6.0), but the displayed source is cut mid-mousemove handler so the input/movement/collision/animation loop can't be confirmed, …
Where Muse Spark 1.2 beat Hermes MoA
The tasks where I gave Muse Spark 1.2 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Gtafoot
Game
Muse Spark 1.2 8.0
·
Hermes MoA 4.5
(+3.5)
What I saw: Strong, polished dusk city that renders cleanly with third-person character, cars, pedestrians, cover crate, street lighting, and a full HUD (health/ammo/kills/cash, wanted stars, minimap). Weak point is a slightly generic blocky world and only screenshot-static evidence of shoot…
Flightsim
Game
Muse Spark 1.2 8.4
·
Hermes MoA 6.5
(+1.9)
· Polished flight HUD
What I saw: Strong render: clean 3D plane, textured runway with markings, terrain with trees, and a genuinely rich flight HUD (airspeed/altitude/VS tape, heading compass, throttle/hull, artificial horizon, gear/kills chips). Slightly generic terrain and low-detail plane keep it just below th…
Parachute
Game
Muse Spark 1.2 8.1
·
Hermes MoA 6.5
(+1.6)
What I saw: Renders cleanly in the canopy phase with a polished HUD—altitude/health meters, minimap, bearing arrow, wind, and a well-drawn skydiver with deployed chute over jungle terrain with volumetric clouds. Weak spots: the ground plane's hard triangular edge breaks immersion and the jun…
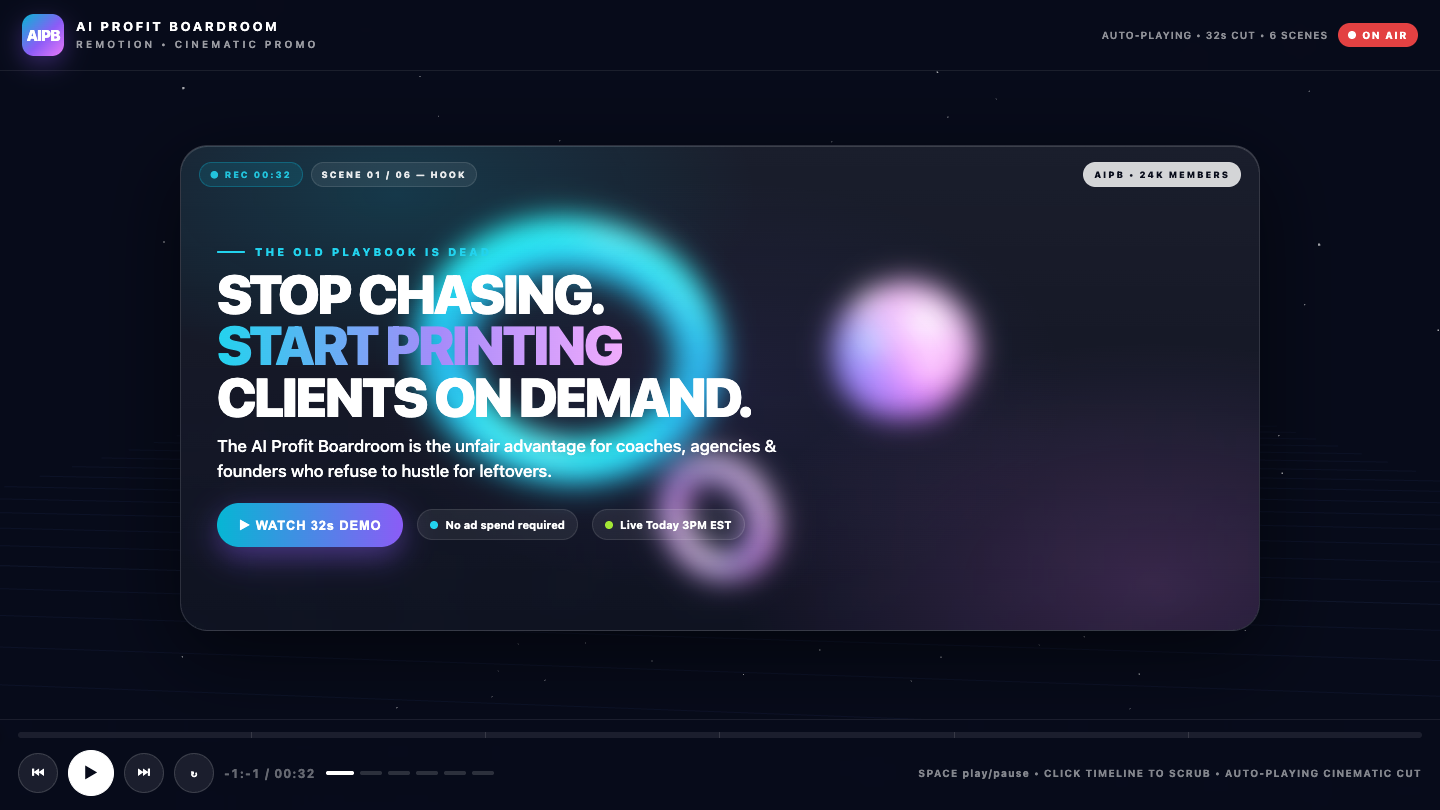
Aipbpromo
Page
Muse Spark 1.2 8.1
·
Hermes MoA 7.0
(+1.1)
What I saw: Strong cinematic hero scene with polished glassmorphic stage, animated glow orbs, video-player chrome (timeline, chapters, transport controls) and clear on-brand copy — very shippable. Minor flaws: the time readout shows a broken '-1:-1 / 00:32' and the top-right hint overlaps in…
Gtadrive
Game
Muse Spark 1.2 8.3
·
Hermes MoA 7.5
(+0.8)
What I saw: Renders a clean 3D open city with player car, traffic, tree props, working minimap with colored blips, and a polished GTA-style HUD (health, wanted stars, cash, speed, controls). Strong and shippable, though buildings look flat/untextured and the fog is aggressive, keeping it jus…
Strengths & weaknesses I logged
Hermes MoA
Strengths
- On GoldieBench, the MoA panel's galaxy edged solo Opus 4.8 — 8.6 vs 8.5 — with a denser 24k-particle spiral (the system beats the model)
- Two gold + one silver across its first three one-shot builds (galaxy, fireworks, arcade)
- Vendor-agnostic — swap any OpenRouter model into a panel or aggregator slot without touching the workflow
Trade-offs
- Latency is the panel's slowest draft plus the aggregator pass — ~110–140s per single-file build vs a solo model's one call
- Costs more per task than any single model (every panel slot + the aggregator are separate calls)
- Only 3 of 42 bench tasks run so far — a representative slice, not the full board
Muse Spark 1.2
Strengths
- Generative art & shader-feel scenes (fractal 8.7, aurora/galaxy/matrix/synthwave 8.6)
- Full app chrome one-shot (macOS-clone desktop 8.6)
- Fast one-shots — most builds landed in 45-80s
- 1M context for whole-repo work
Trade-offs
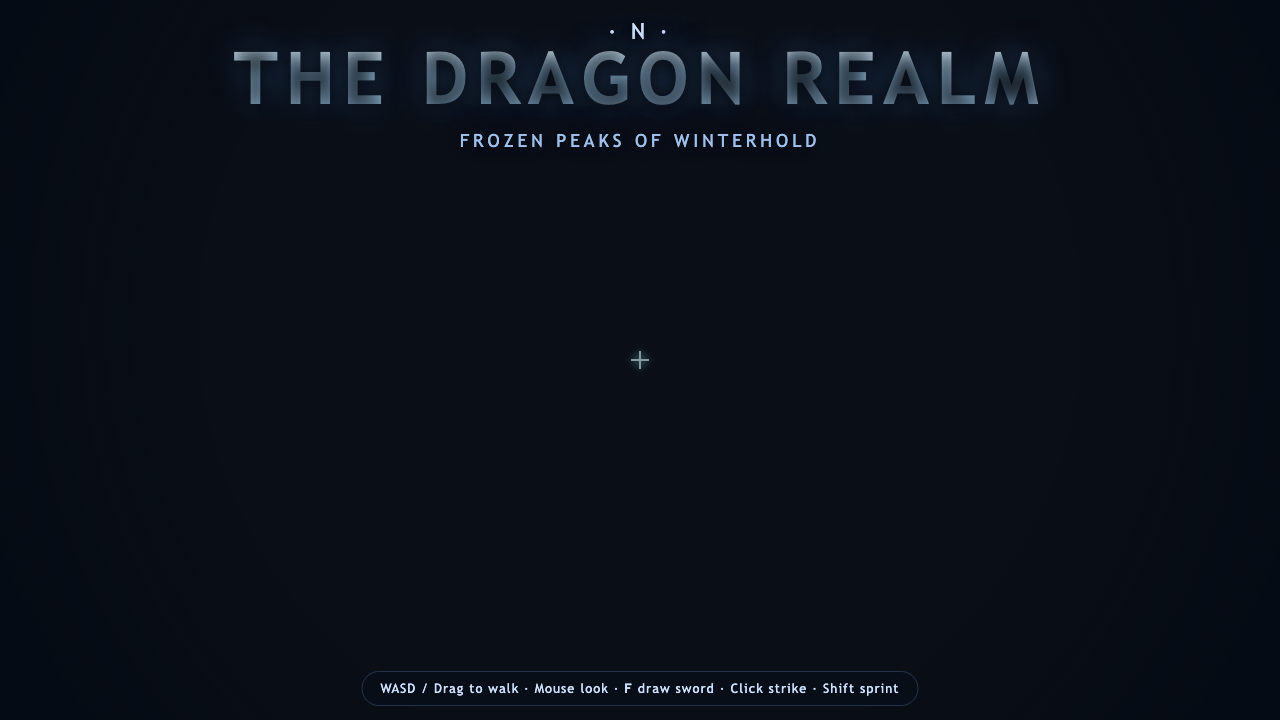
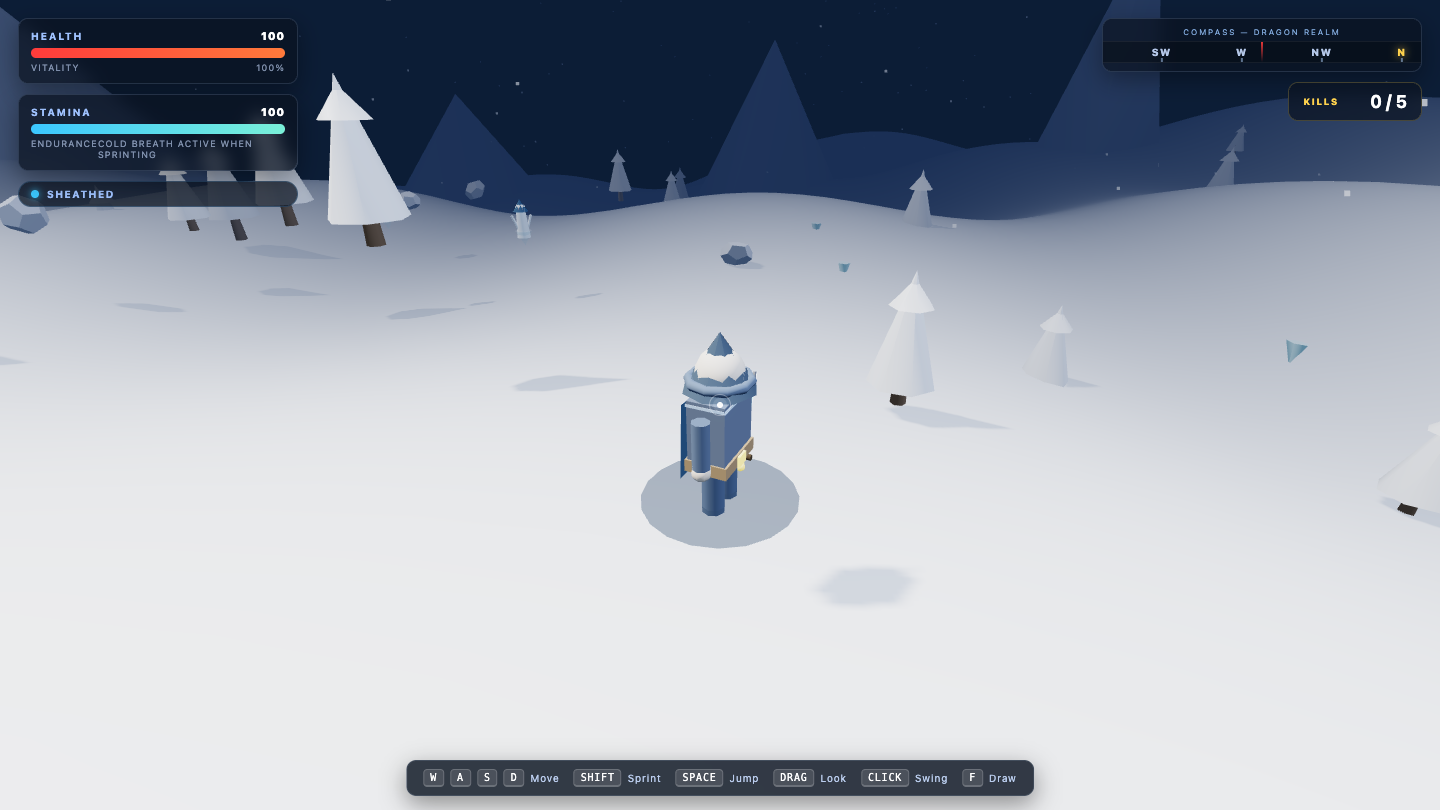
- 3D game worlds often render black/empty (dragonrealm 2.5, dogfight 3.0, doom 3.5)
- Open-world briefs collapse to HUD-only shells
- Reasoning tokens billed as output
Pricing & context — the spec sheet
| Spec | Hermes MoA | Muse Spark 1.2 |
|---|---|---|
| Vendor | Hermes · Mixture of Agents | Meta |
| Context window | Varies — the sum of the panel models' contexts (Opus 4.8 + GPT-5.5) | 1,000,000 tokens |
| Price | Panel + aggregator calls (via OpenRouter) | $1.25 in / $4.25 out per 1M |
| Pricing detail | Hermes Mixture of Agents dispatches one prompt to a configurable panel of frontier models in parallel, then a named aggregator reads every draft and writes one better final answer. Default panel: Claude Opus 4.8 + GPT-5.5, aggregated by Opus 4.8 — all via the OpenRouter key. Unlike a black-box ensemble, every slot is yours to swap from the Mixture tab in the Agent OS. | Meta's coding-optimized reasoning model, released 2026-08-05 beside the Muse Code agent. $0.15/1M cached input. Contributor tier is token-rate-limited in a rolling 5-hour window. Benched release-day via OpenRouter (meta/muse-spark-1.2, first-party listing); Opus 4.8 judged every real rendered poster, same rubric as the whole field. |
| Release | 2026-06-28 | 2026-08-05 |
| Bench coverage | 47/47 scored · avg 8.17/10 | 50/50 scored · avg 7.55/10 |
The verdict — which should you pick?
Across 47 scored shared tasks, Hermes MoA averaged 8.17/10, beating Muse Spark 1.2's 7.58/10 by 0.59 points. Pick Hermes MoA when the build has to ship on the first prompt and you can afford the trade-offs in the comparison below.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire Hermes MoA and Muse Spark 1.2 both into the Agent Operating System and dispatch each from the kanban by task type — high-stakes single prompts where ensemble quality beats single-model speed → Hermes MoA, generative-art visuals → Muse Spark 1.2. That's the same setup I run for the 4,000+ founders inside the AI Profit Boardroom.
FAQ — Hermes MoA vs Muse Spark 1.2
Which is better, Hermes MoA or Muse Spark 1.2?
On Goldie Bench, Hermes MoA averages 8.17/10 across the shared tasks, with 3 gold, 10 silver, 4 bronze overall. Muse Spark 1.2 averages 7.58/10, with 0 gold, 3 silver, 5 bronze. Hermes MoA wins the head-to-head 28–14.
How much does Hermes MoA cost vs Muse Spark 1.2?
Hermes MoA: Hermes Mixture of Agents dispatches one prompt to a configurable panel of frontier models in parallel, then a named aggregator reads every draft and writes one better final answer. Default panel: Claude Opus 4.8 + GPT-5.5, aggregated by Opus 4.8 — all via the OpenRouter key. Unlike a black-box ensemble, every slot is yours to swap from the Mixture tab in the Agent OS. Muse Spark 1.2: Meta's coding-optimized reasoning model, released 2026-08-05 beside the Muse Code agent. $0.15/1M cached input. Contributor tier is token-rate-limited in a rolling 5-hour window. Benched release-day via OpenRouter (meta/muse-spark-1.2, first-party listing); Opus 4.8 judged every real rendered poster, same rubric as the whole field.
What's the context window for Hermes MoA vs Muse Spark 1.2?
Hermes MoA has a Varies — the sum of the panel models' contexts (Opus 4.8 + GPT-5.5) context window. Muse Spark 1.2 has a 1,000,000 tokens context window.
When should I pick Hermes MoA over Muse Spark 1.2?
Pick Hermes MoA for: High-stakes single prompts where ensemble quality beats single-model speed; Squeezing frontier-plus output from models you already have while Fable 5 / GPT-5.6 are still in preview; Production agents that want a configurable panel + vendor-redundancy on every call. The trade-off is the weaknesses we logged on the bench: Latency is the panel's slowest draft plus the aggregator pass — ~110–140s per single-file build vs a solo model's one call; Costs more per task than any single model (every panel slot + the aggregator are separate calls); Only 3 of 42 bench tasks run so far — a representative slice, not the full board.
When should I pick Muse Spark 1.2 over Hermes MoA?
Pick Muse Spark 1.2 for: Generative-art visuals; Dashboard & app-shell one-shots; Long-context refactors (1M window). The trade-off is the weaknesses we logged on the bench: 3D game worlds often render black/empty (dragonrealm 2.5, dogfight 3.0, doom 3.5); Open-world briefs collapse to HUD-only shells; Reasoning tokens billed as output.
How does Goldie Bench score Hermes MoA vs Muse Spark 1.2?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
Hermes MoA vs Fusion Muse Spark 1.2 vs Fusion Hermes MoA vs Claude Opus 5 Muse Spark 1.2 vs Claude Opus 5 Hermes MoA vs GPT-5.6 Sol Muse Spark 1.2 vs GPT-5.6 Sol Hermes MoA vs Claude Fable 5 Muse Spark 1.2 vs Claude Fable 5Full model pages: Hermes MoA · Muse Spark 1.2 · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.
4,000+founders
258documented wins
38countries
$59/momonthly