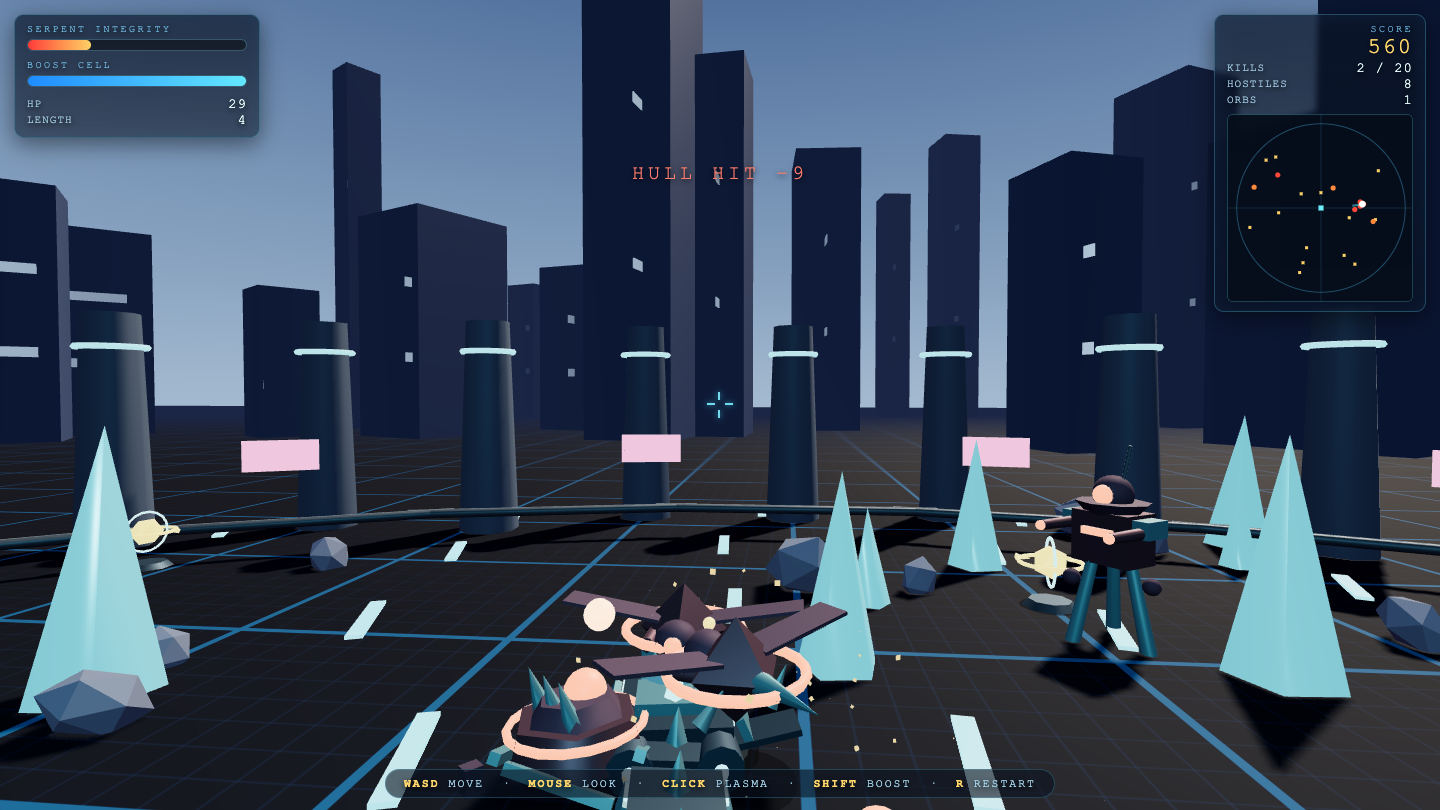
Real head-to-head · same prompt, one shot
Claude Opus 5 vs Claude Opus 5.5
The new Anthropic flagship — benched on all 45 one-shot builds the day it landed. vs Anthropic's Opus 5.5 — benched on all 50 one-shot builds, every game playtested.
Head-to-head verdict: Claude Opus 5 wins 43–5 with 2 ties.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to Claude Opus 5 and Claude Opus 5.5, side by side, on 50 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
Claude Opus 5 · Benched on all 45 GoldieBench tasks via API on release day, incremental deploys as scores landed.
Claude Opus 5.5 · Benched on all 50 GoldieBench tasks via a Claude subscription: one-shot builds, real renders, pixel-diff playtests on every game, then vision-judged.
Side-by-side on 50 shared tasks
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
Claude Opus 5
Claude Opus 5.5
Game
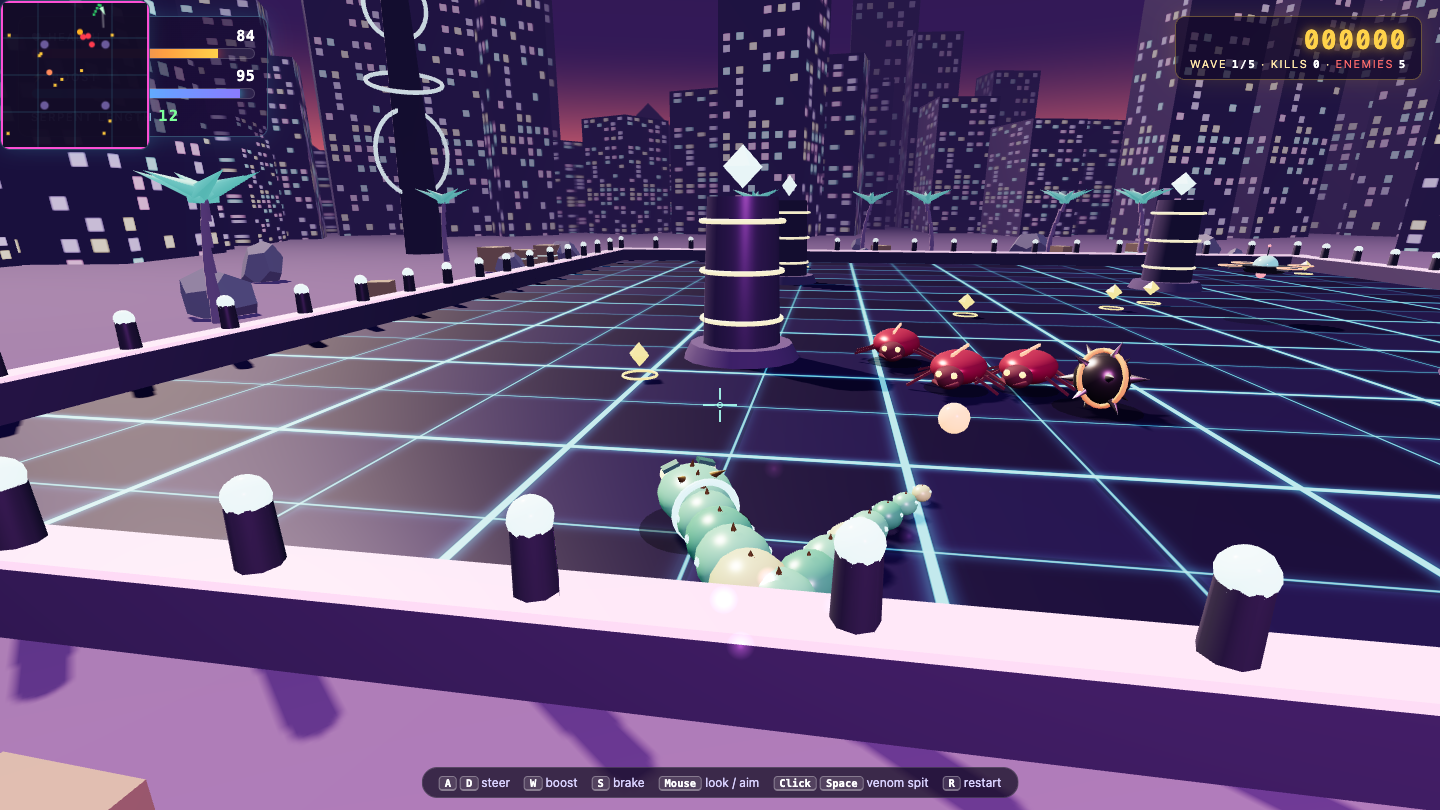
Game
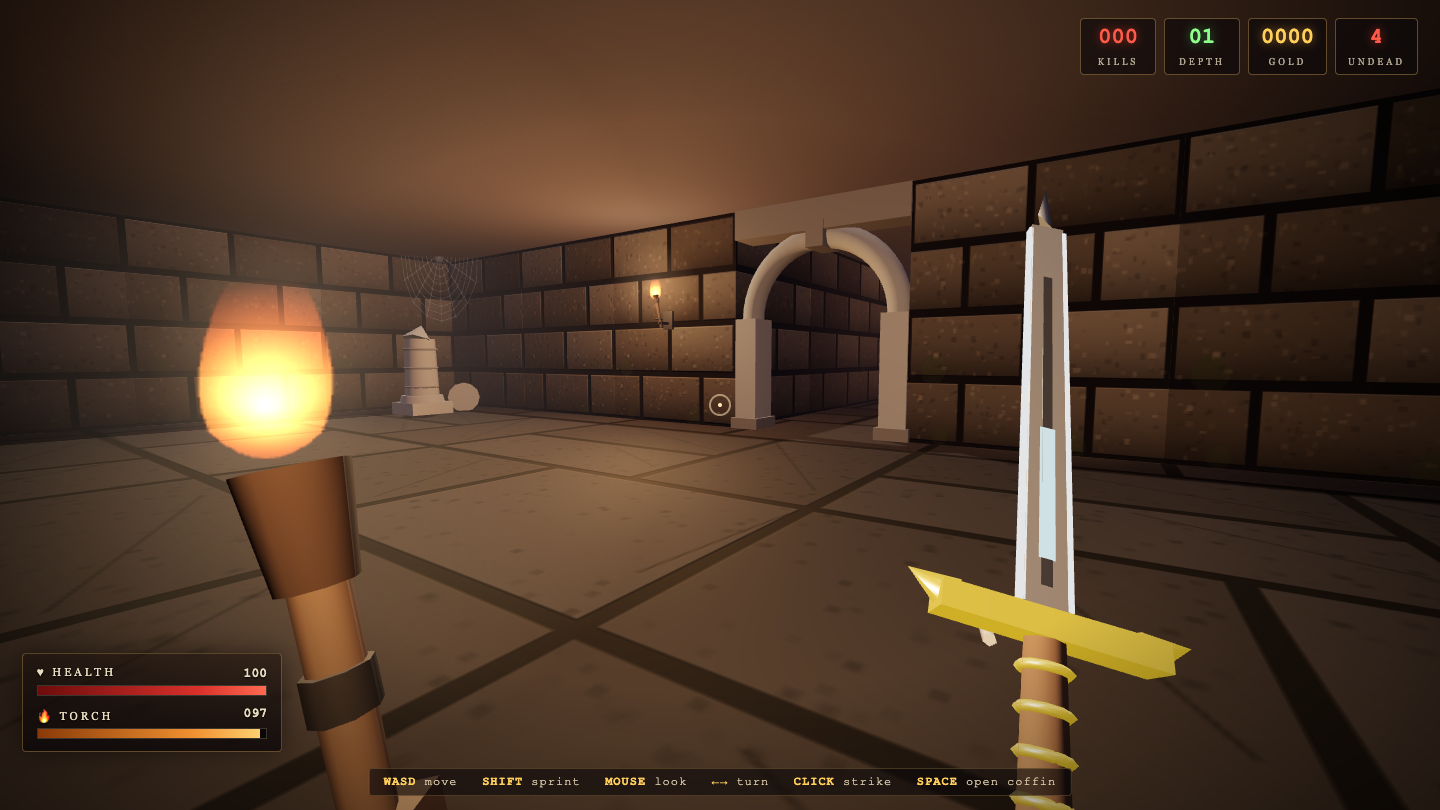
Game
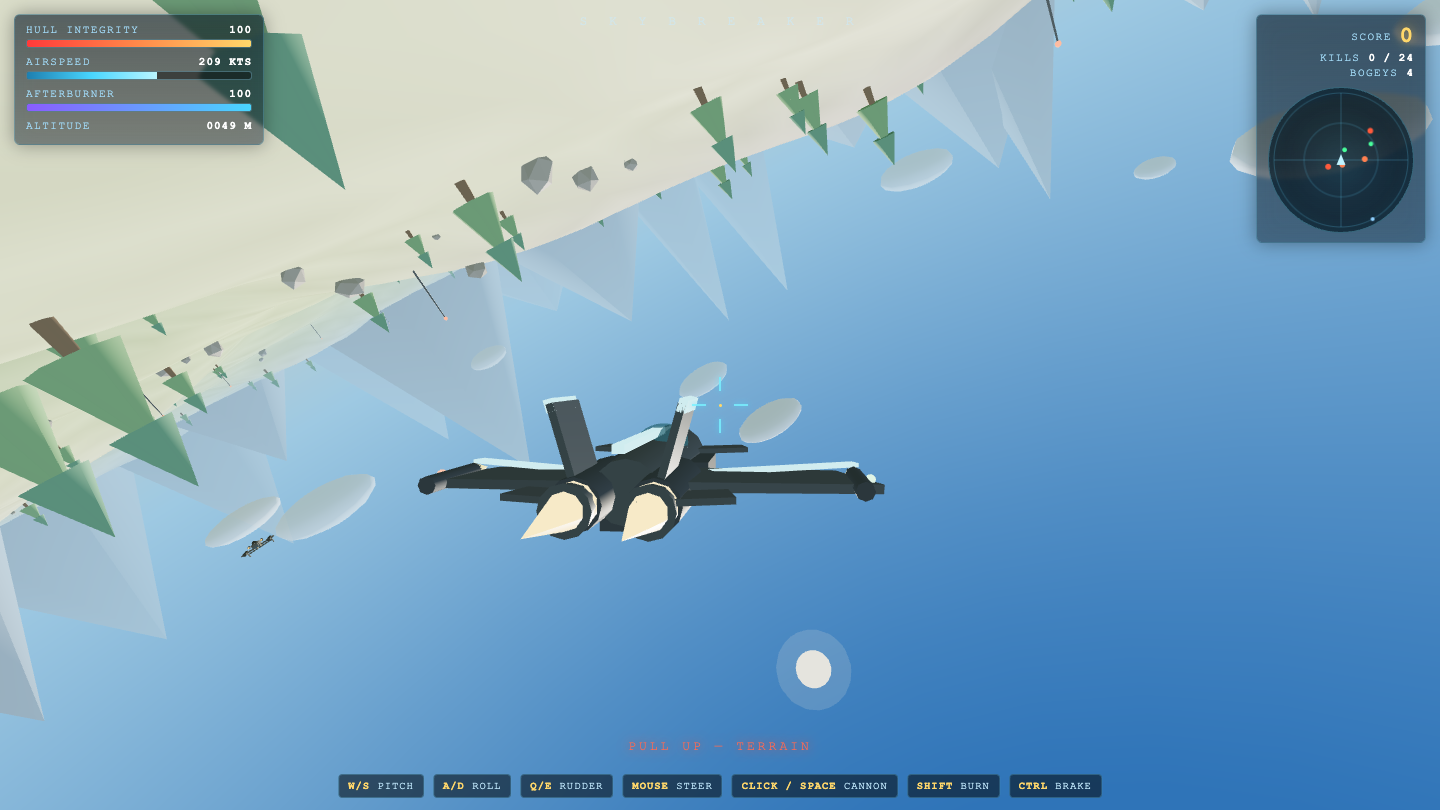
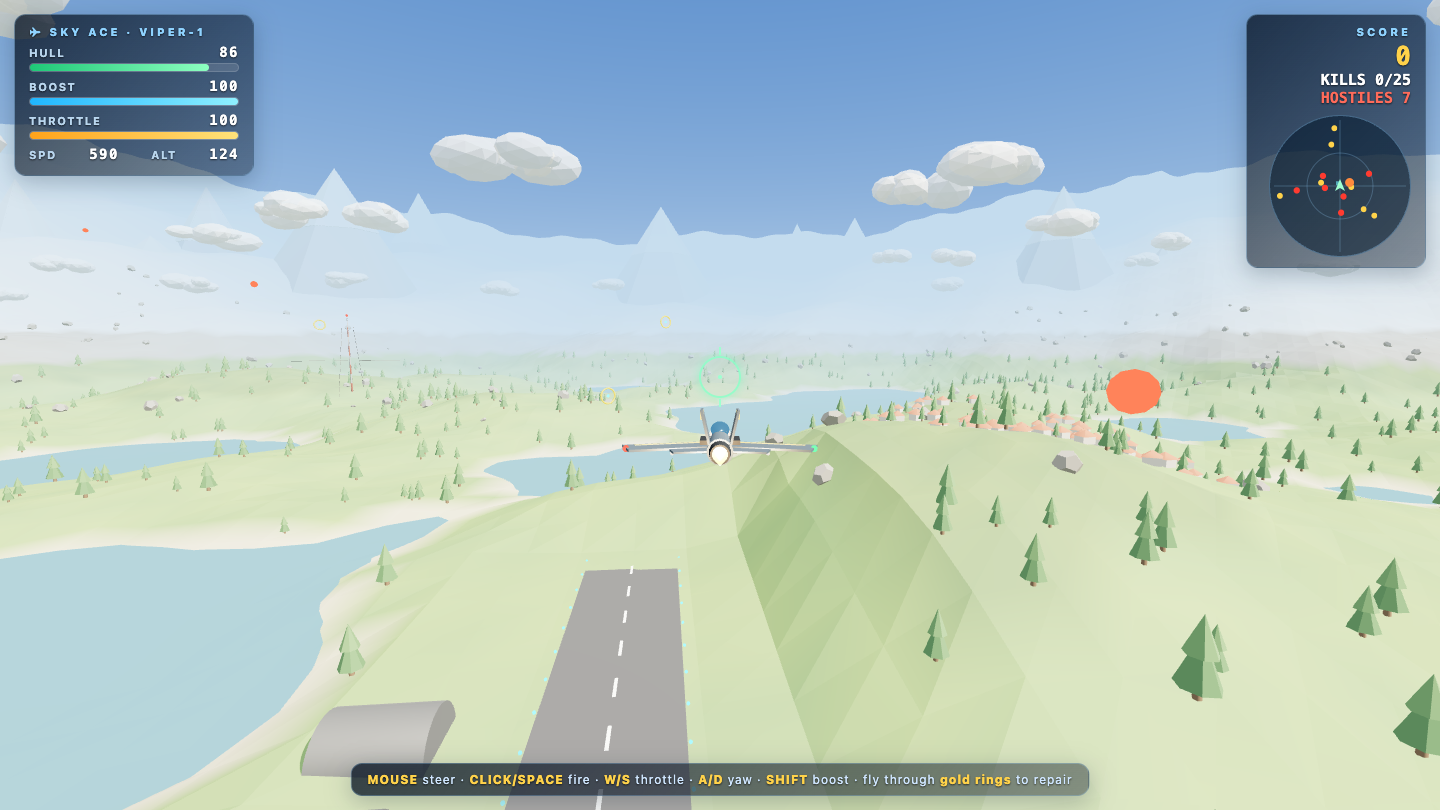
Game
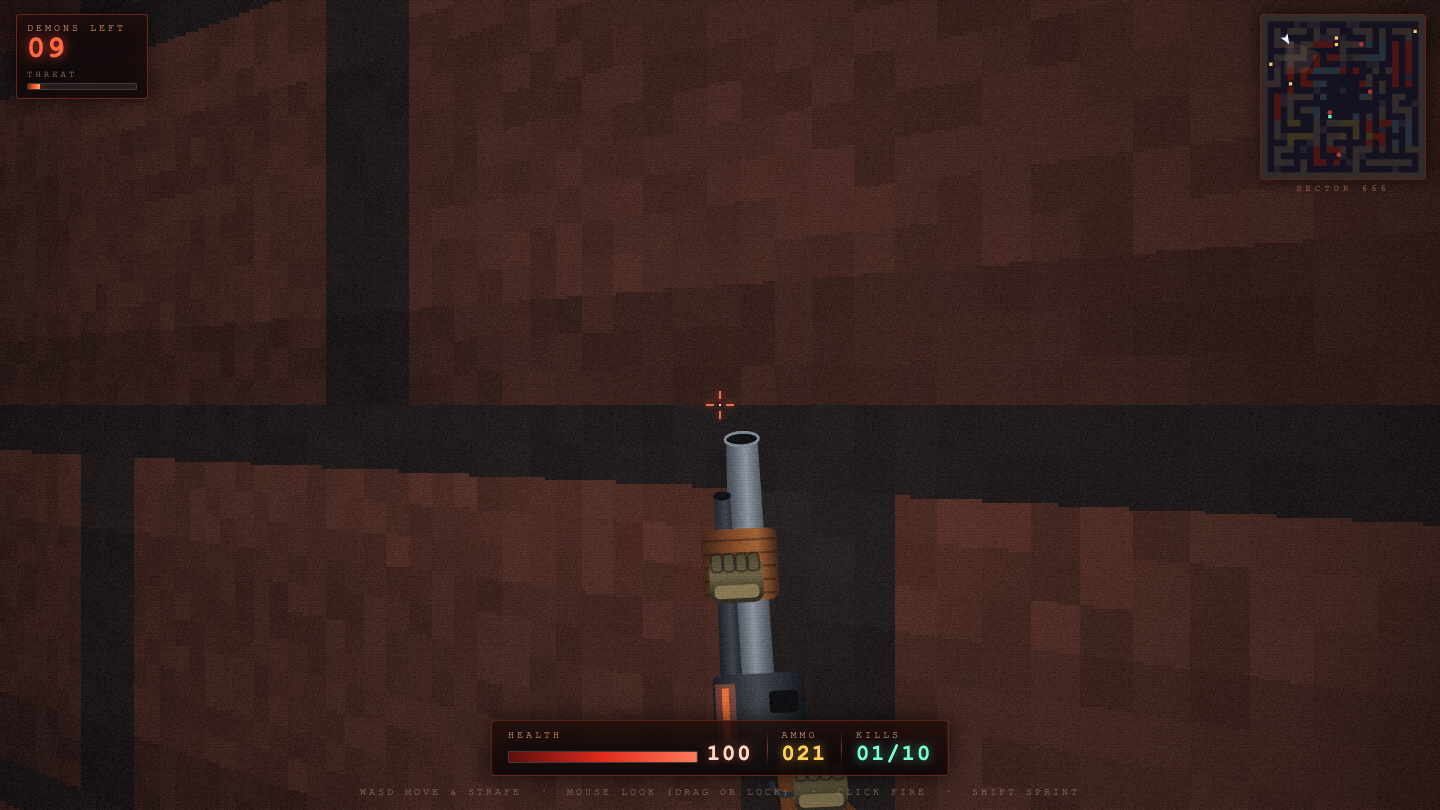
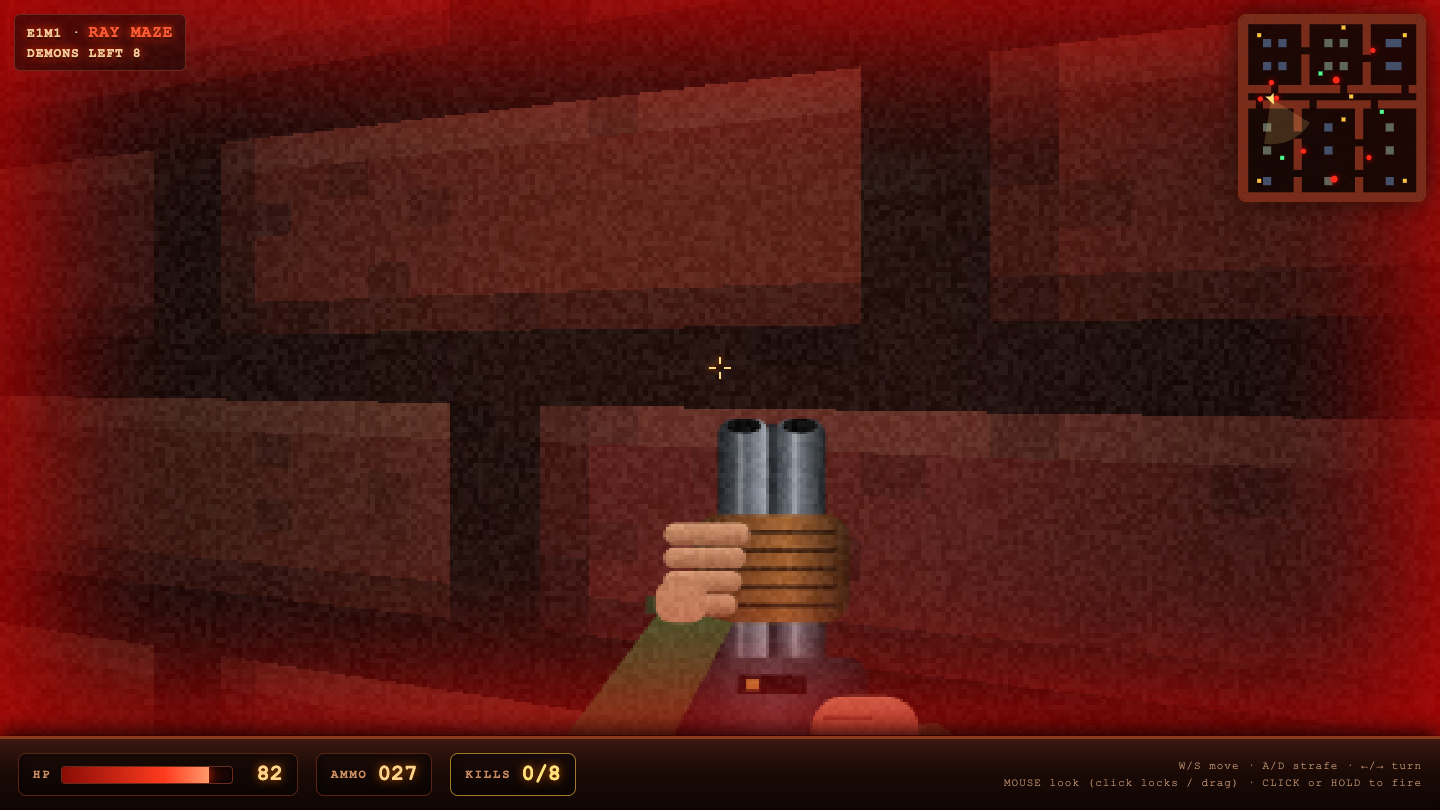
Game
Game
Game
Game
Game
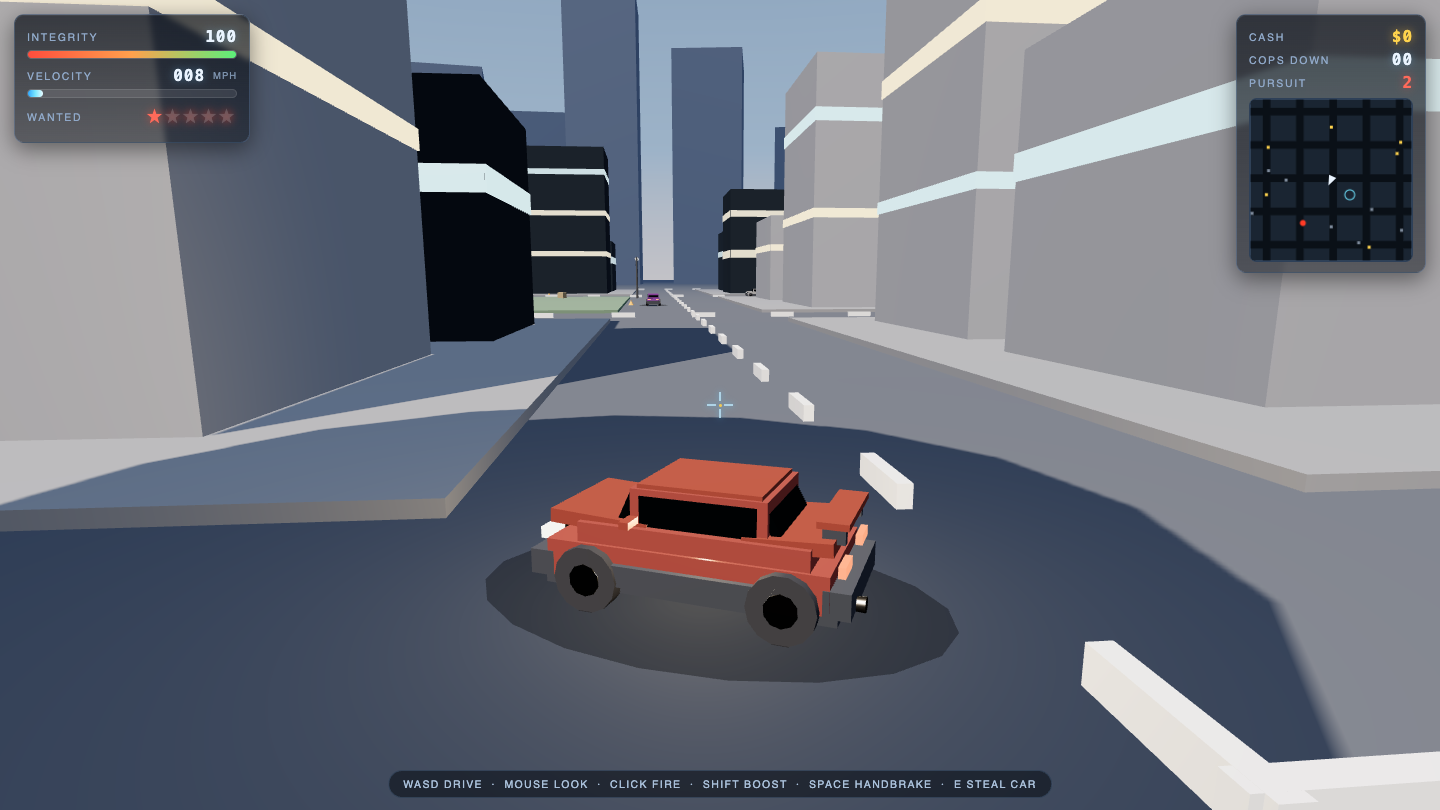
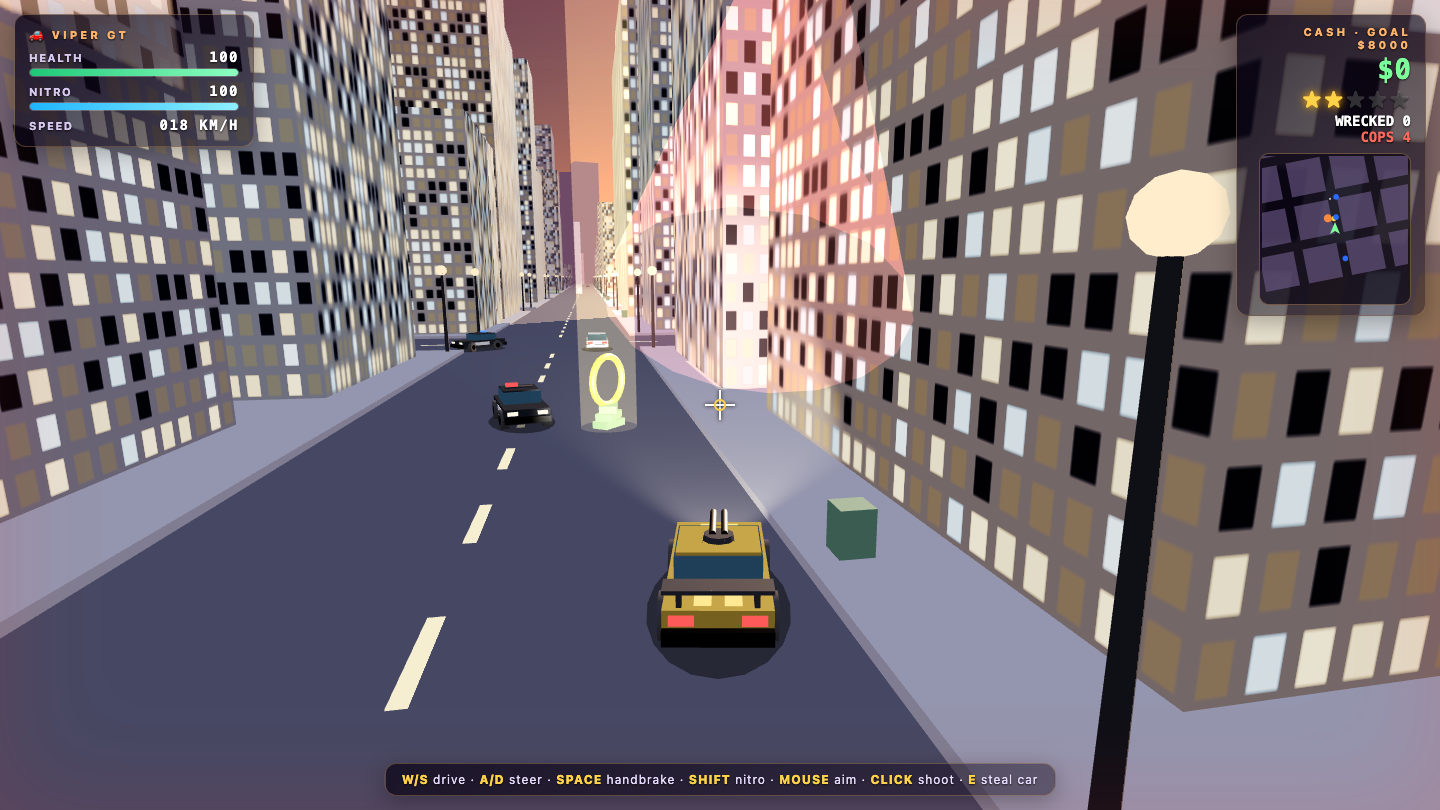
Game
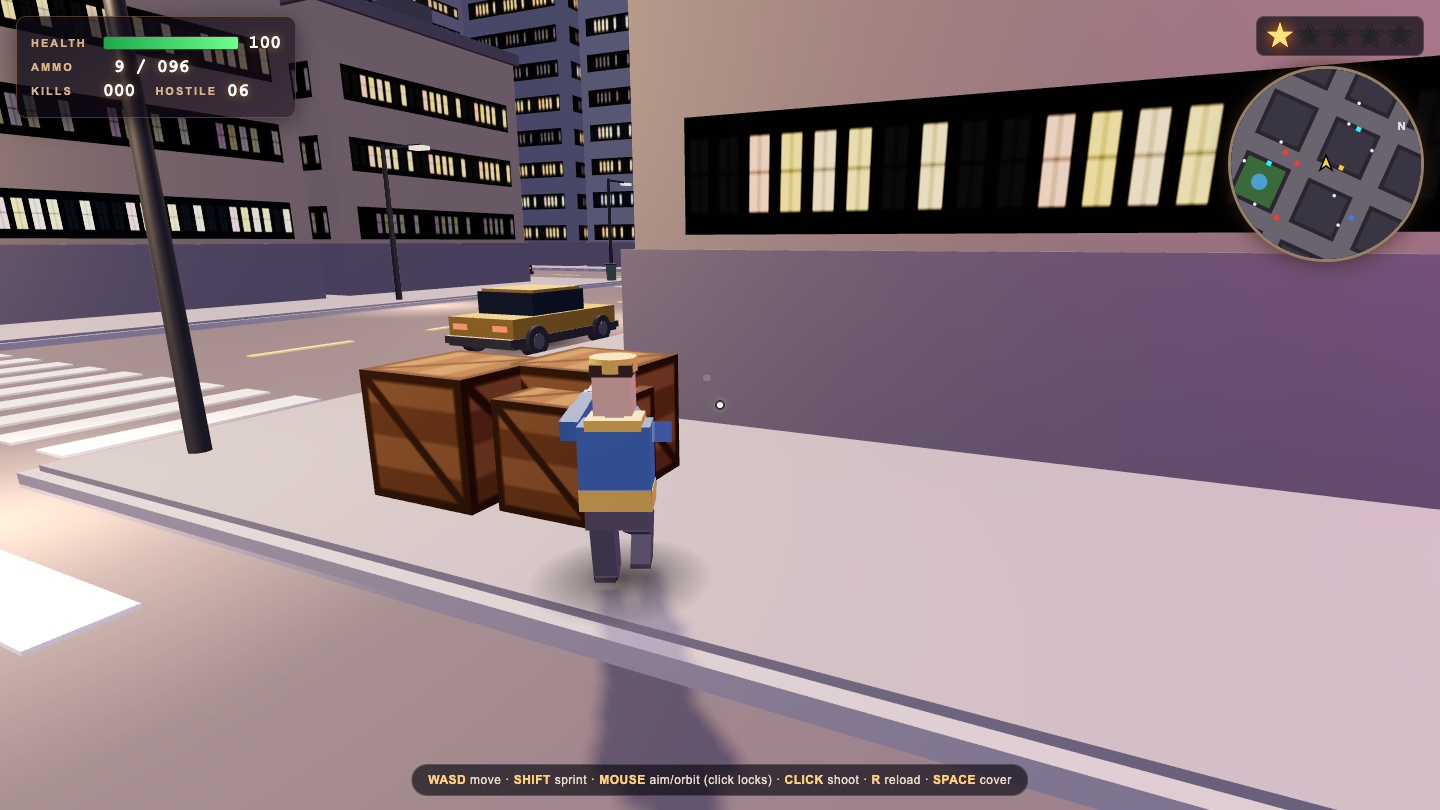
Game
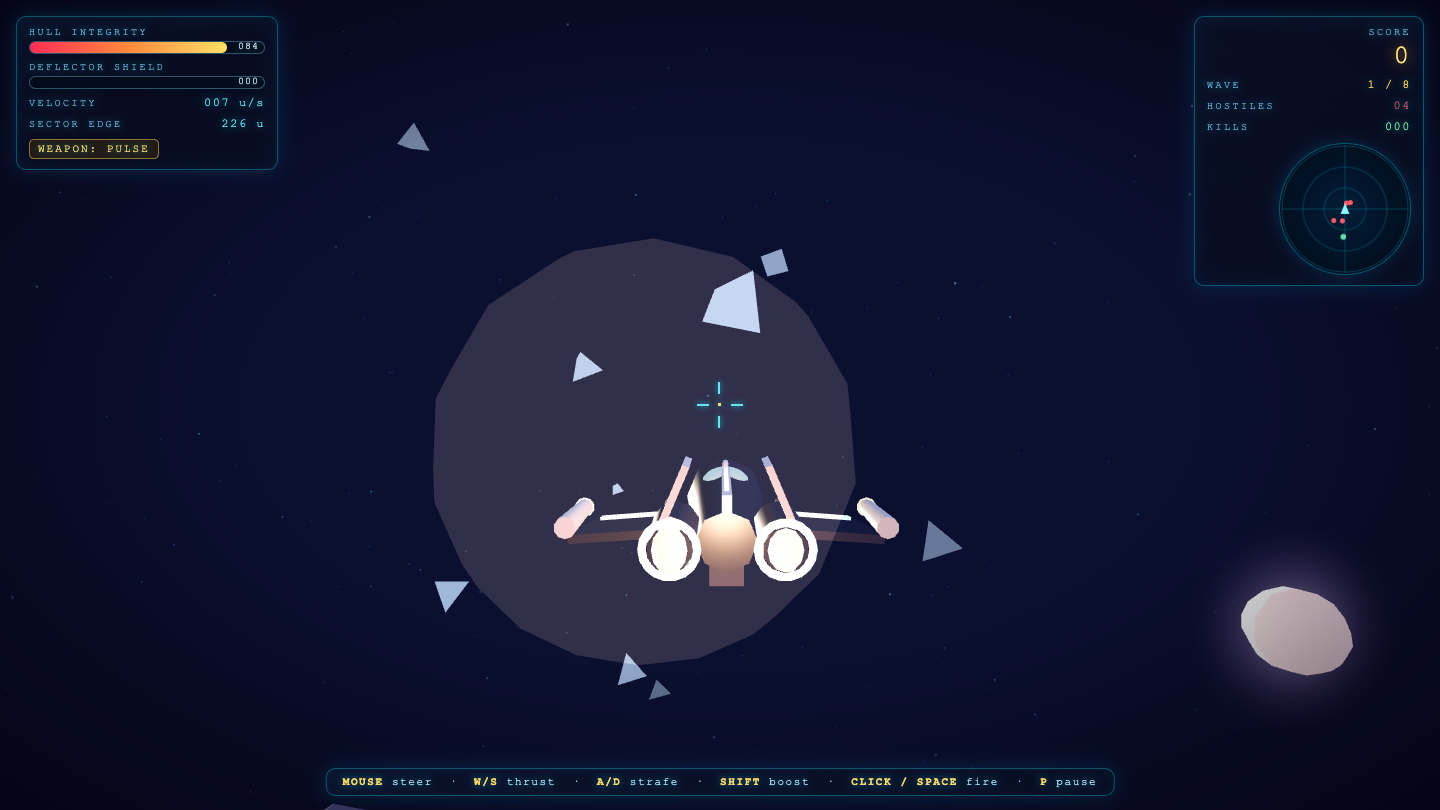
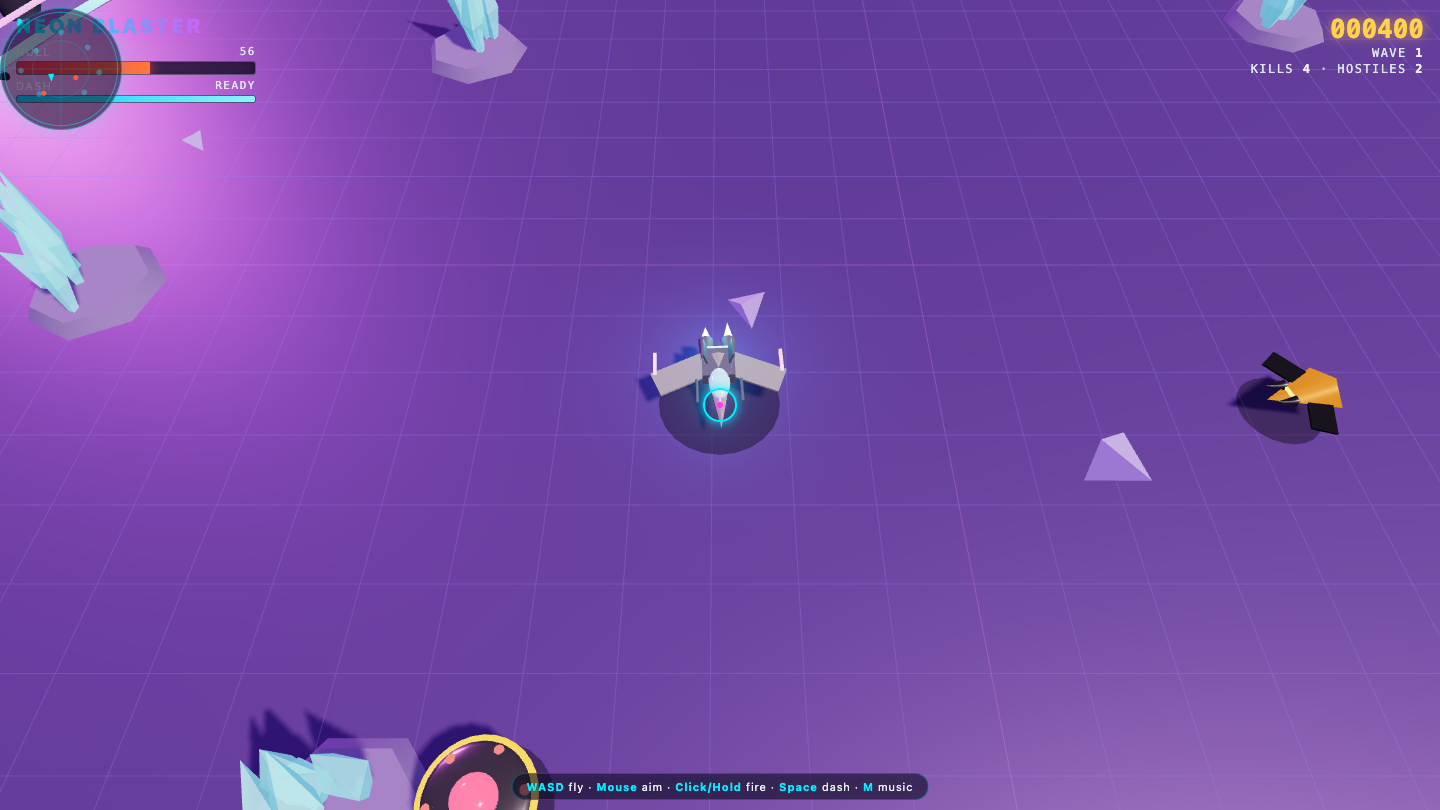
Game
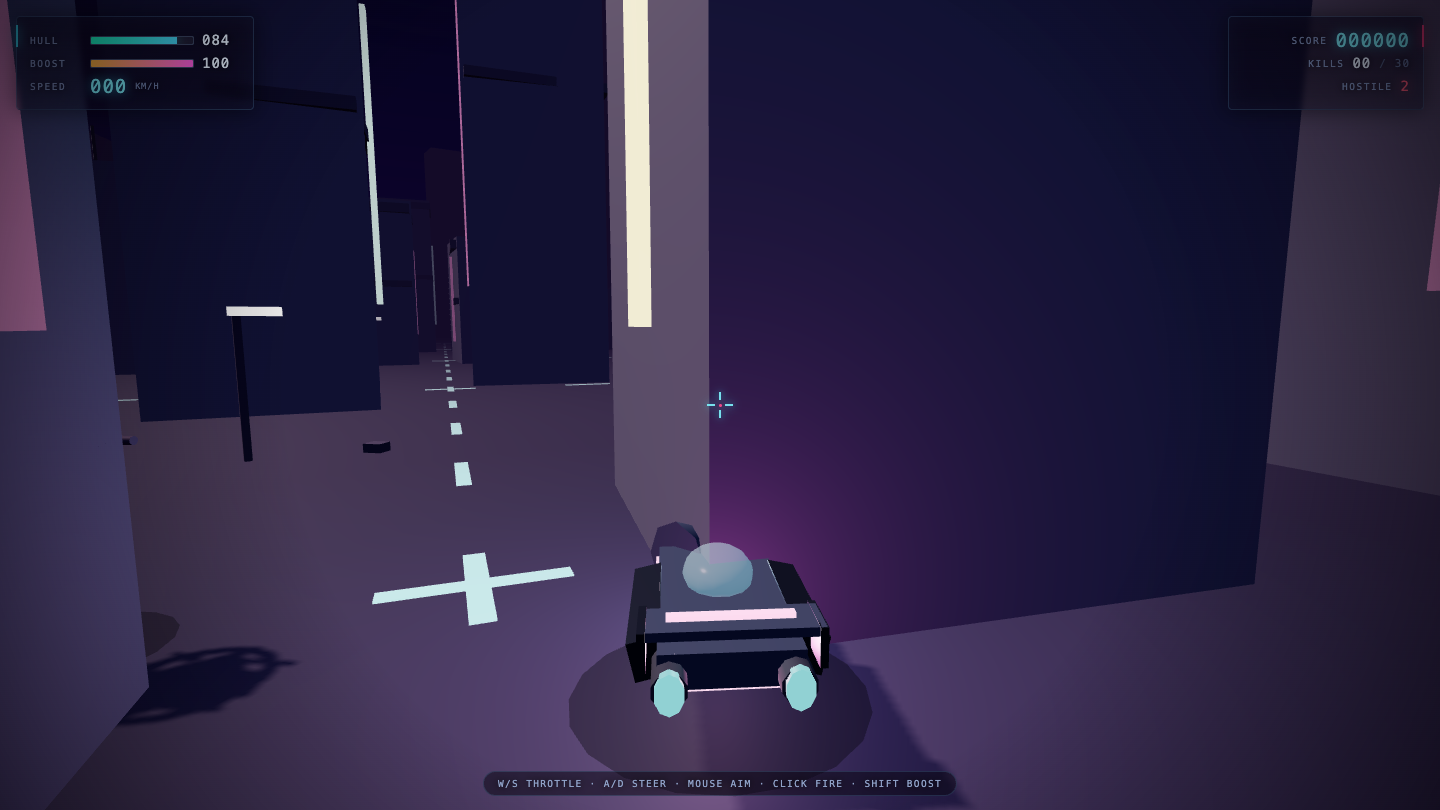
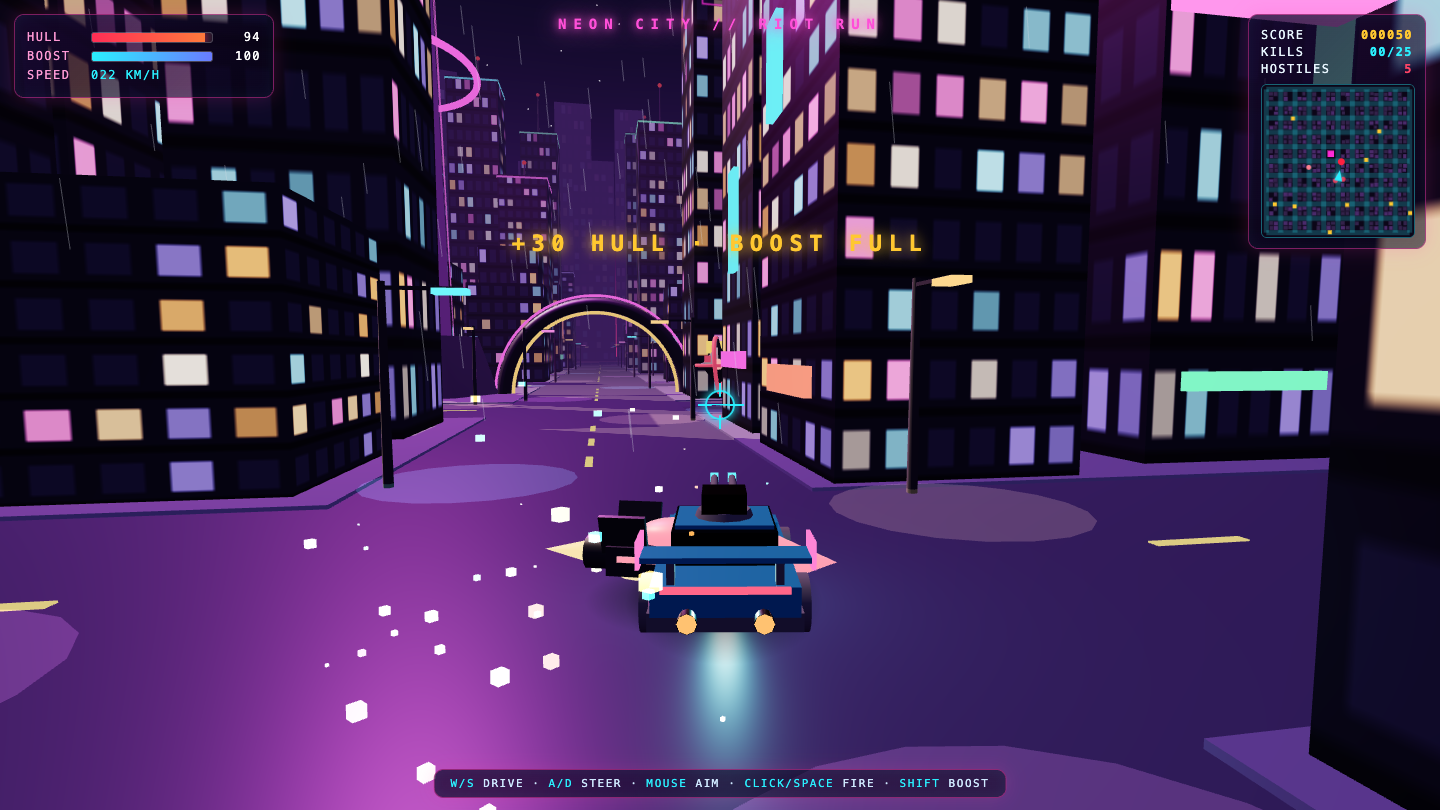
Game
Game
Game
Game
Game
Game
Game
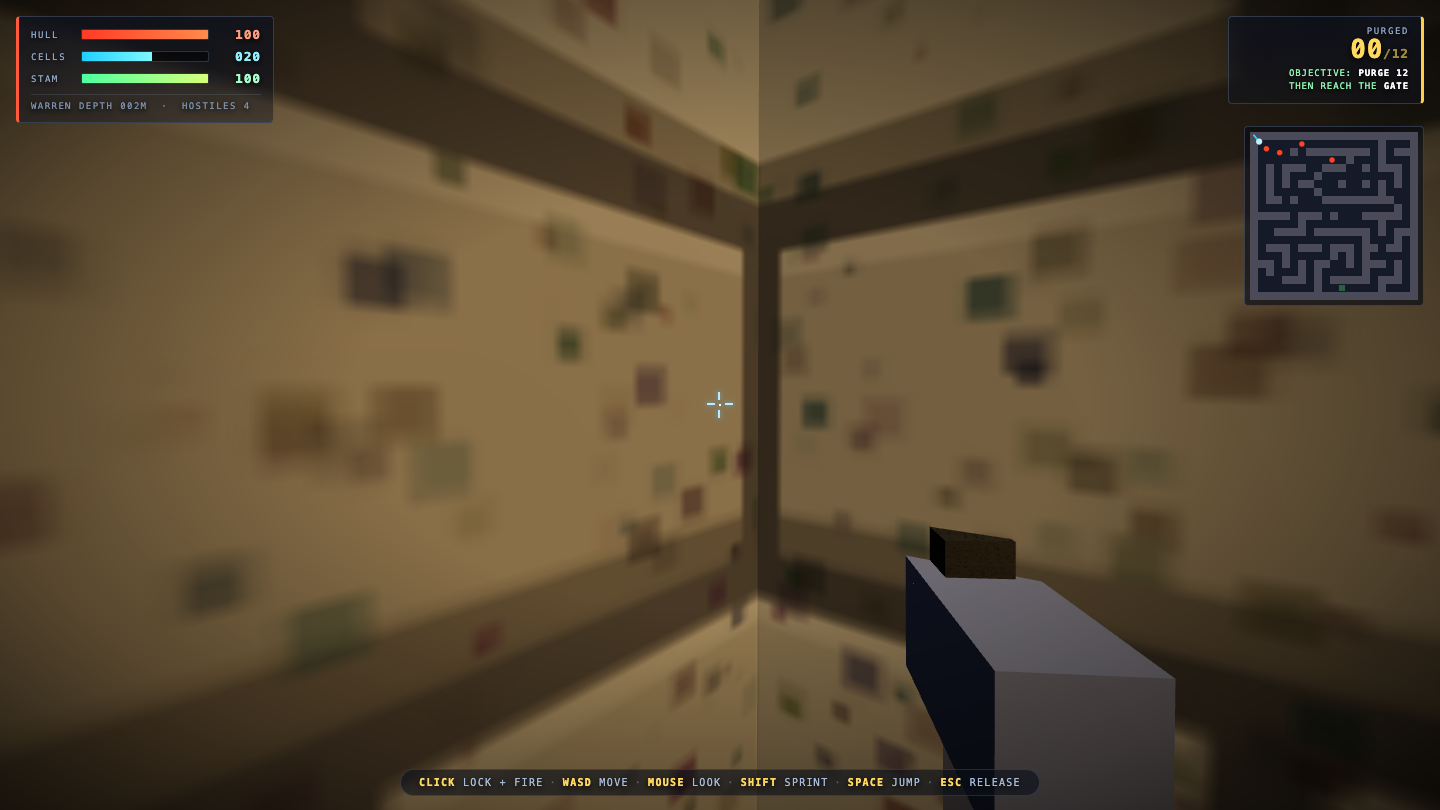
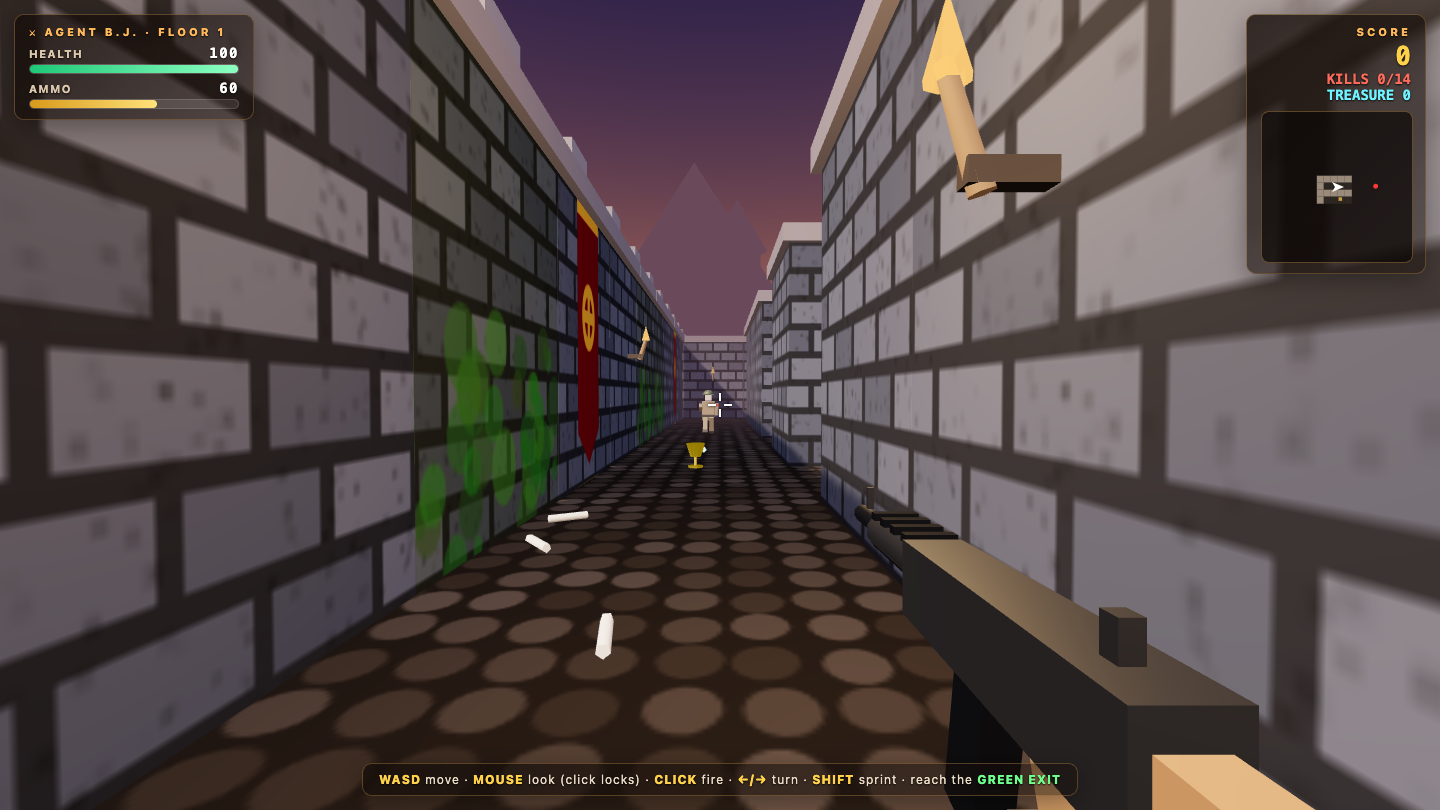
Game
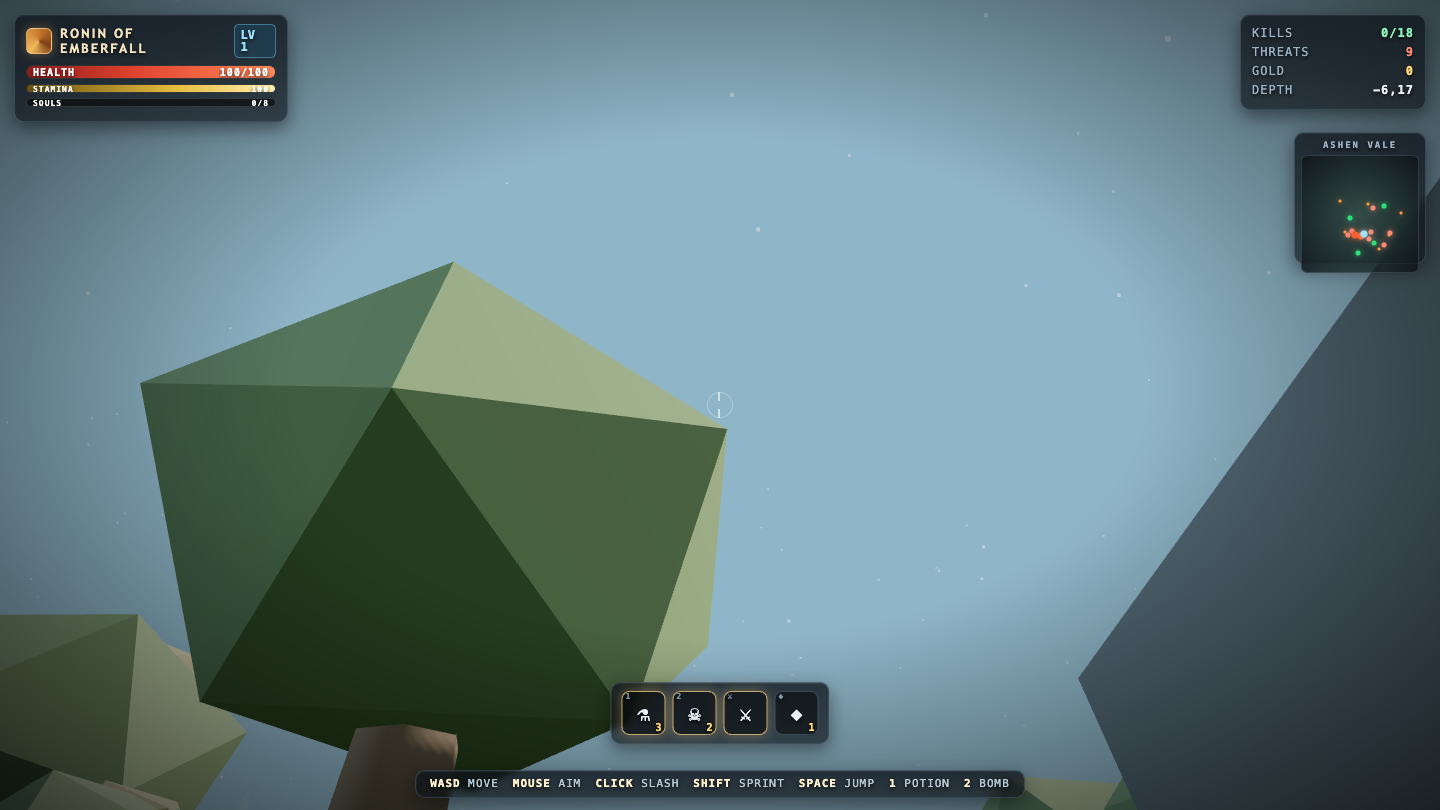
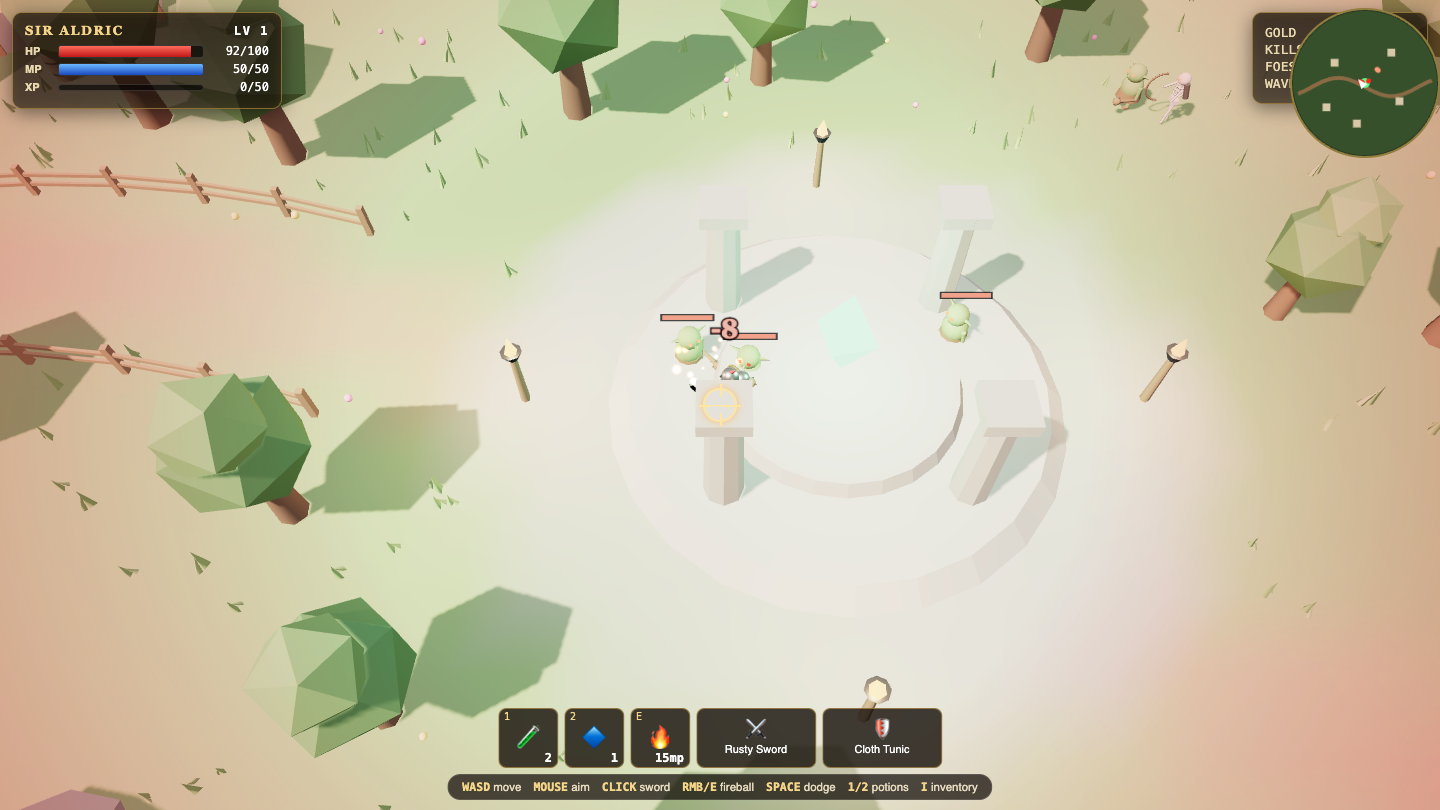
Game
Game
Game
Other
Where Claude Opus 5 beat Claude Opus 5.5
The tasks where I gave Claude Opus 5 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Rpg
Game
Claude Opus 5 8.7
·
Claude Opus 5.5 5.5
(+3.2)
· Polished 3D RPG
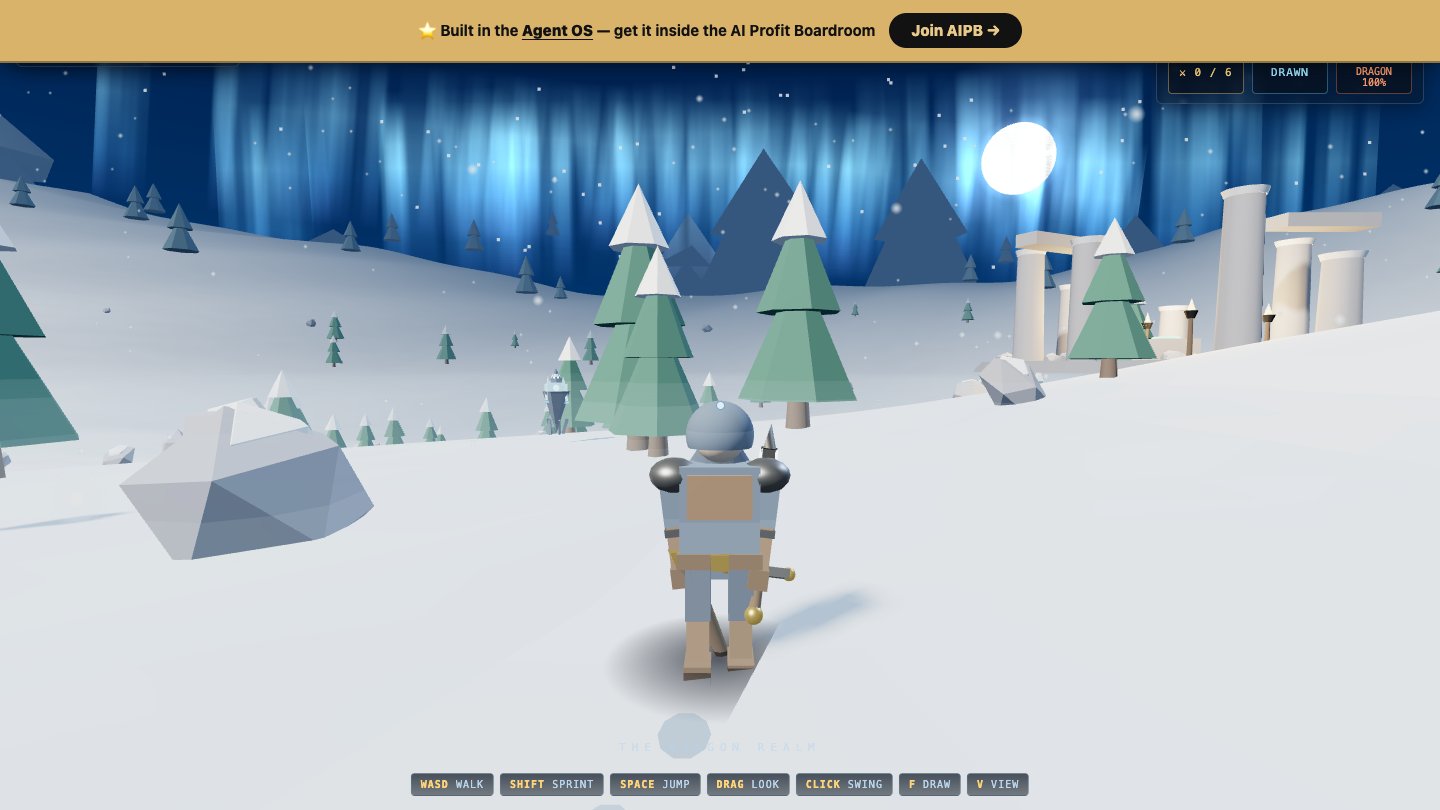
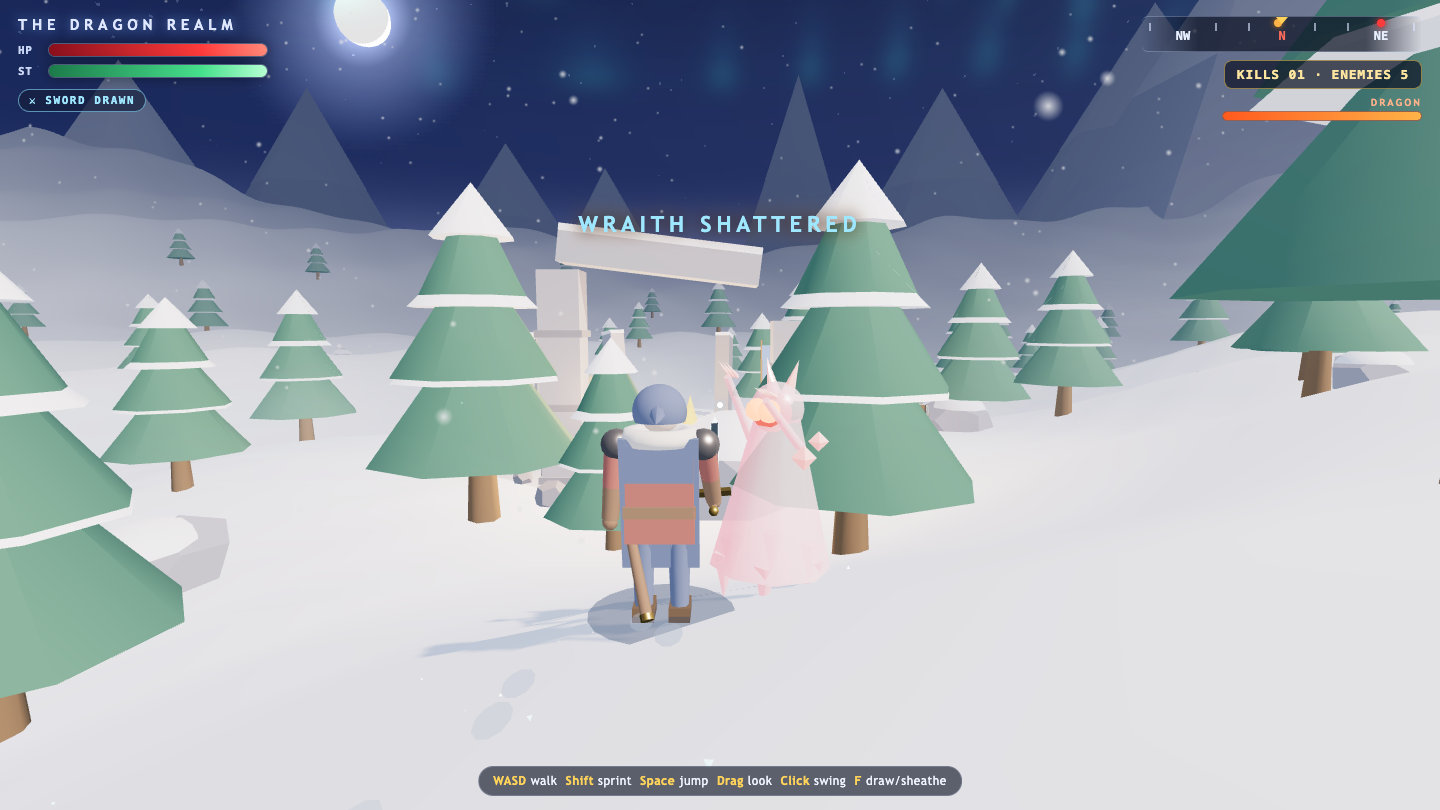
What I saw: Strong: gorgeous low-poly 3D world with a real armored player, visible sword-wielding enemies, full HUD (HP/stamina/souls, kills/threats/gold), inventory hotbar and functional minimap all rendering cleanly. Weak: it's more third-person action-RPG than classic top-down sprite RPG,…
Voxelcraft
Game
Claude Opus 5 8.4
·
Claude Opus 5.5 5.8
(+2.6)
· polished voxel sandbox
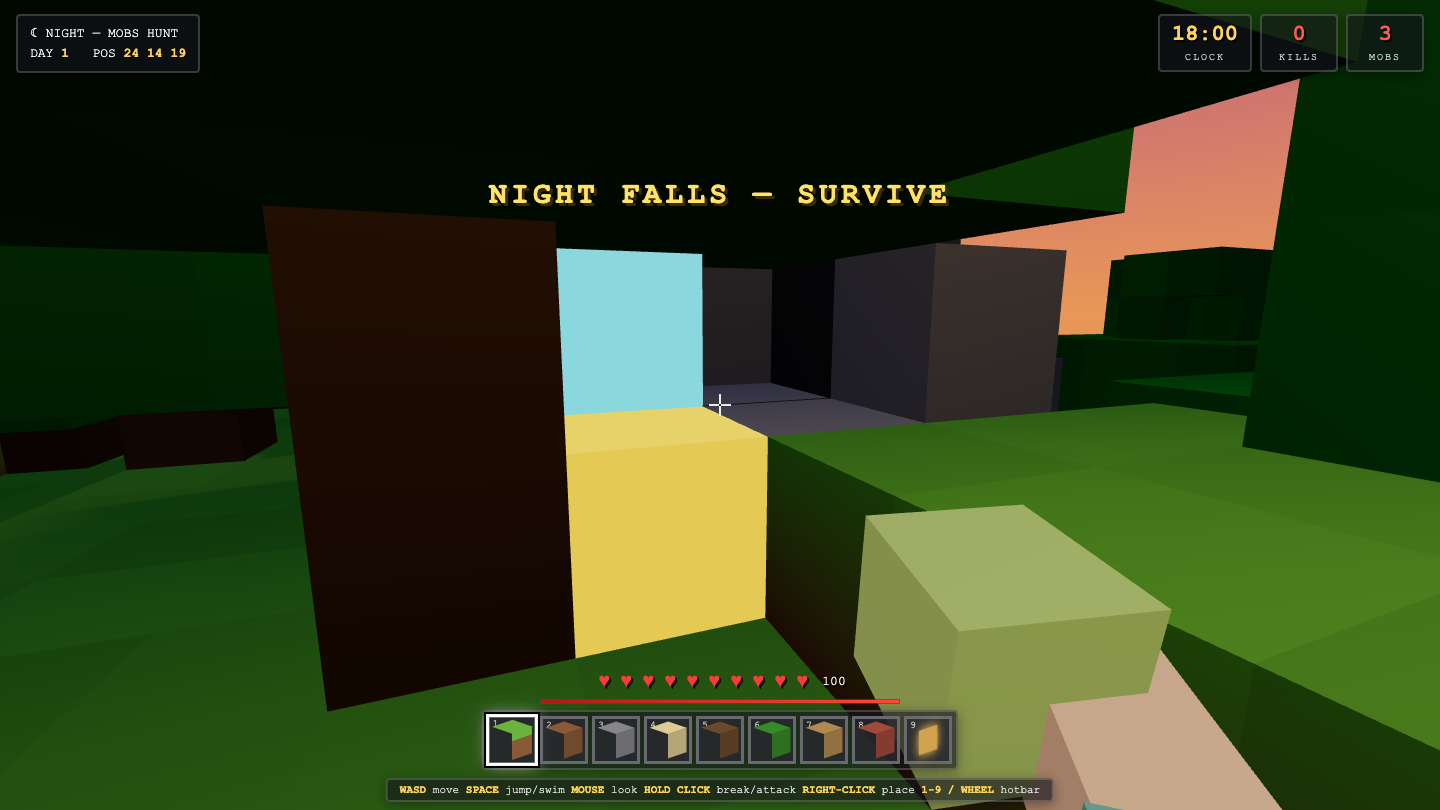
What I saw: Strong terrain generation with varied blocks, trees, and a genuine day/night cycle (screenshot shows night phase with dimmed lighting and 3 active mobs), plus a clean HUD, hotbar, and place/break/combat mechanics. Loses a hair for the visually murky dark-block artifact center-fra…
Dragonflight
Game
Claude Opus 5 8.2
·
Claude Opus 5.5 6.0
(+2.2)
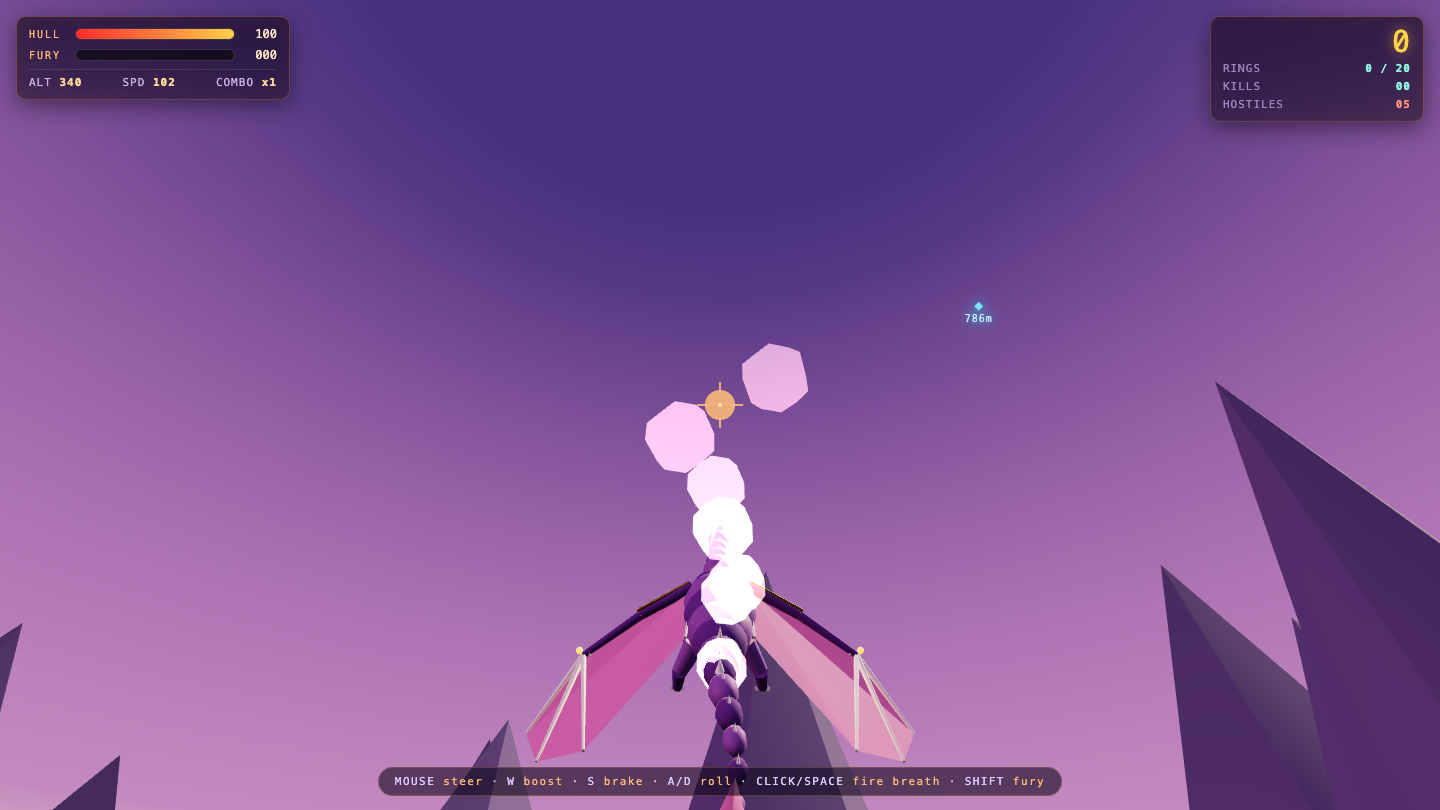
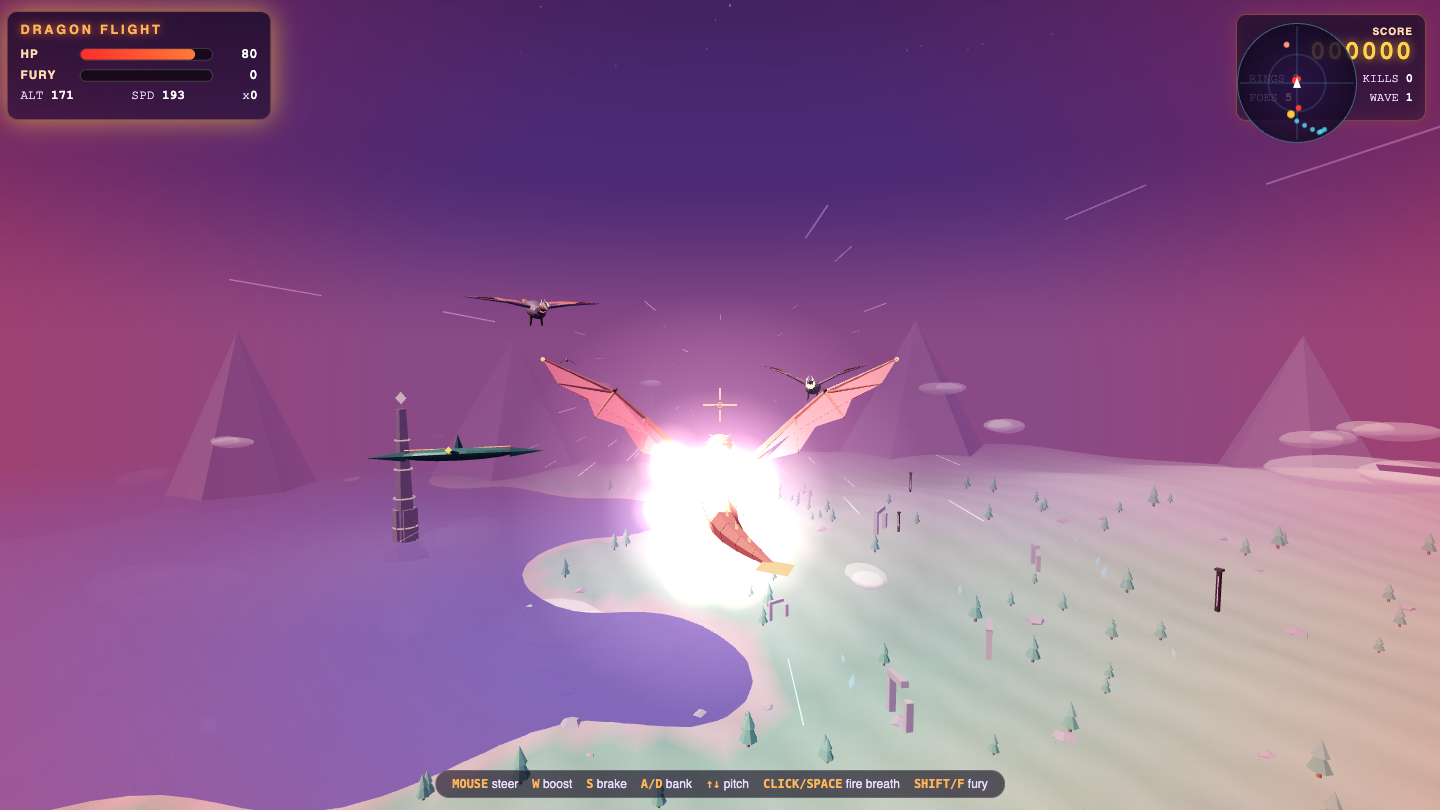
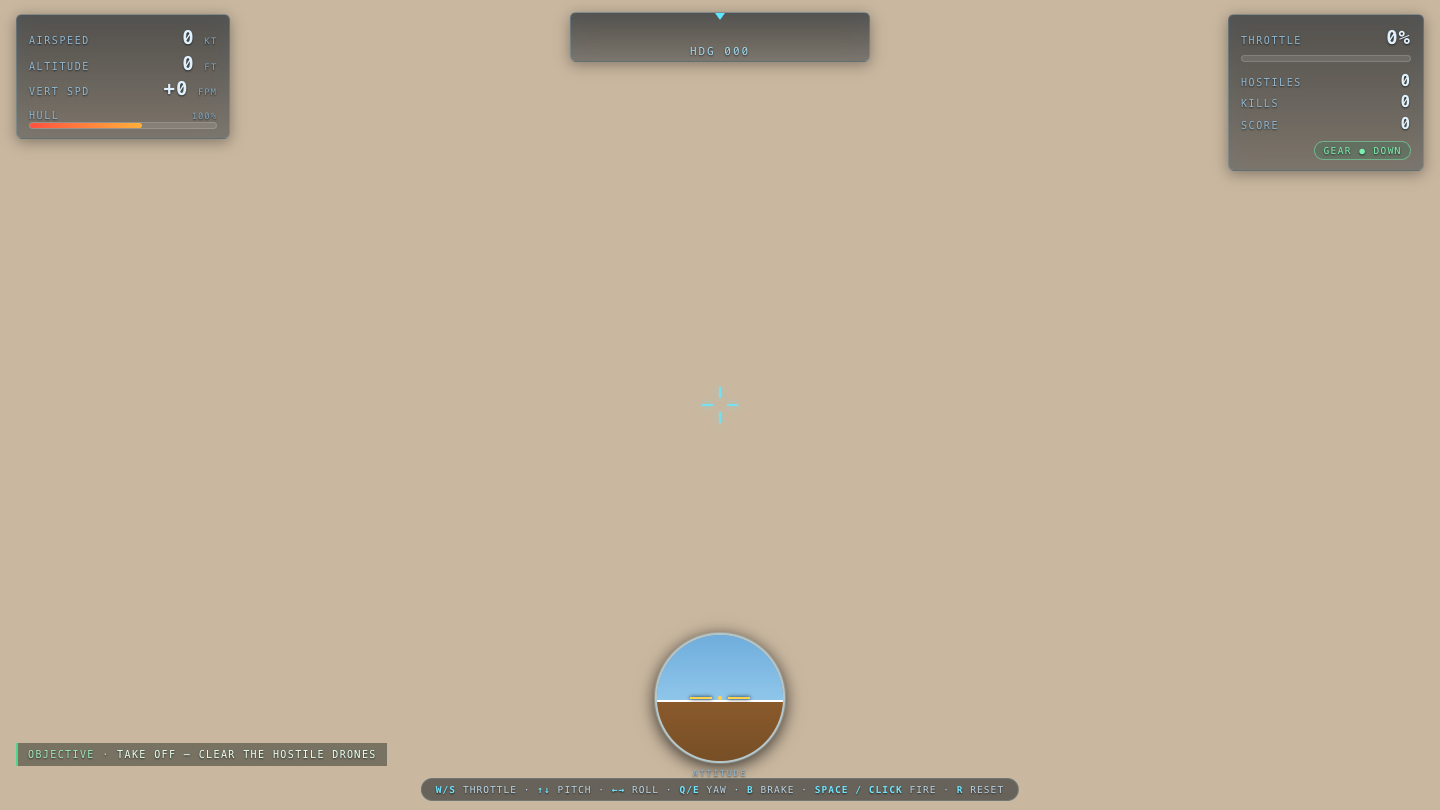
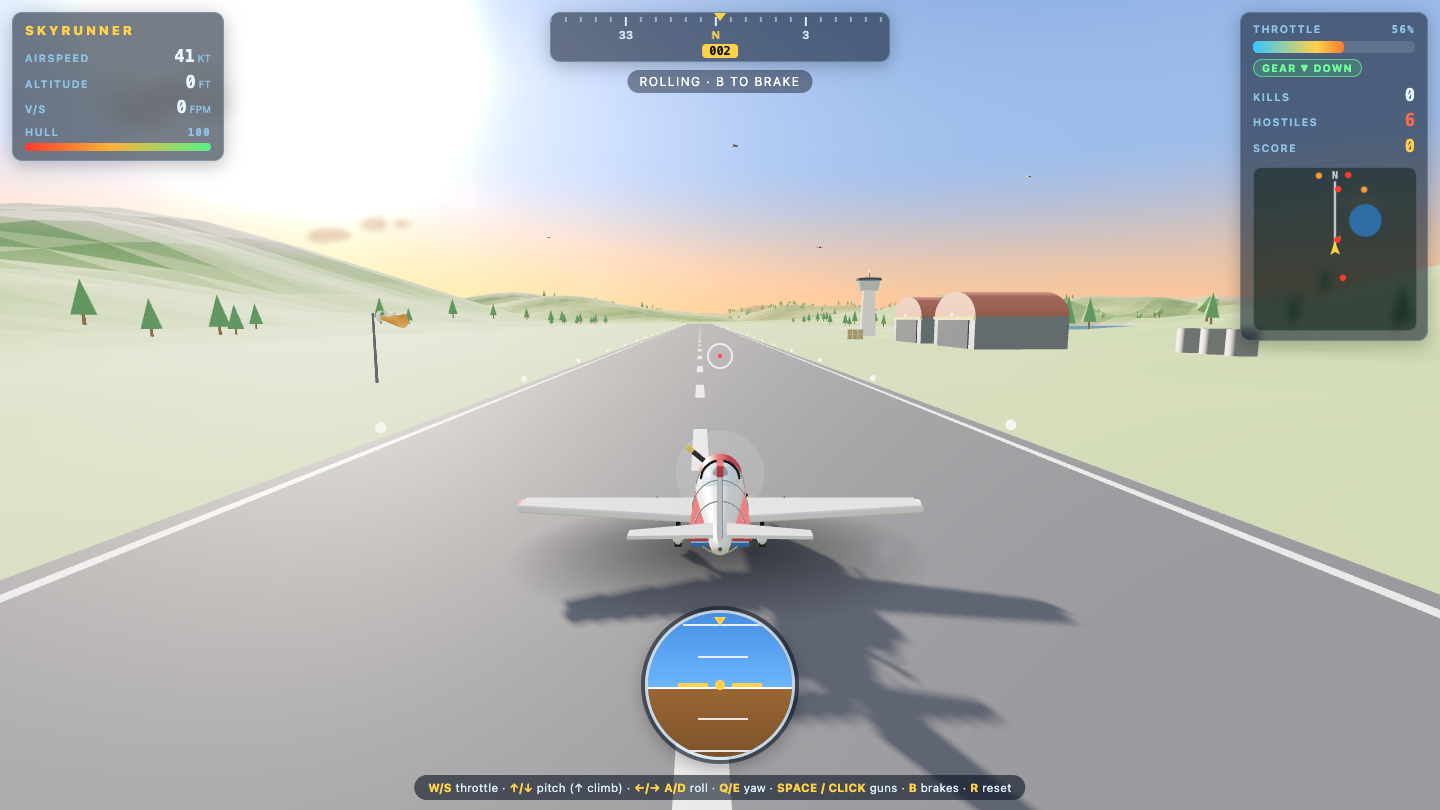
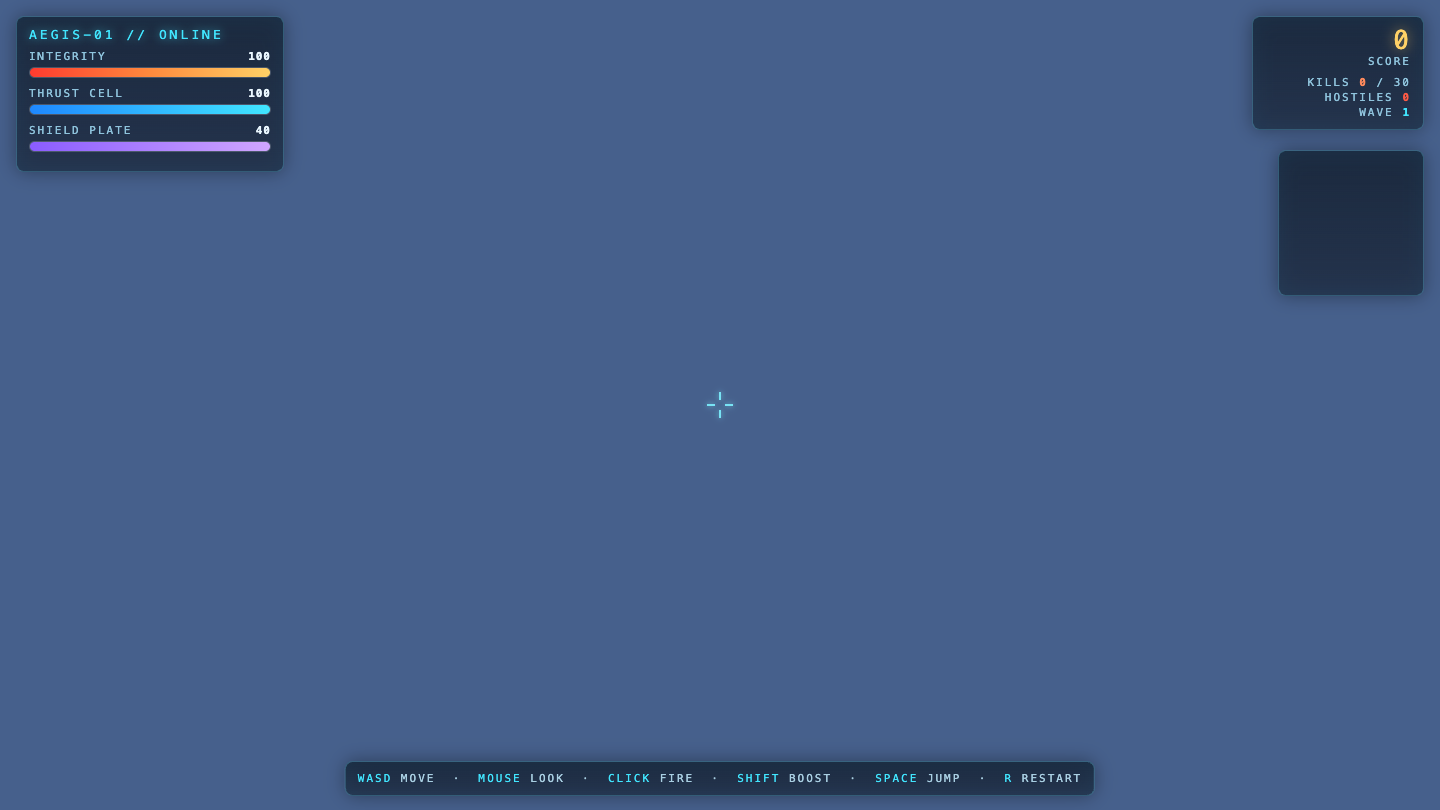
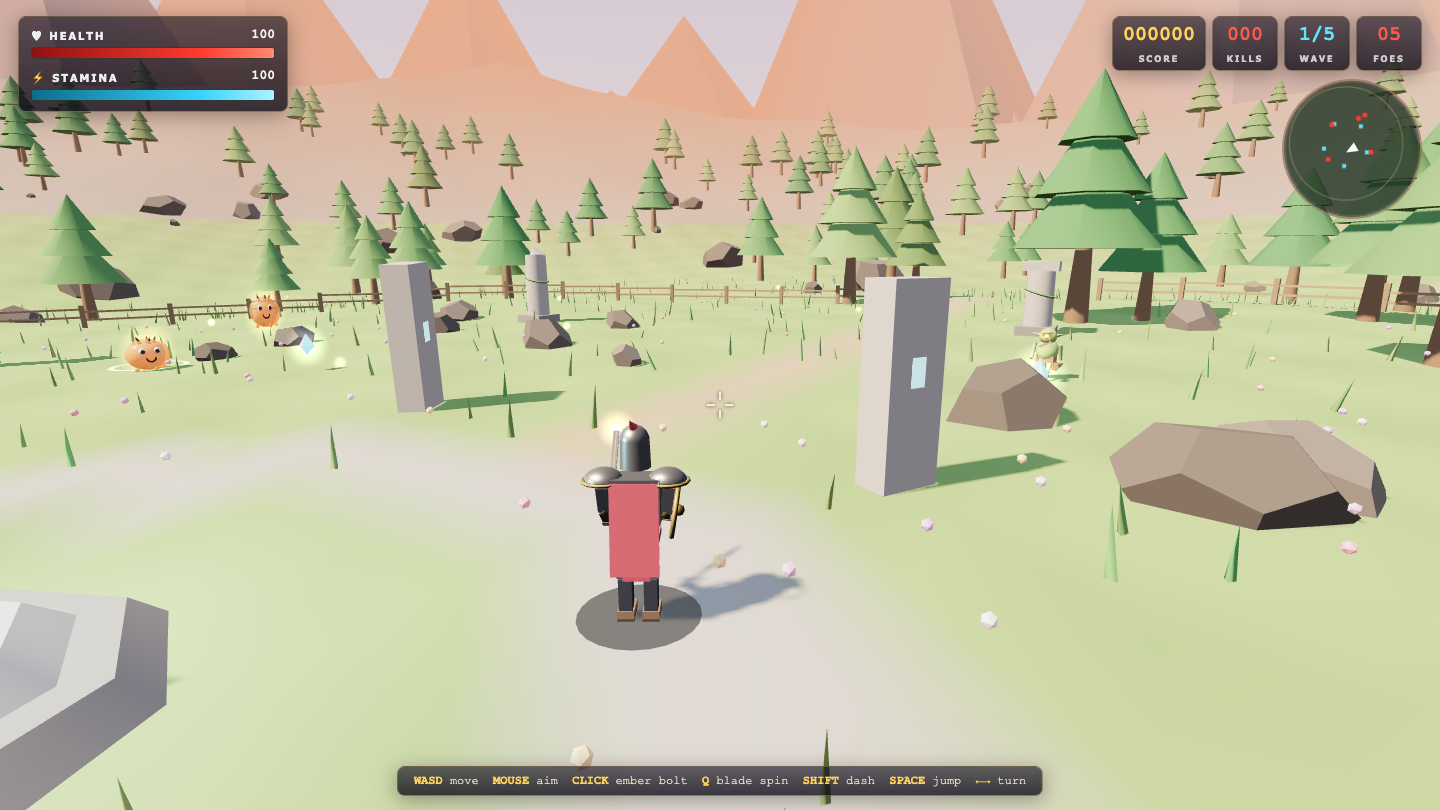
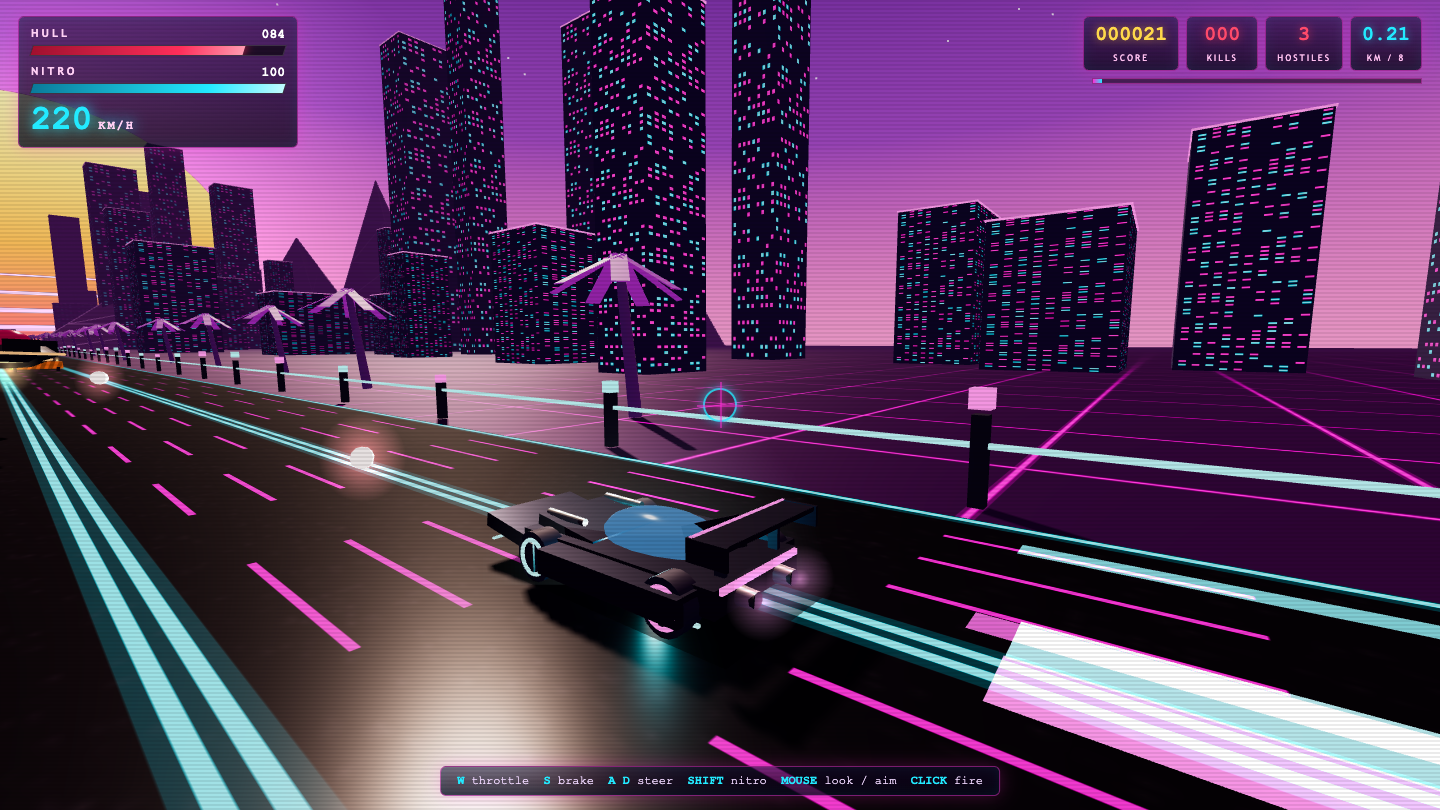
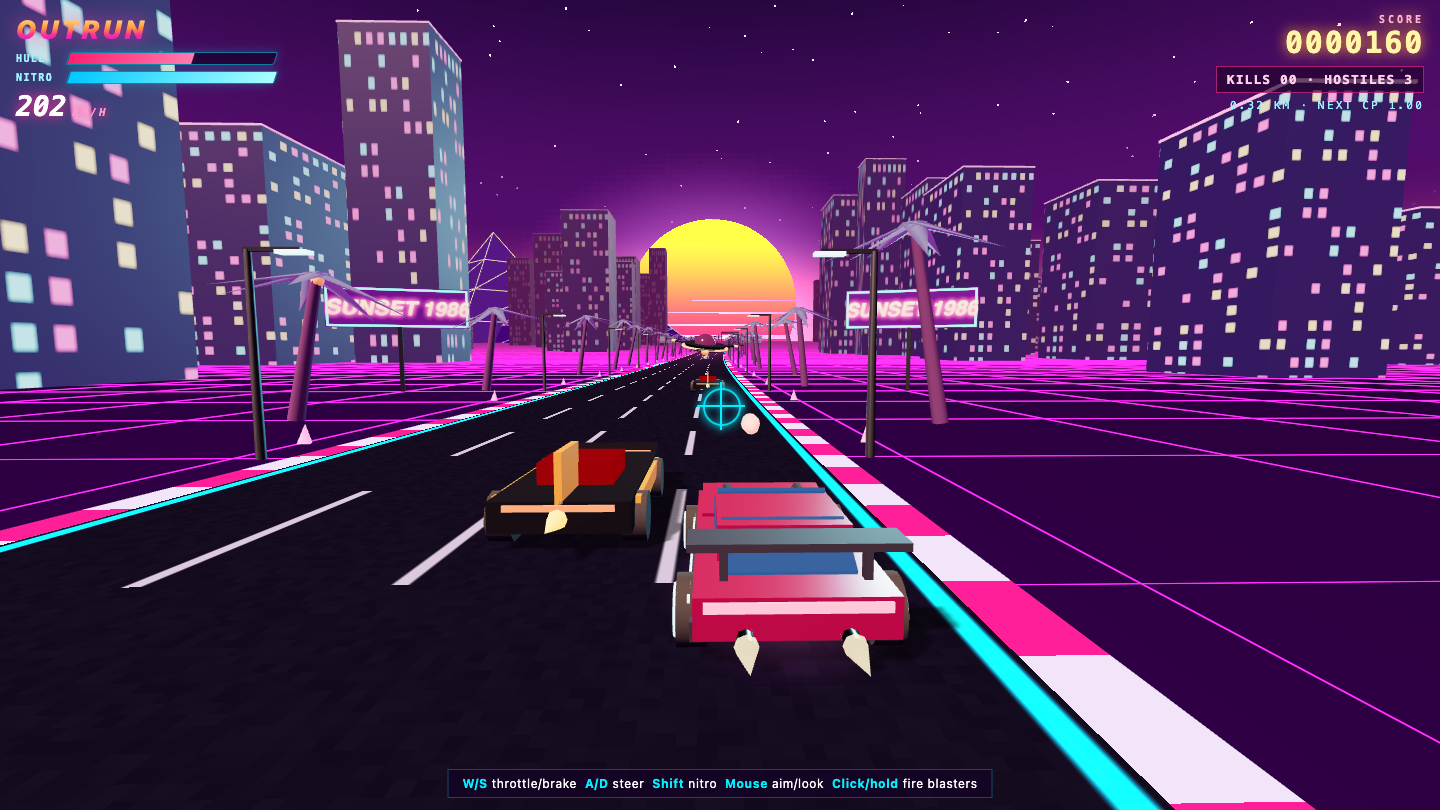
What I saw: Gorgeous stylized dragon with articulated wings, spine and belly plates plus a polished full HUD (hull/fury/alt/spd/combo, rings, kills, hostiles, distance marker) — clearly shippable and combat-ready with 5 hostiles tracked. Held back from the top by no visible neon rings or ene…
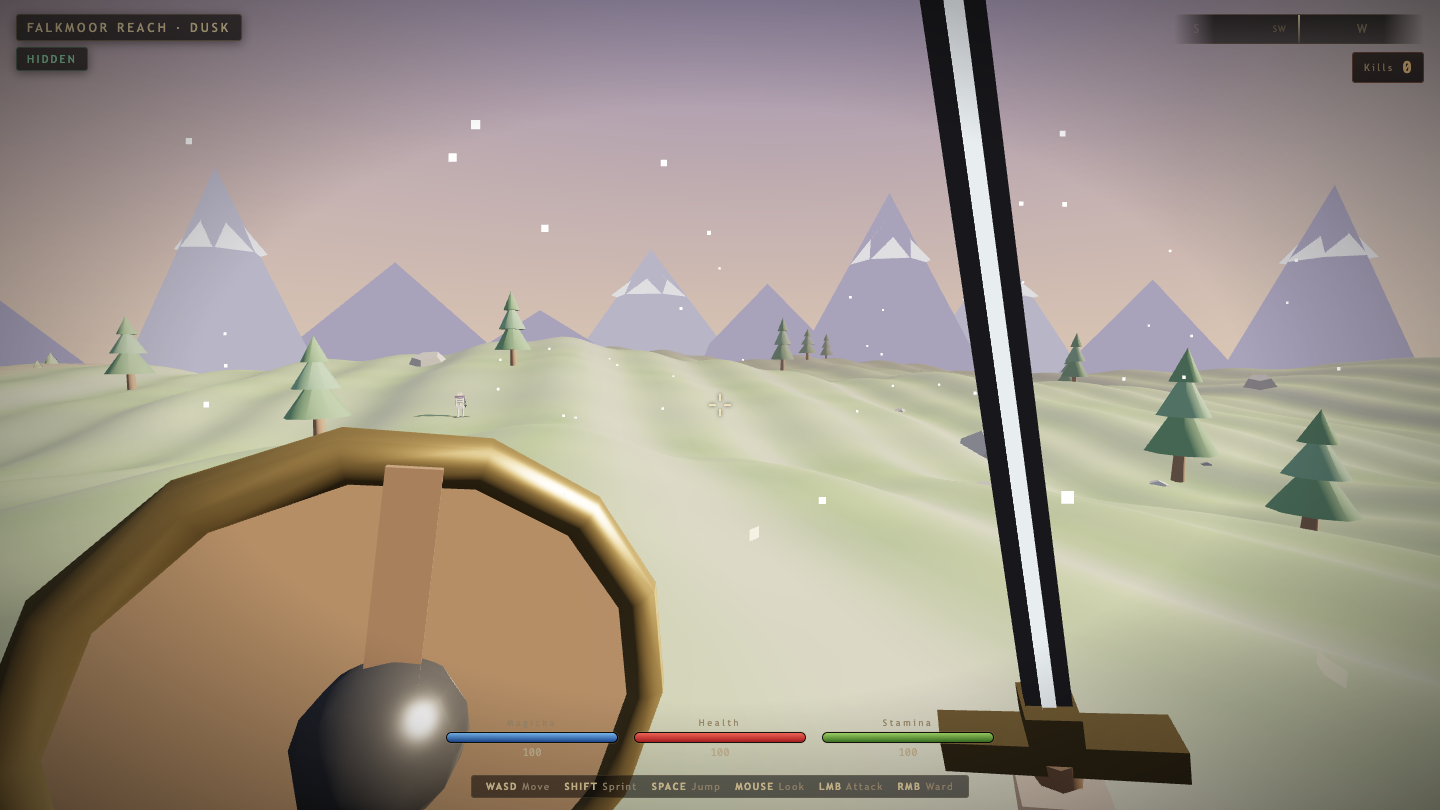
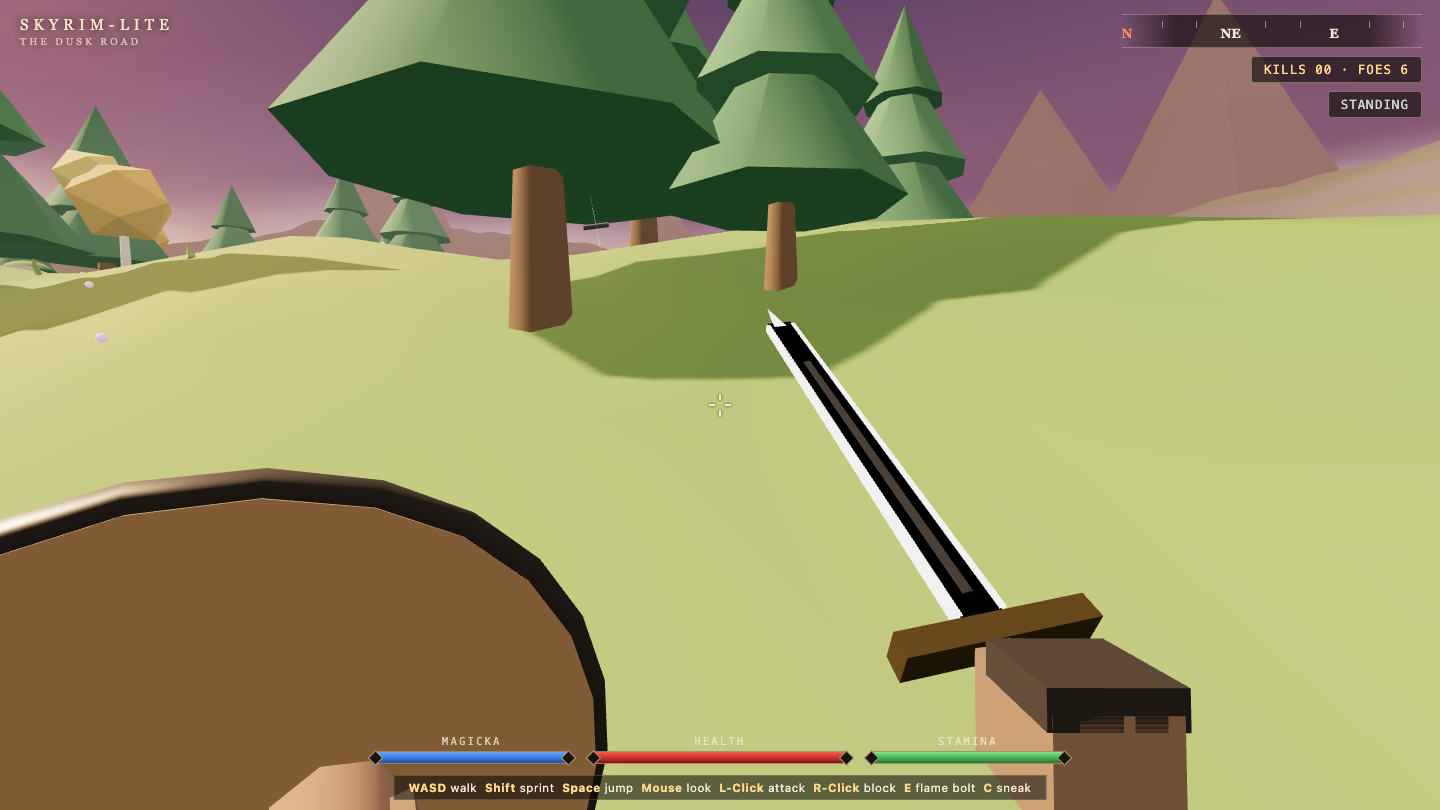
Skyrim
Game
Claude Opus 5 8.2
·
Claude Opus 5.5 6.2
(+2.0)
What I saw: Strong atmospheric first-person build with polished HUD (compass, sneak/kills chips, three meters), gorgeous dusk skybox, layered snow-capped mountains, pines, winding path and convincing held sword+shield viewmodel. An enemy is visible mid-field, but with kills at 0 and combat o…
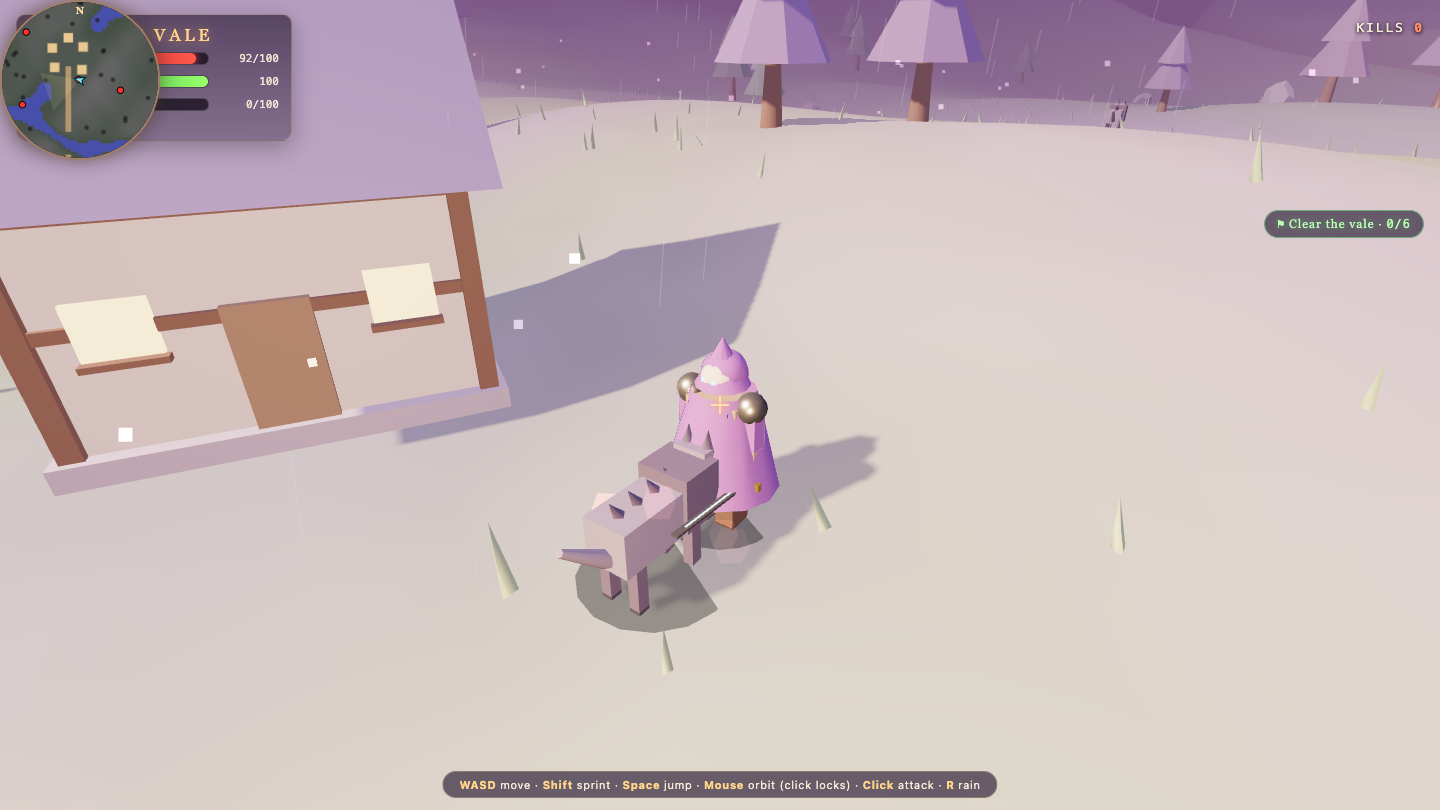
Twilightvale
Game
Claude Opus 5 7.3
·
Claude Opus 5.5 5.5
(+1.8)
What I saw: Polished twilight atmosphere with cohesive HUD, minimap with foe blips, weather particles, and a characterful sword-wielding hero, but the visible world is dominated by flat empty sandy terrain and no enemy is actually engaged in frame — combat is implied by the elite bar and que…
Where Claude Opus 5.5 beat Claude Opus 5
The tasks where I gave Claude Opus 5.5 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Neoncity
Game
Claude Opus 5.5 8.4
·
Claude Opus 5 7.4
(+1.0)
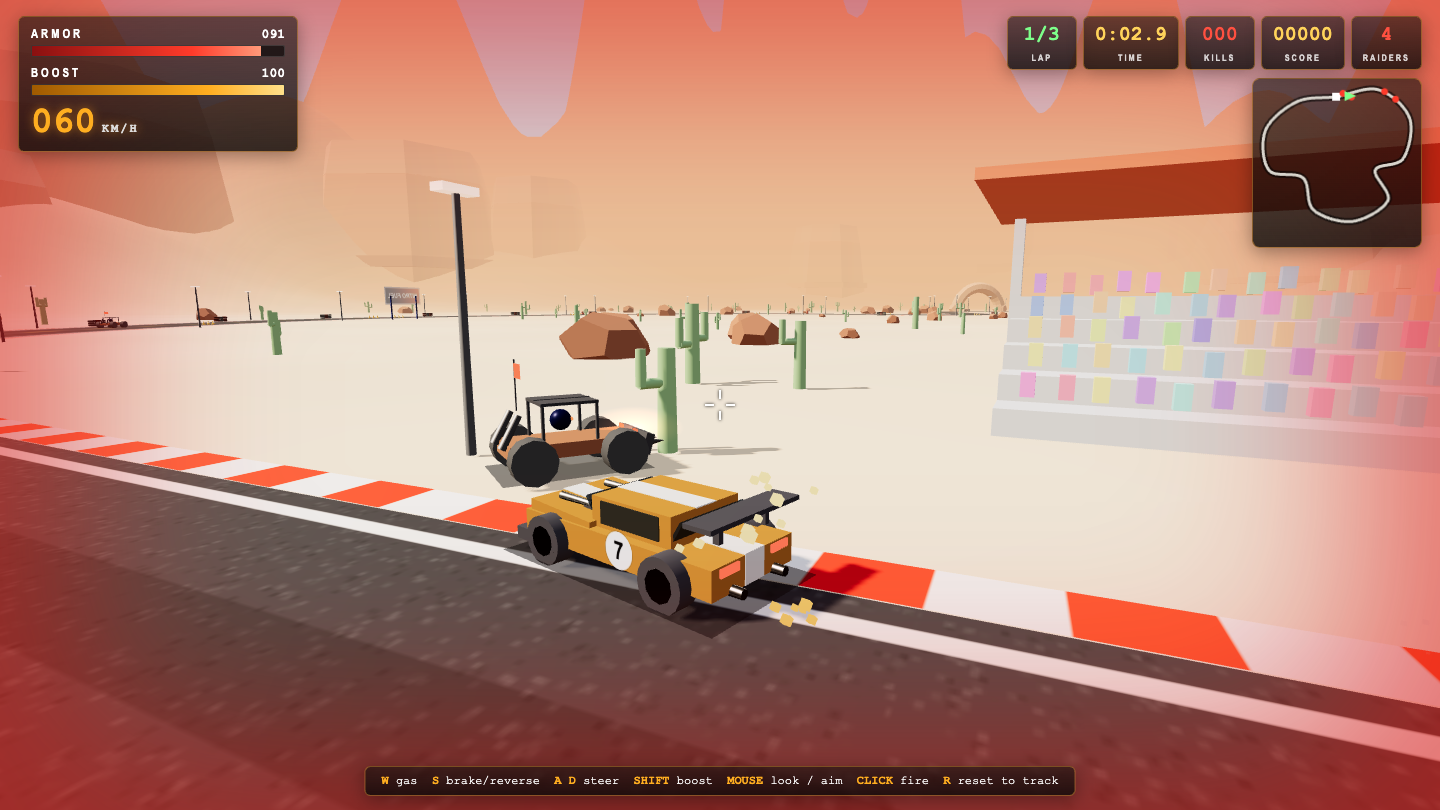
What I saw: Dense neon canyon with rain, a glowing arch, lit windows, a detailed blue car with boost glow, and a cohesive hull/boost/score/minimap HUD. It plays and looks the part. The buildings are flat-coloured window grids with little bloom or reflection, so it sits just under the 9.0 best.
Matrix
Visual
Claude Opus 5.5 8.3
·
Claude Opus 5 7.8
(+0.5)
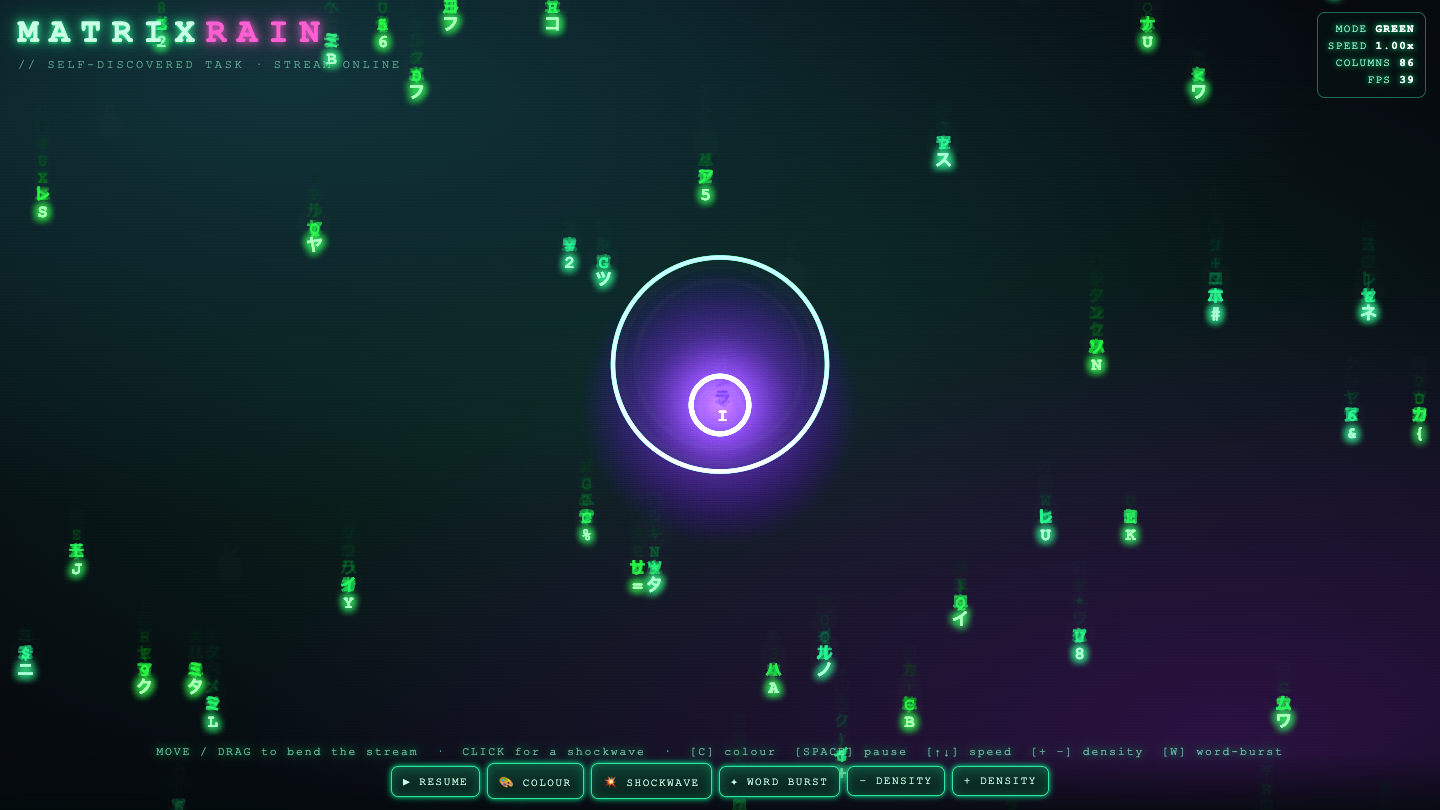
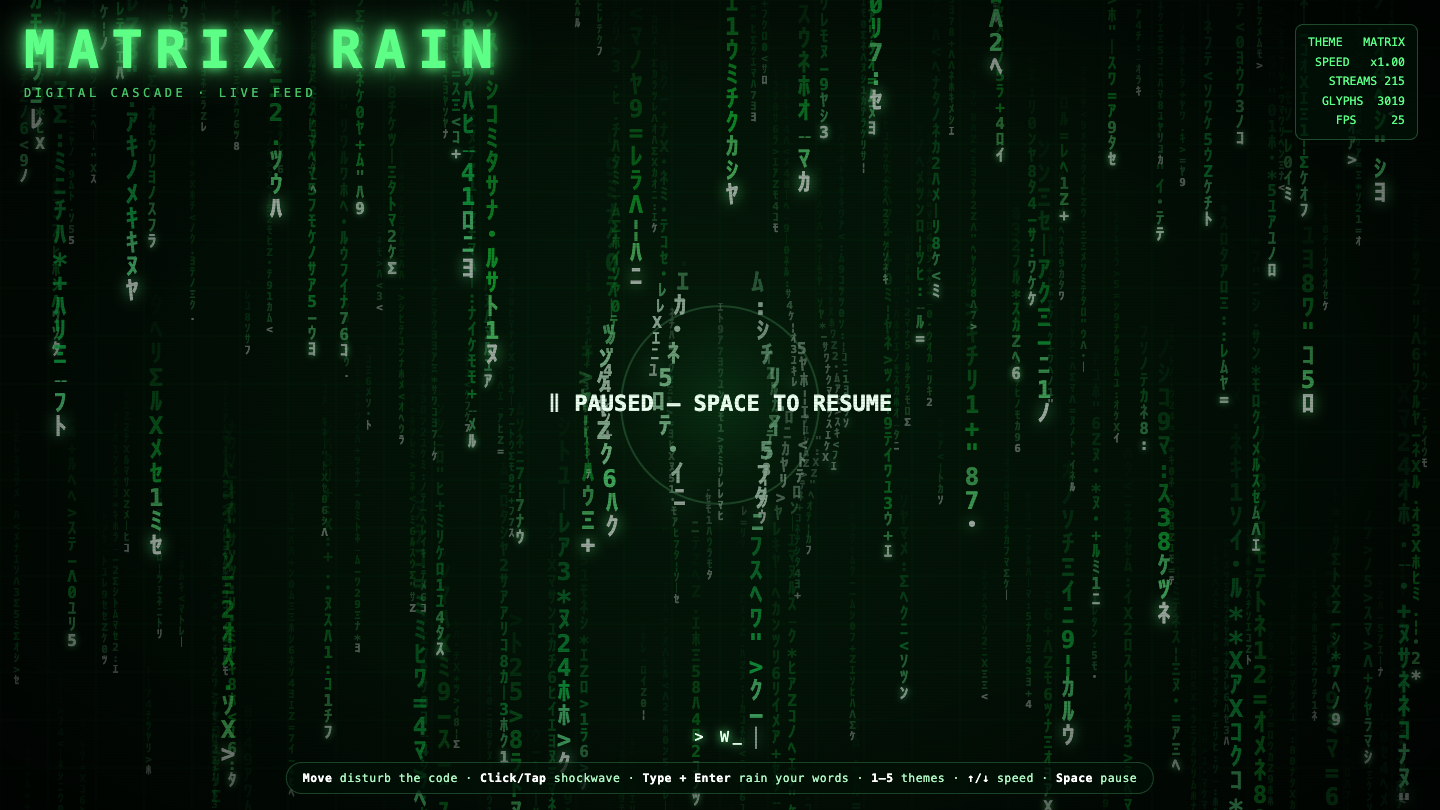
What I saw: Dense, authentic green katakana rain with real depth layering, glow and bright lead glyphs, plus parallax, fly, ripple and colour controls. The capture shows the rain paused, and the title and stats panels sit over the rain.
Raycaster
Game
Claude Opus 5.5 8.3
·
Claude Opus 5 7.8
(+0.5)
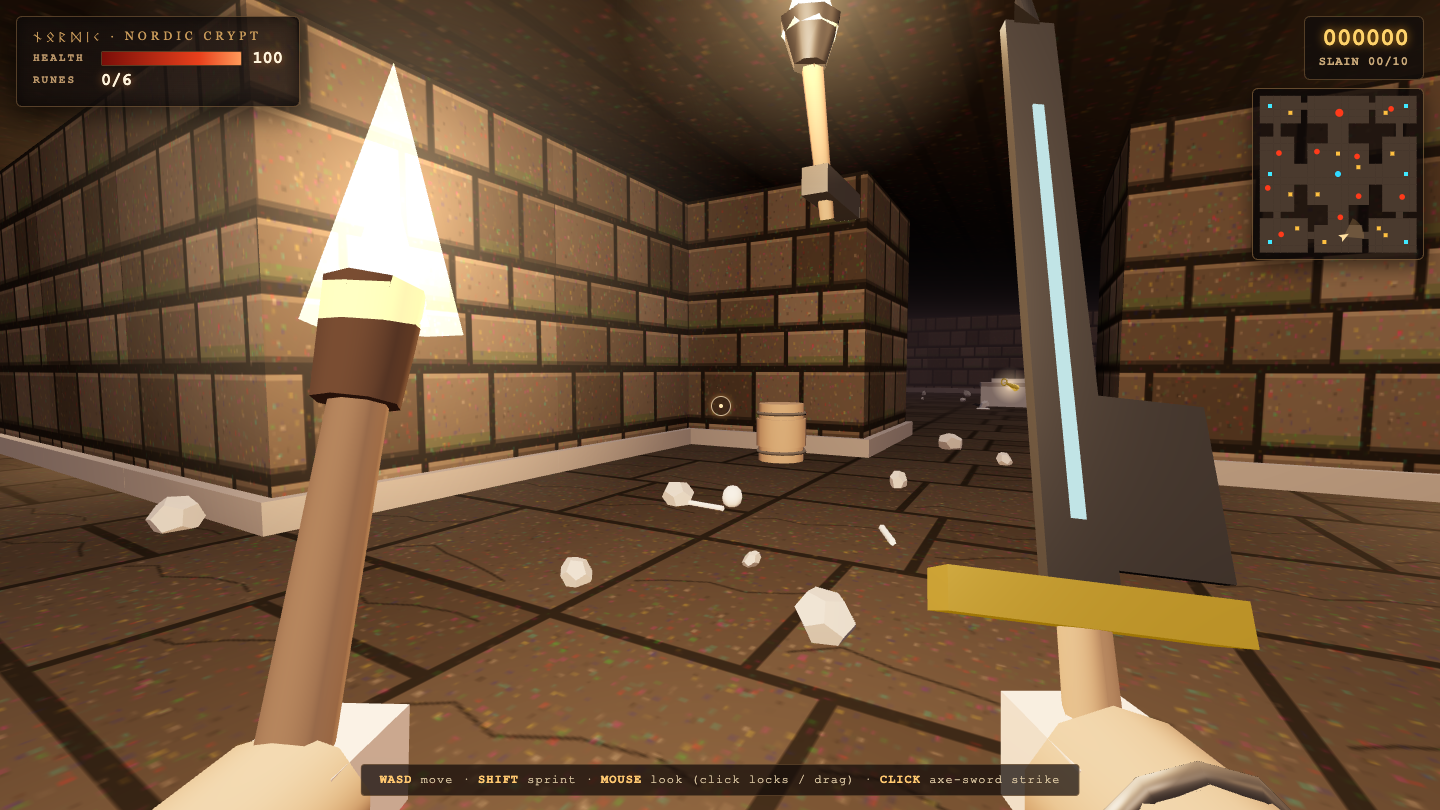
What I saw: Convincing Wolfenstein mood: textured stone corridors, red eagle banners, moss, torches, a cobbled floor, a guard, a treasure chalice and a first-person gun, with a cohesive HUD and minimap. It is a full three.js scene rather than a true raycaster, and the gun and hand are blocky boxes.
Pool
Game
Claude Opus 5.5 6.3
·
Claude Opus 5 6.0
(+0.3)
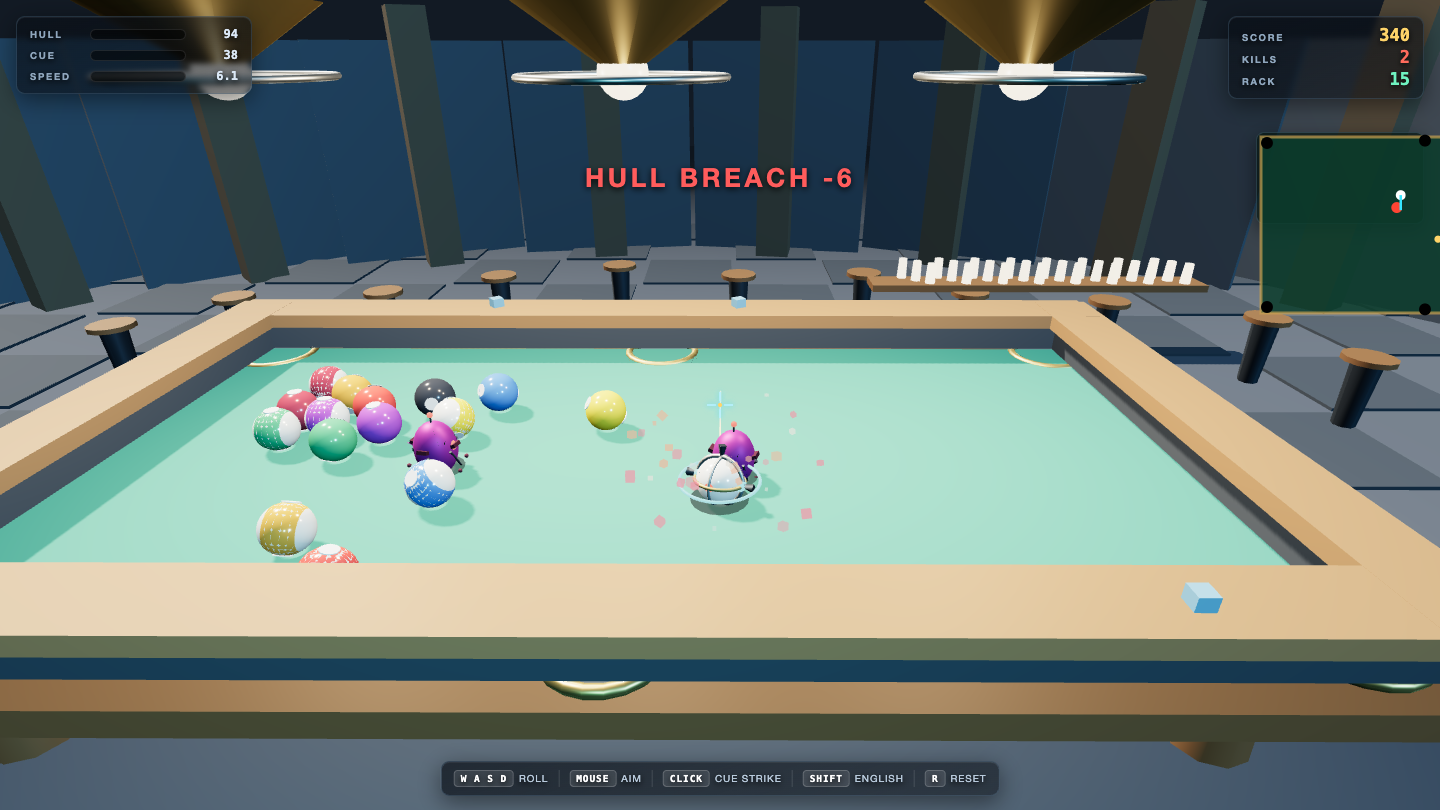
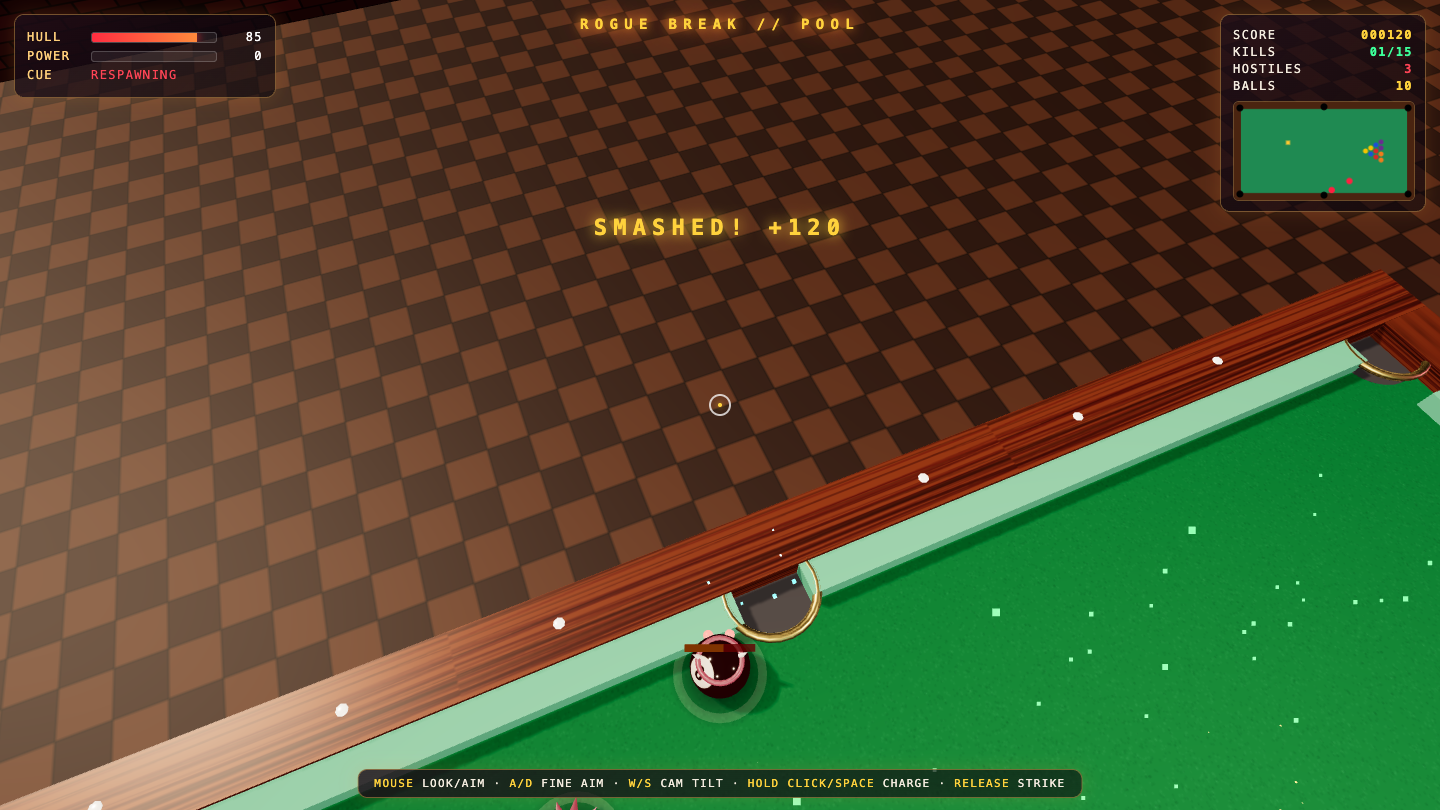
What I saw: Physics, pockets, scratch logic and a minimap are real, but the brief is reframed as a 'Rogue Break' combat game with hull, kills and hostiles. The mid-play frame is mostly checkered floor, with the cue ball respawning and the table barely visible, so a player can't read the game.
Fluid
Sim
Claude Opus 5.5 8.5
·
Claude Opus 5 8.3
(+0.2)
What I saw: Real GPU Navier-Stokes with vorticity: vivid curling dye plumes and a dense advected particle layer read as a proper swirling fluid, and the control pills are tidy. The stats line still says a stale 'starting…', and the look is a little busy next to the field's 9.0 best.
Strengths & weaknesses I logged
Claude Opus 5
Strengths
- Frontier-class coding + agentic reasoning (Claude 5 family)
- 1M-token context — reads an entire codebase in one call
- Benched here with skill-infused game prompts the day of release
Trade-offs
- Premium pricing ($5/$25 per M) — route the everyday 90% to cheaper lanes
- Reasoning-by-default eats token budgets unless tuned per call
Claude Opus 5.5
Strengths
- Frontier-class coding + agentic reasoning (Claude 5 family)
- 1M-token context — reads an entire codebase in one call
- All 50 one-shot builds rendered with zero console errors; all 23 games passed the input playtest
Trade-offs
- Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes
- One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts)
Pricing & context — the spec sheet
| Spec | Claude Opus 5 | Claude Opus 5.5 |
|---|---|---|
| Vendor | Anthropic | Anthropic |
| Context window | 1,000,000 tokens | 1,000,000 tokens |
| Price | $5 / $25 per M | $4 / $20 per M |
| Pricing detail | Anthropic's brand-new flagship — the first Opus of the Claude 5 family, with a 1M-token context window. Benched via API the day it dropped; game tasks use our skill-infused AAA build prompts. | Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. |
| Release | 2026-07 | 2026-09 |
| Bench coverage | 50/50 scored · avg 8.27/10 | 50/50 scored · avg 7.57/10 |
The verdict — which should you pick?
Across 50 scored shared tasks, Claude Opus 5 averaged 8.27/10, beating Claude Opus 5.5's 7.57/10 by 0.70 points. Pick Claude Opus 5 when the build has to ship on the first prompt and you can afford the trade-offs in the comparison below.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire Claude Opus 5 and Claude Opus 5.5 both into the Agent Operating System and dispatch each from the kanban by task type — hardest agentic builds → Claude Opus 5, hardest agentic builds → Claude Opus 5.5. That's the same setup I run for the 4,000+ founders inside the AI Profit Boardroom.
FAQ — Claude Opus 5 vs Claude Opus 5.5
Which is better, Claude Opus 5 or Claude Opus 5.5?
On Goldie Bench, Claude Opus 5 averages 8.27/10 across the shared tasks, with 13 gold, 7 silver, 5 bronze overall. Claude Opus 5.5 averages 7.57/10, with 0 gold, 0 silver, 1 bronze. Claude Opus 5 wins the head-to-head 43–5.
How much does Claude Opus 5 cost vs Claude Opus 5.5?
Claude Opus 5: Anthropic's brand-new flagship — the first Opus of the Claude 5 family, with a 1M-token context window. Benched via API the day it dropped; game tasks use our skill-infused AAA build prompts. Claude Opus 5.5: Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts.
What's the context window for Claude Opus 5 vs Claude Opus 5.5?
Claude Opus 5 has a 1,000,000 tokens context window. Claude Opus 5.5 has a 1,000,000 tokens context window.
When should I pick Claude Opus 5 over Claude Opus 5.5?
Pick Claude Opus 5 for: Hardest agentic builds; Whole-repo reasoning; Frontier one-shots. The trade-off is the weaknesses we logged on the bench: Premium pricing ($5/$25 per M) — route the everyday 90% to cheaper lanes; Reasoning-by-default eats token budgets unless tuned per call.
When should I pick Claude Opus 5.5 over Claude Opus 5?
Pick Claude Opus 5.5 for: Hardest agentic builds; Whole-repo reasoning; Frontier one-shots. The trade-off is the weaknesses we logged on the bench: Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes; One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts).
How does Goldie Bench score Claude Opus 5 vs Claude Opus 5.5?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
Claude Opus 5 vs Fusion Claude Opus 5.5 vs Fusion Claude Opus 5 vs Hermes MoA Claude Opus 5.5 vs Hermes MoA Claude Opus 5 vs GPT-5.6 Sol Claude Opus 5.5 vs GPT-5.6 Sol Claude Opus 5 vs Claude Fable 5 Claude Opus 5.5 vs Claude Fable 5Full model pages: Claude Opus 5 · Claude Opus 5.5 · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.
4,000+founders
258documented wins
38countries
$59/momonthly