Real head-to-head · same prompt, one shot
MiMo-V2.6 Pro vs DeepSeek V4 Pro
Open weights that score level with Opus 5 on agents, for cents. vs DeepSeek's flagship tier — benched head-to-head against its own cheap Flash.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to MiMo-V2.6 Pro and DeepSeek V4 Pro, side by side, on 50 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
MiMo-V2.6 Pro · Benched on all 50 GoldieBench tasks through OpenRouter at the model's default reasoning effort: one-shot build, real rendered poster, Opus 4.8 vision judge, game tasks skill-infused. No retries, no hand fixes; the broken builds are scored as they shipped.
DeepSeek V4 Pro · Benched on all 50 GoldieBench tasks via api.deepseek.com with the same pipeline as the Flash 0731 run, then published as a live side-by-side: goldiebench.com/vs-live/deepseek-flash-vs-pro.html loads both builds of every task in twin panes.
Side-by-side on 50 shared tasks
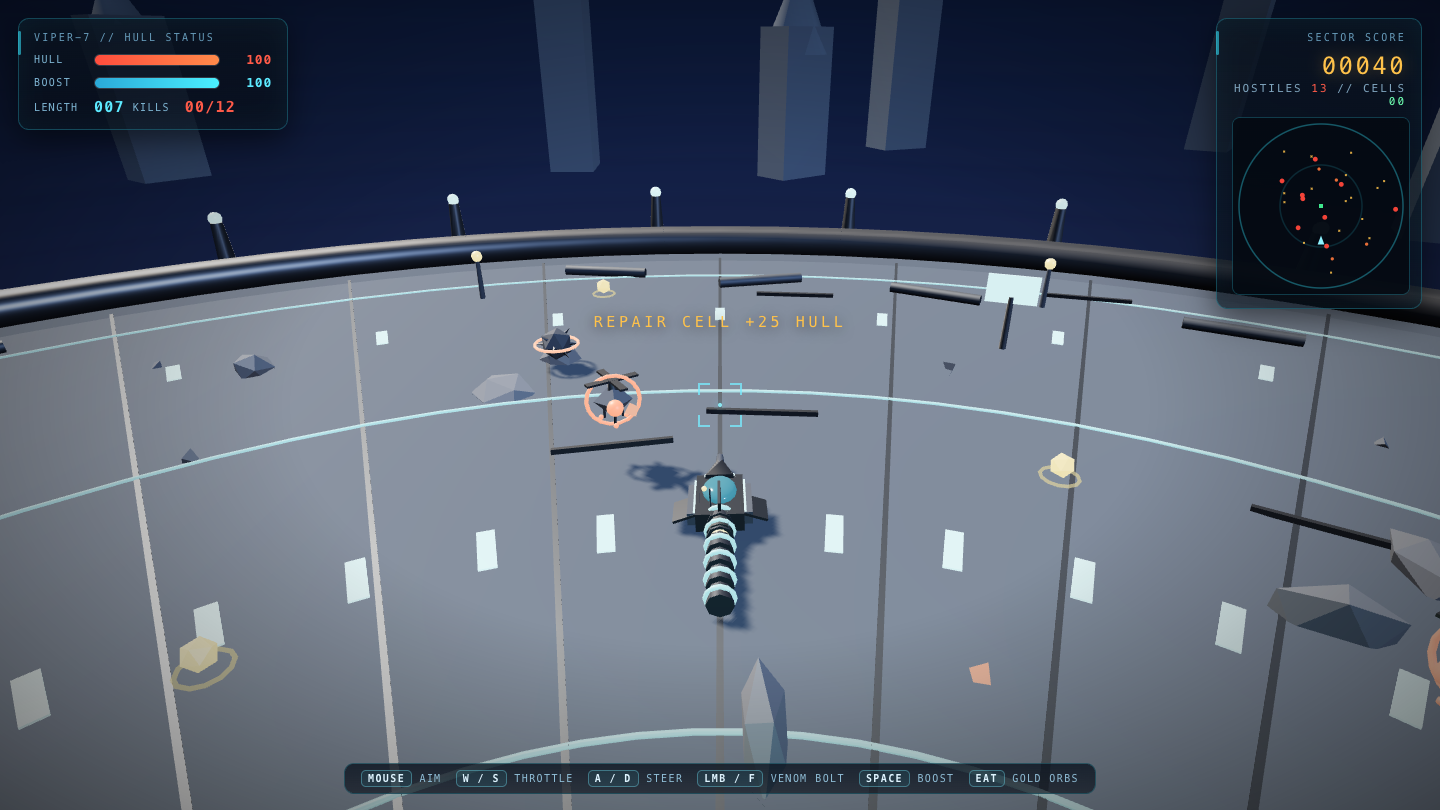
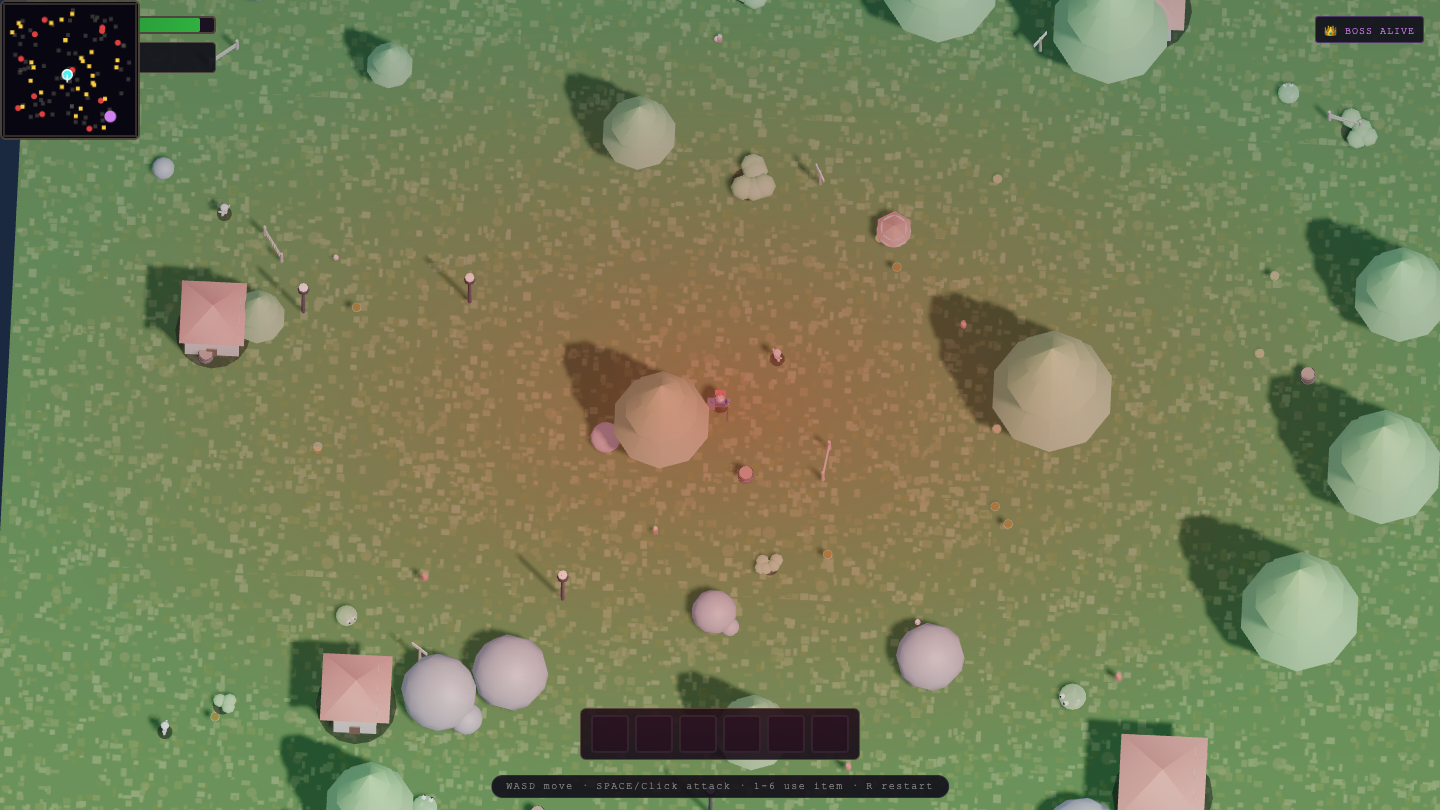
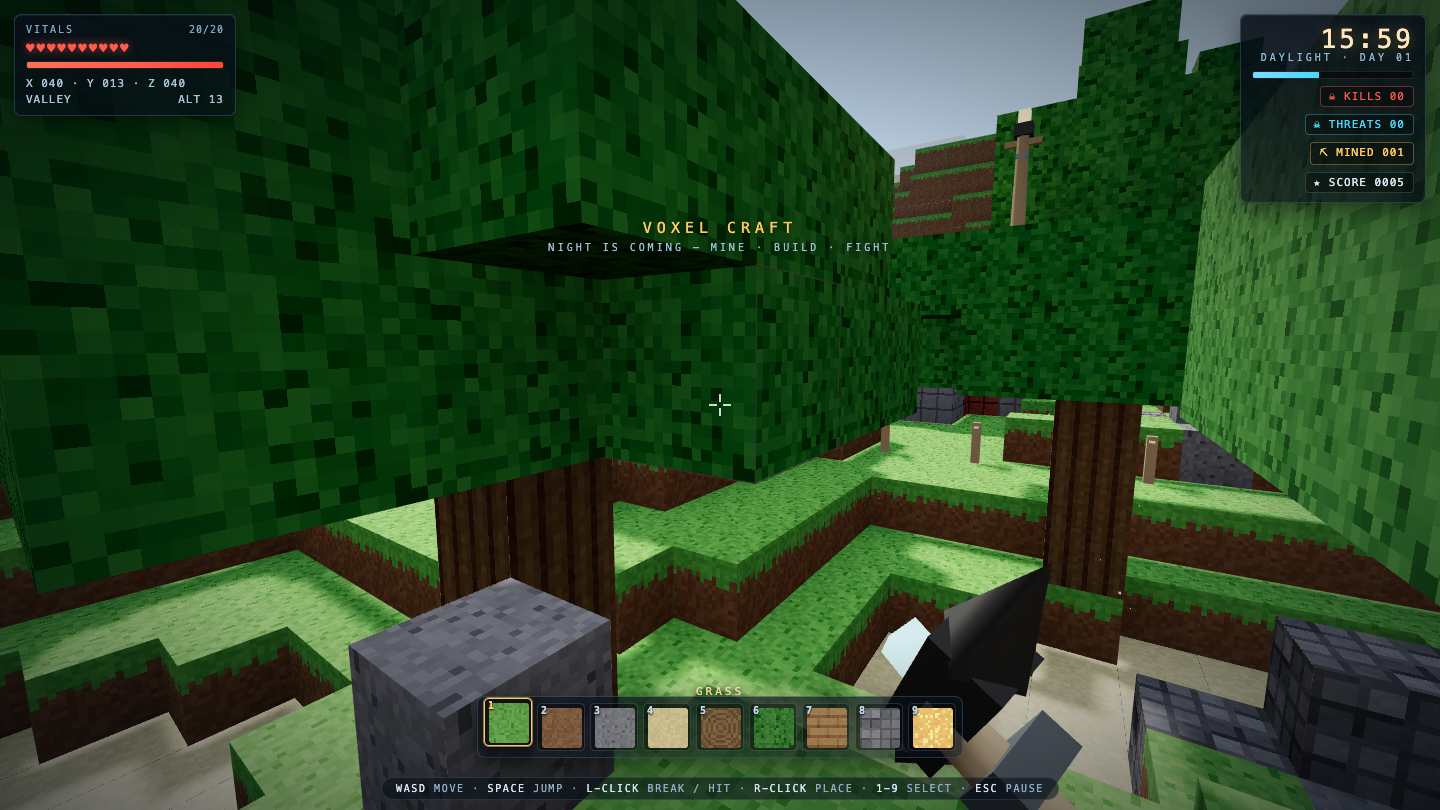
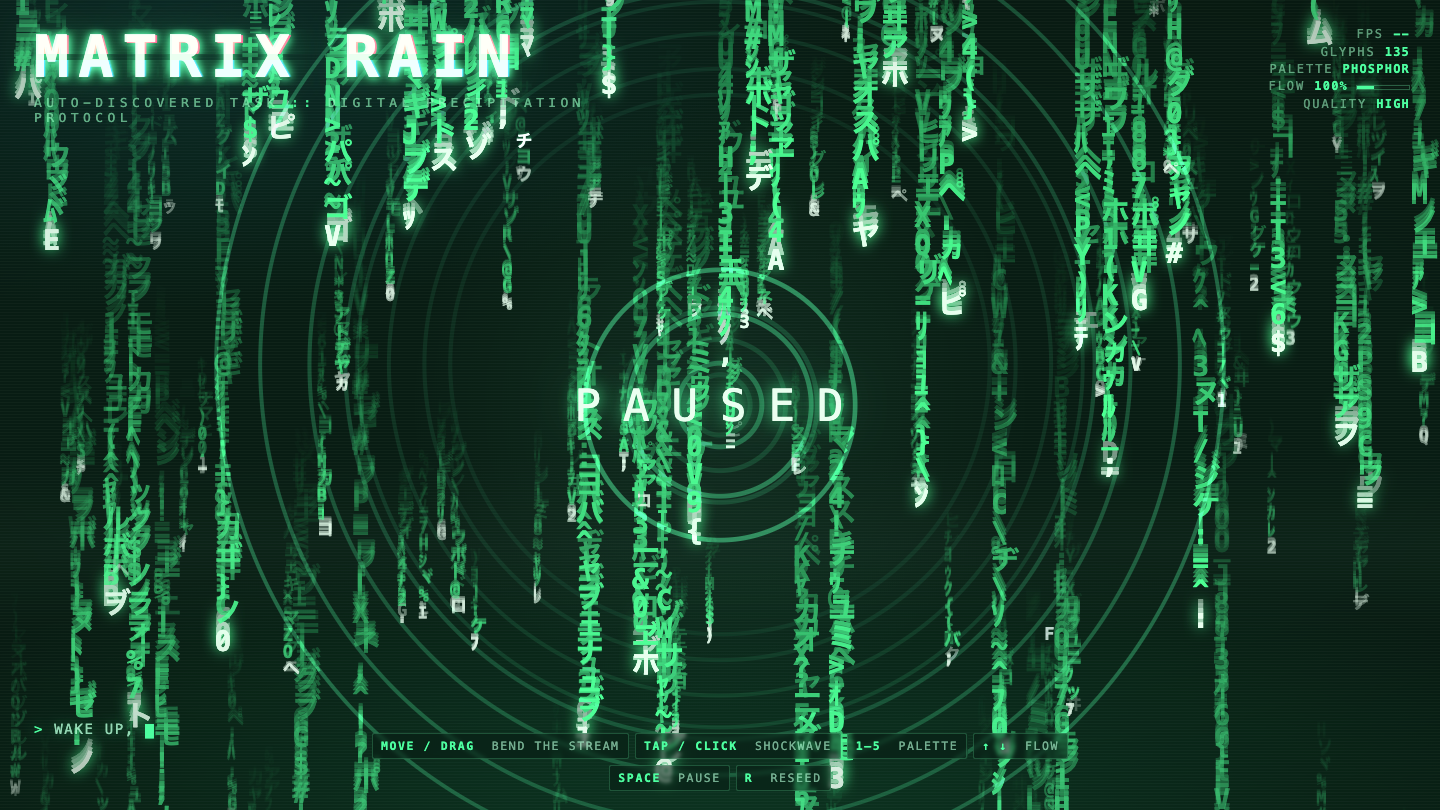
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
MiMo-V2.6 Pro
DeepSeek V4 Pro
Game
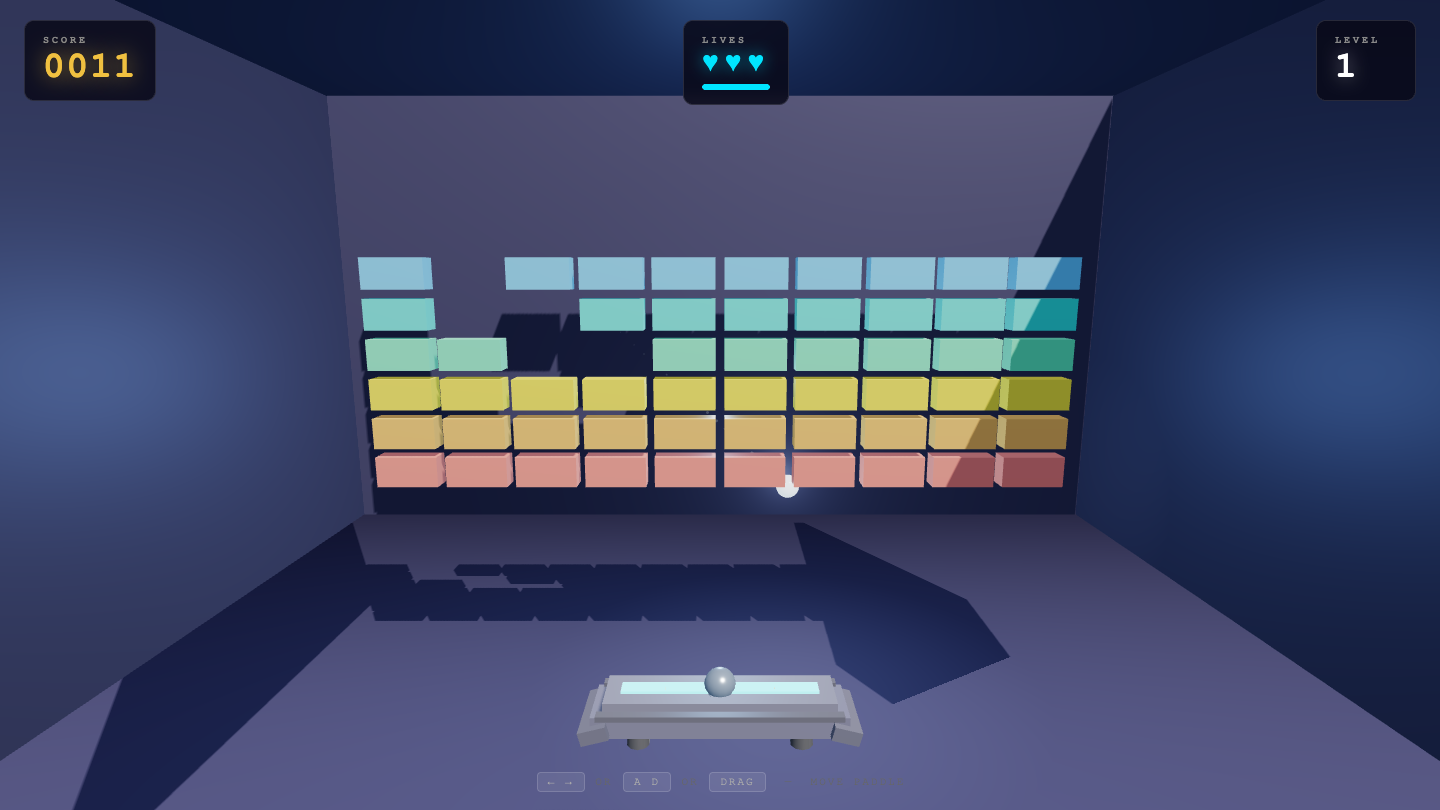
Game
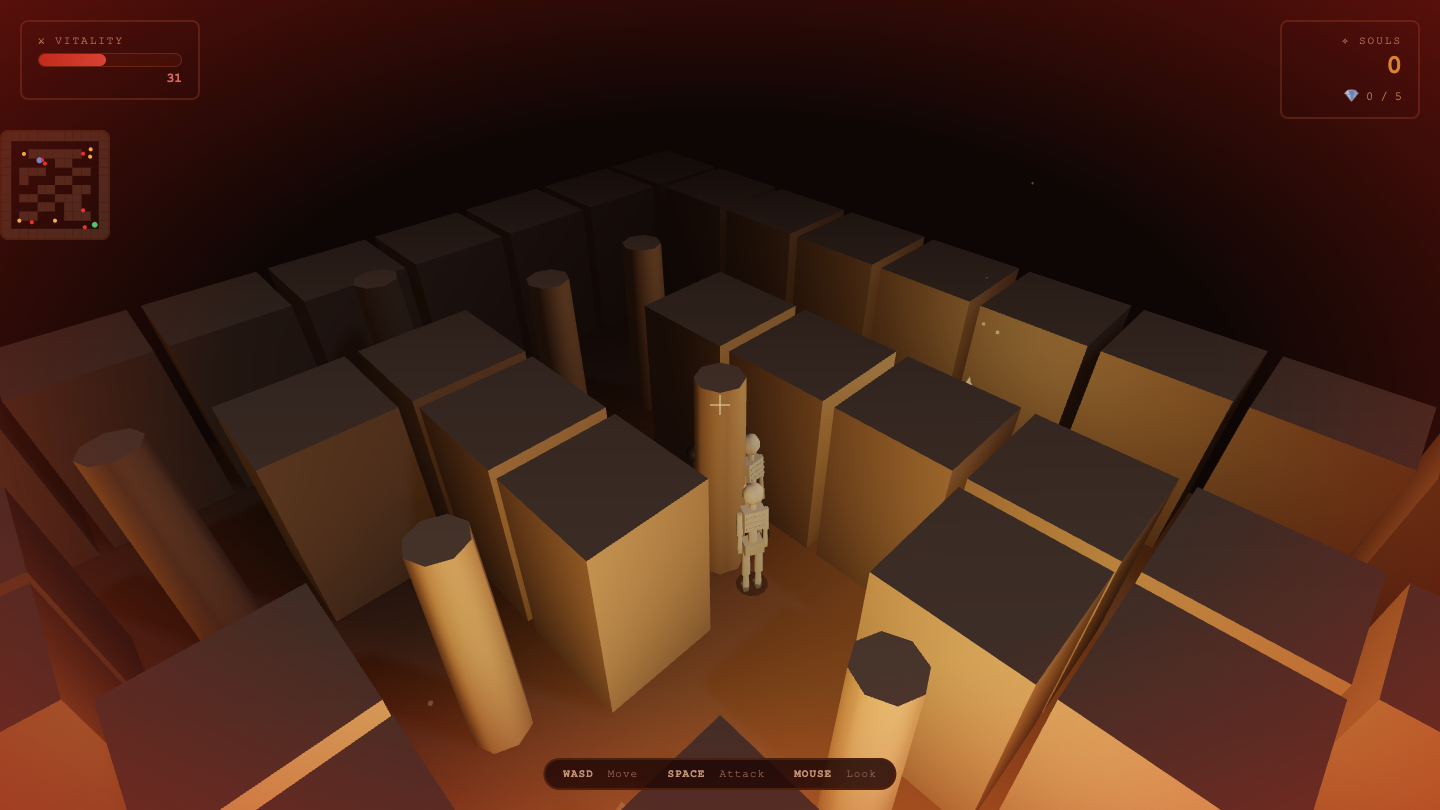
Game
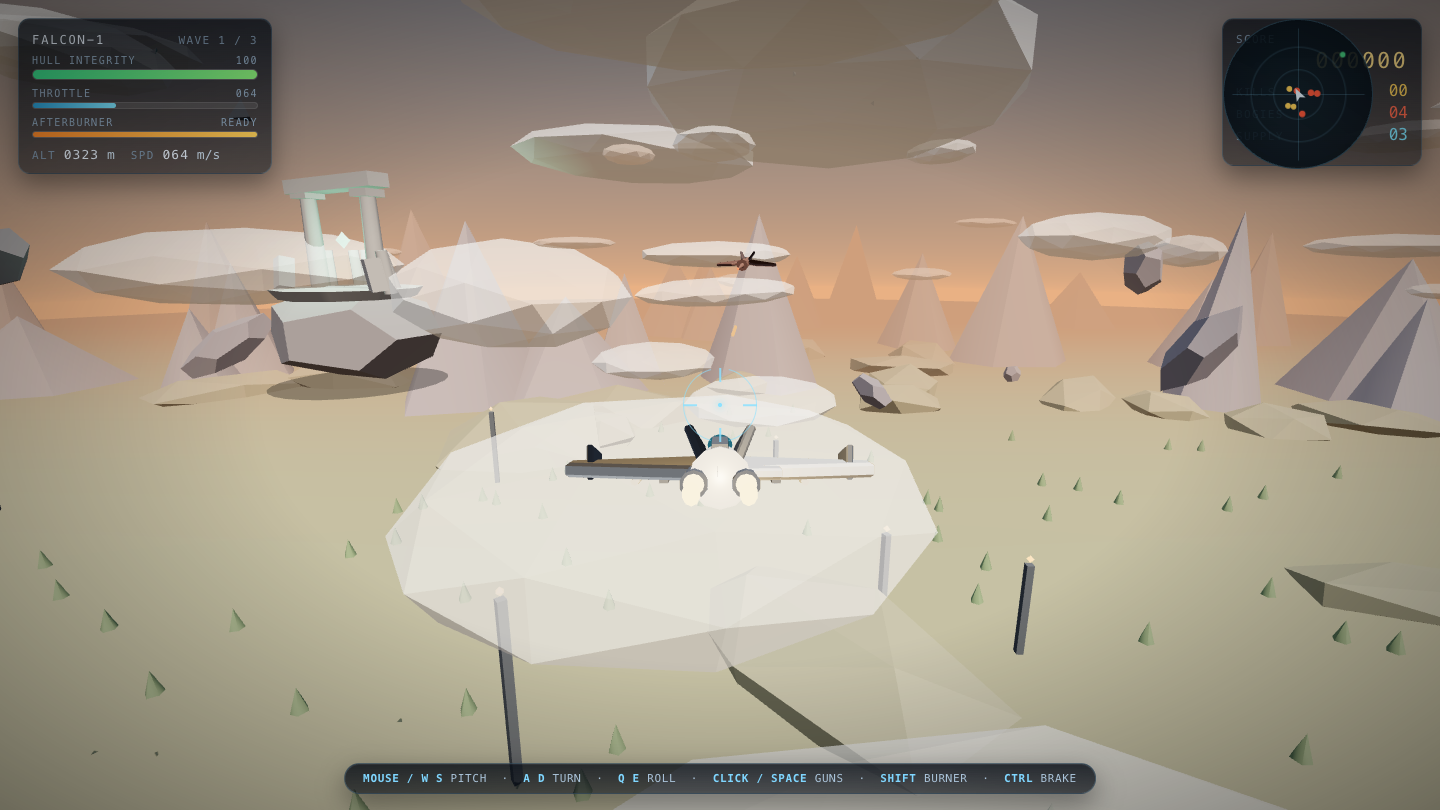
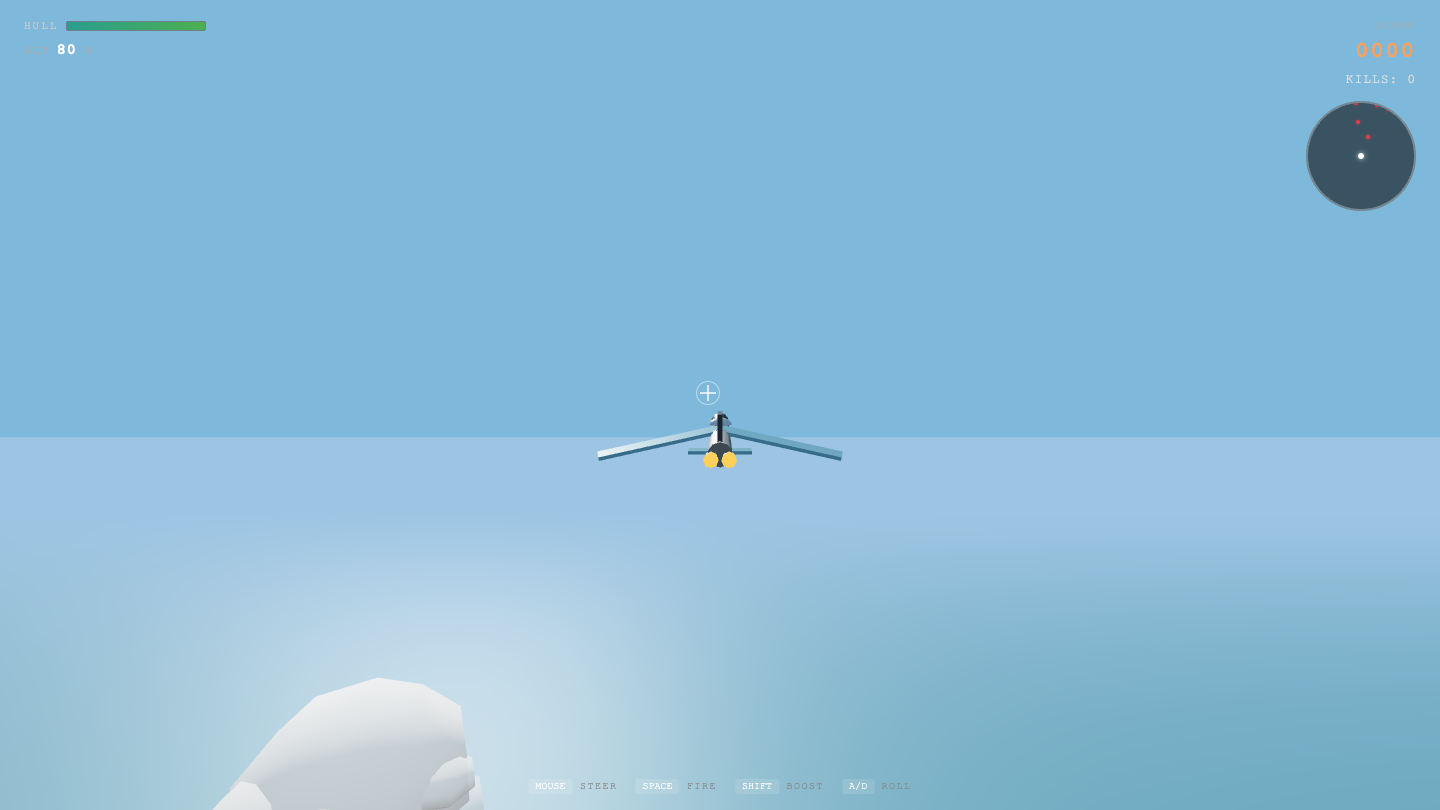
Game
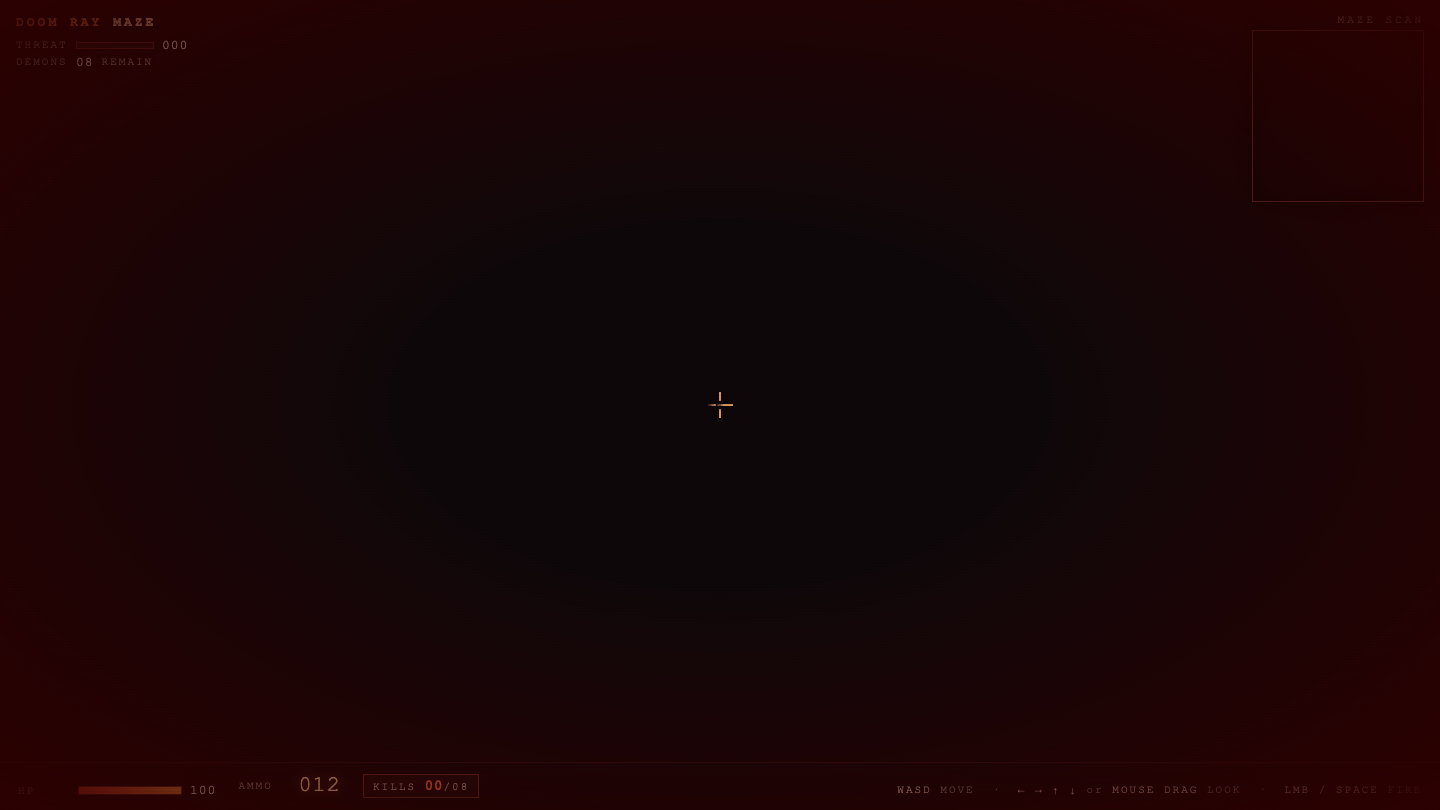
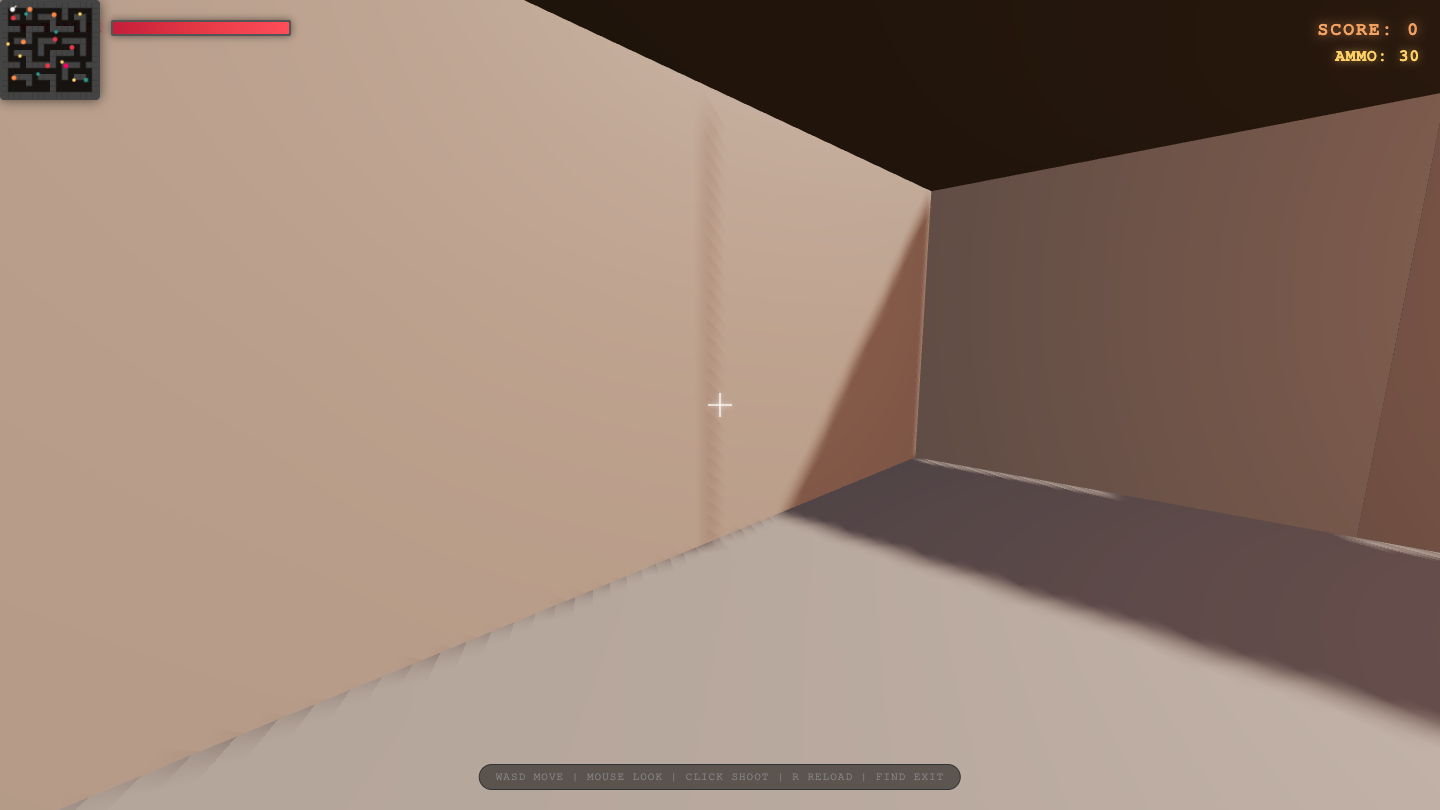
Game
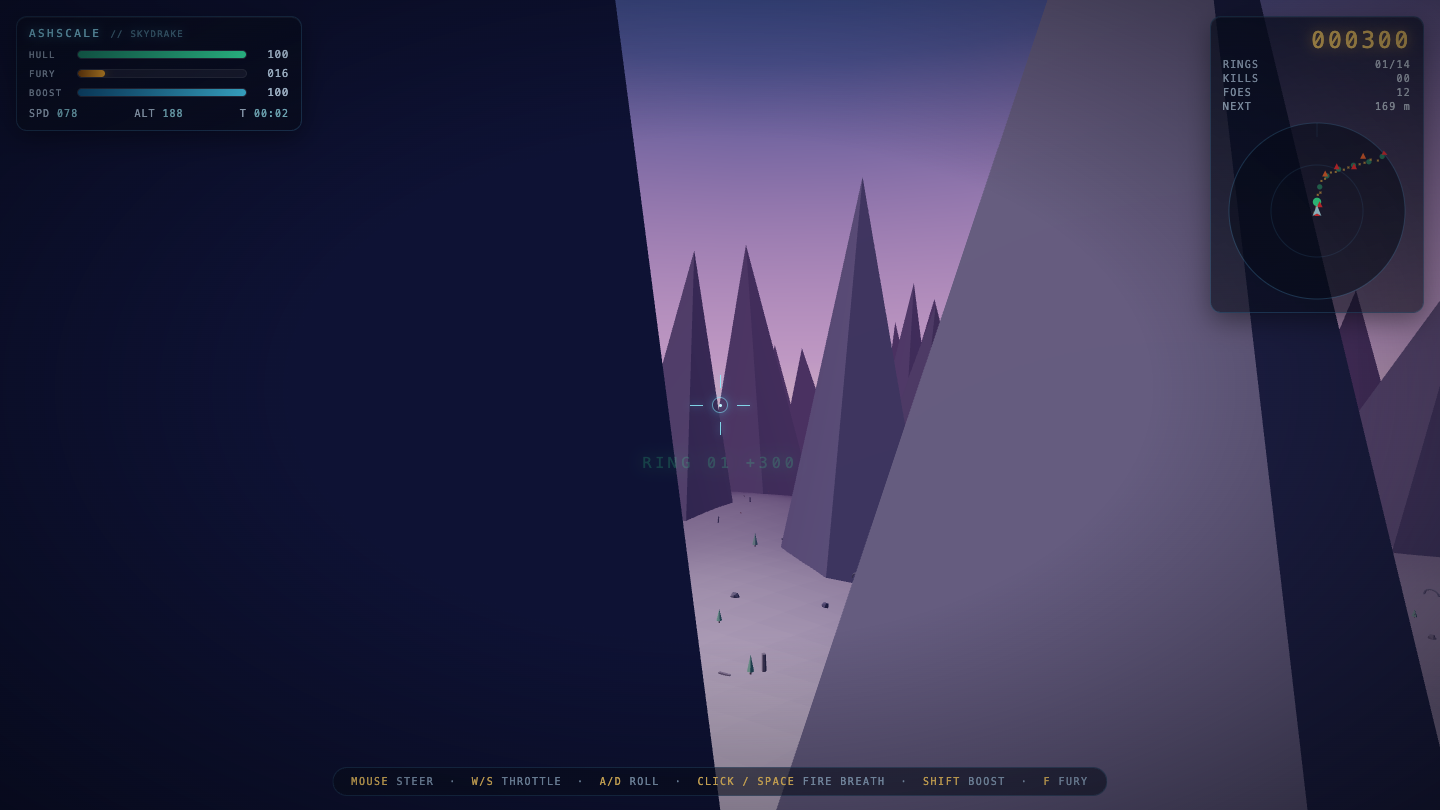
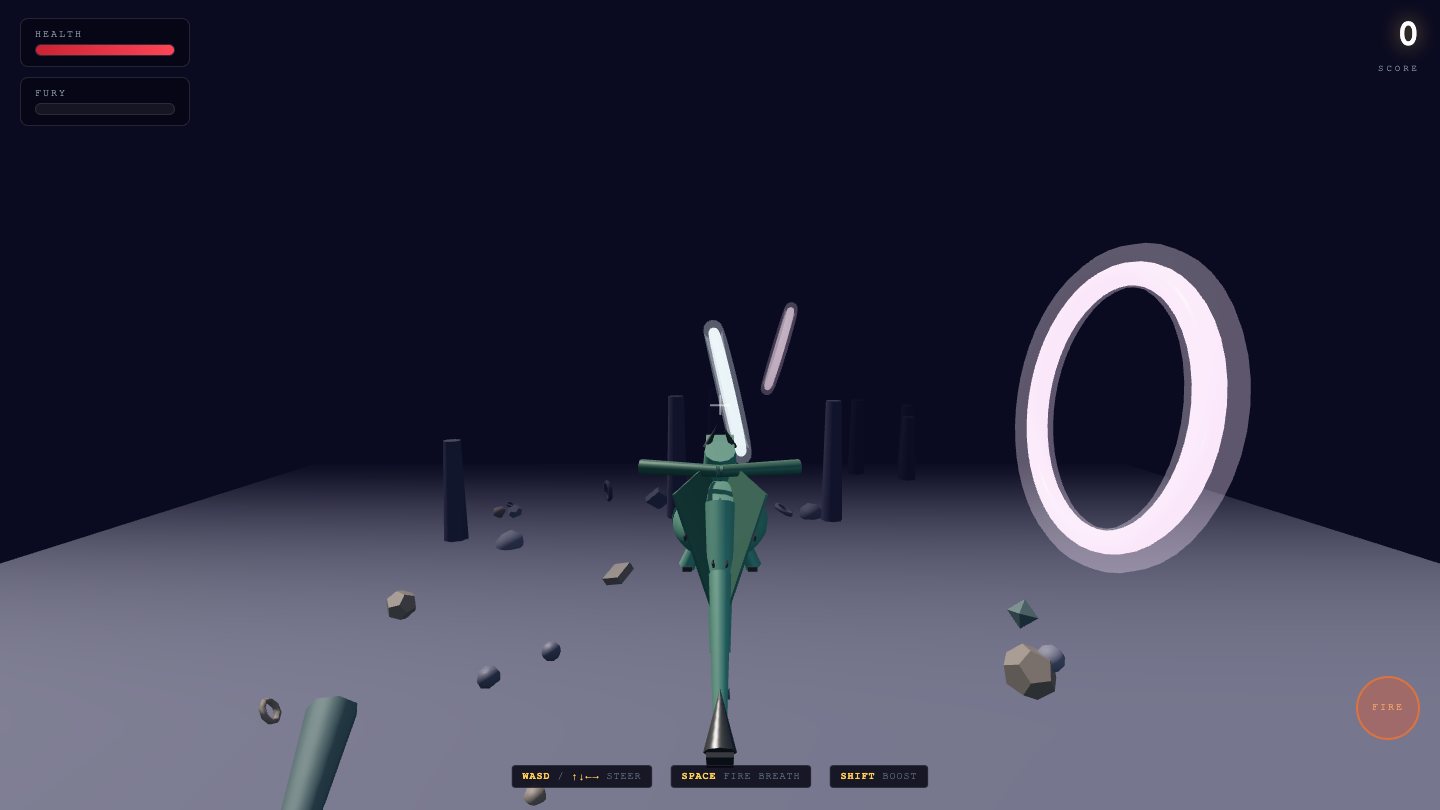
Game
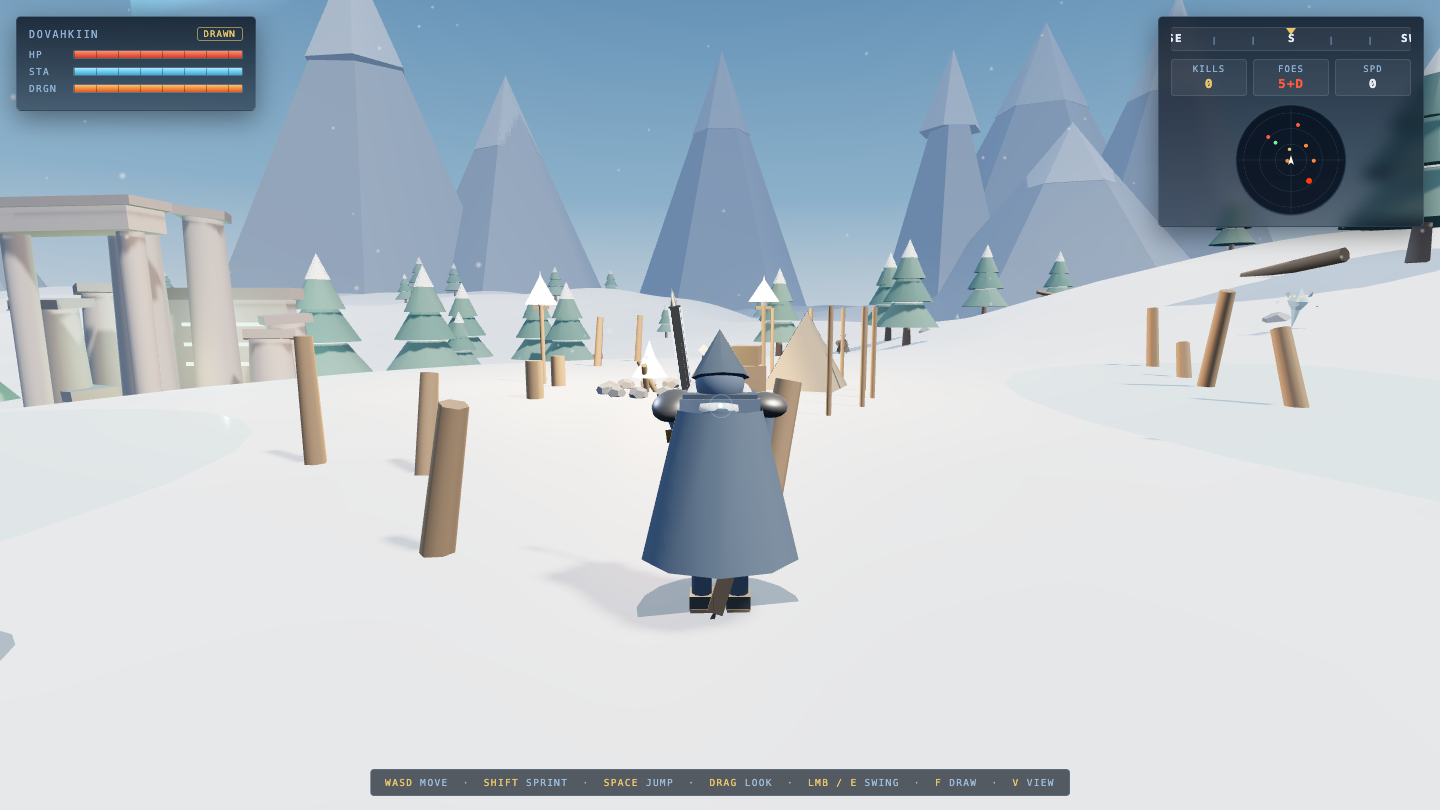
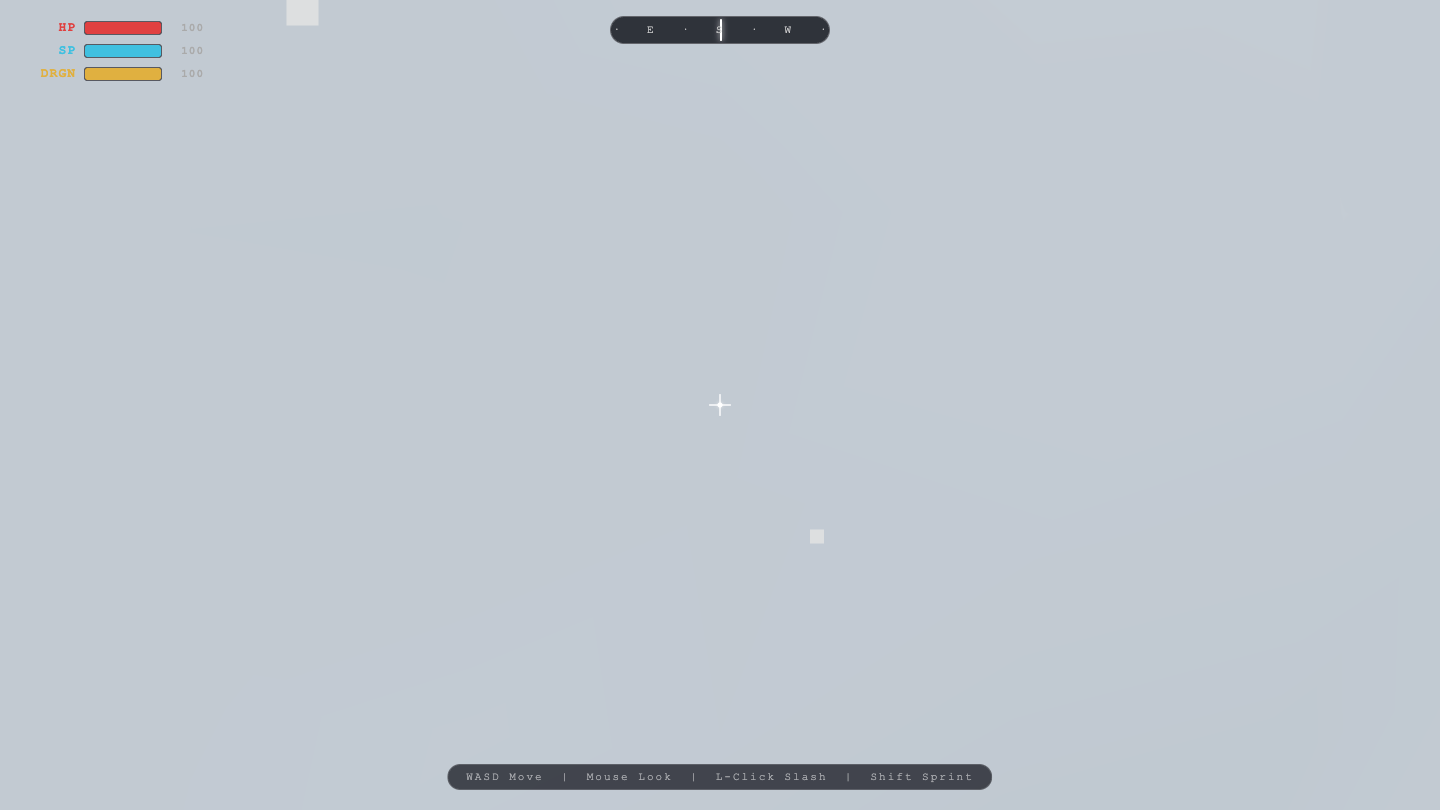
Game
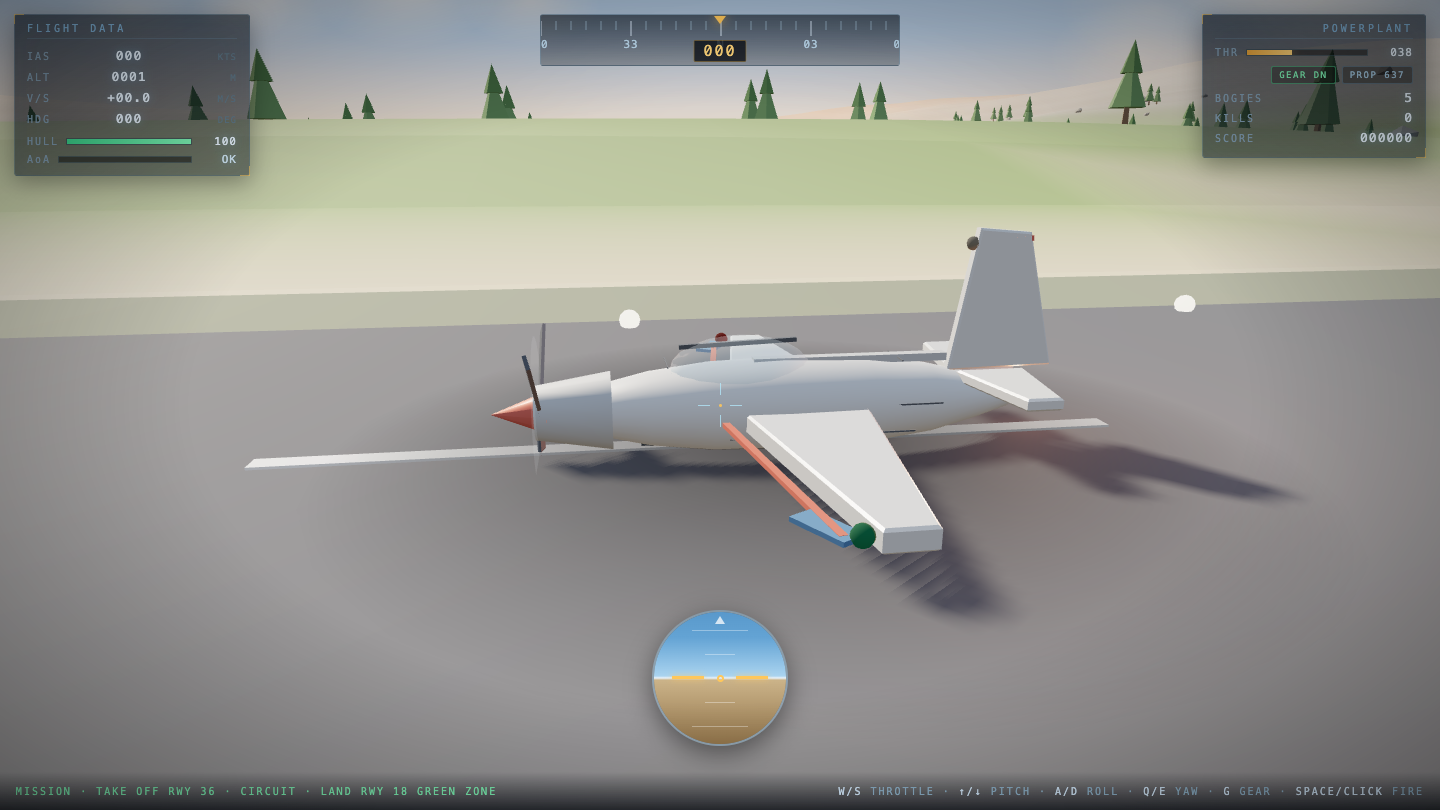
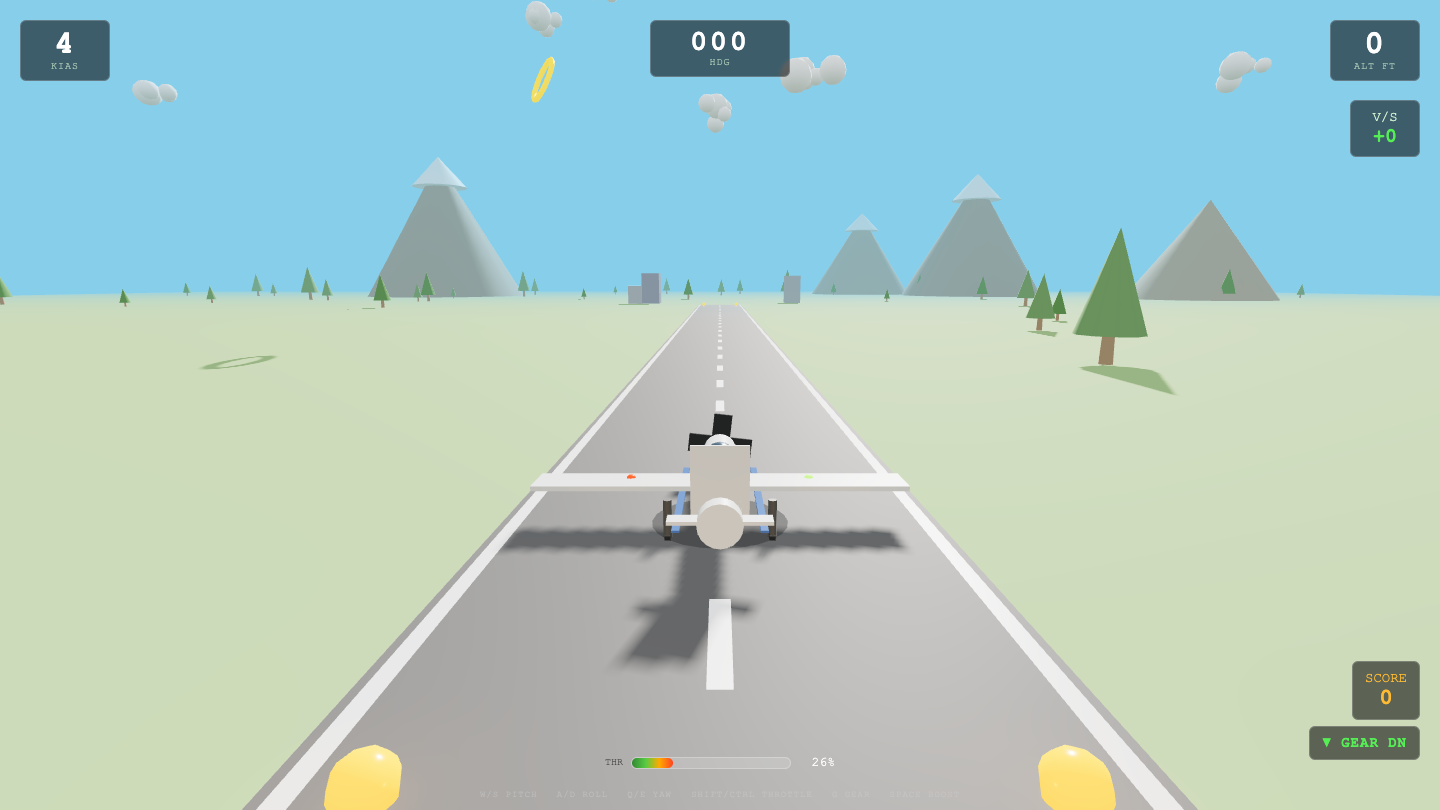
Game
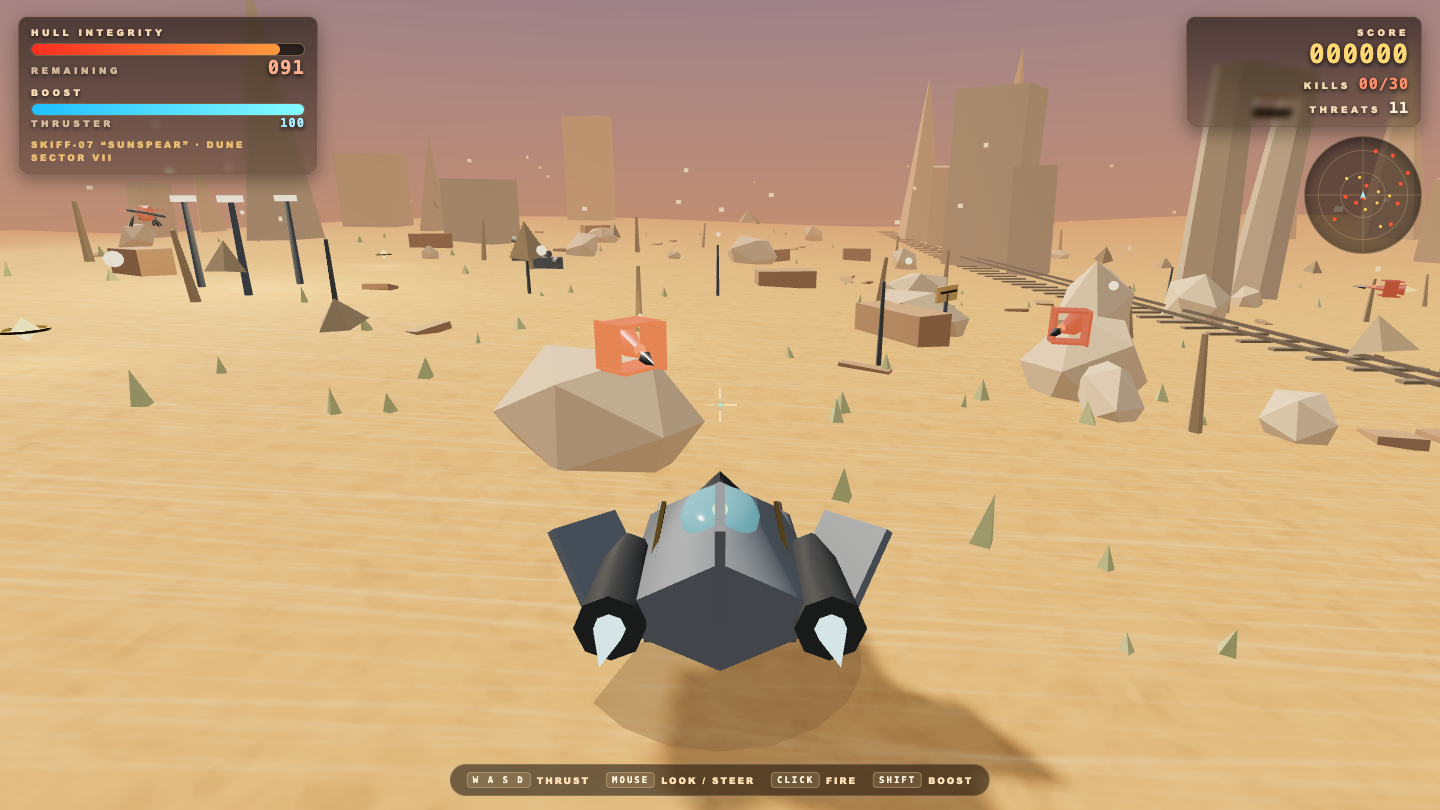
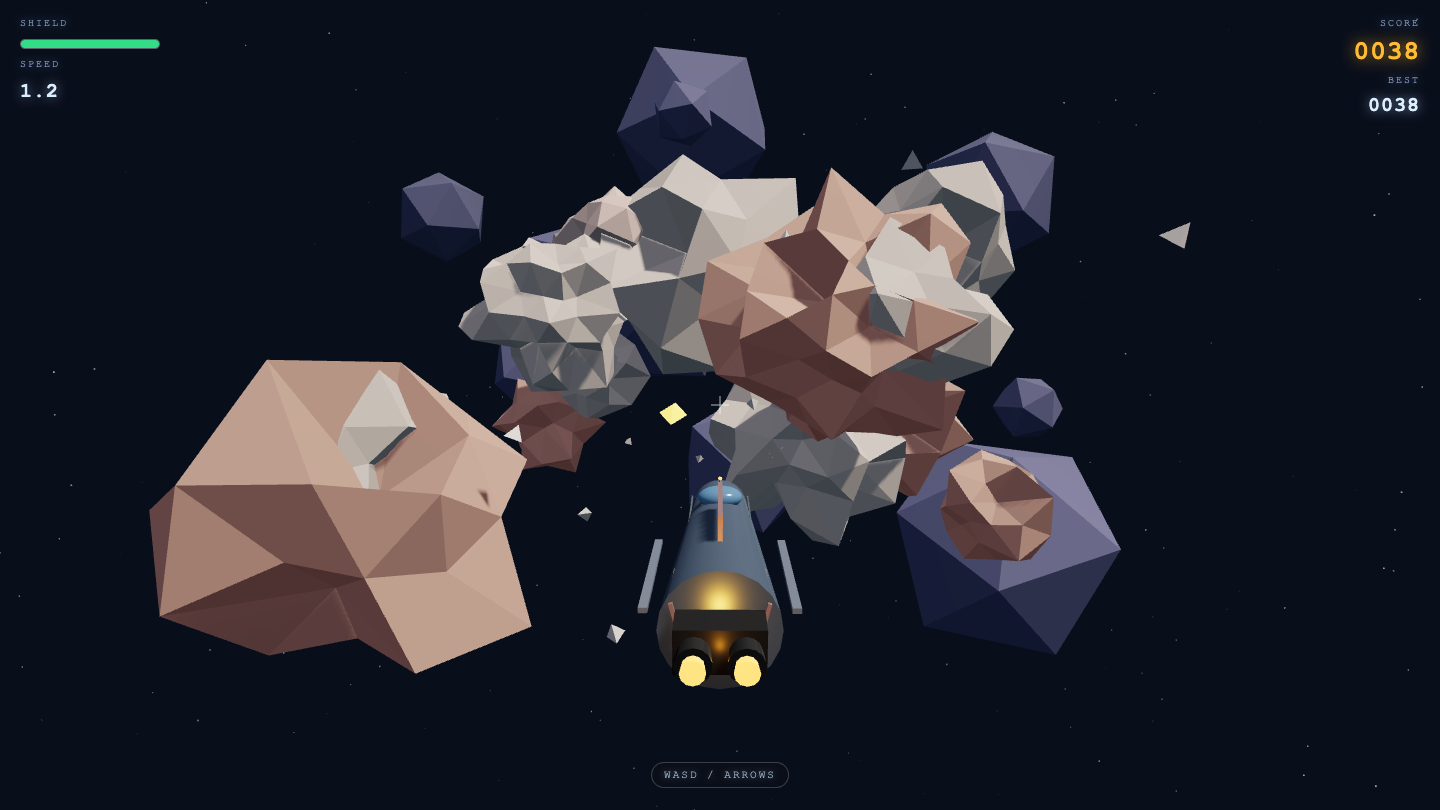
Game
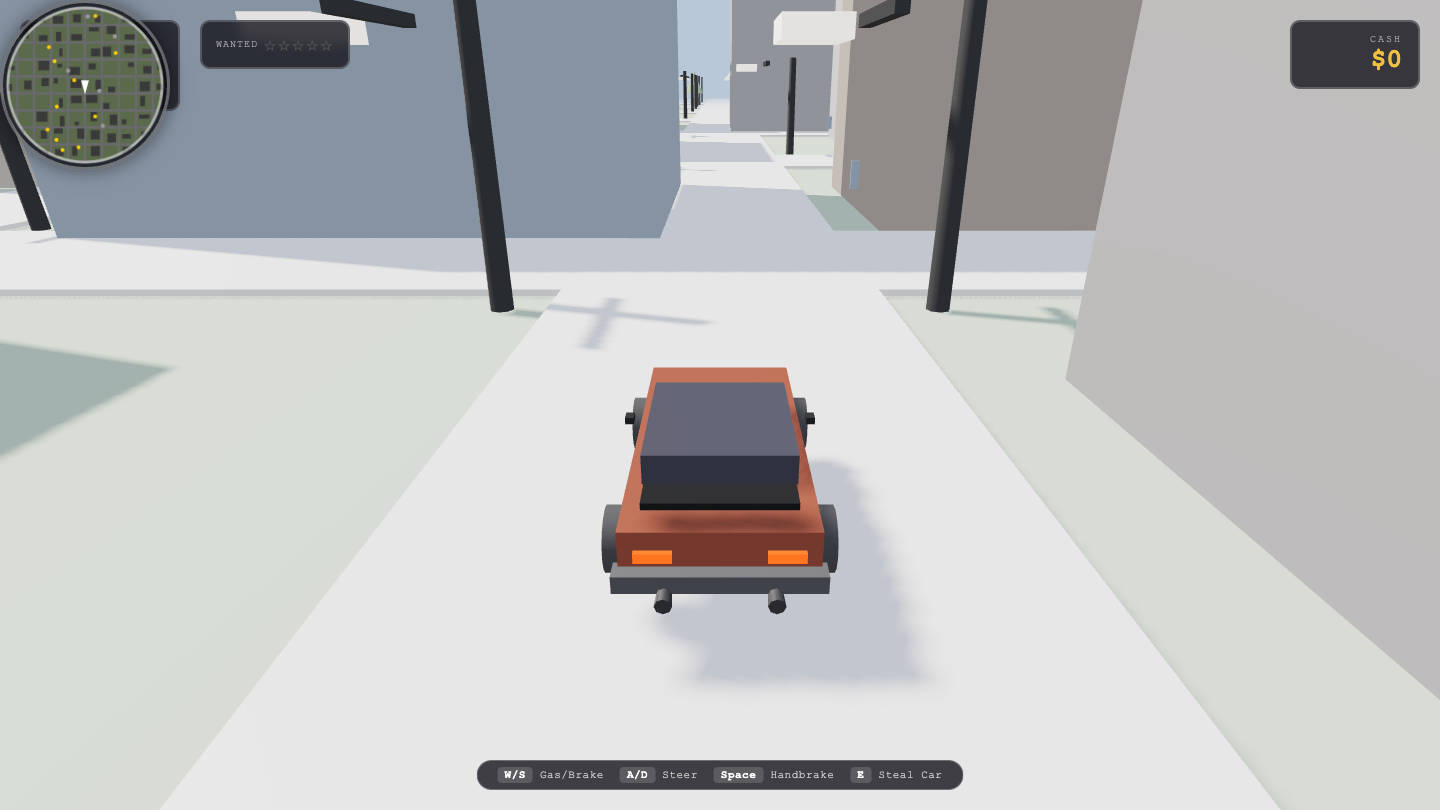
Game
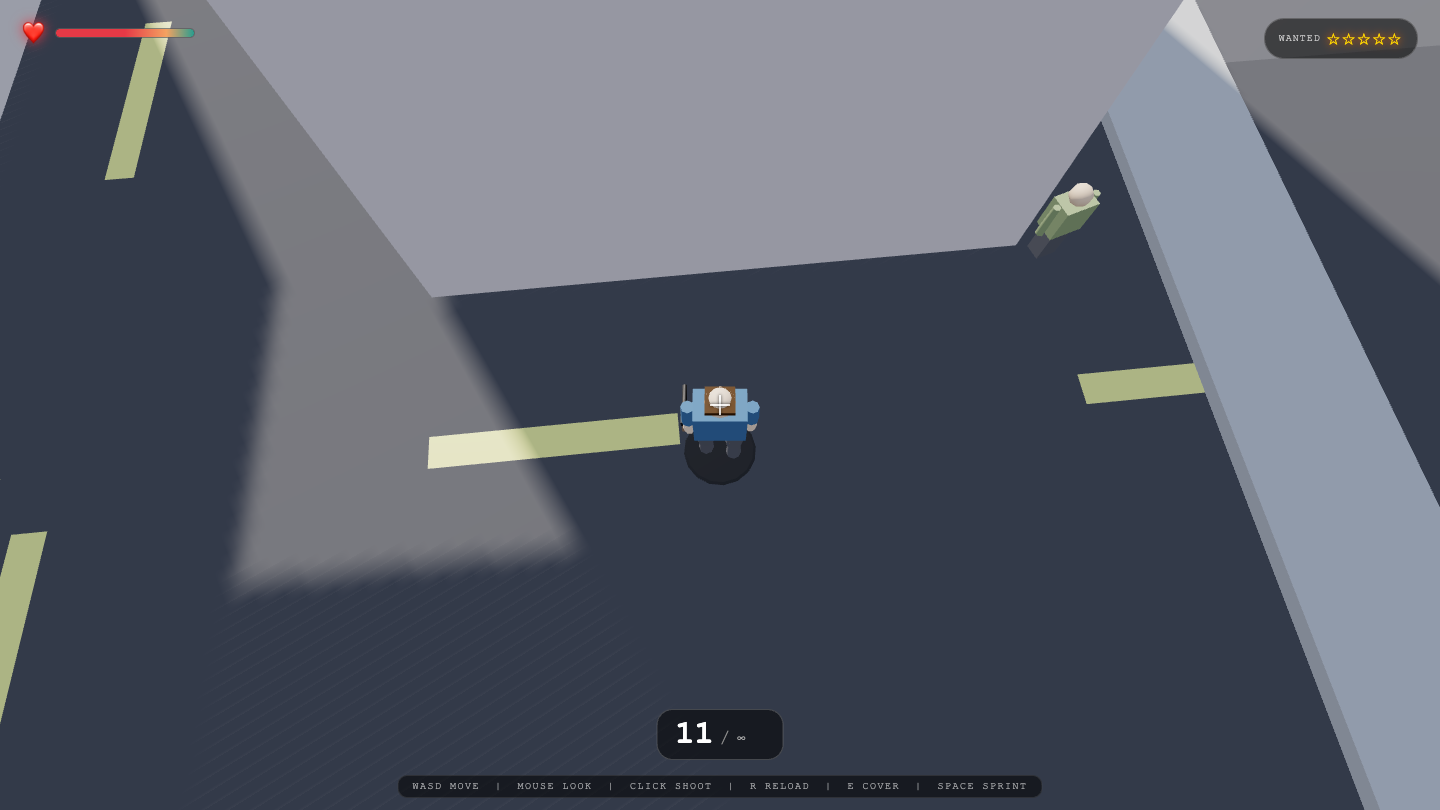
Game
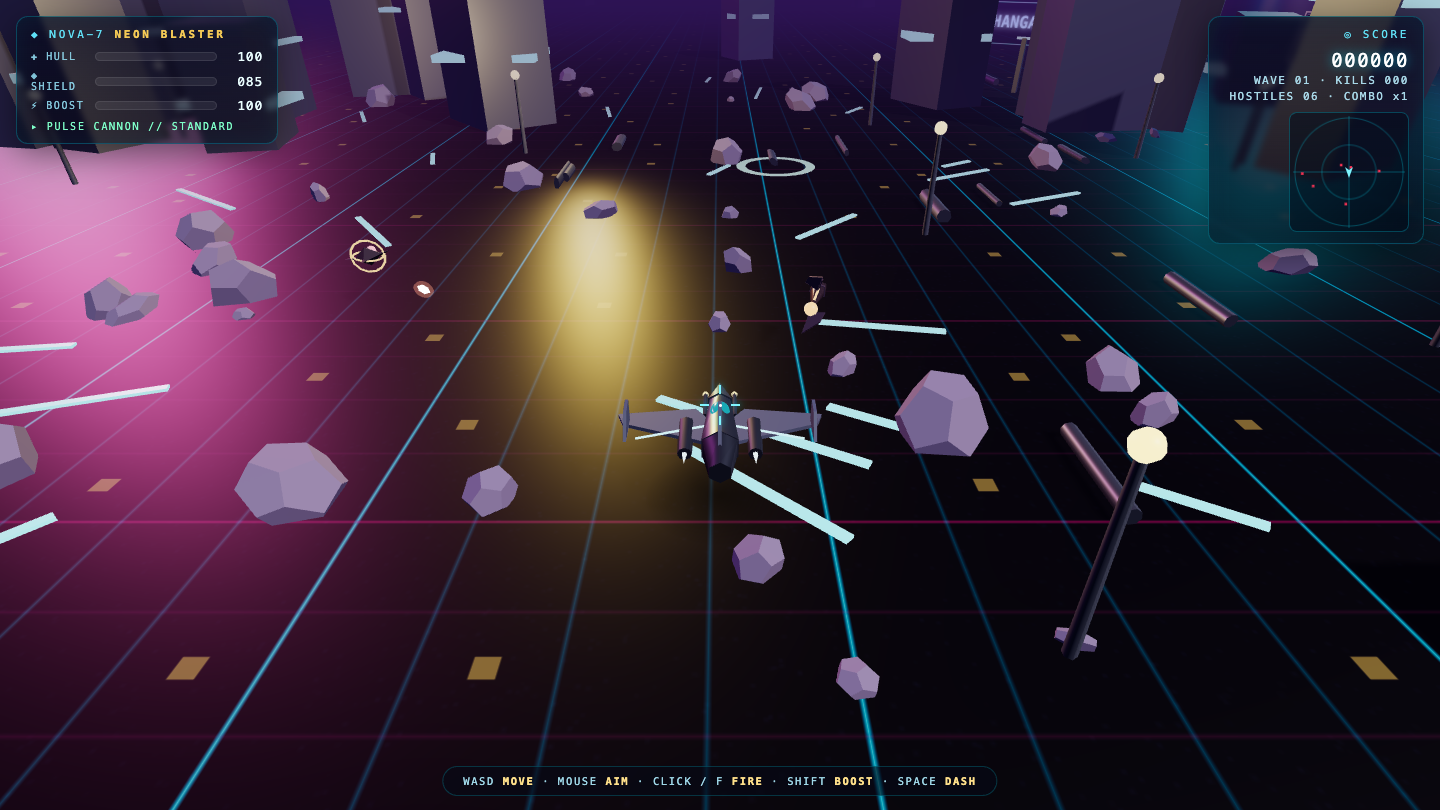
Game
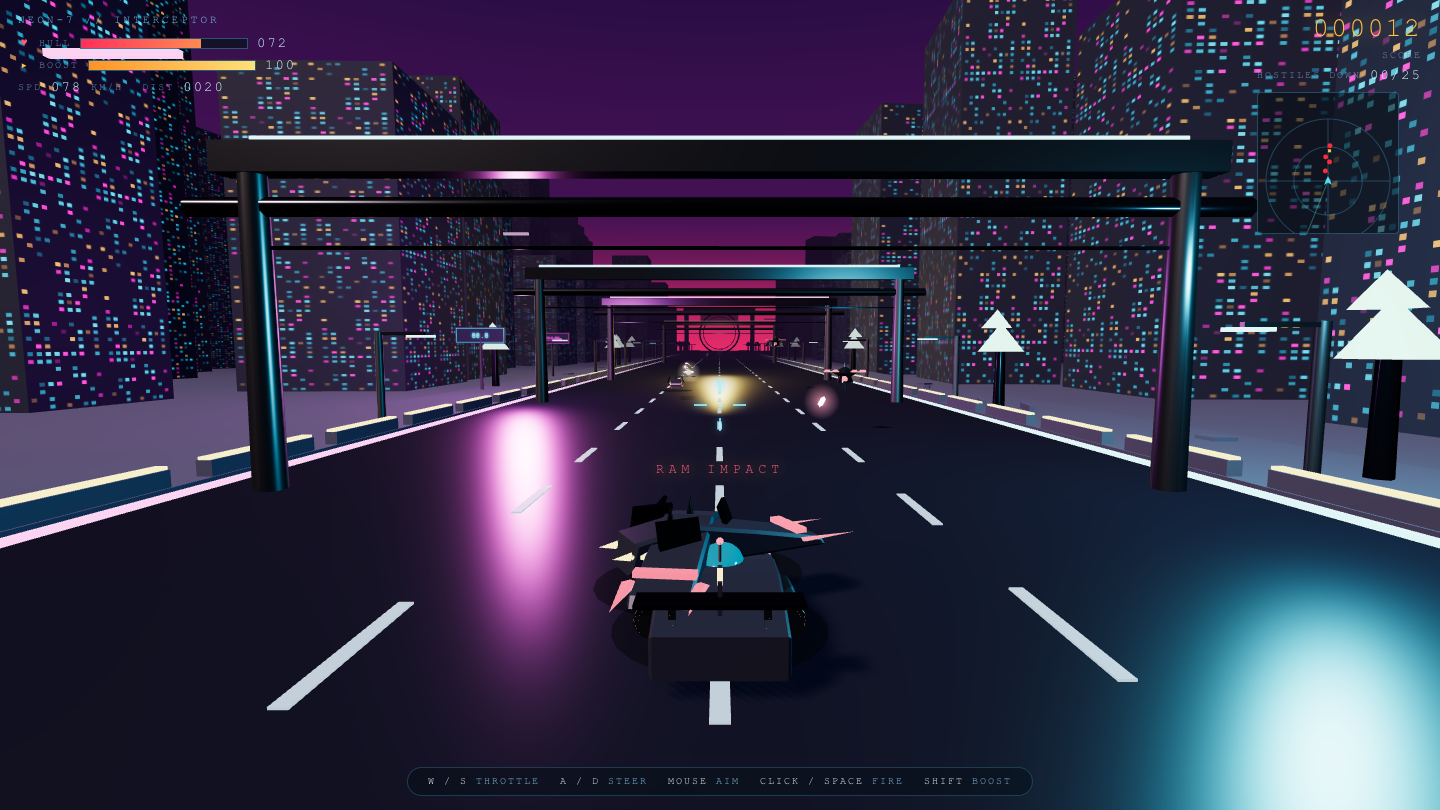
Game
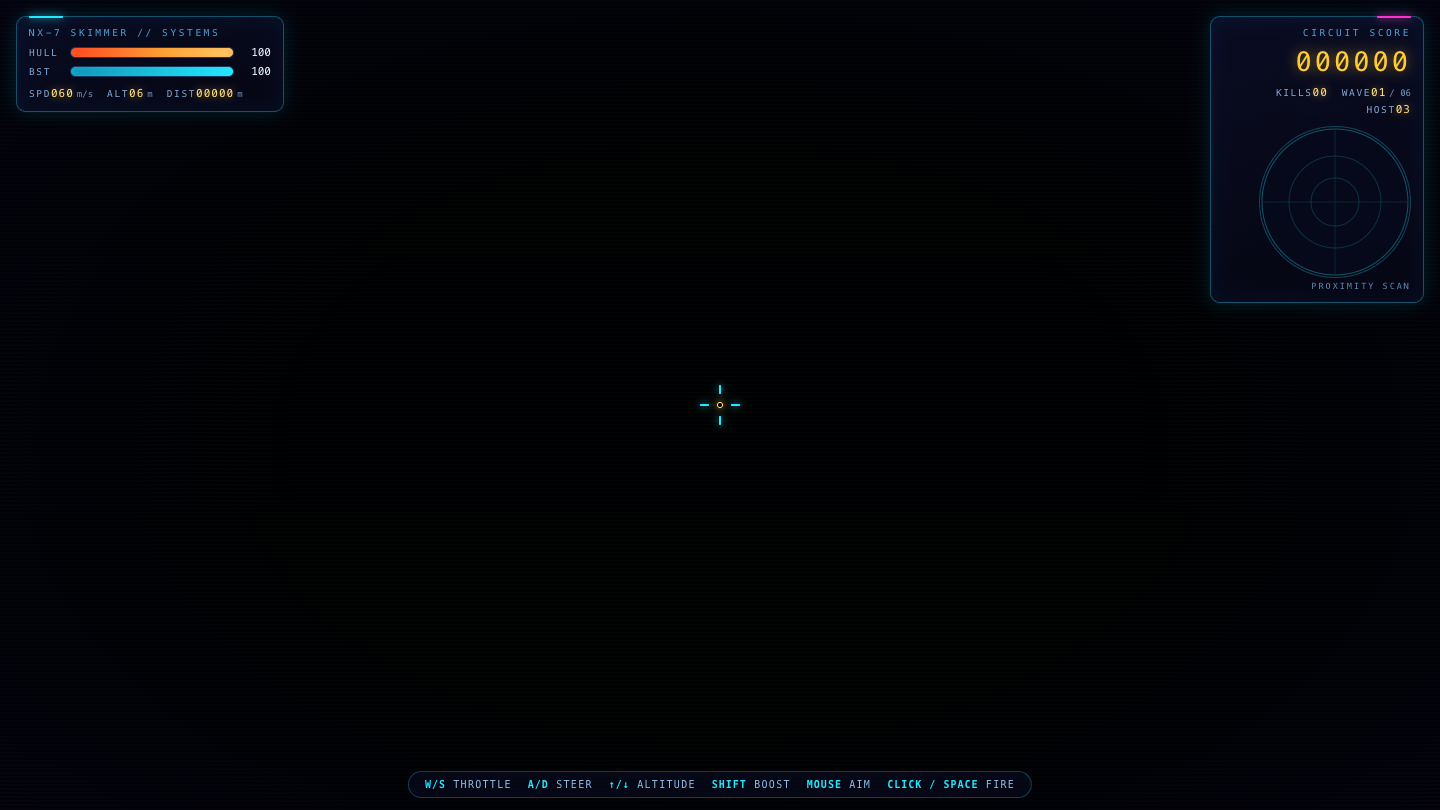
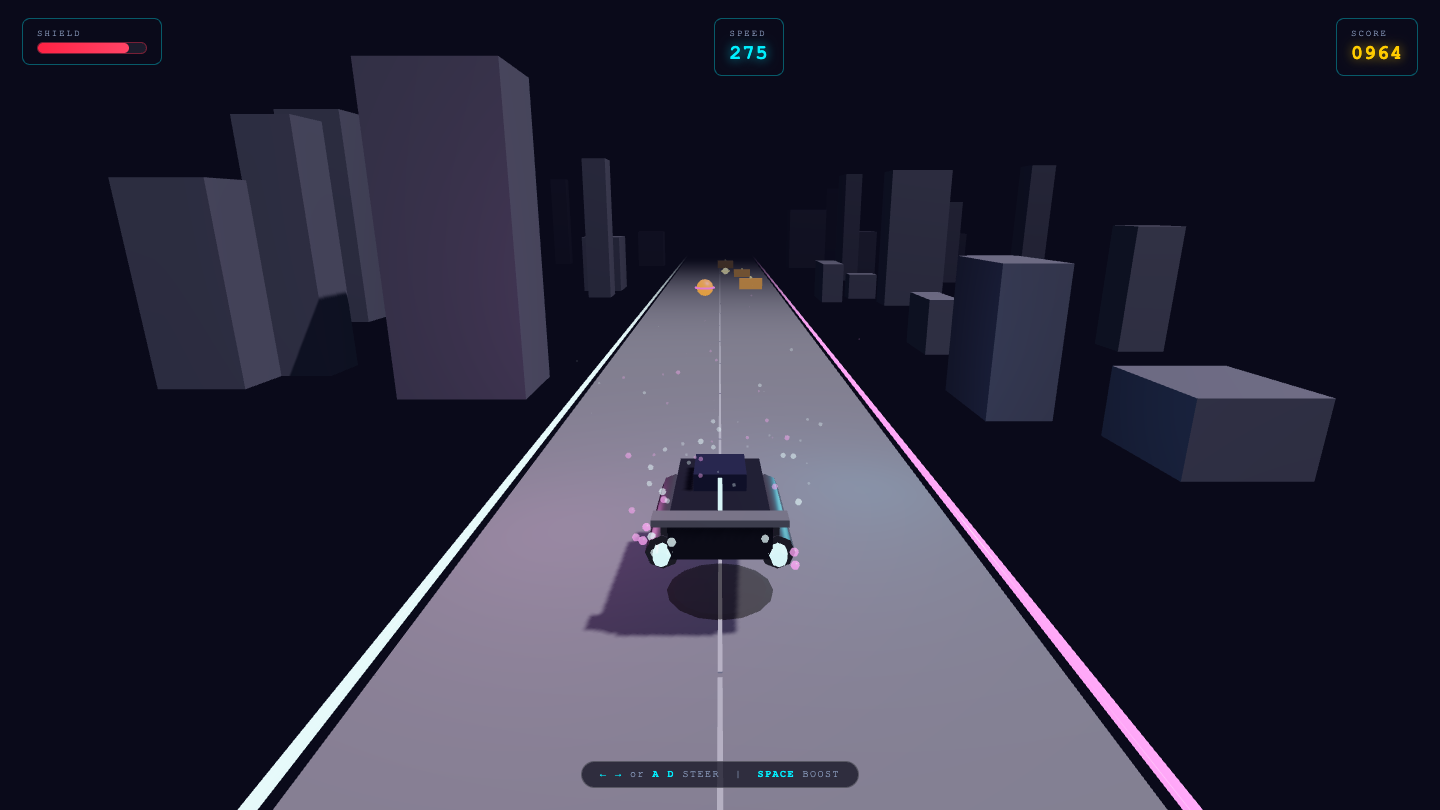
Game
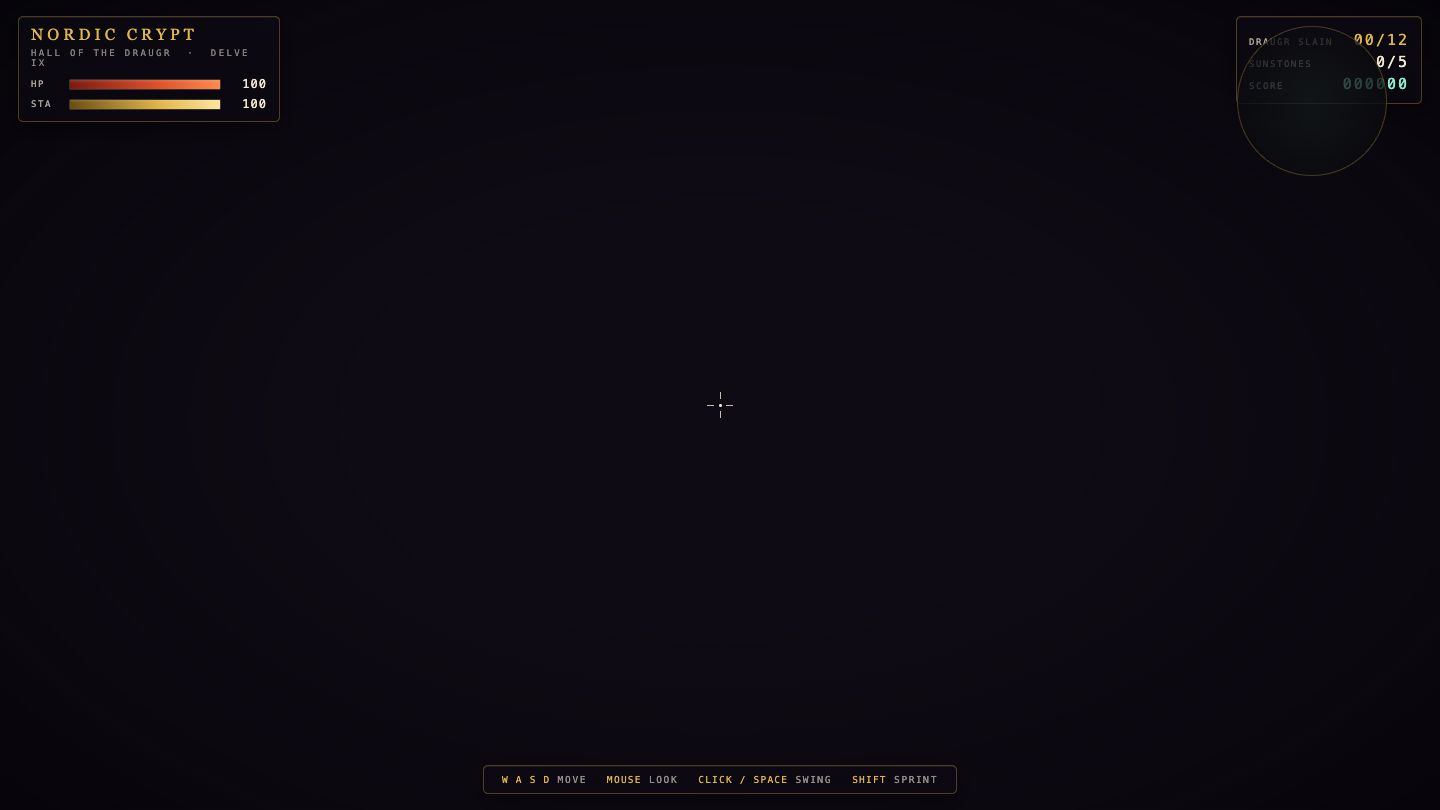
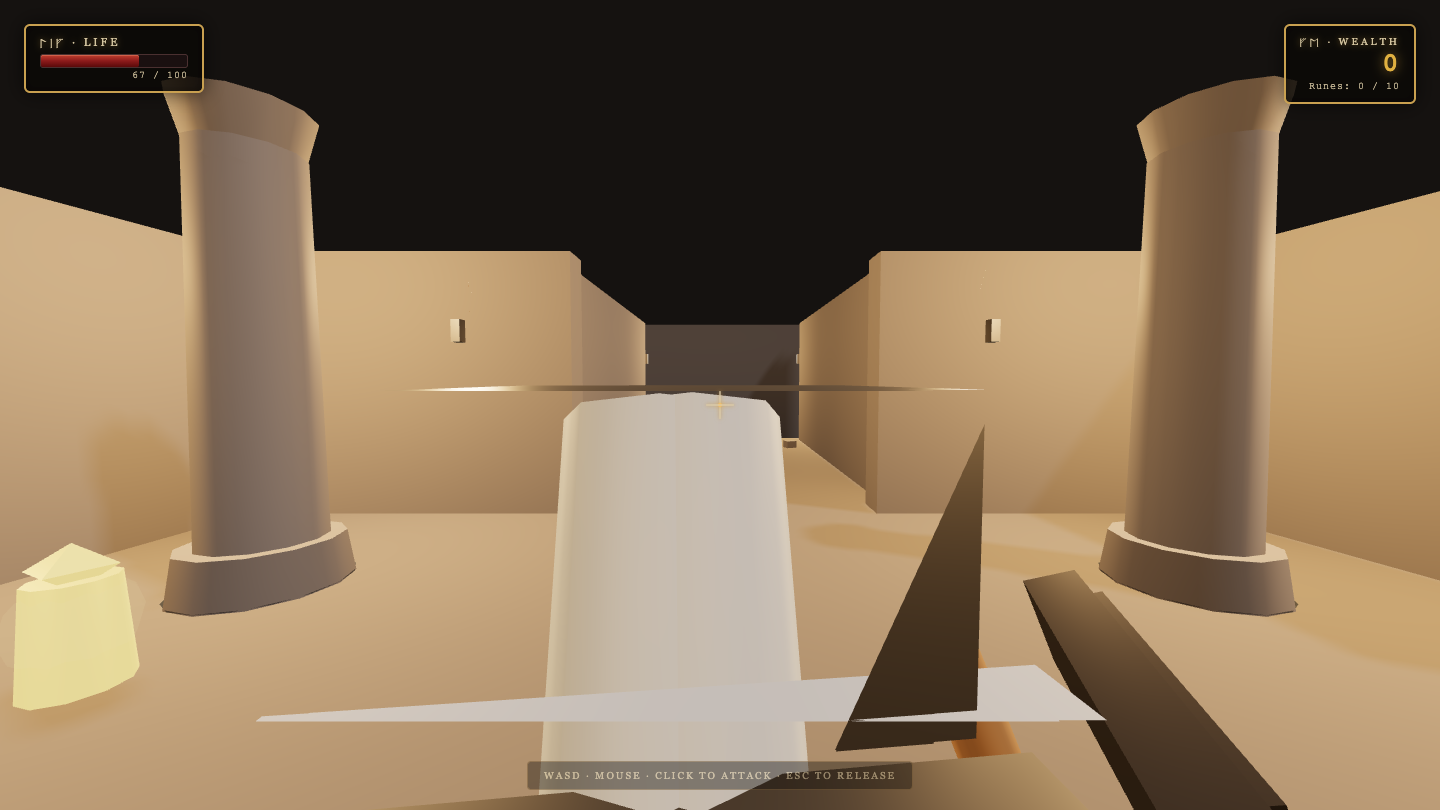
Game
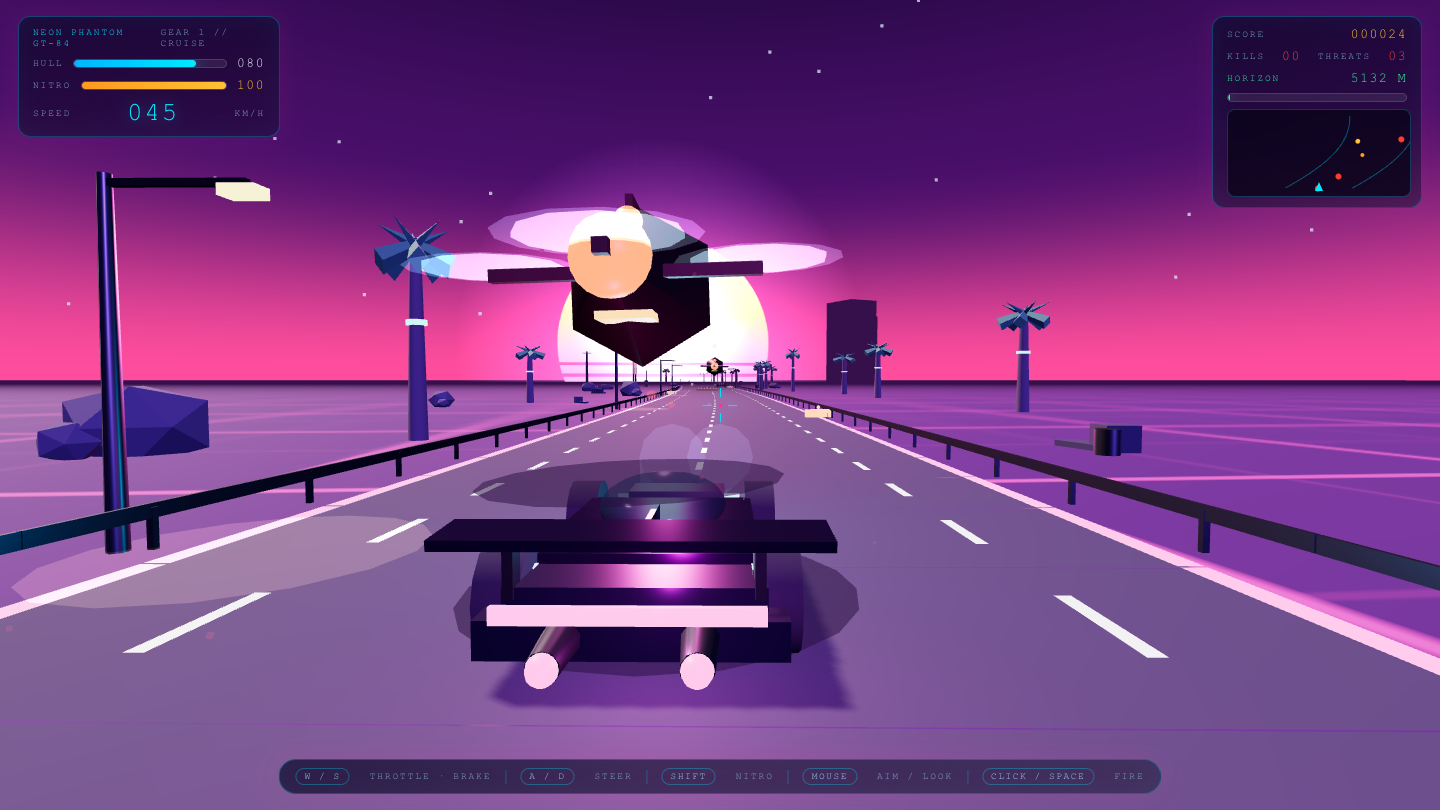
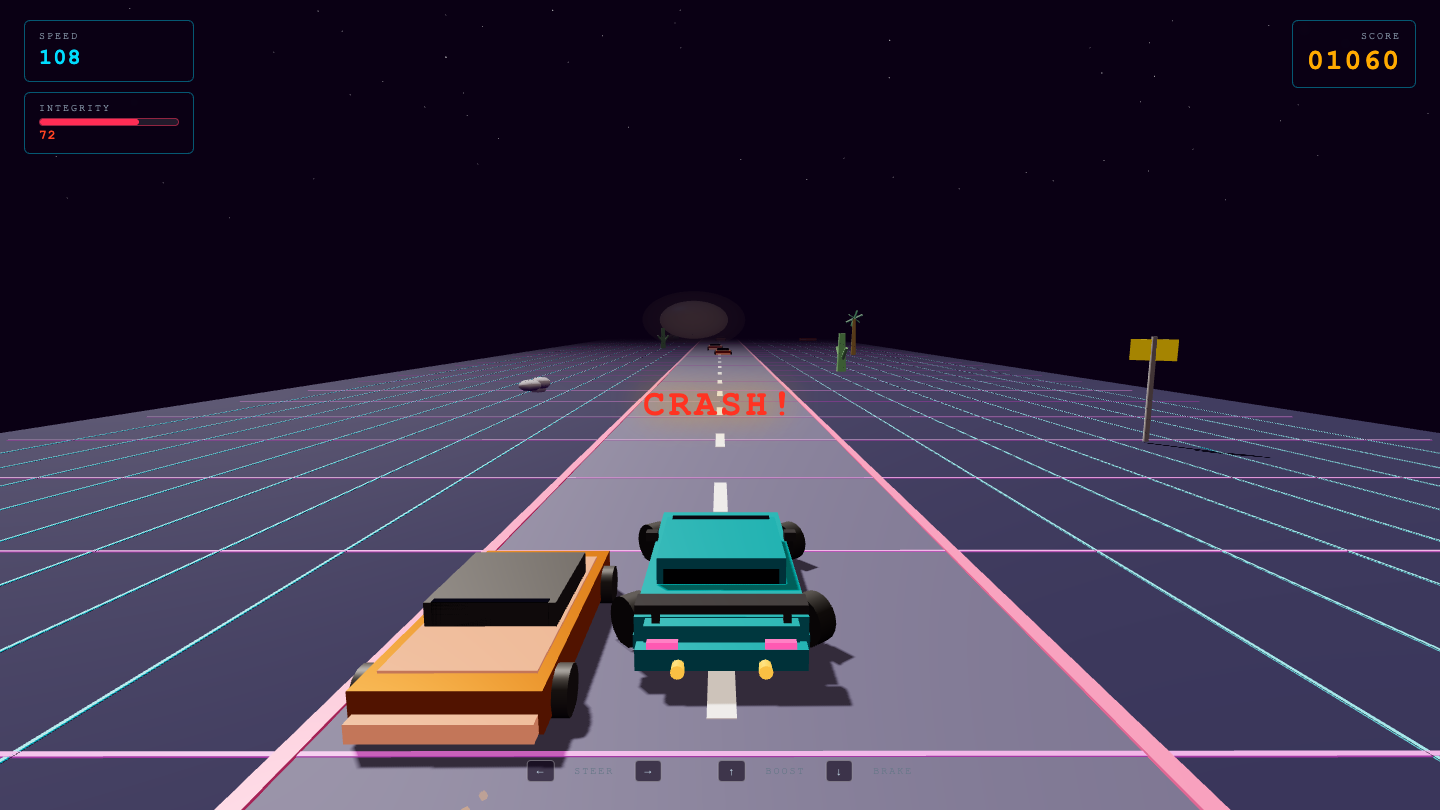
Game
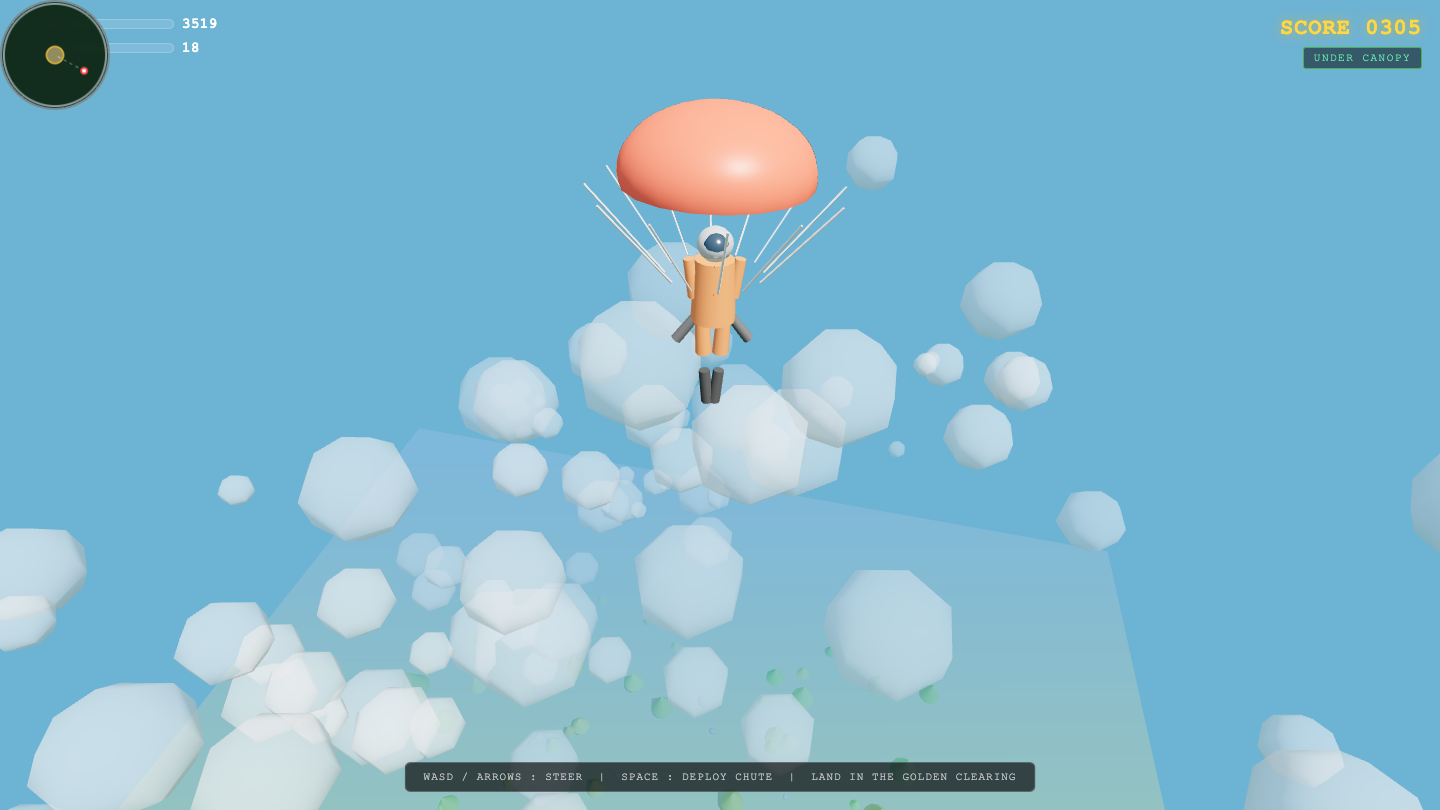
Game
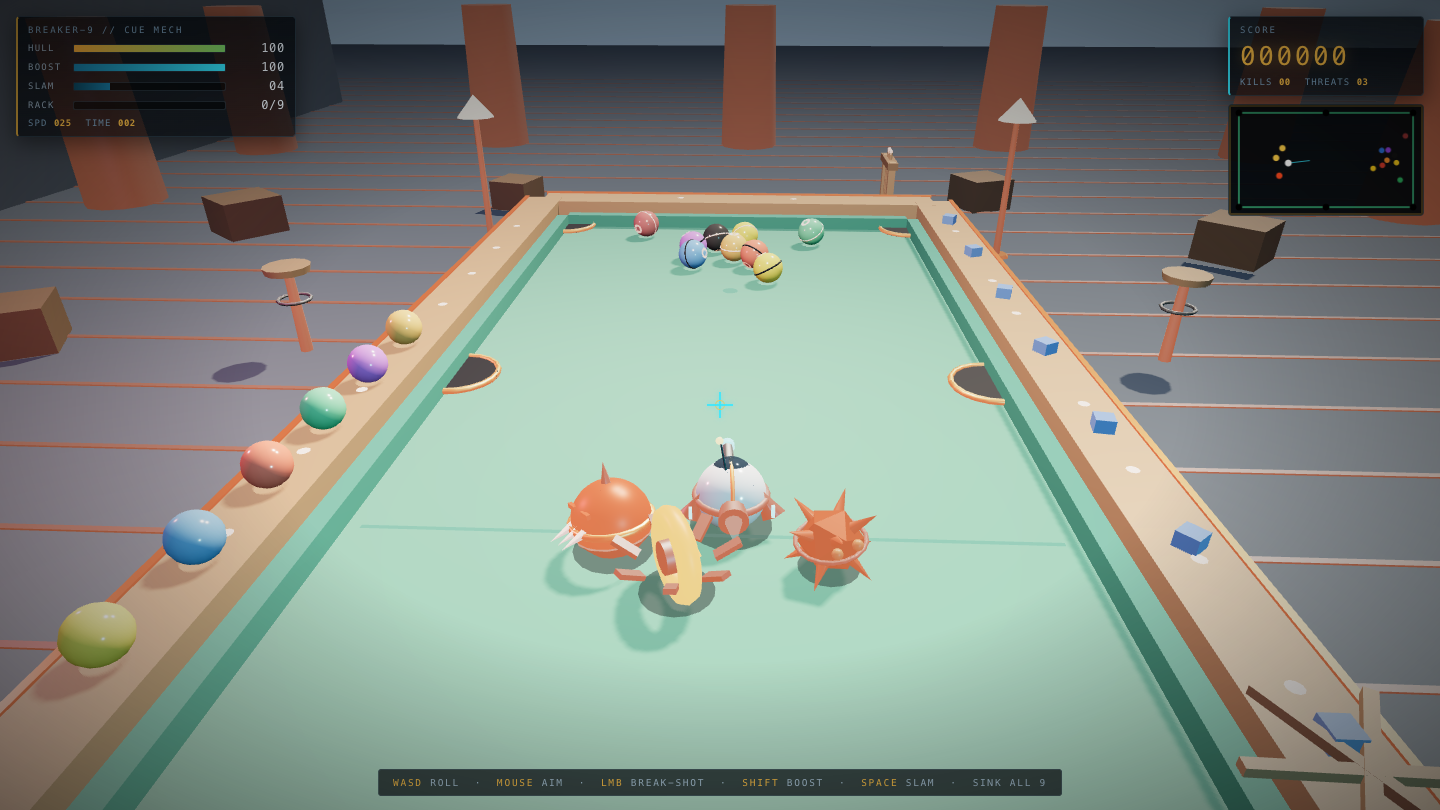
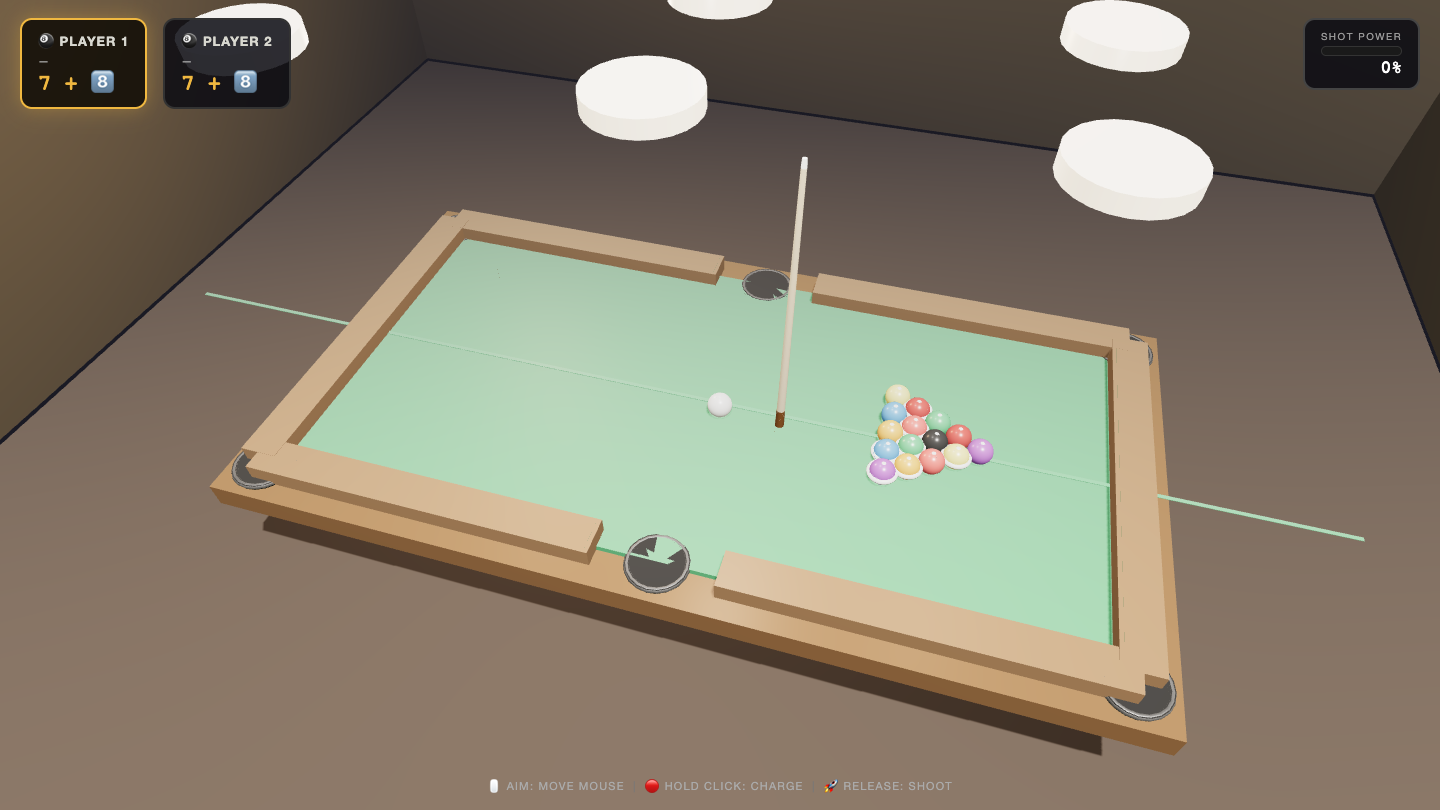
Game
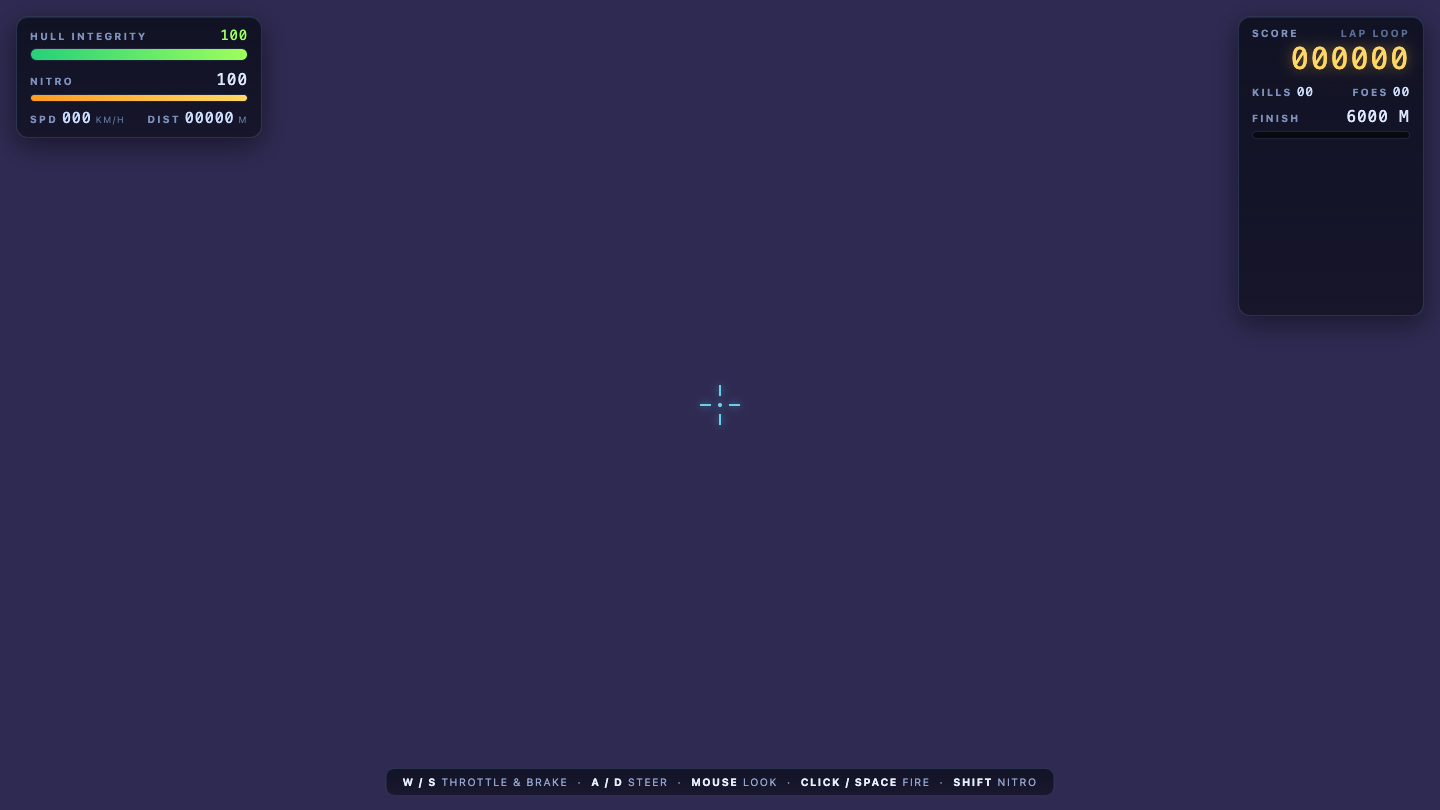
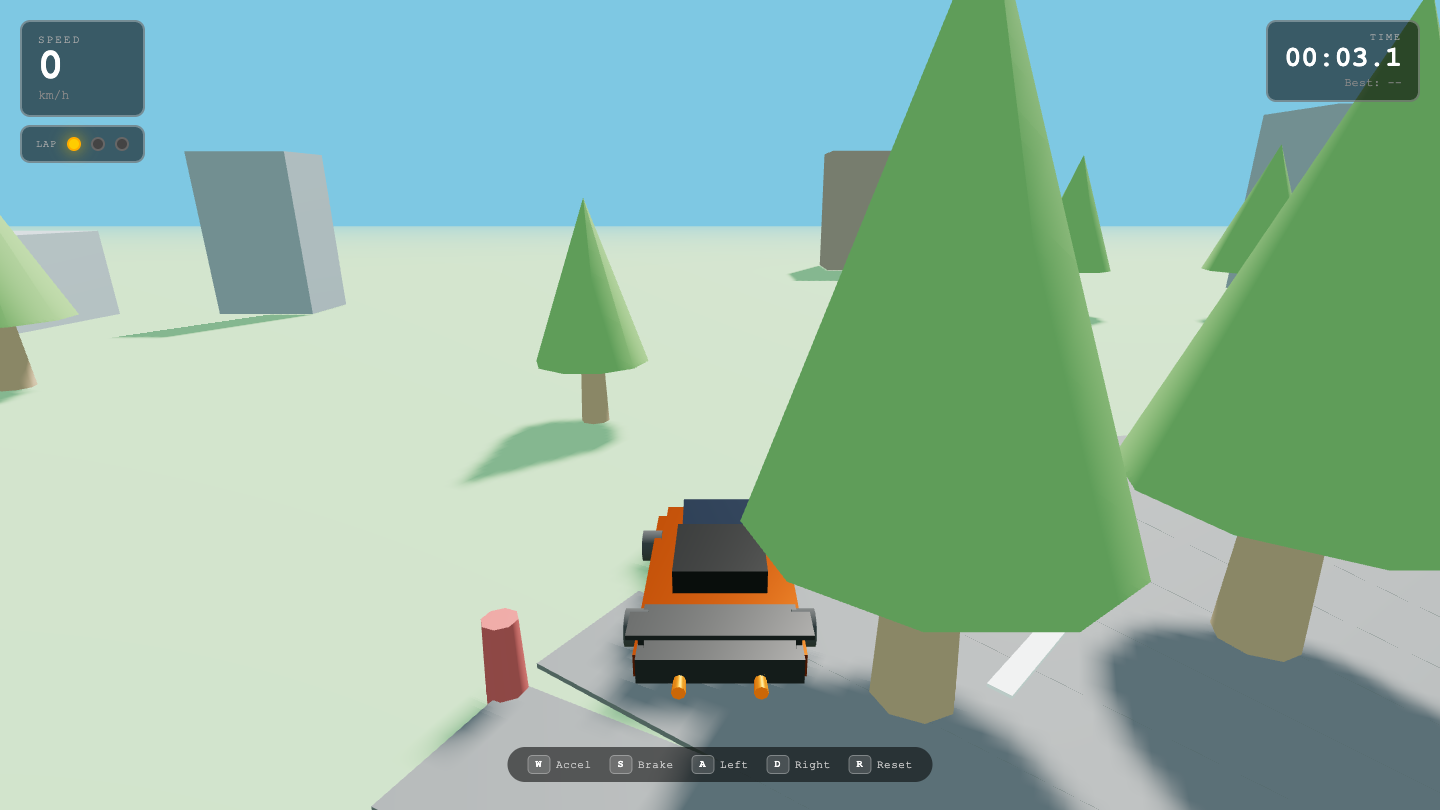
Game
Game
Game
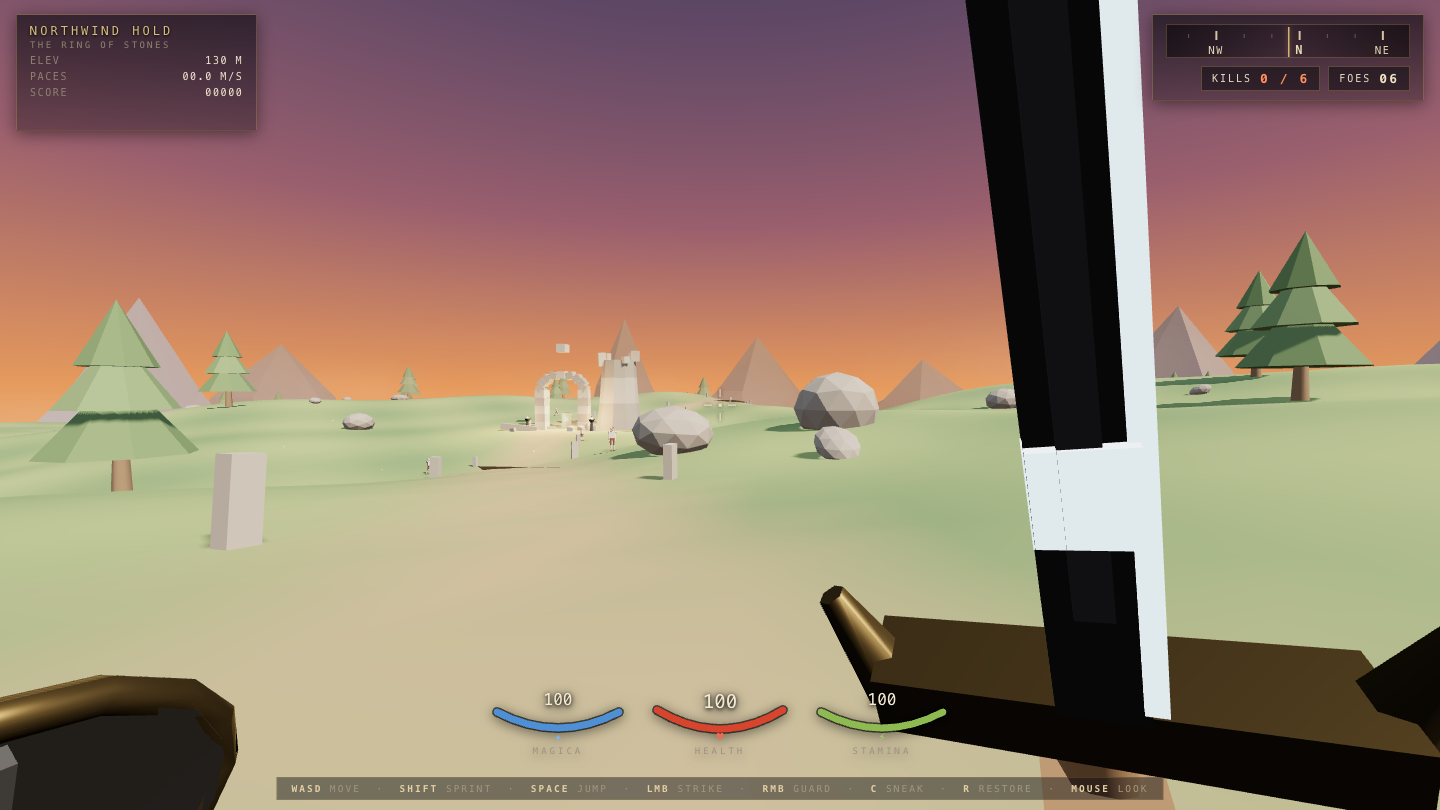
Game
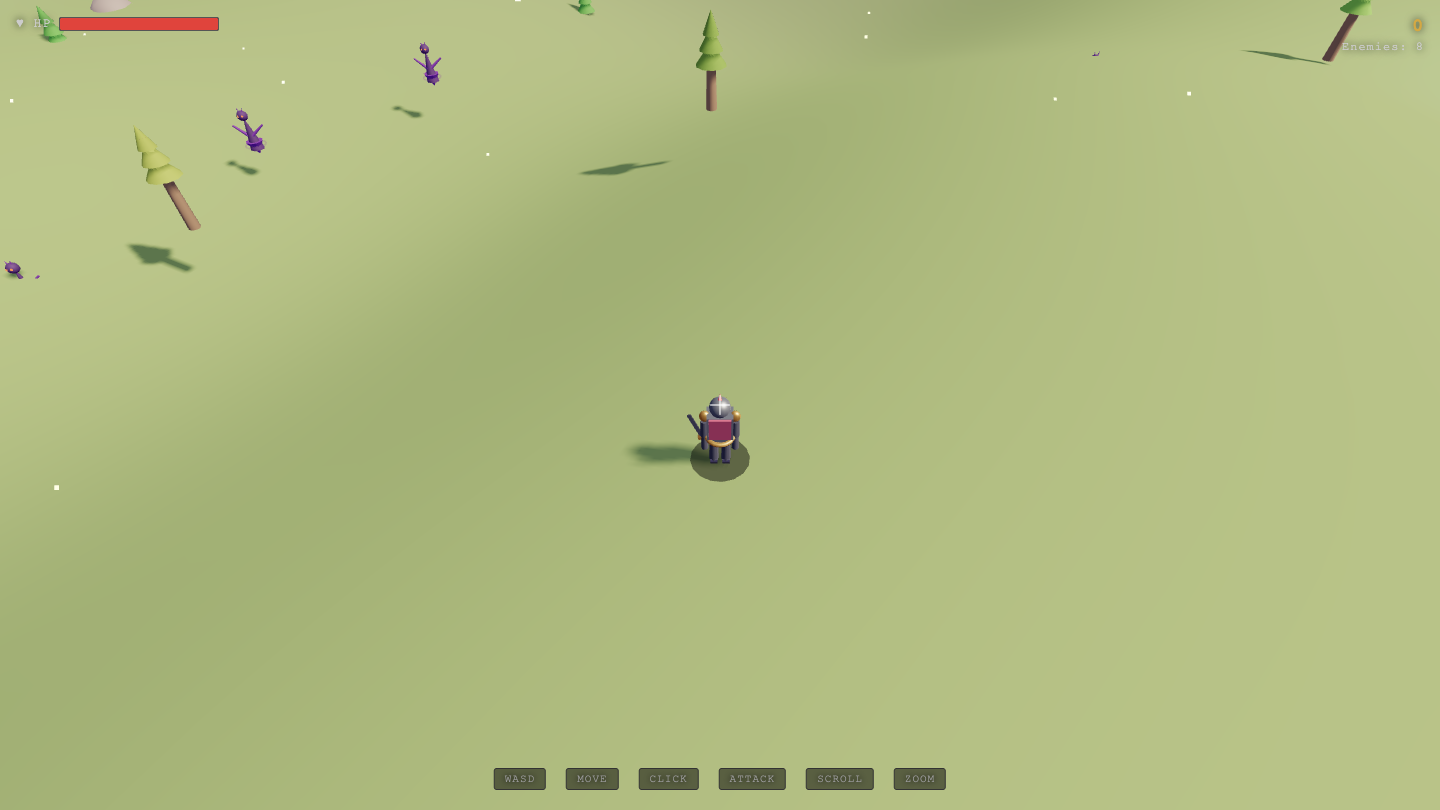
Game
Other
Strengths & weaknesses I logged
MiMo-V2.6 Pro
Strengths
- Simulations and visual pieces are top-tier one-shots: the black hole lensing scored 9.0 and the matrix rain, lava lamp, ocean waves, web desktop, boids and galaxy all landed 8.6 or higher
- Strong flight and driving output when the build holds together: a polished 3D dogfight (8.6), a flight sim (8.4) and the synthwave outrun (8.4)
- Big, complete files: builds ran 30 to 70 KB with full HUDs, control hints and settings panels
- The weights are MIT and on Hugging Face, so the same model can run on your own hardware
Trade-offs
- 18 of 50 builds scored under 5: long game files shipped with garbled tokens (a stray 'martin' or 'martial' identifier breaks the whole script), uninitialised references and bad canvas values, so the HUD paints but the 3D scene stays black
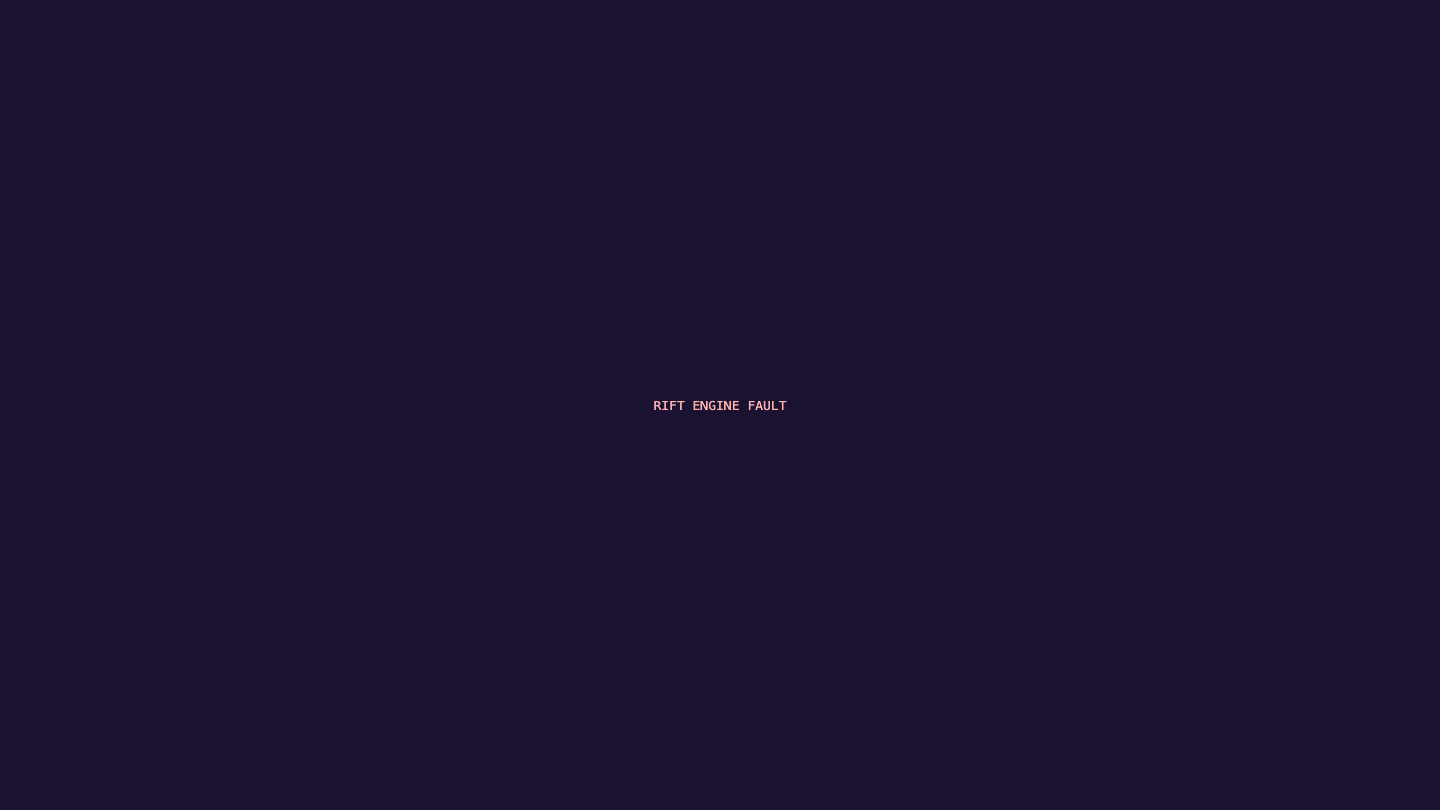
- Two hard crashes: the RPG threw an engine fault on load and the solar system rendered nothing at all
- It reasons for a long time at default effort: builds took 5 to 60 minutes each through OpenRouter
DeepSeek V4 Pro
Strengths
- Flagship reasoning tier on the same official API and 1M context as Flash
- Ran the identical 50-prompt set as V4 Flash 0731 — a clean same-vendor A/B
- Reasoning-first: thinks before writing every build
Trade-offs
- Unranked — builds are on the bench but not yet scored by the Opus vision judge
- Slower and pricier per build than Flash — the whole question is whether that buys quality
Pricing & context — the spec sheet
| Spec | MiMo-V2.6 Pro | DeepSeek V4 Pro |
|---|---|---|
| Vendor | Xiaomi | DeepSeek |
| Context window | 1,000,000 tokens | 1,000,000-token context window |
| Price | $0.435 in / $0.87 out per M tokens | API · pro tier |
| Pricing detail | Xiaomi's September 2026 open-weight flagship (MIT licence, 1.02T total / 42B active parameters). $0.435 per million input tokens and $0.87 per million output on OpenRouter, with cache hits at a fraction of a cent, which is roughly a quarter of Grok 4.7 and a twentieth of the closed frontier models it scores level with on agent benchmarks. | DeepSeek's flagship tier, benched on `deepseek-v4-pro` via api.deepseek.com — the exact same 50 one-shot prompts, skill-infused game prompt and pipeline as the V4 Flash 0731 run, so the two runs are directly comparable side by side. DeepSeek's own line on the 0731 Flash refresh is that its post-training now beats the older V4-Pro-Preview — this run tests the current Pro against that claim. |
| Release | 2026-09 | 2026-07 |
| Bench coverage | 50/50 scored · avg 6.35/10 | 0/50 scored · avg — |
The verdict — which should you pick?
Not enough scored shared tasks yet for a head-to-head average. The live demos for both are on the matrix above — play them and form your own opinion.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire MiMo-V2.6 Pro and DeepSeek V4 Pro both into the Agent Operating System and dispatch each from the kanban by task type — simulations, shaders and visual scenes in one shot, at a fraction of frontier prices → MiMo-V2.6 Pro, checking whether deepseek's pro tier is worth the premium over flash 0731 → DeepSeek V4 Pro. That's the same setup I run for the 4,000+ founders inside the AI Profit Boardroom.
FAQ — MiMo-V2.6 Pro vs DeepSeek V4 Pro
Which is better, MiMo-V2.6 Pro or DeepSeek V4 Pro?
On Goldie Bench, MiMo-V2.6 Pro averages no scored verdicts yet across the shared tasks, with 5 gold, 8 silver, 4 bronze overall. DeepSeek V4 Pro averages no scored verdicts yet, with 0 gold, 0 silver, 0 bronze. Not enough scored shared tasks yet to call a winner.
How much does MiMo-V2.6 Pro cost vs DeepSeek V4 Pro?
MiMo-V2.6 Pro: Xiaomi's September 2026 open-weight flagship (MIT licence, 1.02T total / 42B active parameters). $0.435 per million input tokens and $0.87 per million output on OpenRouter, with cache hits at a fraction of a cent, which is roughly a quarter of Grok 4.7 and a twentieth of the closed frontier models it scores level with on agent benchmarks. DeepSeek V4 Pro: DeepSeek's flagship tier, benched on `deepseek-v4-pro` via api.deepseek.com — the exact same 50 one-shot prompts, skill-infused game prompt and pipeline as the V4 Flash 0731 run, so the two runs are directly comparable side by side. DeepSeek's own line on the 0731 Flash refresh is that its post-training now beats the older V4-Pro-Preview — this run tests the current Pro against that claim.
What's the context window for MiMo-V2.6 Pro vs DeepSeek V4 Pro?
MiMo-V2.6 Pro has a 1,000,000 tokens context window. DeepSeek V4 Pro has a 1,000,000-token context window context window.
When should I pick MiMo-V2.6 Pro over DeepSeek V4 Pro?
Pick MiMo-V2.6 Pro for: Simulations, shaders and visual scenes in one shot, at a fraction of frontier prices; High-volume agent work where an open, MIT-licensed model matters; Pair it with a self-fix loop for games: the failures are single broken tokens, not missing ideas. The trade-off is the weaknesses we logged on the bench: 18 of 50 builds scored under 5: long game files shipped with garbled tokens (a stray 'martin' or 'martial' identifier breaks the whole script), uninitialised references and bad canvas values, so the HUD paints but the 3D scene stays black; Two hard crashes: the RPG threw an engine fault on load and the solar system rendered nothing at all; It reasons for a long time at default effort: builds took 5 to 60 minutes each through OpenRouter.
When should I pick DeepSeek V4 Pro over MiMo-V2.6 Pro?
Pick DeepSeek V4 Pro for: Checking whether DeepSeek's pro tier is worth the premium over Flash 0731; Hard single-shot builds where extra reasoning depth may pay off. The trade-off is the weaknesses we logged on the bench: Unranked — builds are on the bench but not yet scored by the Opus vision judge; Slower and pricier per build than Flash — the whole question is whether that buys quality.
How does Goldie Bench score MiMo-V2.6 Pro vs DeepSeek V4 Pro?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
MiMo-V2.6 Pro vs Fusion DeepSeek V4 Pro vs Fusion MiMo-V2.6 Pro vs Claude Opus 5 DeepSeek V4 Pro vs Claude Opus 5 MiMo-V2.6 Pro vs Hermes MoA DeepSeek V4 Pro vs Hermes MoA MiMo-V2.6 Pro vs GPT-5.6 Sol DeepSeek V4 Pro vs GPT-5.6 SolFull model pages: MiMo-V2.6 Pro · DeepSeek V4 Pro · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.
4,000+founders
258documented wins
38countries
$59/momonthly