Real head-to-head · same prompt, one shot
GLM-5.2 vs Claude Opus 5.5
The never-forgets agent — 1M context, open weights. vs Anthropic's Opus 5.5 — benched on all 50 one-shot builds, every game playtested.
Head-to-head verdict: Claude Opus 5.5 wins 22–21 with 4 ties.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to GLM-5.2 and Claude Opus 5.5, side by side, on 47 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
GLM-5.2 · Default model inside Agent OS for any task that touches a long context — codebase Q&A, multi-file refactors, agent memory replay.
Claude Opus 5.5 · Benched on all 50 GoldieBench tasks via a Claude subscription: one-shot builds, real renders, pixel-diff playtests on every game, then vision-judged.
Side-by-side on 50 shared tasks
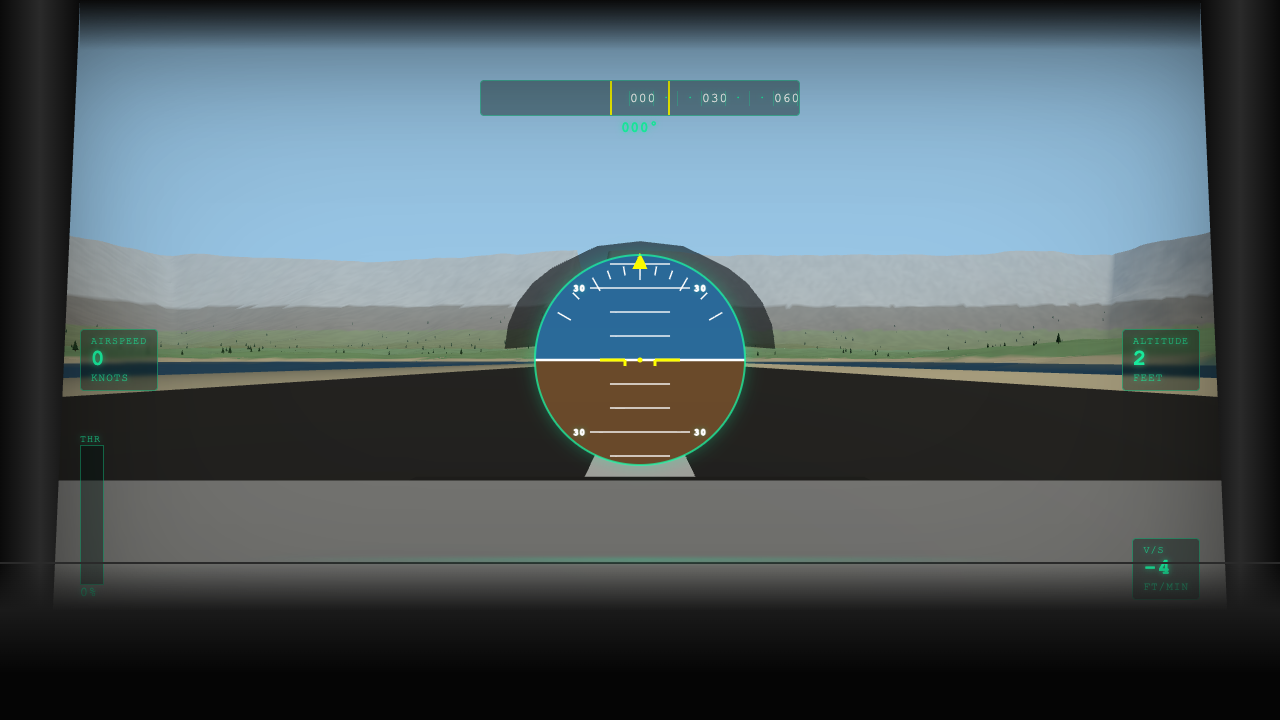
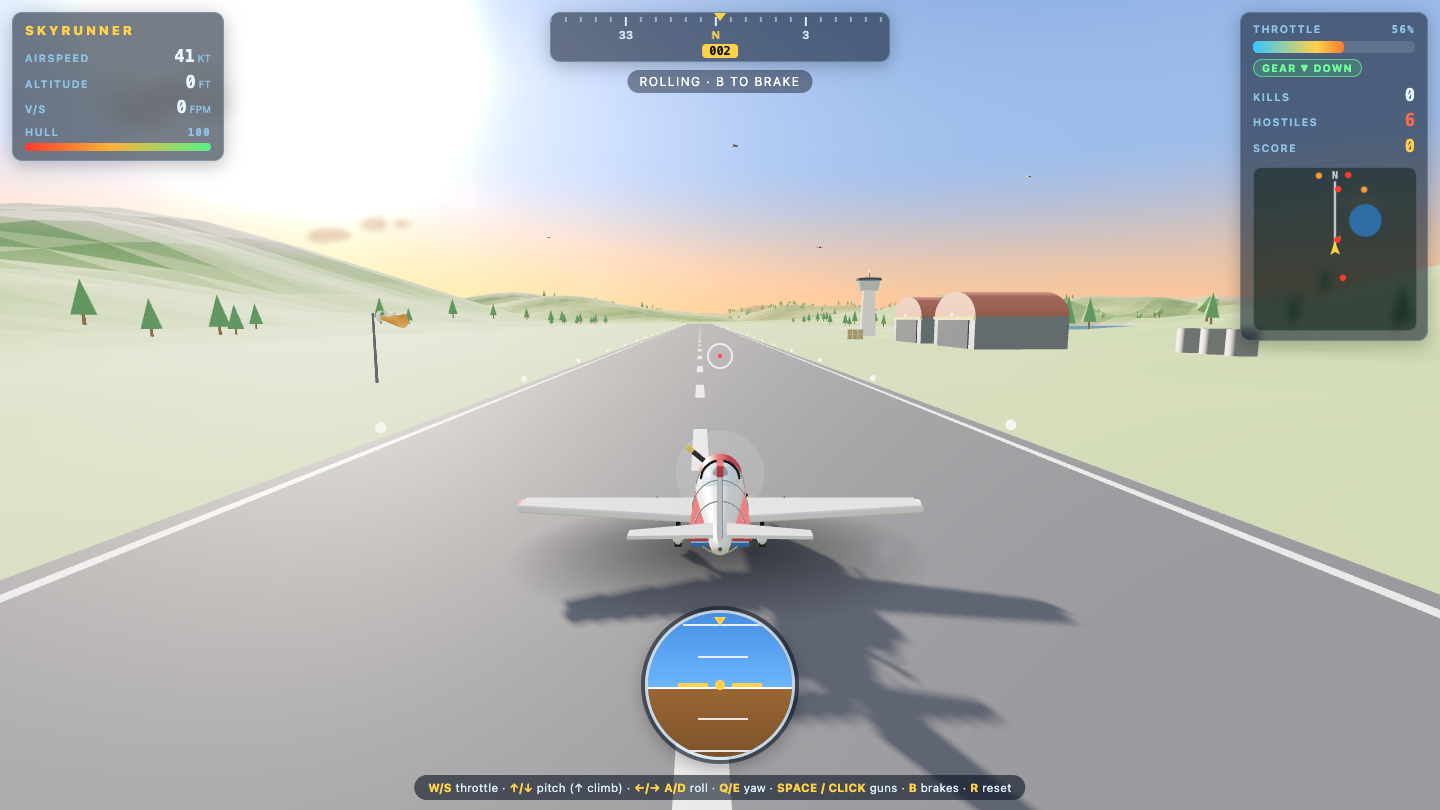
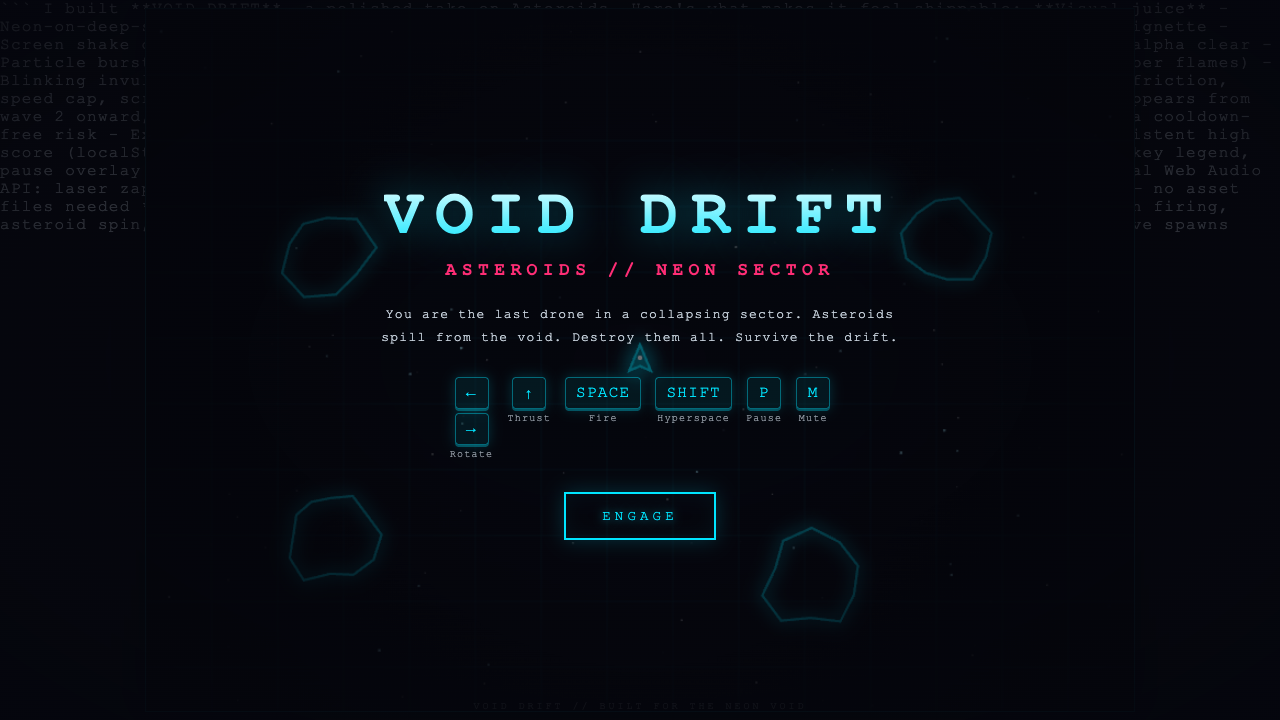
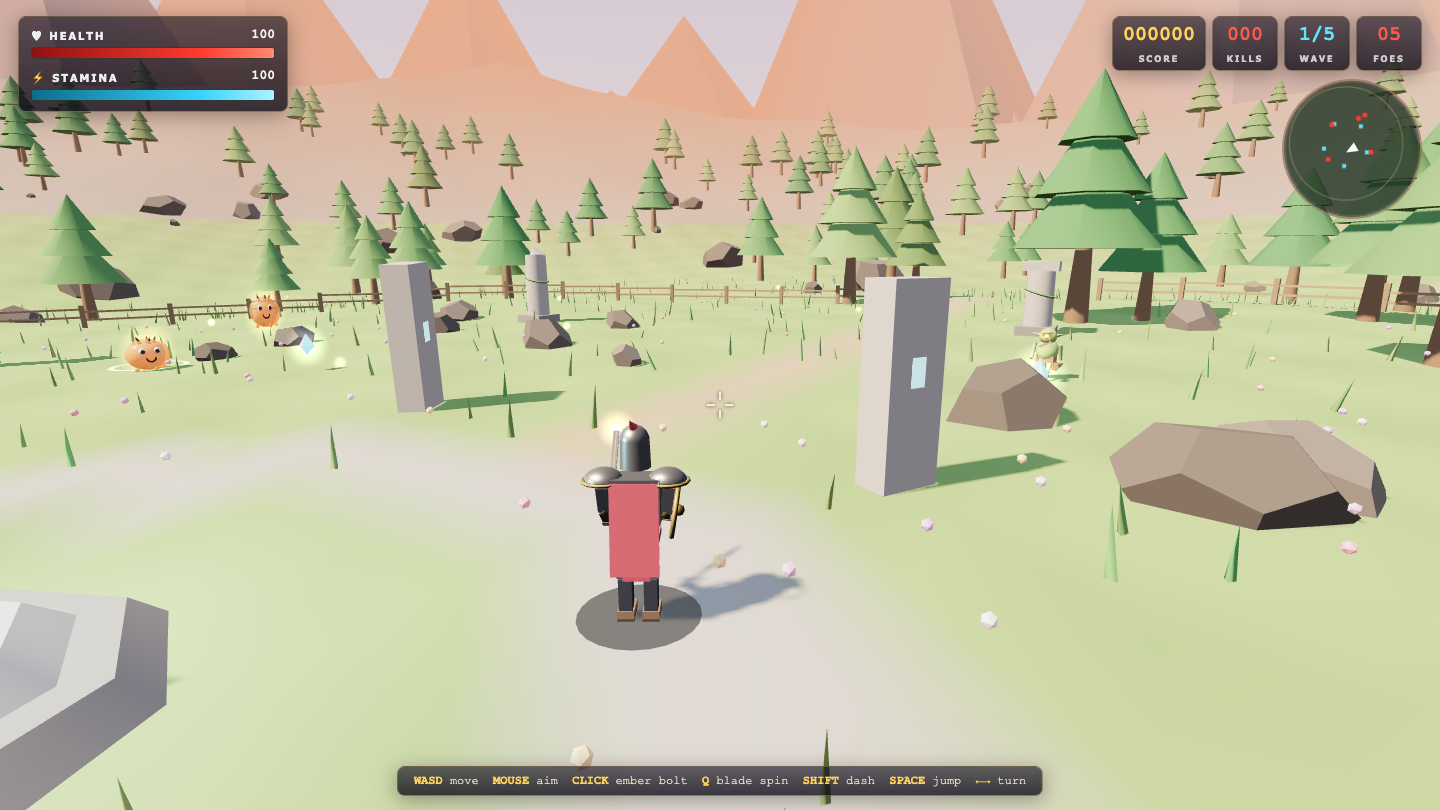
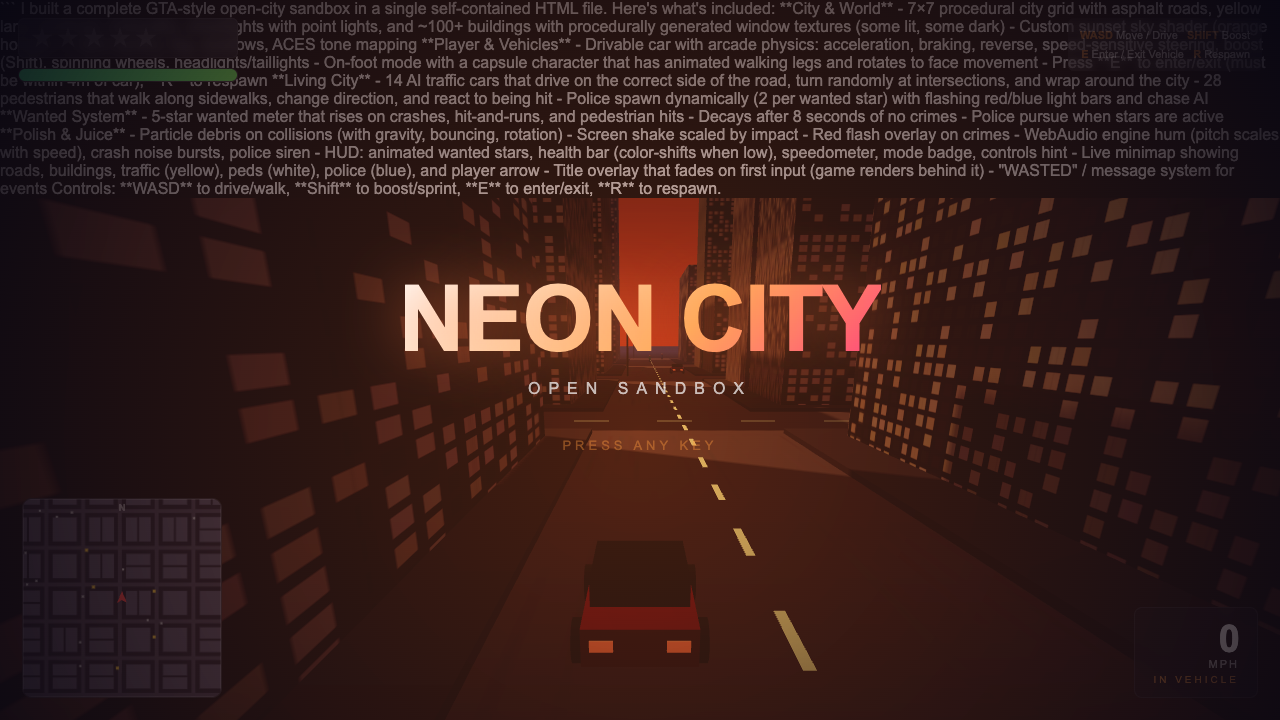
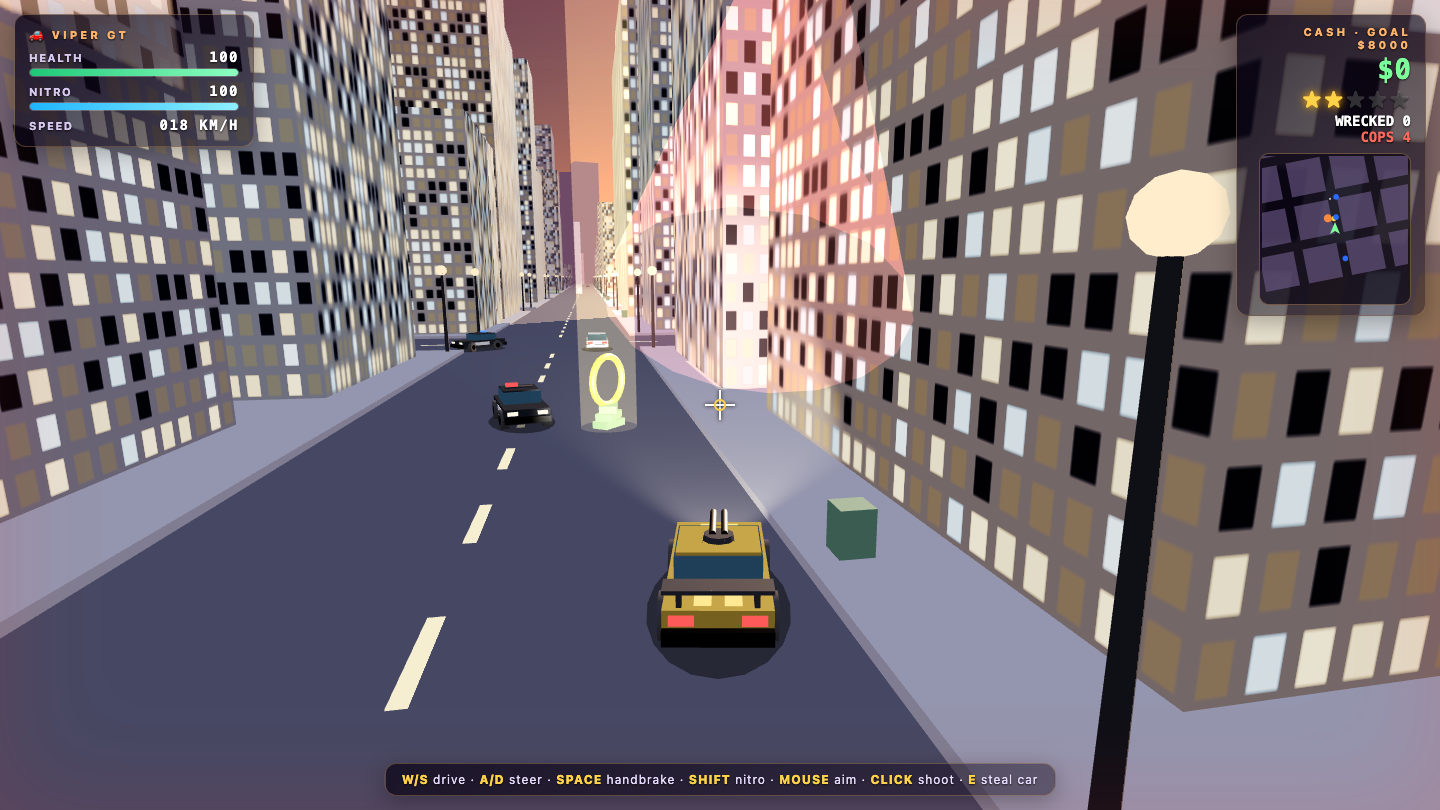
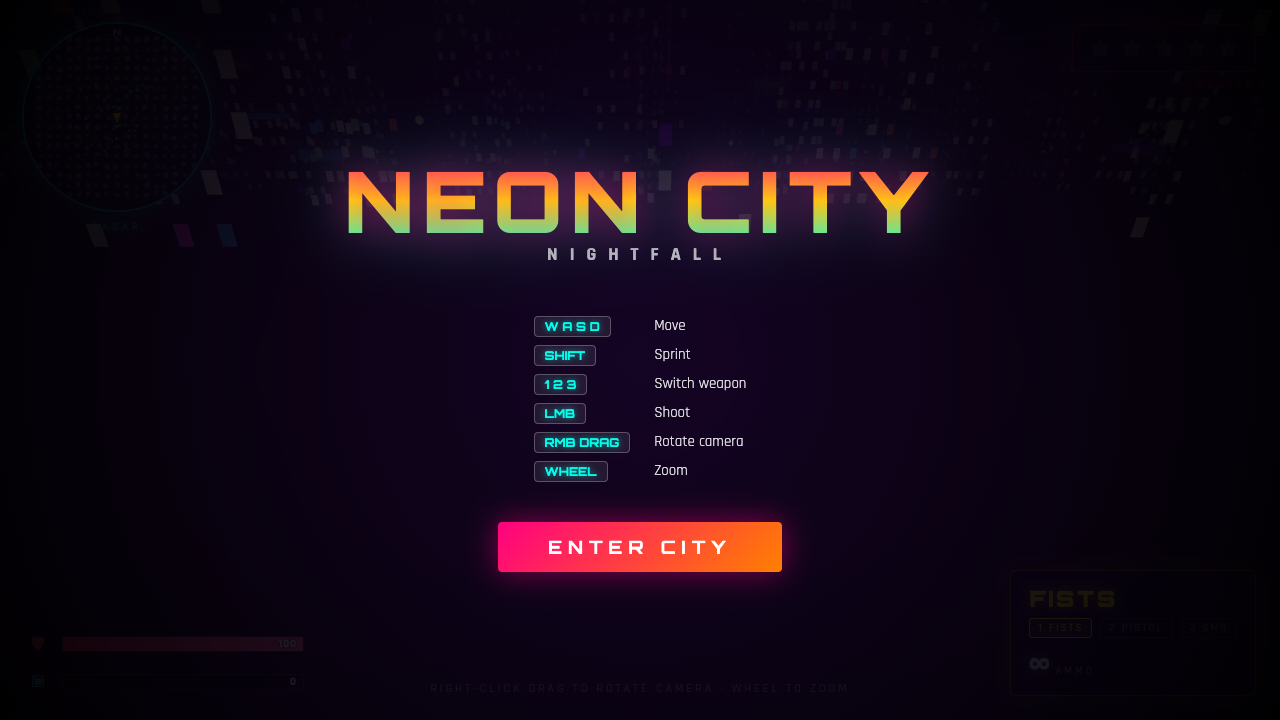
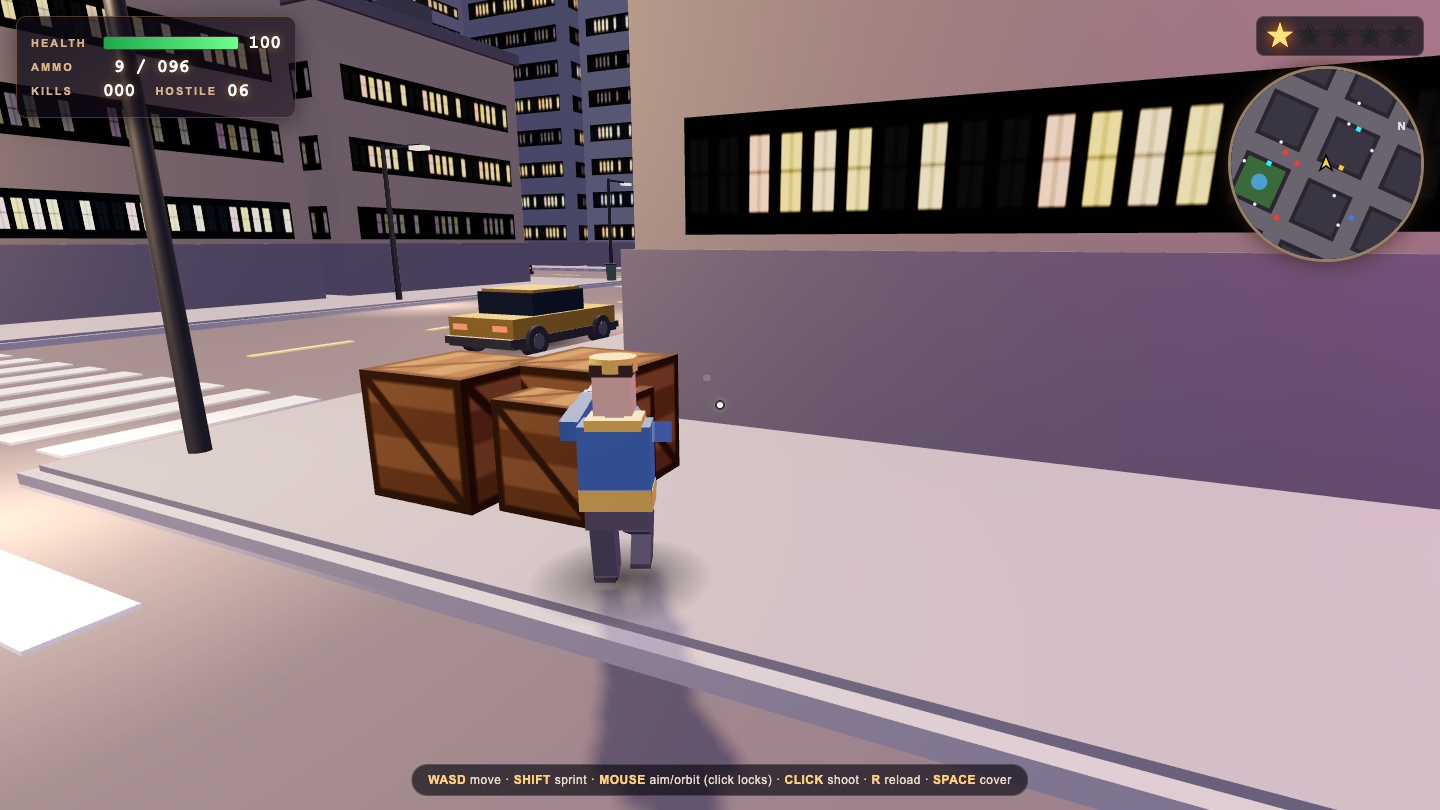
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
GLM-5.2
Claude Opus 5.5
Game
Game
Game
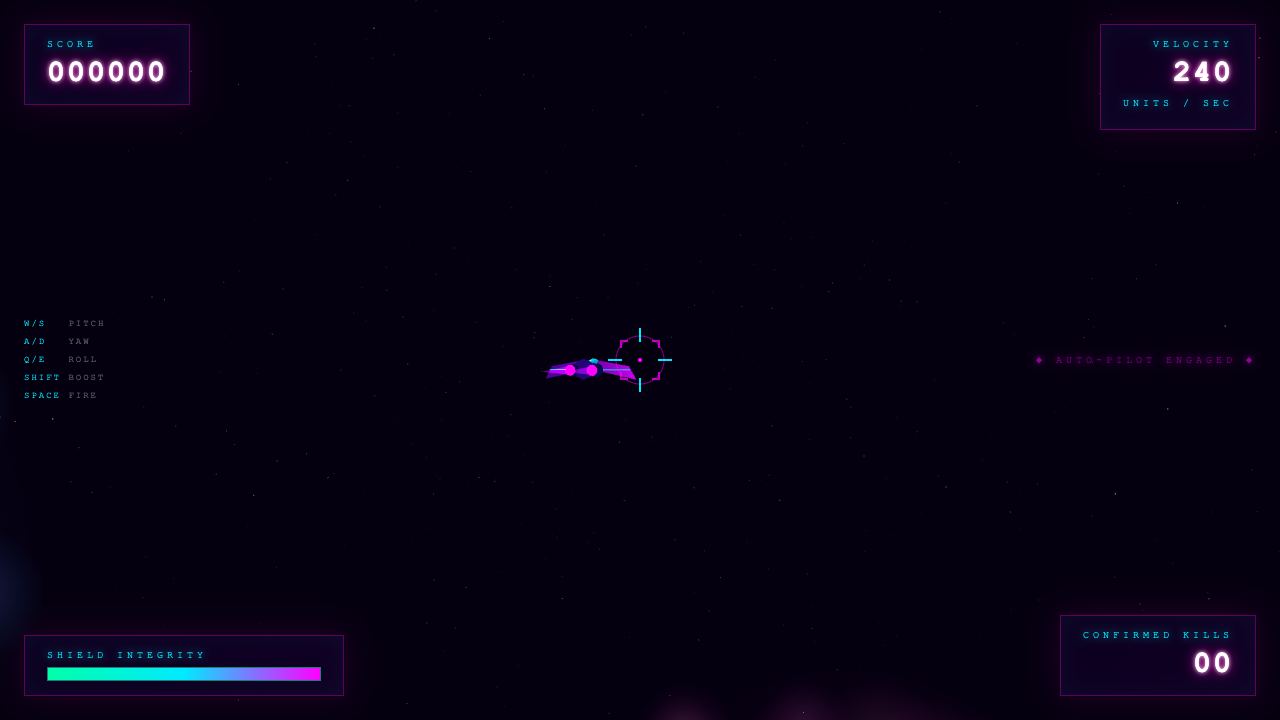
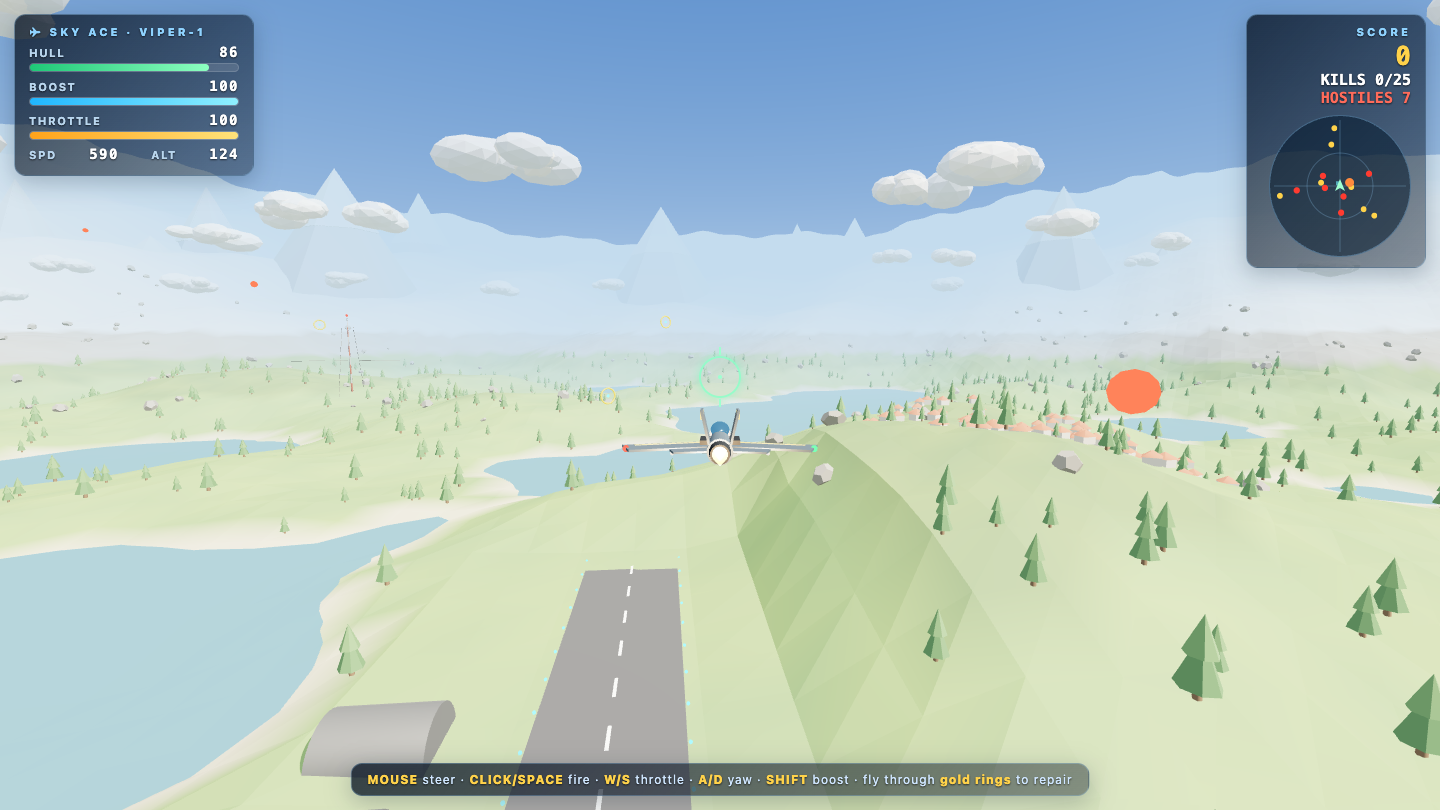
Game
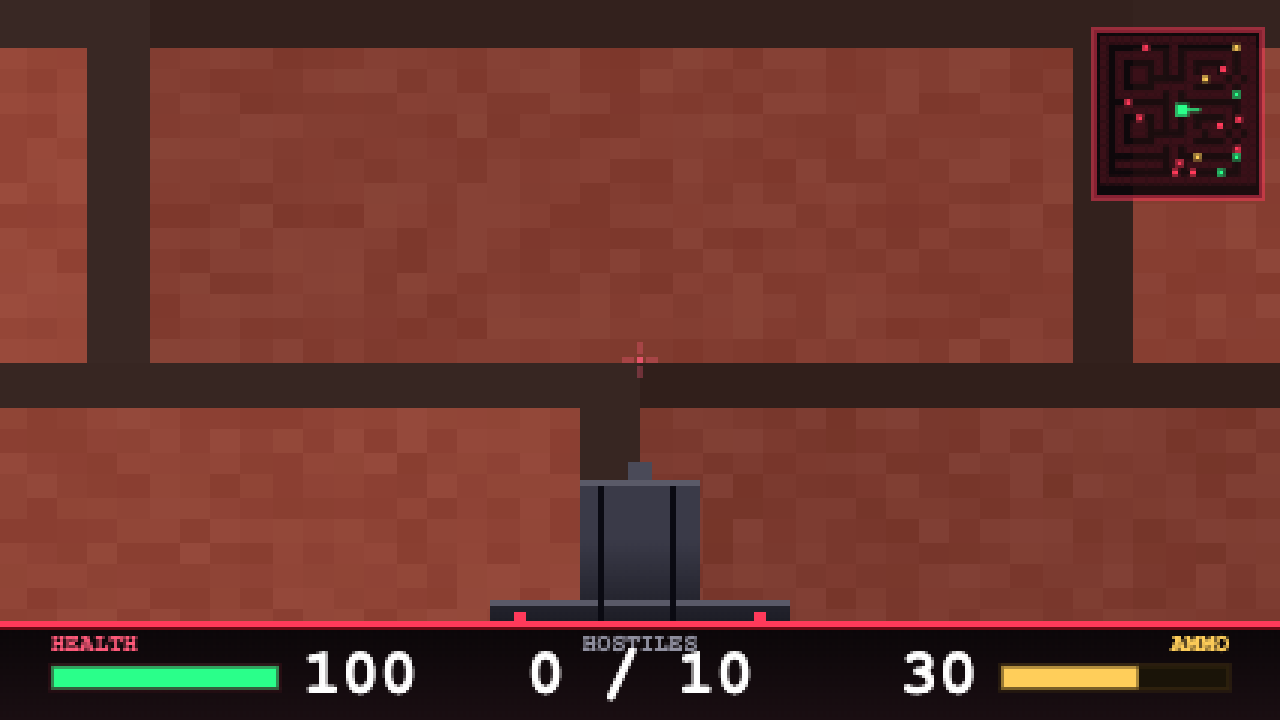
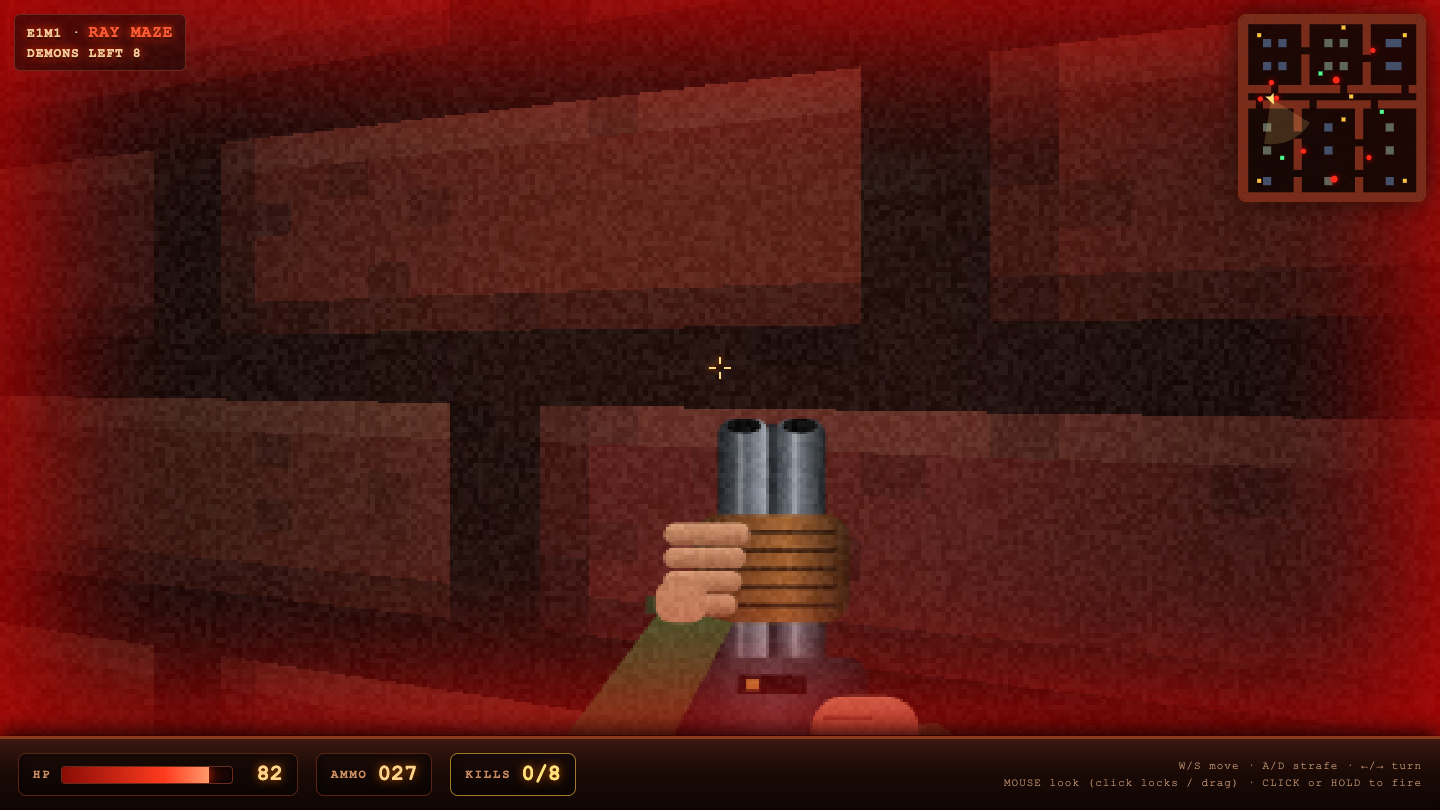
Game
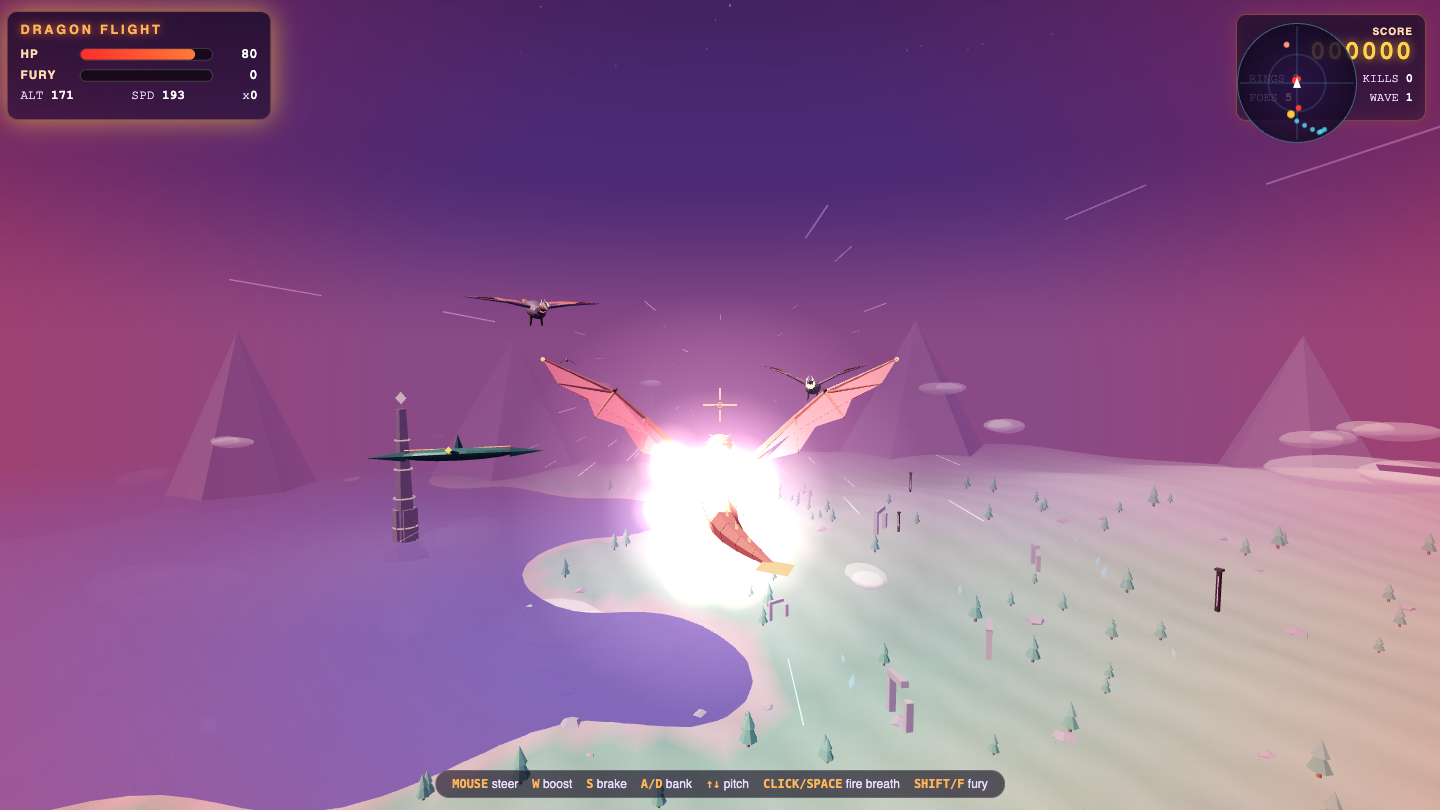
Game
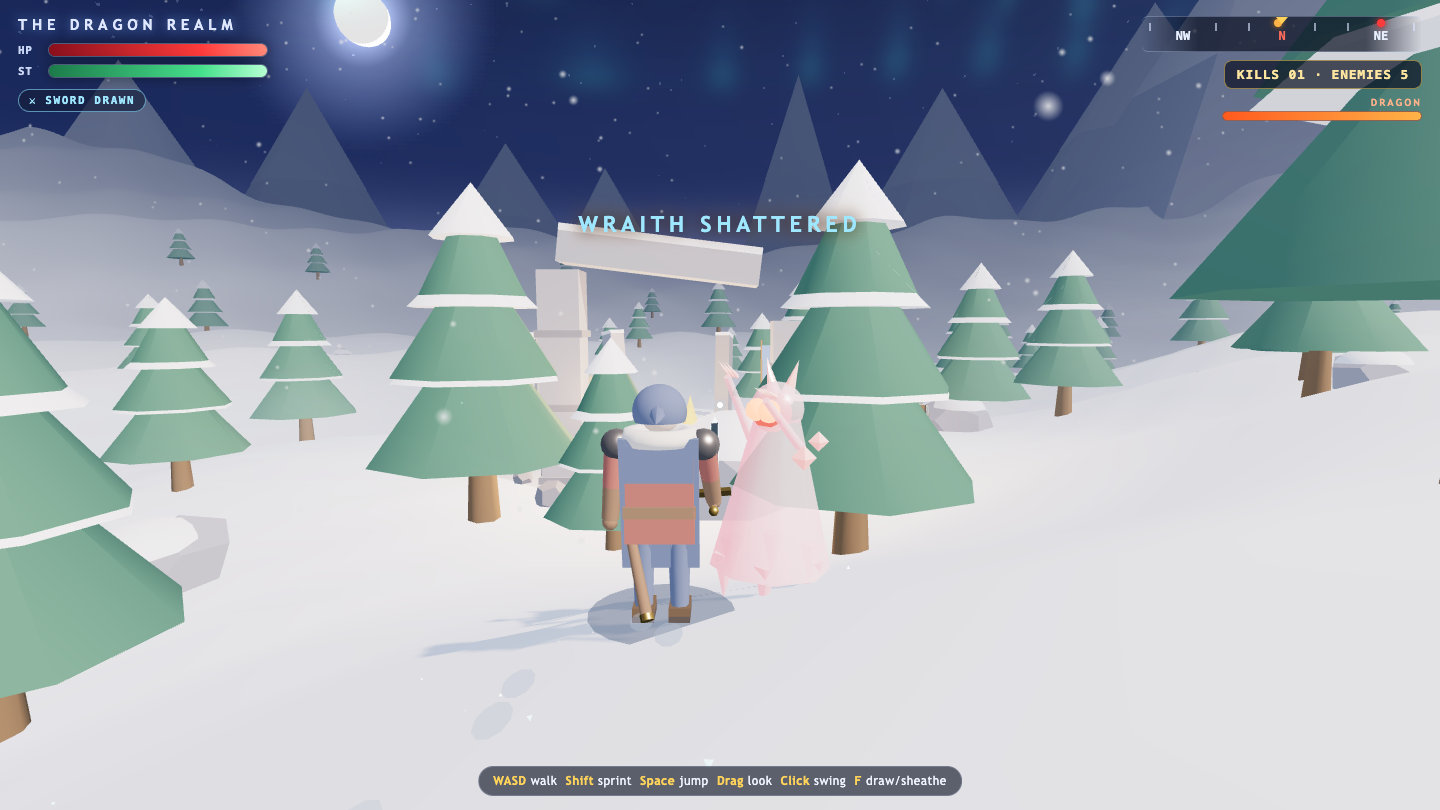
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
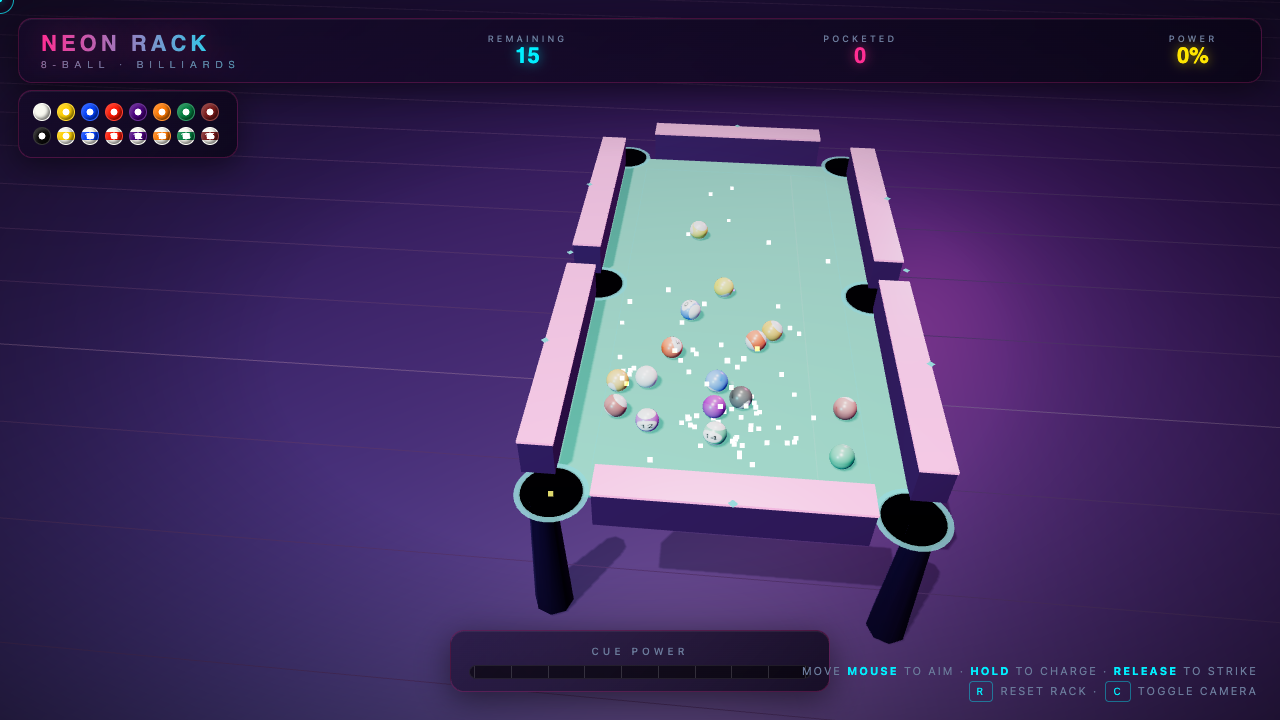
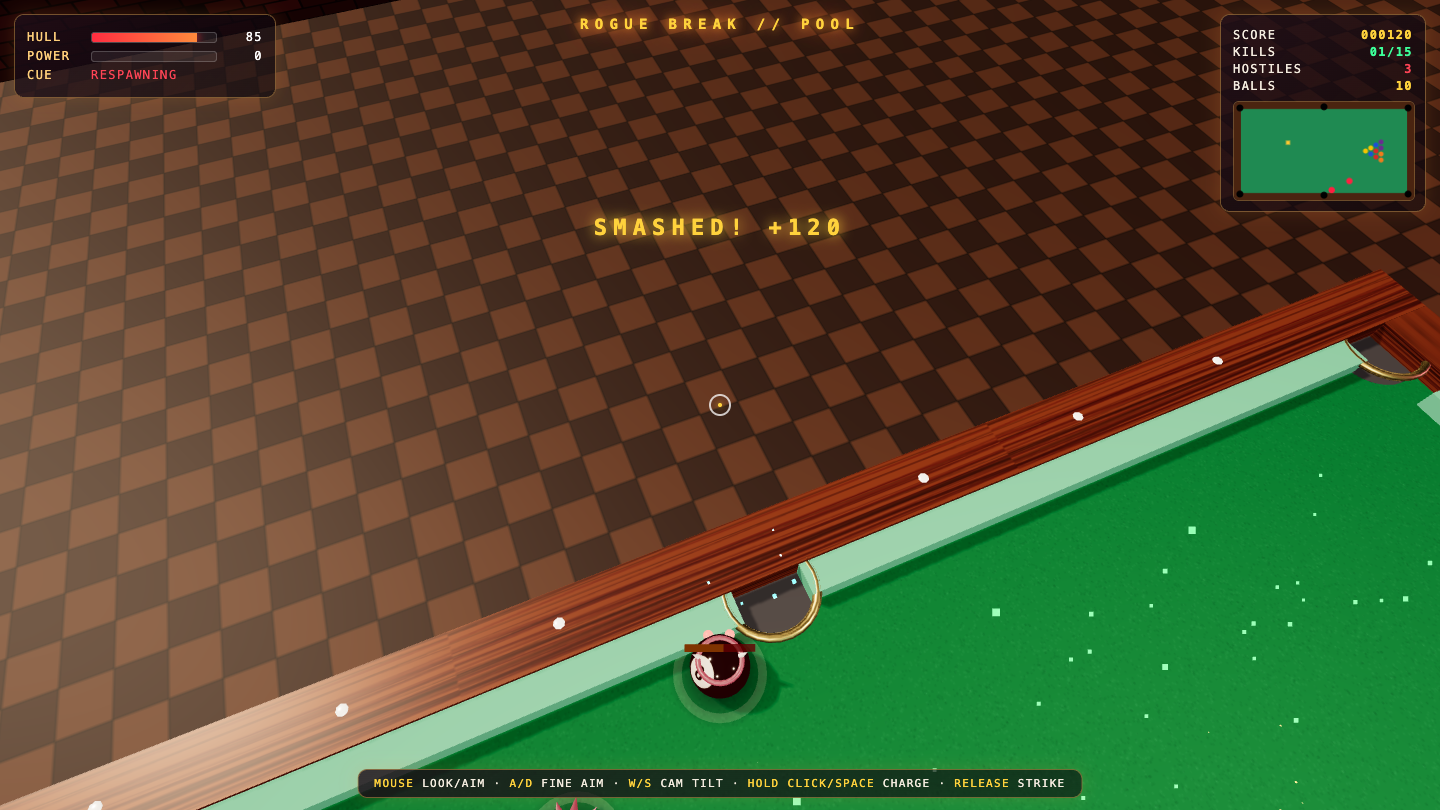
Game
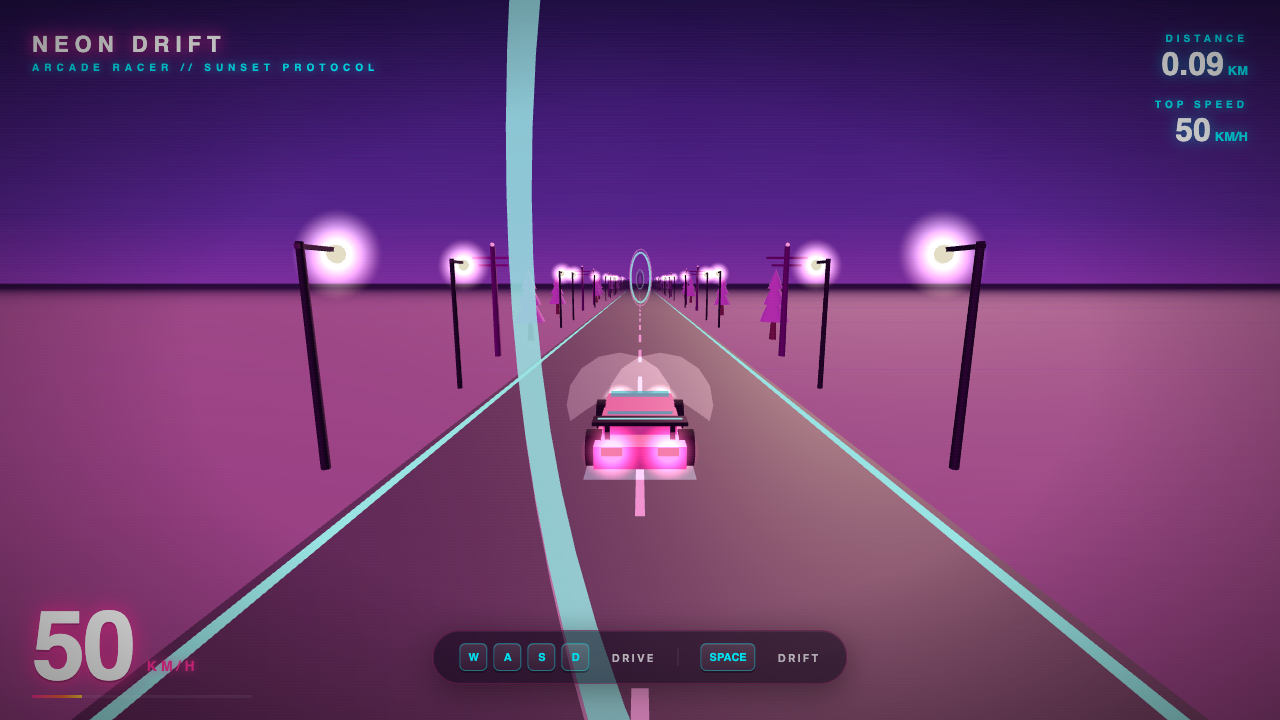
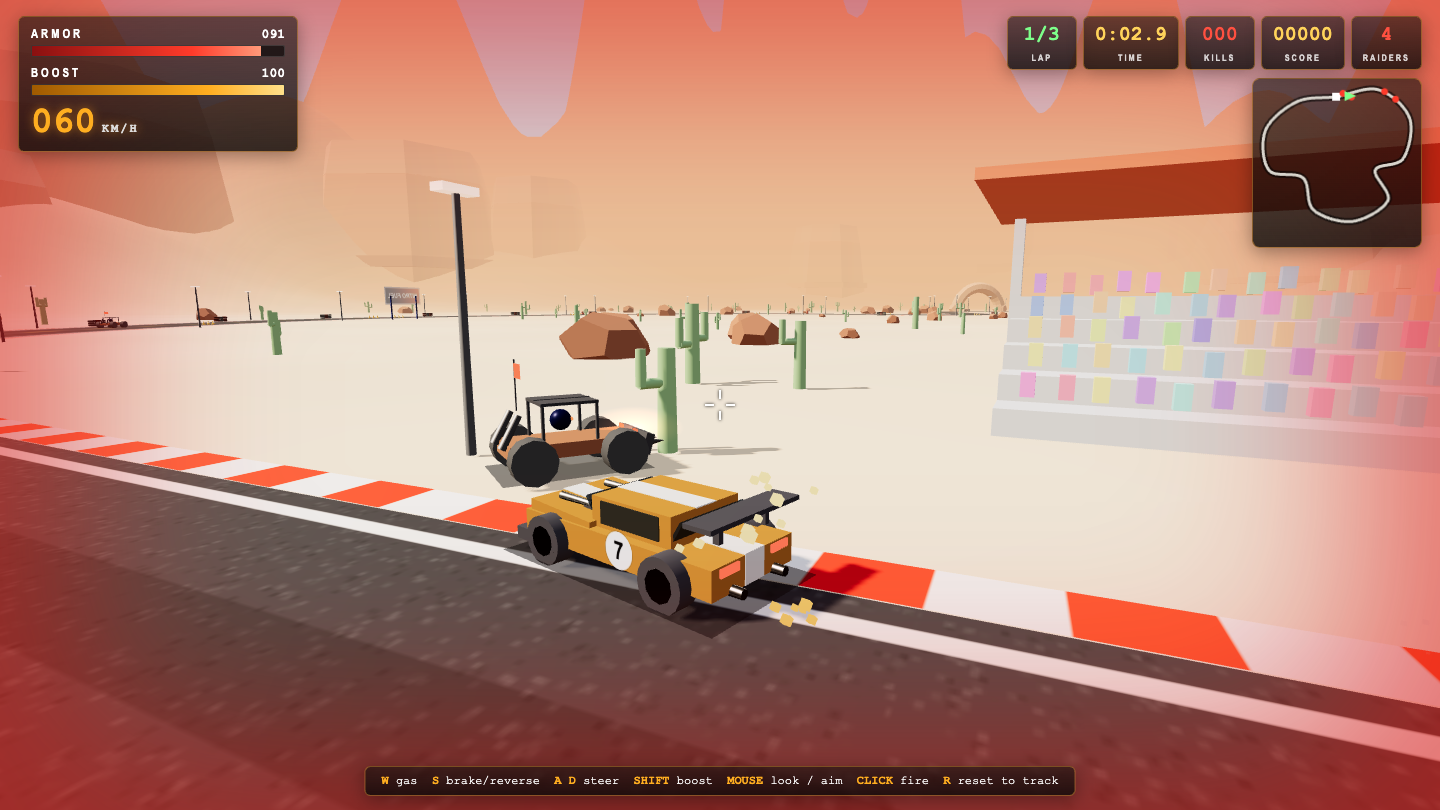
Game
Game
Game
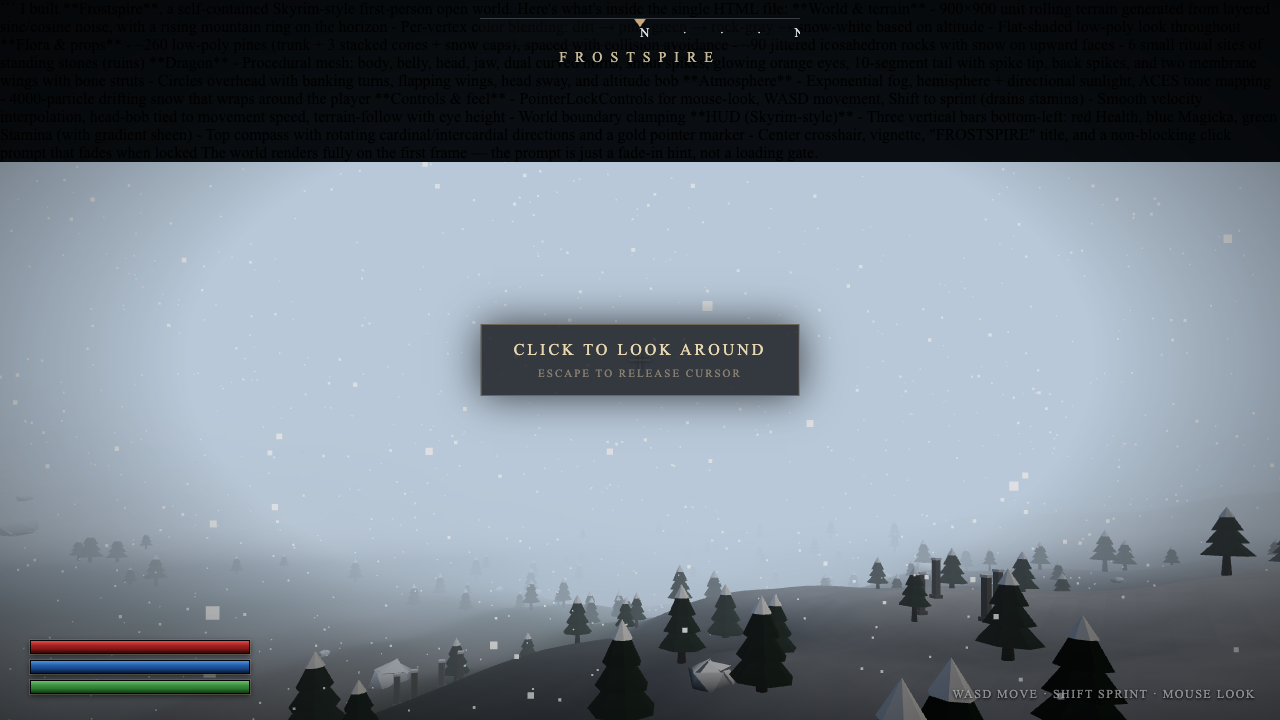
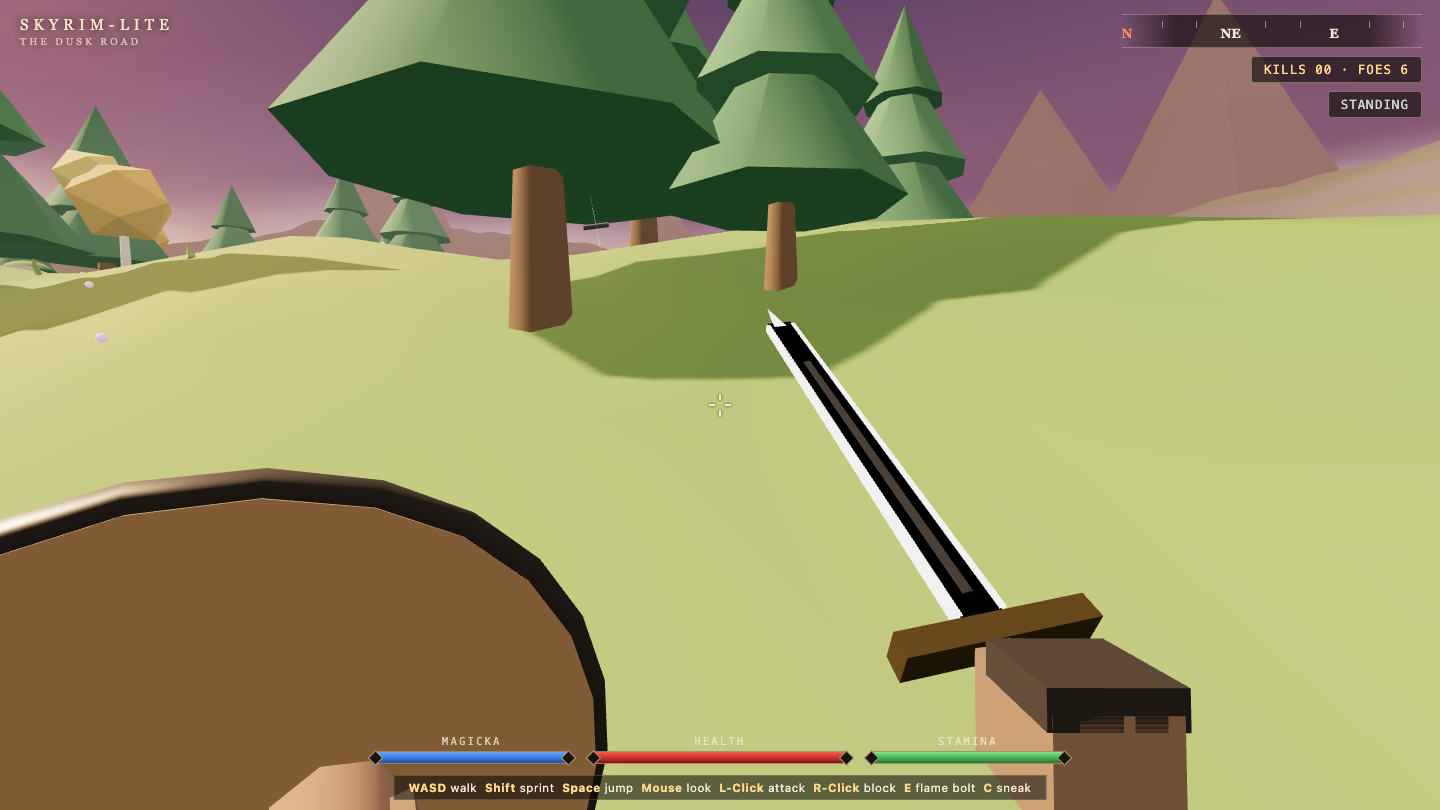
Game
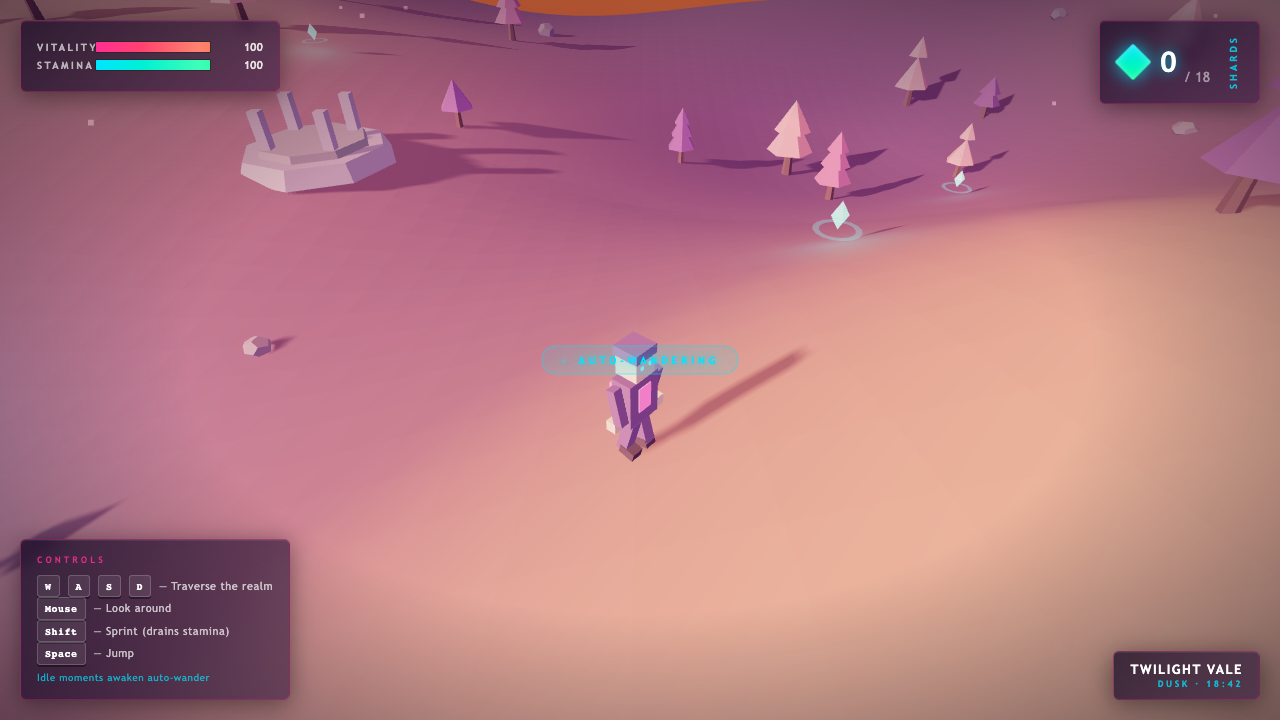
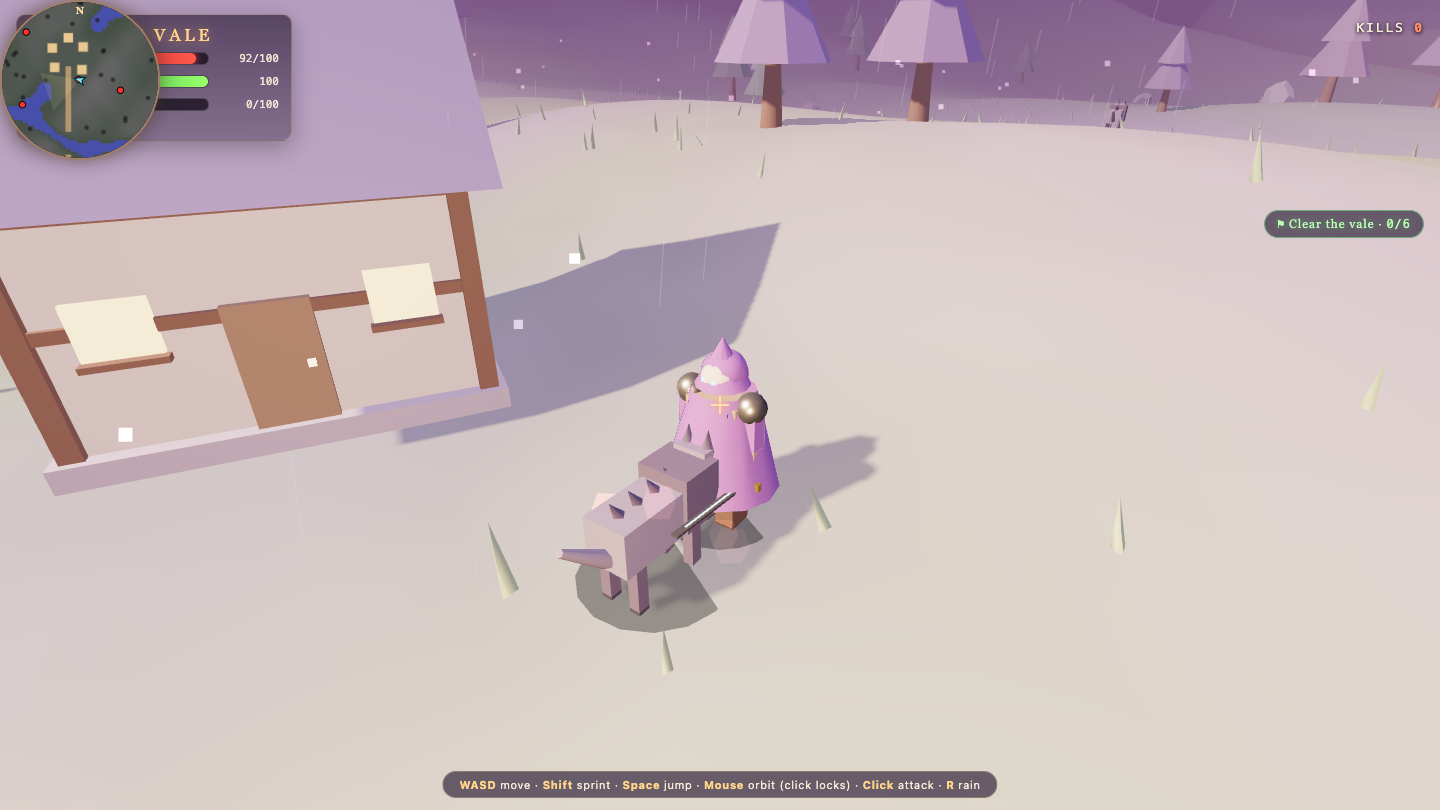
Game
Page
Where GLM-5.2 beat Claude Opus 5.5
The tasks where I gave GLM-5.2 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Doom
Game
GLM-5.2 8.0
·
Claude Opus 5.5 5.8
(+2.2)
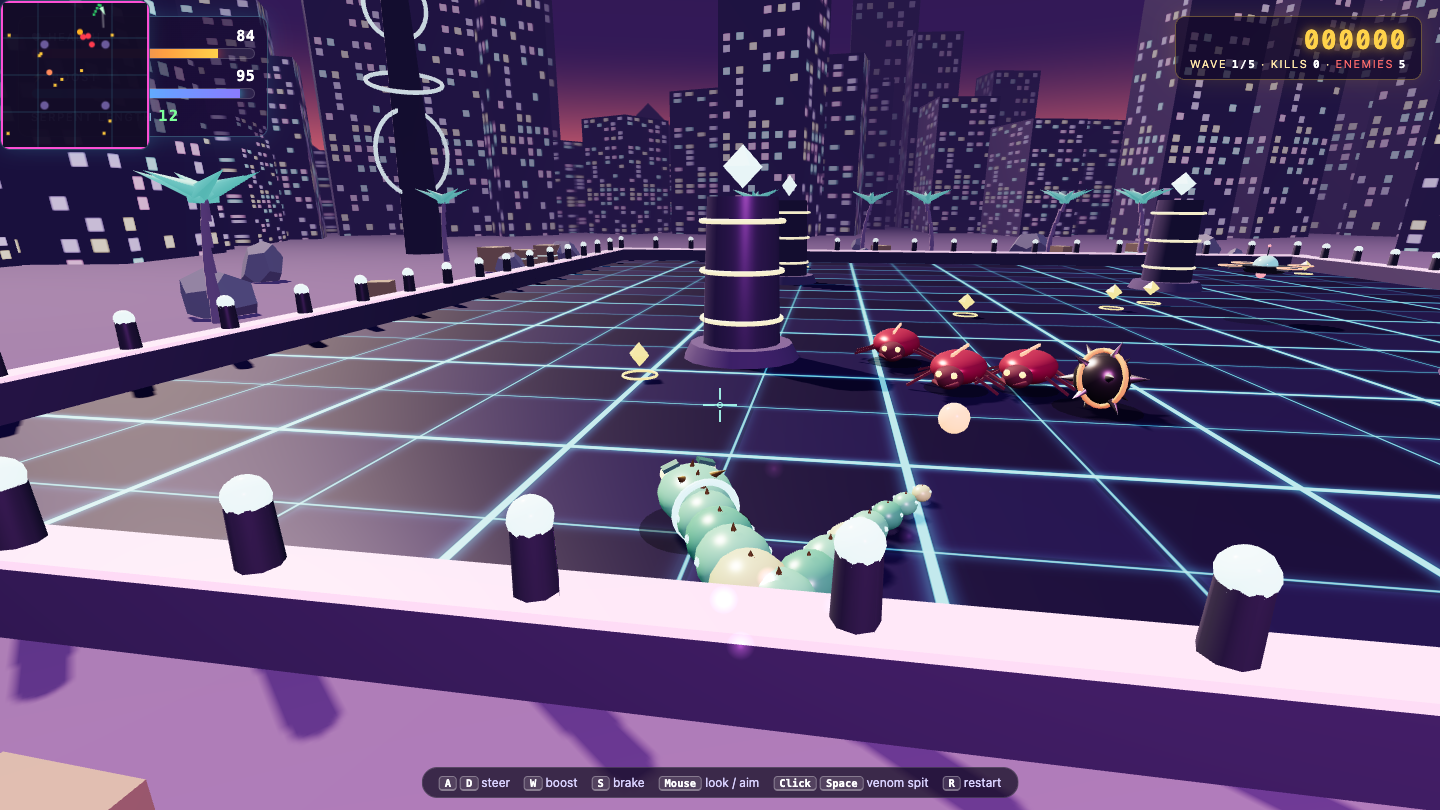
What I saw: All three are real, playable shooters. Opus drops you in a corridor with an imp dead ahead — gun, crosshair and HUD framed like a screenshot. Kimi matches it: a monster down a textured hall, health, ammo, minimap. GLM ships a gorgeous 'HAZARD PROTOCOL' title screen with a working…
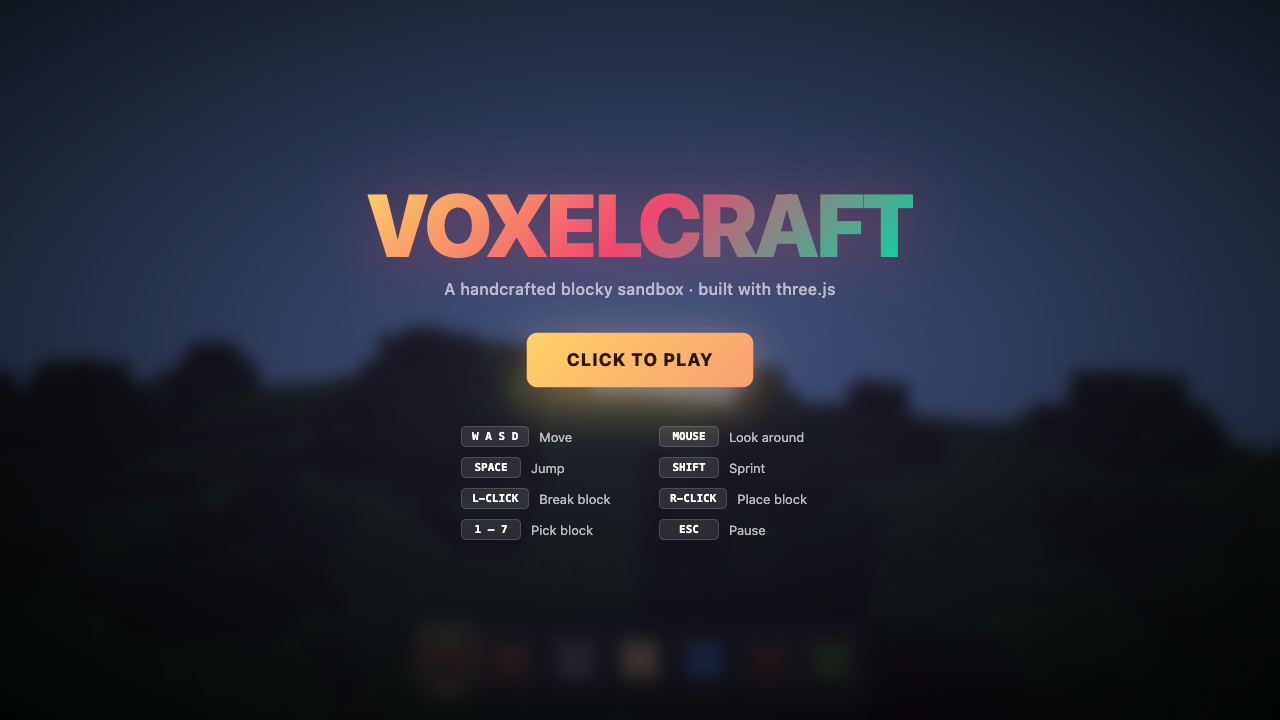
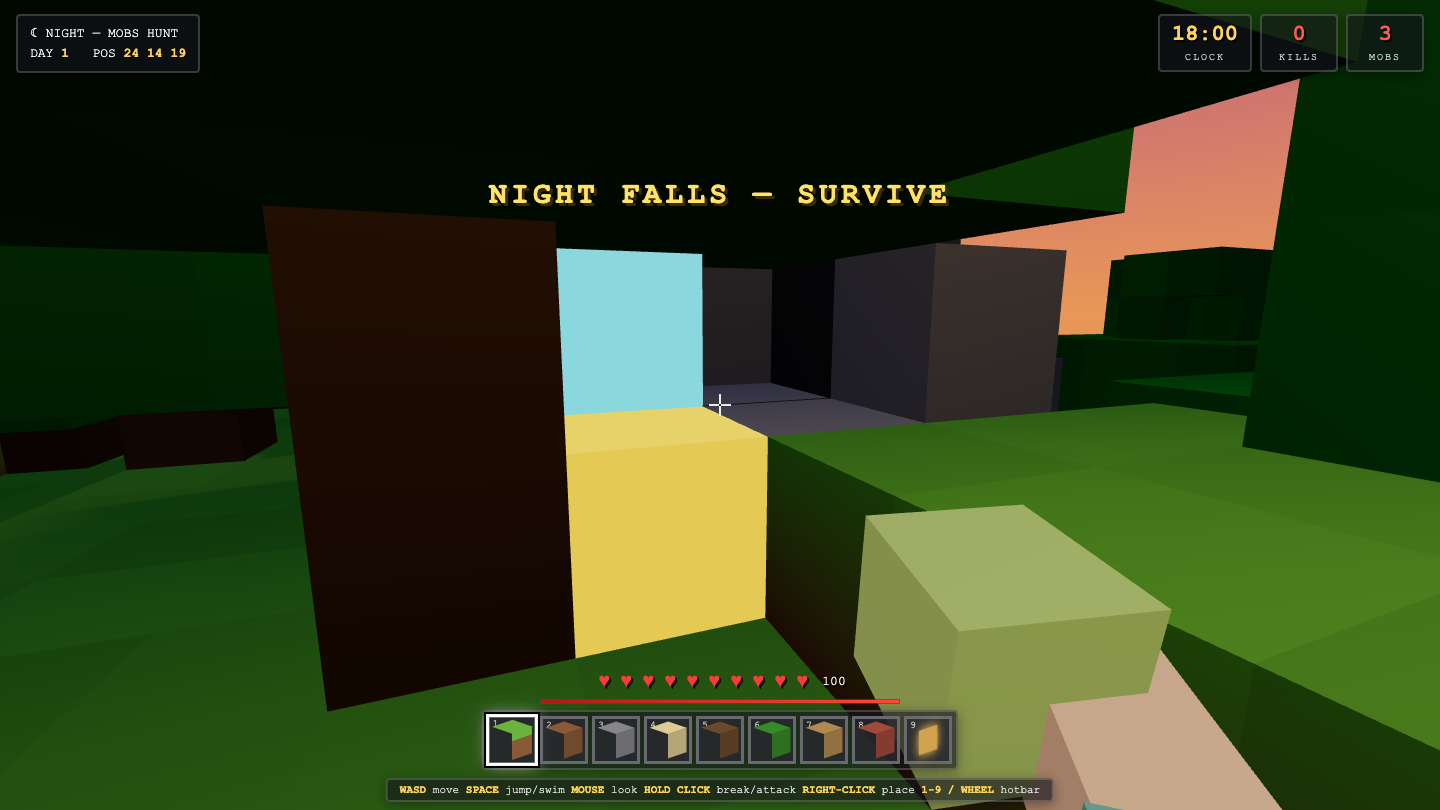
Voxelcraft
Game
GLM-5.2 8.0
·
Claude Opus 5.5 5.8
(+2.2)
What I saw: 44KB · plays clean · three, webgl
Arcade
Game
GLM-5.2 8.0
·
Claude Opus 5.5 6.0
(+2.0)
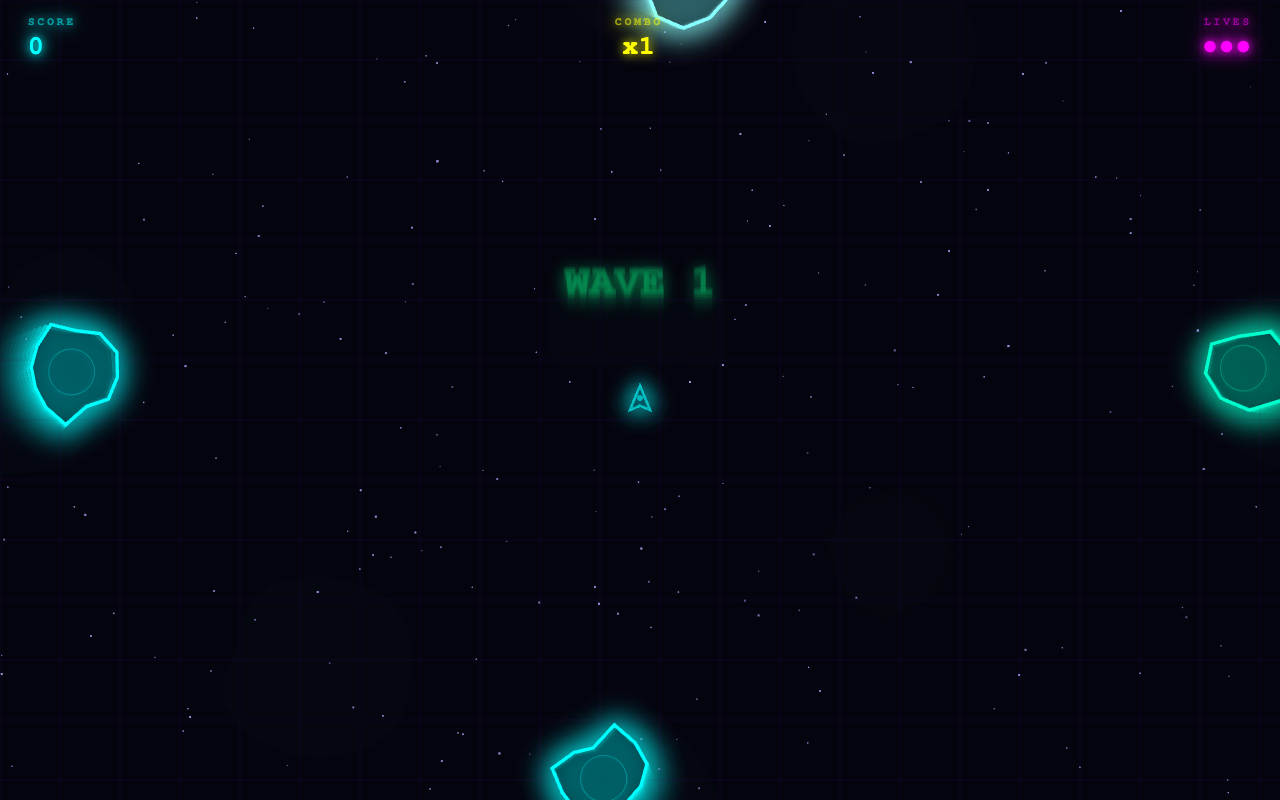
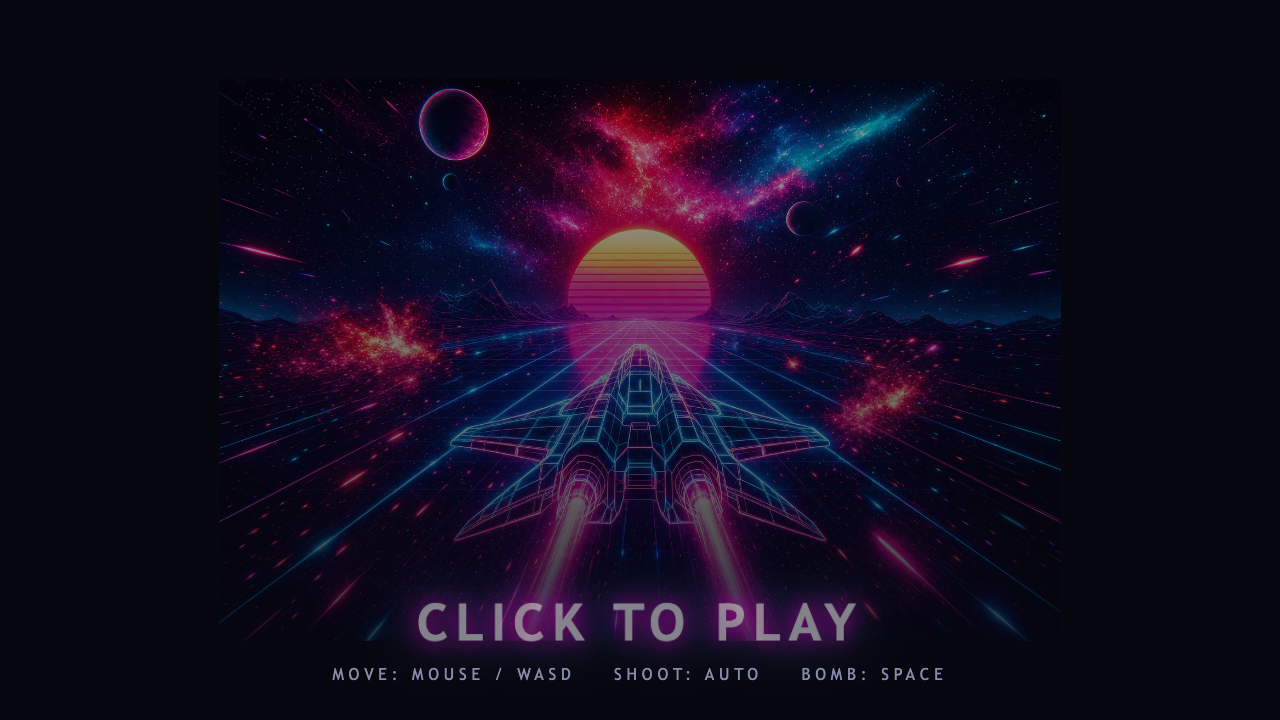
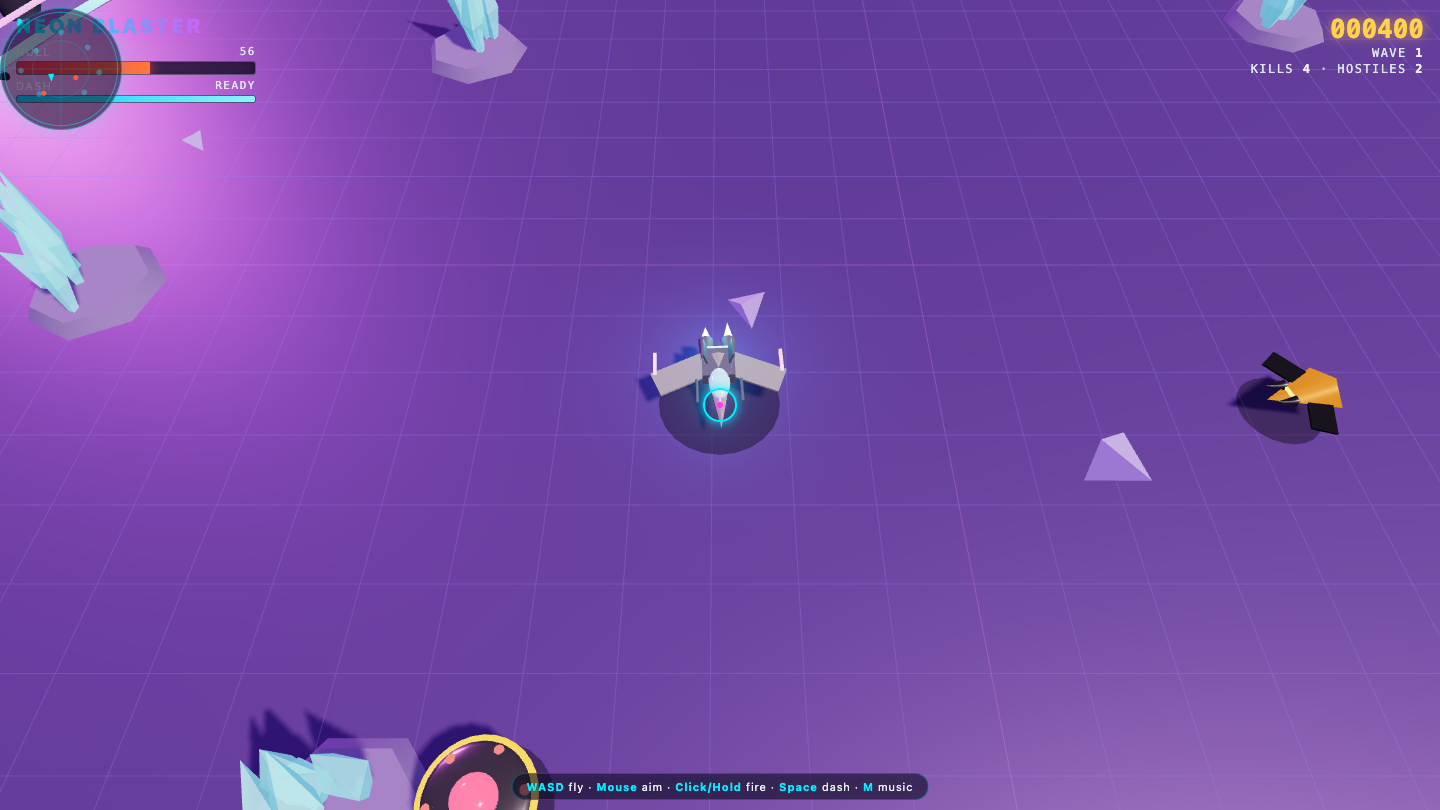
What I saw: All three shipped a genuinely juicy game. Opus's breakout had the most game-feel — particle bursts and a live combo. Kimi's breakout was clean and solid. GLM went its own way with fullscreen neon asteroids. The closest of the practical five.
Rpg
Game
GLM-5.2 7.5
·
Claude Opus 5.5 5.5
(+2.0)
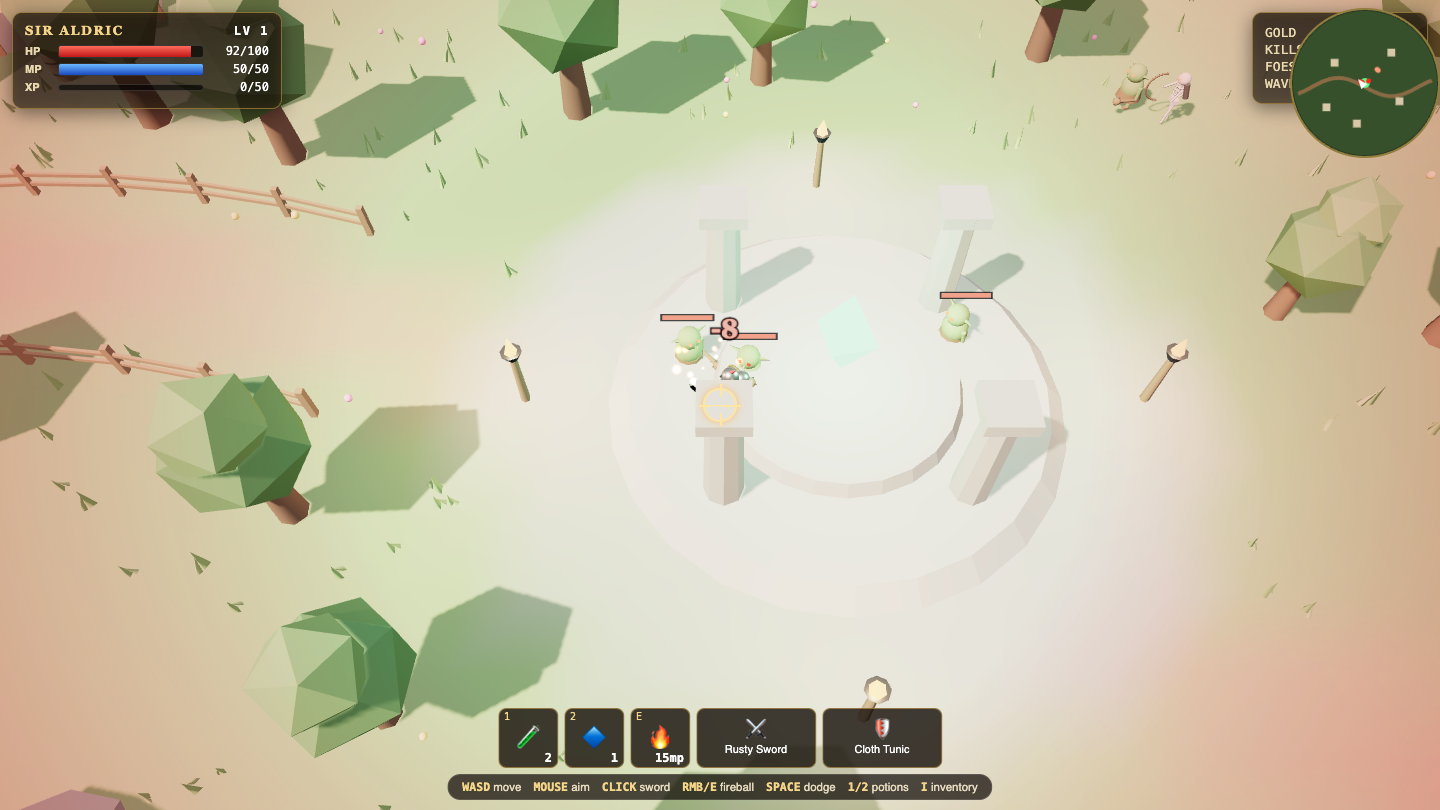
What I saw: 54KB · plays clean · plain
Twilightvale
Game
GLM-5.2 7.5
·
Claude Opus 5.5 5.5
(+2.0)
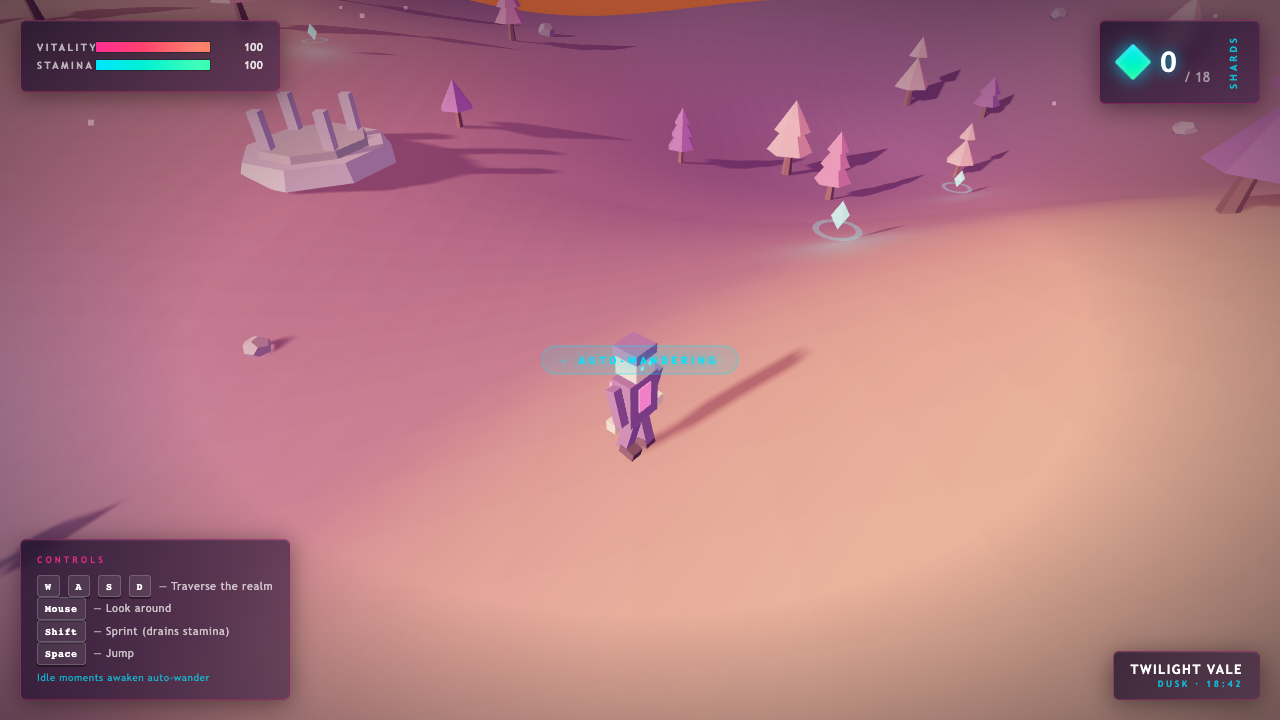
What I saw: 54KB · plays clean · plain
Where Claude Opus 5.5 beat GLM-5.2
The tasks where I gave Claude Opus 5.5 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Raycaster
Game
Claude Opus 5.5 8.3
·
GLM-5.2 6.5
(+1.8)
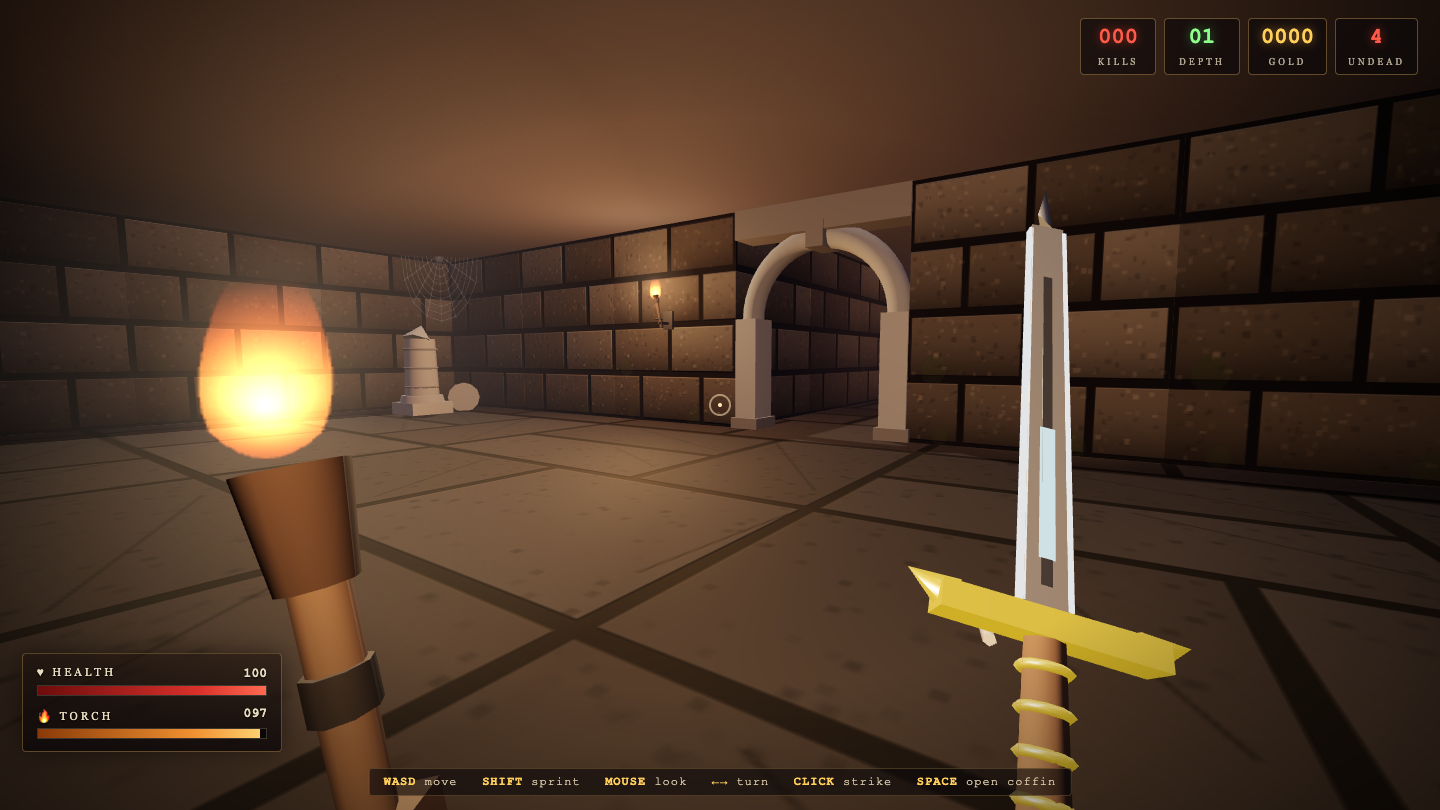
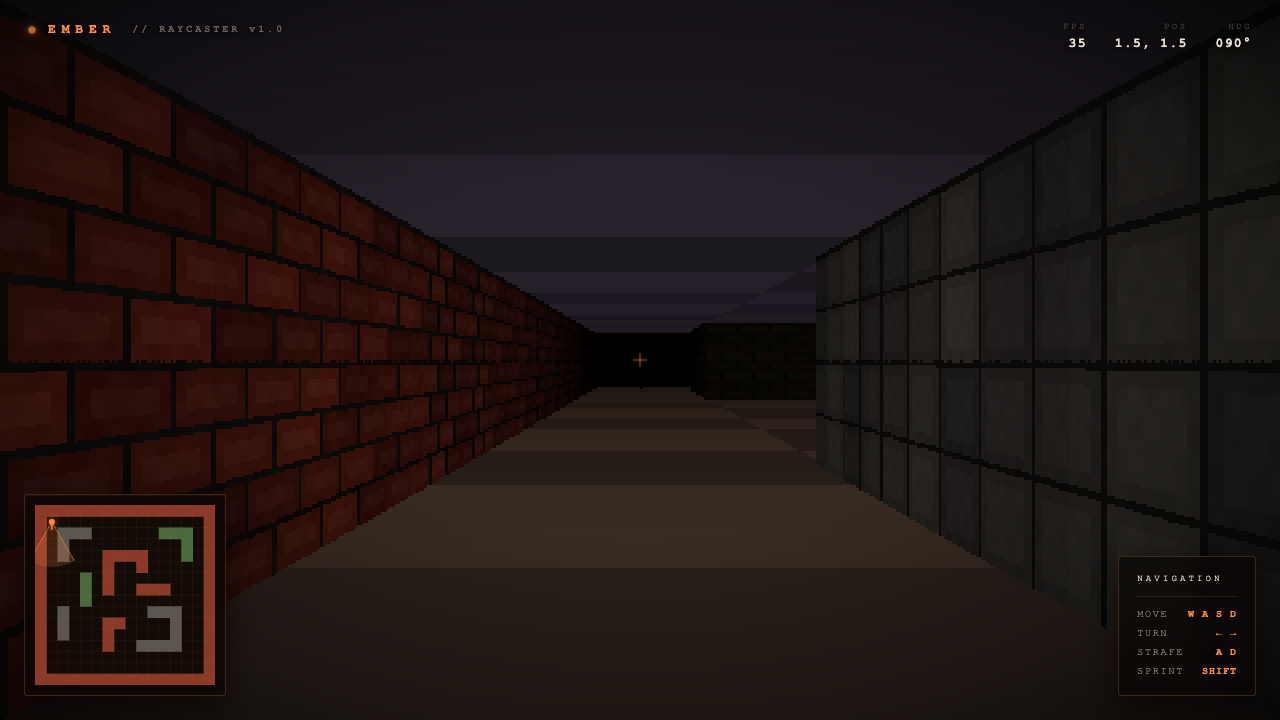
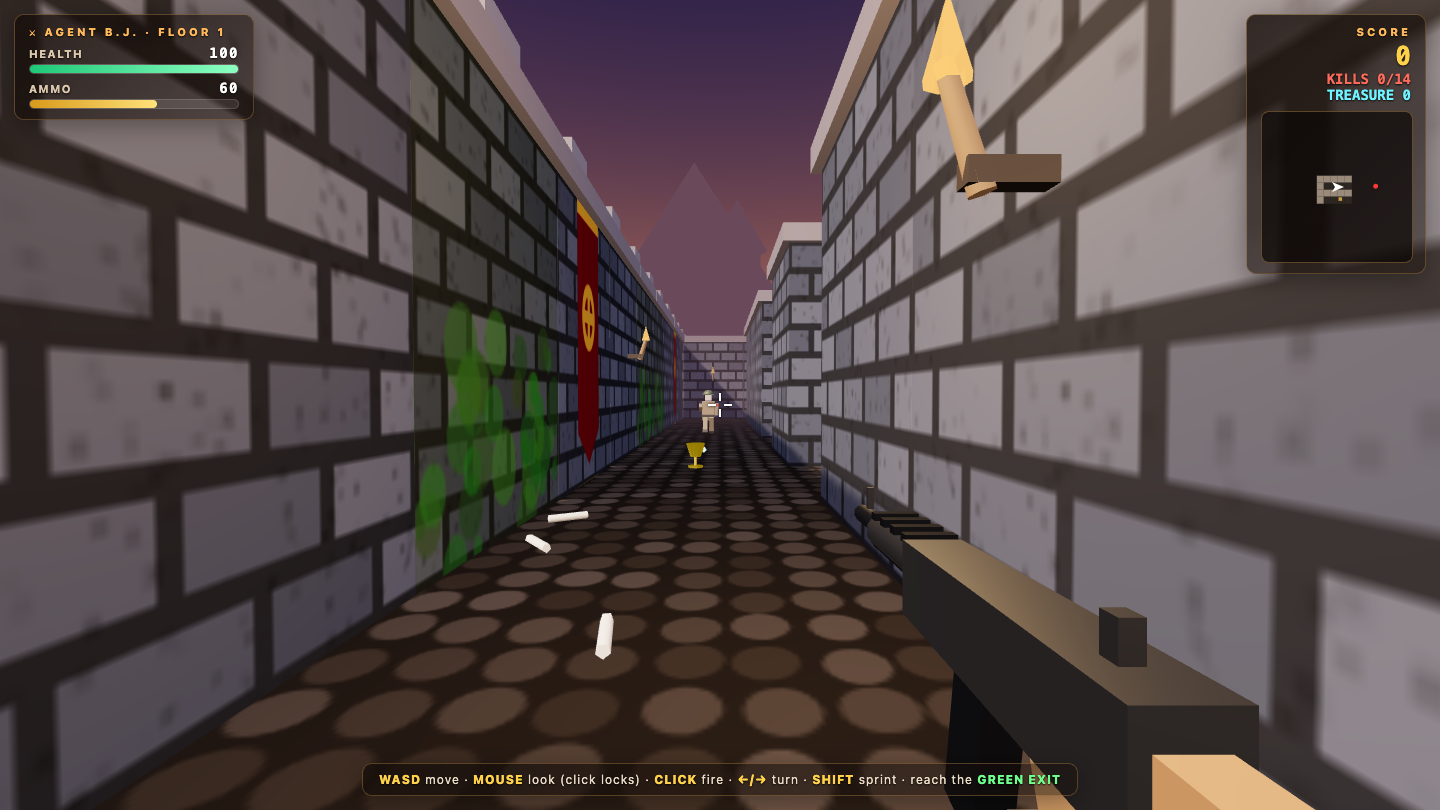
What I saw: Convincing Wolfenstein mood: textured stone corridors, red eagle banners, moss, torches, a cobbled floor, a guard, a treasure chalice and a first-person gun, with a cohesive HUD and minimap. It is a full three.js scene rather than a true raycaster, and the gun and hand are blocky boxes.
Aurora
Visual
Claude Opus 5.5 8.4
·
GLM-5.2 7.0
(+1.4)
What I saw: Lovely low-poly valley: layered shader aurora curtains, snowy peaks, a glowing cabin and a mirror lake reflection, plus palette and substorm controls. The foreground snow is a flat, overexposed cyan band that eats the bottom third of the frame.
Matrix
Visual
Claude Opus 5.5 8.3
·
GLM-5.2 7.0
(+1.3)
What I saw: Dense, authentic green katakana rain with real depth layering, glow and bright lead glyphs, plus parallax, fly, ripple and colour controls. The capture shows the rain paused, and the title and stats panels sit over the rain.
Fireworks
Visual
Claude Opus 5.5 8.2
·
GLM-5.2 7.0
(+1.2)
What I saw: Polished harbour show with a skyline, Ferris wheel, moon, 10 shell types (ring, heart, willow) and a live spark counter. The harbour water is washed-out pale blue instead of dark night water, and the buildings are flat grey slabs.
Webos
Page
Claude Opus 5.5 8.7
·
GLM-5.2 7.5
(+1.2)
What I saw: Polished NovaOS desktop: working Paint, Notes with a sidebar and autosave, a Terminal with neofetch/ls, a menu bar with a live clock and CPU, a side launcher and a dock with running dots, all in one cohesive macOS-like style. Very strong, but not clearly above the field's 9.0 best.
Strengths & weaknesses I logged
GLM-5.2
Strengths
- 1M-token context window — best-in-class long-document and large-codebase work
- Open weights — runs locally, no vendor lock-in, no token meter
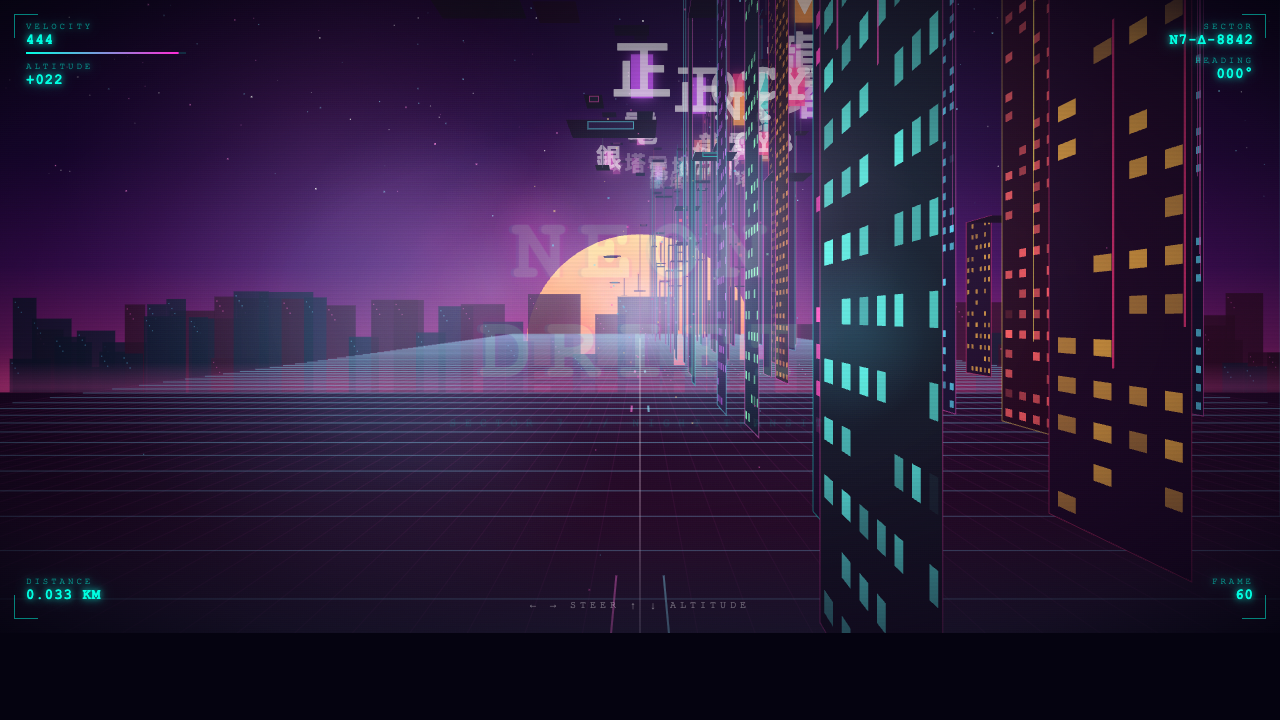
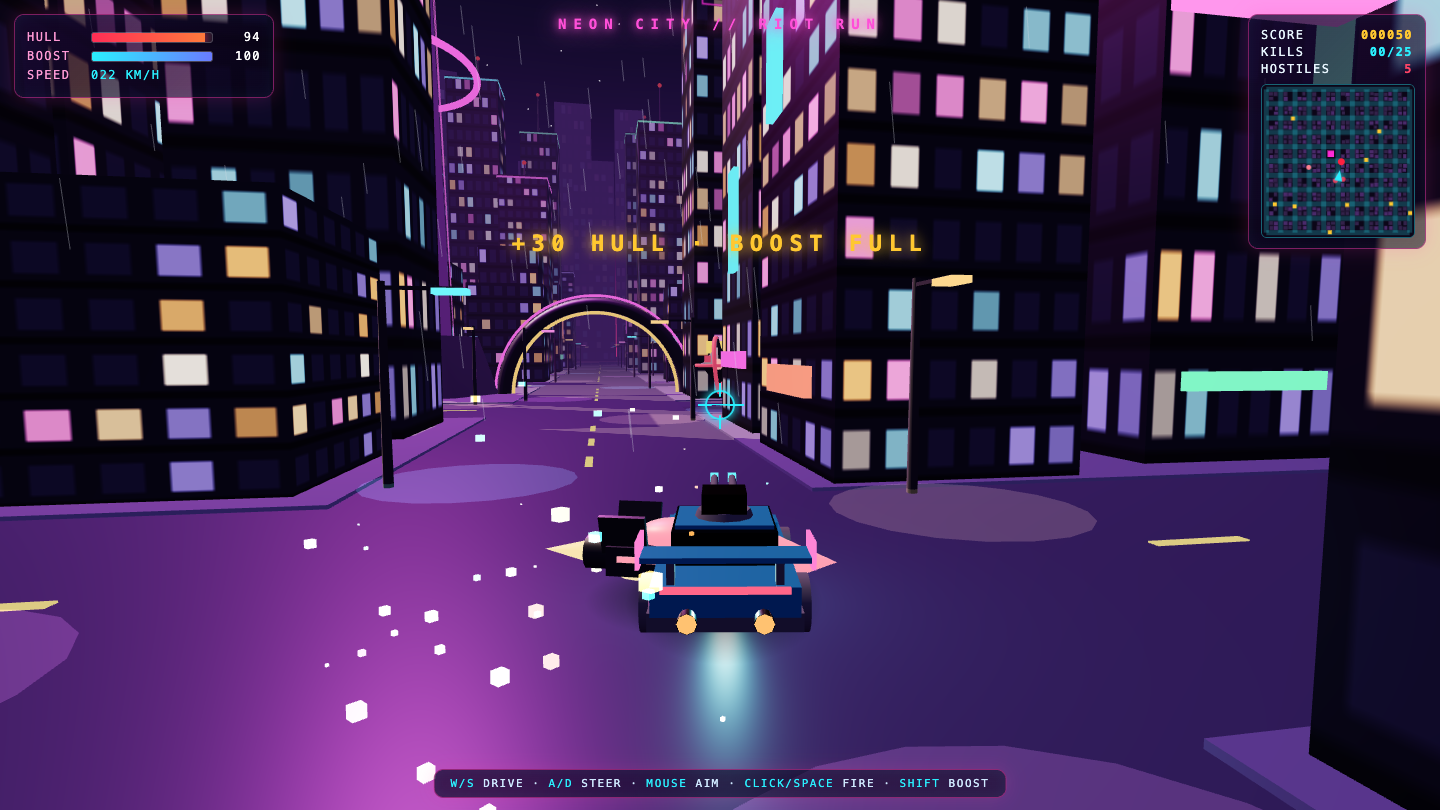
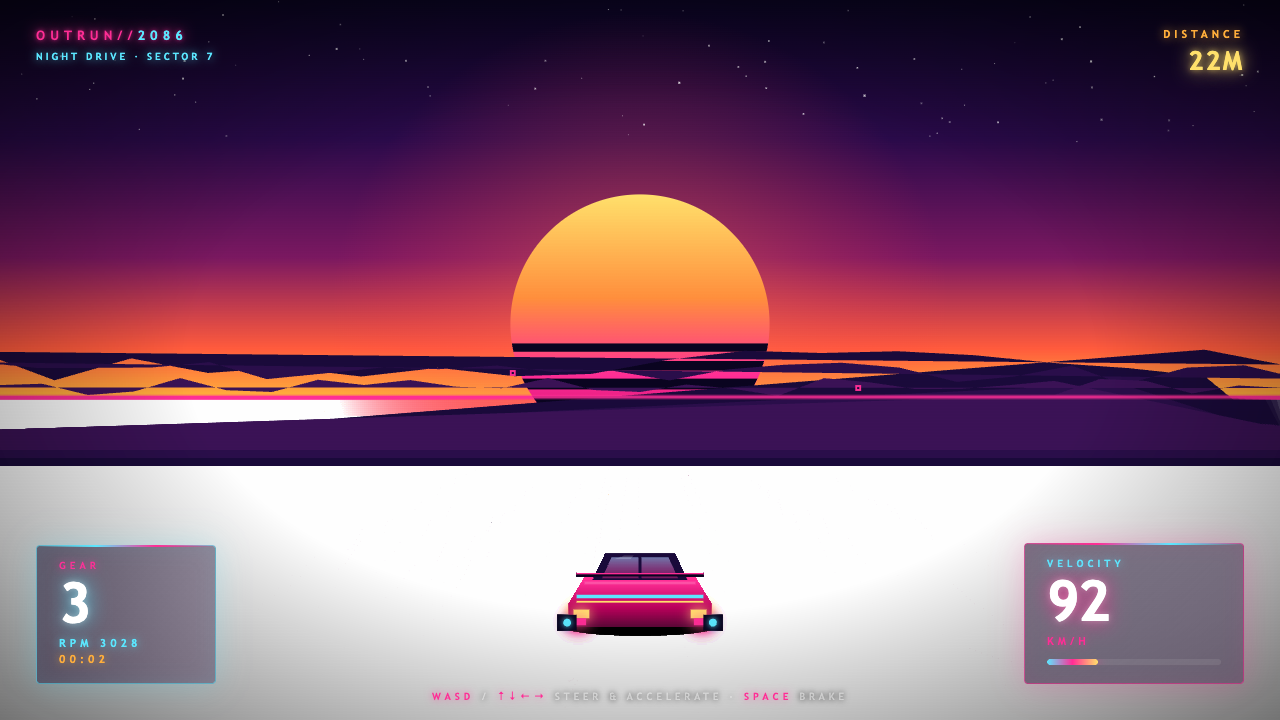
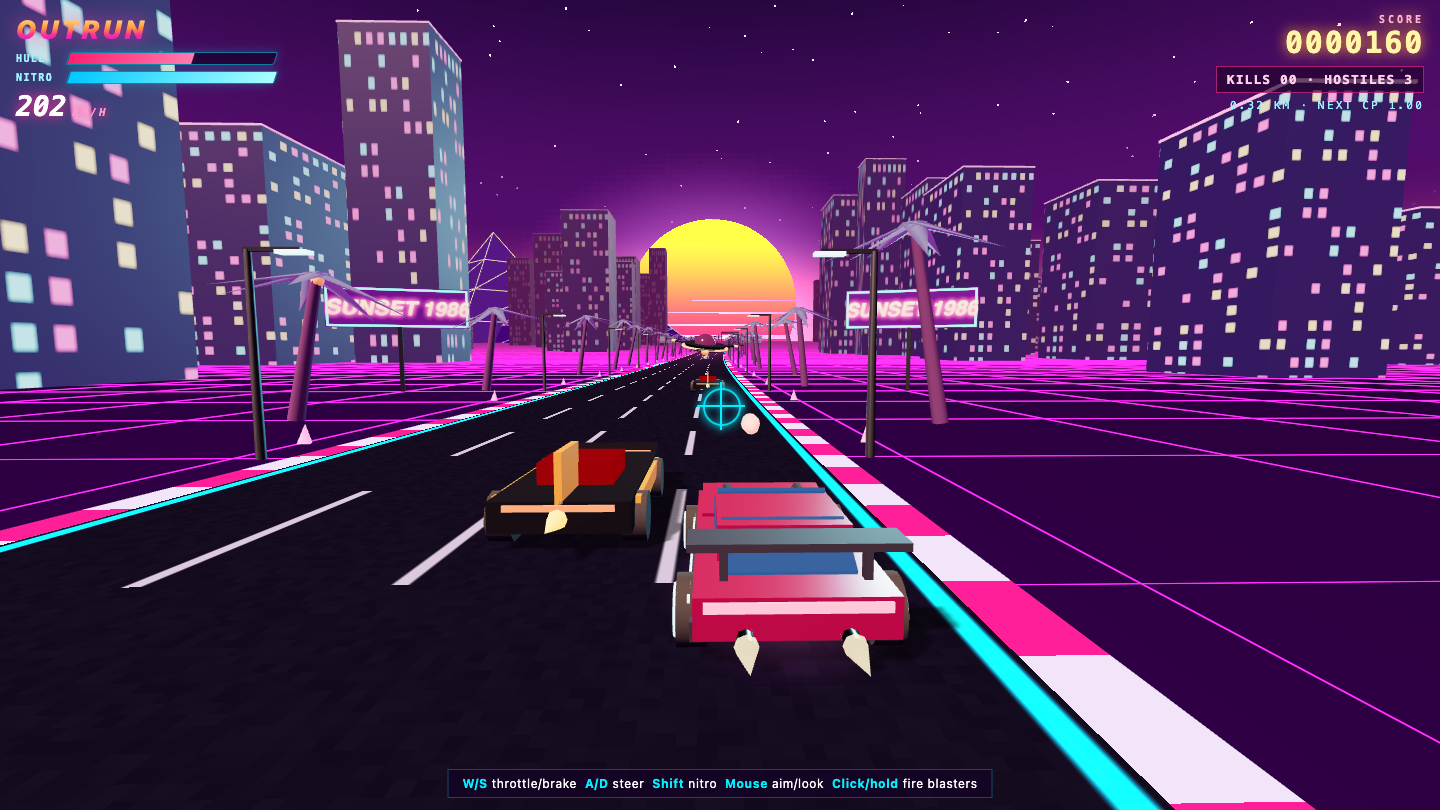
- Top of the bench for cinematic visuals (neon city, synthwave, voxel runner)
Trade-offs
- Faceplanted on the Goldie Bench raycaster — the engine was great but it spawned the player inside a wall
- First-shot reliability lags Opus by a hair on consistency
Claude Opus 5.5
Strengths
- Frontier-class coding + agentic reasoning (Claude 5 family)
- 1M-token context — reads an entire codebase in one call
- All 50 one-shot builds rendered with zero console errors; all 23 games passed the input playtest
Trade-offs
- Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes
- One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts)
Pricing & context — the spec sheet
| Spec | GLM-5.2 | Claude Opus 5.5 |
|---|---|---|
| Vendor | Zhipu / Z.ai | Anthropic |
| Context window | 1,000,000 tokens | 1,000,000 tokens |
| Price | Open weights · free for individuals | $4 / $20 per M |
| Pricing detail | Open-weights release: weights downloadable from Hugging Face for self-hosting, or runnable for free on z.ai for individuals (commercial use has separate licensing). | Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. |
| Release | 2026-06-14 | 2026-09 |
| Bench coverage | 47/47 scored · avg 7.77/10 | 50/50 scored · avg 7.57/10 |
The verdict — which should you pick?
Across 47 scored shared tasks, the averages are essentially tied — GLM-5.2 7.77 vs Claude Opus 5.5 7.60. This isn't the comparison where one wins; it's the comparison where you pick based on context, pricing, and what you're actually trying to ship.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire GLM-5.2 and Claude Opus 5.5 both into the Agent Operating System and dispatch each from the kanban by task type — long-context agent loops — pasting a whole codebase into one prompt → GLM-5.2, hardest agentic builds → Claude Opus 5.5. That's the same setup I run for the 4,000+ founders inside the AI Profit Boardroom.
FAQ — GLM-5.2 vs Claude Opus 5.5
Which is better, GLM-5.2 or Claude Opus 5.5?
On Goldie Bench, GLM-5.2 averages 7.77/10 across the shared tasks, with 5 gold, 0 silver, 0 bronze overall. Claude Opus 5.5 averages 7.60/10, with 0 gold, 0 silver, 1 bronze. Claude Opus 5.5 wins the head-to-head 22–21.
How much does GLM-5.2 cost vs Claude Opus 5.5?
GLM-5.2: Open-weights release: weights downloadable from Hugging Face for self-hosting, or runnable for free on z.ai for individuals (commercial use has separate licensing). Claude Opus 5.5: Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts.
What's the context window for GLM-5.2 vs Claude Opus 5.5?
GLM-5.2 has a 1,000,000 tokens context window. Claude Opus 5.5 has a 1,000,000 tokens context window.
When should I pick GLM-5.2 over Claude Opus 5.5?
Pick GLM-5.2 for: Long-context agent loops — pasting a whole codebase into one prompt; Cinematic visual builds — landing pages, voxel scenes, synthwave runners; Anyone who needs to run a frontier coder locally for $0. The trade-off is the weaknesses we logged on the bench: Faceplanted on the {{SITE_NAME}} raycaster — the engine was great but it spawned the player inside a wall; First-shot reliability lags Opus by a hair on consistency.
When should I pick Claude Opus 5.5 over GLM-5.2?
Pick Claude Opus 5.5 for: Hardest agentic builds; Whole-repo reasoning; Frontier one-shots. The trade-off is the weaknesses we logged on the bench: Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes; One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts).
How does Goldie Bench score GLM-5.2 vs Claude Opus 5.5?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
GLM-5.2 vs Fusion Claude Opus 5.5 vs Fusion GLM-5.2 vs Claude Opus 5 Claude Opus 5.5 vs Claude Opus 5 GLM-5.2 vs Hermes MoA Claude Opus 5.5 vs Hermes MoA GLM-5.2 vs GPT-5.6 Sol Claude Opus 5.5 vs GPT-5.6 SolFull model pages: GLM-5.2 · Claude Opus 5.5 · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.
4,000+founders
258documented wins
38countries
$59/momonthly