Real head-to-head · same prompt, one shot
Fugu Ultra vs Claude Opus 5.5
Sakana's multi-agent answer to Fusion — frontier ensemble without single-vendor risk. vs Anthropic's Opus 5.5 — benched on all 50 one-shot builds, every game playtested.
Head-to-head verdict: Fugu Ultra wins 28–13 with 1 tie.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to Fugu Ultra and Claude Opus 5.5, side by side, on 42 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
Fugu Ultra · Dispatched from Agent OS as the panel-ensemble alternative to OpenRouter Fusion. Bench scored by Claude judge against the same 42 prompts as every other model.
Claude Opus 5.5 · Benched on all 50 GoldieBench tasks via a Claude subscription: one-shot builds, real renders, pixel-diff playtests on every game, then vision-judged.
Side-by-side on 50 shared tasks
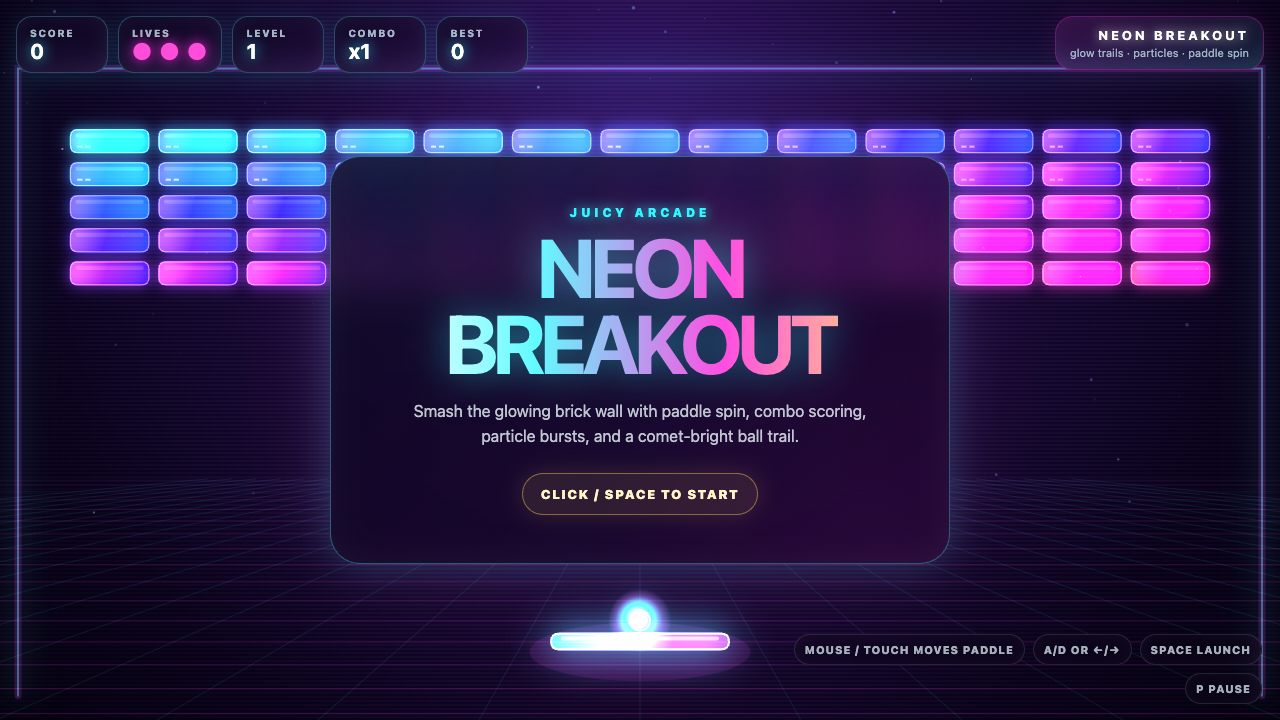
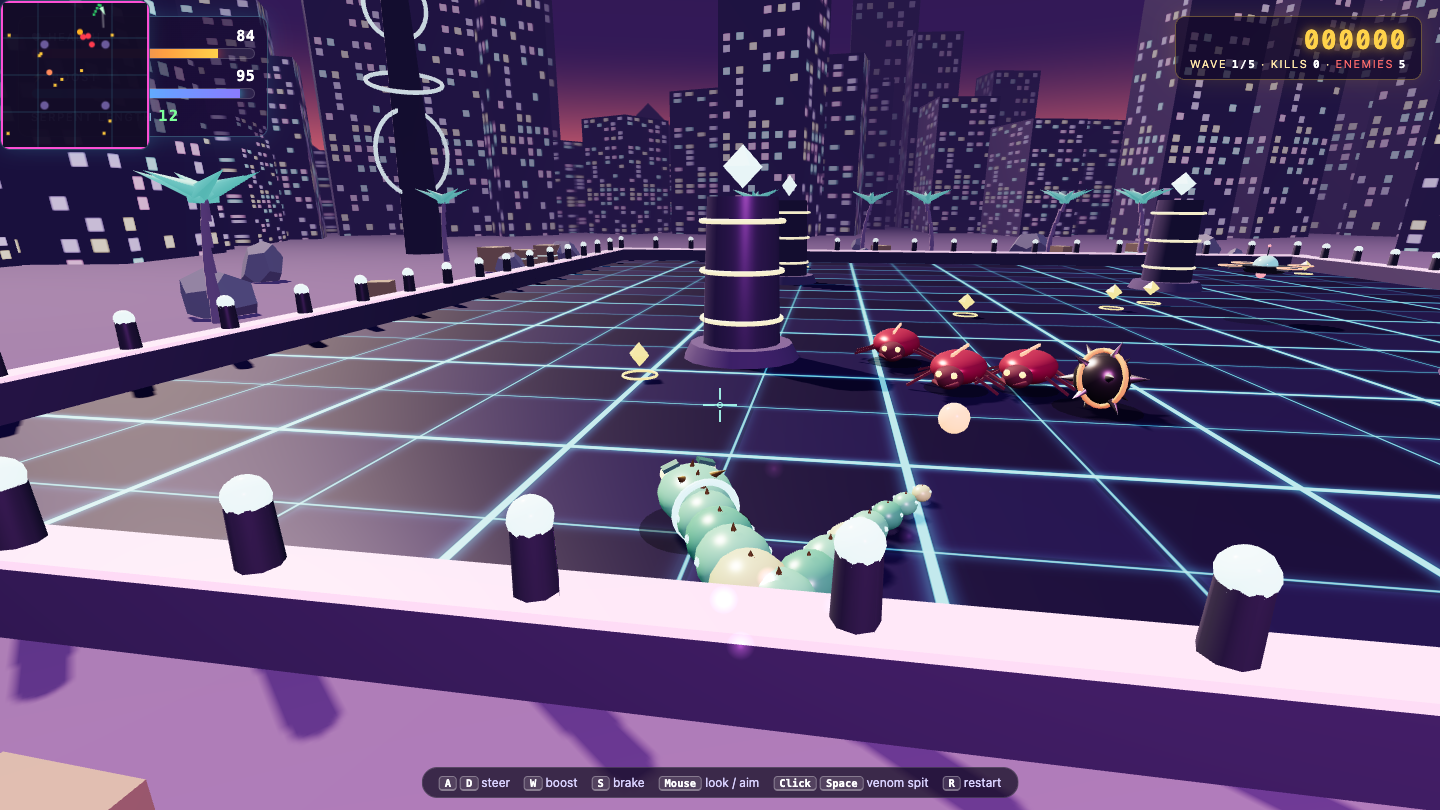
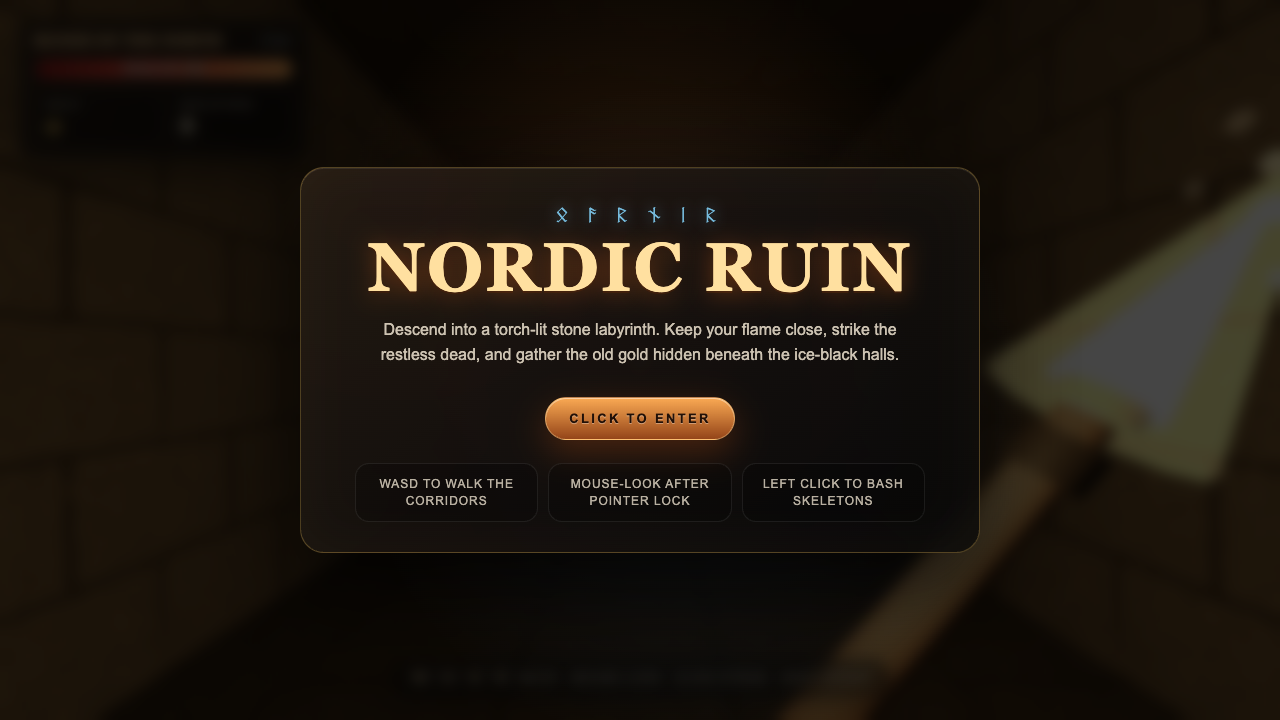
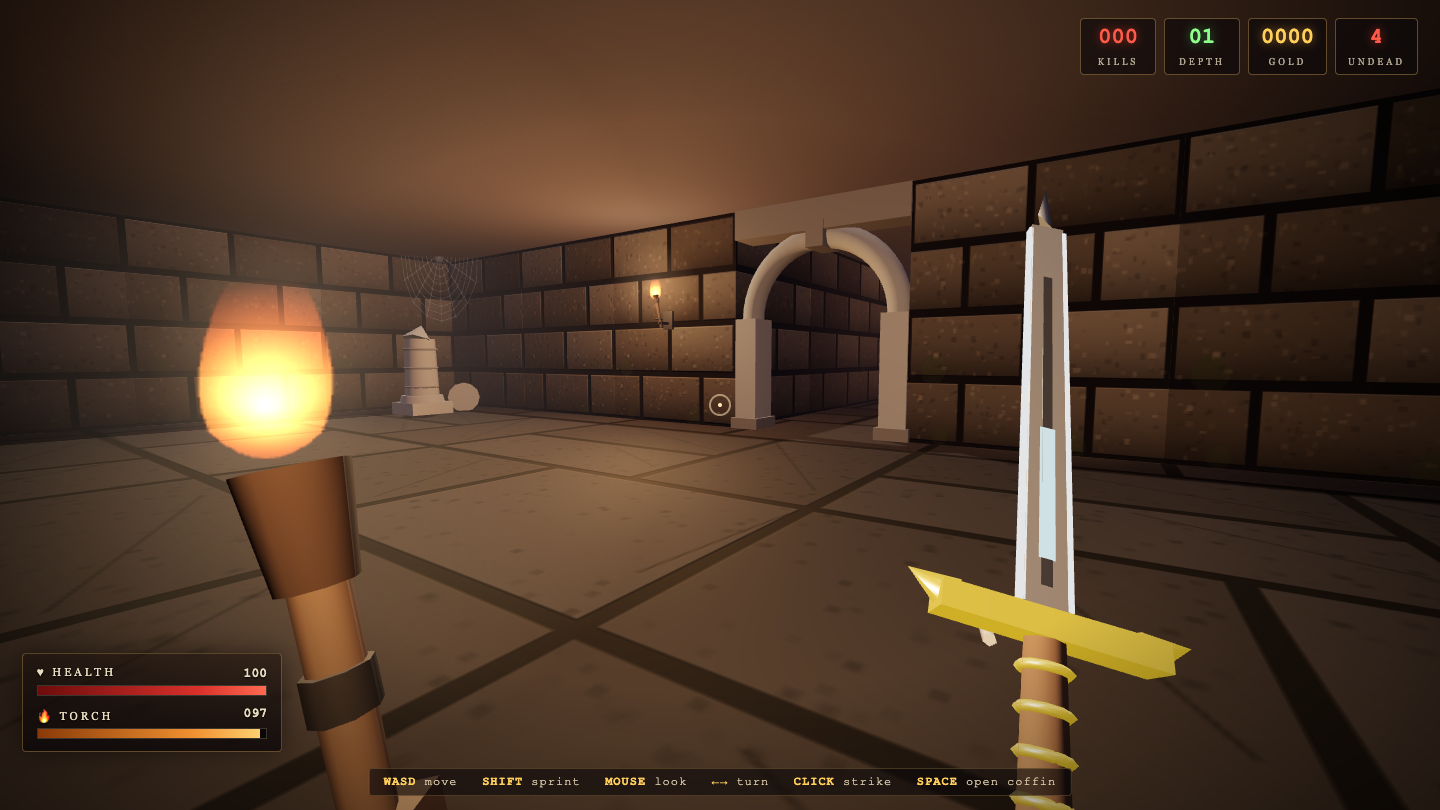
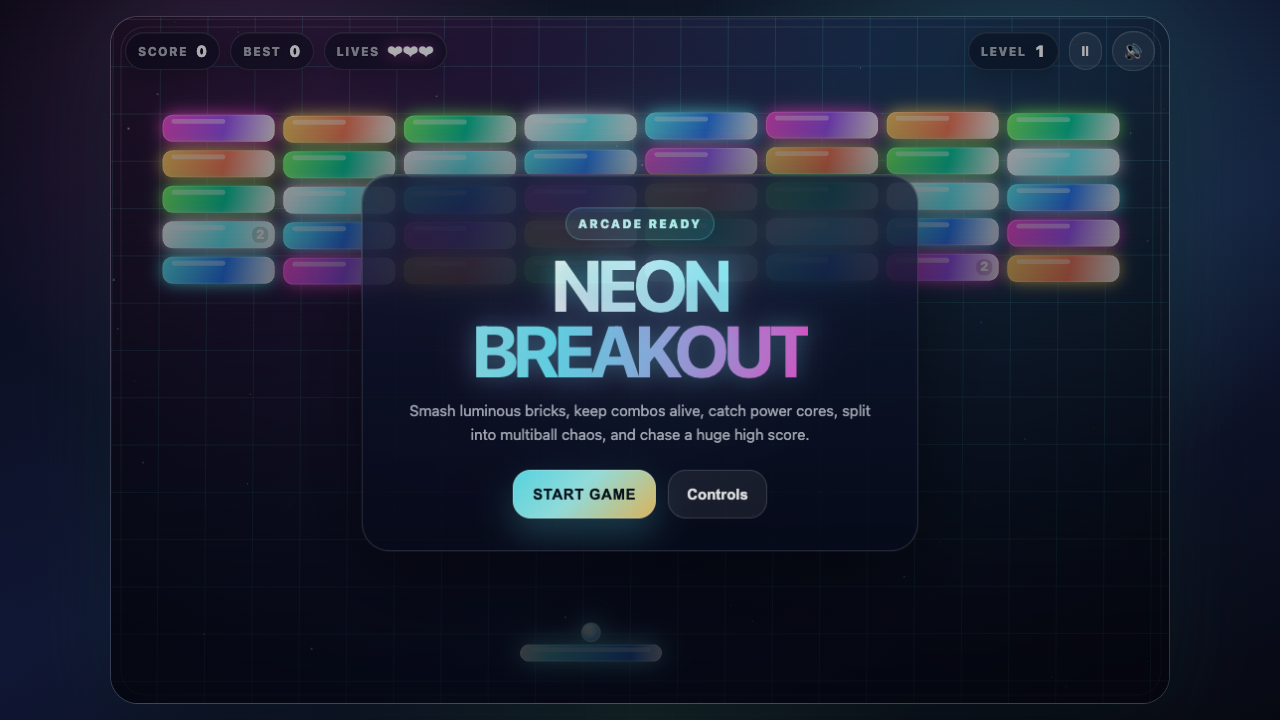
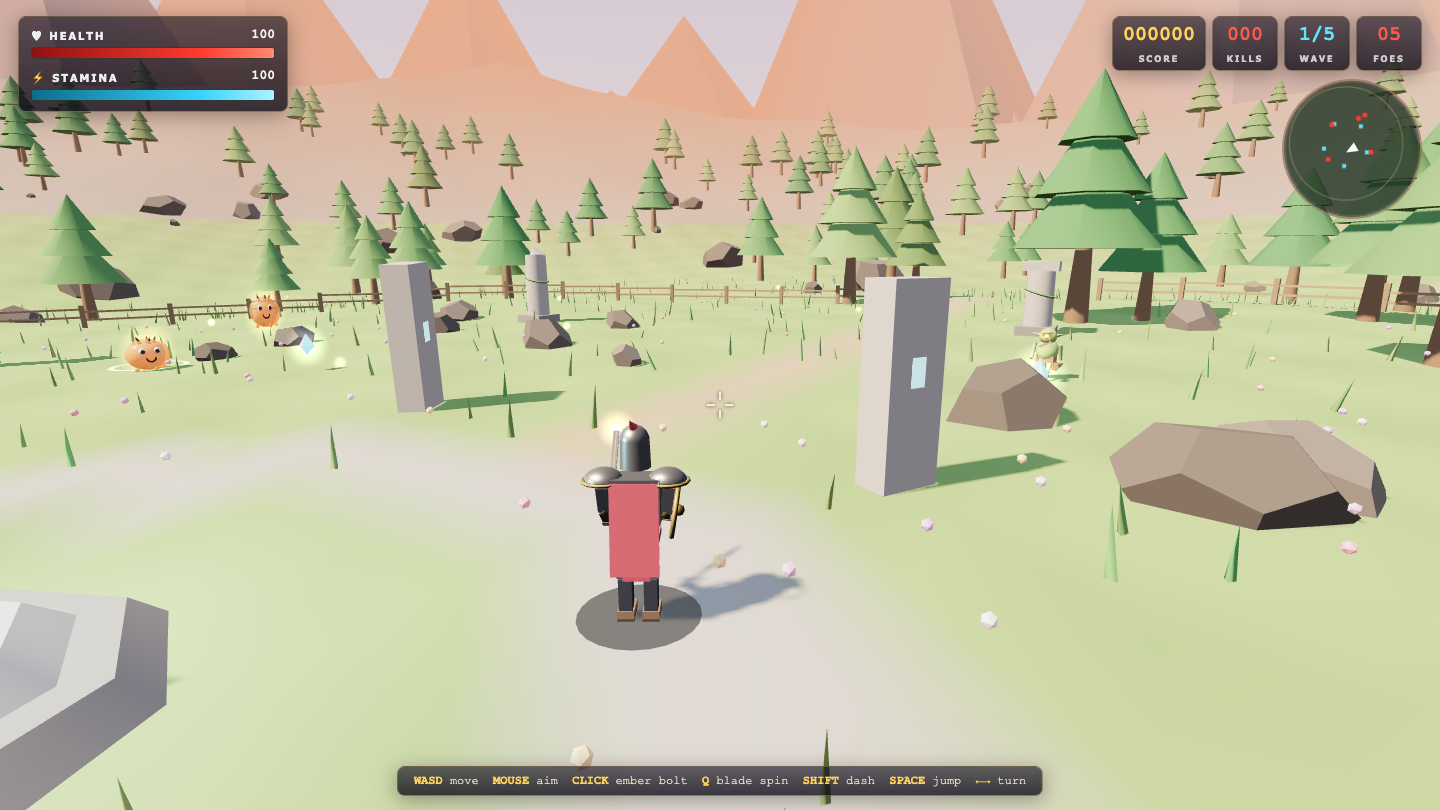
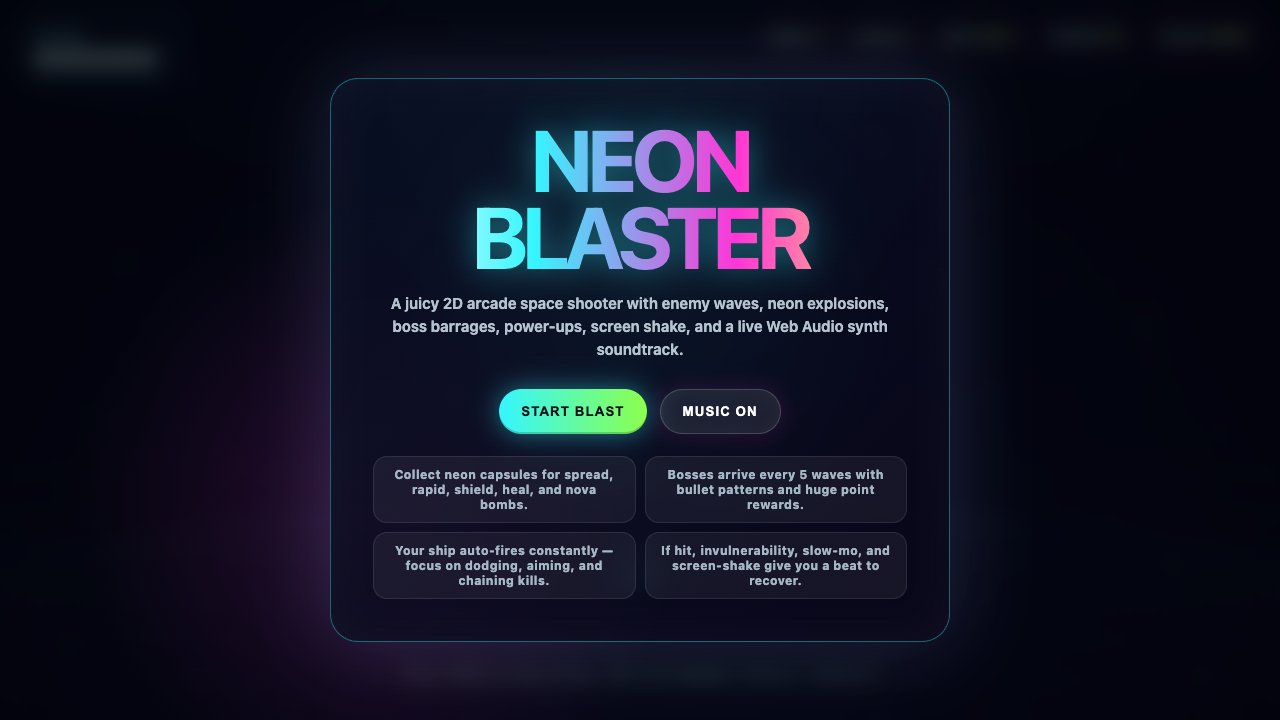
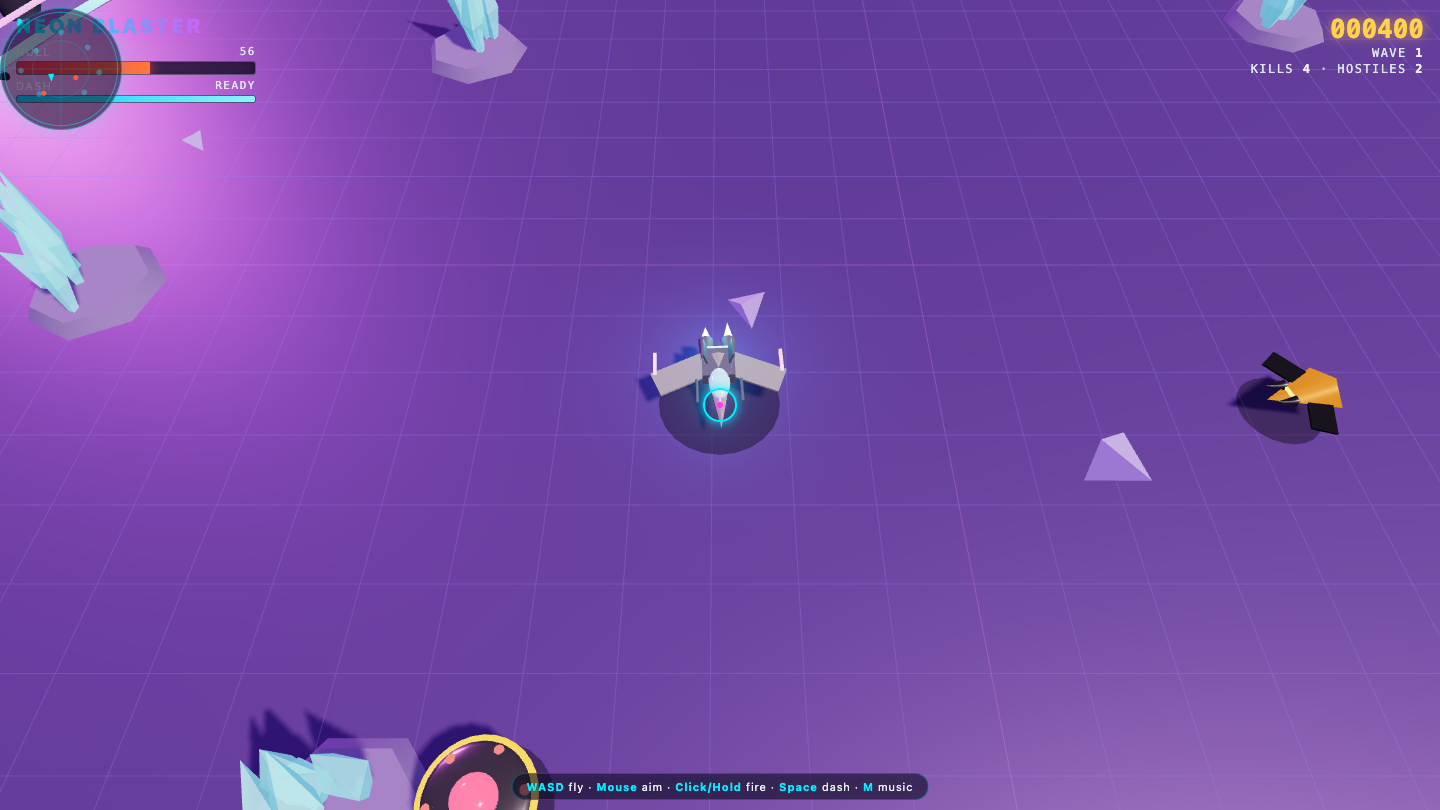
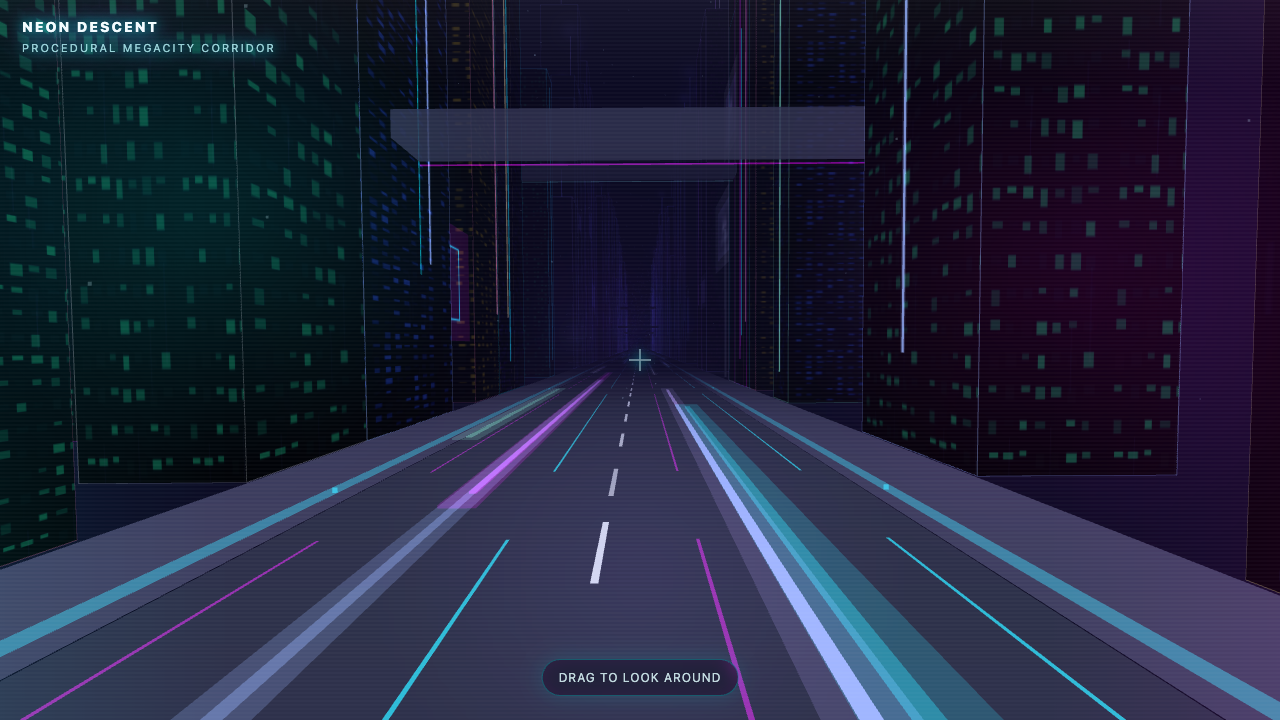
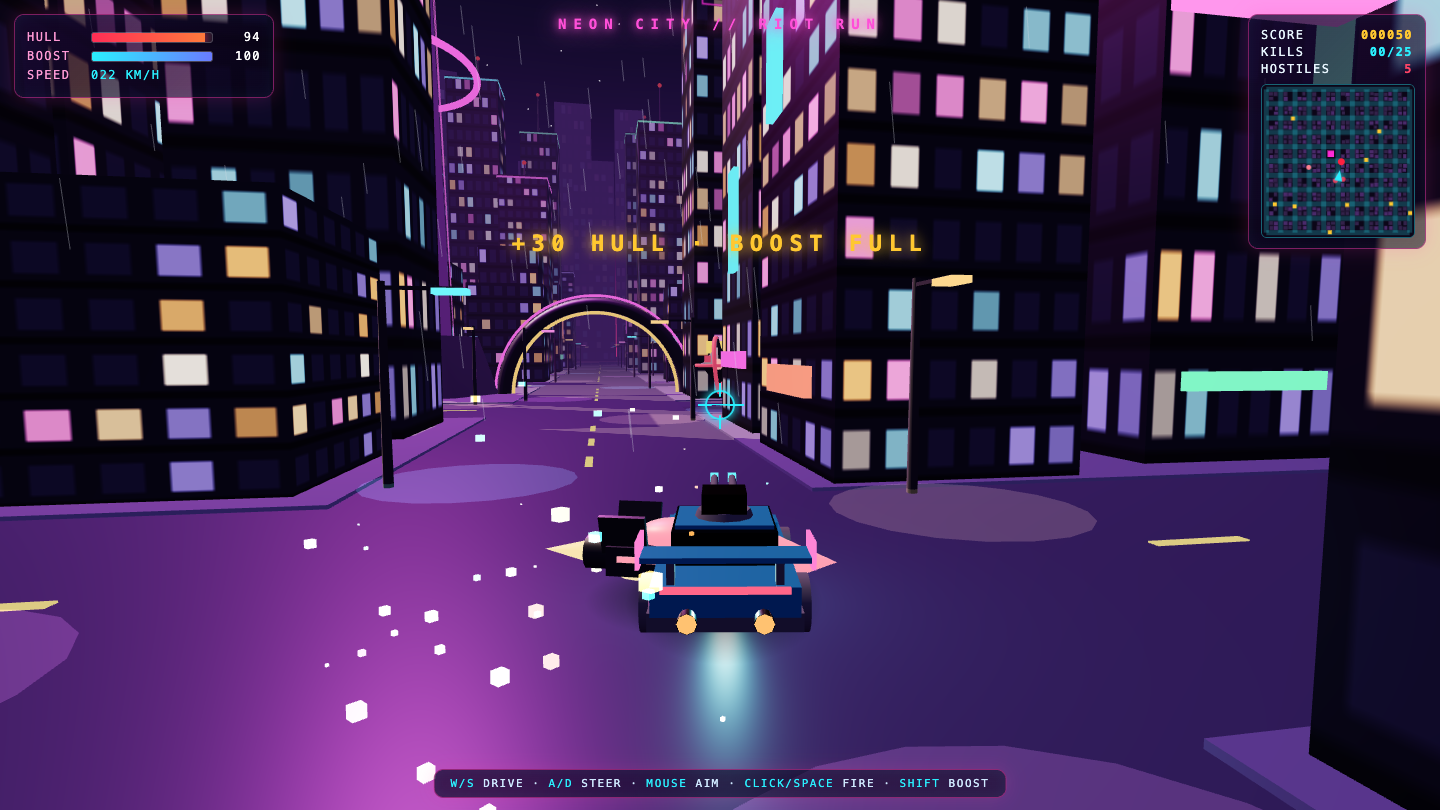
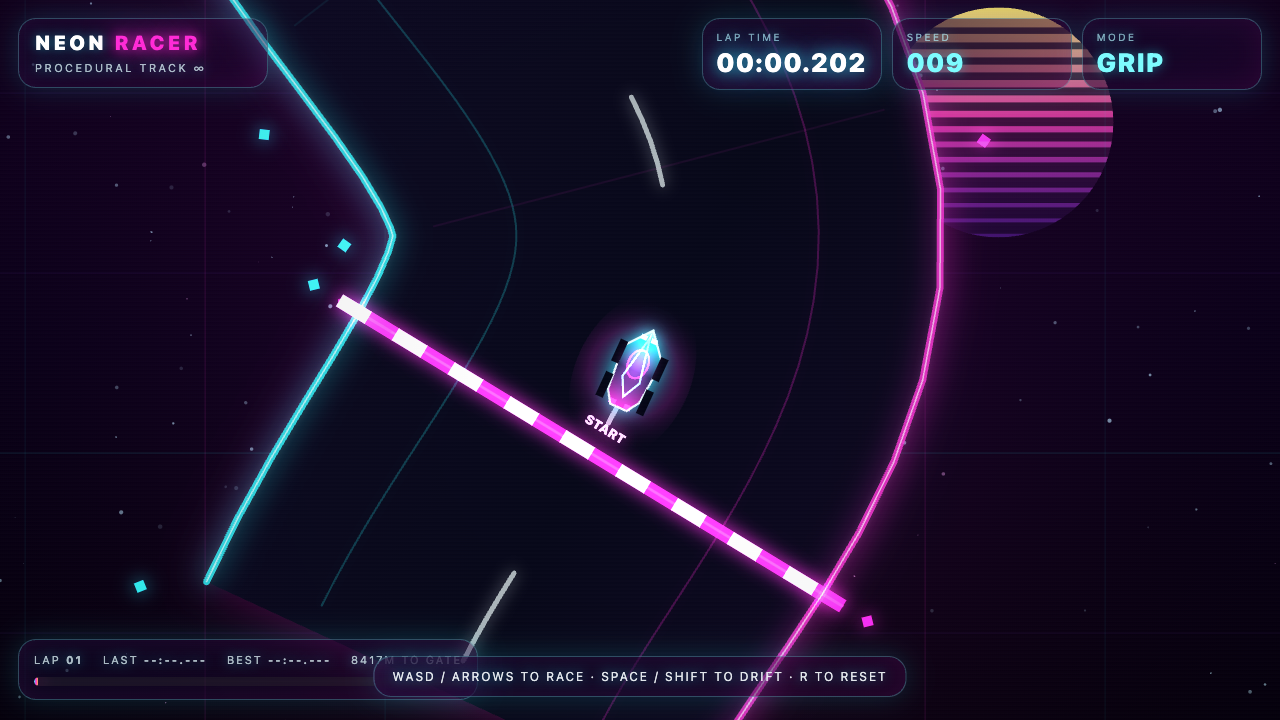
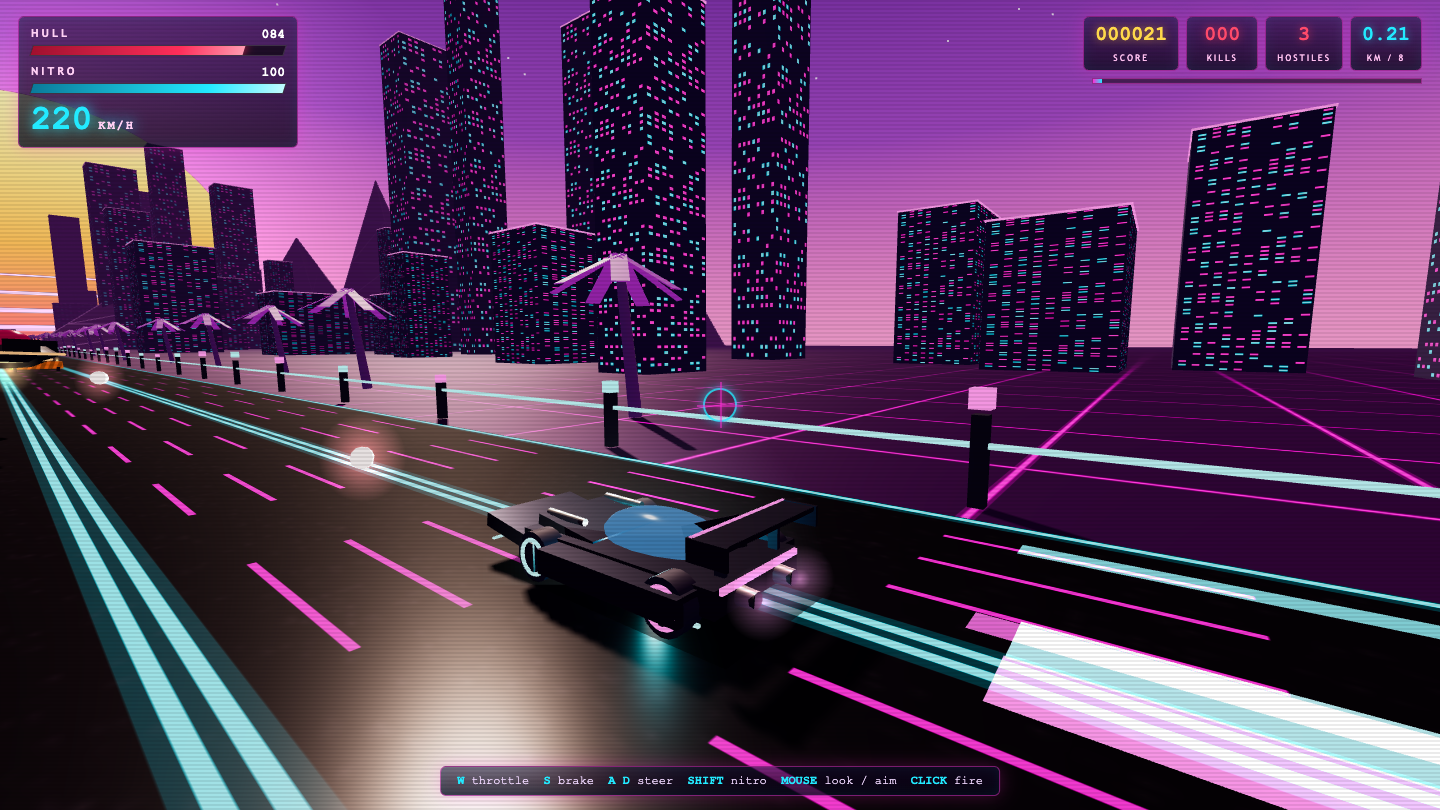
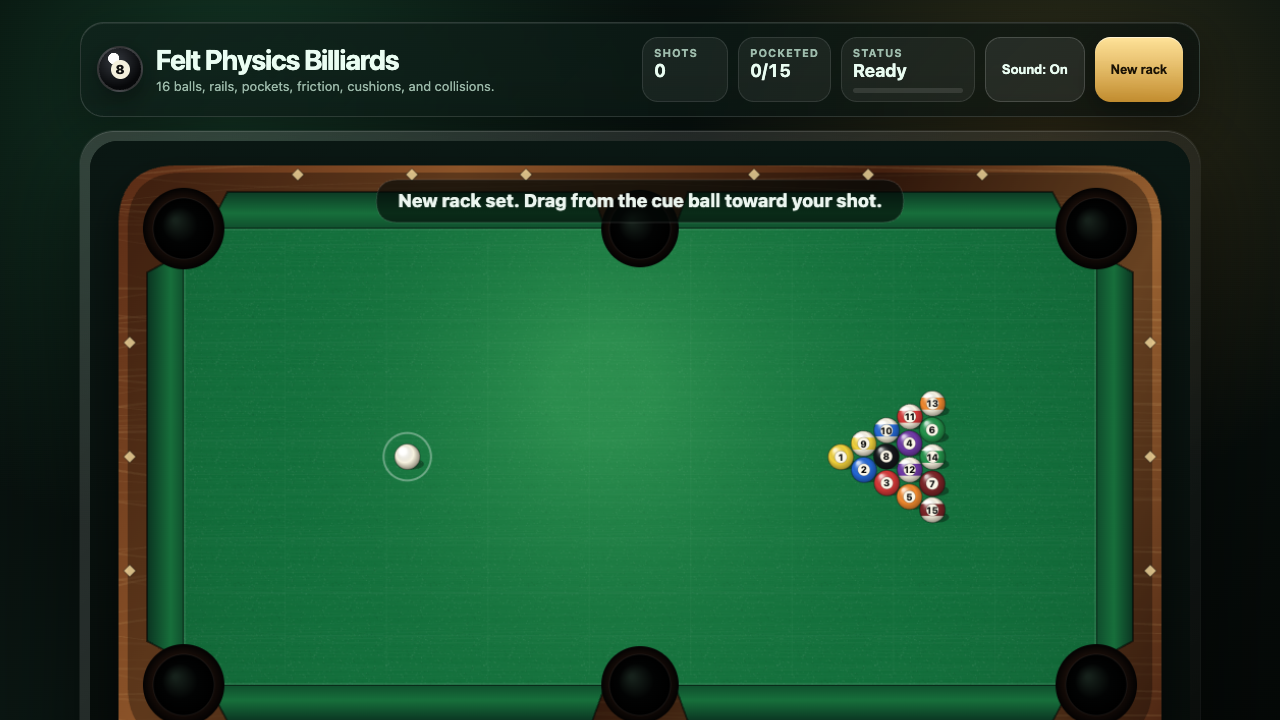
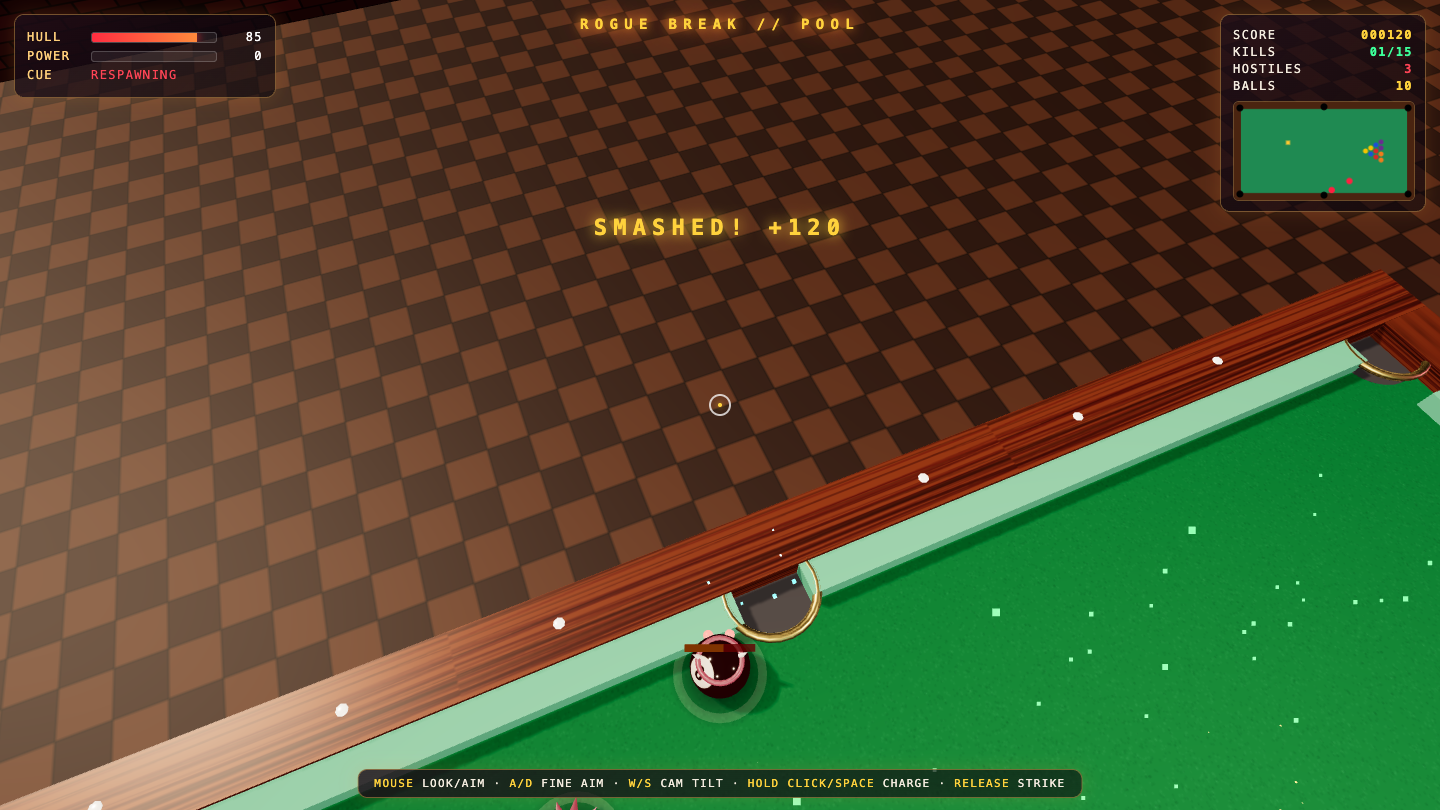
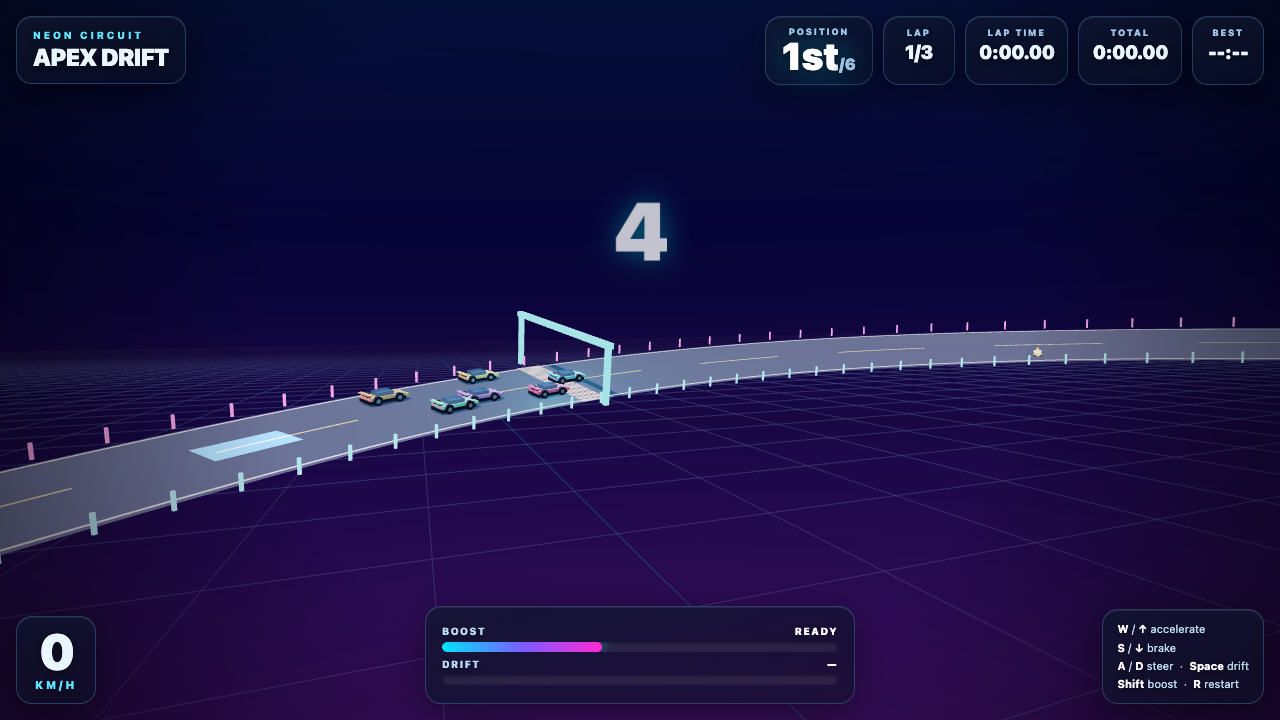
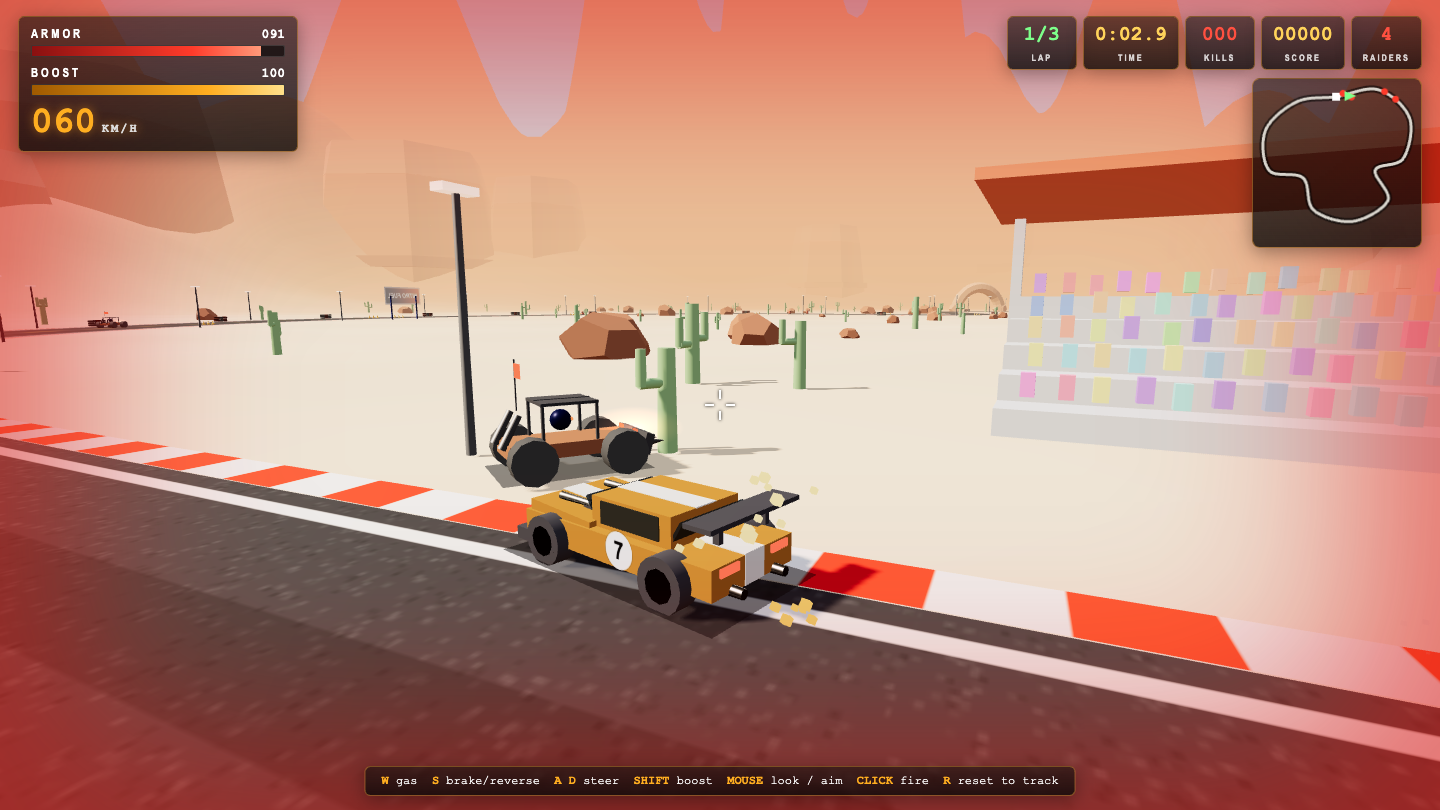
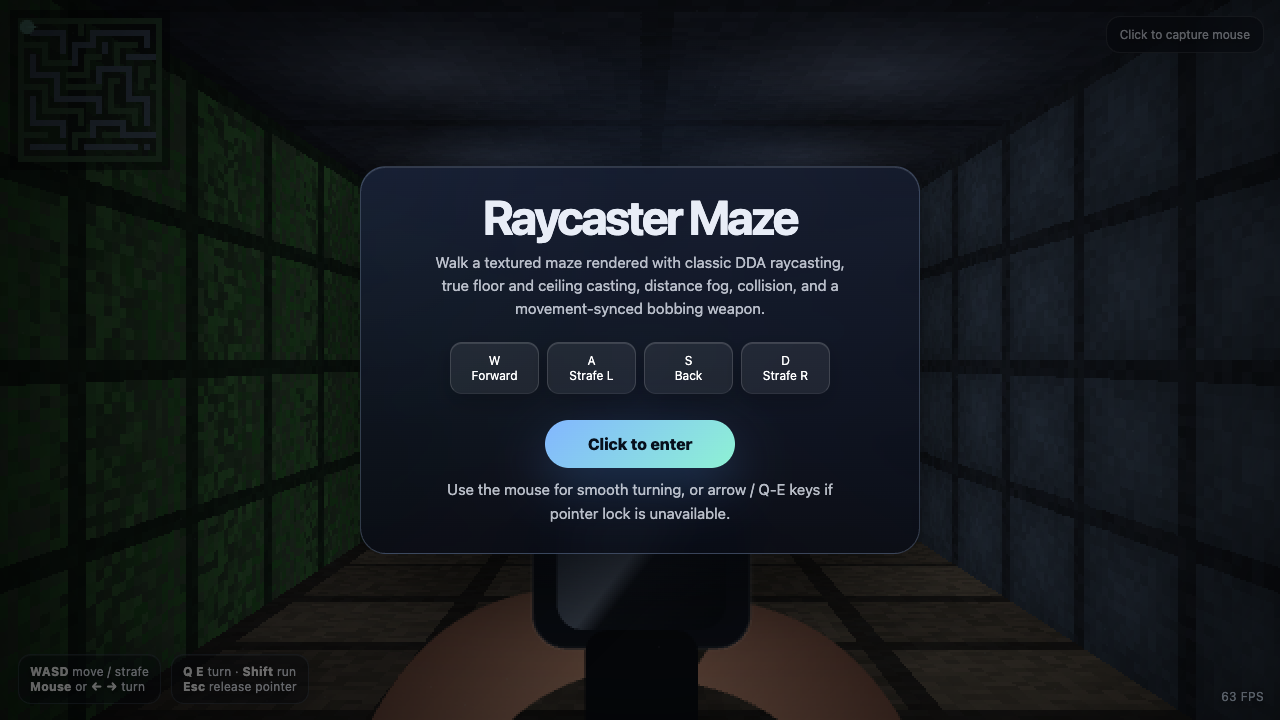
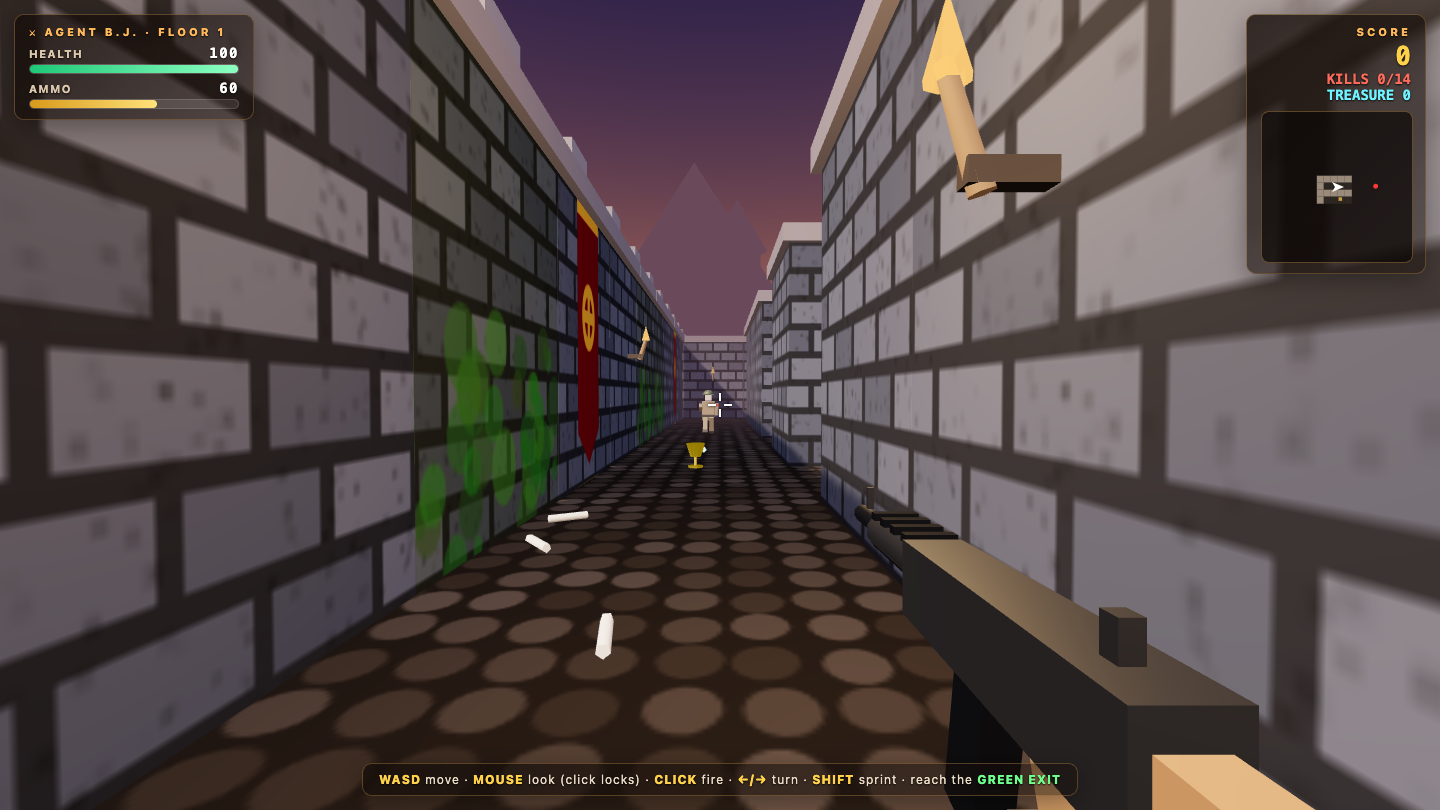
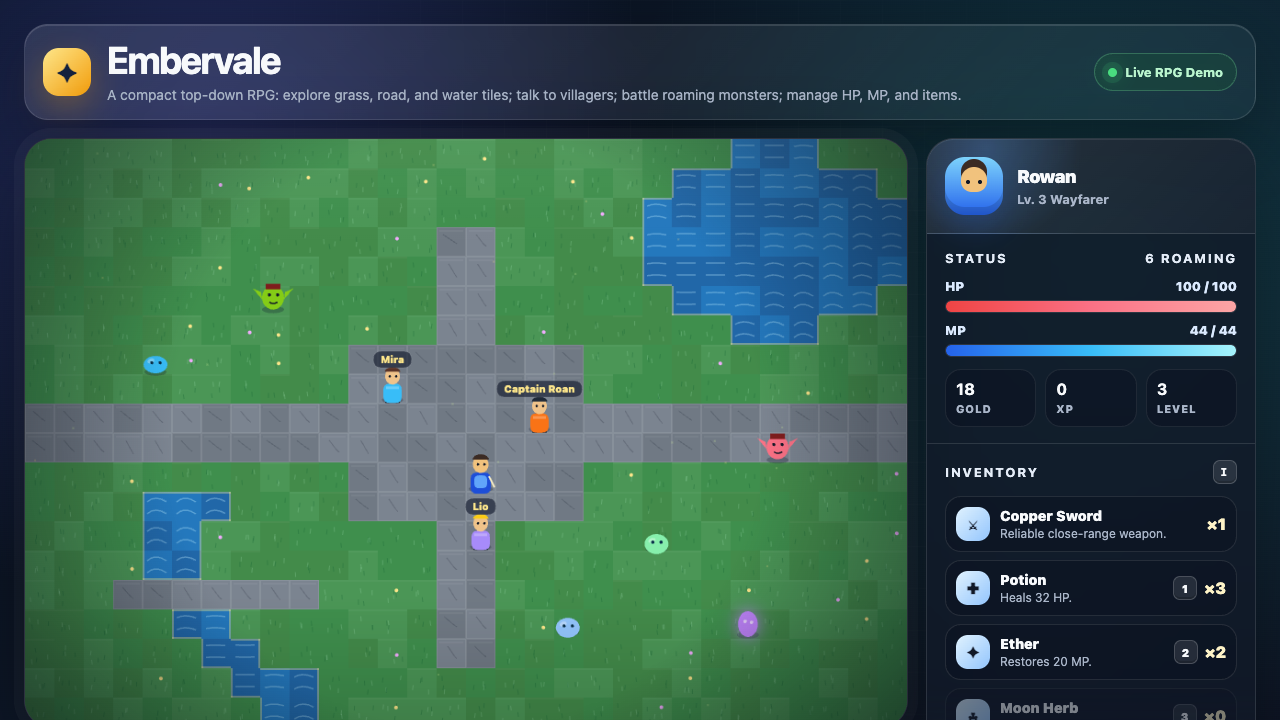
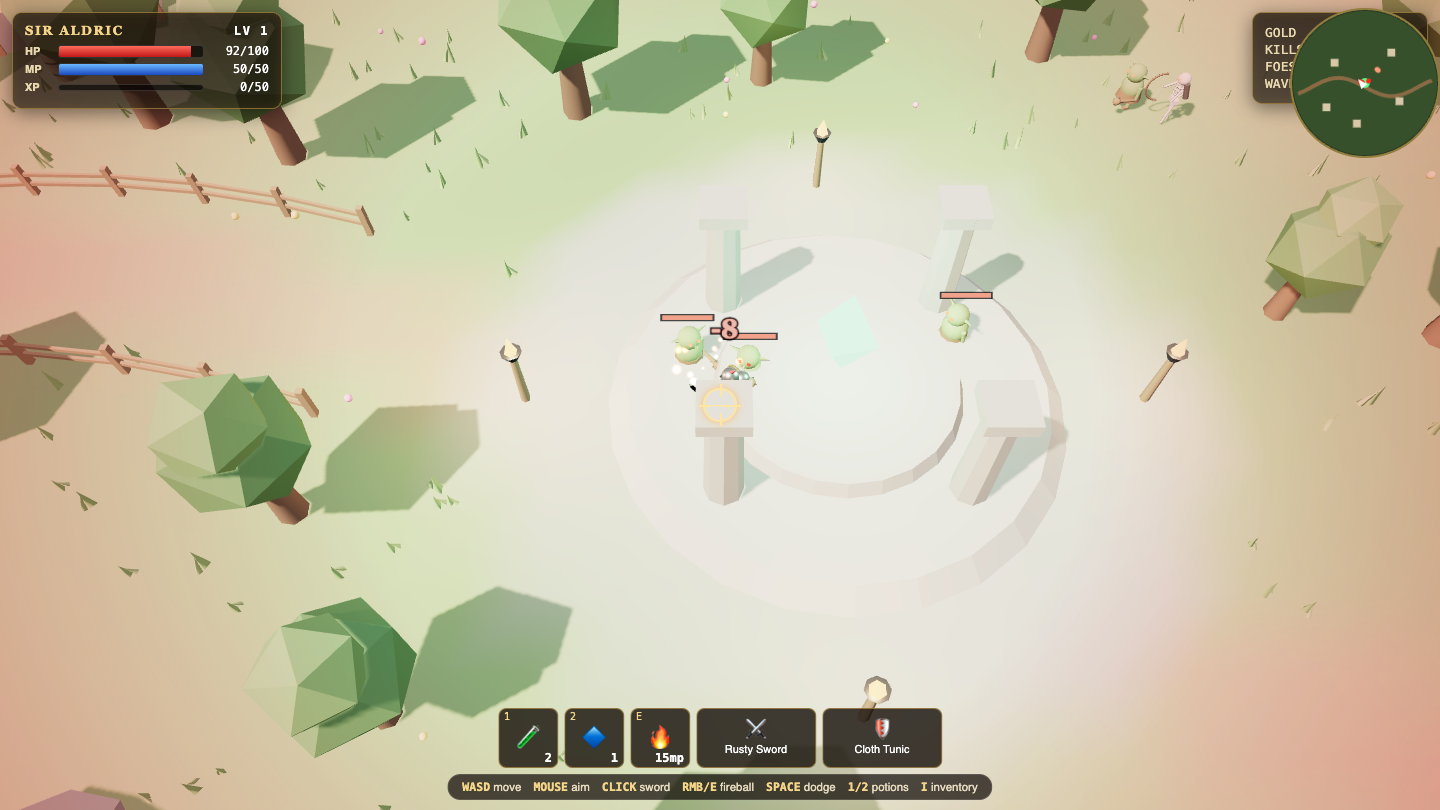
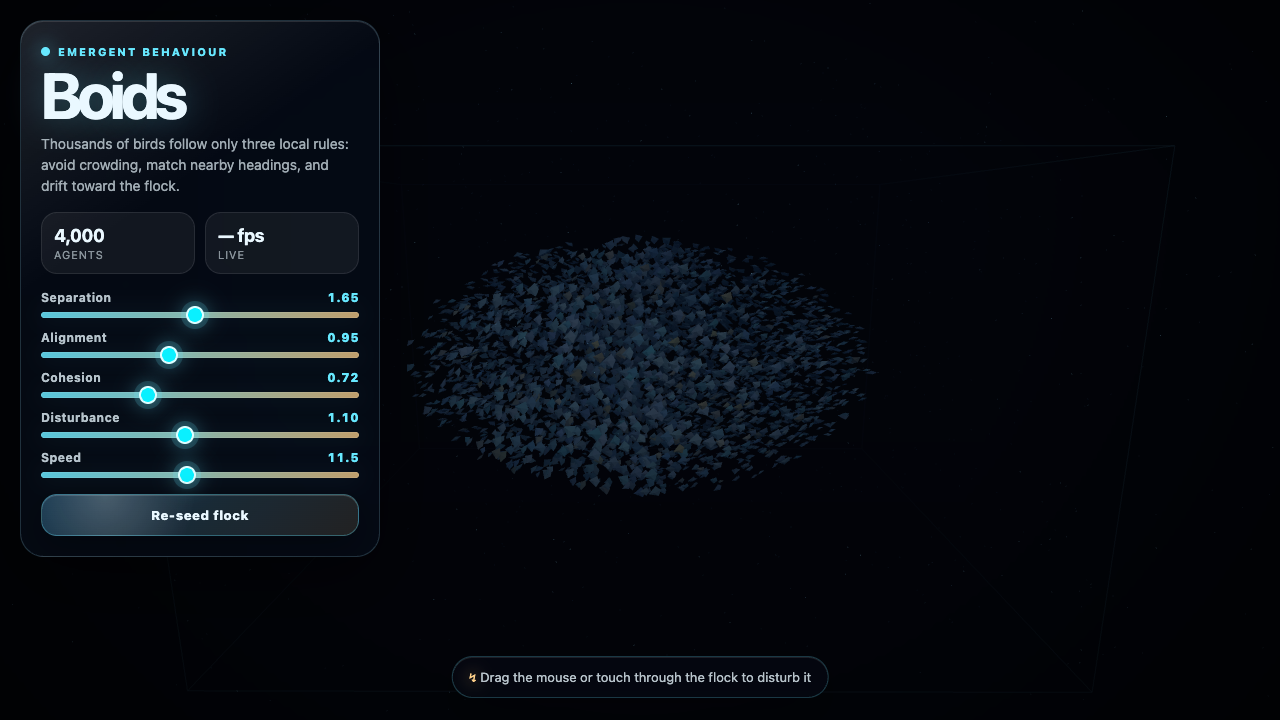
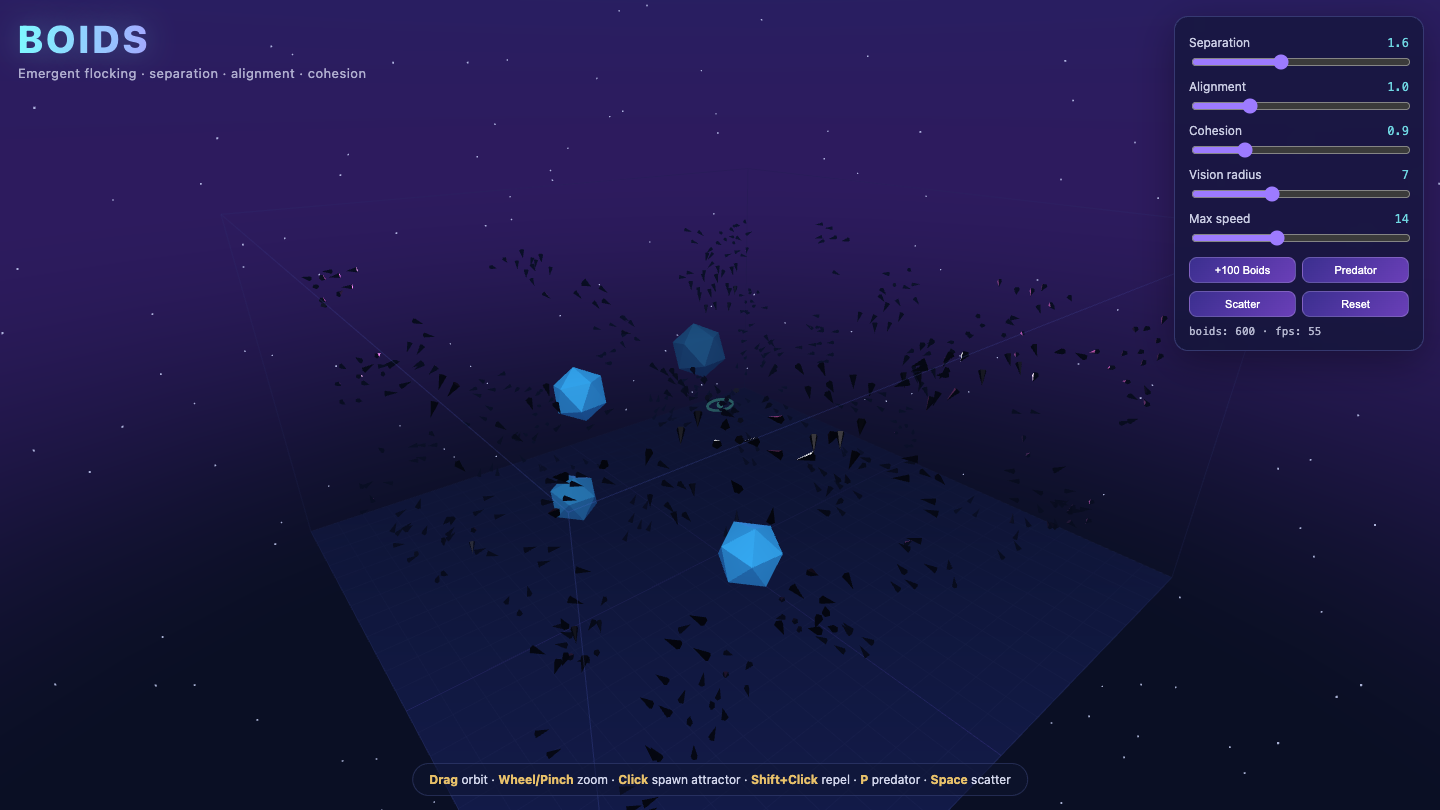
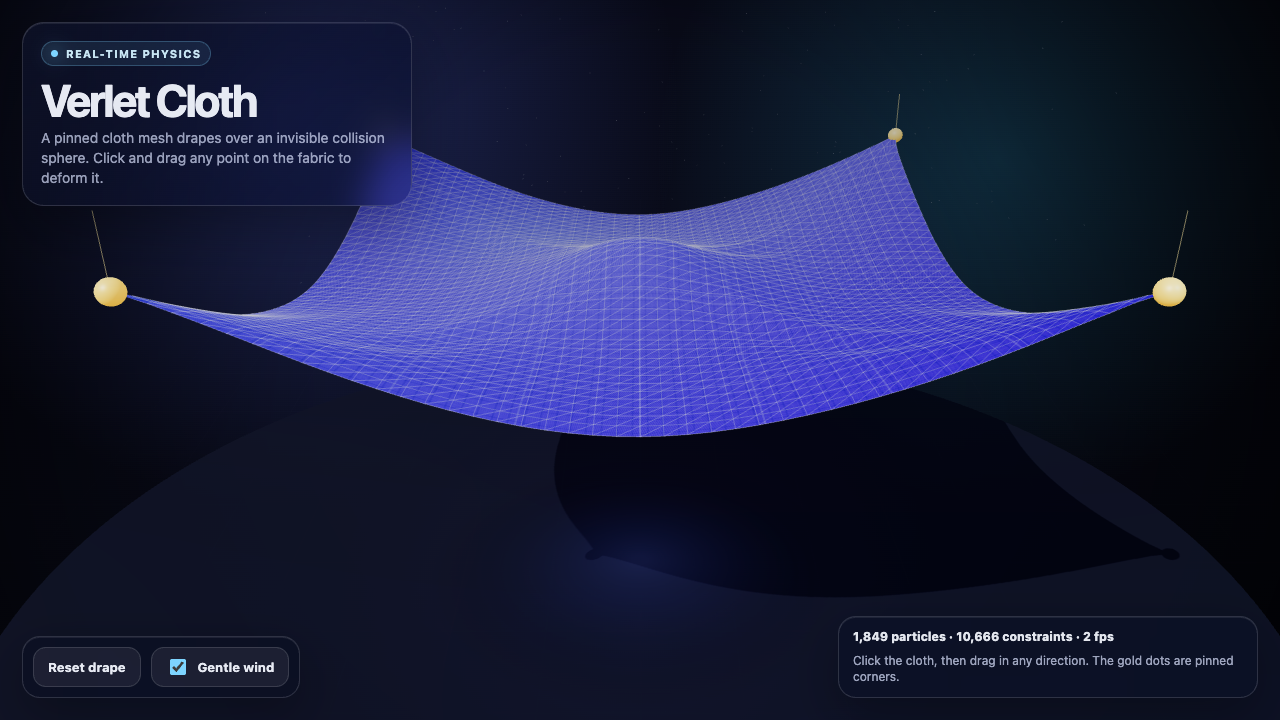
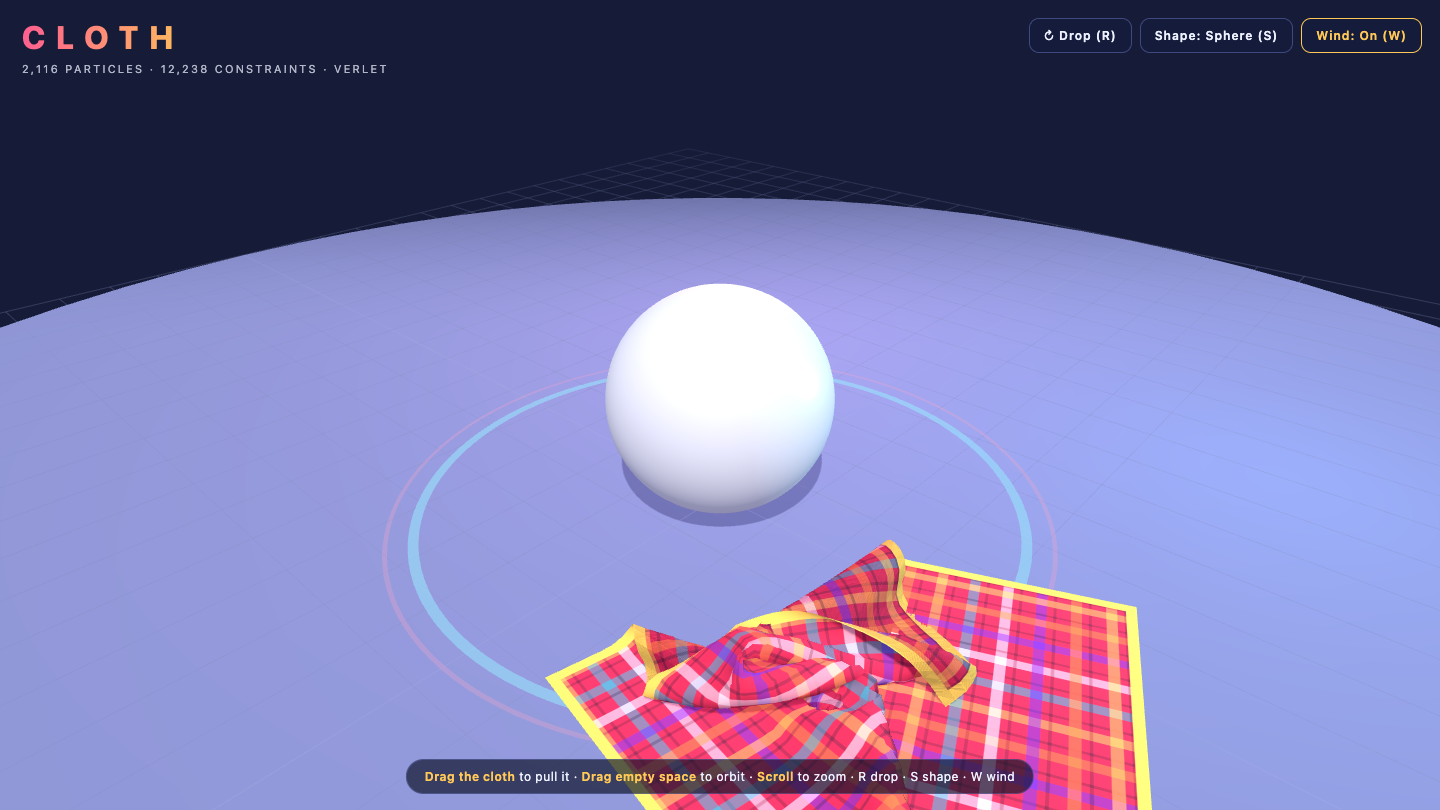
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
Fugu Ultra
Claude Opus 5.5
Game
Game
Game
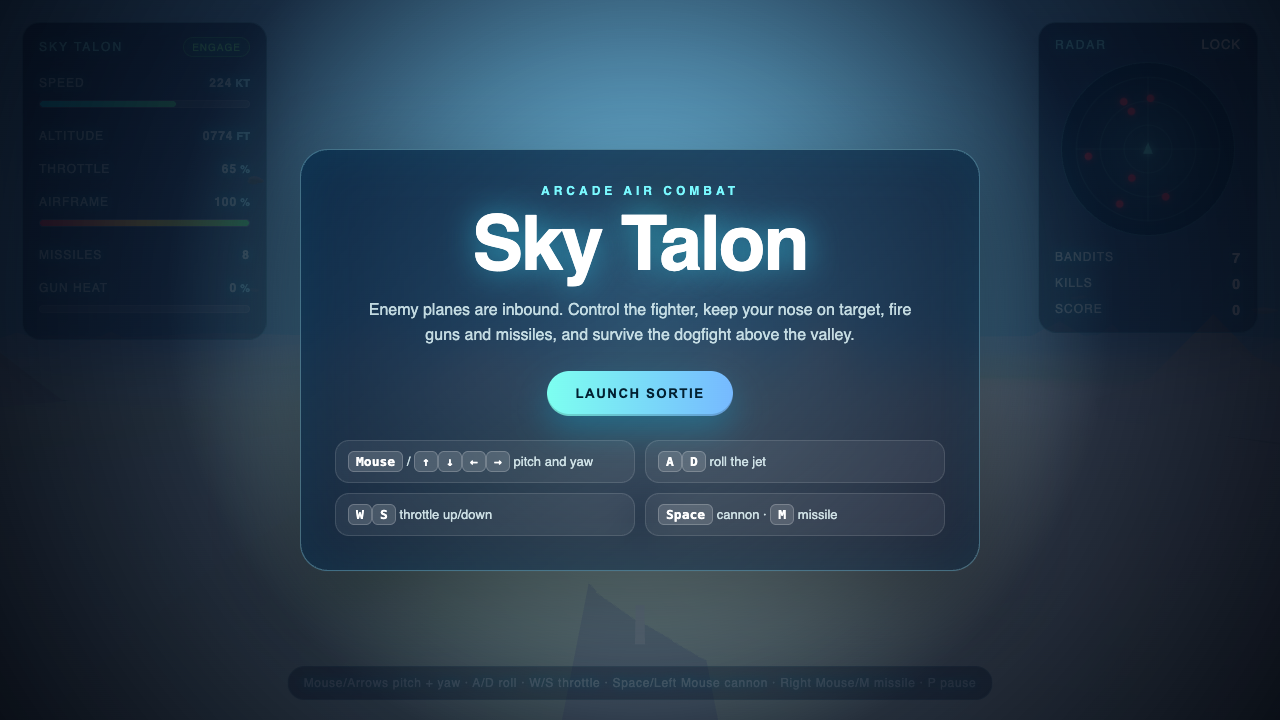
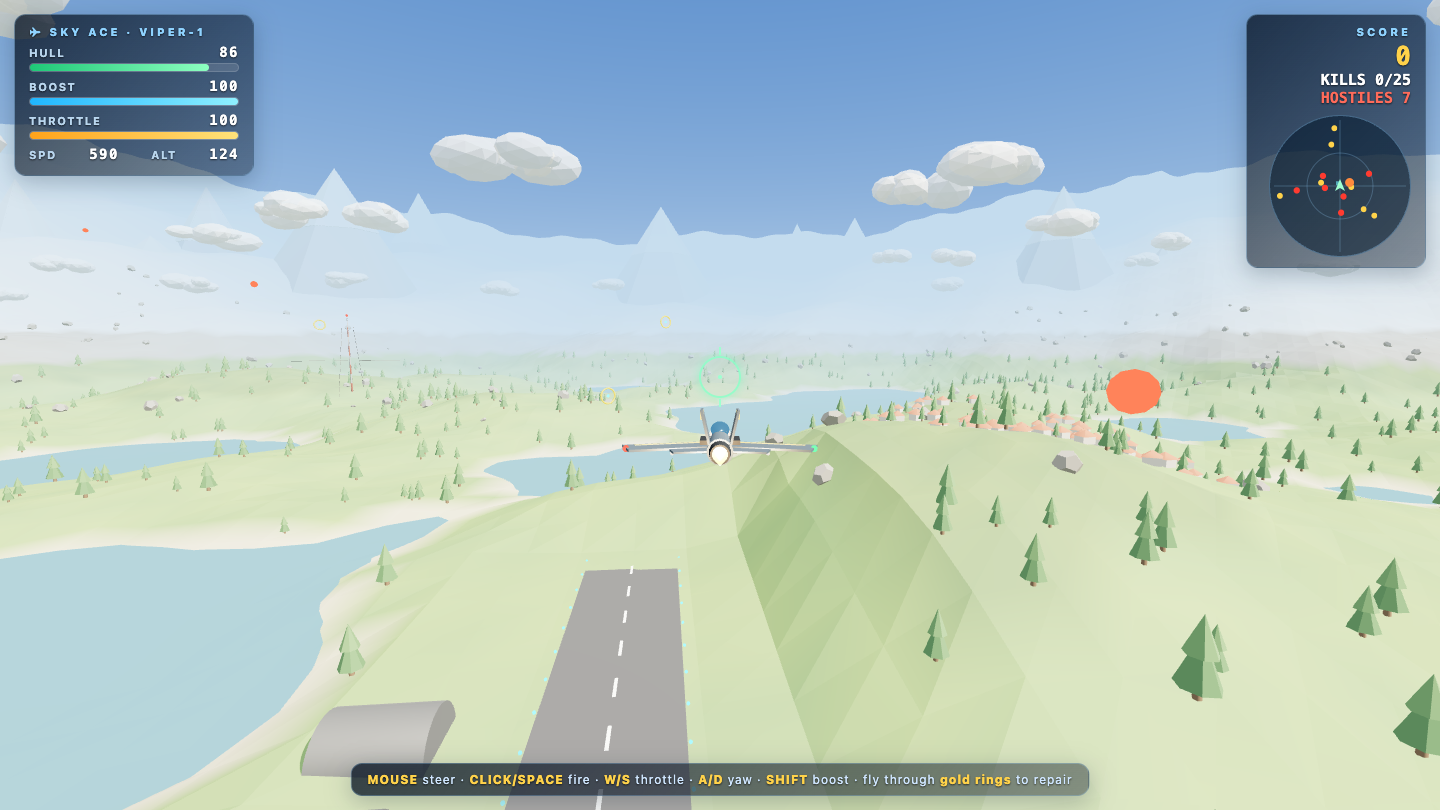
Game
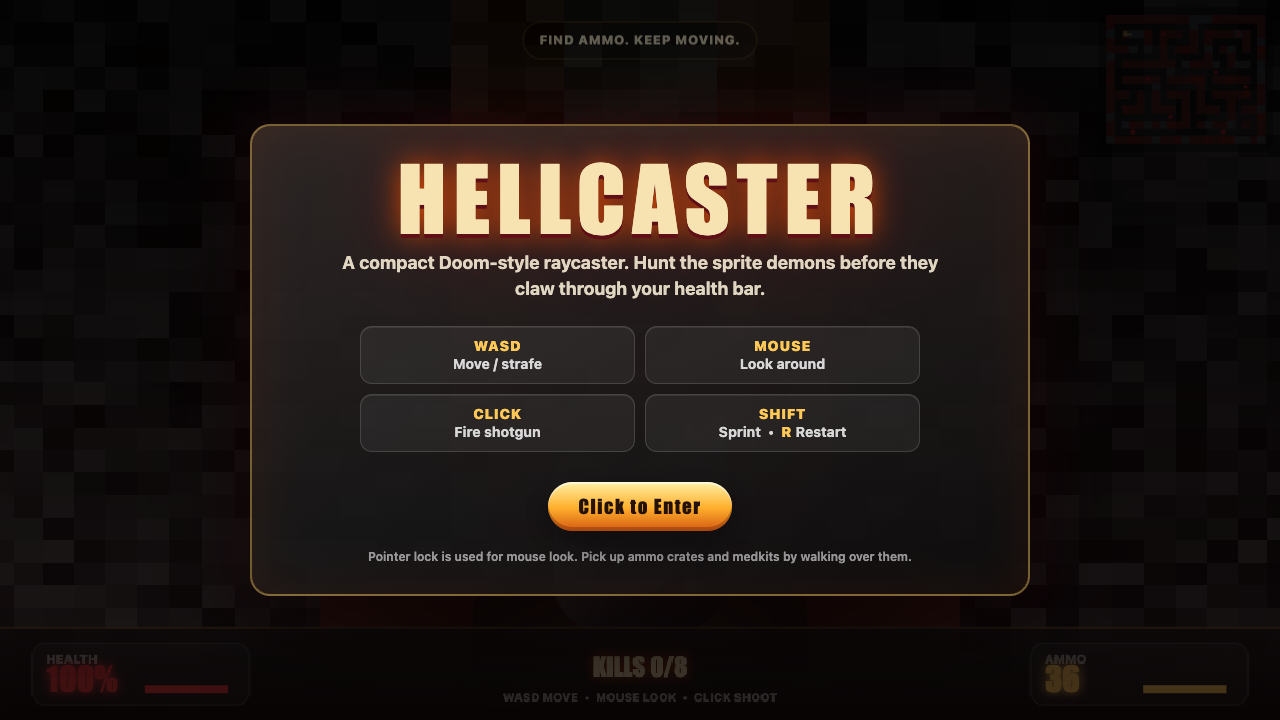
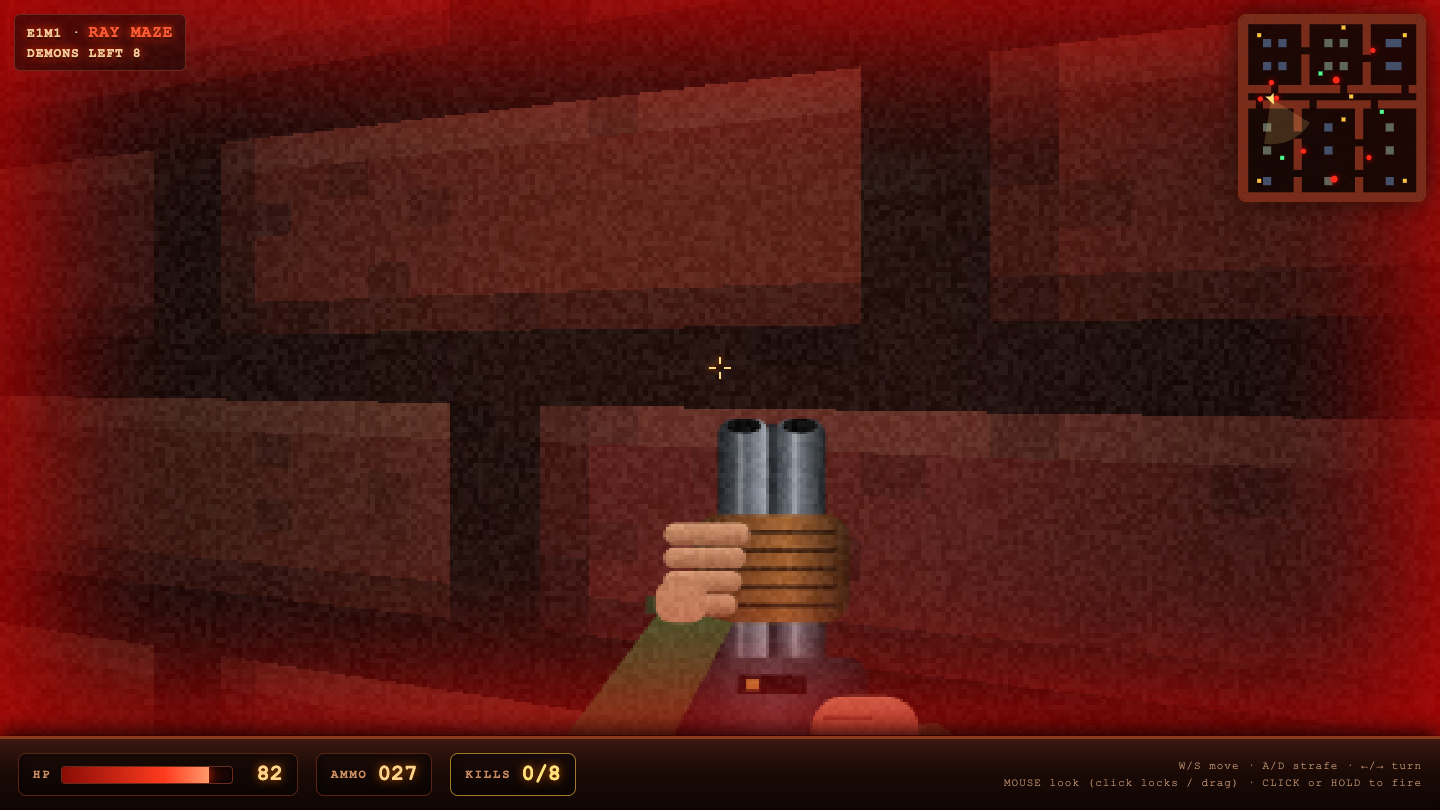
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
Page
Page
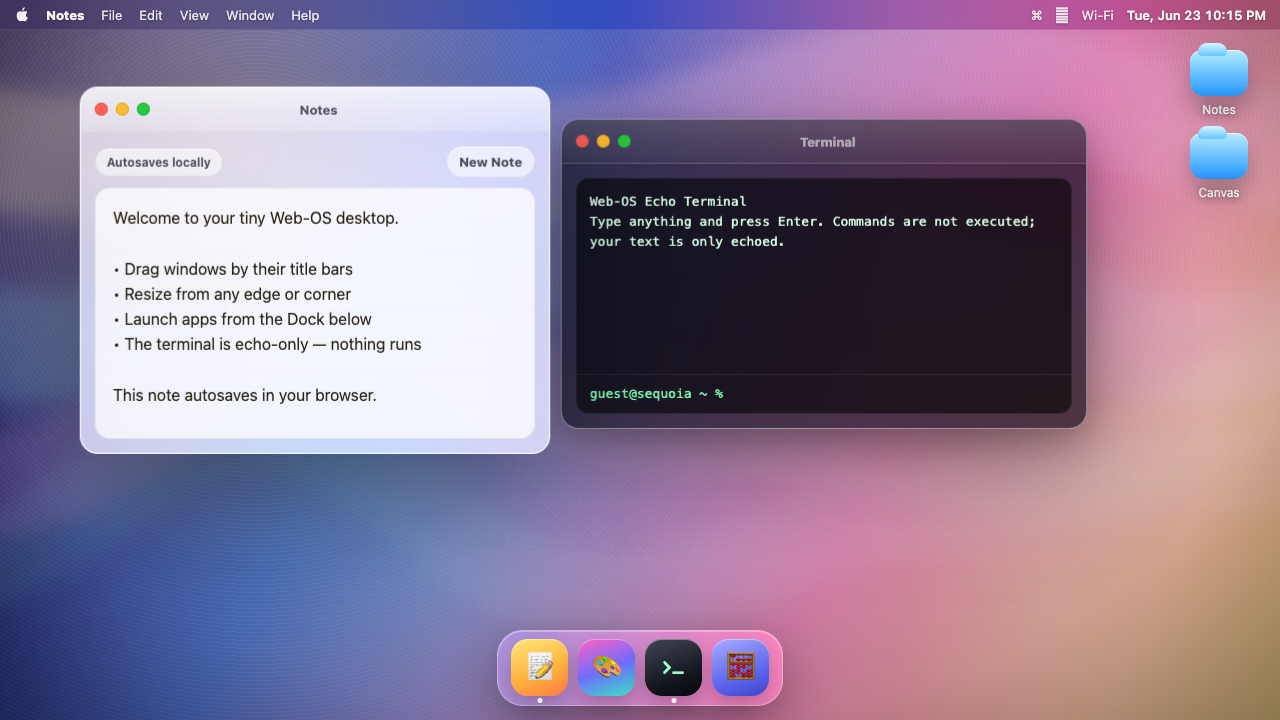
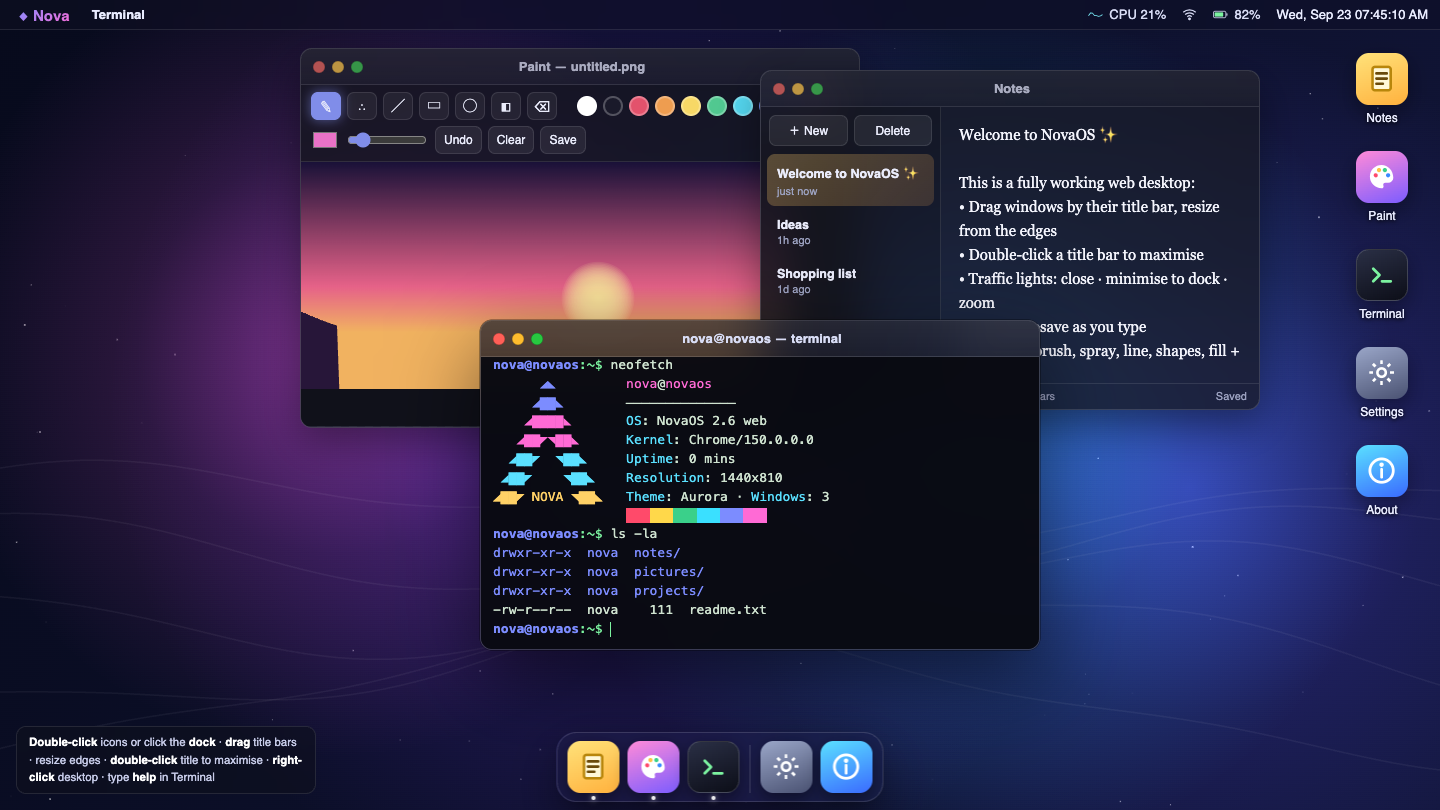
Sim
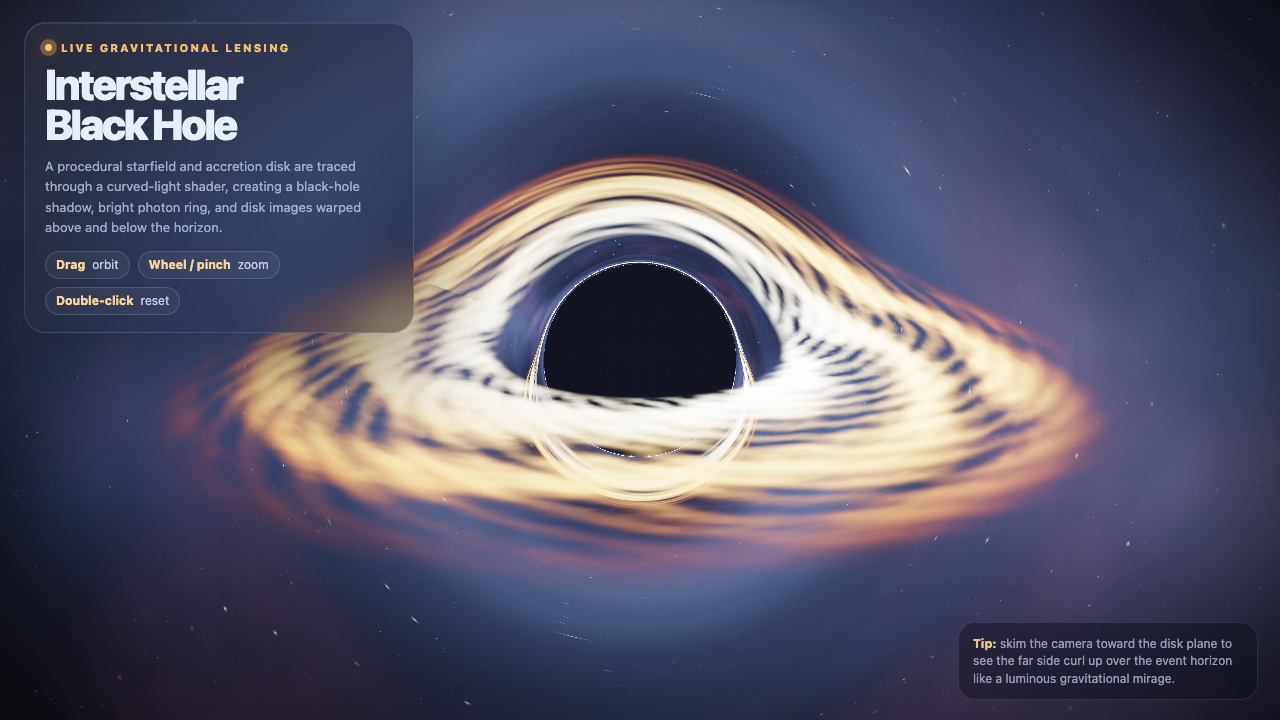
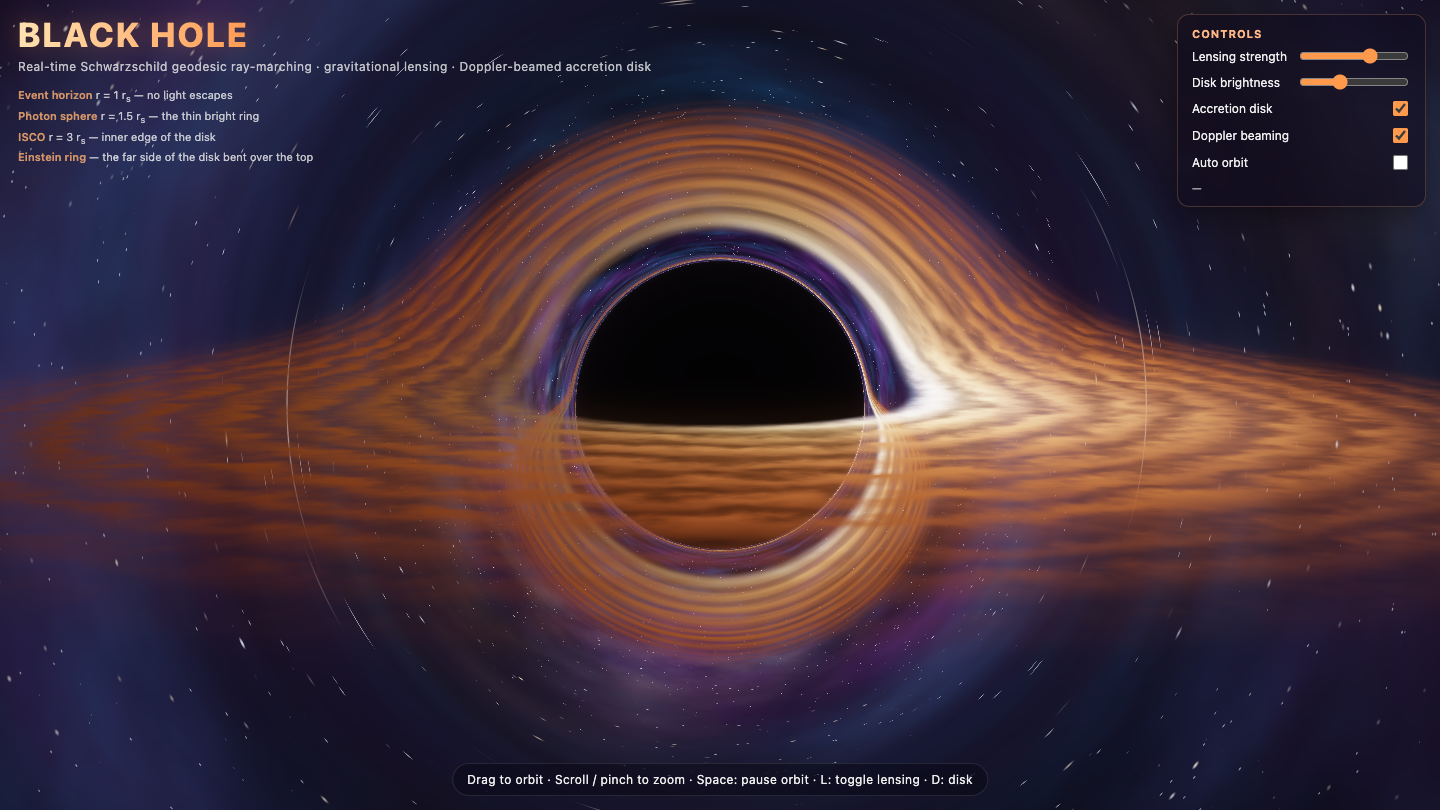
Sim
Sim
Where Fugu Ultra beat Claude Opus 5.5
The tasks where I gave Fugu Ultra a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
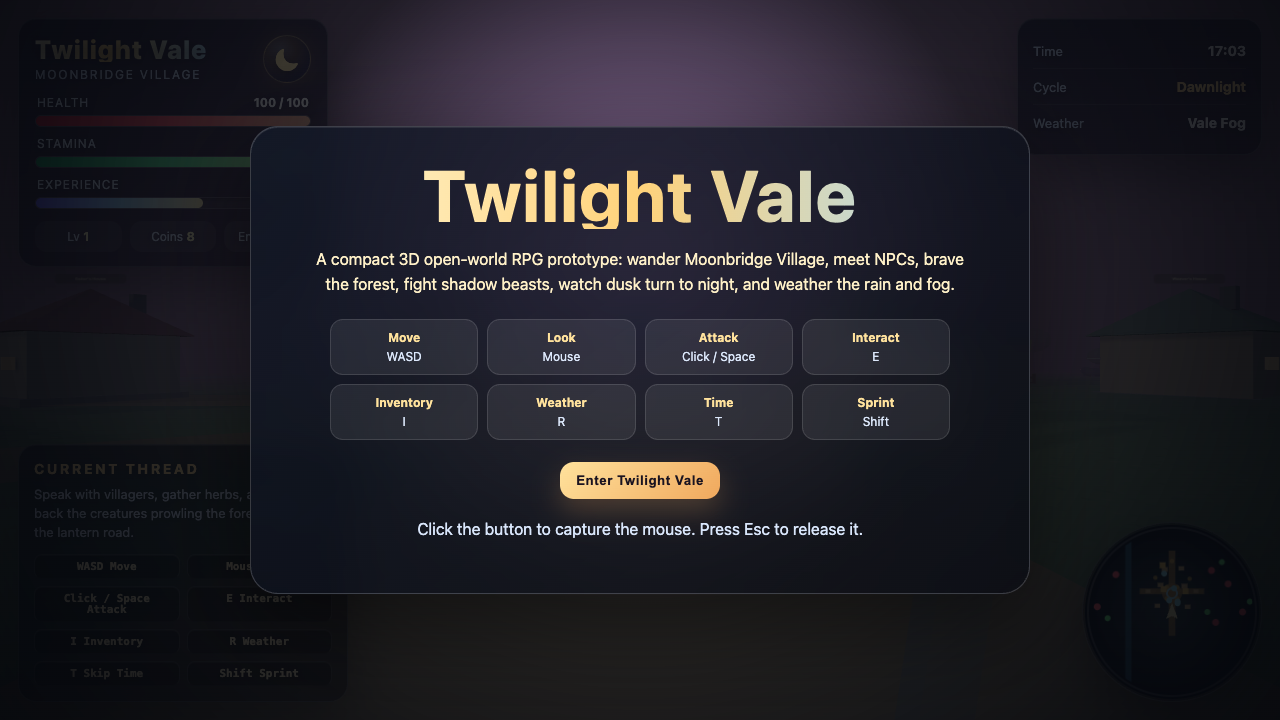
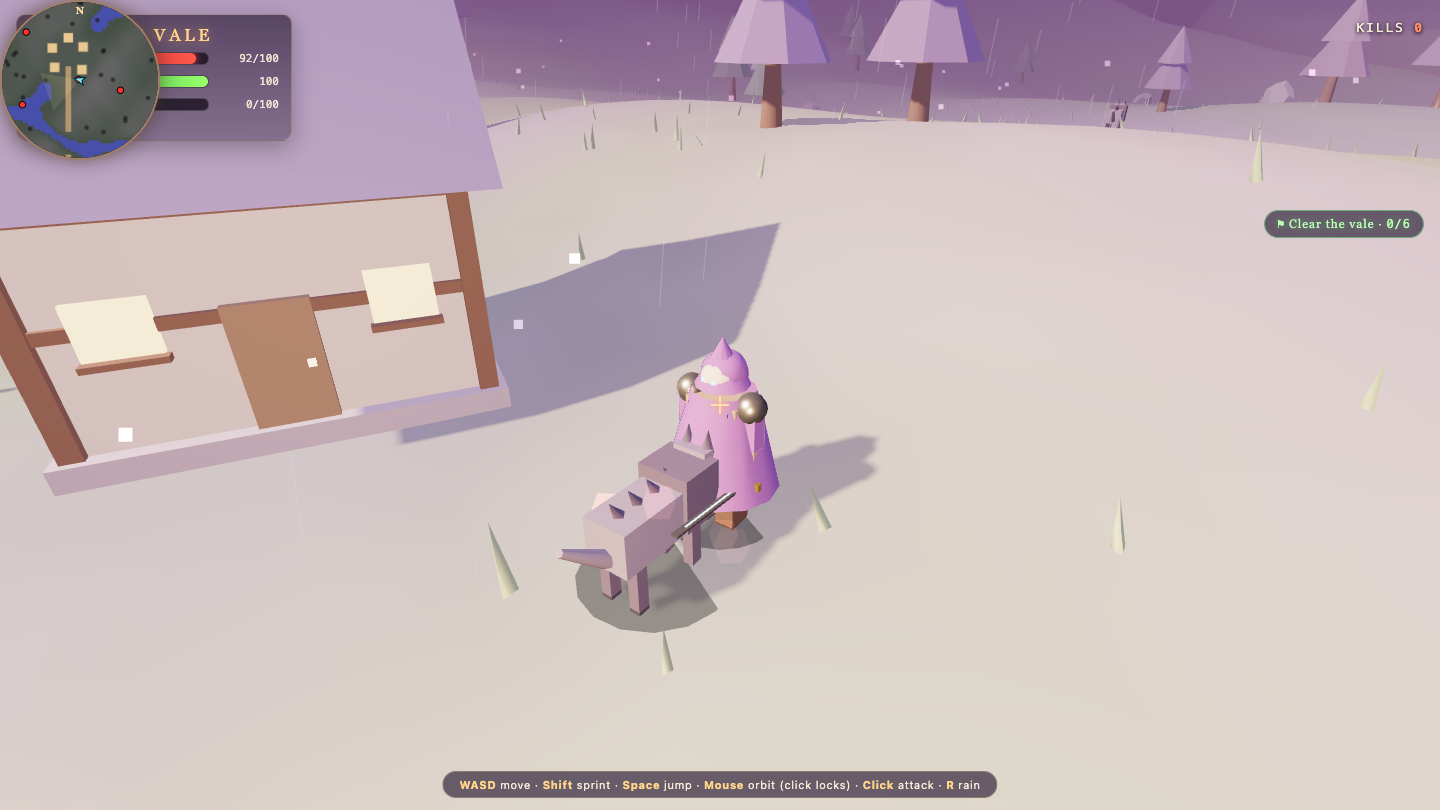
Twilightvale
Game
Fugu Ultra 9.0
·
Claude Opus 5.5 5.5
(+3.5)
· winner · open-world depth
What I saw: Ultra v2 — 61.8KB open-world RPG (village, NPCs, weather, day/night). Smoke-test PASS. Densest Ultra build on the bench.
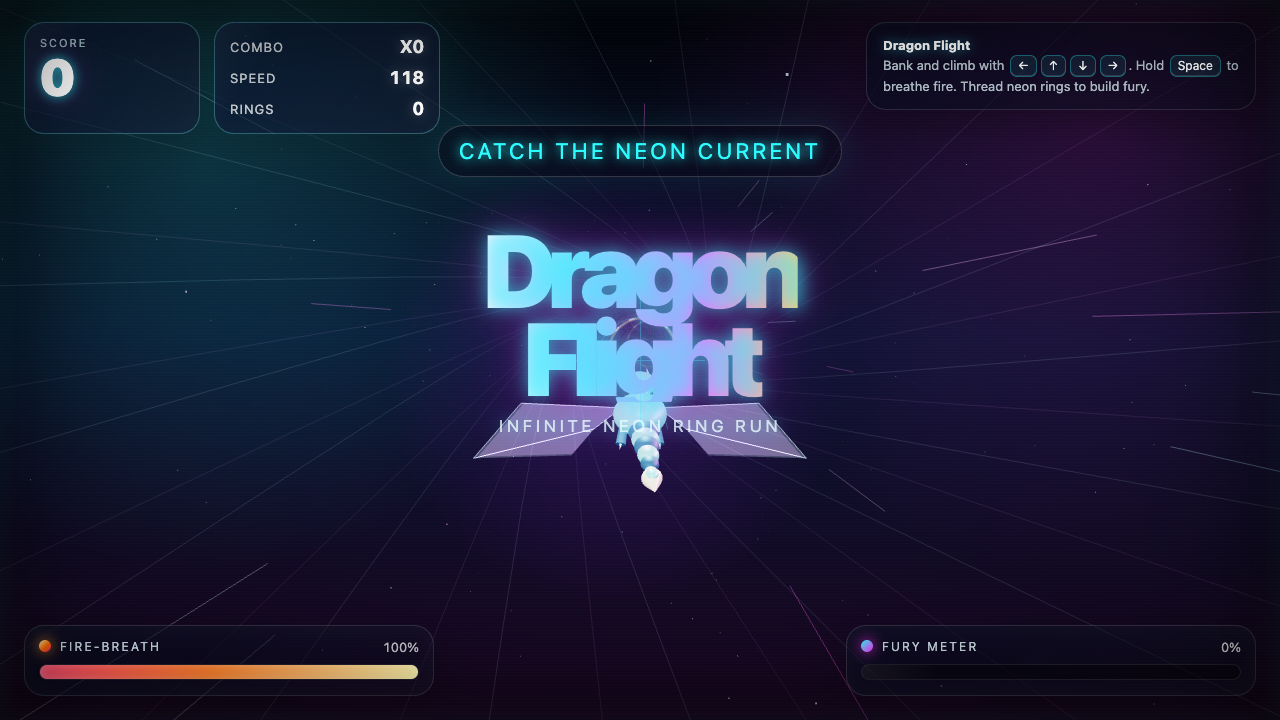
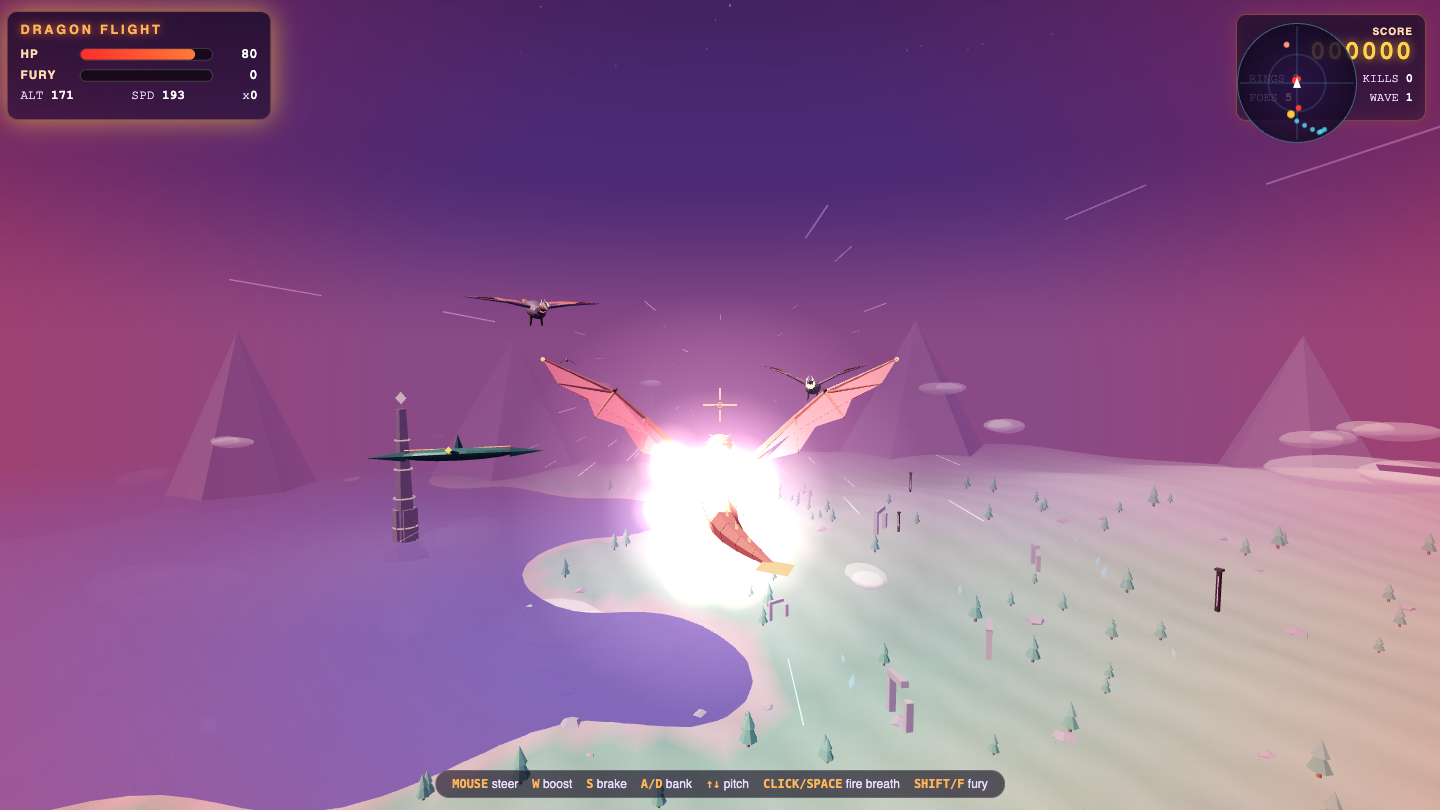
Dragonflight
Game
Fugu Ultra 8.5
·
Claude Opus 5.5 6.0
(+2.5)
What I saw: Ultra v2 — dragon through neon rings, full HUD. Smoke-test PASS (4.2% pixel diff).
Rpg
Game
Fugu Ultra 8.0
·
Claude Opus 5.5 5.5
(+2.5)
What I saw: Ultra v2 (gap-fill) — top-down RPG with tilemap + NPCs. Smoke-test PASS (1.1% diff).
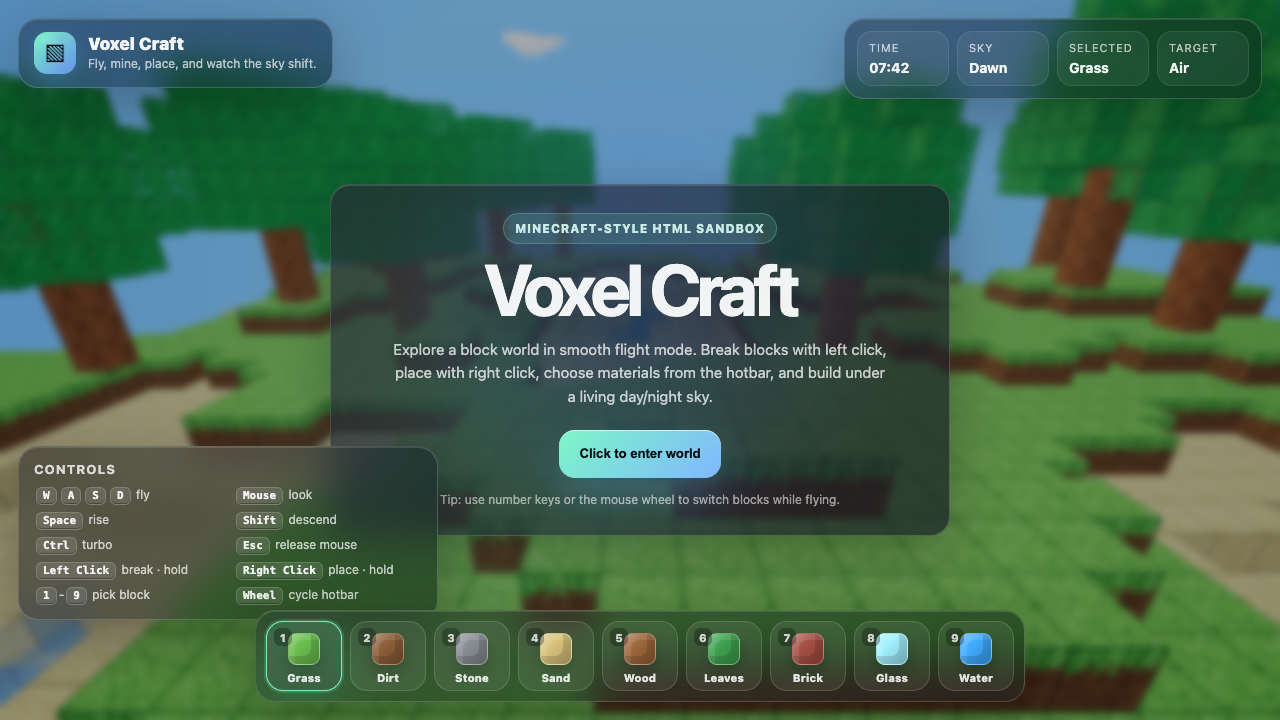
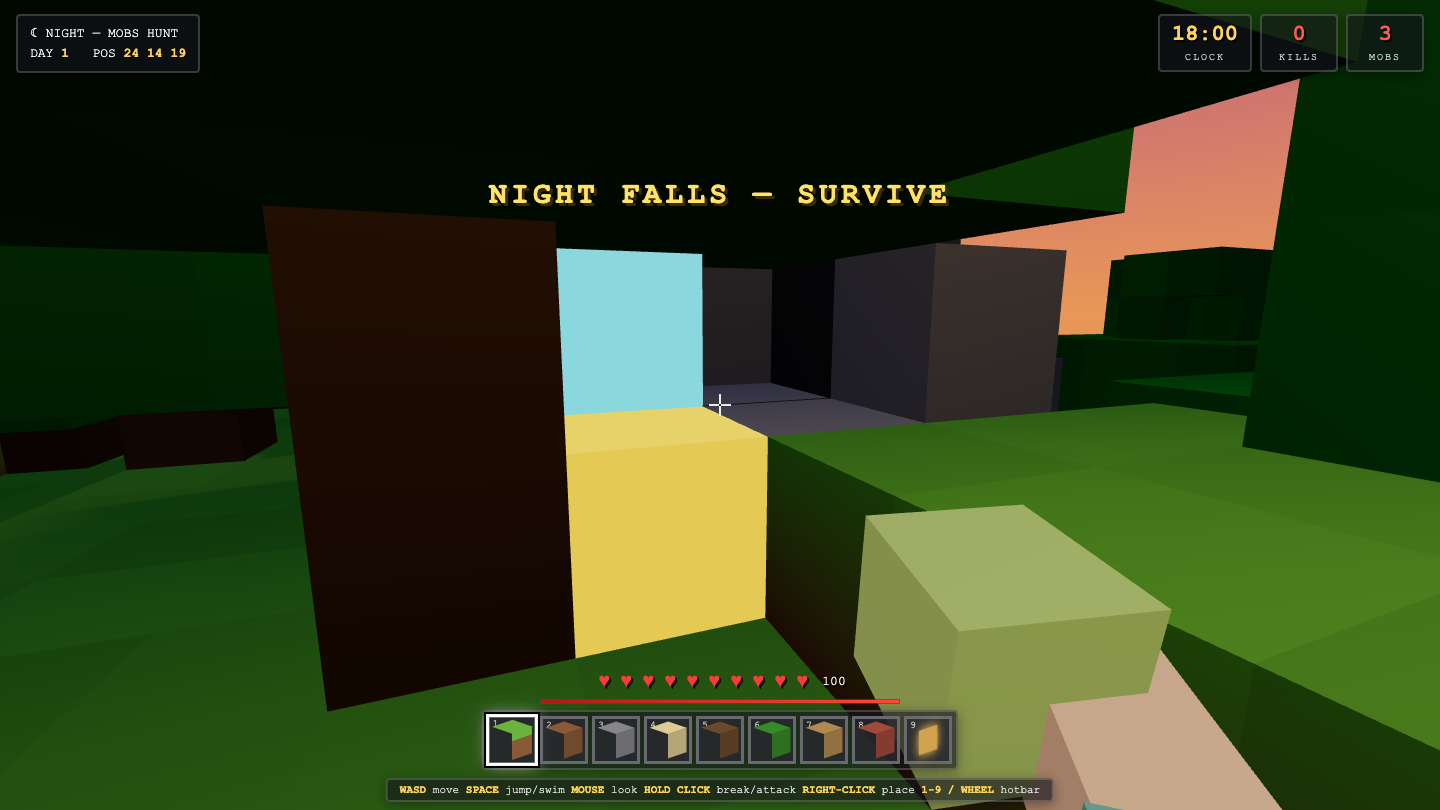
Voxelcraft
Game
Fugu Ultra 8.0
·
Claude Opus 5.5 5.8
(+2.2)
What I saw: Ultra v2 (gap-fill) — Minecraft-style voxel sandbox. Smoke-test PASS.
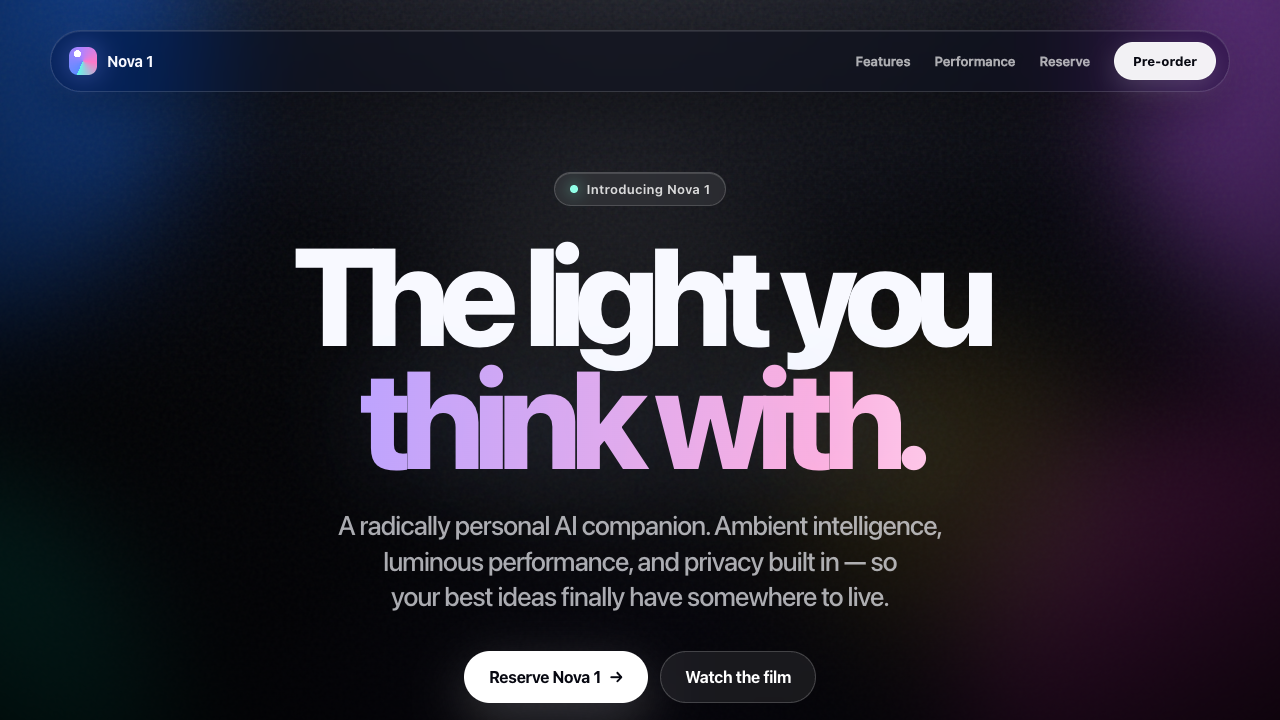
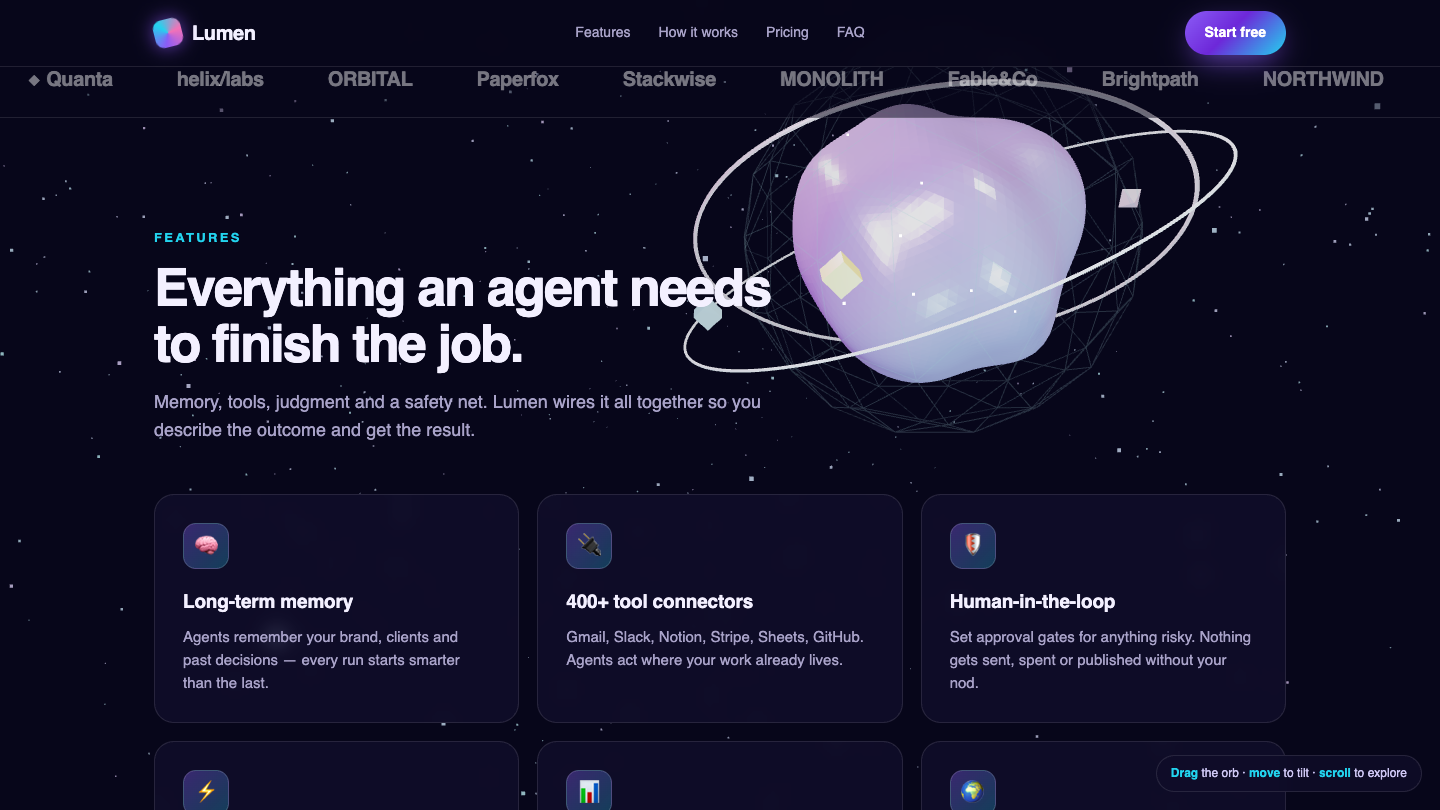
Landing
Page
Fugu Ultra 9.0
·
Claude Opus 5.5 7.5
(+1.5)
· winner · denser build
What I saw: Sakana Fugu Ultra shipped a 32KB Apple-keynote landing — bigger than Fusion's 20KB attempt at the same prompt. Animated mesh gradient, multi-section, polished. $0.32 vs Fusion's $1.30 for the same output — 4× cheaper, denser result.
Where Claude Opus 5.5 beat Fugu Ultra
The tasks where I gave Claude Opus 5.5 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Fluid
Sim
Claude Opus 5.5 8.5
·
Fugu Ultra 6.5
(+2.0)
What I saw: Real GPU Navier-Stokes with vorticity: vivid curling dye plumes and a dense advected particle layer read as a proper swirling fluid, and the control pills are tidy. The stats line still says a stale 'starting…', and the look is a little busy next to the field's 9.0 best.
Webos
Page
Claude Opus 5.5 8.7
·
Fugu Ultra 7.0
(+1.7)
What I saw: Polished NovaOS desktop: working Paint, Notes with a sidebar and autosave, a Terminal with neofetch/ls, a menu bar with a live clock and CPU, a side launcher and a dock with running dots, all in one cohesive macOS-like style. Very strong, but not clearly above the field's 9.0 best.
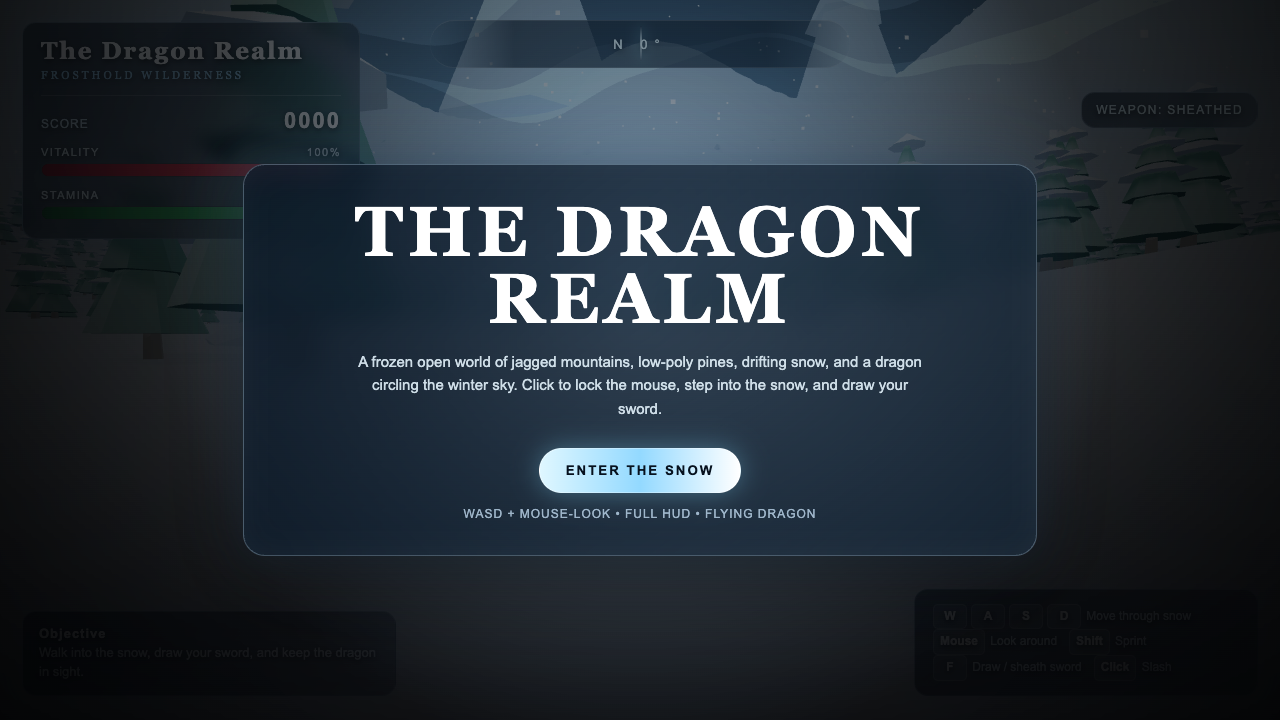
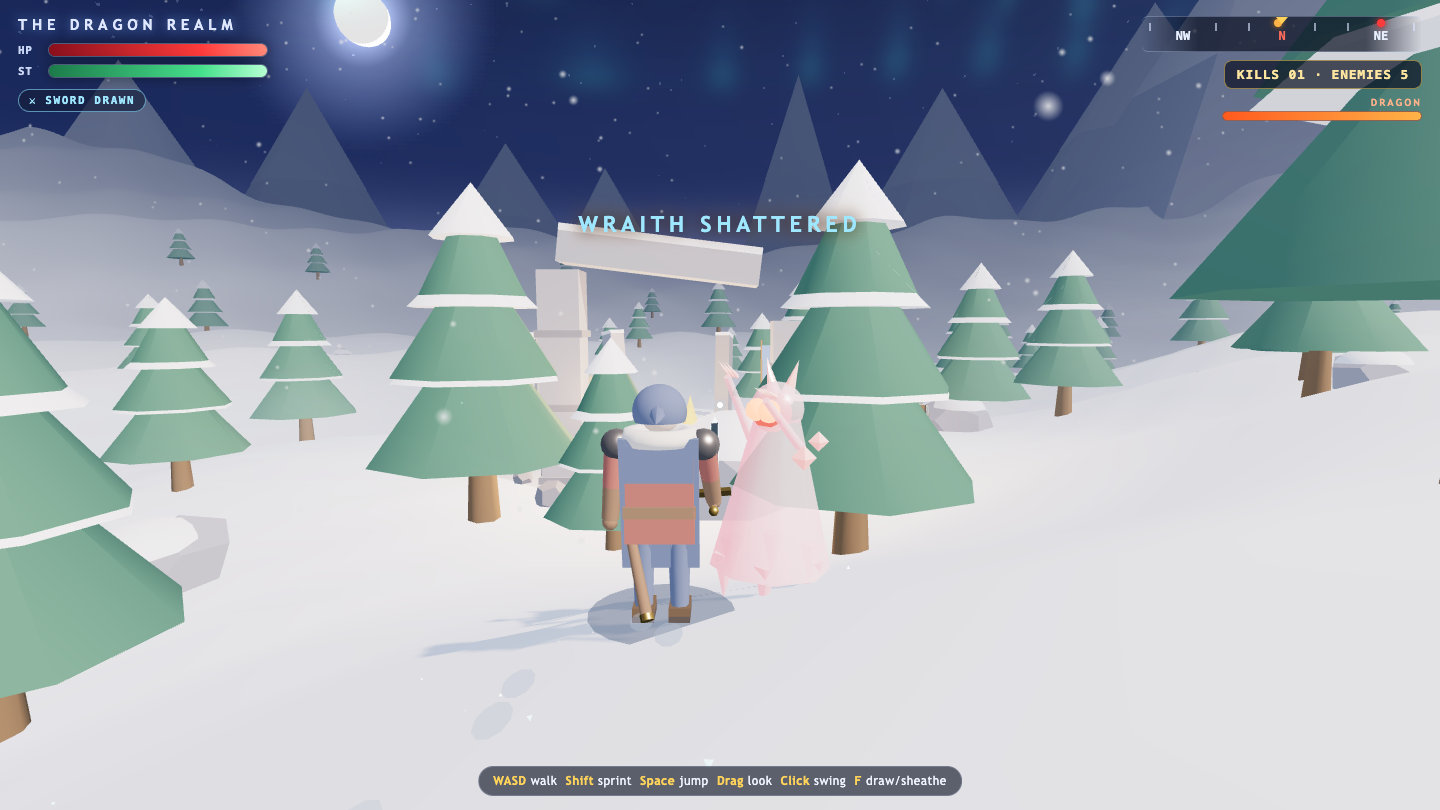
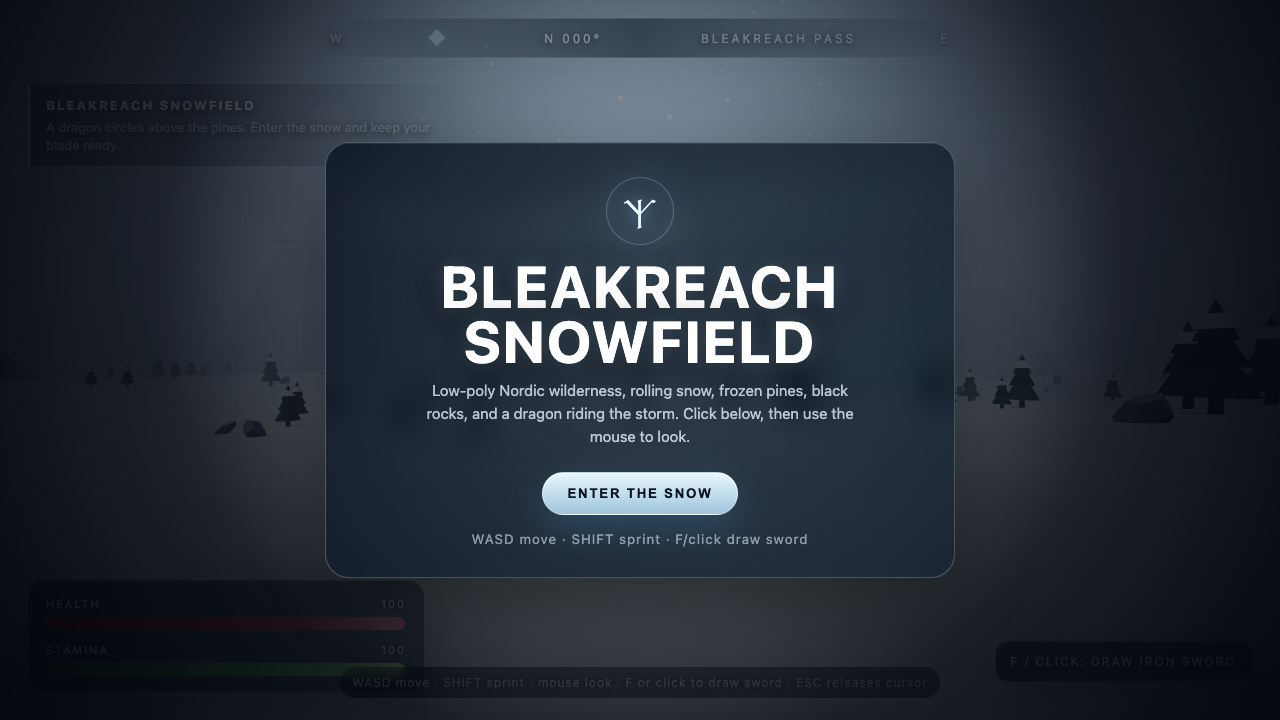
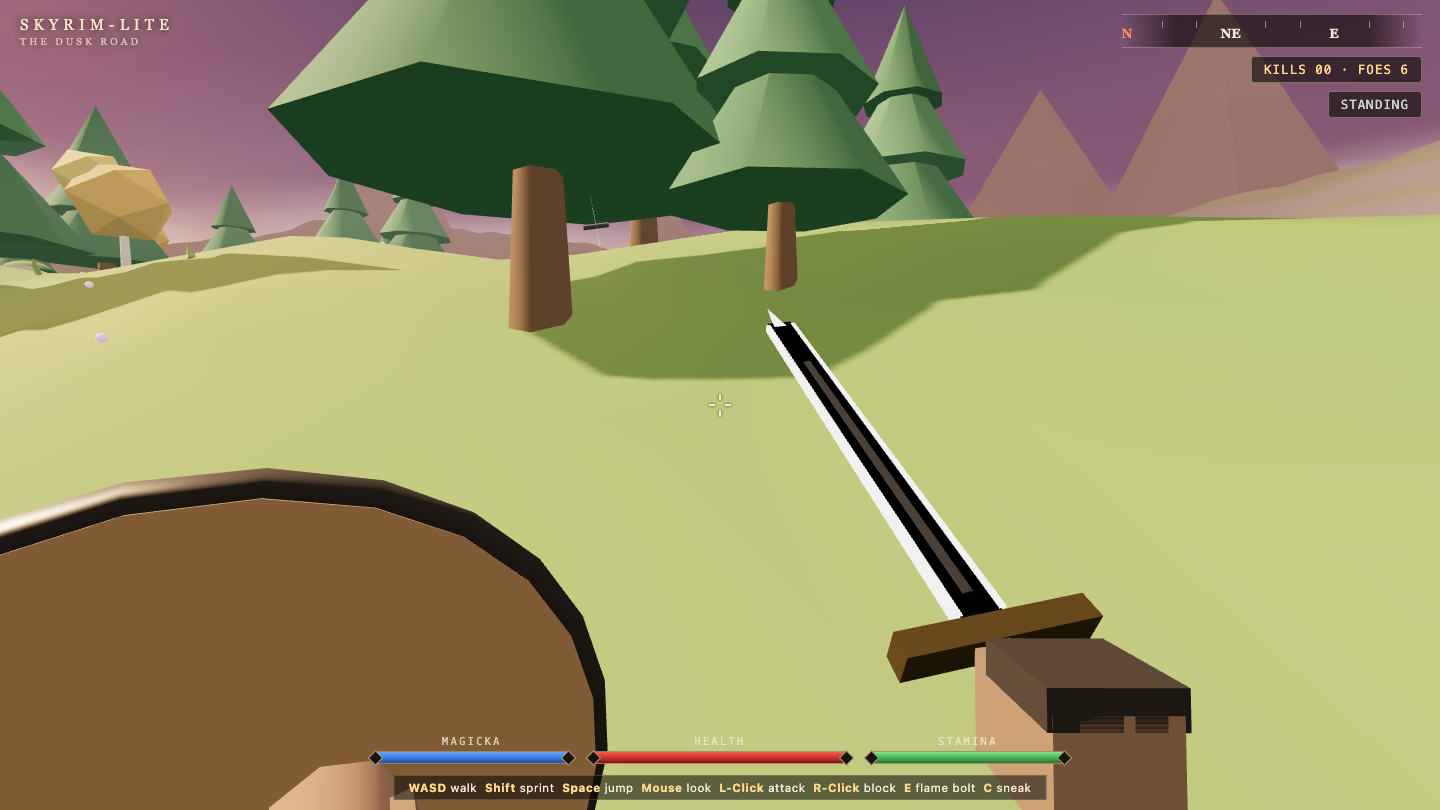
Dragonrealm
Game
Claude Opus 5.5 8.3
·
Fugu Ultra 7.0
(+1.3)
What I saw: Charming frozen world: snowfall, moon, snow-capped pines, ruins arch, a modelled armoured hero with a drawn sword, a wraith enemy, and a cohesive HP/ST/compass/dragon HUD. Low-poly and stylised rather than epic, and the fog-flattened snow reads a little bland, so it falls short o…
Wormhole
Sim
Claude Opus 5.5 8.3
·
Fugu Ultra 7.0
(+1.3)
What I saw: Striking glowing lattice tunnel with real depth, sector themes, velocity/distance HUD, warp and barrel roll, and it is clean and on-brief. The bloom is heavy enough to blow out the outer frame, and it is just short of the field best.
Outrun
Game
Claude Opus 5.5 8.1
·
Fugu Ultra 7.0
(+1.1)
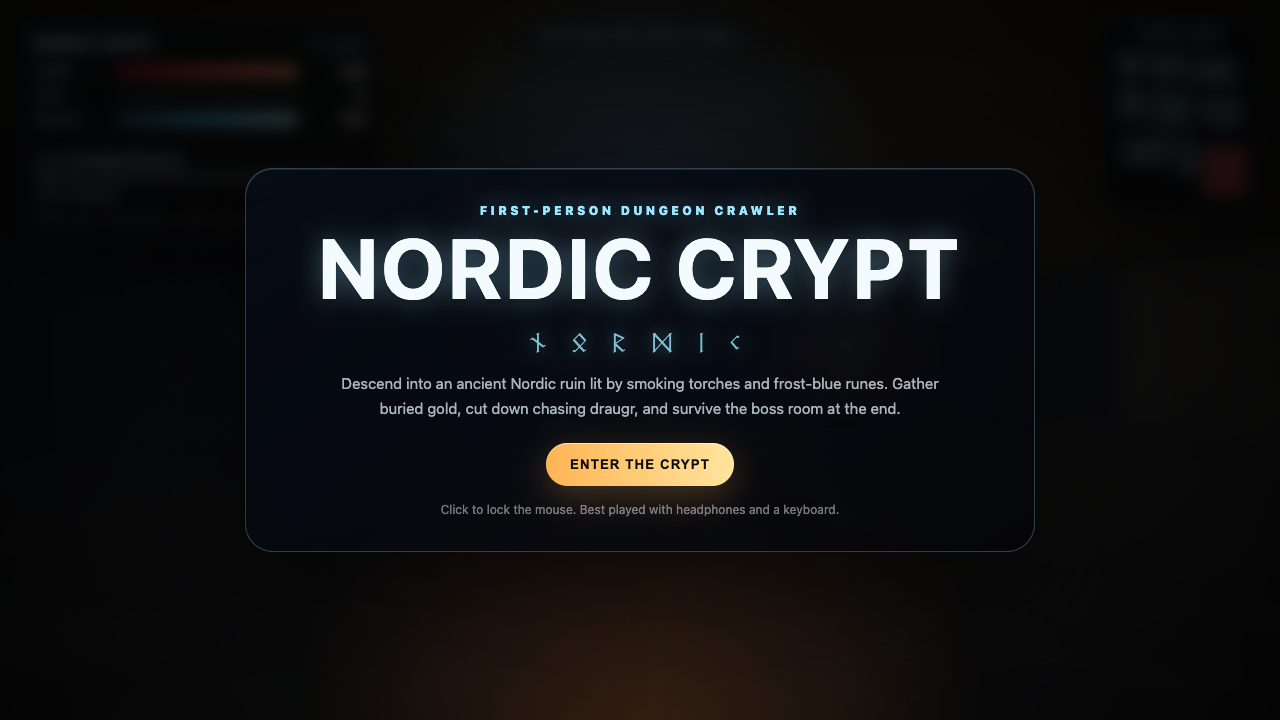
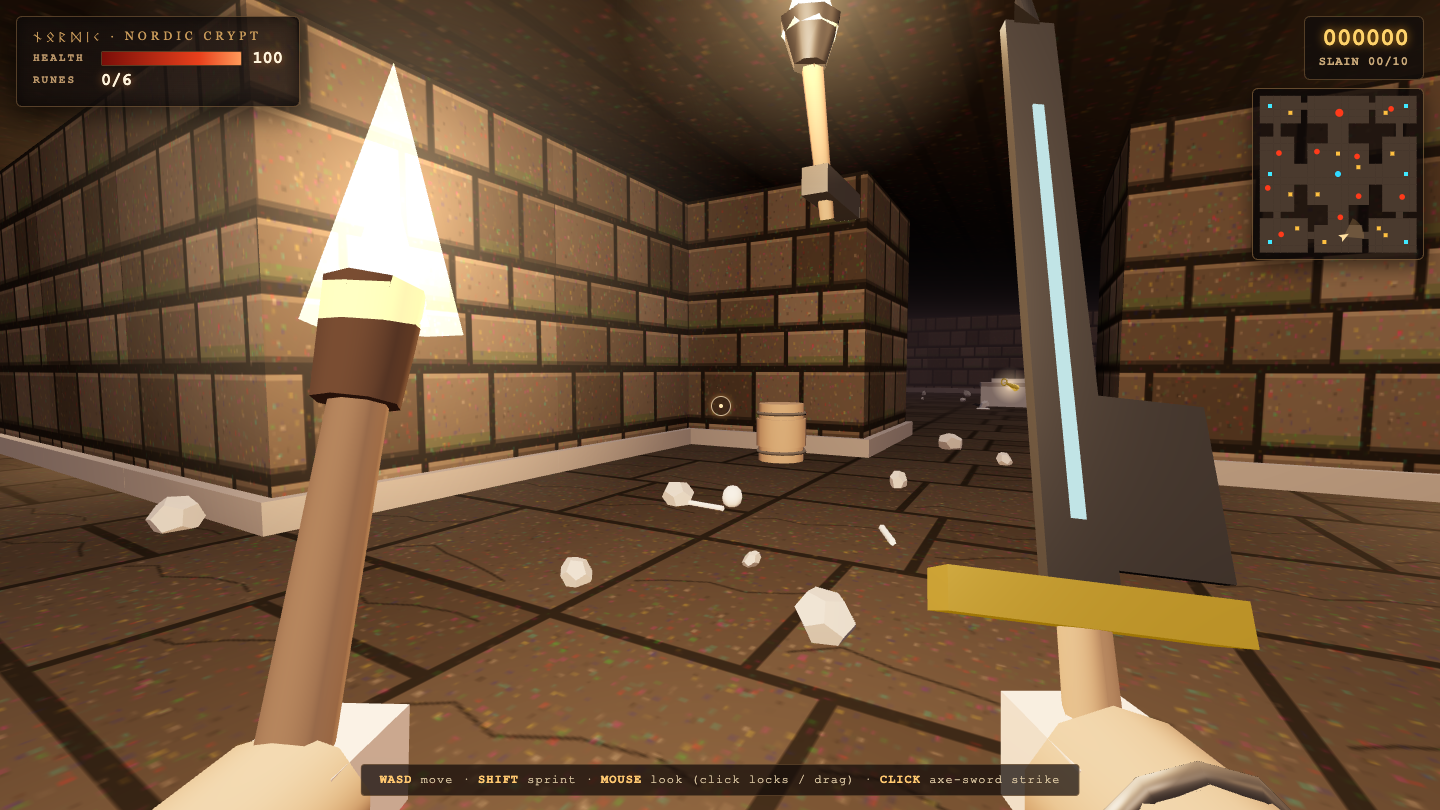
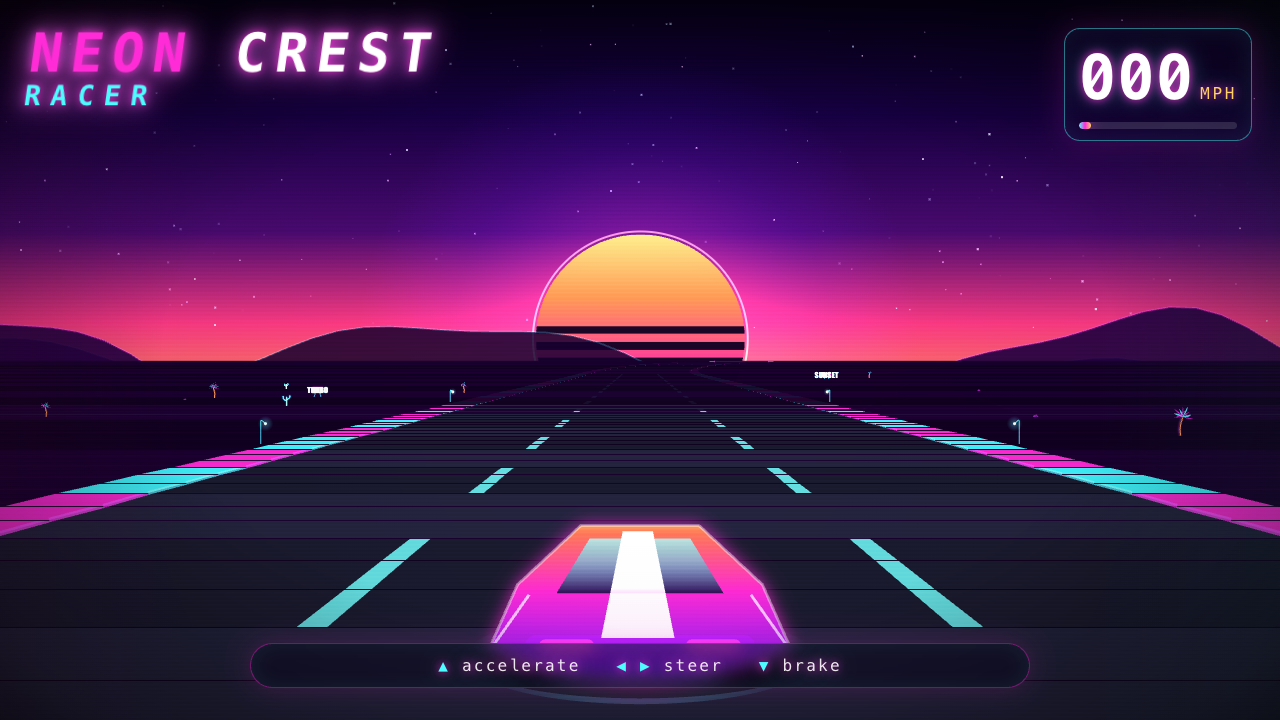
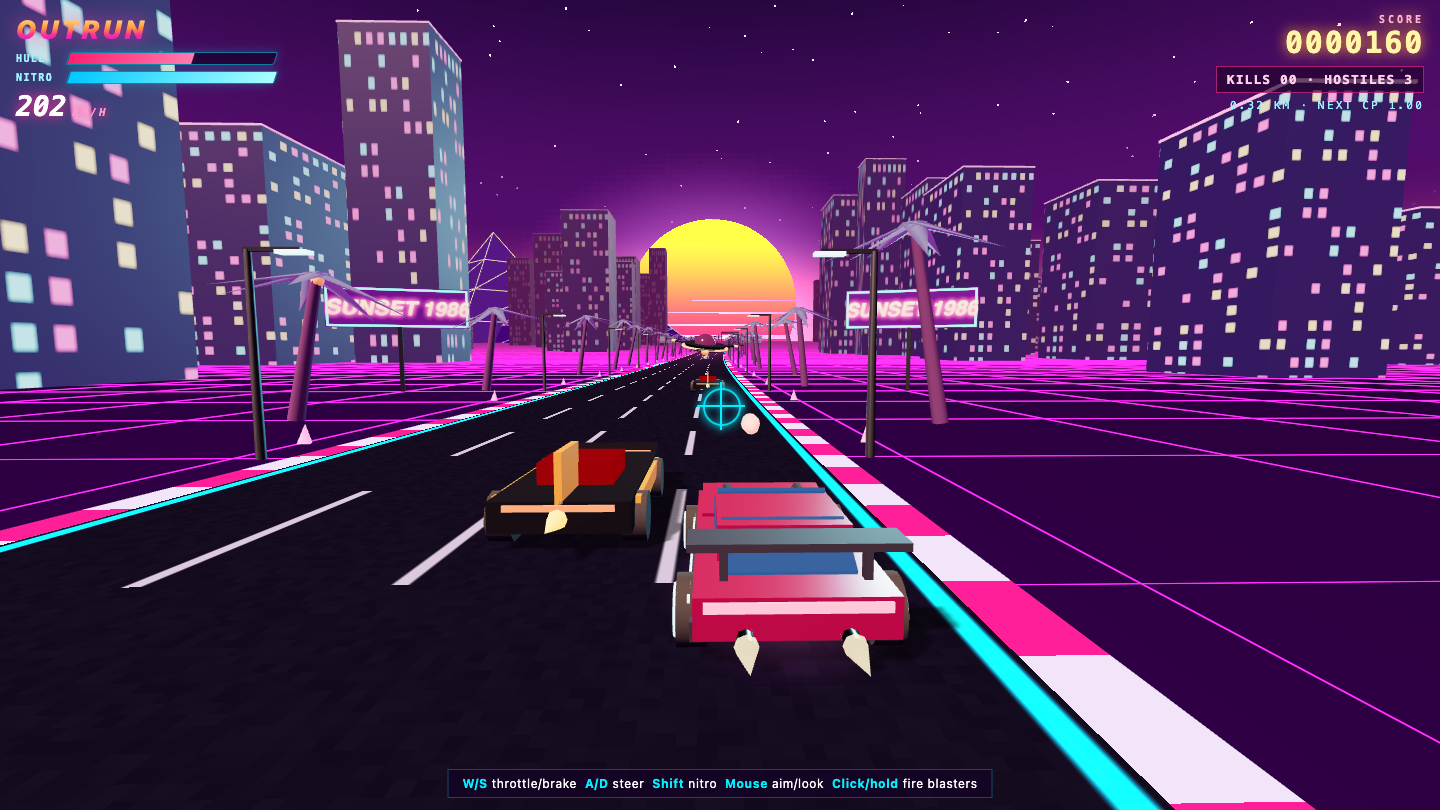
What I saw: Strong synthwave palette: striped sun, magenta grid, palms, SUNSET 1986 billboards, a modelled red car, traffic/hostiles and a tidy HUD. It uses a real 3D road rather than pseudo-3D, and the dim km/h label and chunky boxy cars keep it short of the top.
Strengths & weaknesses I logged
Fugu Ultra
Strengths
- SWE Bench Pro 73.7 · GPQA-D 95.5 · MRCRv2 93.6 — Sakana's published frontier-tier benchmark scores
- Vendor-agnostic ensemble — opt out of specific providers for compliance / export-control
- OpenAI-compatible API at api.sakana.ai — drop-in for existing tooling
Trade-offs
- Panel orchestration adds latency — even a 'pong' burns ~2k orchestration tokens
- Newer than Fusion; less community calibration on long-tail prompts
Claude Opus 5.5
Strengths
- Frontier-class coding + agentic reasoning (Claude 5 family)
- 1M-token context — reads an entire codebase in one call
- All 50 one-shot builds rendered with zero console errors; all 23 games passed the input playtest
Trade-offs
- Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes
- One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts)
Pricing & context — the spec sheet
| Spec | Fugu Ultra | Claude Opus 5.5 |
|---|---|---|
| Vendor | Sakana AI | Anthropic |
| Context window | 272,000 tokens with the standard rate. Calls exceeding 272K context are billed at the higher 'long-context' rates. | 1,000,000 tokens |
| Price | $5 / 1M input · $30 / 1M output (Fugu Ultra) | $4 / $20 per M |
| Pricing detail | Sakana's multi-agent orchestration: a single API call internally dispatches to multiple frontier models and synthesises the answer. Subscription plans run $20-$200/mo (Standard / Pro / Max); PAYG is $5/M input + $30/M output for Fugu Ultra. Direct competitor to OpenRouter Fusion's panel approach. | Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. |
| Release | 2026-06-15 | 2026-09 |
| Bench coverage | 42/42 scored · avg 7.94/10 | 50/50 scored · avg 7.57/10 |
The verdict — which should you pick?
Across 42 scored shared tasks, Fugu Ultra averaged 7.94/10, beating Claude Opus 5.5's 7.58/10 by 0.36 points. Pick Fugu Ultra when the build has to ship on the first prompt and you can afford the trade-offs in the comparison below.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire Fugu Ultra and Claude Opus 5.5 both into the Agent Operating System and dispatch each from the kanban by task type — teams that want fusion-class quality but need a different vendor risk profile → Fugu Ultra, hardest agentic builds → Claude Opus 5.5. That's the same setup I run for the 4,000+ founders inside the AI Profit Boardroom.
FAQ — Fugu Ultra vs Claude Opus 5.5
Which is better, Fugu Ultra or Claude Opus 5.5?
On Goldie Bench, Fugu Ultra averages 7.94/10 across the shared tasks, with 5 gold, 2 silver, 2 bronze overall. Claude Opus 5.5 averages 7.58/10, with 0 gold, 0 silver, 1 bronze. Fugu Ultra wins the head-to-head 28–13.
How much does Fugu Ultra cost vs Claude Opus 5.5?
Fugu Ultra: Sakana's multi-agent orchestration: a single API call internally dispatches to multiple frontier models and synthesises the answer. Subscription plans run $20-$200/mo (Standard / Pro / Max); PAYG is $5/M input + $30/M output for Fugu Ultra. Direct competitor to OpenRouter Fusion's panel approach. Claude Opus 5.5: Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts.
What's the context window for Fugu Ultra vs Claude Opus 5.5?
Fugu Ultra has a 272,000 tokens with the standard rate. Calls exceeding 272K context are billed at the higher 'long-context' rates. context window. Claude Opus 5.5 has a 1,000,000 tokens context window.
When should I pick Fugu Ultra over Claude Opus 5.5?
Pick Fugu Ultra for: Teams that want Fusion-class quality but need a different vendor risk profile; Operators avoiding export-controlled providers (Sakana emphasises this in their pitch); Deep-research workflows where ensemble verdicts beat single-model answers. The trade-off is the weaknesses we logged on the bench: Panel orchestration adds latency — even a 'pong' burns ~2k orchestration tokens; Newer than Fusion; less community calibration on long-tail prompts.
When should I pick Claude Opus 5.5 over Fugu Ultra?
Pick Claude Opus 5.5 for: Hardest agentic builds; Whole-repo reasoning; Frontier one-shots. The trade-off is the weaknesses we logged on the bench: Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes; One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts).
How does Goldie Bench score Fugu Ultra vs Claude Opus 5.5?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
Fugu Ultra vs Fusion Claude Opus 5.5 vs Fusion Fugu Ultra vs Claude Opus 5 Claude Opus 5.5 vs Claude Opus 5 Fugu Ultra vs Hermes MoA Claude Opus 5.5 vs Hermes MoA Fugu Ultra vs GPT-5.6 Sol Claude Opus 5.5 vs GPT-5.6 SolFull model pages: Fugu Ultra · Claude Opus 5.5 · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.
4,000+founders
258documented wins
38countries
$59/momonthly