Real head-to-head · same prompt, one shot
Qwen 3.8 vs Claude Opus 5.5
Alibaba's 2.4T flagship — benched through Qoder. vs Anthropic's Opus 5.5 — benched on all 50 one-shot builds, every game playtested.
Head-to-head verdict: Qwen 3.8 wins 34–10 with 1 tie.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to Qwen 3.8 and Claude Opus 5.5, side by side, on 45 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
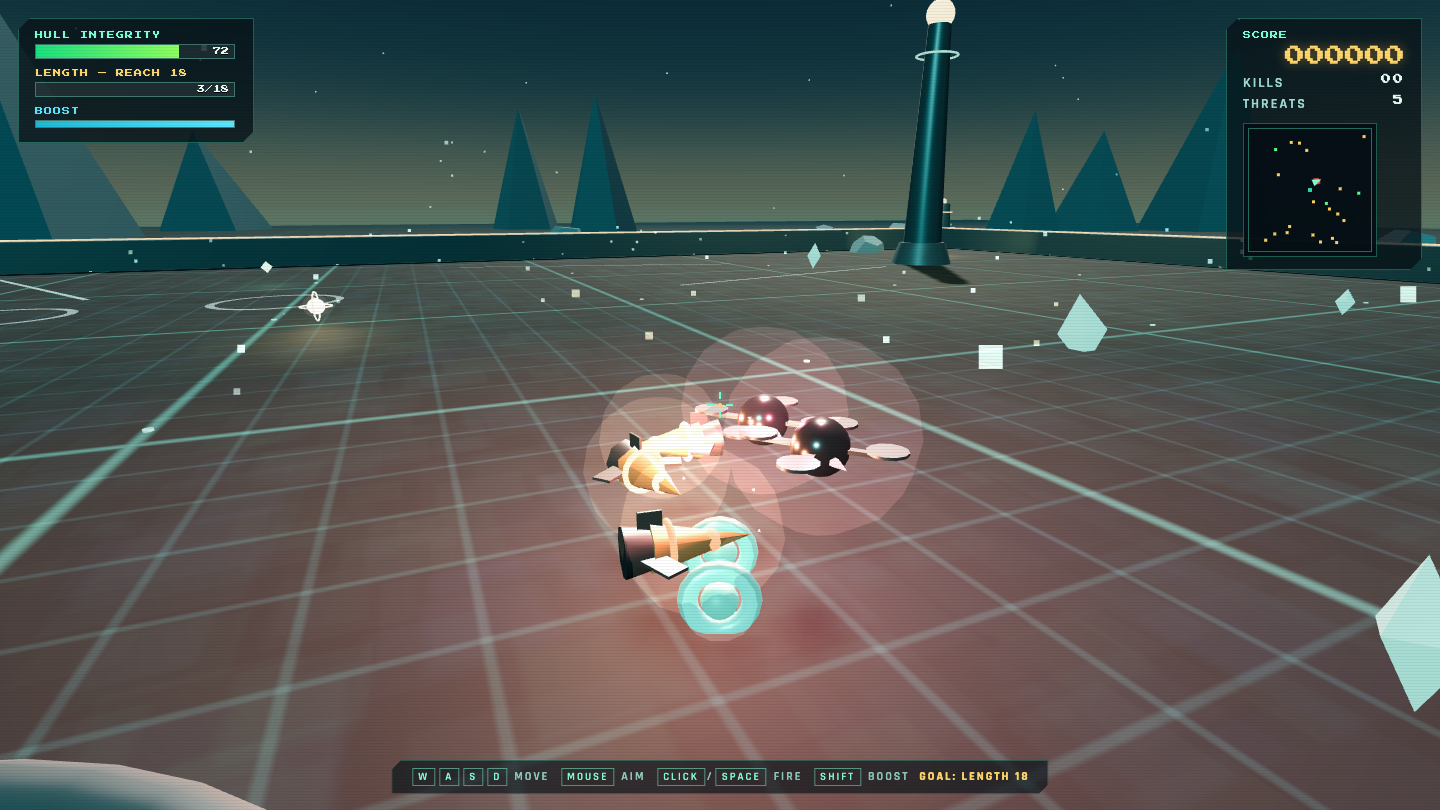
Qwen 3.8 · Benched on GoldieBench via the Qoder CLI (`qoder-qwen`, model Qwen3.8-Max-Preview) — the only door while it has no public API. Non-game tasks are one-shot like the rest of the field. GAME tasks run in Qoder's real AGENT mode: skill-infused build, then up to 2 QA fix rounds where a vision judge + live console errors are fed back and Qwen 3.8 edits its own file (it took crypt from a black-screen 3.0 to a torch-lit 7.8). Scored on a mid-play frame by the same Opus judge as everyone else.
Claude Opus 5.5 · Benched on all 50 GoldieBench tasks via a Claude subscription: one-shot builds, real renders, pixel-diff playtests on every game, then vision-judged.
Side-by-side on 50 shared tasks
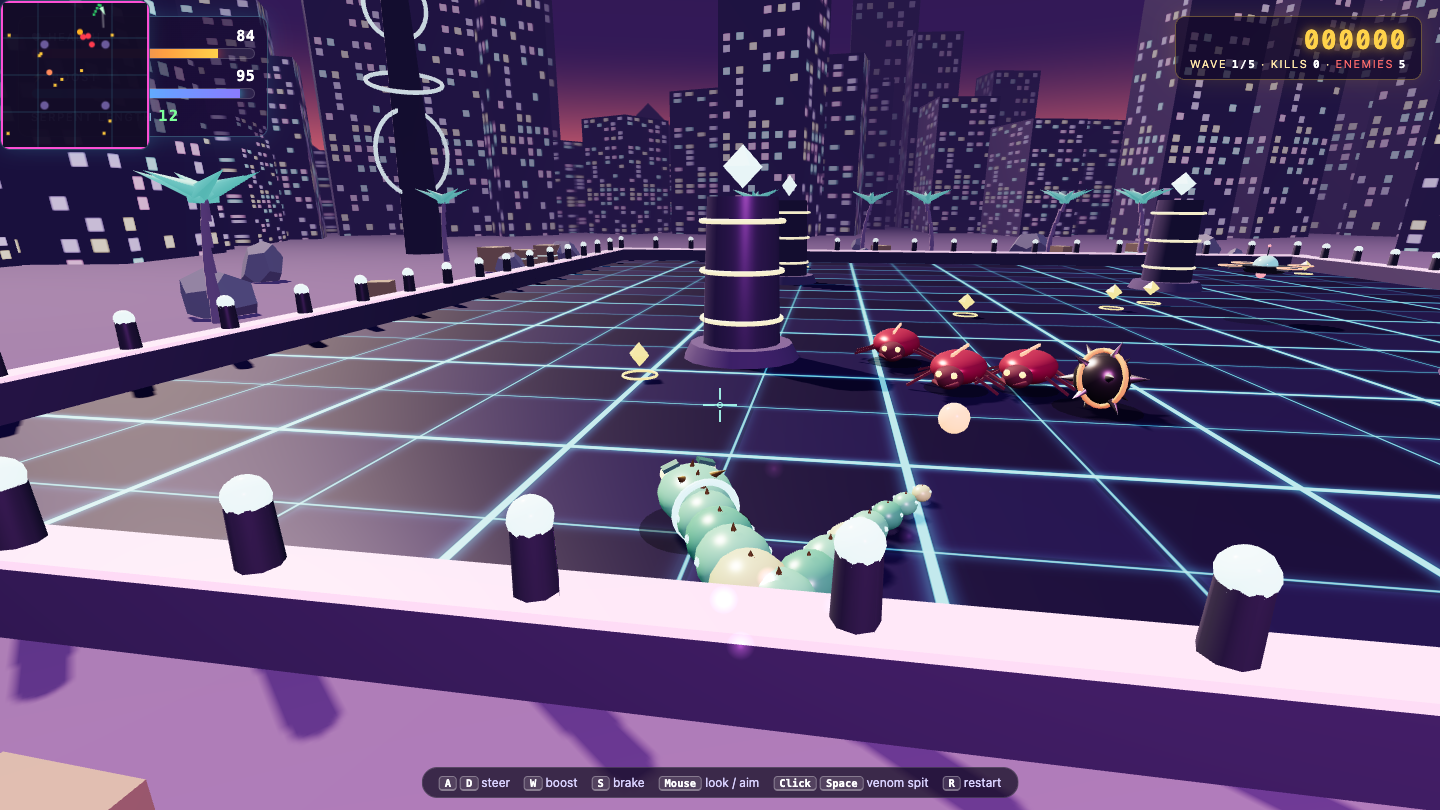
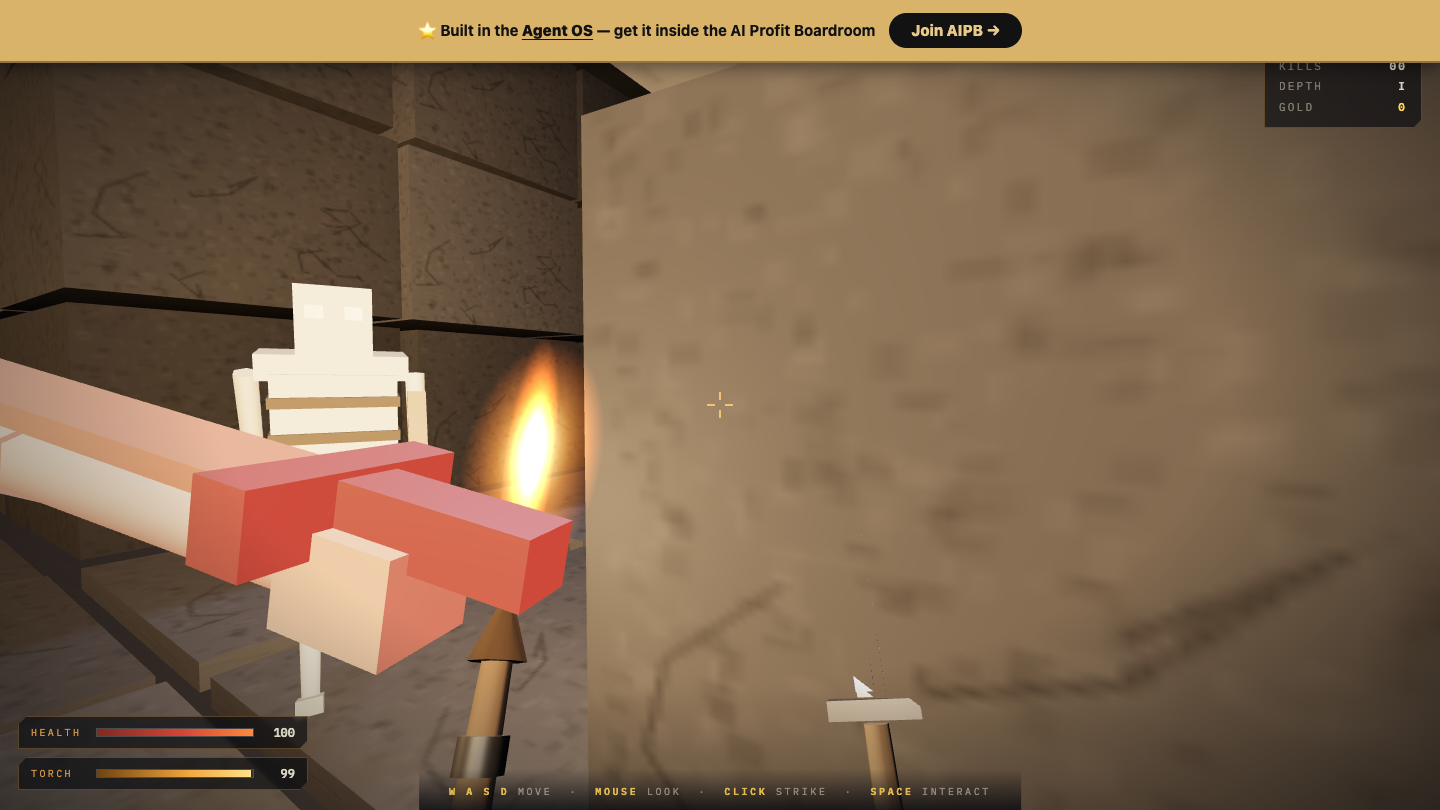
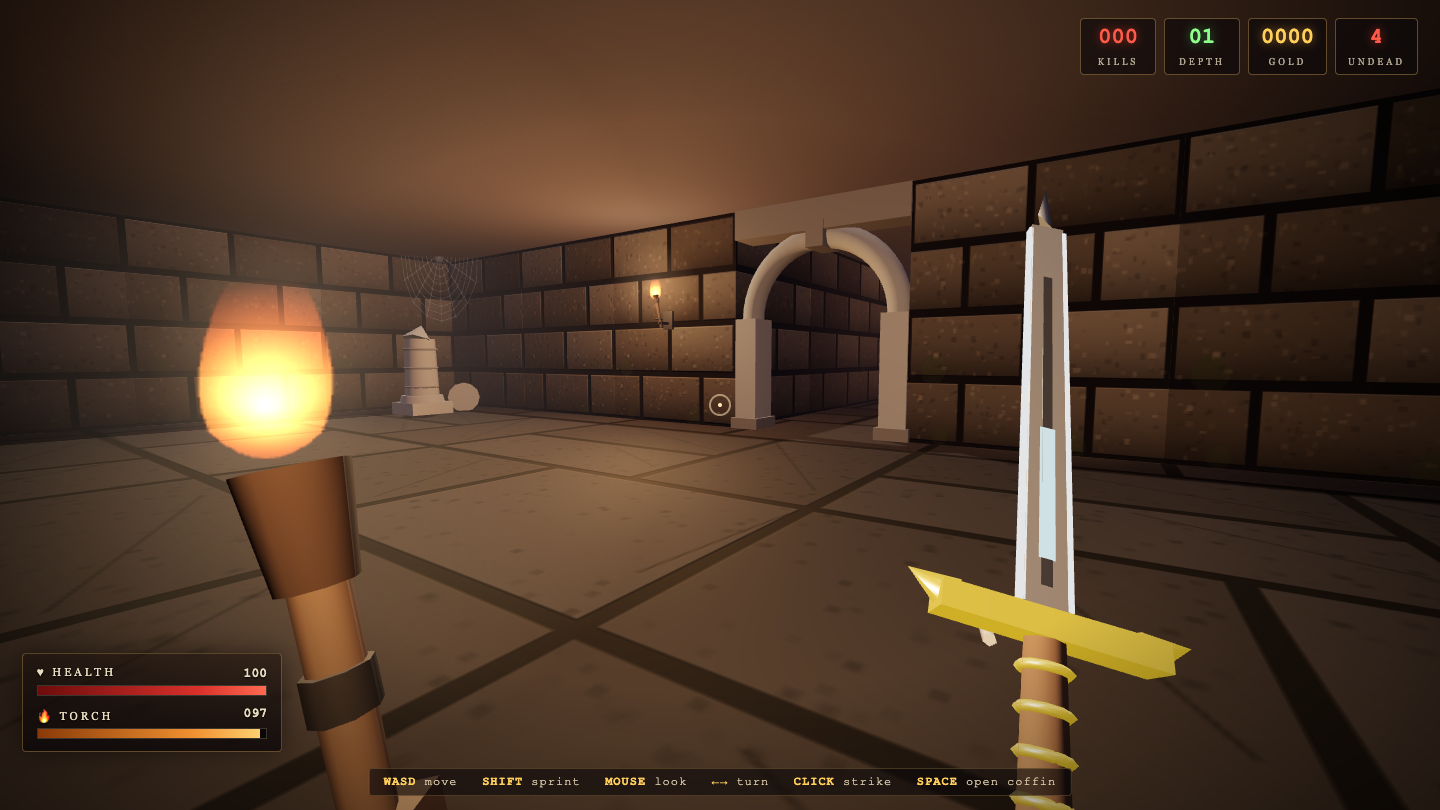
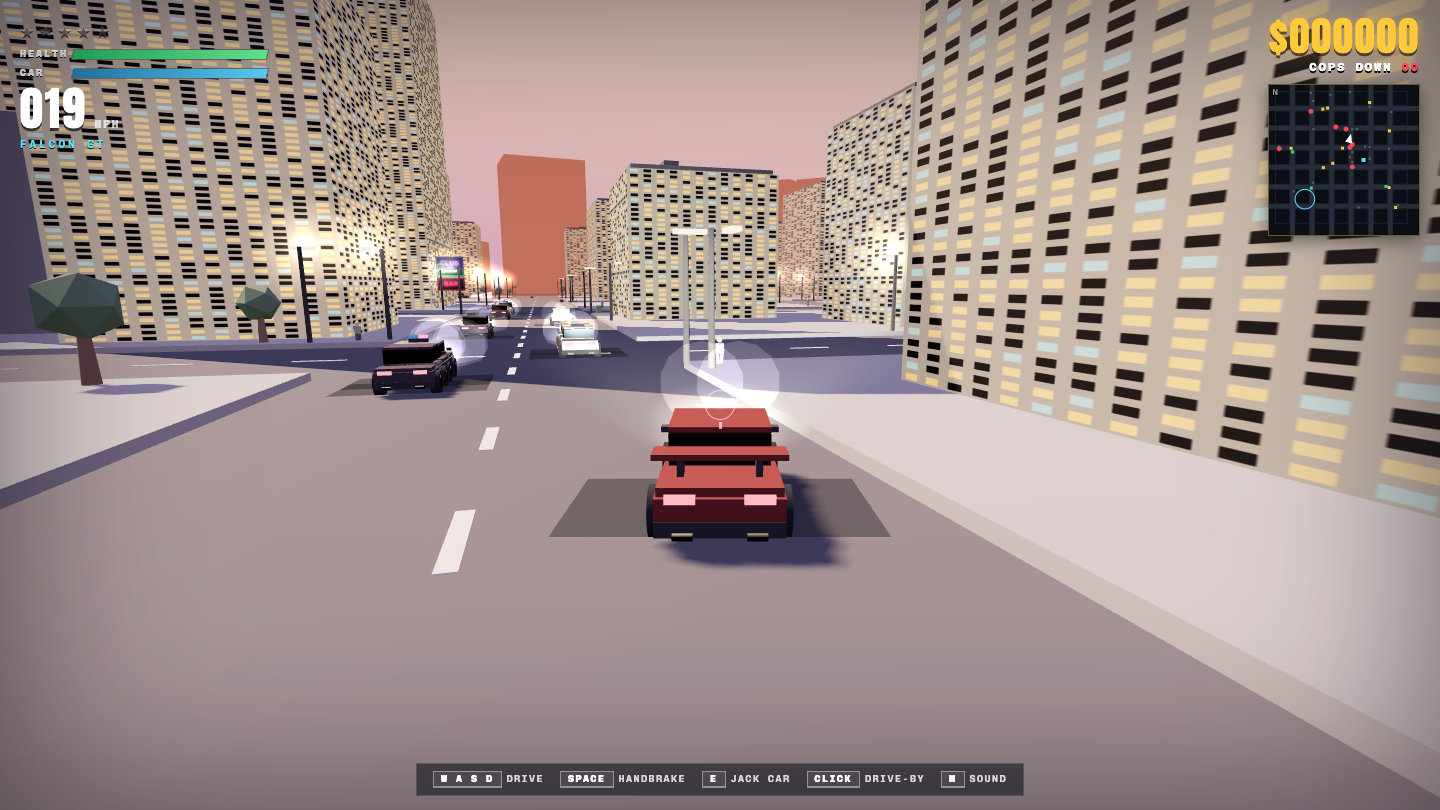
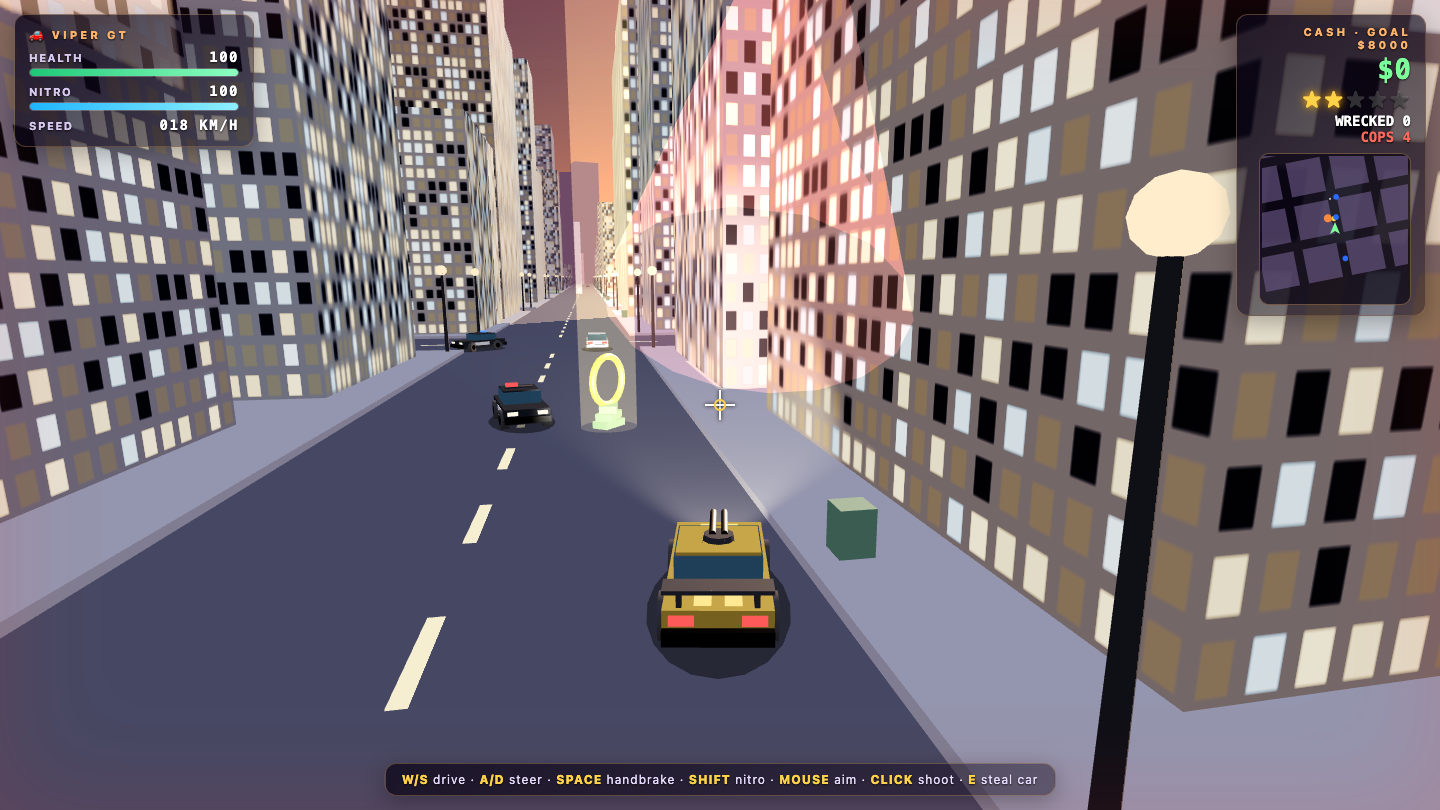
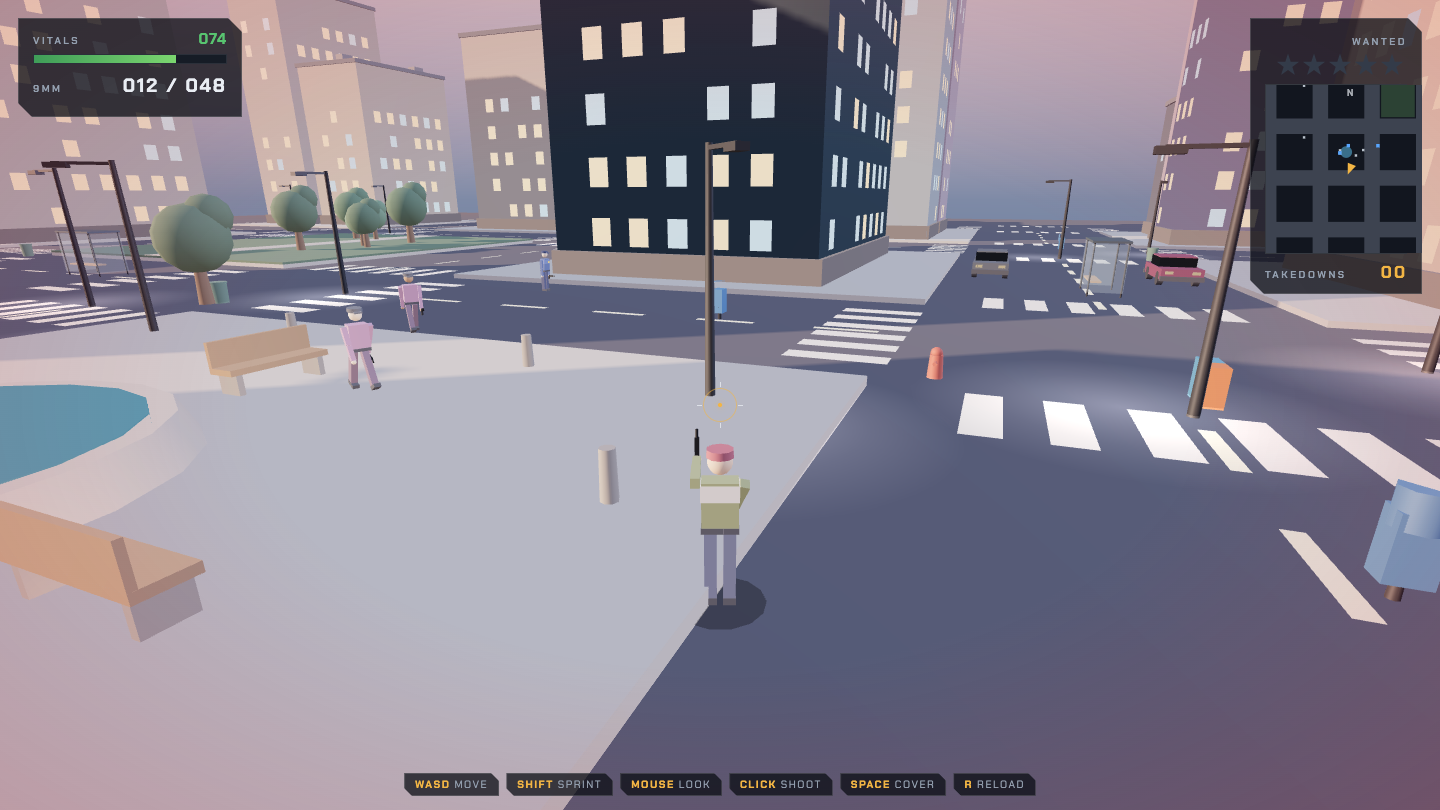
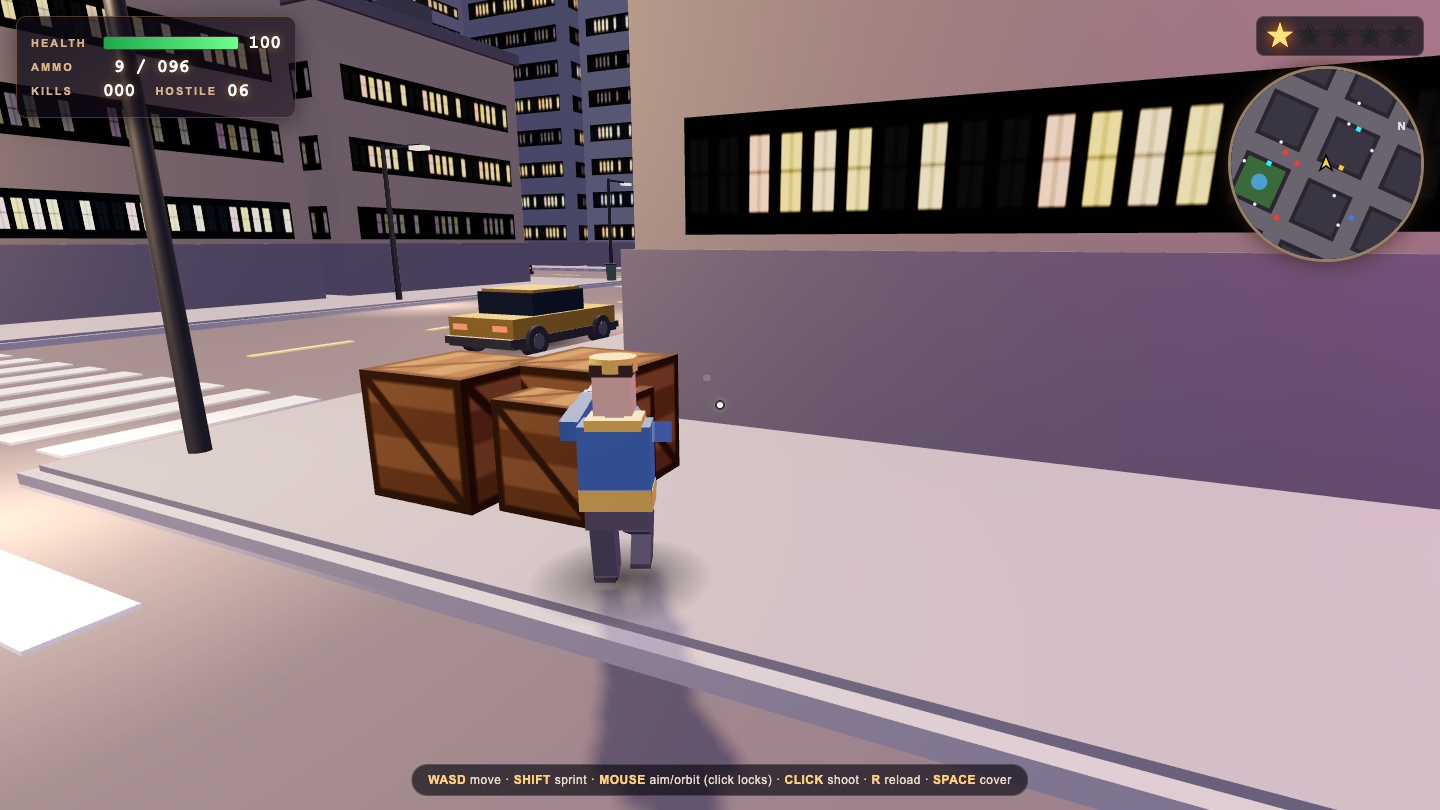
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
Qwen 3.8
Claude Opus 5.5
Game
Game
Game
Game
Game
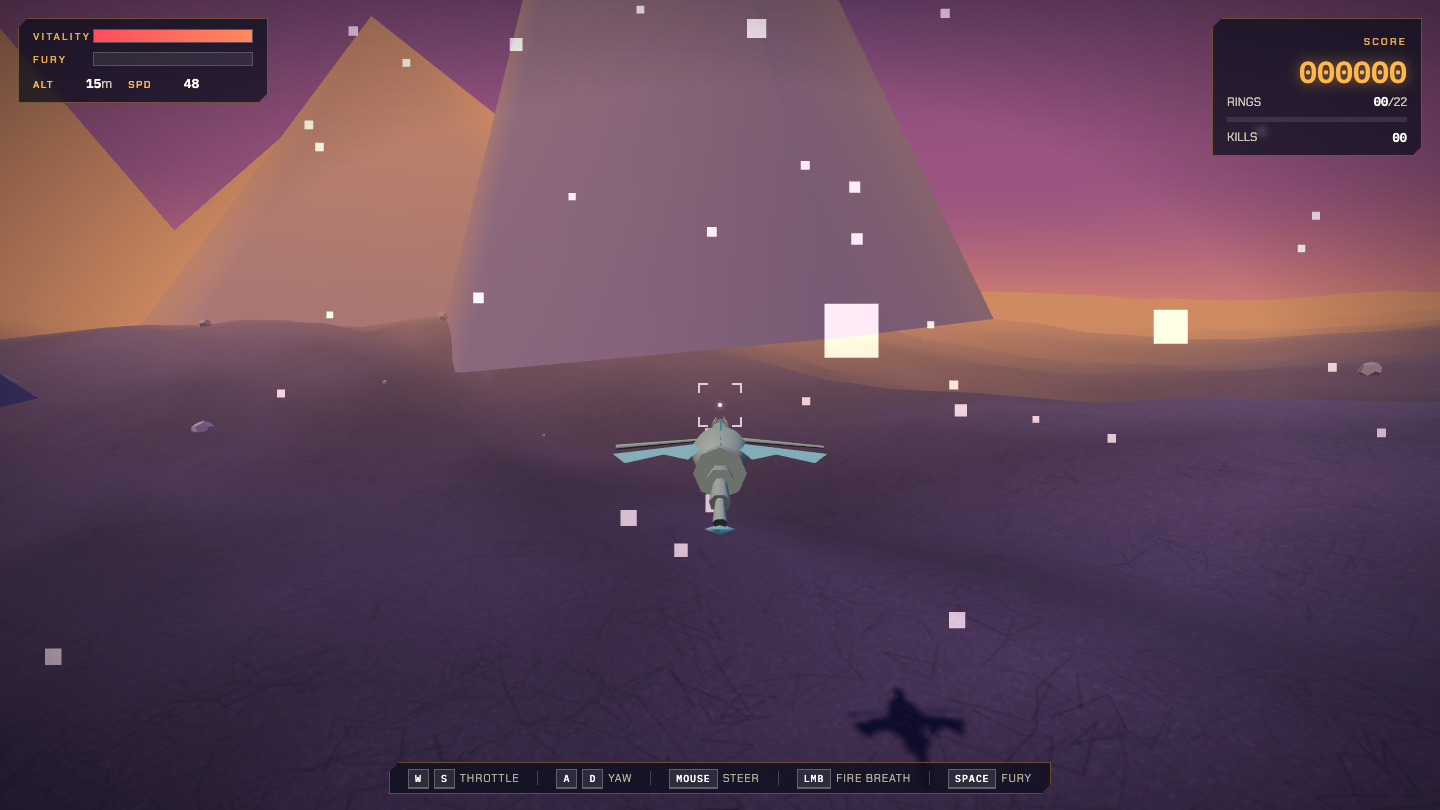
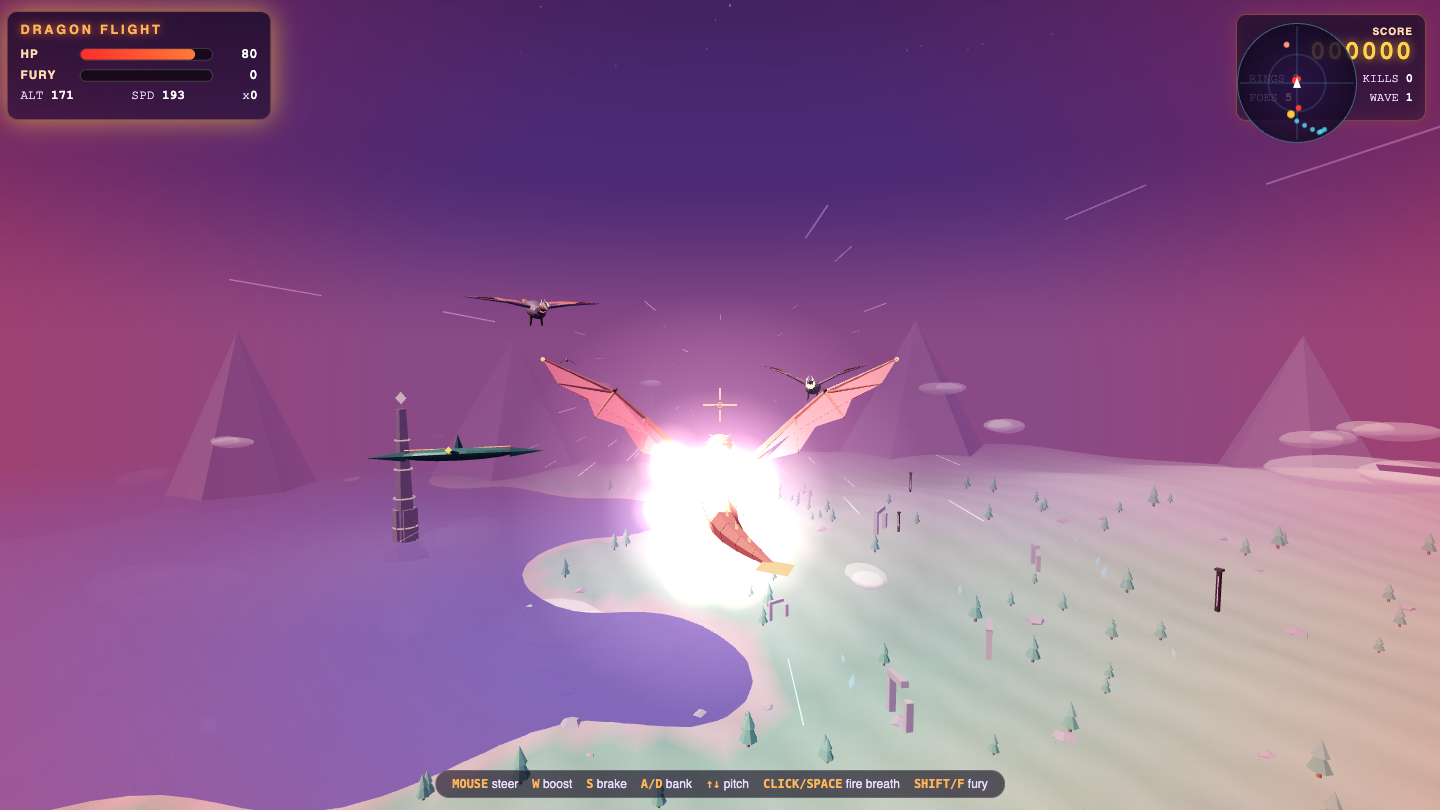
Game
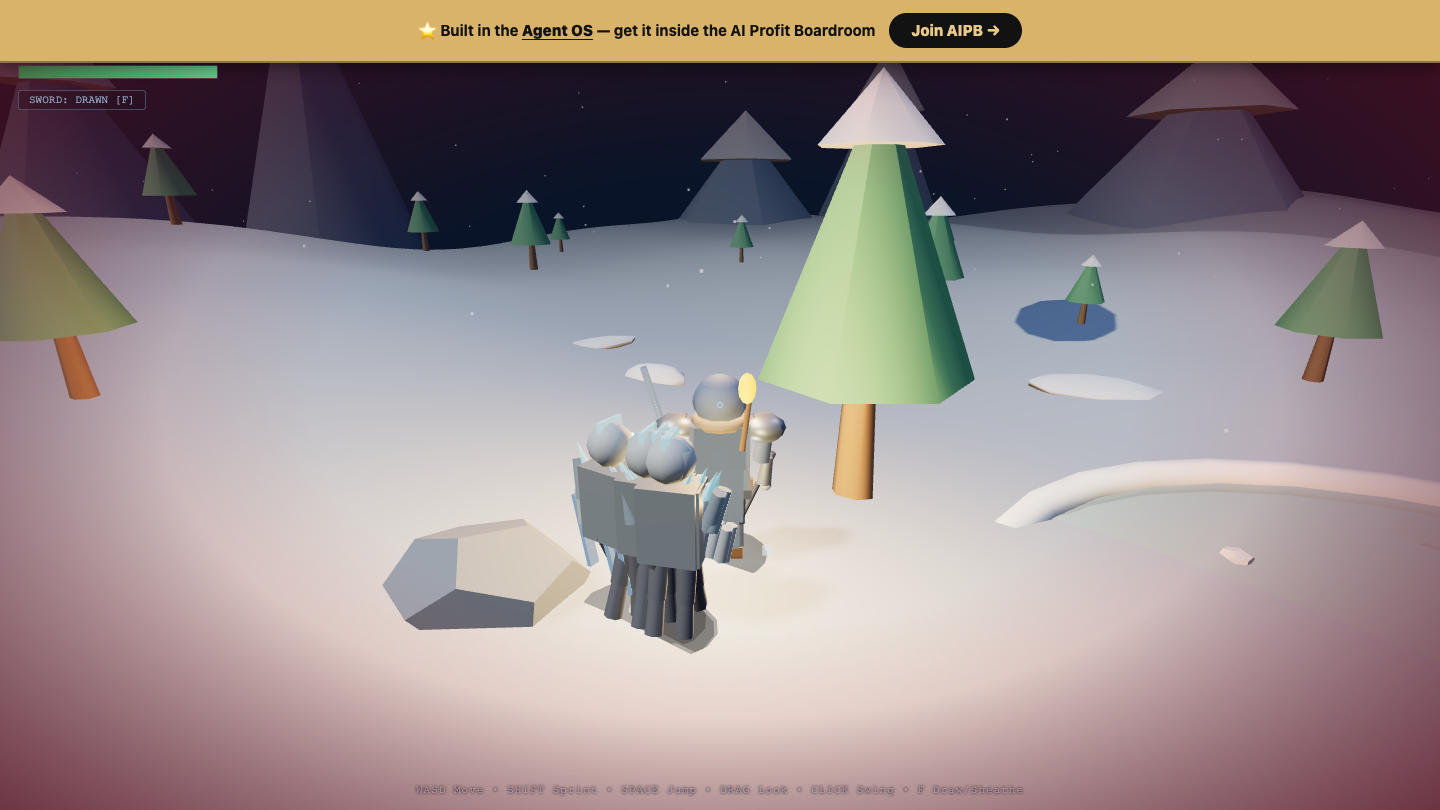
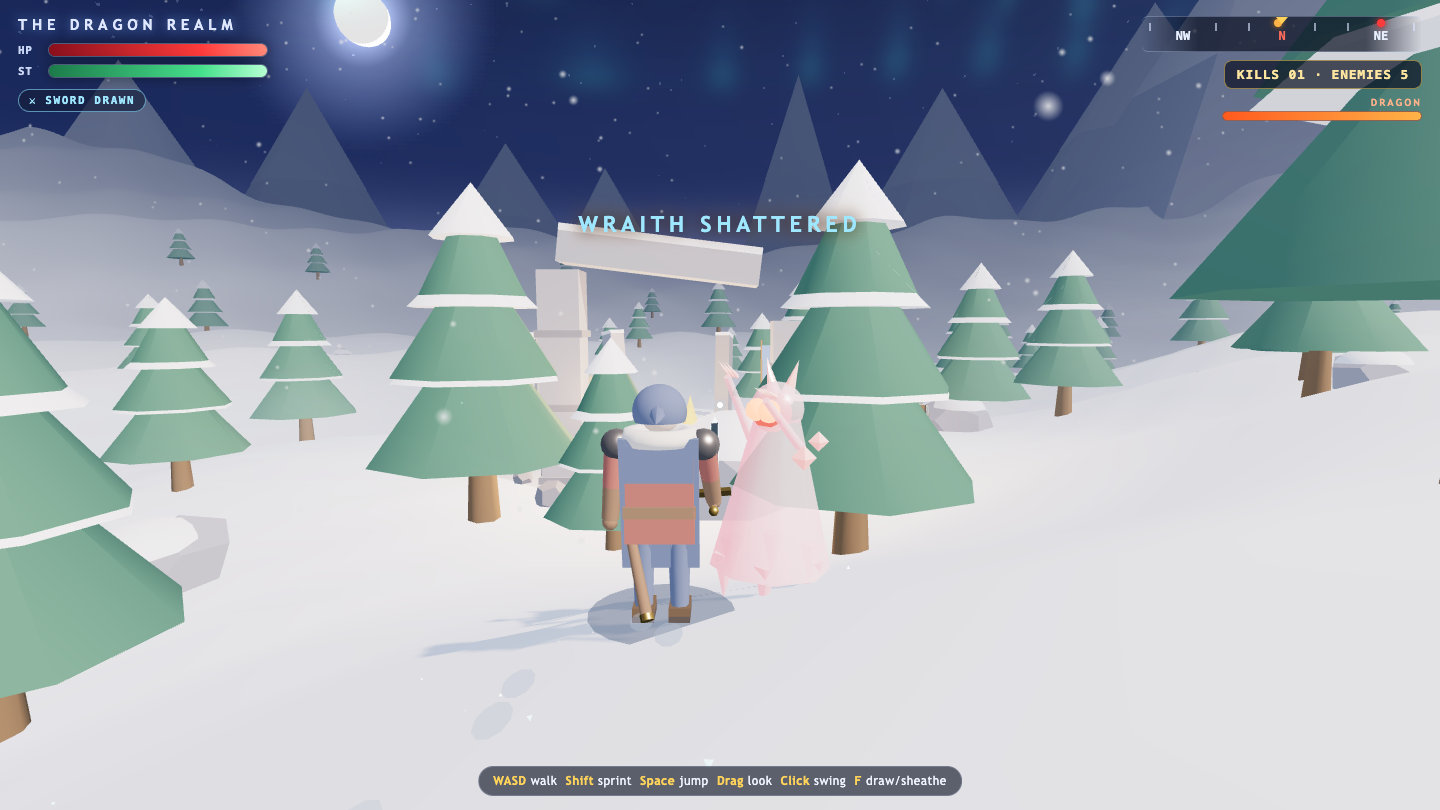
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
Game
Other
Other
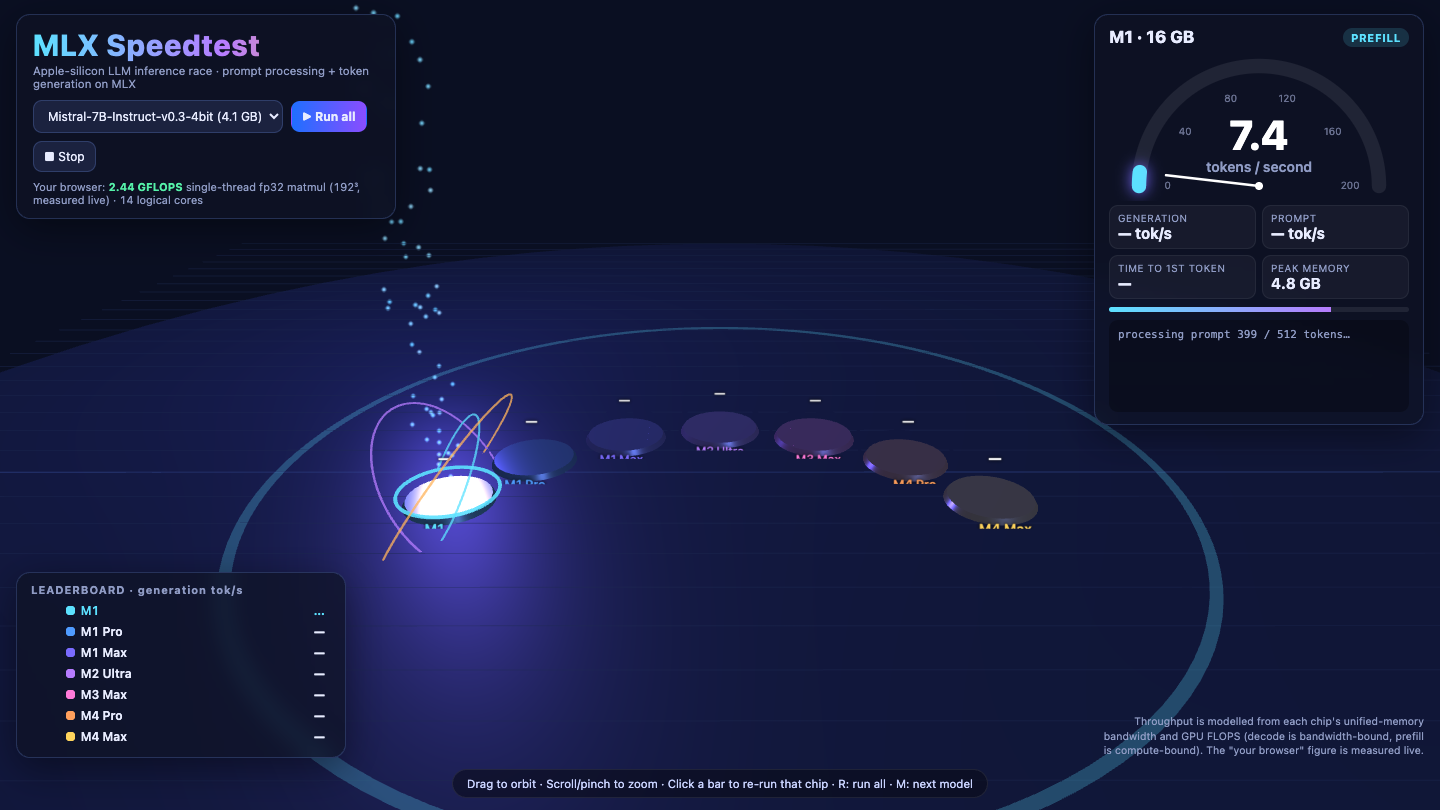
Other
Page
Page
Page
Where Qwen 3.8 beat Claude Opus 5.5
The tasks where I gave Qwen 3.8 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Twilightvale
Game
Qwen 3.8 8.4
·
Claude Opus 5.5 5.5
(+2.9)
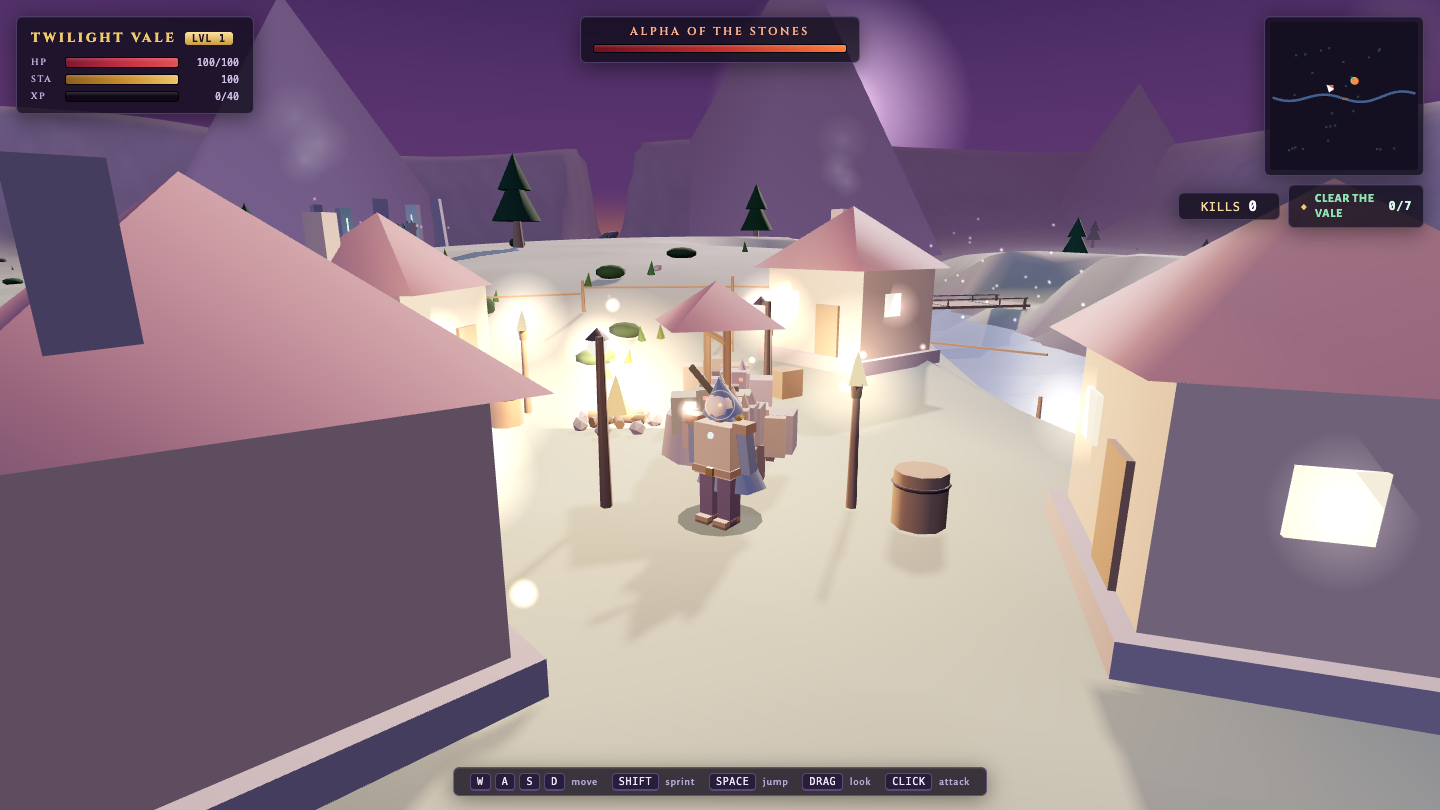
· Atmospheric twilight village
What I saw: Strong twilight atmosphere with cohesive low-poly village, snow, lit lanterns, character model, and polished HUD (minimap, quest, elite bar) all rendering cleanly on-brief. Held just under top tier because the screenshot shows no visible enemies engaged and combat/weather can't b…
Neonblaster
Game
Qwen 3.8 8.7
·
Claude Opus 5.5 5.8
(+2.9)
· synthwave 3D shooter
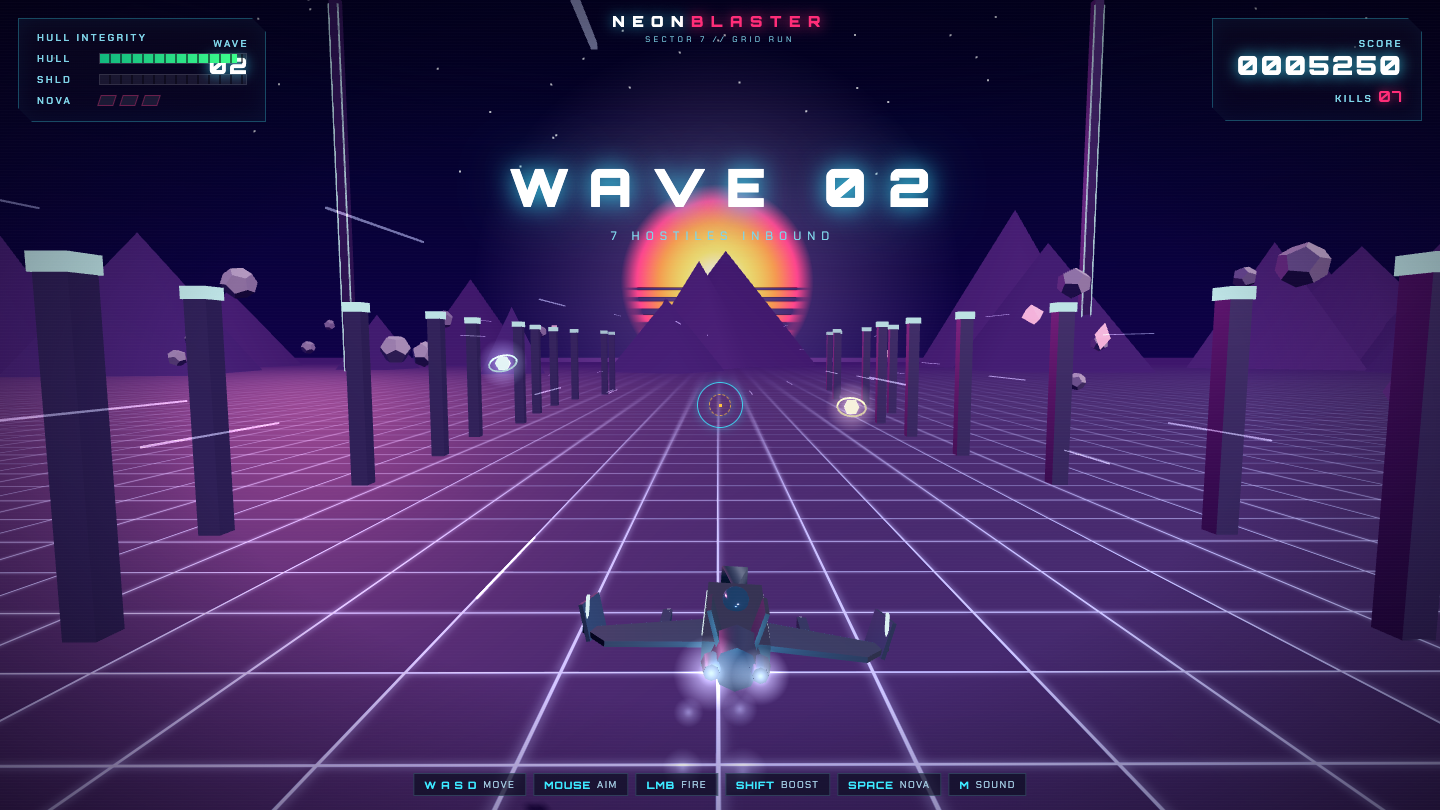
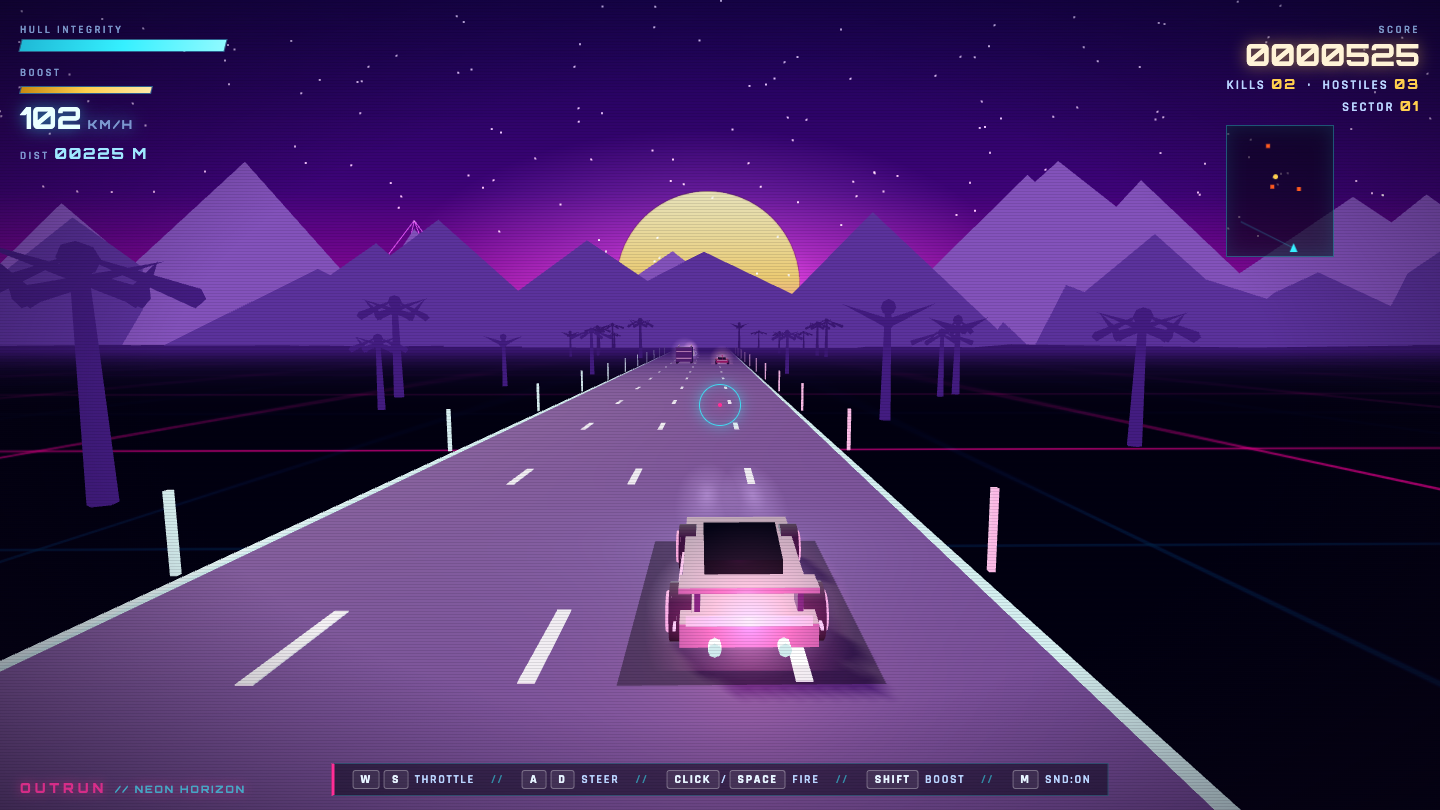
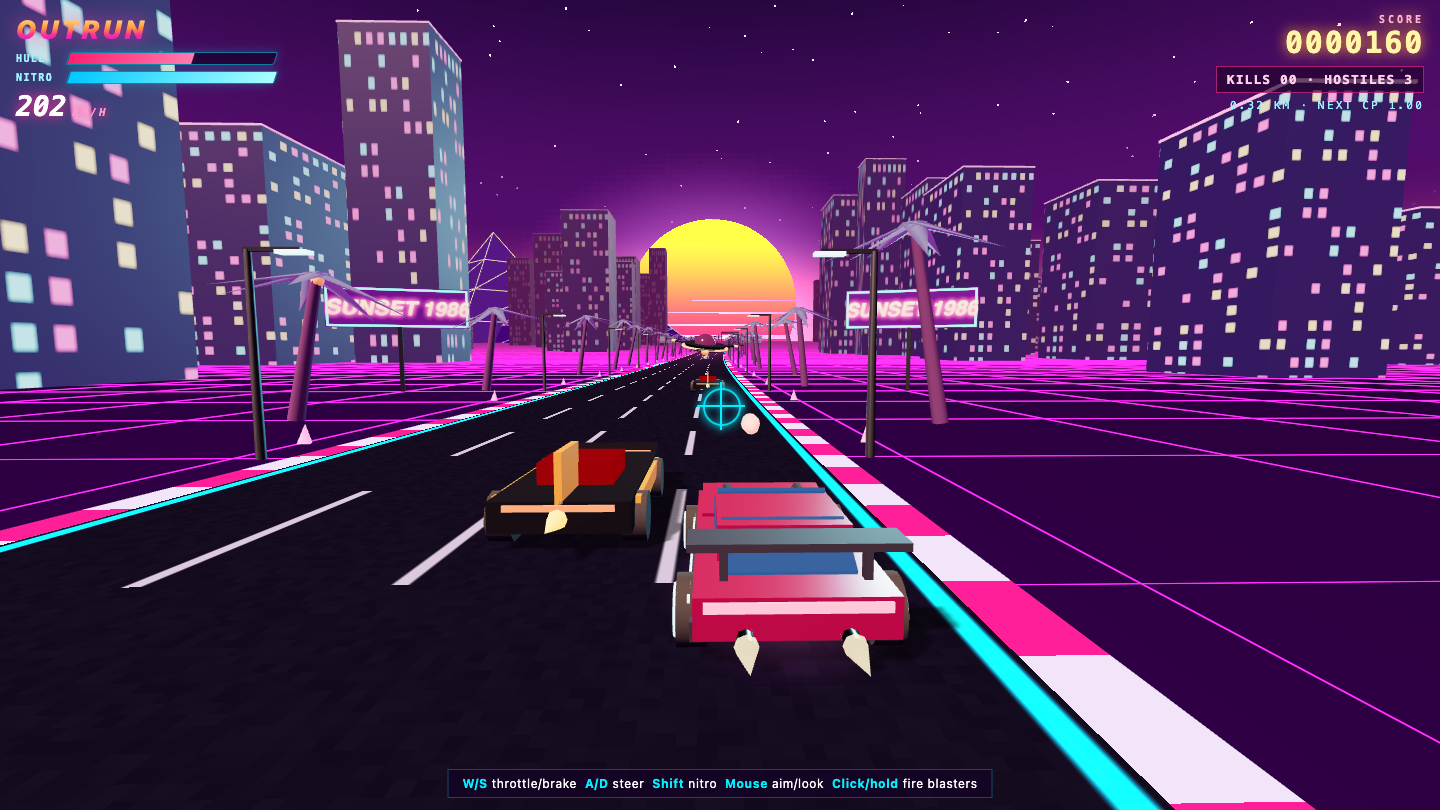
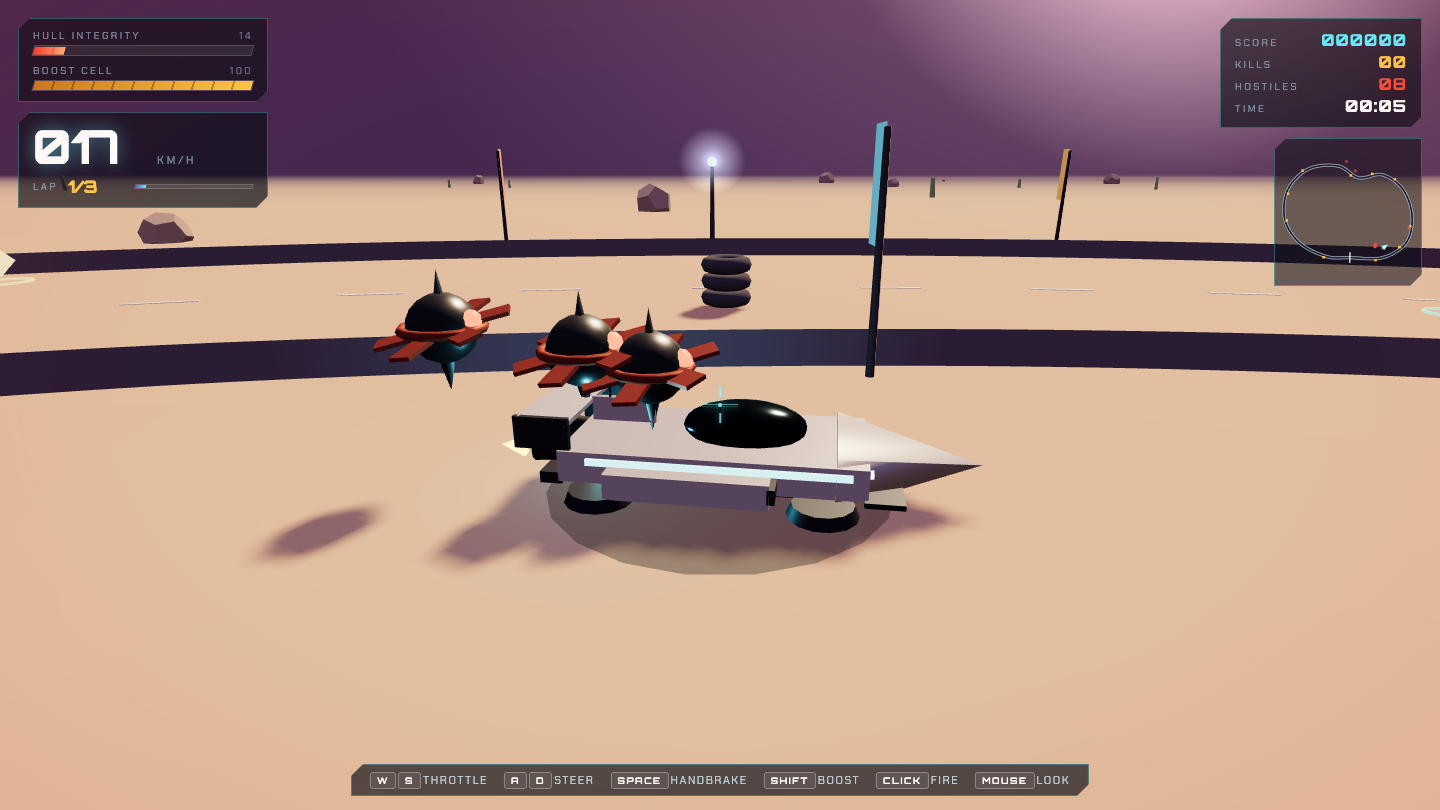
What I saw: Stunning outrun-style 3D perspective with pyramids, sun, grid floor and a beautifully rendered ship plus polished HUD, wave banner, and enemies inbound — visually well above the field's typical 2D shooters. Screenshot shows active wave (score 5250, 7 kills, hostiles visible), and…
Rpg
Game
Qwen 3.8 8.2
·
Claude Opus 5.5 5.5
(+2.7)
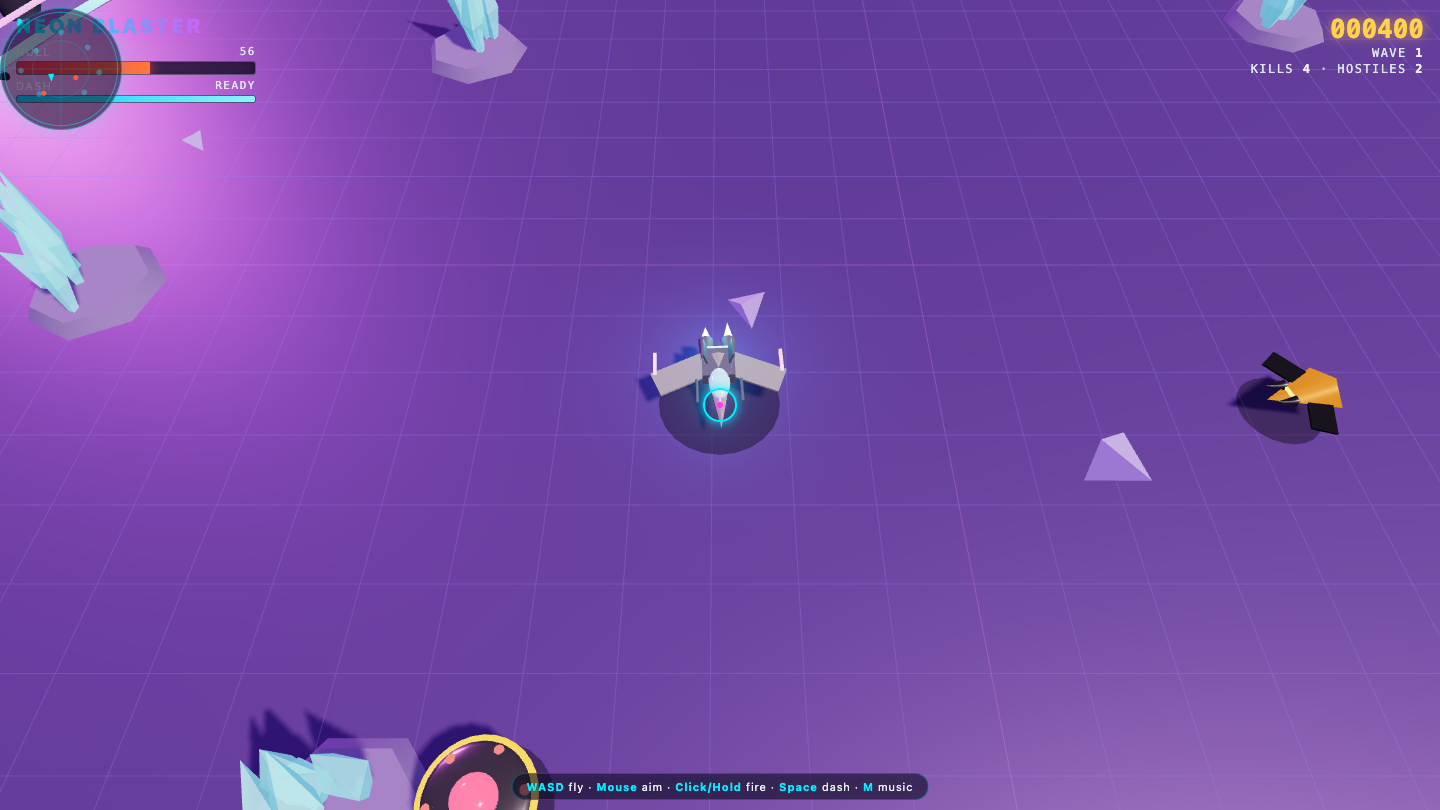
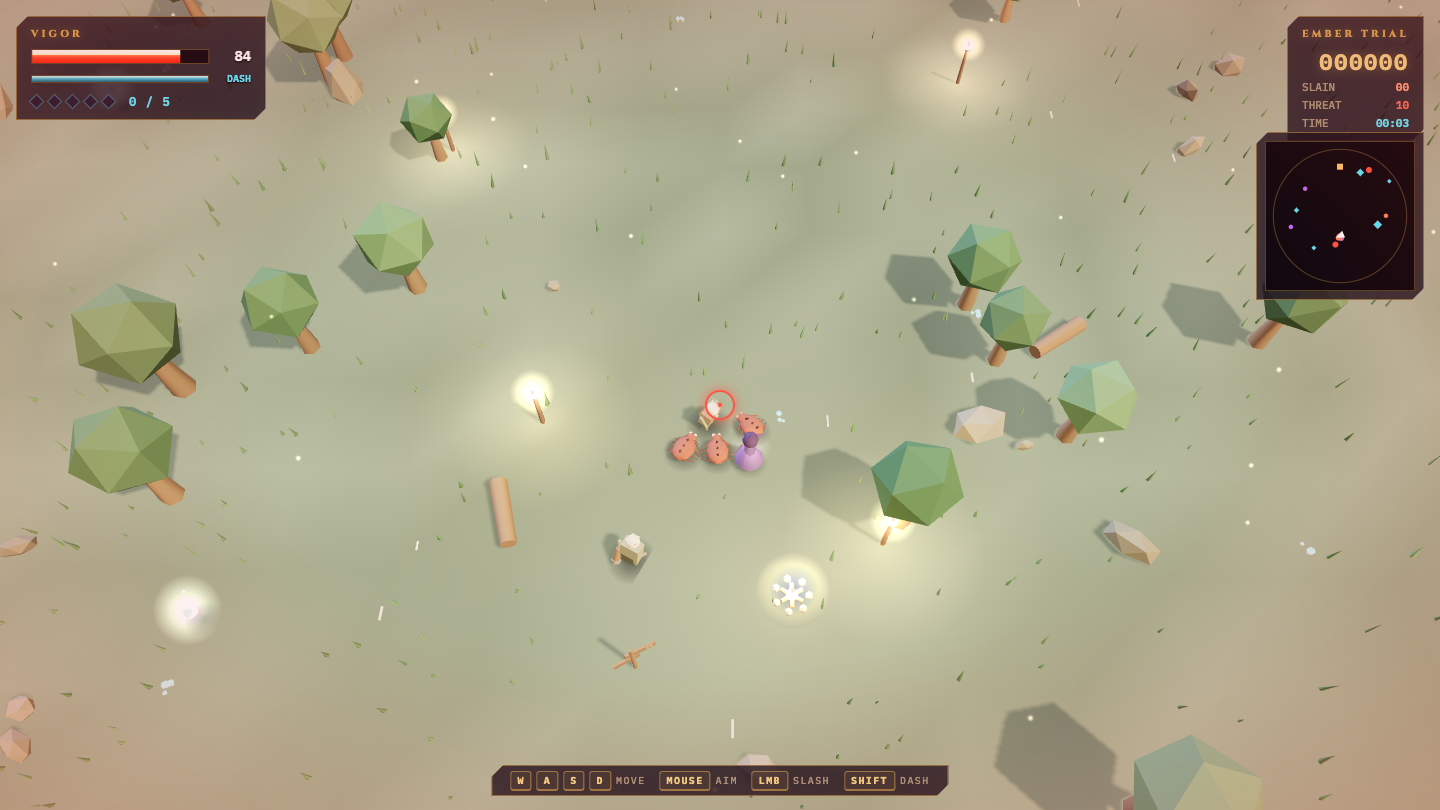
What I saw: Strong, polished 3D top-down action-RPG with a gorgeous low-poly world, working enemies (threat 10, active combat with player being surrounded), crisp HUD/minimap and ember-collection objective. Combat and sprites deliver, but it leans more twin-stick arena than full RPG (invento…
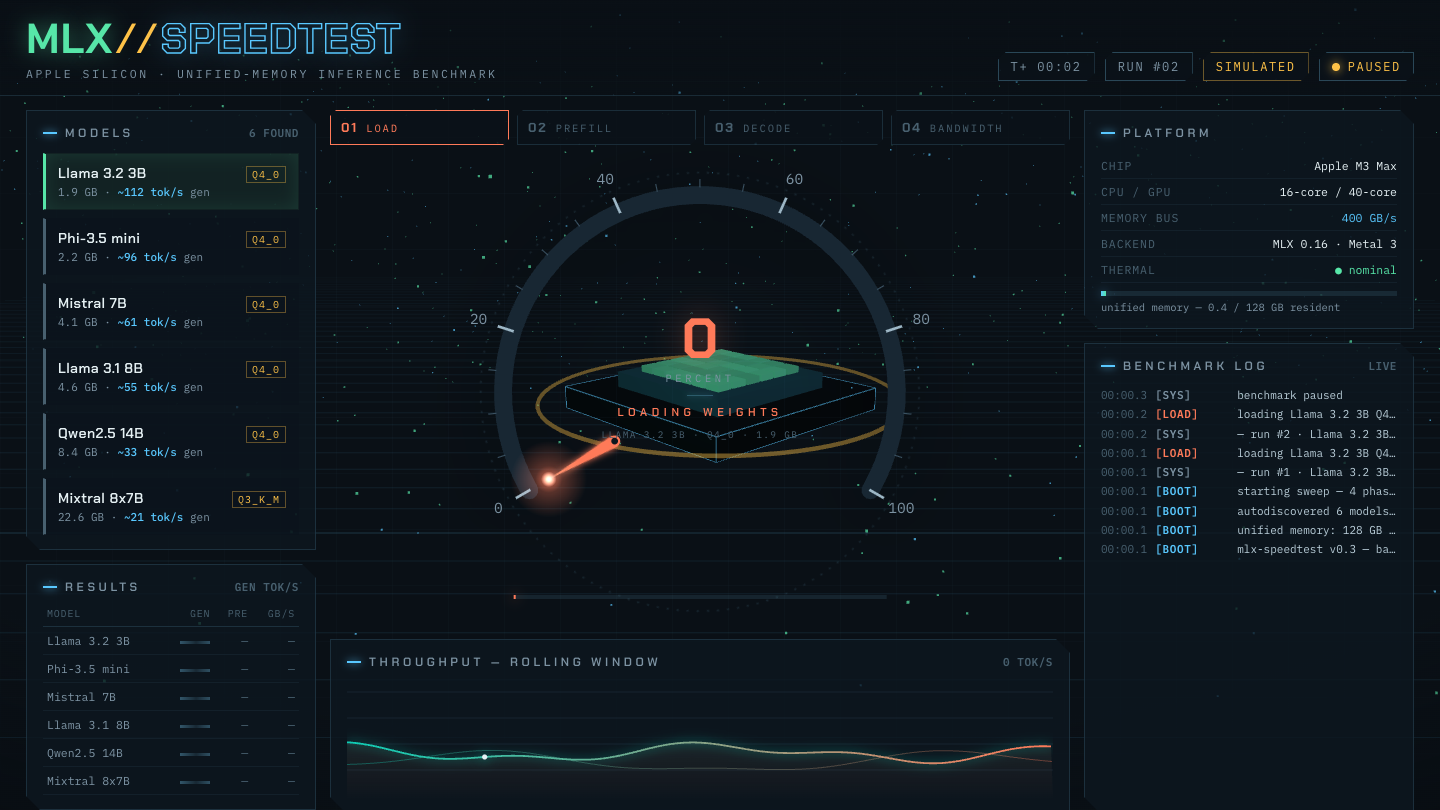
Mlx Speedtest
Other
Qwen 3.8 8.4
·
Claude Opus 5.5 6.0
(+2.4)
· Polished MLX dashboard
What I saw: Strong on-brief render: crisp MLX branding, 6 discovered models with tok/s estimates, phased benchmark steps, a 3D gauge with needle, live log, platform specs and a throughput chart — highly polished and cohesive. Slight weakness is the paused/loading state means the gauge reads …
Skyrim
Game
Qwen 3.8 8.6
·
Claude Opus 5.5 6.2
(+2.4)
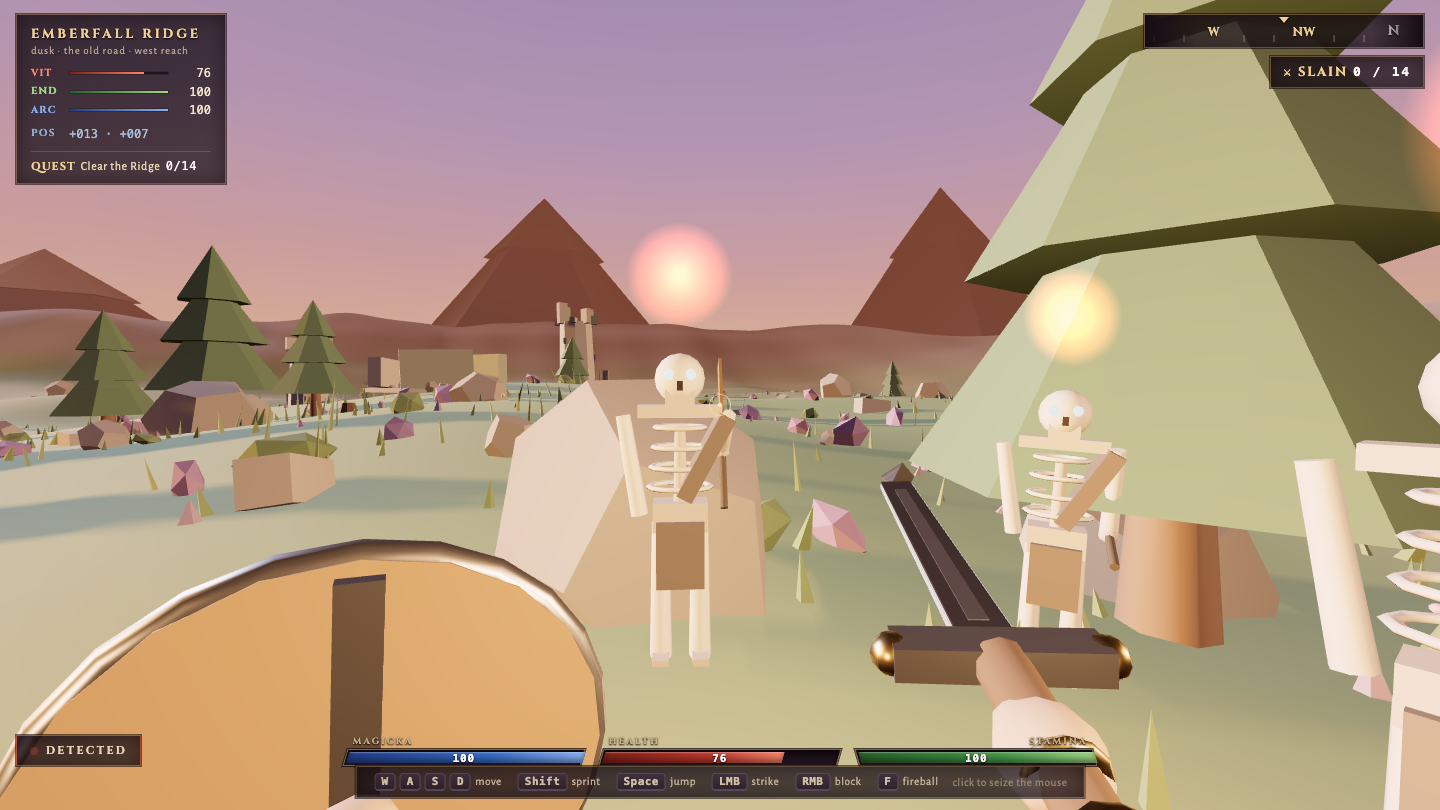
· Skeletons at dusk
What I saw: Strong first-person fantasy scene with a beautiful dusk palette, low-poly terrain and trees, plus visible skeleton enemies, a held weapon/shield, working HUD (Skyrim-style HP/magicka/stamina), compass, kill quest and DETECTED stealth chip — genuinely combat-ready rather than an e…
Where Claude Opus 5.5 beat Qwen 3.8
The tasks where I gave Claude Opus 5.5 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Waves
Visual
Claude Opus 5.5 8.4
·
Qwen 3.8 2.0
(+6.4)
What I saw: Gerstner ocean with a believable choppy surface, specular sunset glints, a bobbing buoy and sailboat, gulls, and a live sea-state readout. The sliders and presets panel is well built. Wave crests lack foam and the far field flattens into a painted look.
Game
Game
Claude Opus 5.5 8.0
·
Qwen 3.8 6.5
(+1.5)
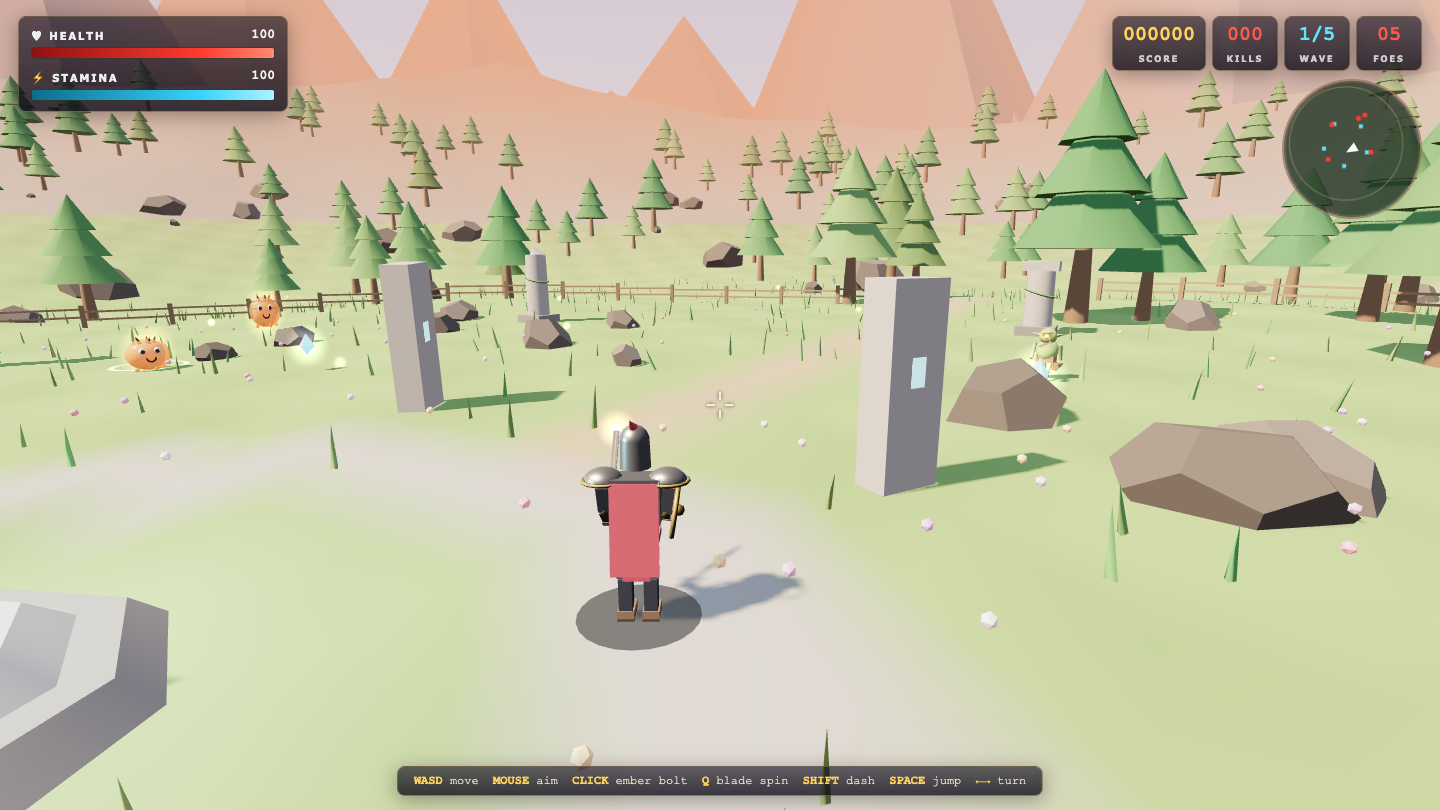
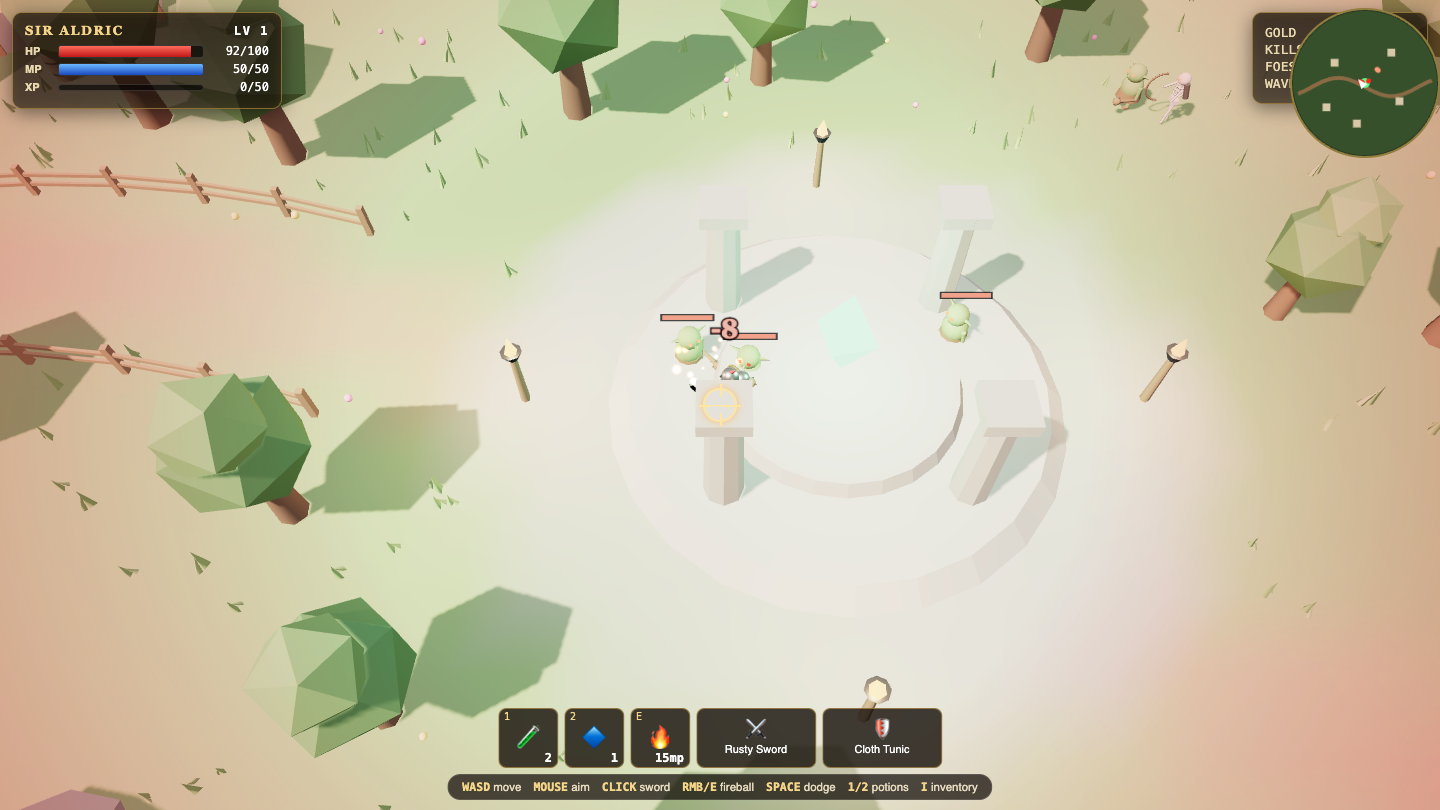
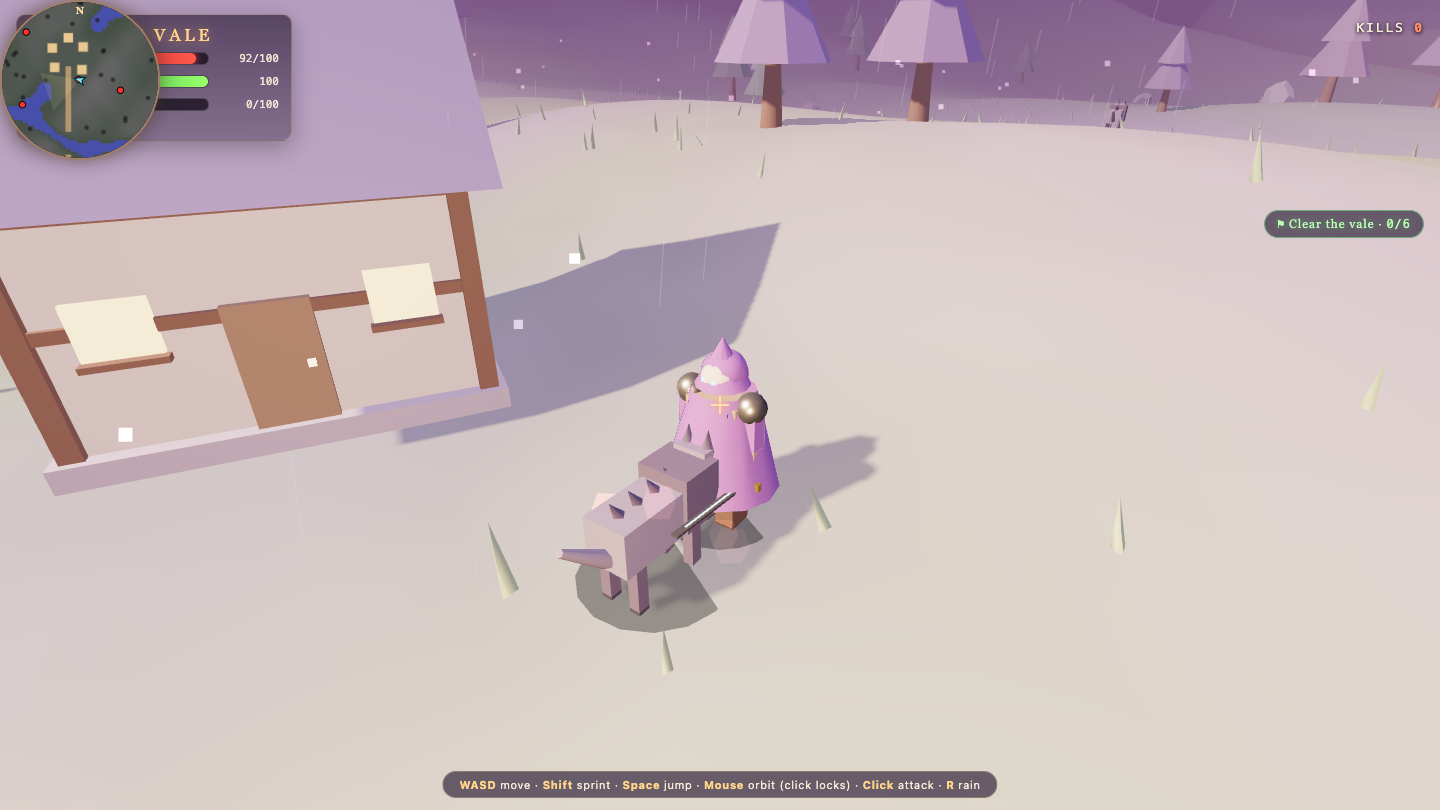
What I saw: Emberfall Vale is a cohesive low-poly third-person action game with an armoured knight, slime and goblin enemies, runestones, a minimap and a clean HUD. Well made, but a generic fantasy-arena take with a fairly bland open field.
Nordiccrypt
Game
Claude Opus 5.5 7.6
·
Qwen 3.8 6.4
(+1.2)
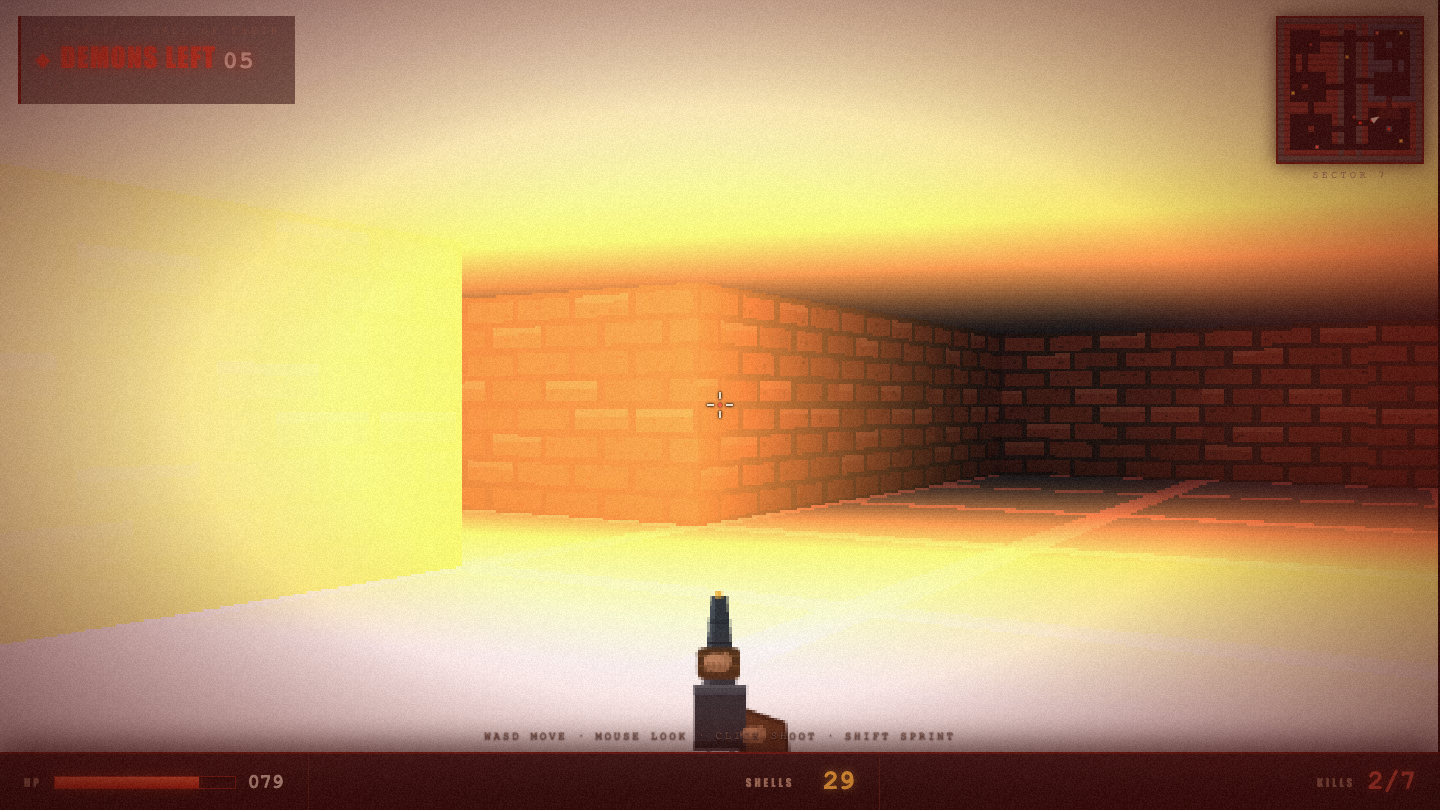
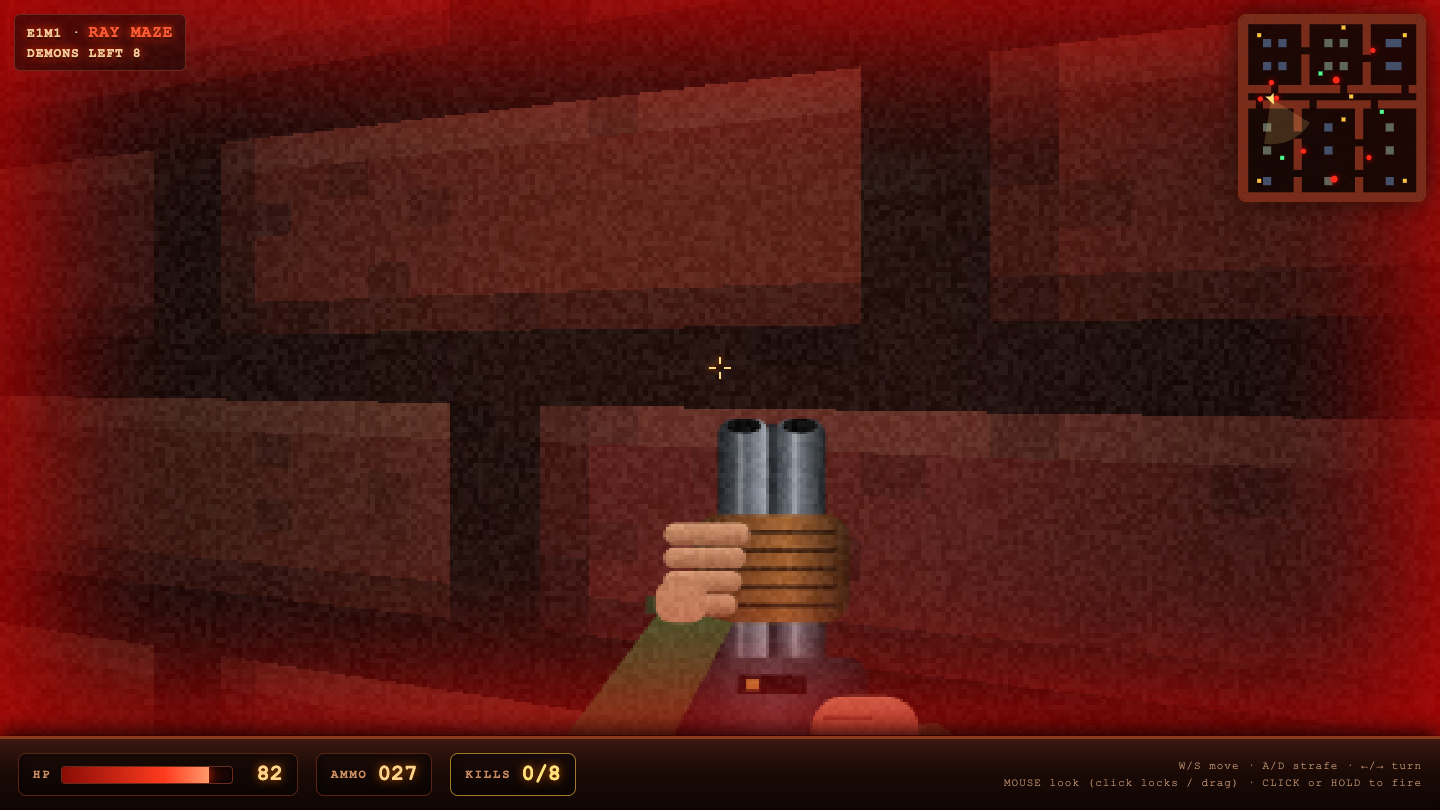
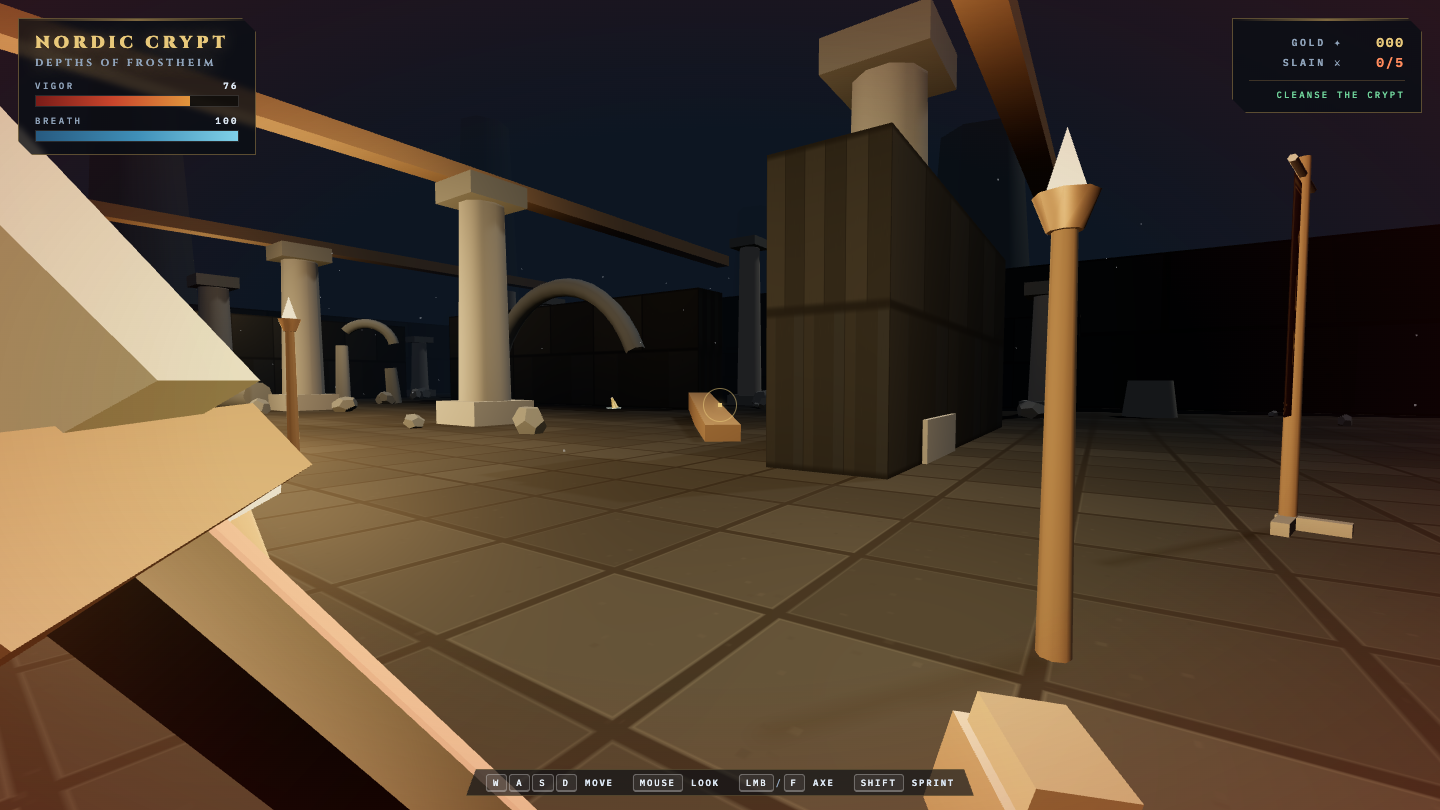
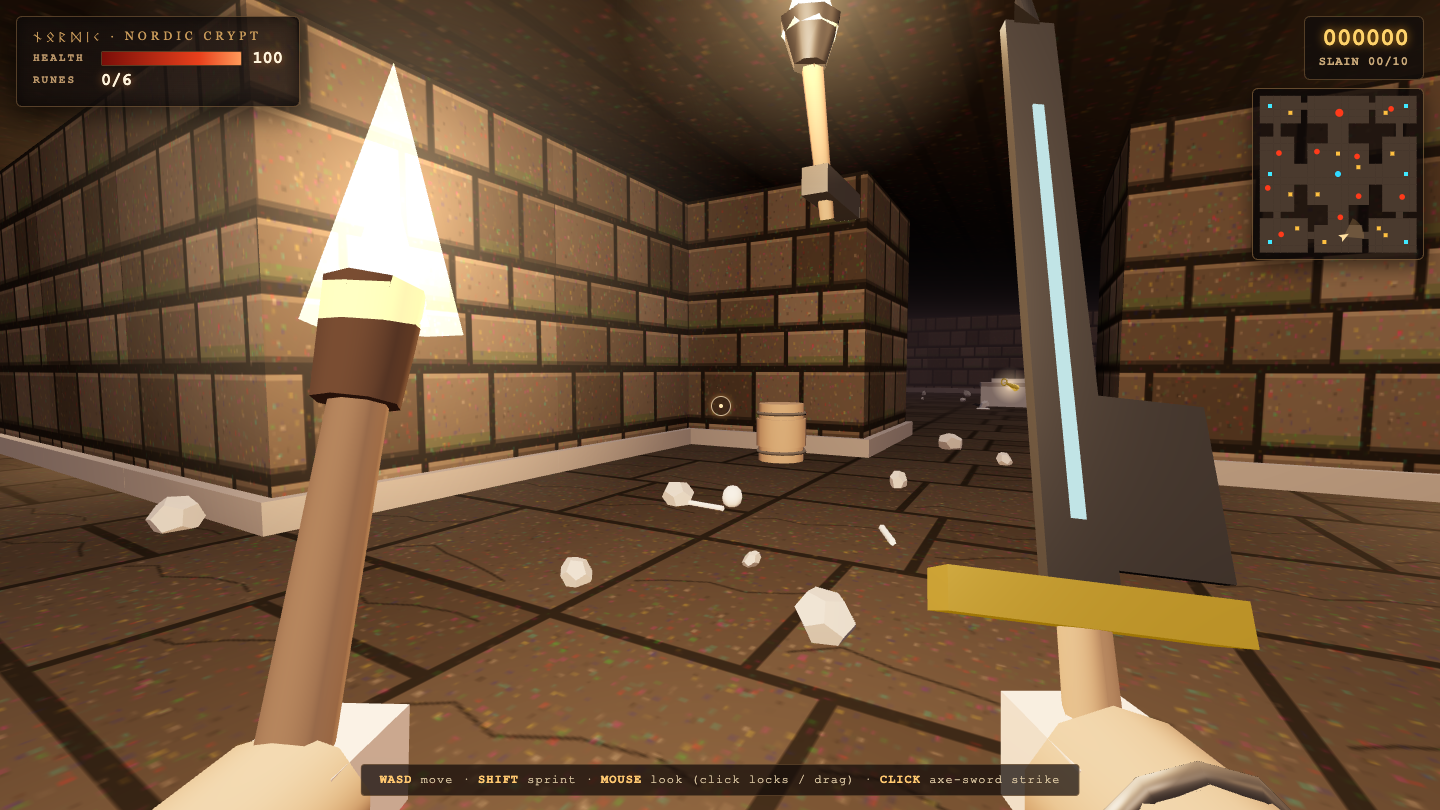
What I saw: Warm torch-lit brick corridors with bones, barrels, a rune counter, a minimap and a cohesive Nordic HUD make it a proper first-person crawler. The held torch flame is a solid white cone, the axe-sword and hands are crude flat blocks, and no draugr is in view, well short of the fi…
Dogfight
Game
Claude Opus 5.5 7.8
·
Qwen 3.8 6.8
(+1.0)
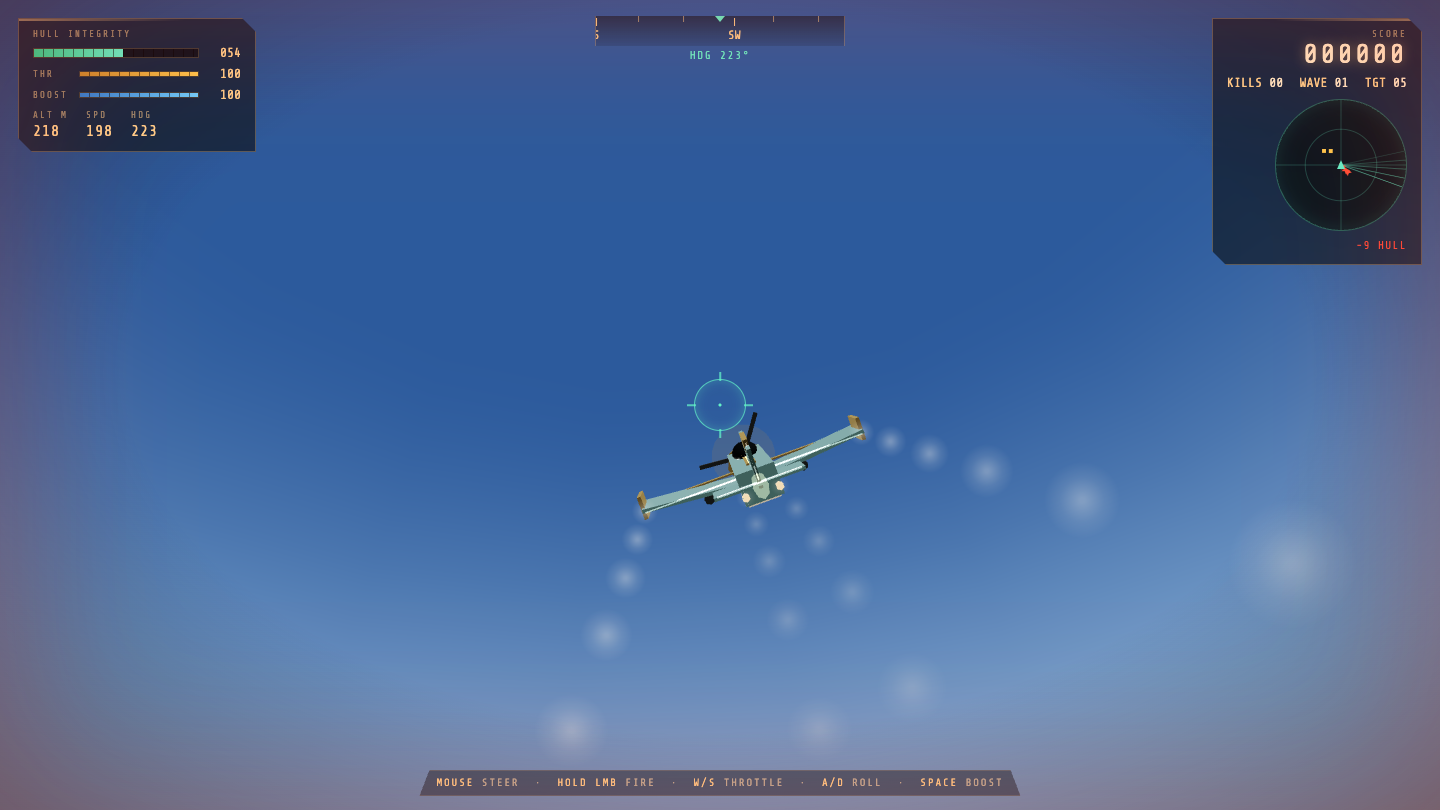
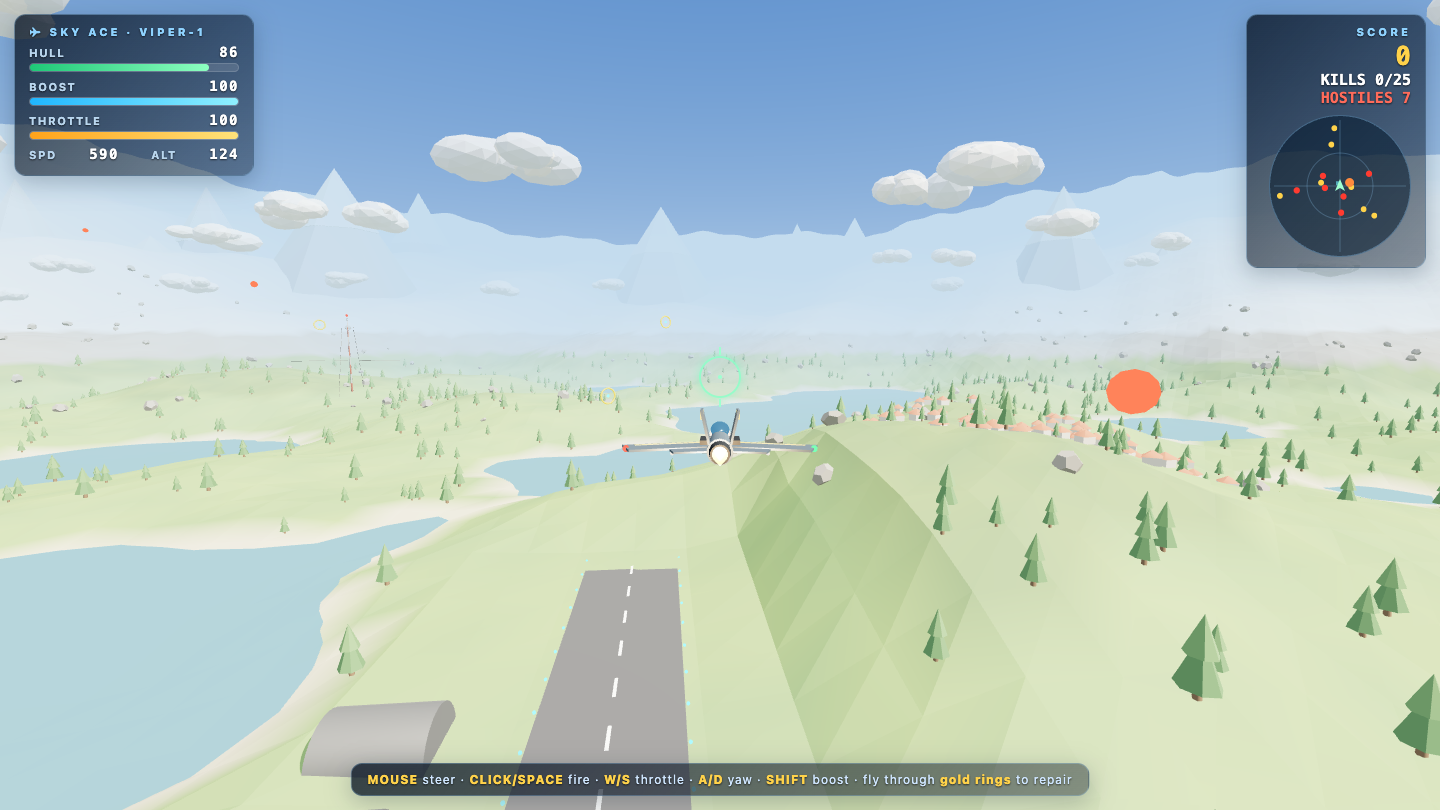
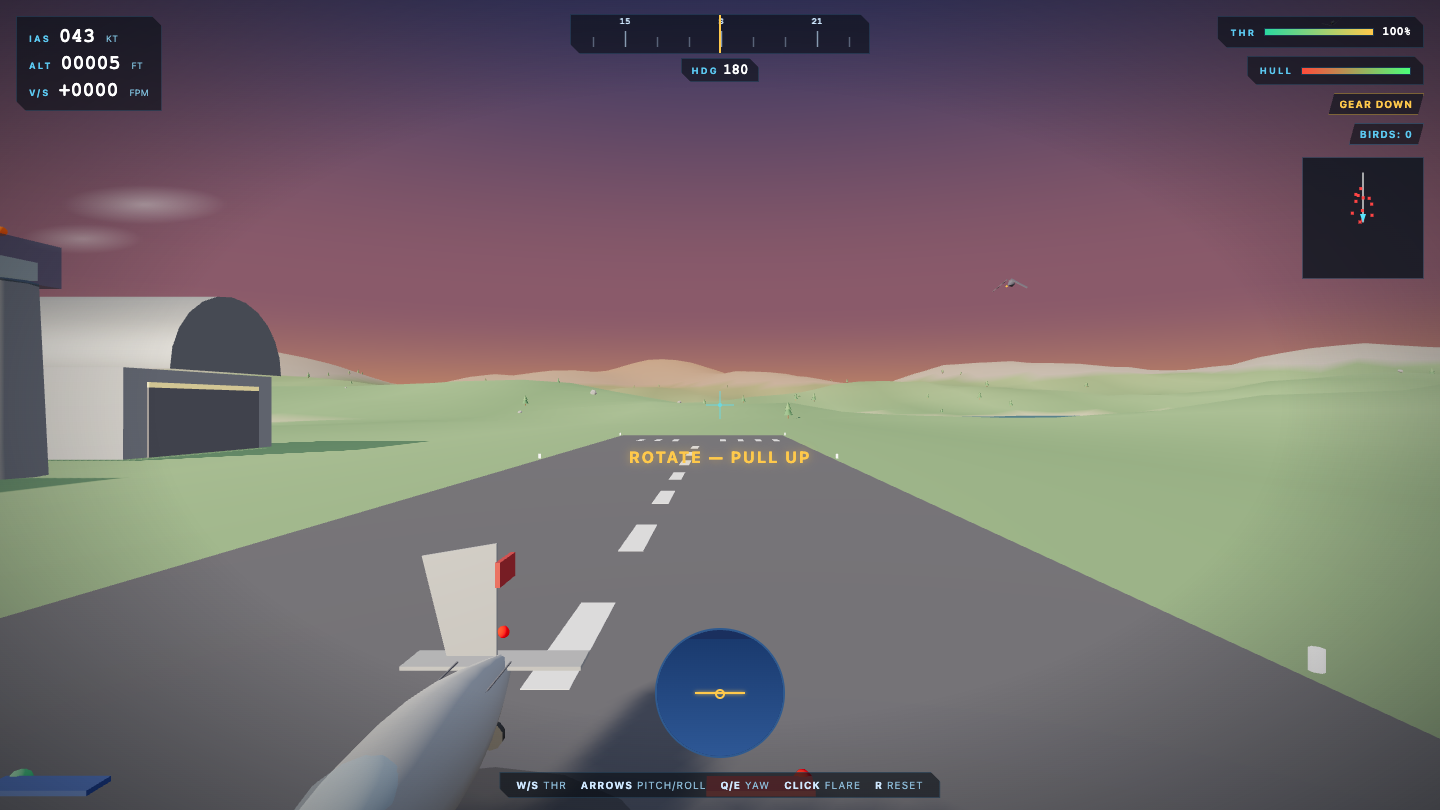
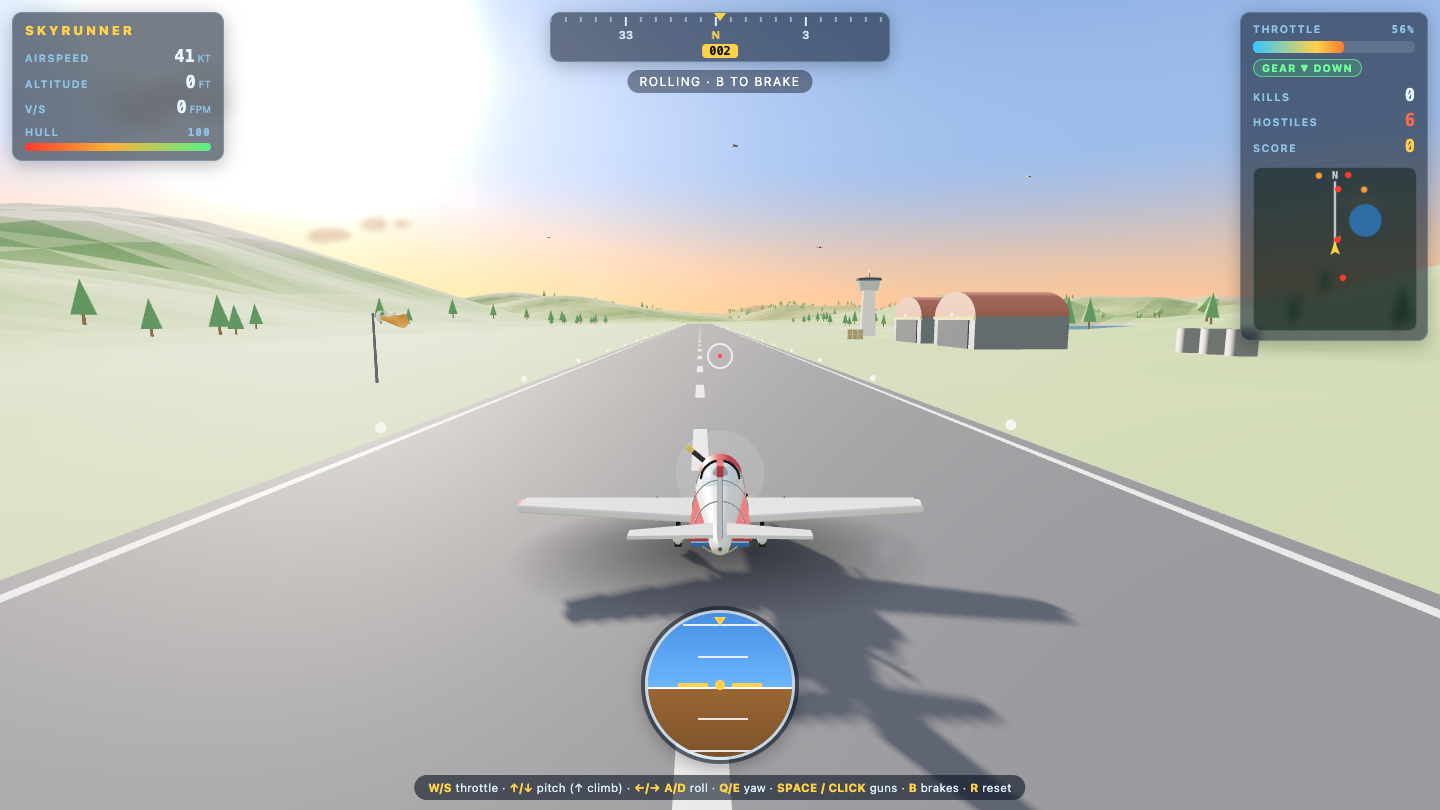
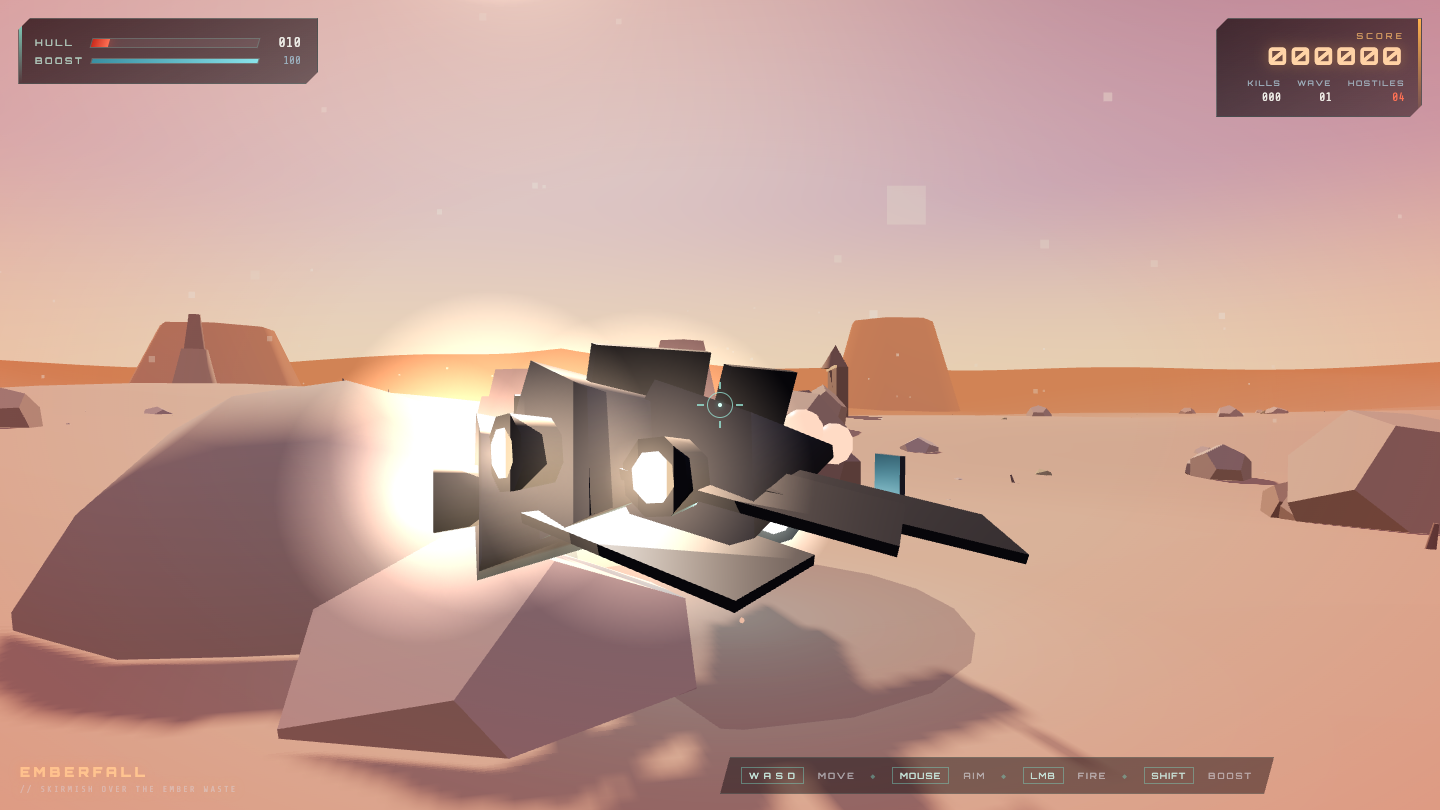
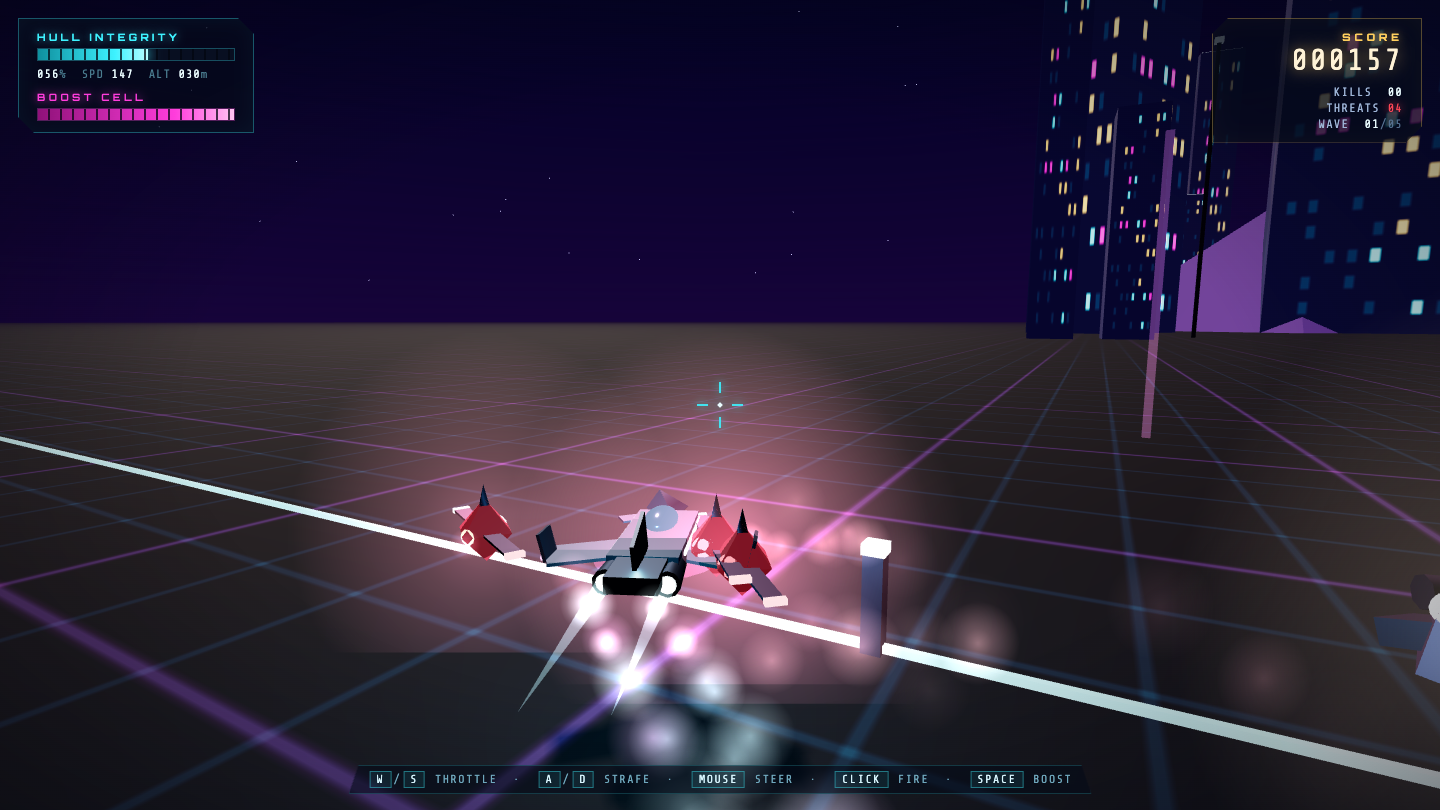
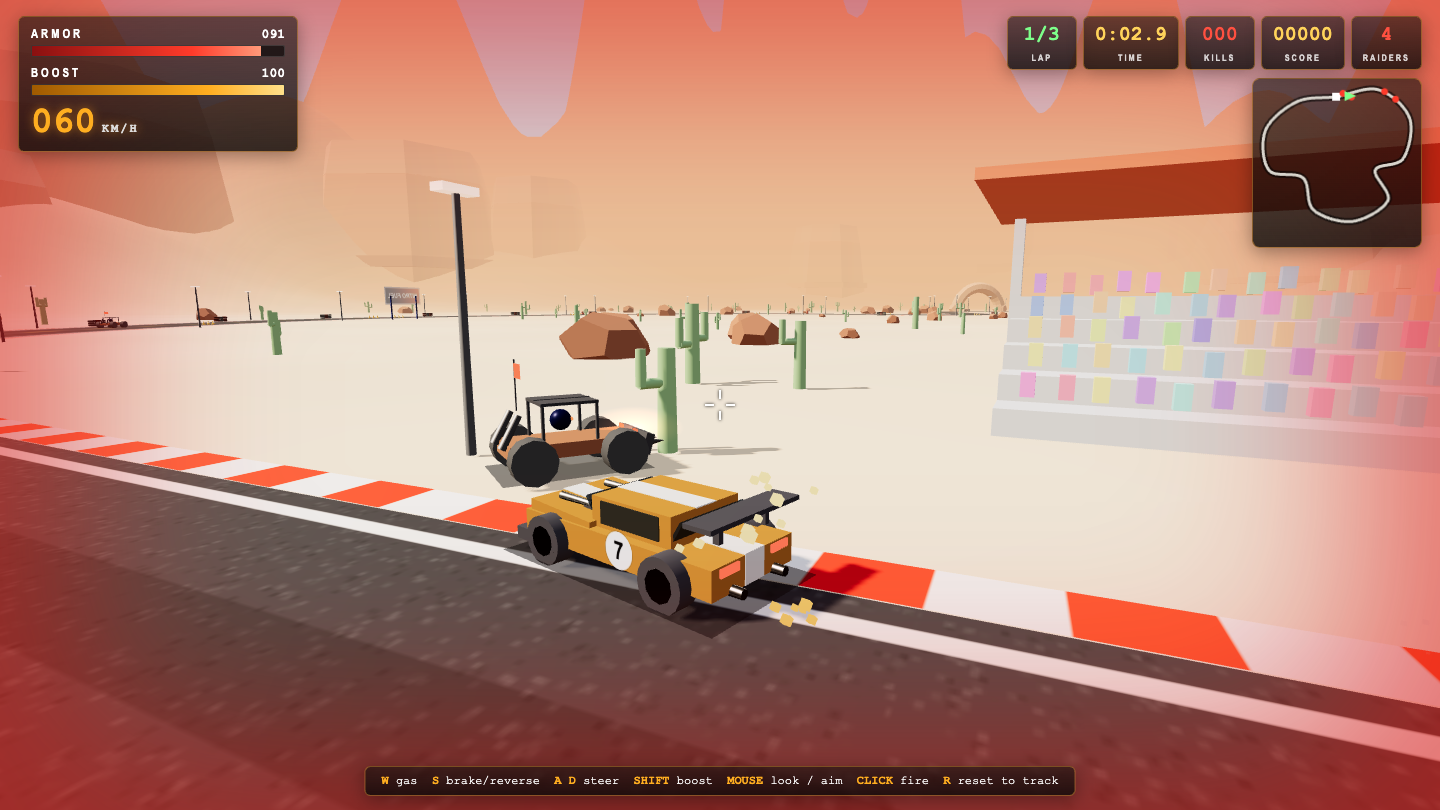
What I saw: Bright, well-lit low-poly world (lakes, forests, village, runway) with a decent jet model and a clean hull/boost/throttle HUD plus radar. The frame reads more like a flight sim than a fight: enemies are specks, the score is 0, and there is an odd flat orange disc in the scene.
Neonsnake
Other
Claude Opus 5.5 7.4
·
Qwen 3.8 6.8
(+0.6)
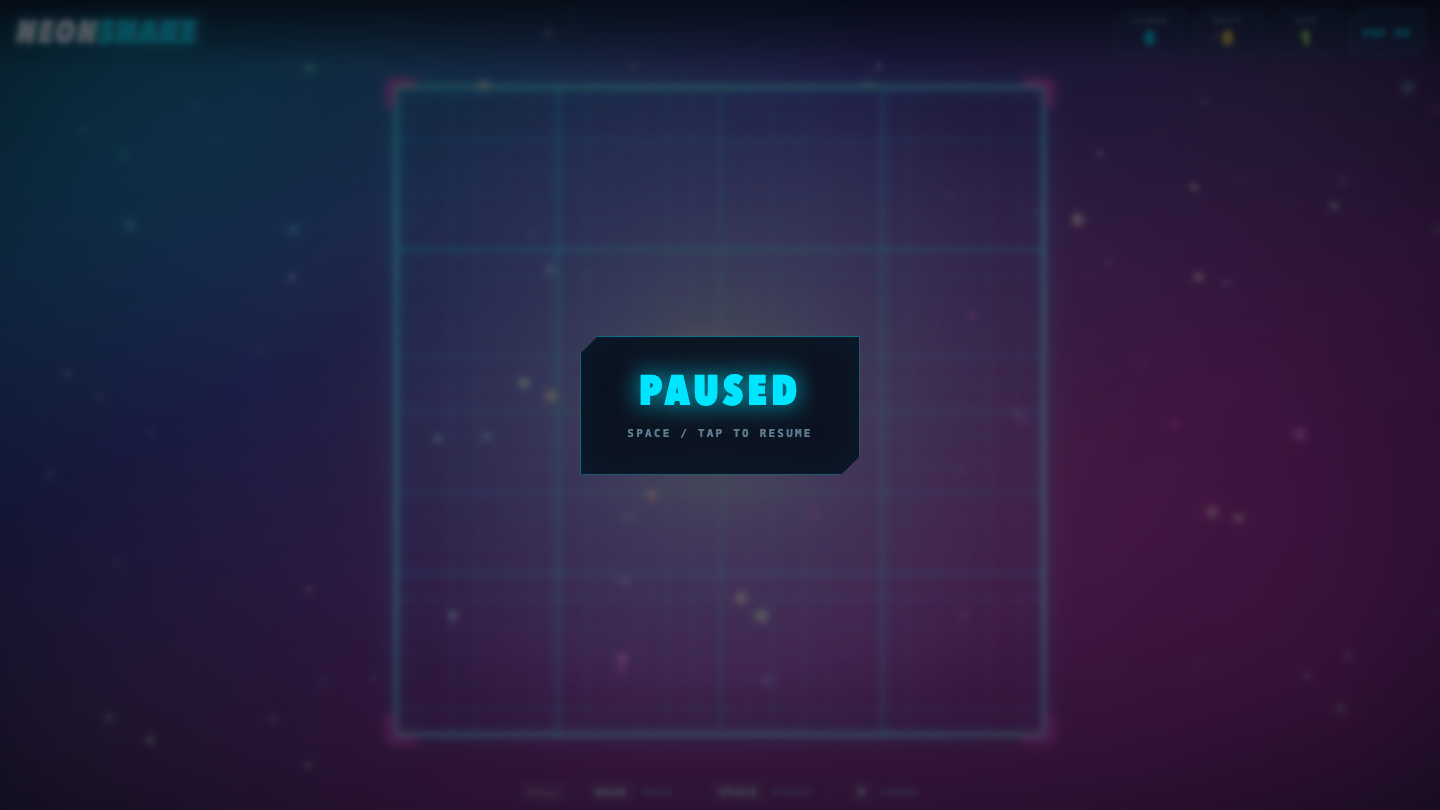
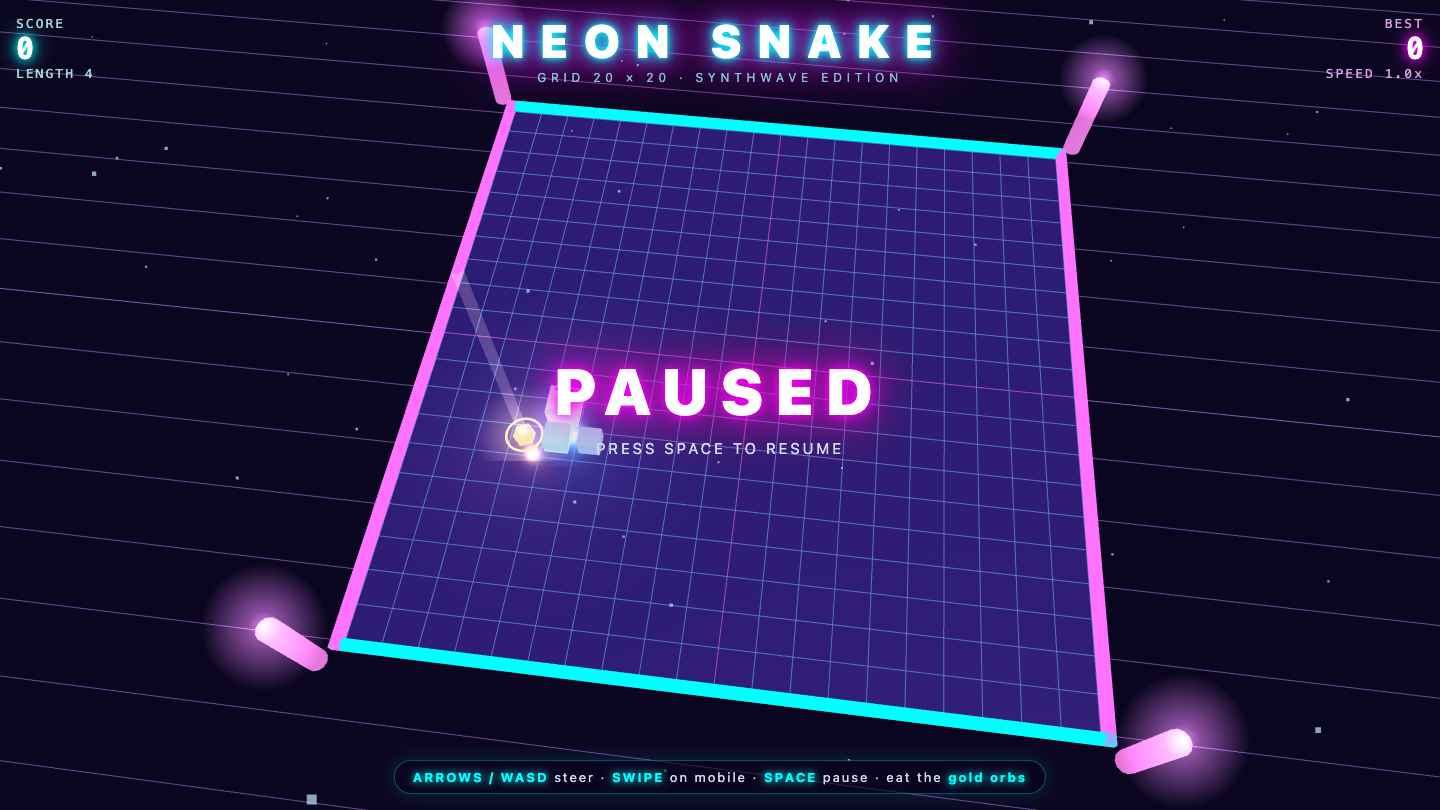
What I saw: Strong synthwave presentation: a tilted neon 3D grid arena, glowing corner pylons and a clean score/best HUD. The frame shows a paused board with a tiny 4-segment snake. The known bug where body segments snap cell-to-cell while only the head glides makes play choppy.
Strengths & weaknesses I logged
Qwen 3.8
Strengths
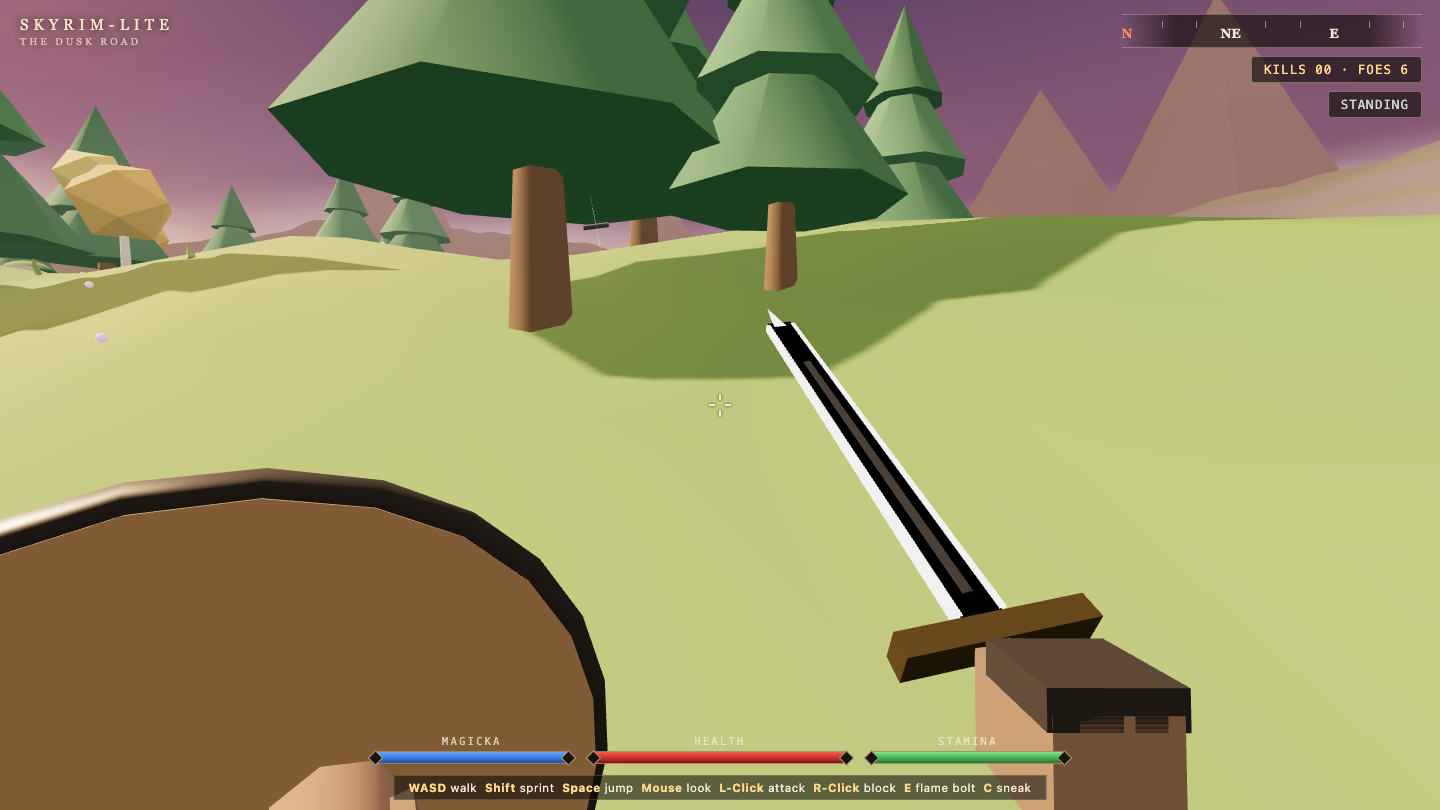
- Skyrim-style open worlds — the Dragon Realm build rendered a lit snowfield, first-person sword and working roaming enemies (7.8)
- Held up across game genres early — voxel sandbox and Doom raycaster both came out shippable
- Runs as a real agentic coder inside Qoder (writes + iterates on files), not just a chat model
Trade-offs
- Torch-lit dungeon (crypt) came out generic (6.3); one open-world RPG one-shot black-screened (twilightvale 2.5) — classic three.js r128 API drift
- Preview is Qoder / Token-Plan only — no OpenRouter or public API, so it can't be routed into an app the way the OpenRouter models can
Claude Opus 5.5
Strengths
- Frontier-class coding + agentic reasoning (Claude 5 family)
- 1M-token context — reads an entire codebase in one call
- All 50 one-shot builds rendered with zero console errors; all 23 games passed the input playtest
Trade-offs
- Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes
- One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts)
Pricing & context — the spec sheet
| Spec | Qwen 3.8 | Claude Opus 5.5 |
|---|---|---|
| Vendor | Alibaba | Anthropic |
| Context window | Served through Alibaba's Qoder agent platform; the 3.8-Max preview has no standalone public context window yet. | 1,000,000 tokens |
| Price | Qoder plan | $4 / $20 per M |
| Pricing detail | Qwen3.8-Max-Preview is Alibaba's ~2.4T-parameter flagship, positioned just behind Claude Fable 5. It is NOT on OpenRouter or a public API yet — the only access today is inside Qoder (Alibaba's agentic coding platform, free 2-week Pro trial). Benched here via the Qoder CLI on model `Qwen3.8-Max-Preview`, one-shot. | Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. |
| Release | 2026-07 | 2026-09 |
| Bench coverage | 45/45 scored · avg 8.10/10 | 50/50 scored · avg 7.57/10 |
The verdict — which should you pick?
Across 45 scored shared tasks, Qwen 3.8 averaged 8.10/10, beating Claude Opus 5.5's 7.60/10 by 0.50 points. Pick Qwen 3.8 when the build has to ship on the first prompt and you can afford the trade-offs in the comparison below.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire Qwen 3.8 and Claude Opus 5.5 both into the Agent Operating System and dispatch each from the kanban by task type — one-shot 3d game and world prototypes where atmosphere matters → Qwen 3.8, hardest agentic builds → Claude Opus 5.5. That's the same setup I run for the 4,000+ founders inside the AI Profit Boardroom.
FAQ — Qwen 3.8 vs Claude Opus 5.5
Which is better, Qwen 3.8 or Claude Opus 5.5?
On Goldie Bench, Qwen 3.8 averages 8.10/10 across the shared tasks, with 8 gold, 6 silver, 7 bronze overall. Claude Opus 5.5 averages 7.60/10, with 0 gold, 0 silver, 1 bronze. Qwen 3.8 wins the head-to-head 34–10.
How much does Qwen 3.8 cost vs Claude Opus 5.5?
Qwen 3.8: Qwen3.8-Max-Preview is Alibaba's ~2.4T-parameter flagship, positioned just behind Claude Fable 5. It is NOT on OpenRouter or a public API yet — the only access today is inside Qoder (Alibaba's agentic coding platform, free 2-week Pro trial). Benched here via the Qoder CLI on model `Qwen3.8-Max-Preview`, one-shot. Claude Opus 5.5: Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts.
What's the context window for Qwen 3.8 vs Claude Opus 5.5?
Qwen 3.8 has a Served through Alibaba's Qoder agent platform; the 3.8-Max preview has no standalone public context window yet. context window. Claude Opus 5.5 has a 1,000,000 tokens context window.
When should I pick Qwen 3.8 over Claude Opus 5.5?
Pick Qwen 3.8 for: One-shot 3D game and world prototypes where atmosphere matters; Anyone already in the Qoder IDE/CLI wanting a near-frontier model free on the Pro trial; A cheaper stand-in for Fable 5 on creative-visual builds. The trade-off is the weaknesses we logged on the bench: Torch-lit dungeon (crypt) came out generic (6.3); one open-world RPG one-shot black-screened (twilightvale 2.5) — classic three.js r128 API drift; Preview is Qoder / Token-Plan only — no OpenRouter or public API, so it can't be routed into an app the way the OpenRouter models can.
When should I pick Claude Opus 5.5 over Qwen 3.8?
Pick Claude Opus 5.5 for: Hardest agentic builds; Whole-repo reasoning; Frontier one-shots. The trade-off is the weaknesses we logged on the bench: Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes; One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts).
How does Goldie Bench score Qwen 3.8 vs Claude Opus 5.5?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
Qwen 3.8 vs Fusion Claude Opus 5.5 vs Fusion Qwen 3.8 vs Claude Opus 5 Claude Opus 5.5 vs Claude Opus 5 Qwen 3.8 vs Hermes MoA Claude Opus 5.5 vs Hermes MoA Qwen 3.8 vs GPT-5.6 Sol Claude Opus 5.5 vs GPT-5.6 SolFull model pages: Qwen 3.8 · Claude Opus 5.5 · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.
4,000+founders
258documented wins
38countries
$59/momonthly