Real head-to-head · same prompt, one shot
Claude Opus 5.5 vs Muse Spark 1.2
Anthropic's Opus 5.5 — benched on all 50 one-shot builds, every game playtested. vs Meta's coding reasoning model — co-trained with its own agent, 1M-token window.
Head-to-head verdict: Muse Spark 1.2 wins 30–17 with 3 ties.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to Claude Opus 5.5 and Muse Spark 1.2, side by side, on 50 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
Claude Opus 5.5 · Benched on all 50 GoldieBench tasks via a Claude subscription: one-shot builds, real renders, pixel-diff playtests on every game, then vision-judged.
Muse Spark 1.2 · Cloud coder via OpenRouter; the Muse Code agent (one-command install) is its native harness.
Side-by-side on 50 shared tasks
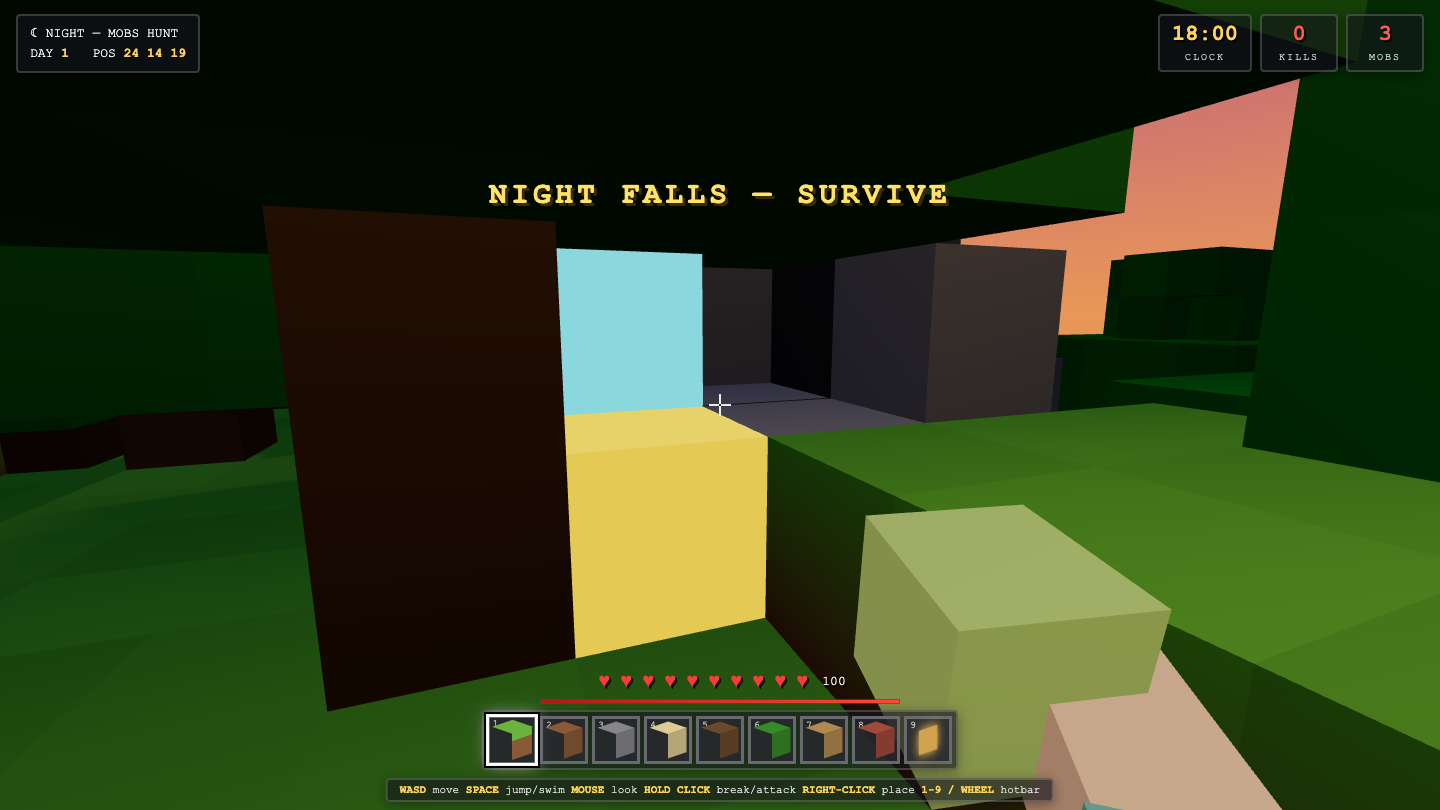
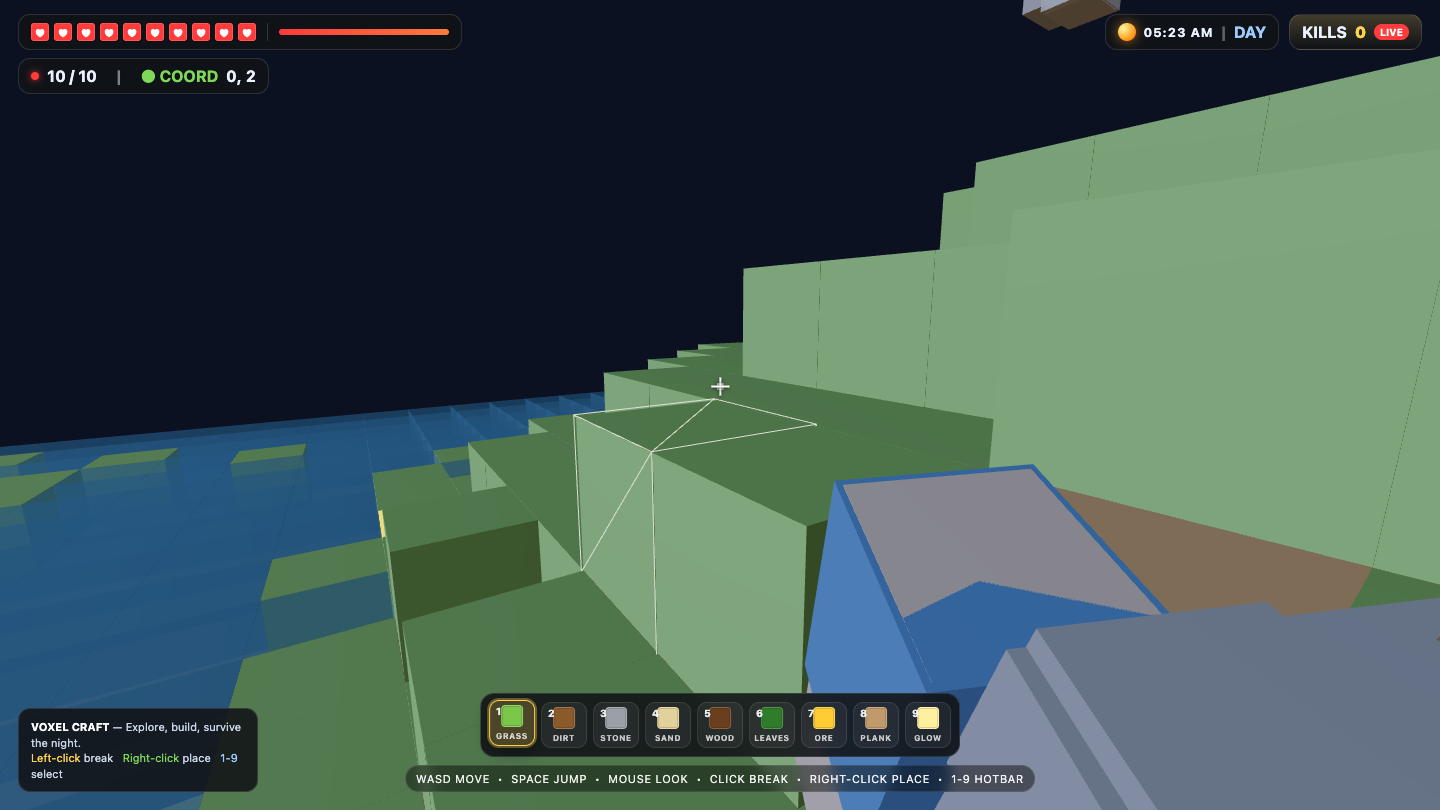
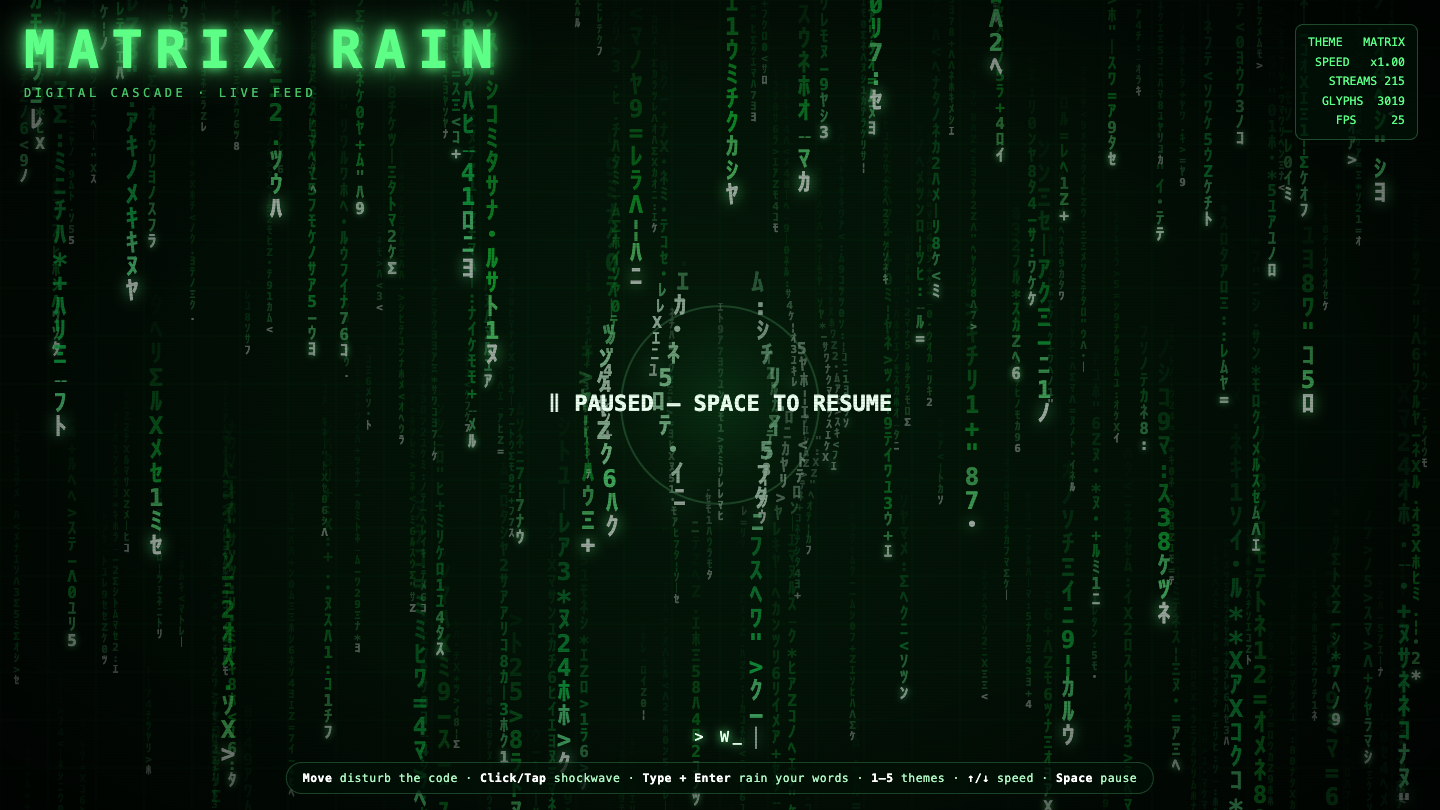
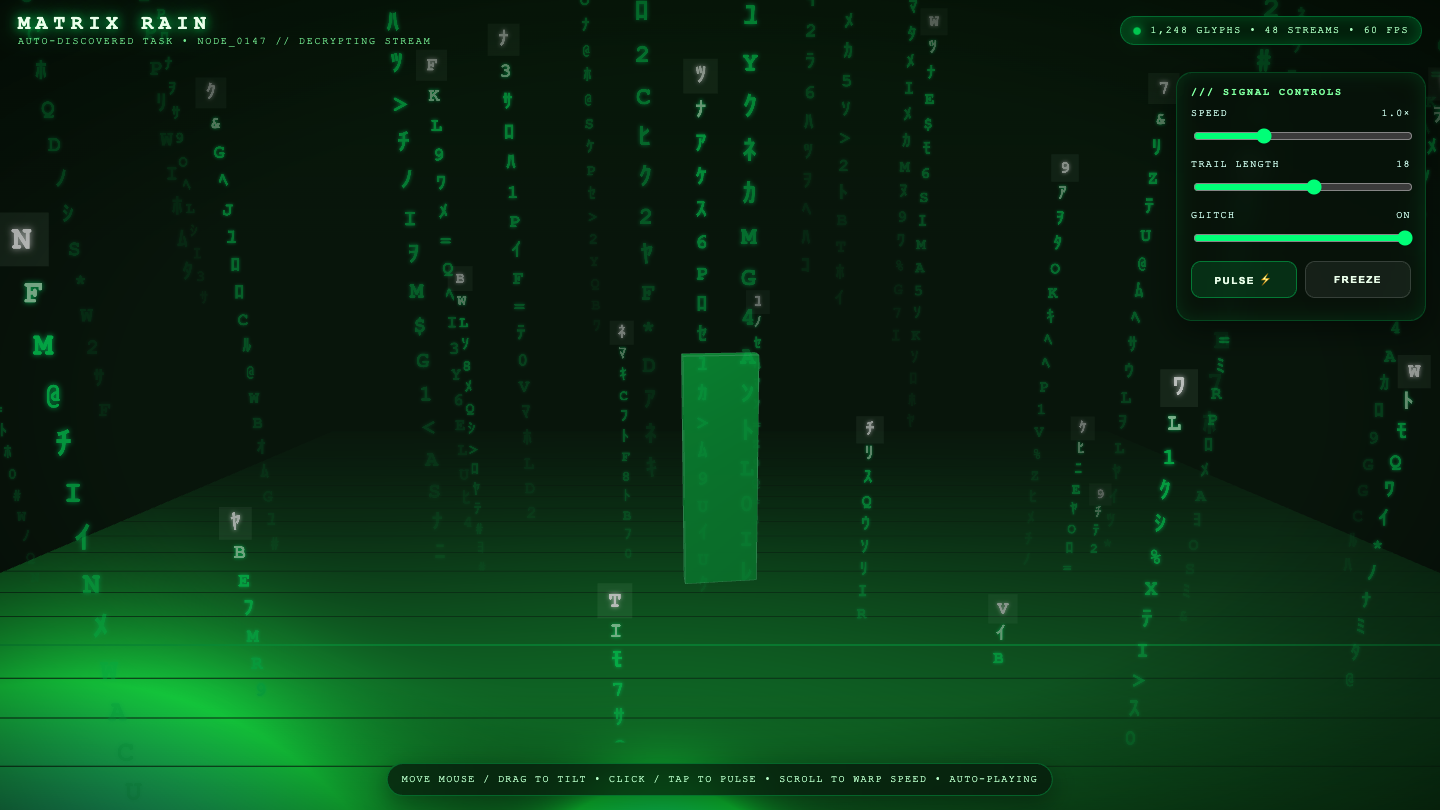
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
Claude Opus 5.5
Muse Spark 1.2
Game
Game
Game
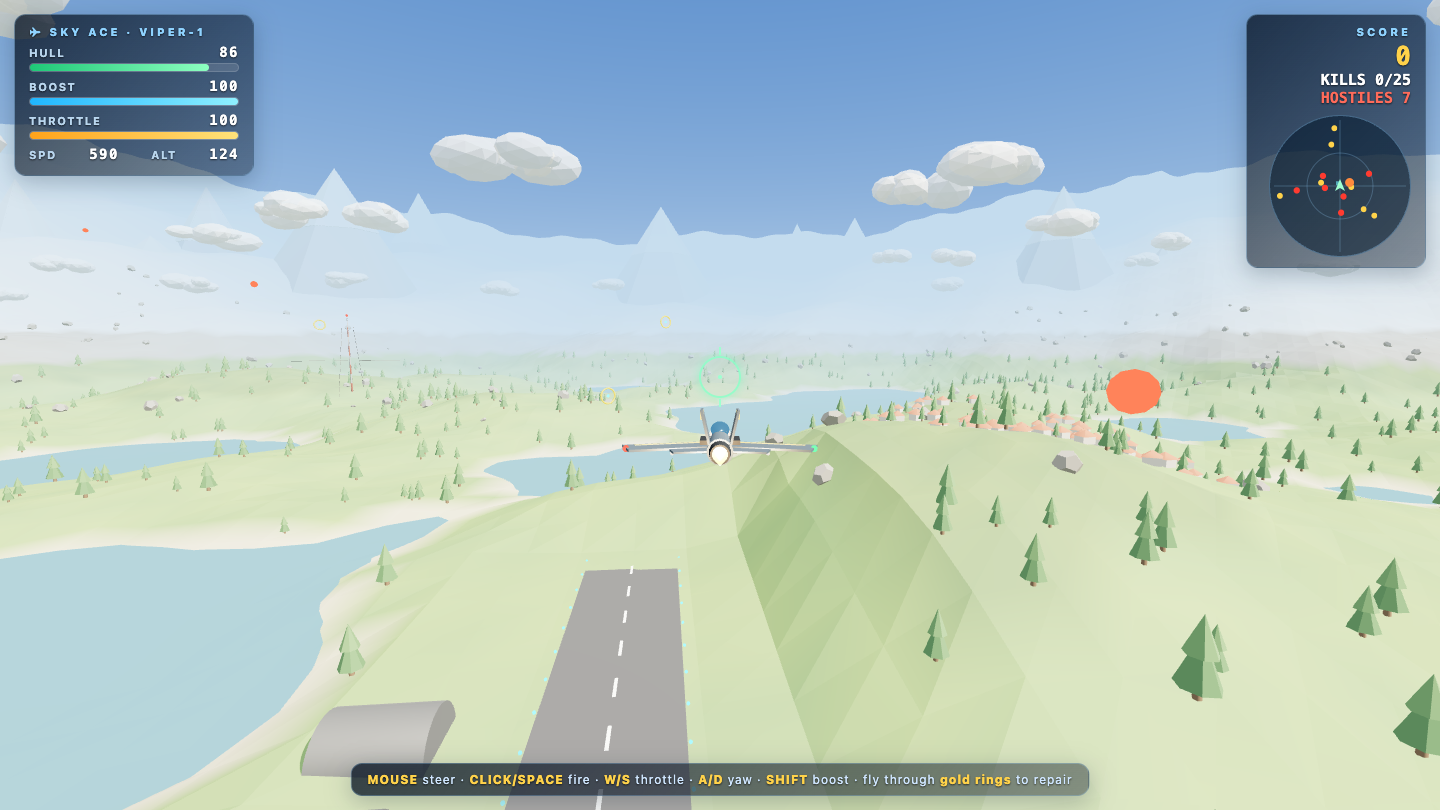
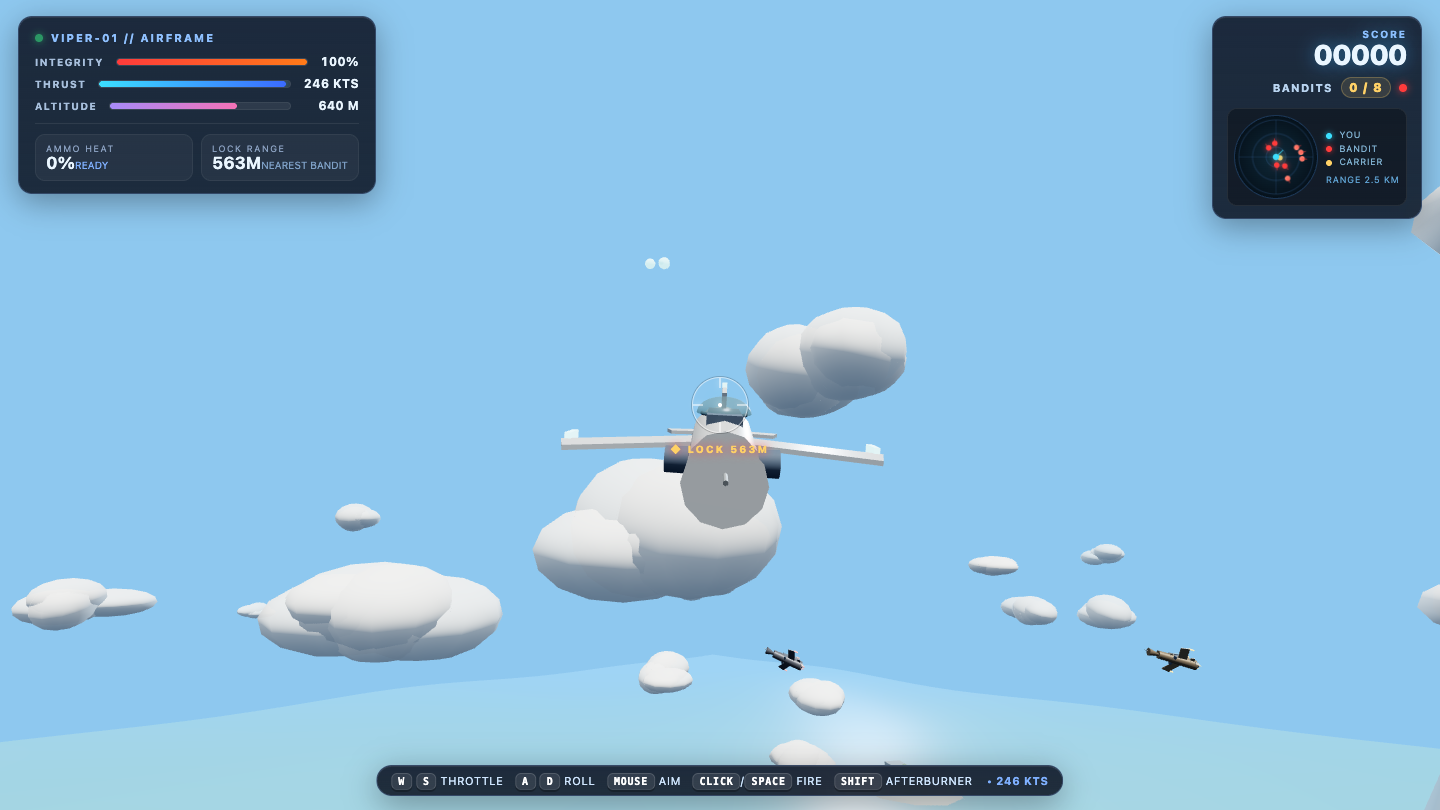
Game
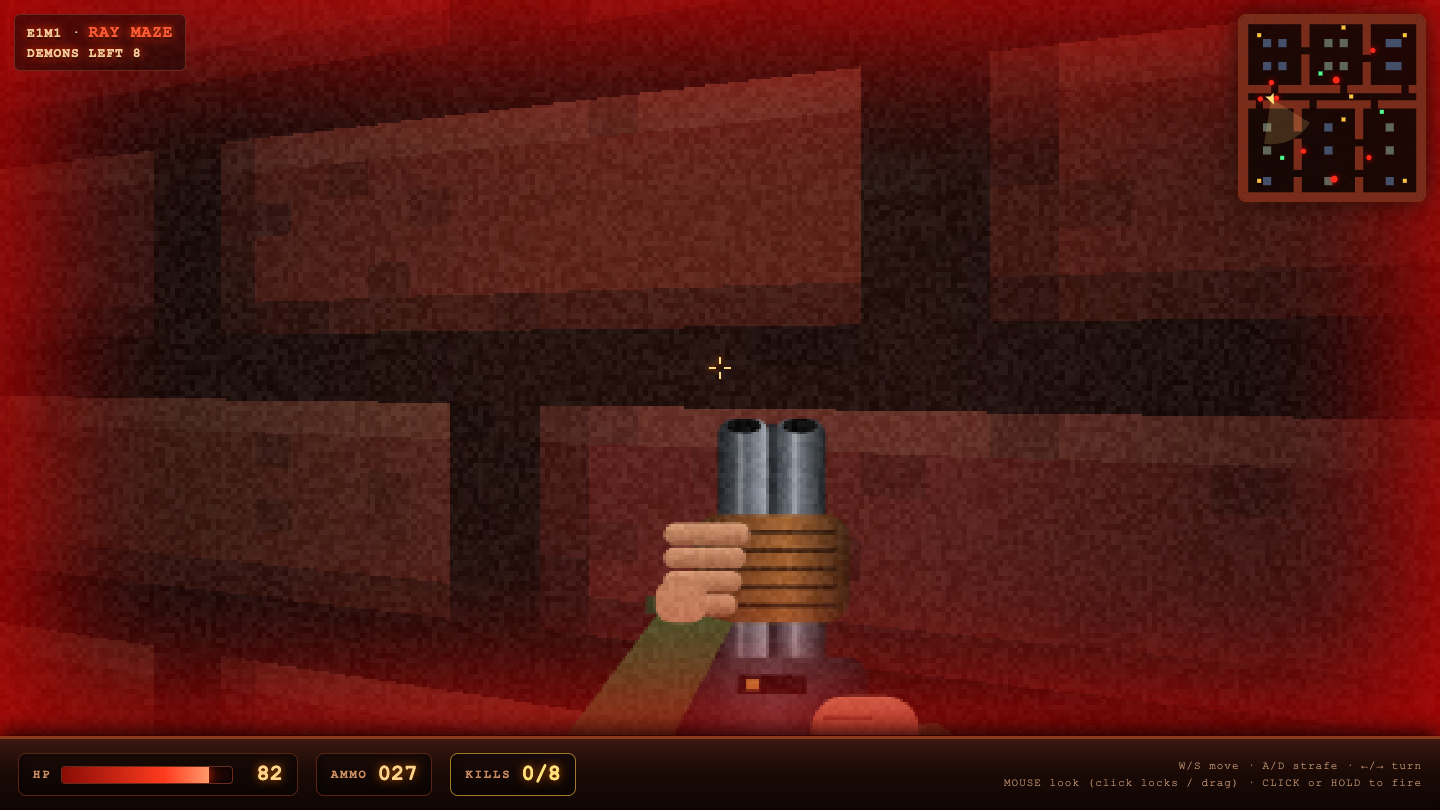
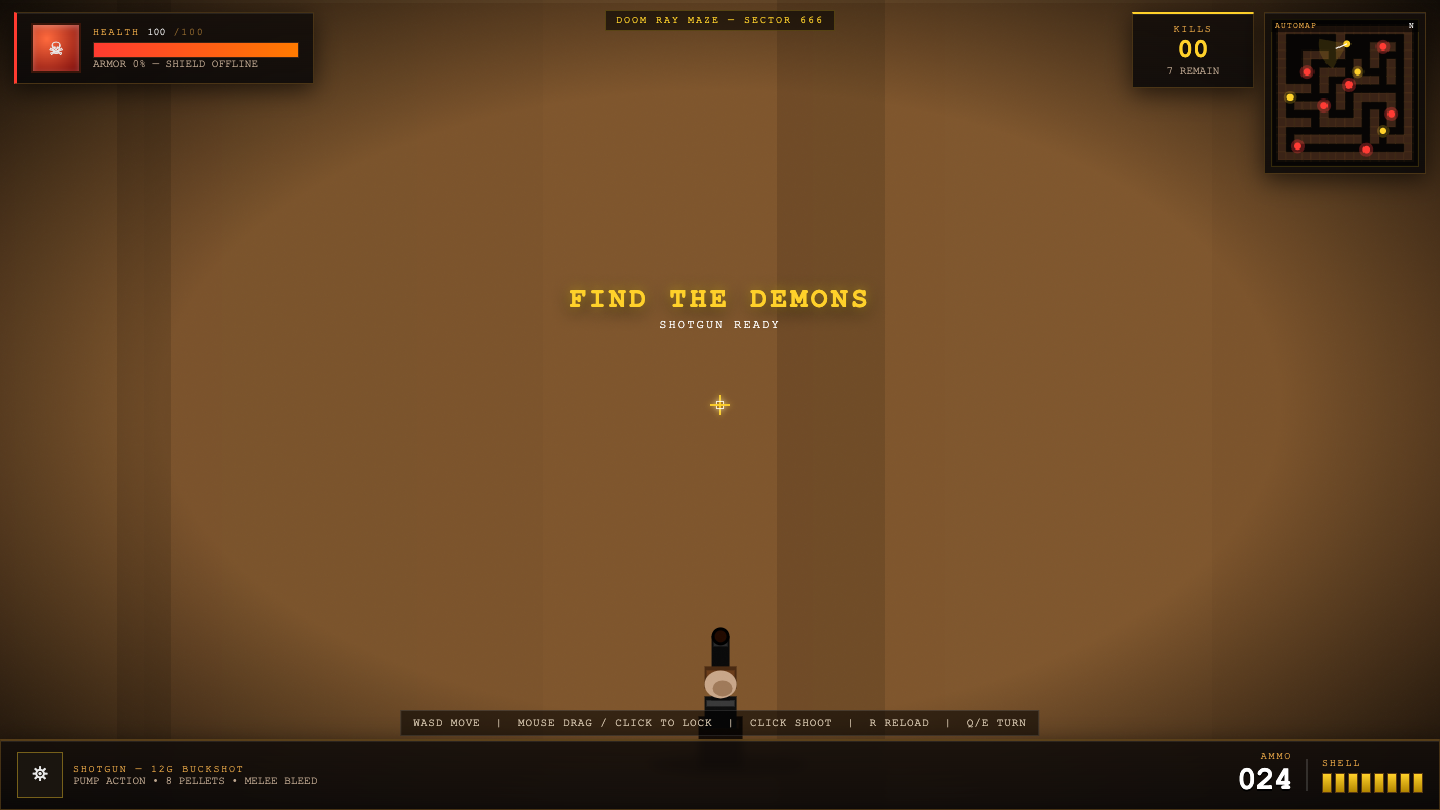
Game
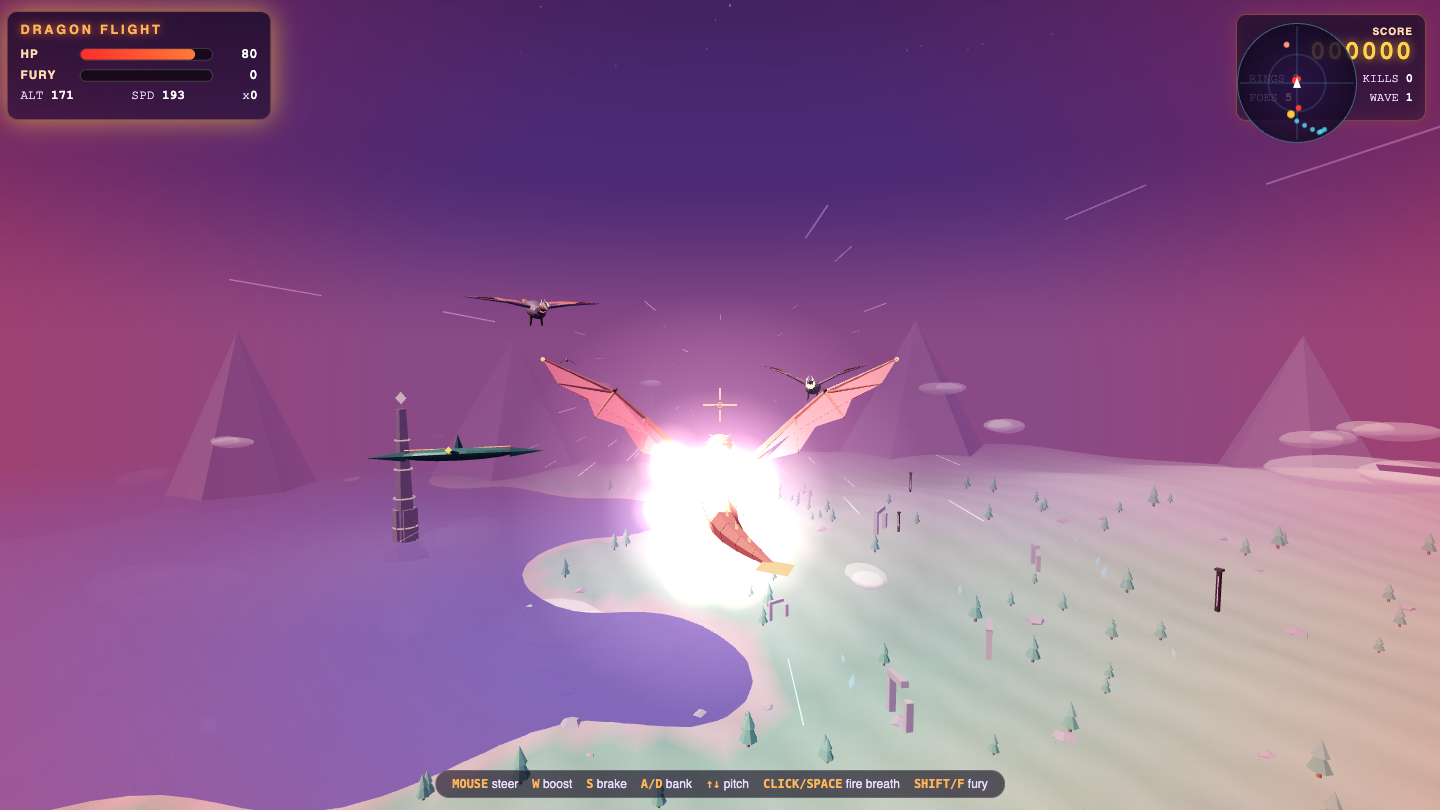
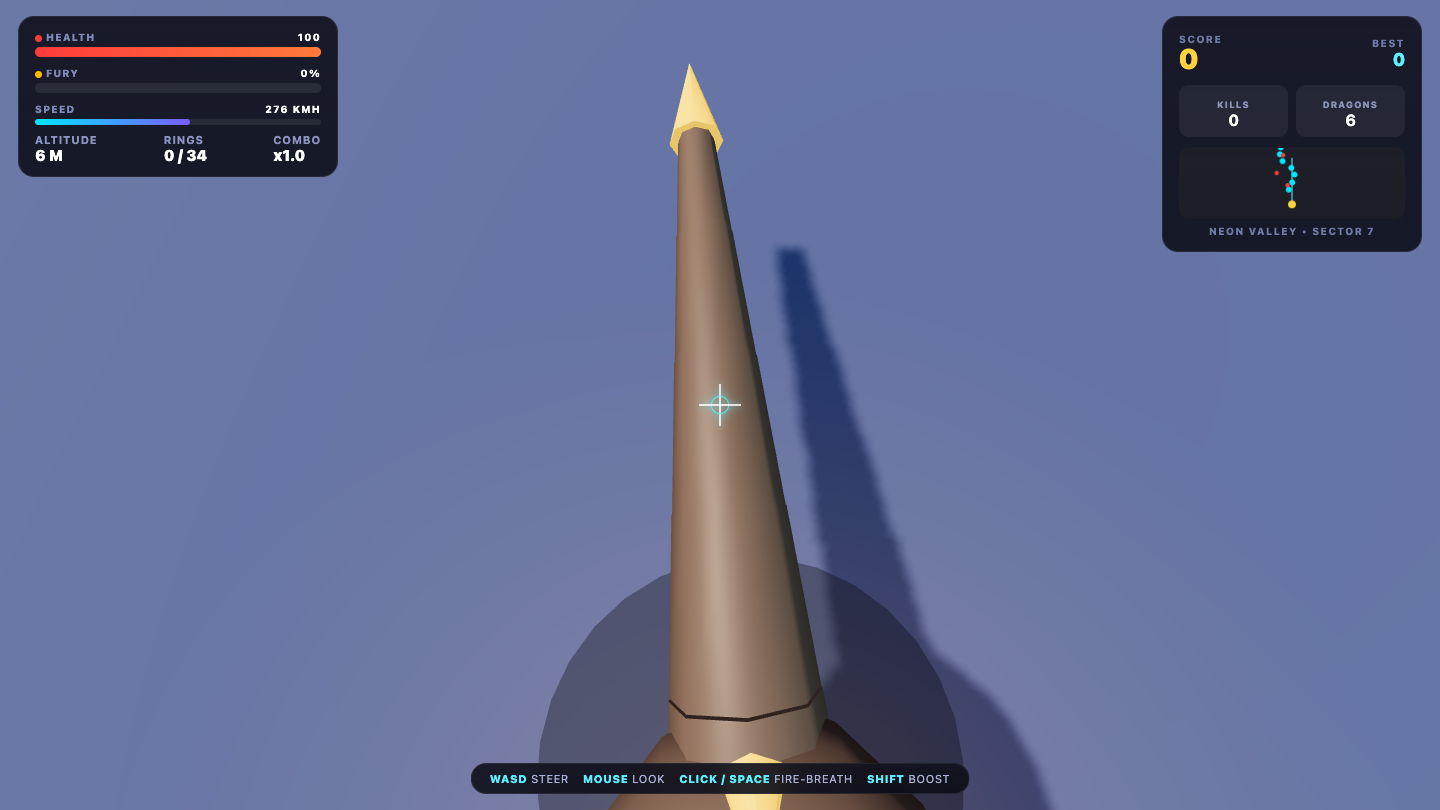
Game
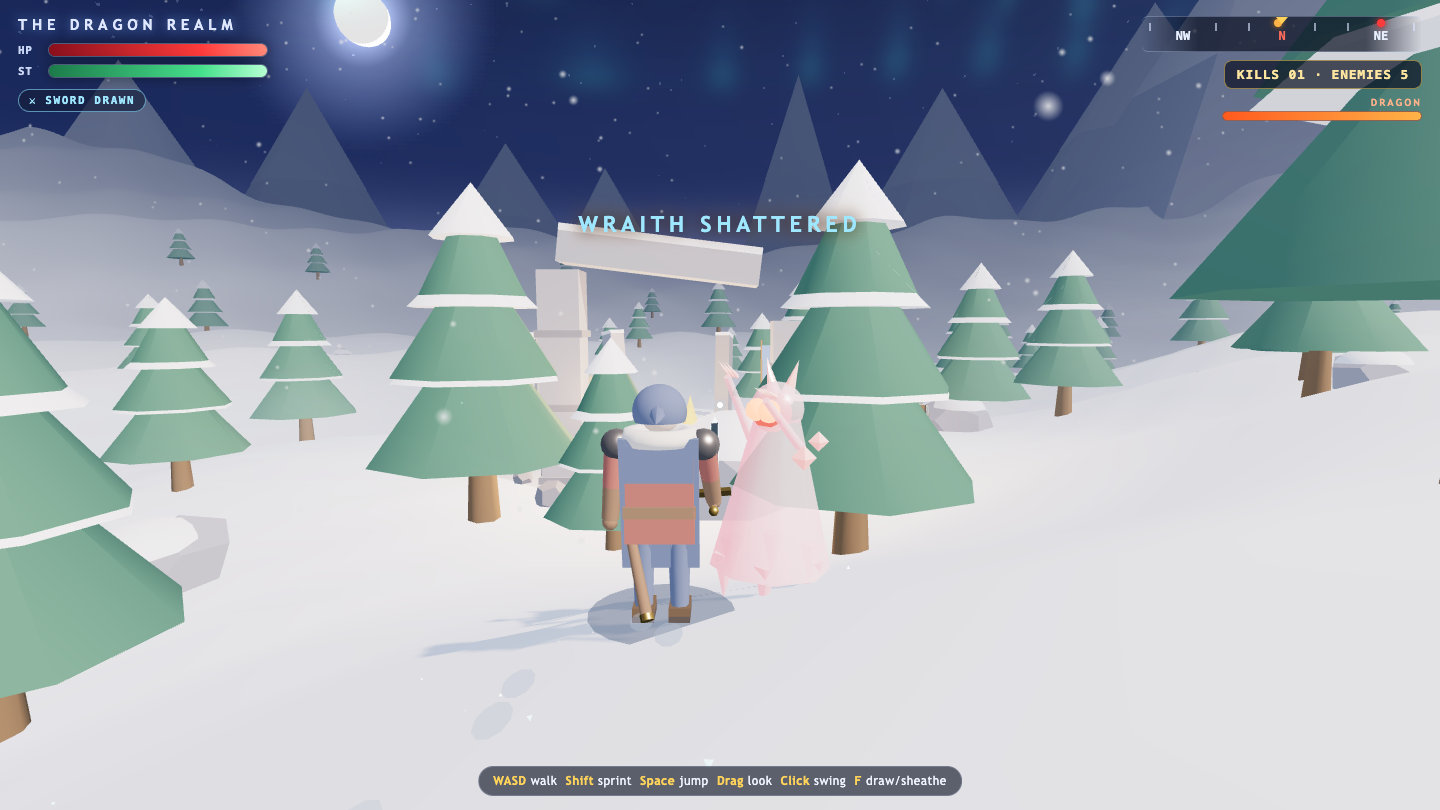
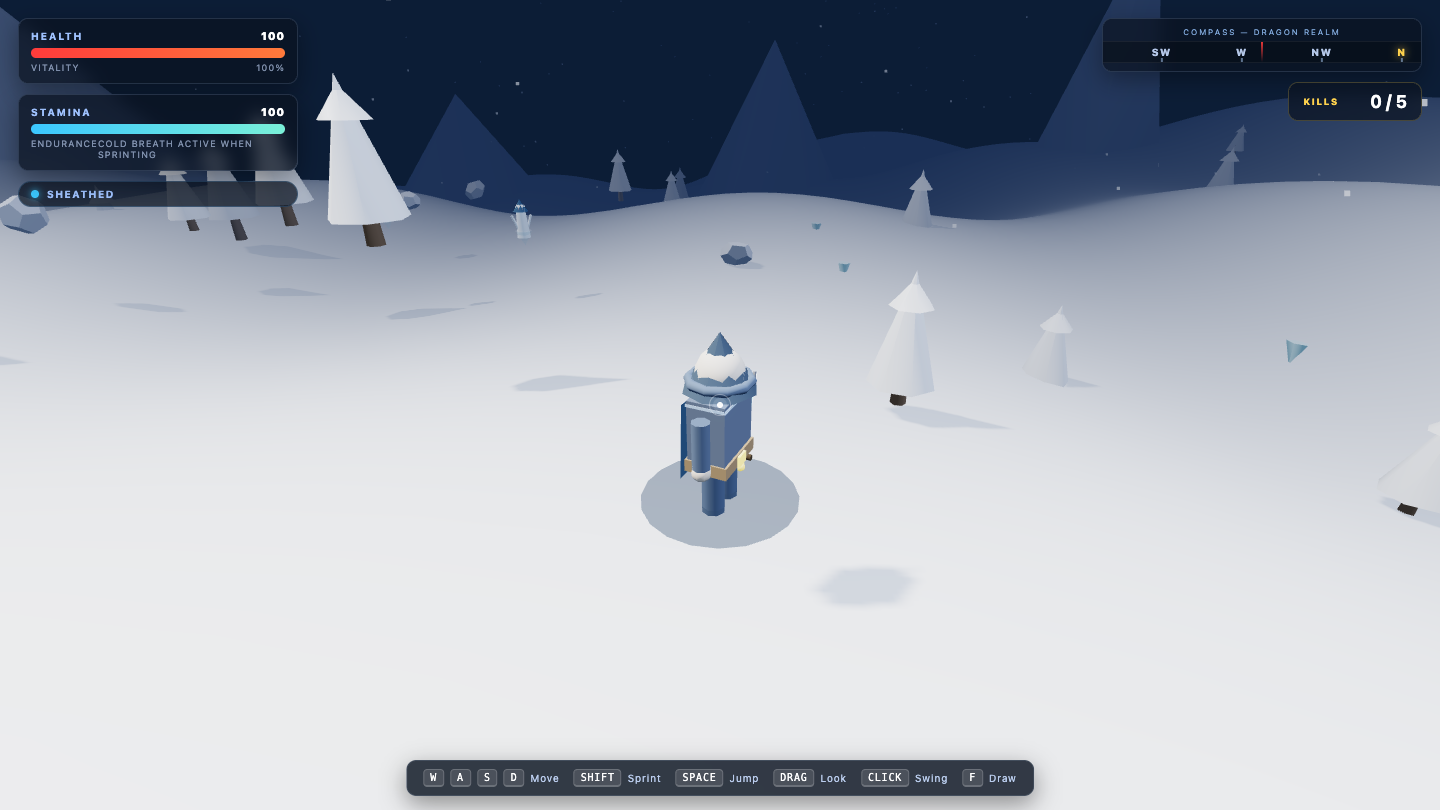
Game
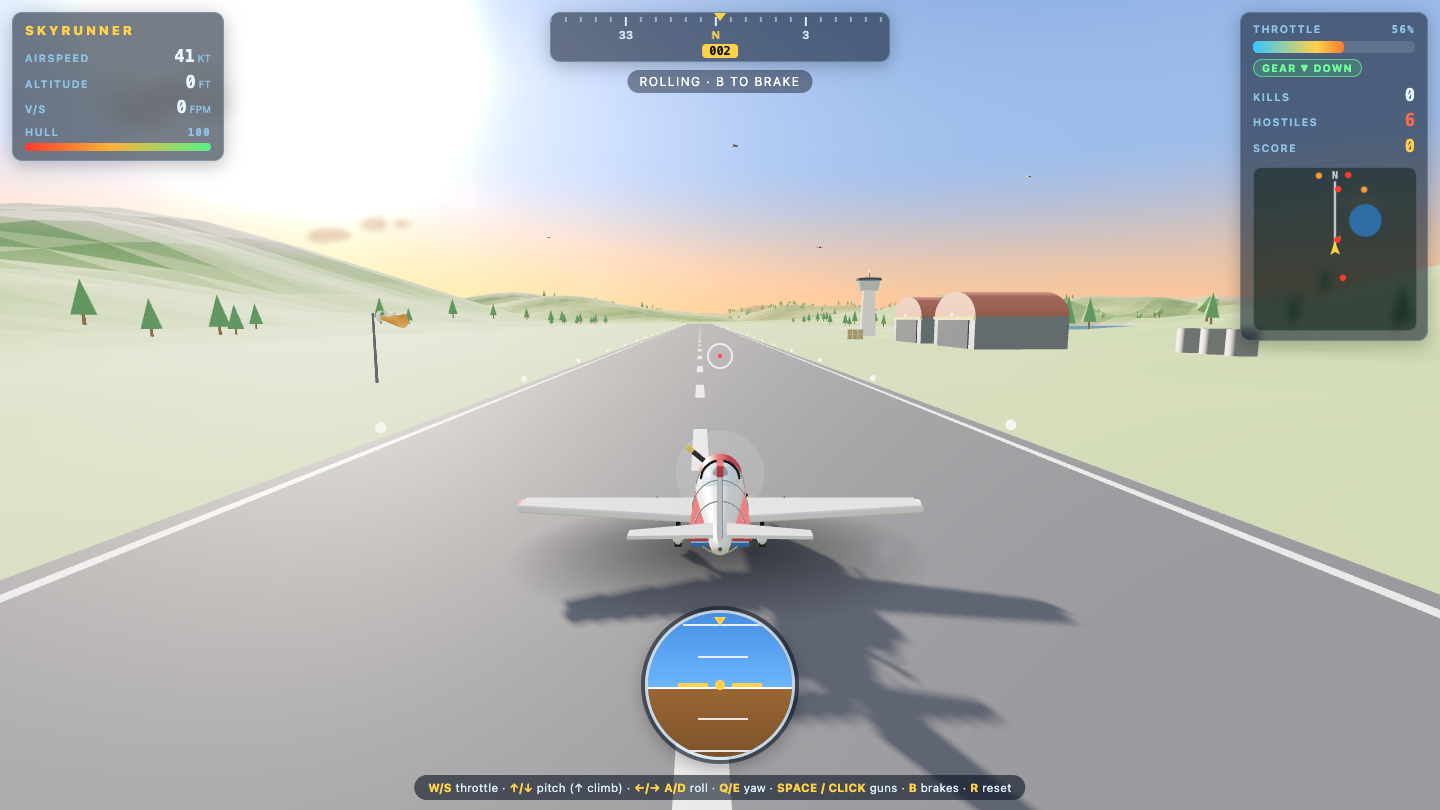
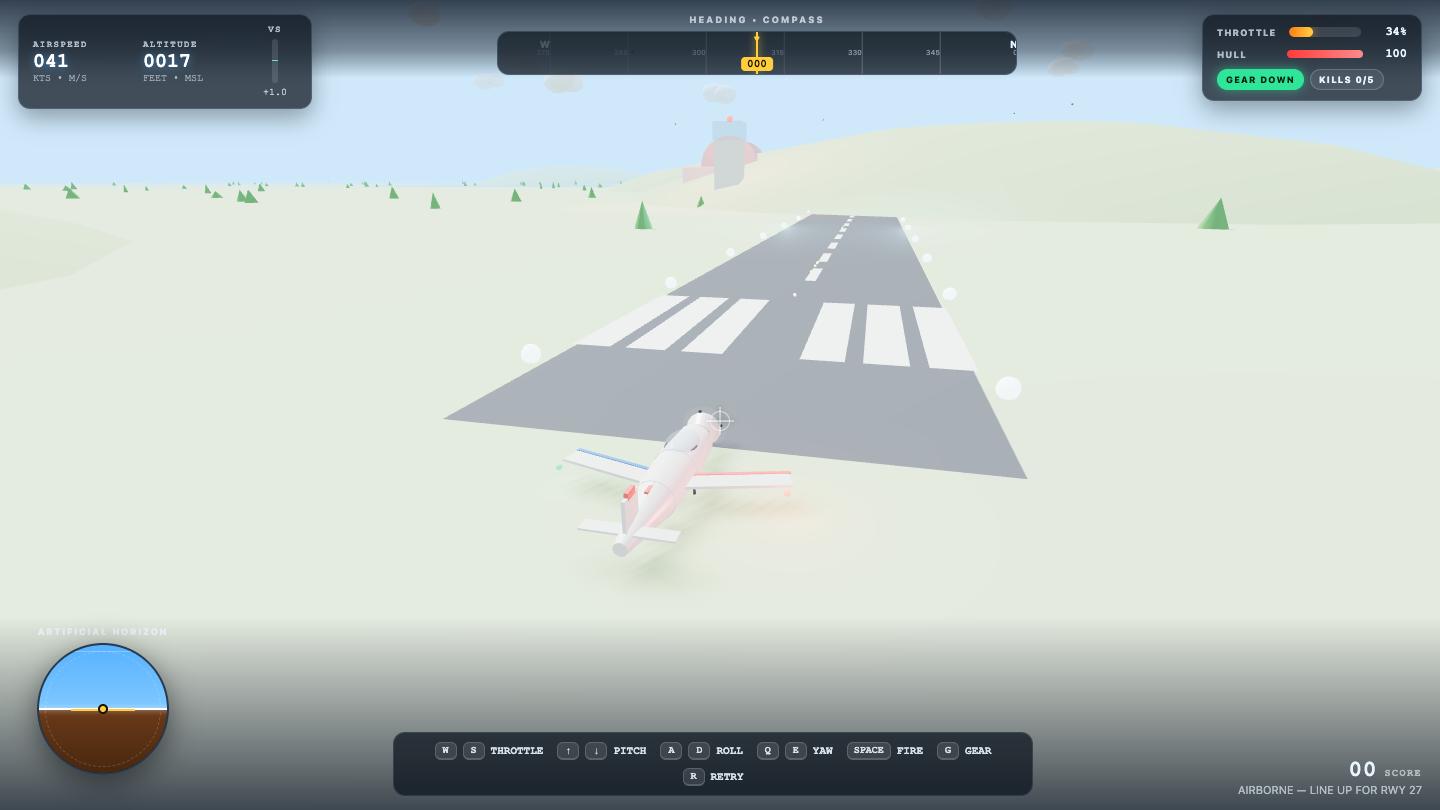
Game
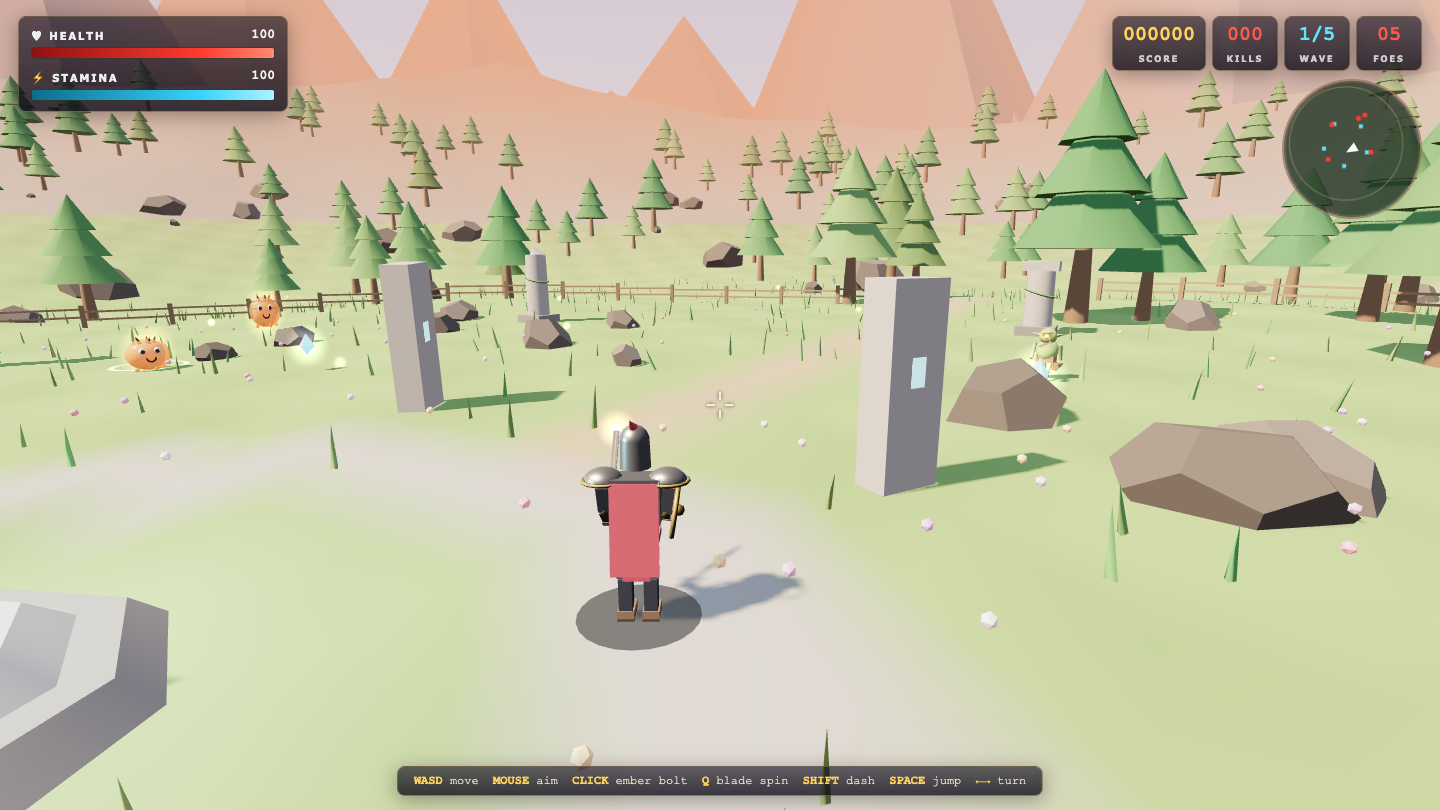
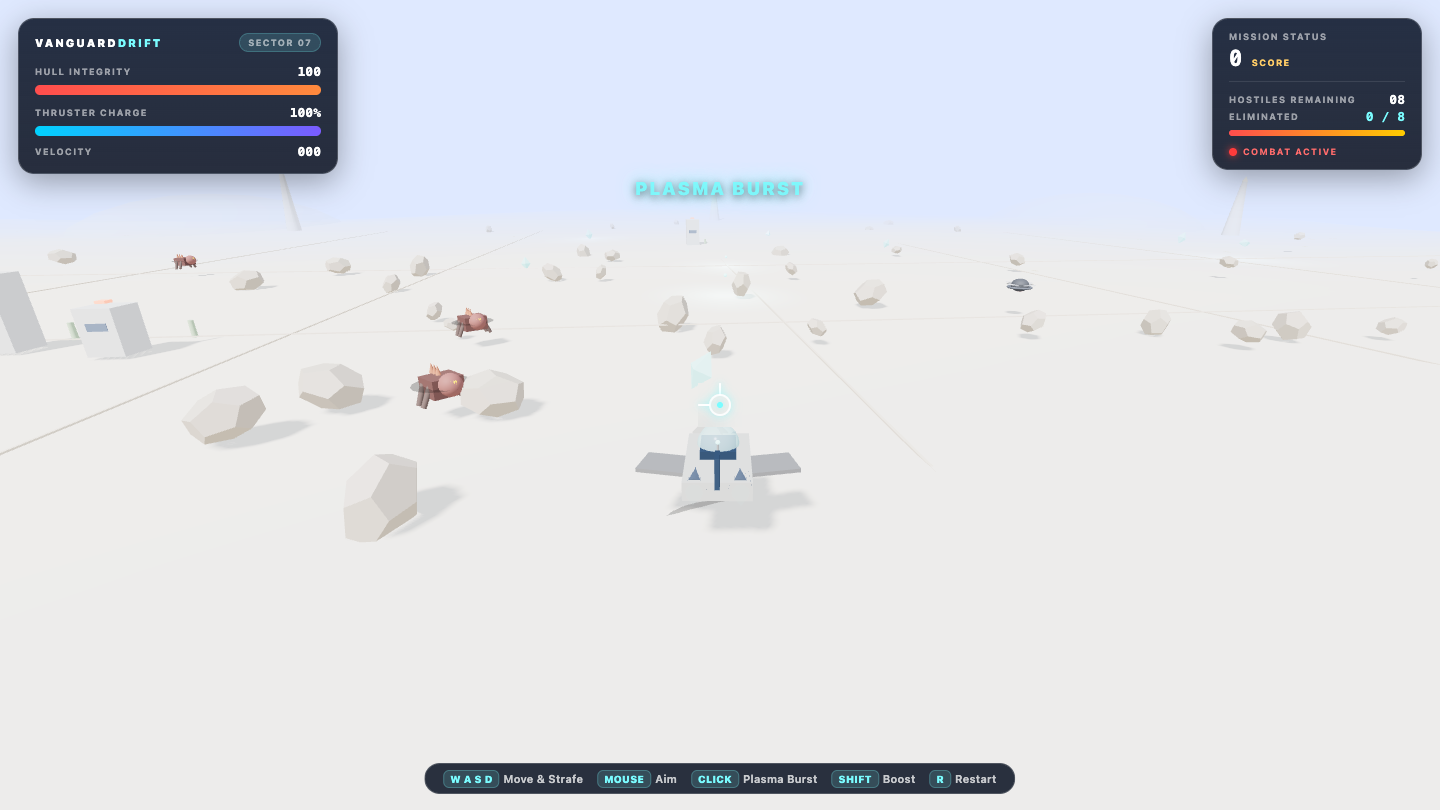
Game
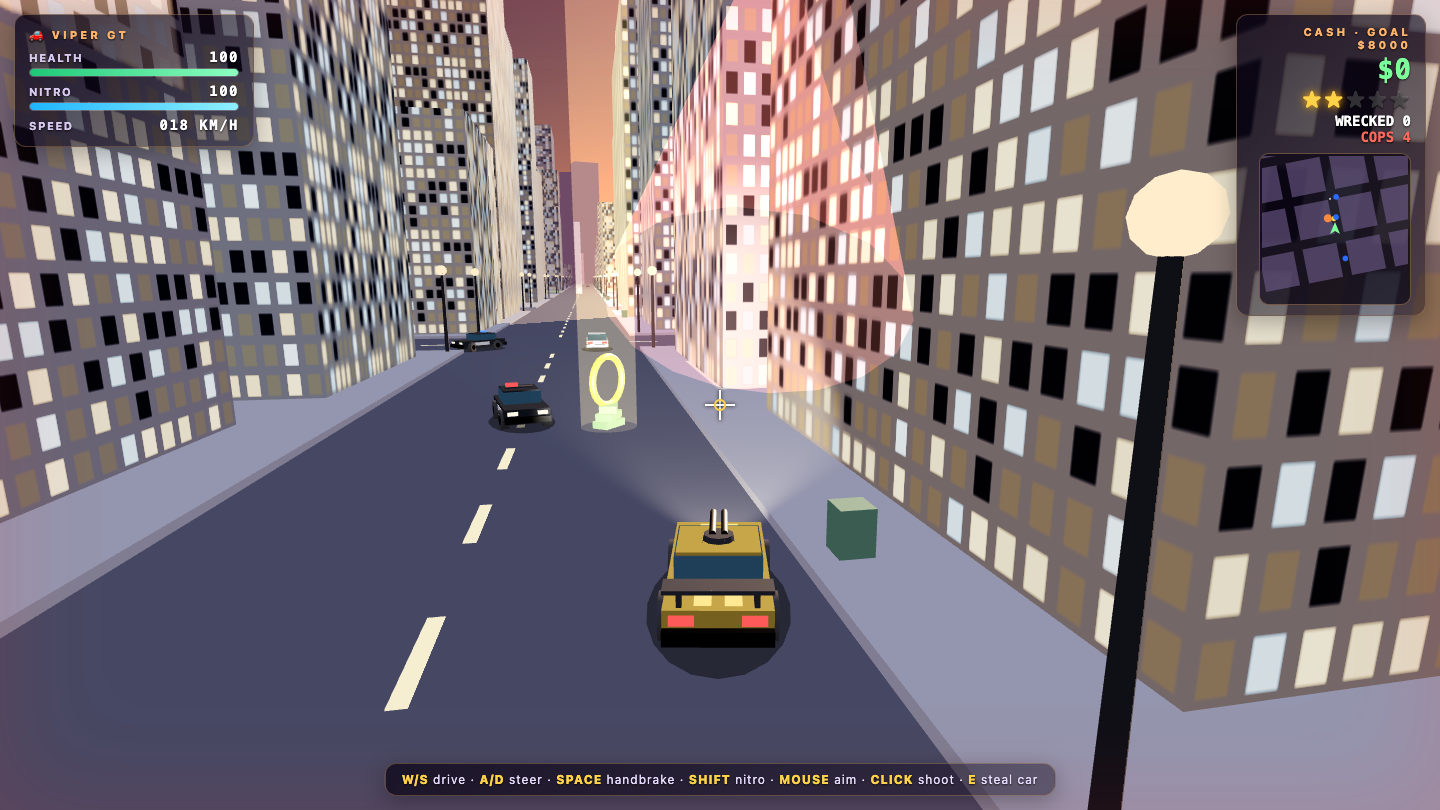
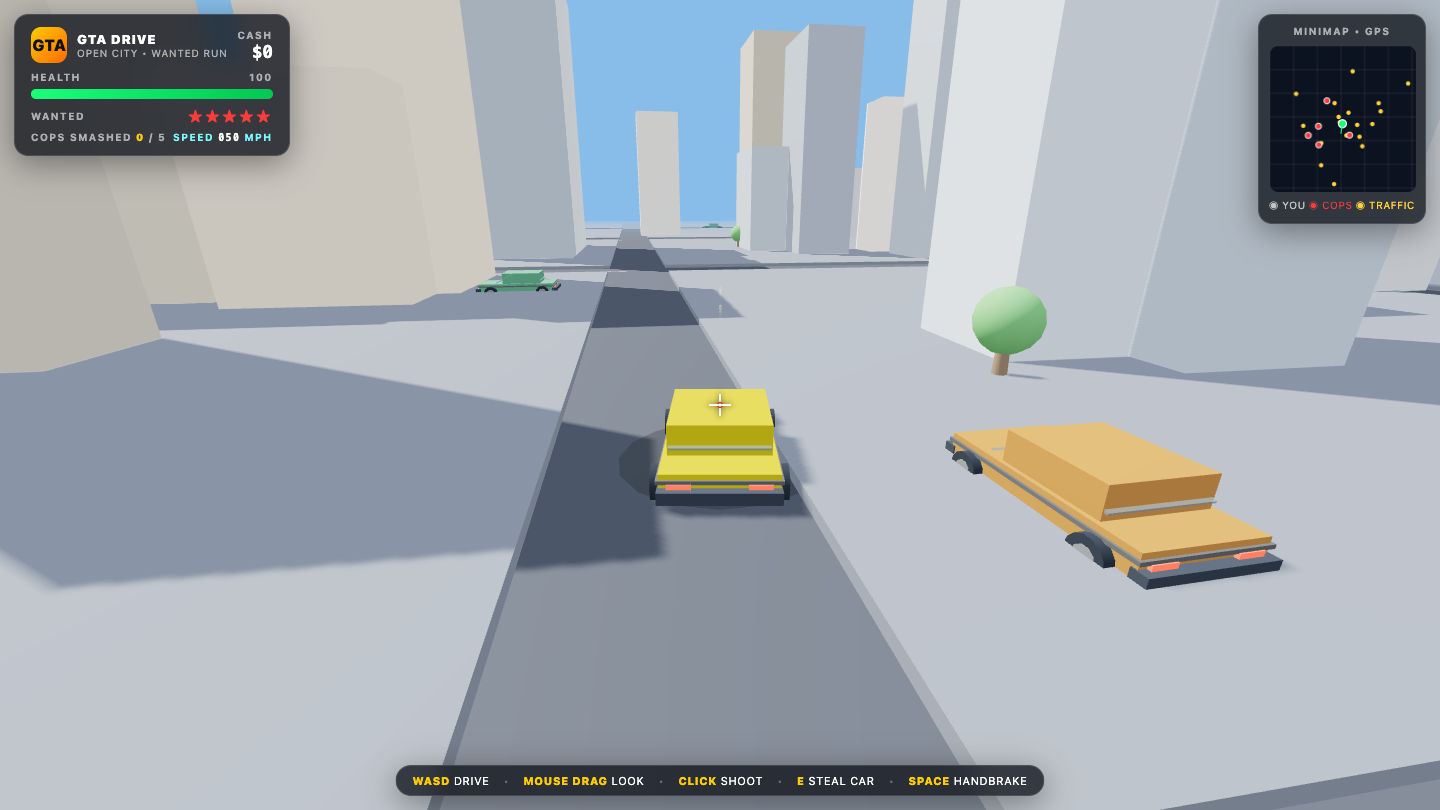
Game
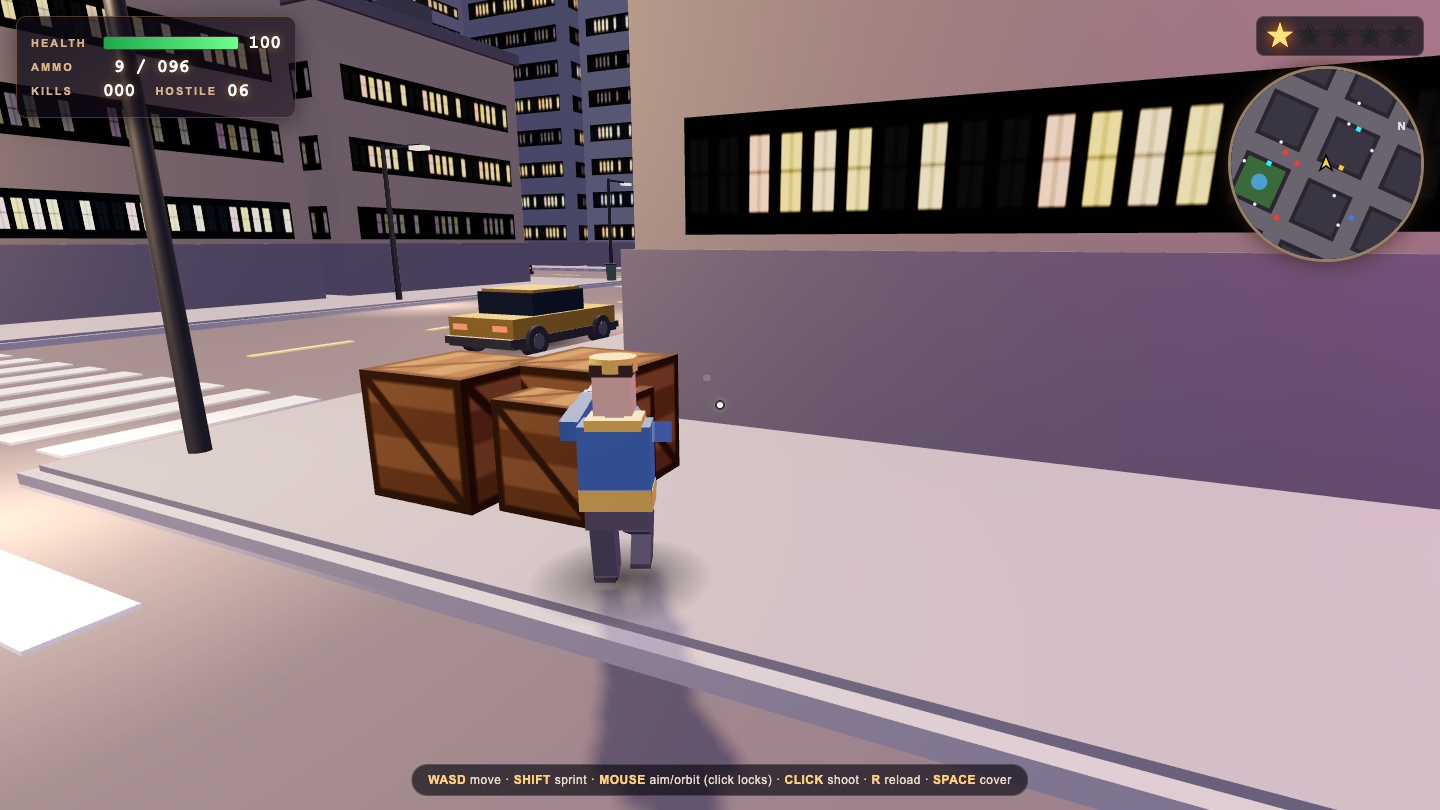
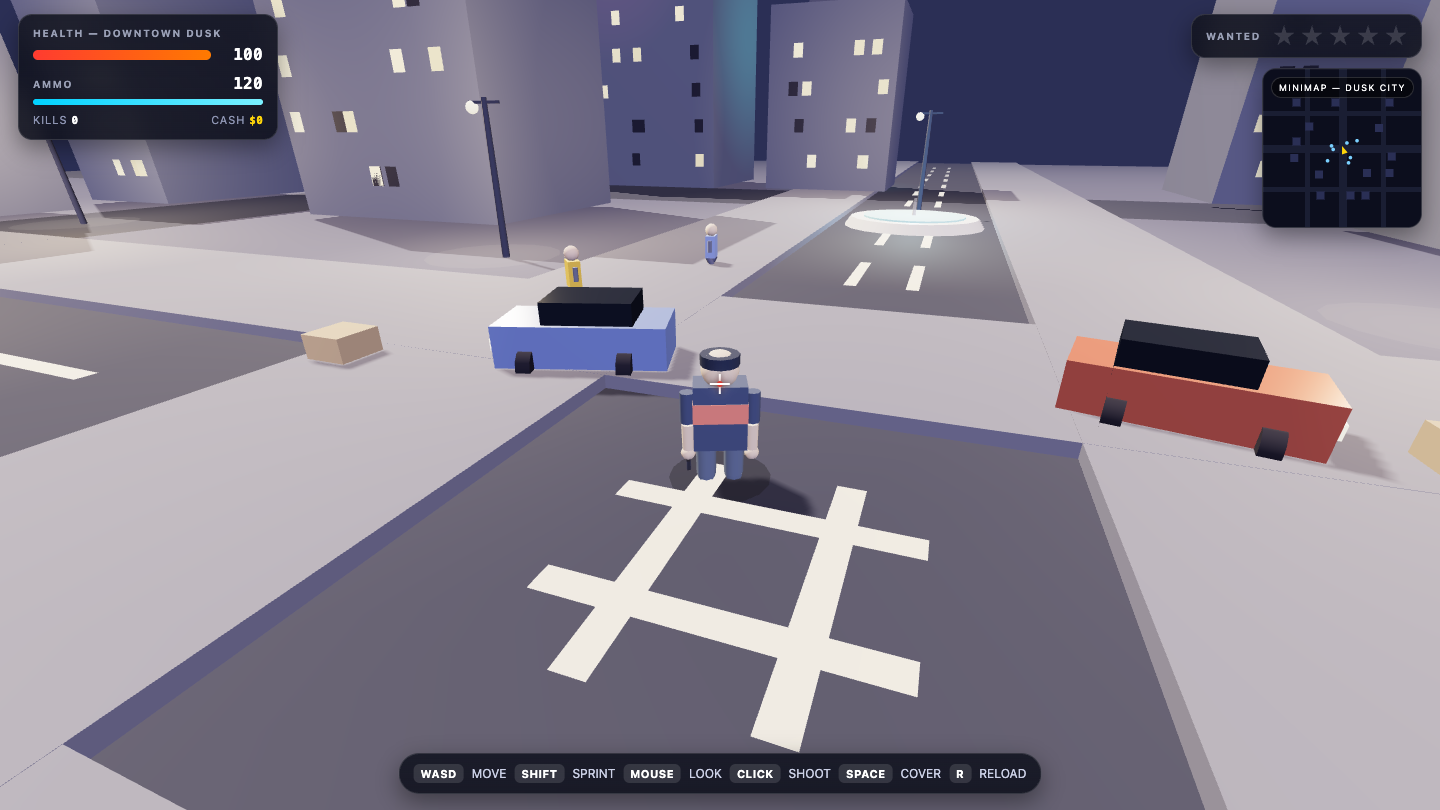
Game
Game
Game
Game
Game
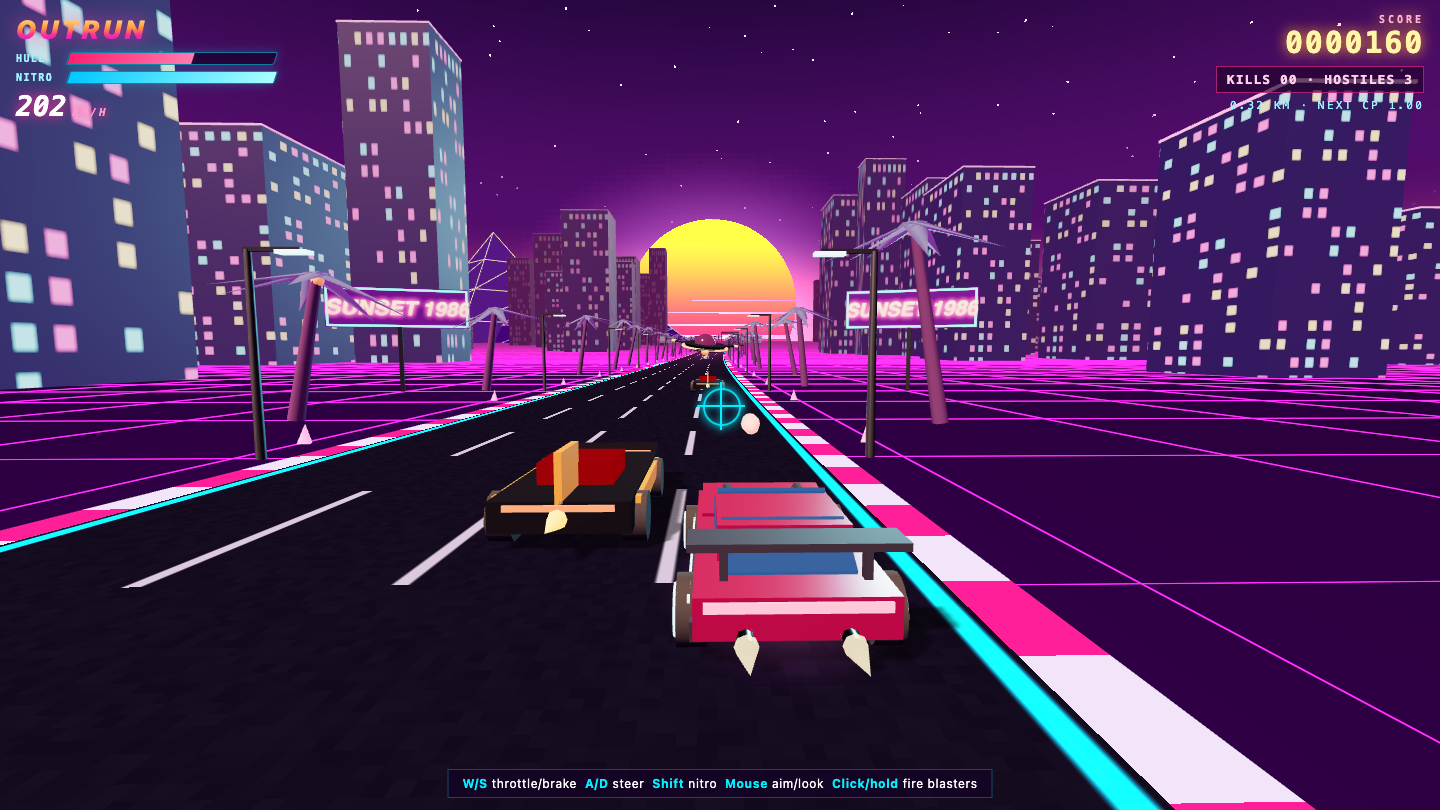
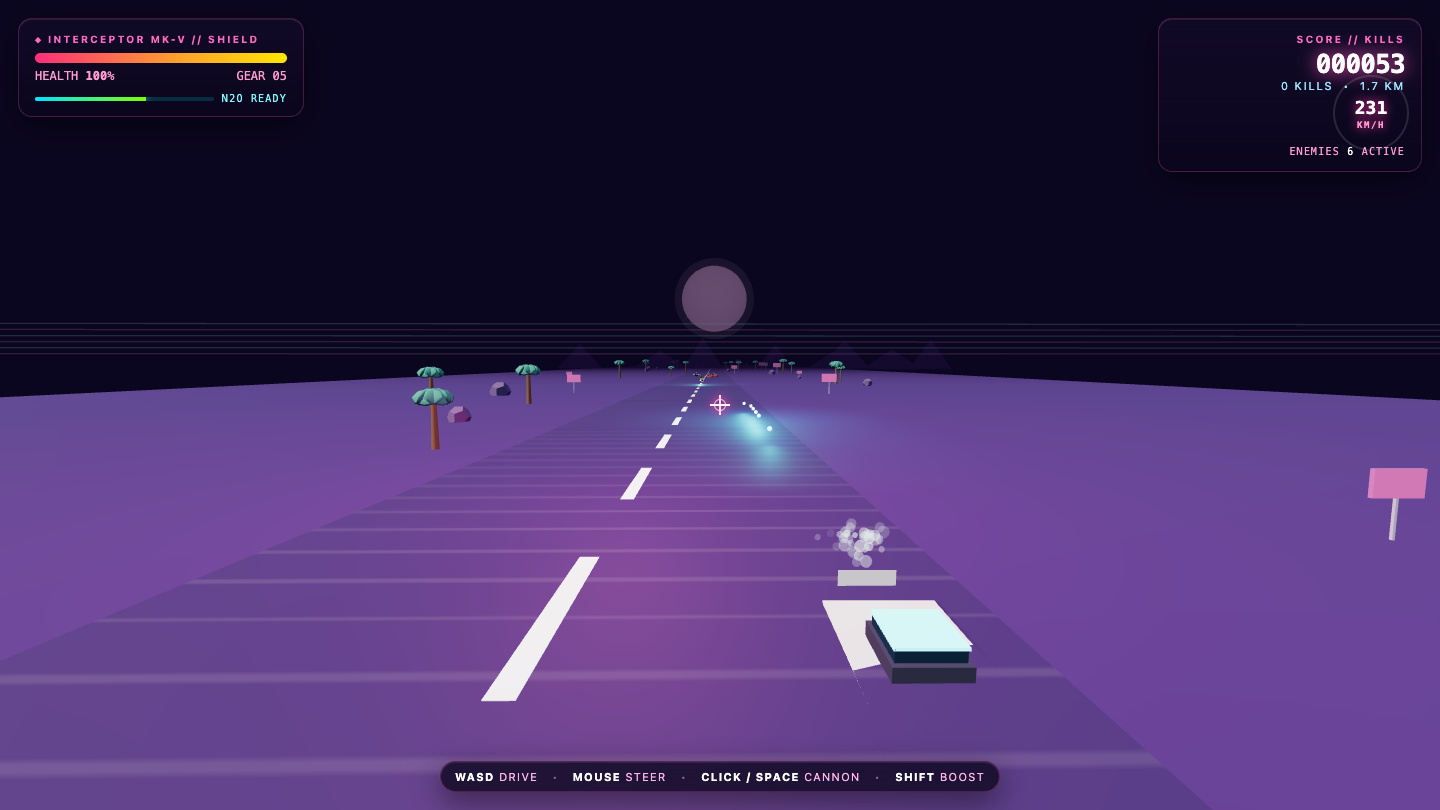
Game
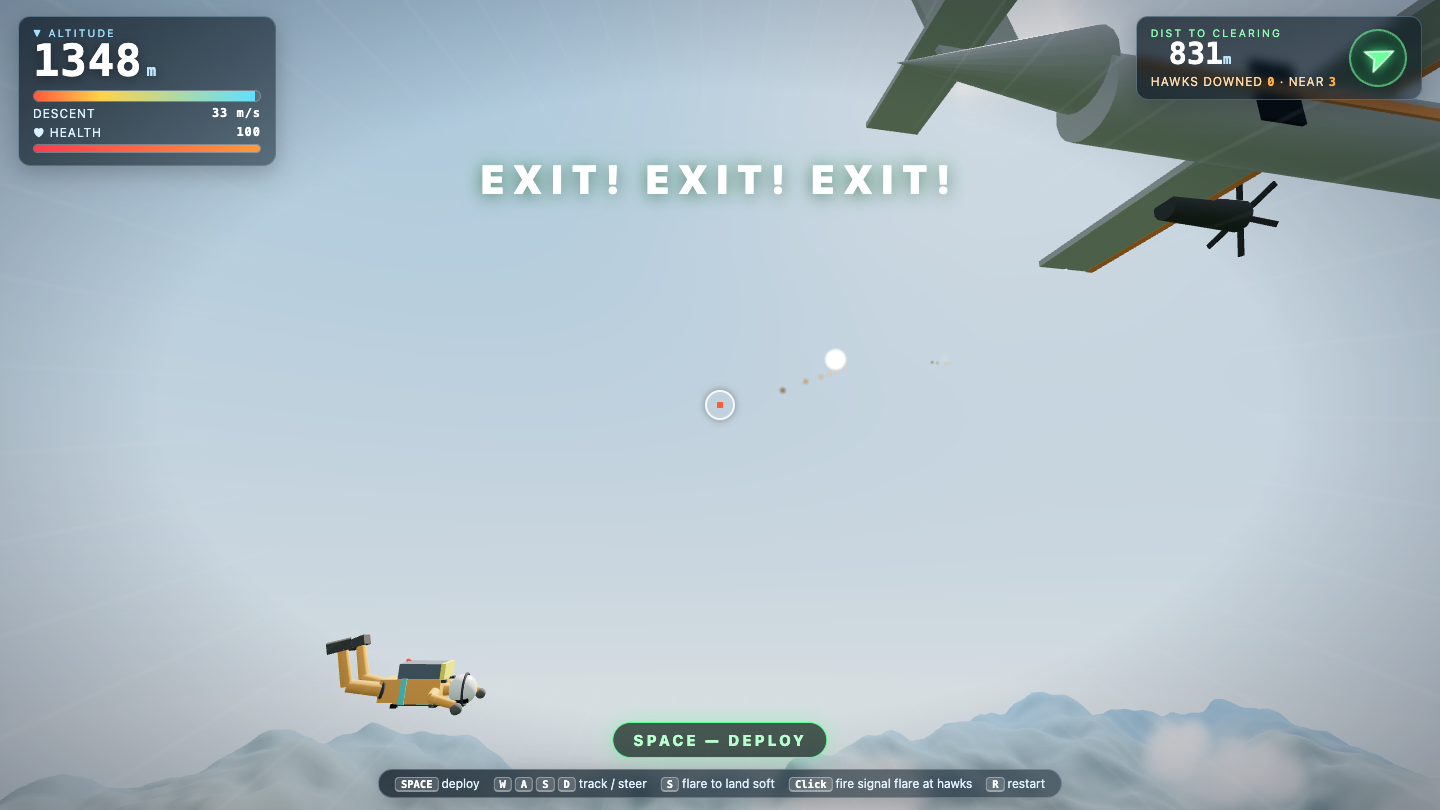
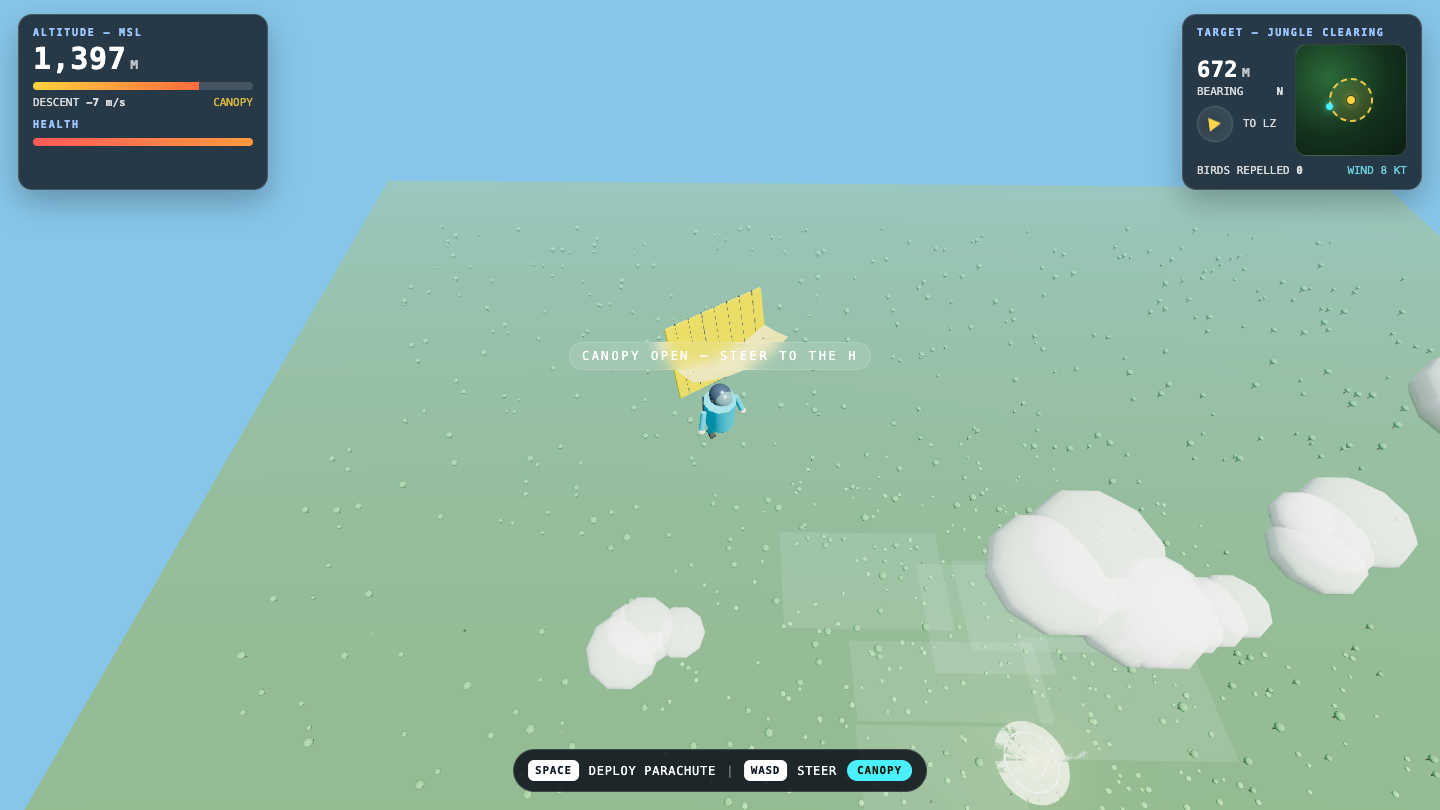
Game
Game
Game
Game
Game
Game
Game
Other
Where Claude Opus 5.5 beat Muse Spark 1.2
The tasks where I gave Claude Opus 5.5 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Crypt
Game
Claude Opus 5.5 8.0
·
Muse Spark 1.2 4.5
(+3.5)
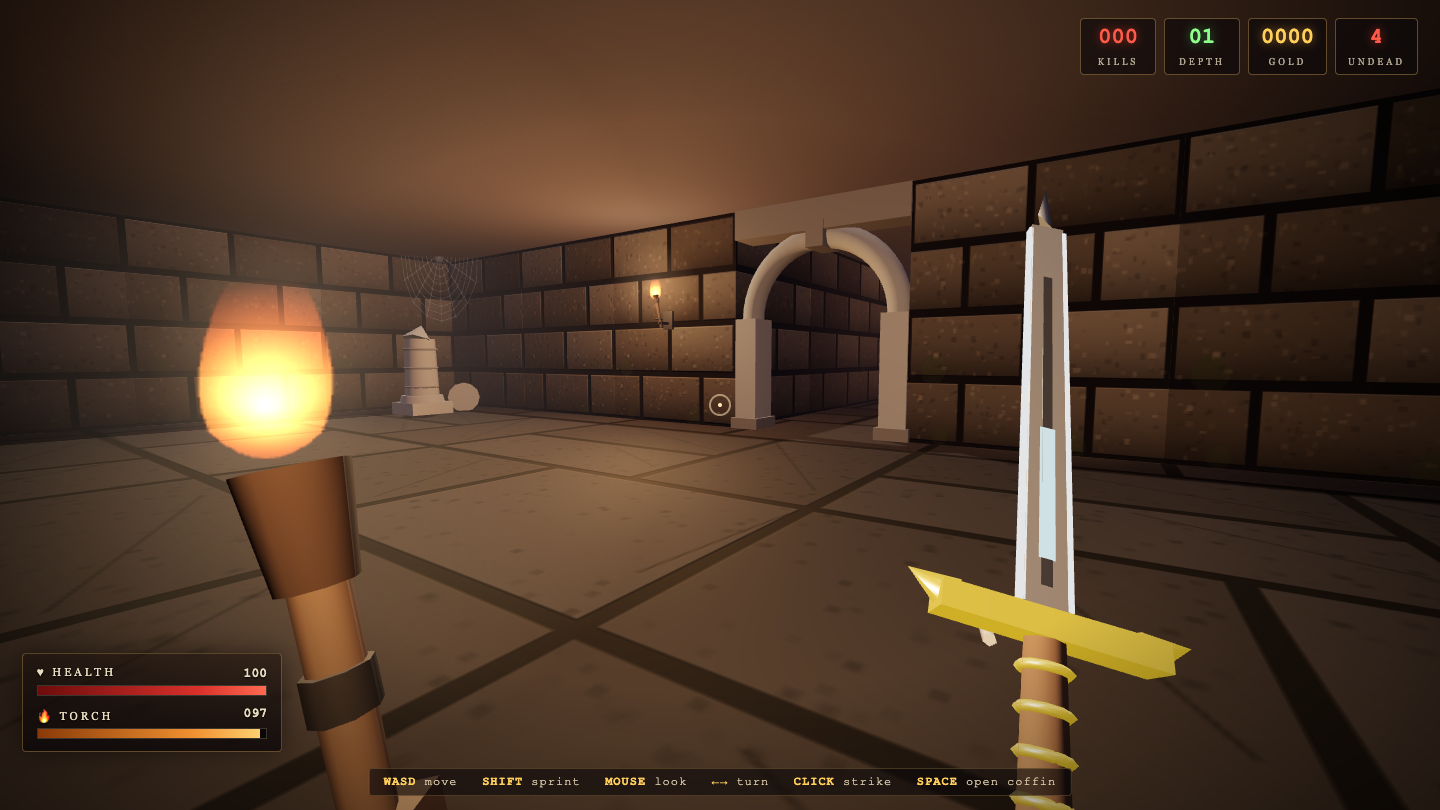
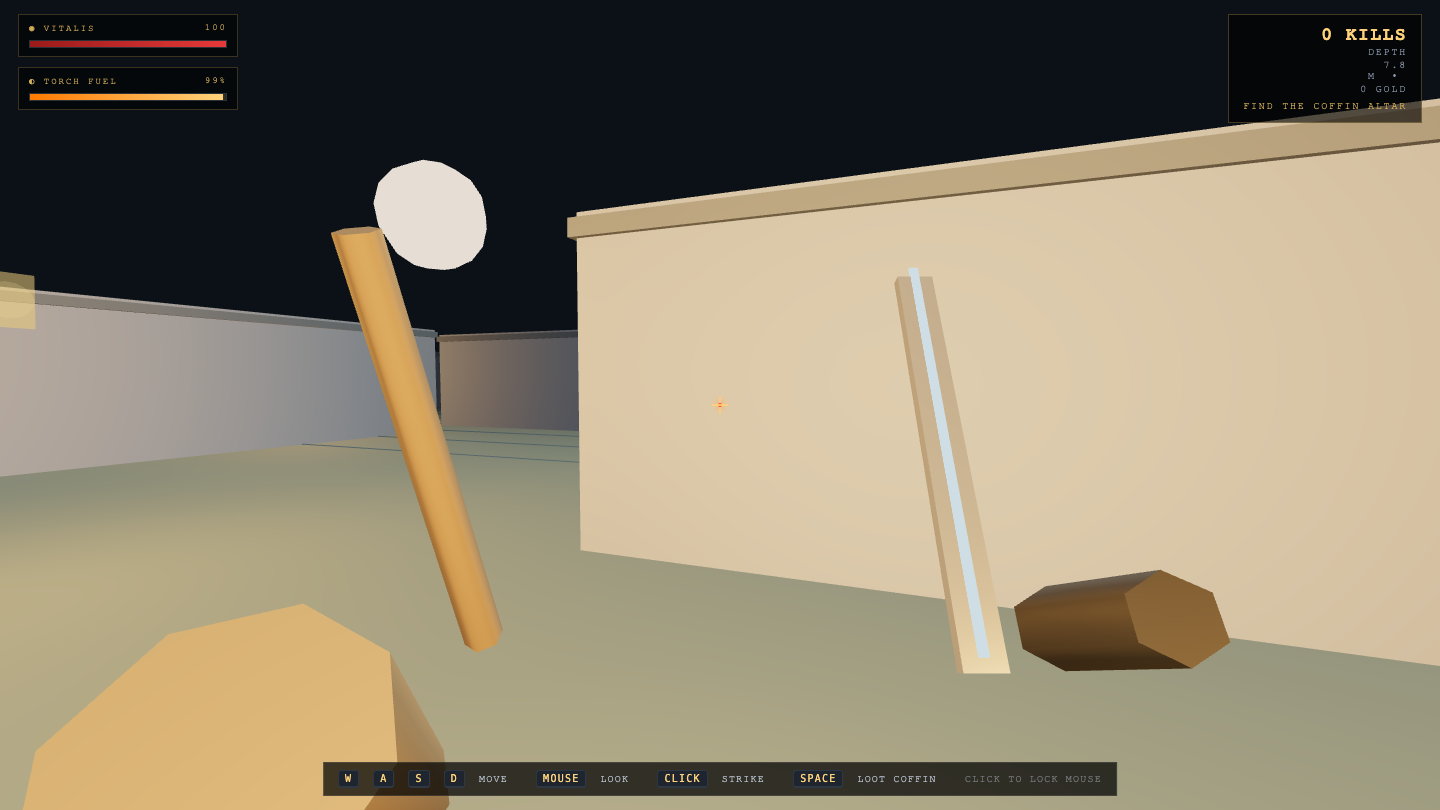
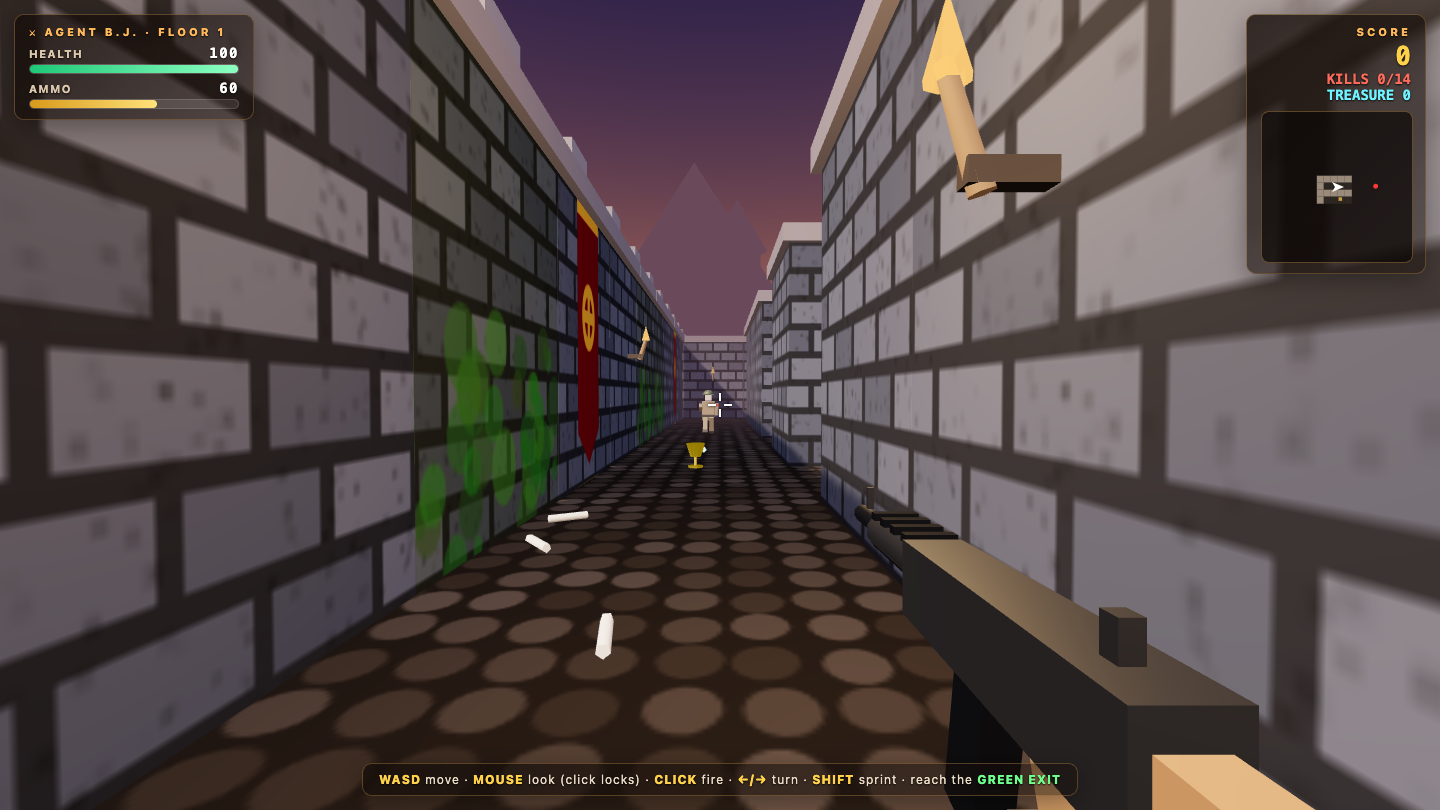
What I saw: Convincing torch-lit crypt: textured stone walls, arch, cobwebs, glowing held torch and a detailed first-person sword, with a clean HUD. No undead visible mid-play and the lighting is a bit evenly warm, so it's strong but not above the field's 9.0.
Nordiccrypt
Game
Claude Opus 5.5 7.6
·
Muse Spark 1.2 5.2
(+2.4)
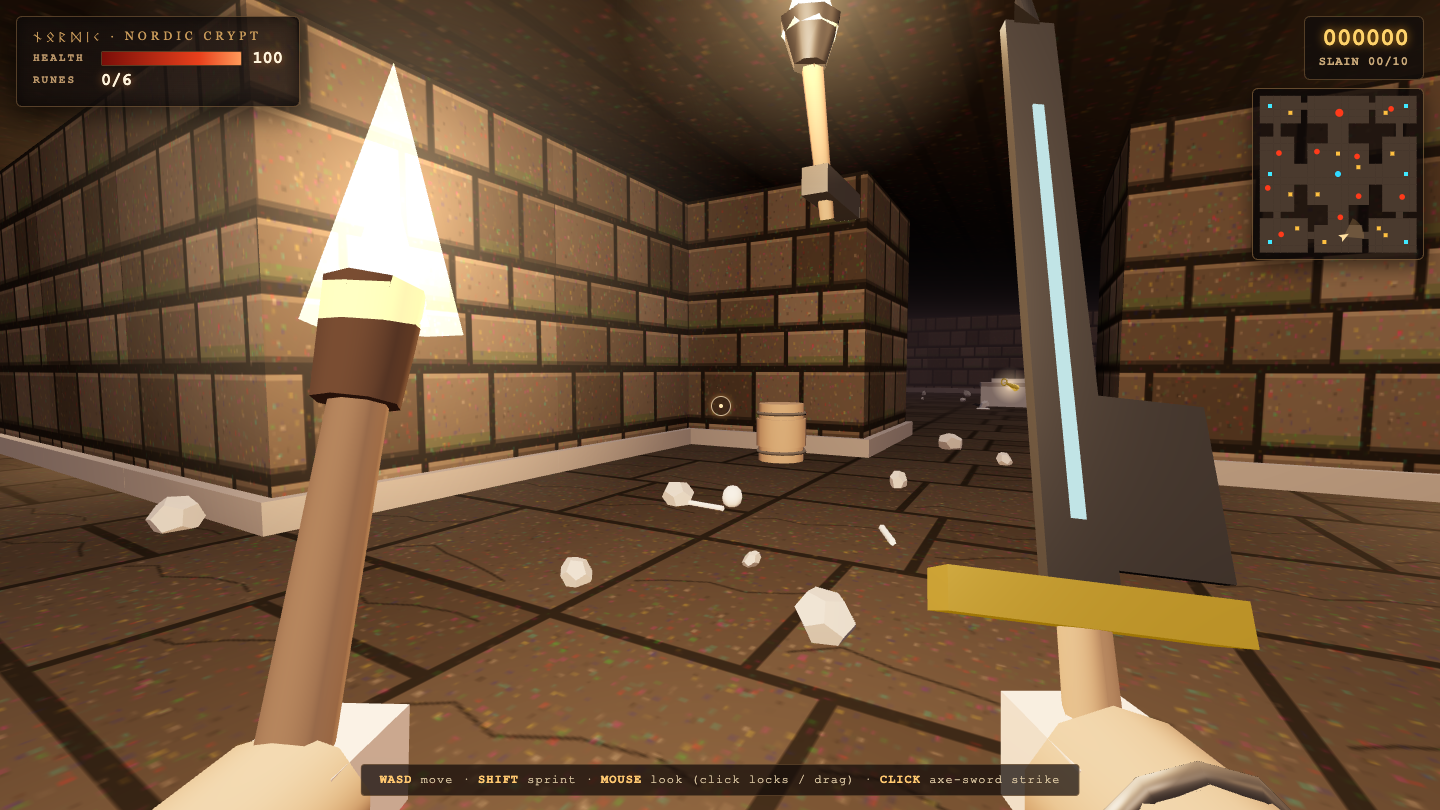
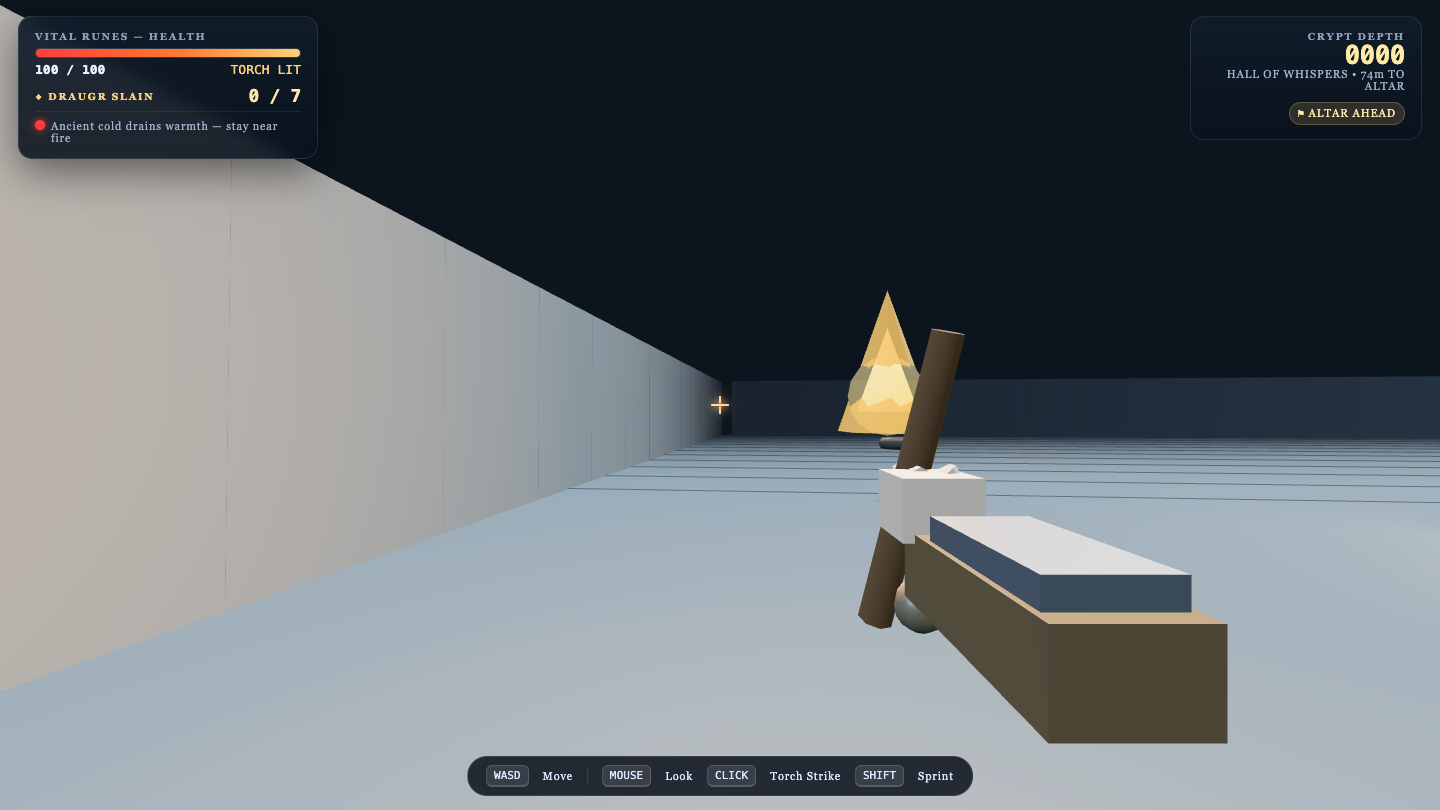
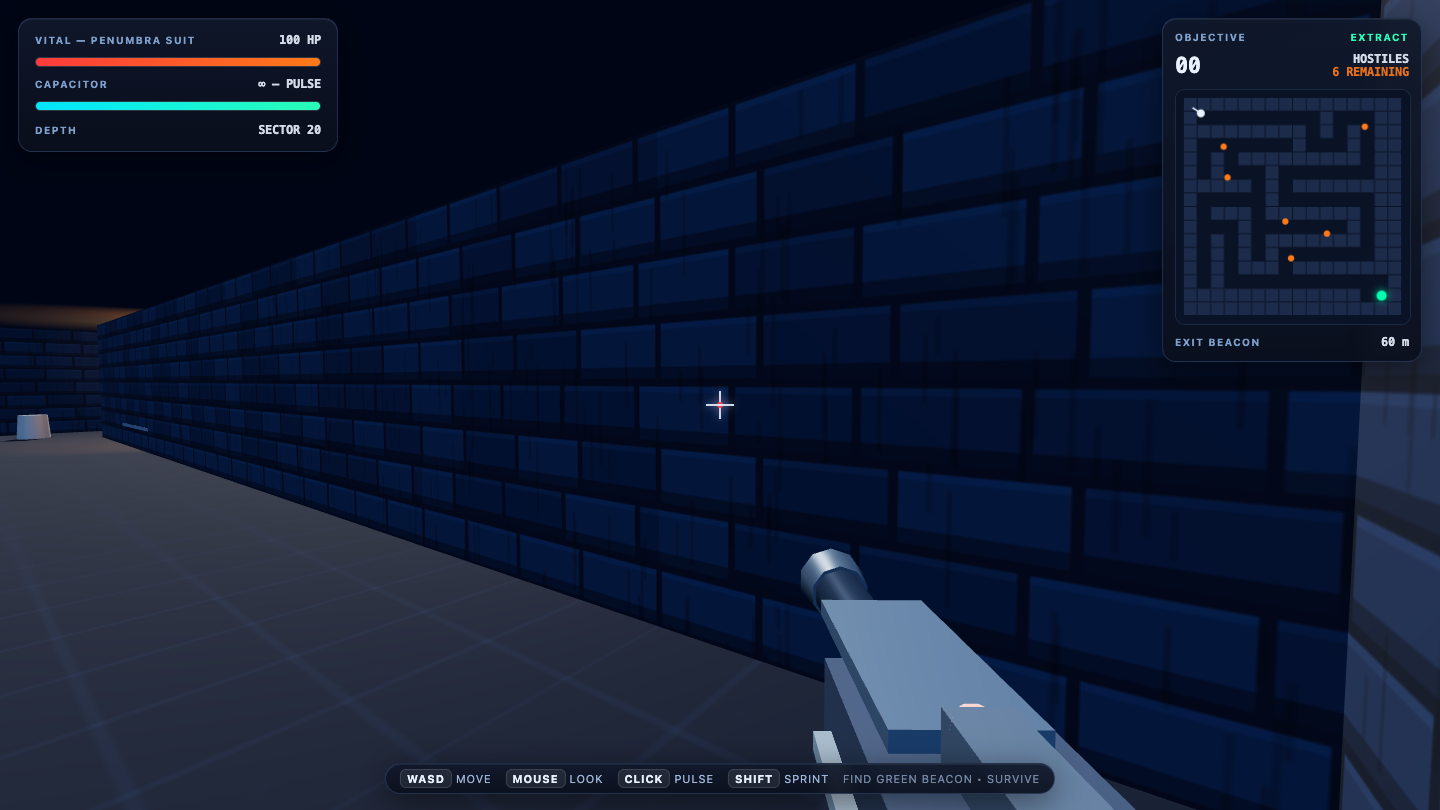
What I saw: Warm torch-lit brick corridors with bones, barrels, a rune counter, a minimap and a cohesive Nordic HUD make it a proper first-person crawler. The held torch flame is a solid white cone, the axe-sword and hands are crude flat blocks, and no draugr is in view, well short of the fi…
Waves
Visual
Claude Opus 5.5 8.4
·
Muse Spark 1.2 6.2
(+2.2)
What I saw: Gerstner ocean with a believable choppy surface, specular sunset glints, a bobbing buoy and sailboat, gulls, and a live sea-state readout. The sliders and presets panel is well built. Wave crests lack foam and the far field flattens into a painted look.
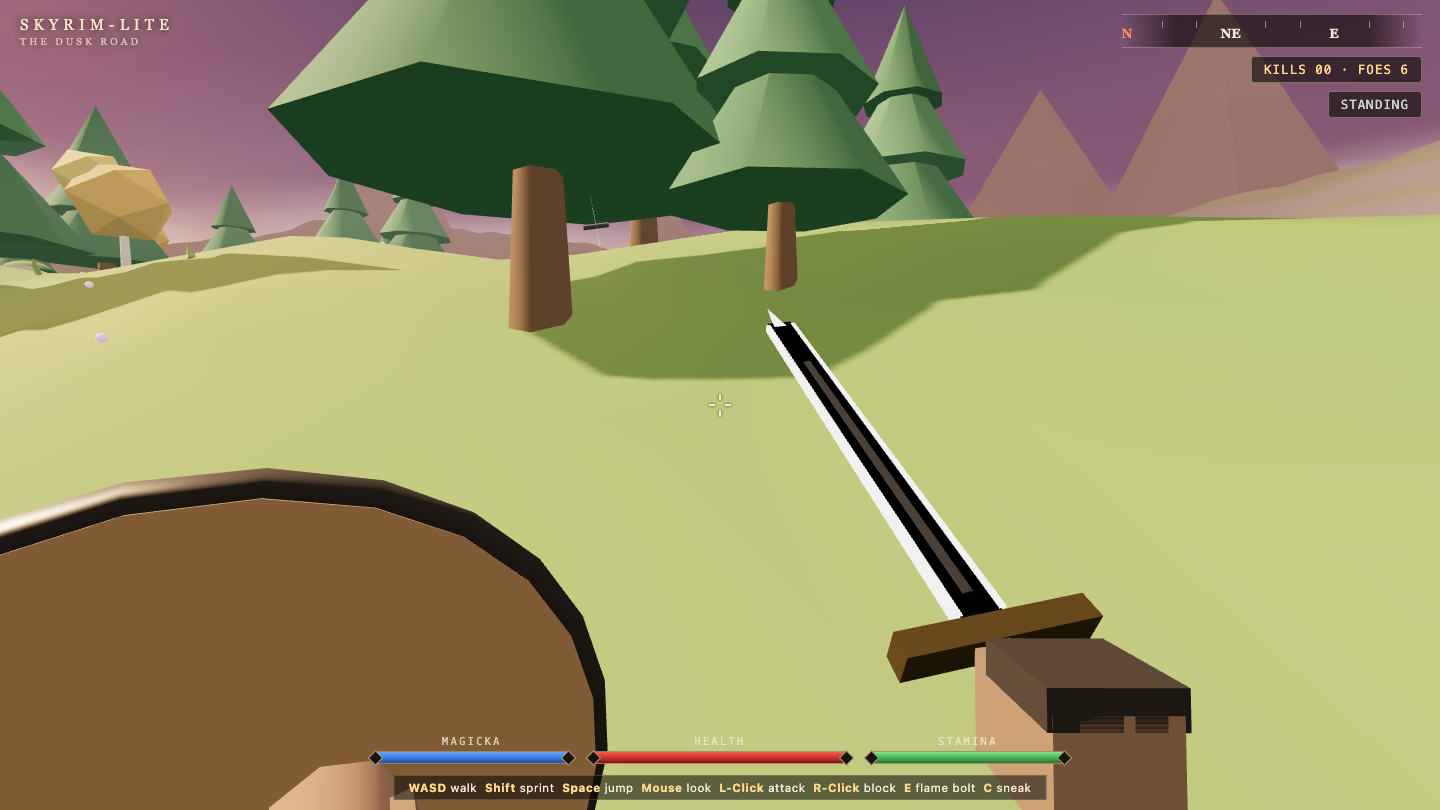
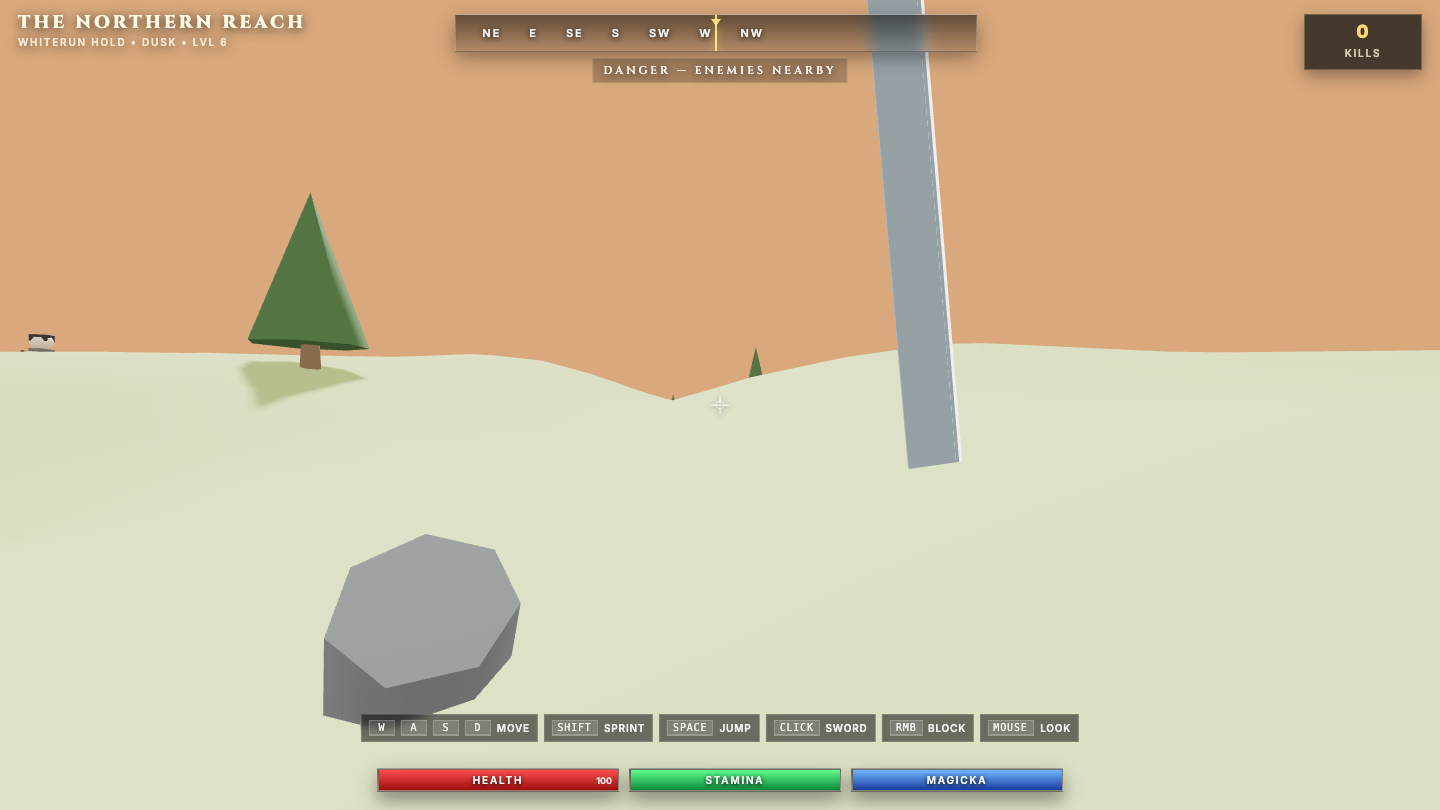
Skyrim
Game
Claude Opus 5.5 6.2
·
Muse Spark 1.2 4.2
(+2.0)
What I saw: First-person with sword, shield, magicka/health/stamina bars, compass and foes, so the systems are there. Visually it's flat: plain green hills under dusk haze, a huge untextured brown shield disc covering a third of the screen, and a stark black-and-white sword, with little atmo…
Neonsnake
Other
Claude Opus 5.5 7.4
·
Muse Spark 1.2 5.5
(+1.9)
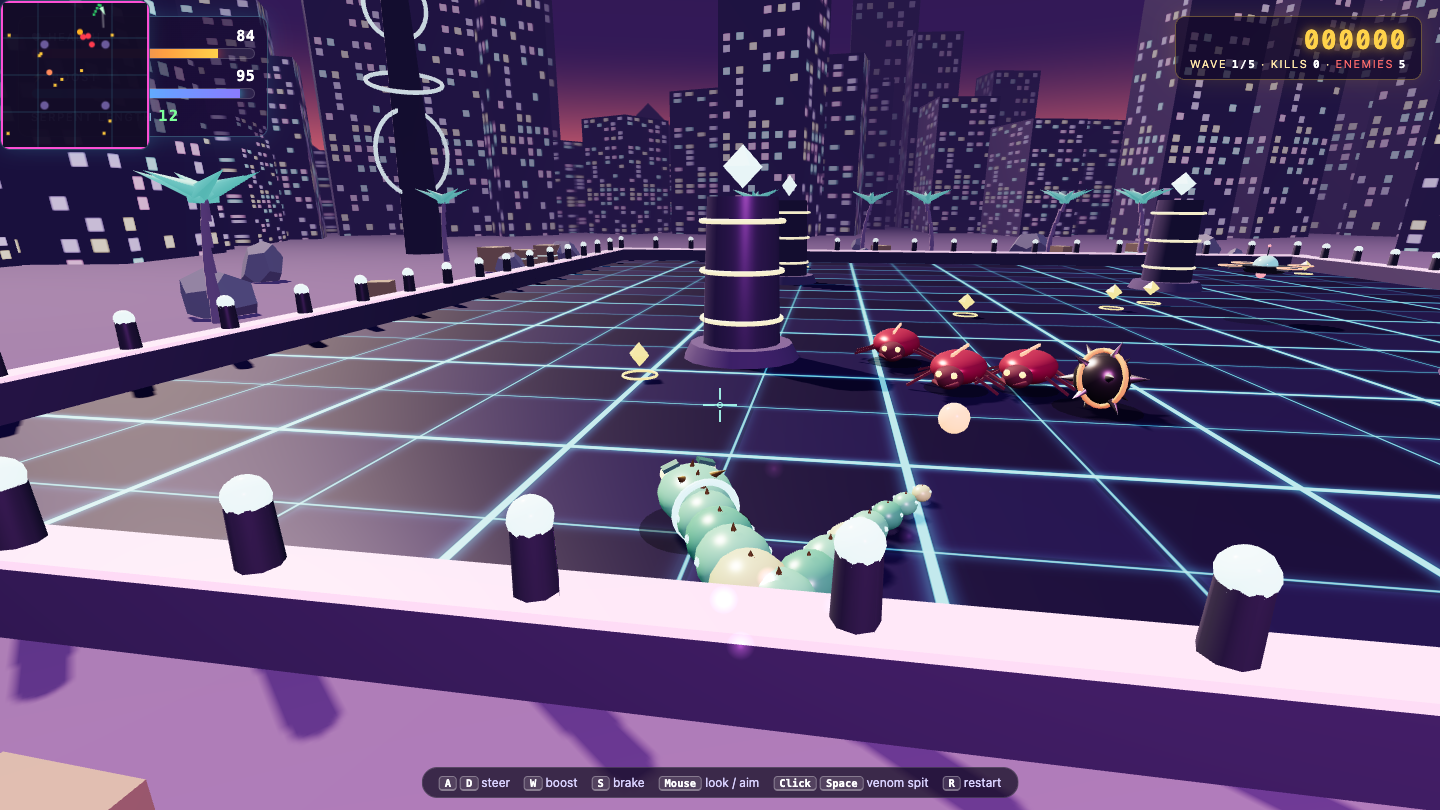
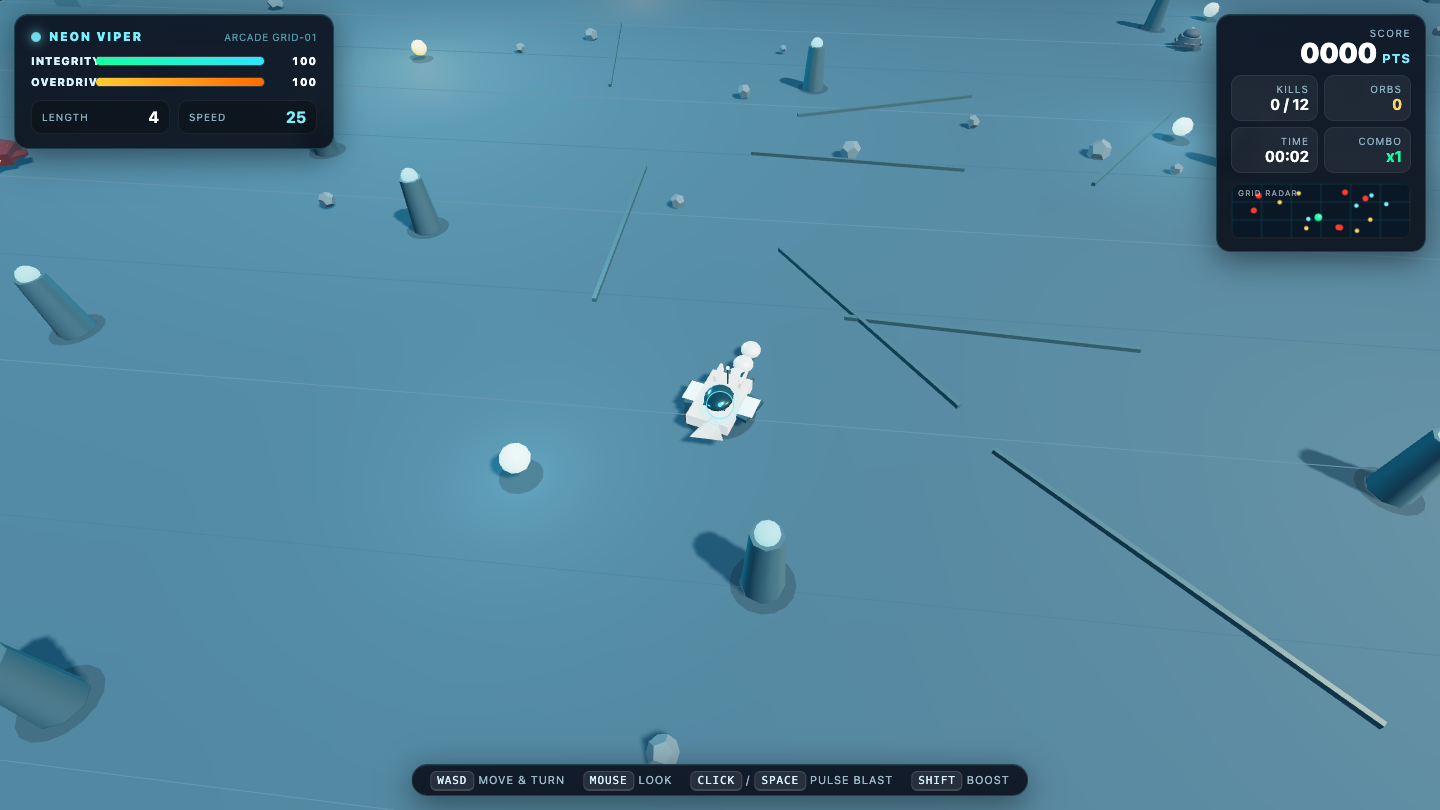
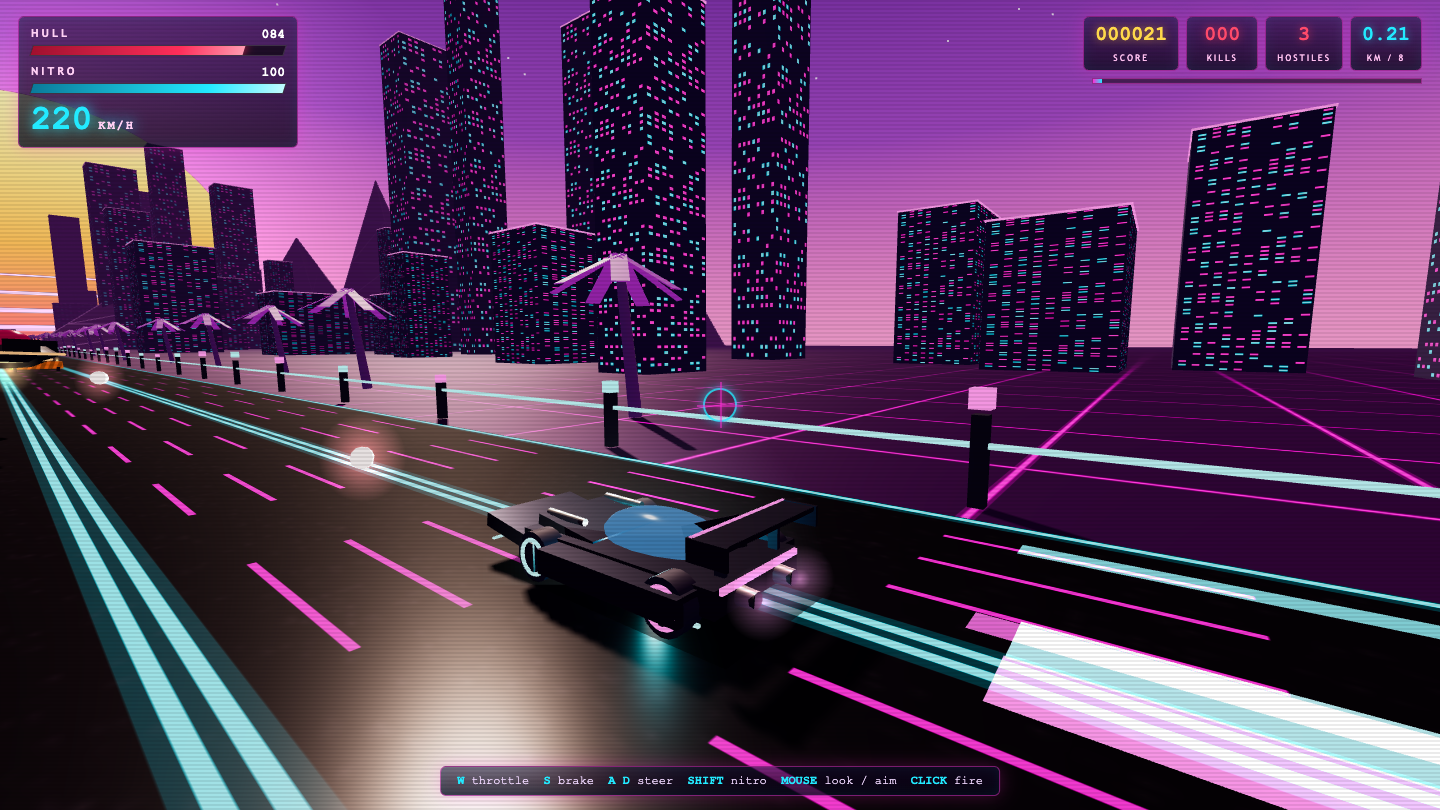
What I saw: Strong synthwave presentation: a tilted neon 3D grid arena, glowing corner pylons and a clean score/best HUD. The frame shows a paused board with a tiny 4-segment snake. The known bug where body segments snap cell-to-cell while only the head glides makes play choppy.
Where Muse Spark 1.2 beat Claude Opus 5.5
The tasks where I gave Muse Spark 1.2 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Rpg
Game
Muse Spark 1.2 7.8
·
Claude Opus 5.5 5.5
(+2.3)
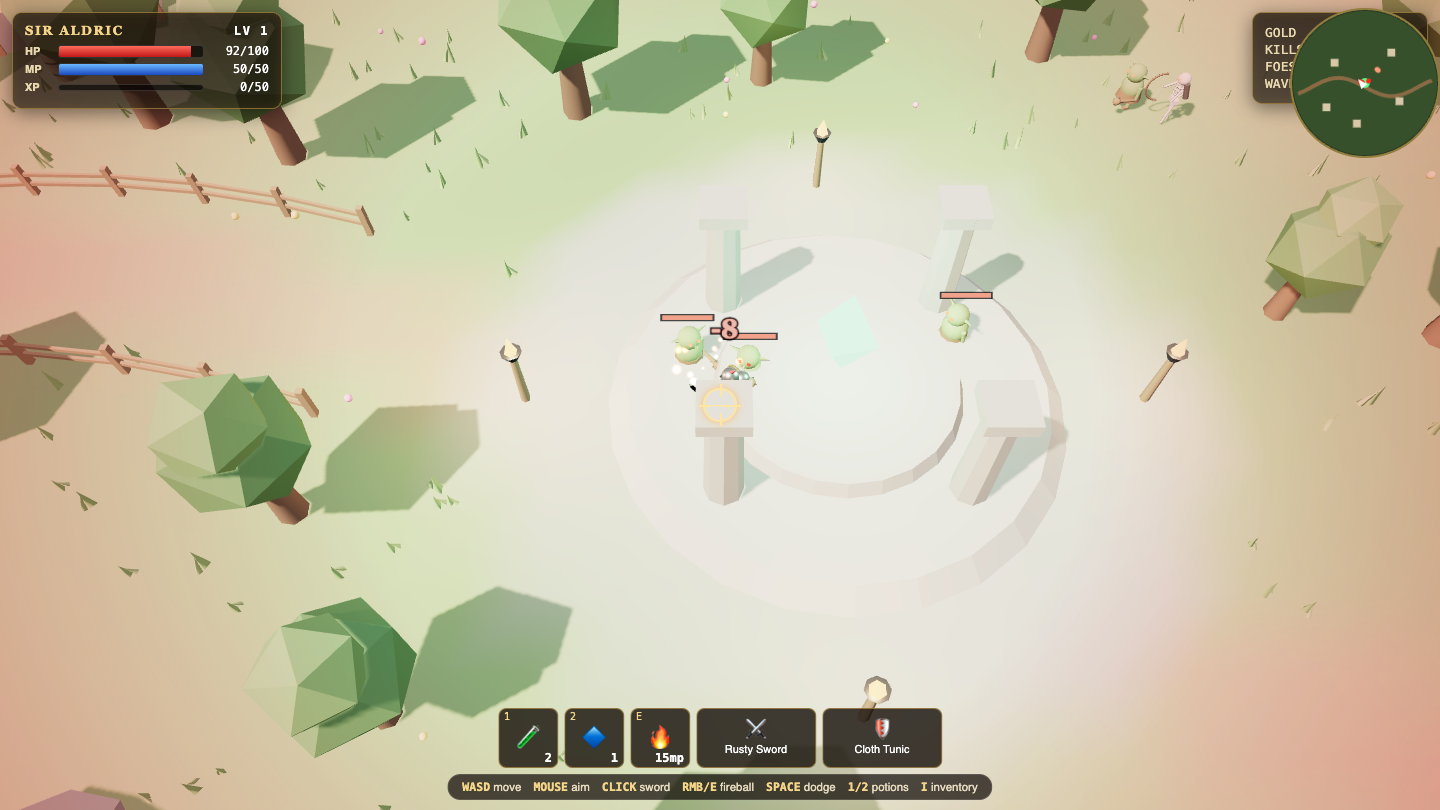
What I saw: Strong polished 3D HUD with cohesive stat bars, inventory slots, minimap, quest KPIs, and a floating damage banner that reads as real combat; weaker on brief-fit since it's a 3D top-down build with a low-part hero rather than the sprite-based feel, and the world reads a bit spars…
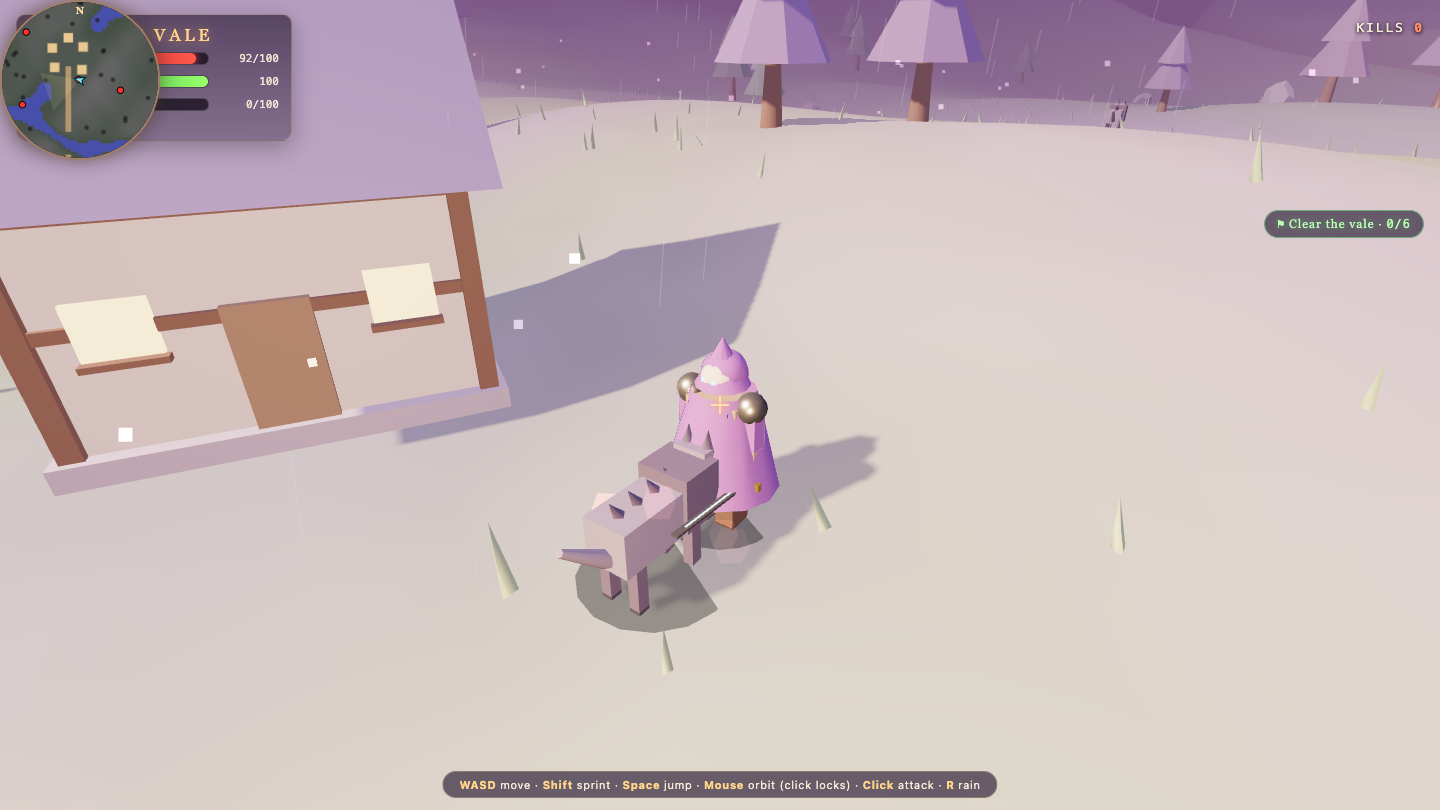
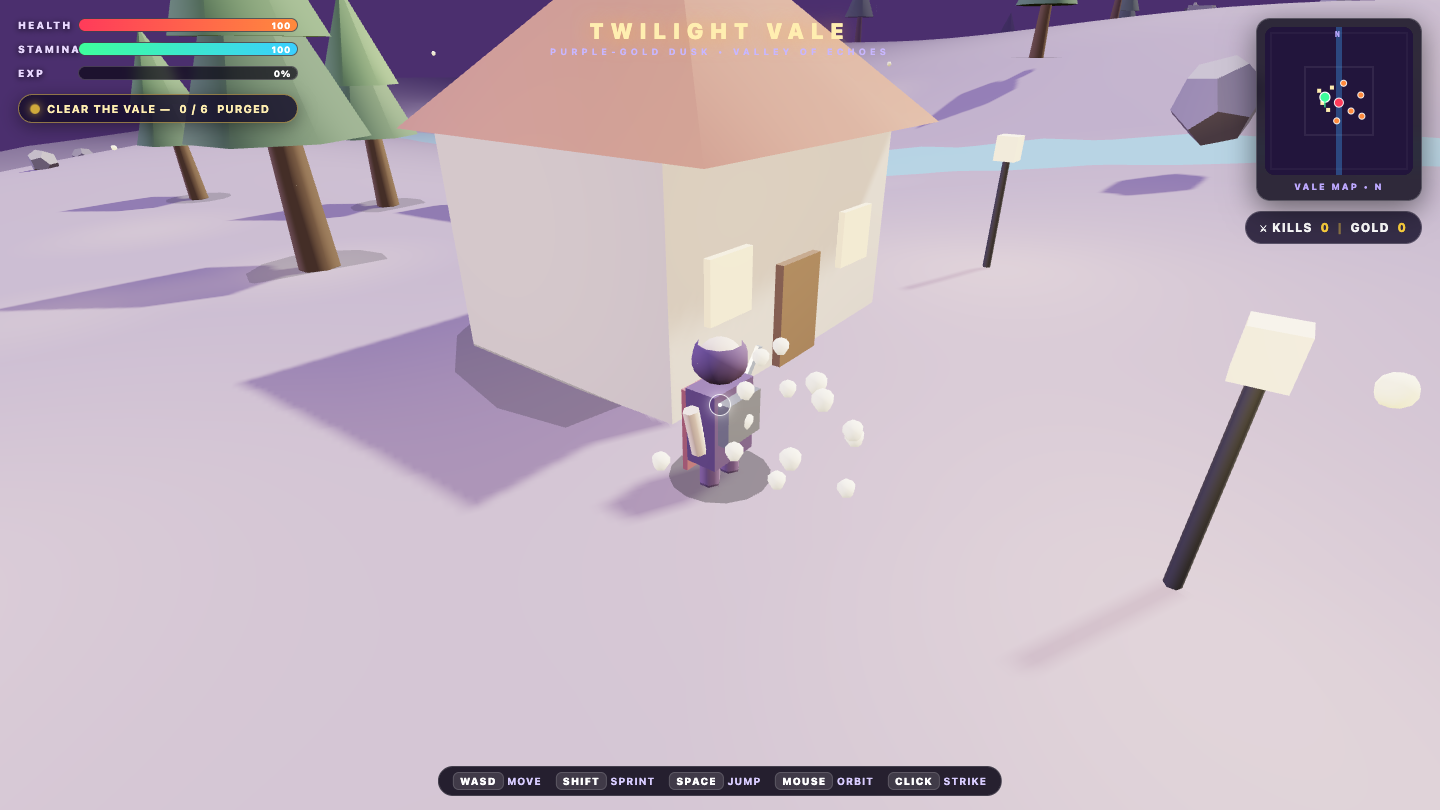
Twilightvale
Game
Muse Spark 1.2 7.8
·
Claude Opus 5.5 5.5
(+2.3)
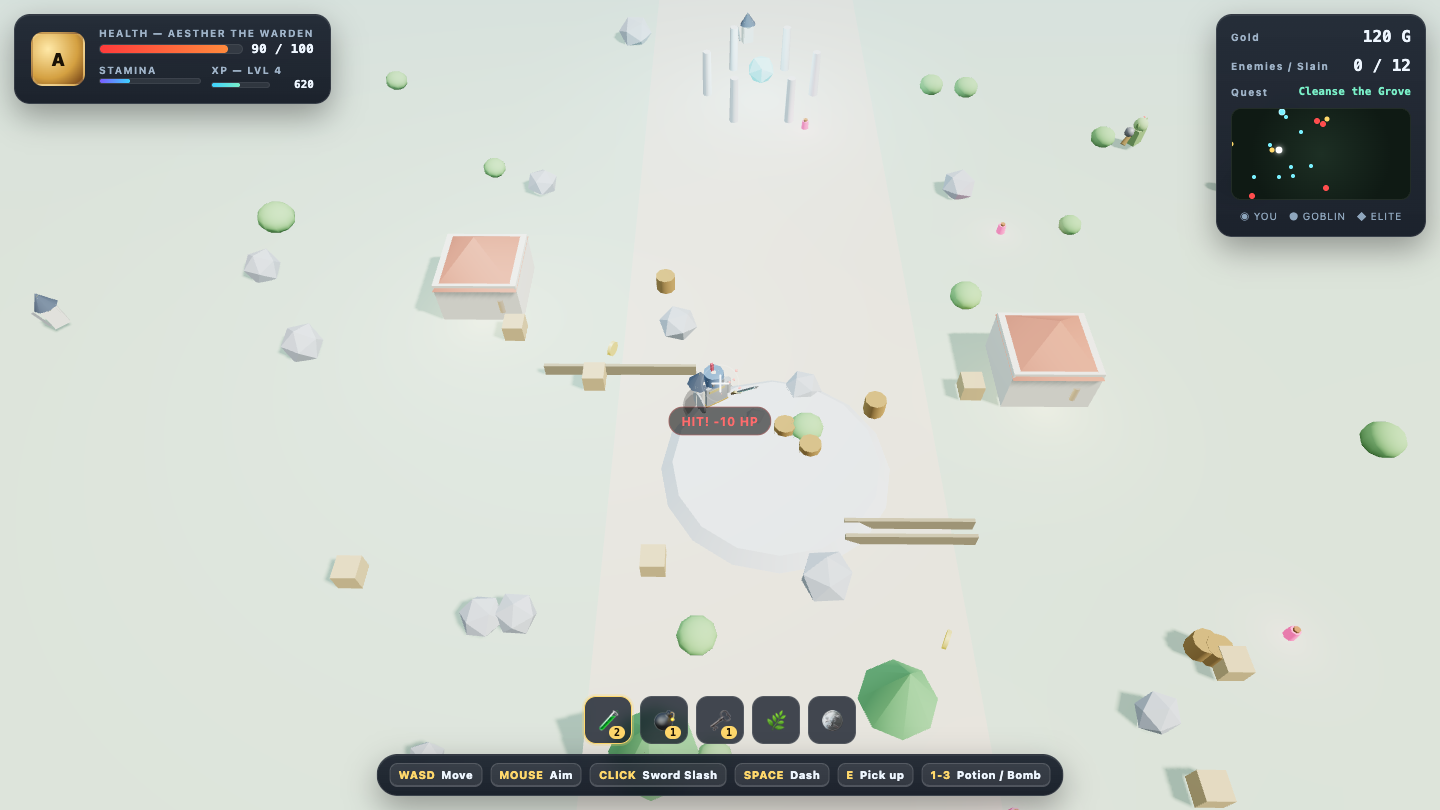
What I saw: Renders a clean 3D world with cottage, trees, character, terrain, minimap and full RPG HUD (health/stamina/exp, quest, kills/gold) — polished and cohesive purple-gold dusk palette. Weaker on the 'weather/terrain' ambition (looks snowy but flat lighting, floating white cubes read …
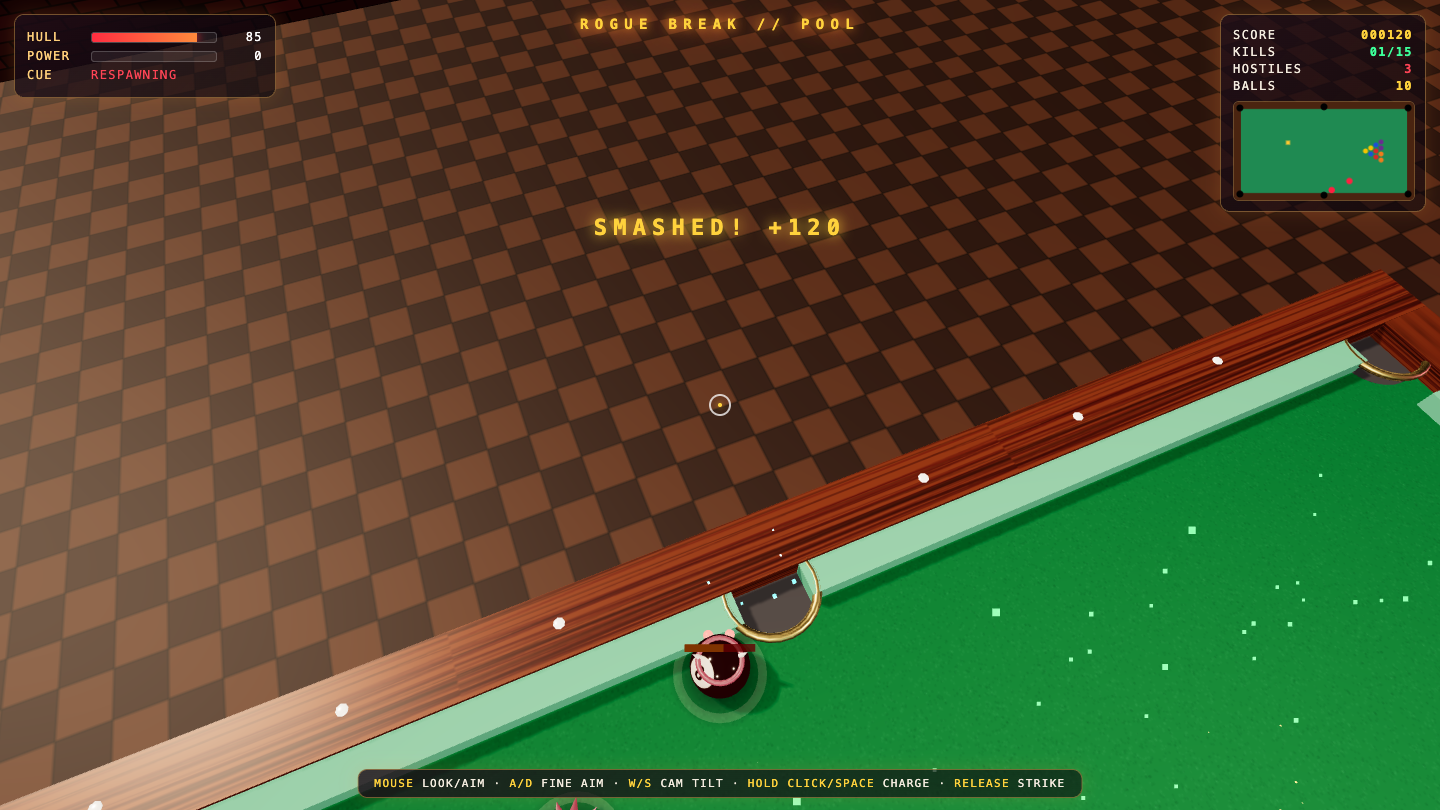
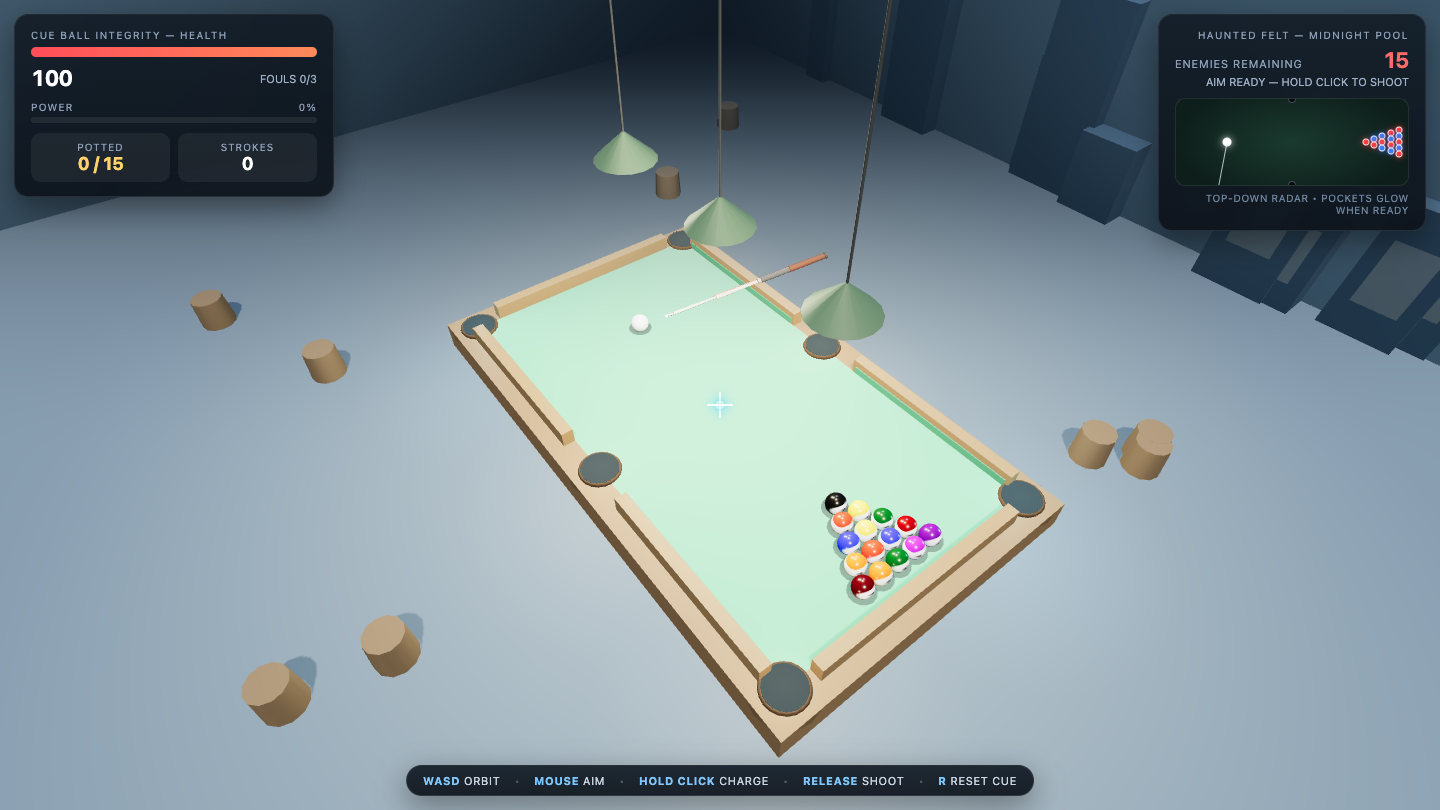
Pool
Game
Muse Spark 1.2 8.2
·
Claude Opus 5.5 6.3
(+1.9)
What I saw: Strong 3D render with a proper racked triangle, six pockets, cue ball, aiming stick, polished HUD and a working top-down radar. Environment lighting looks slightly washed/gray and the RPG-style 'health/enemies' framing is a gimmicky overlay on a solid billiards sim, keeping it ju…
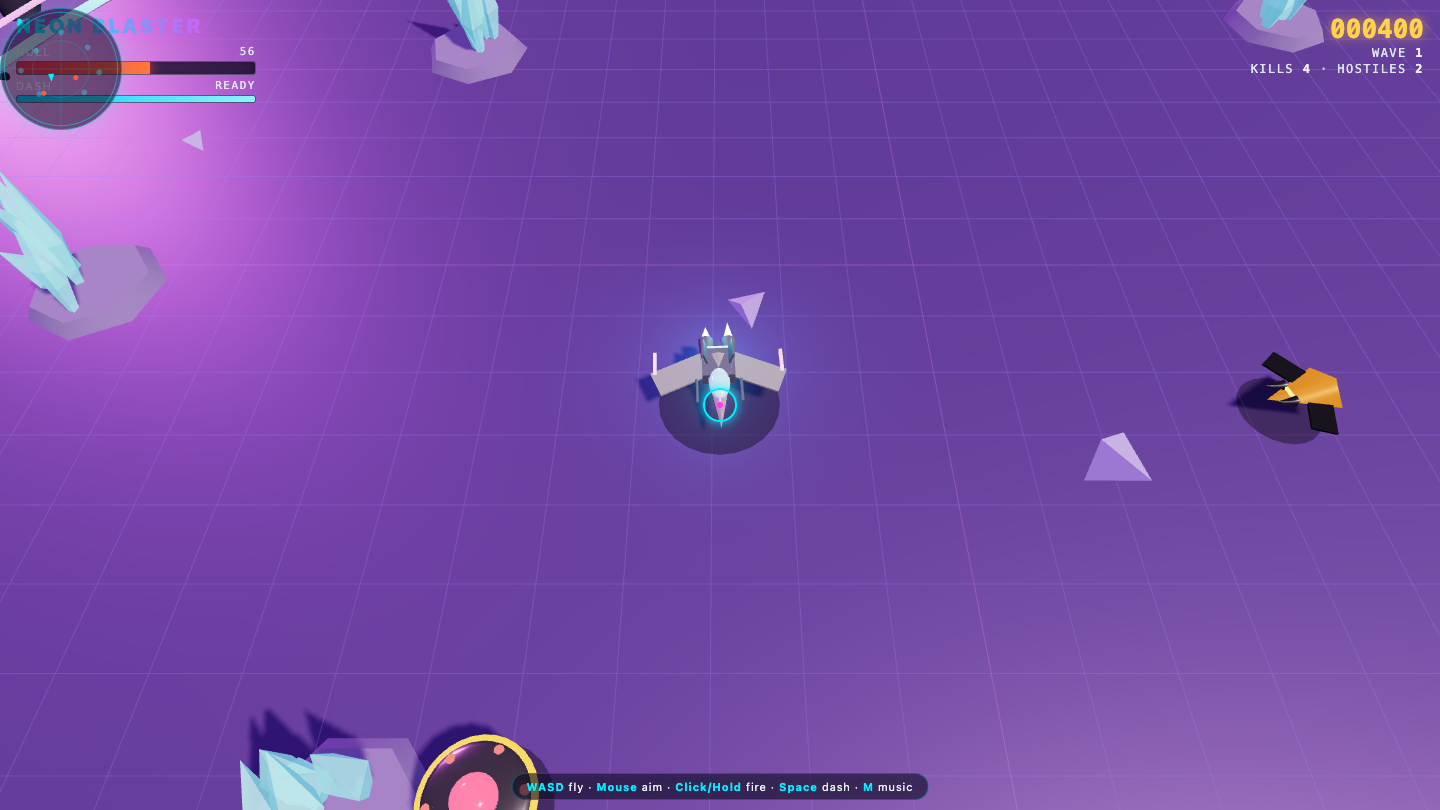
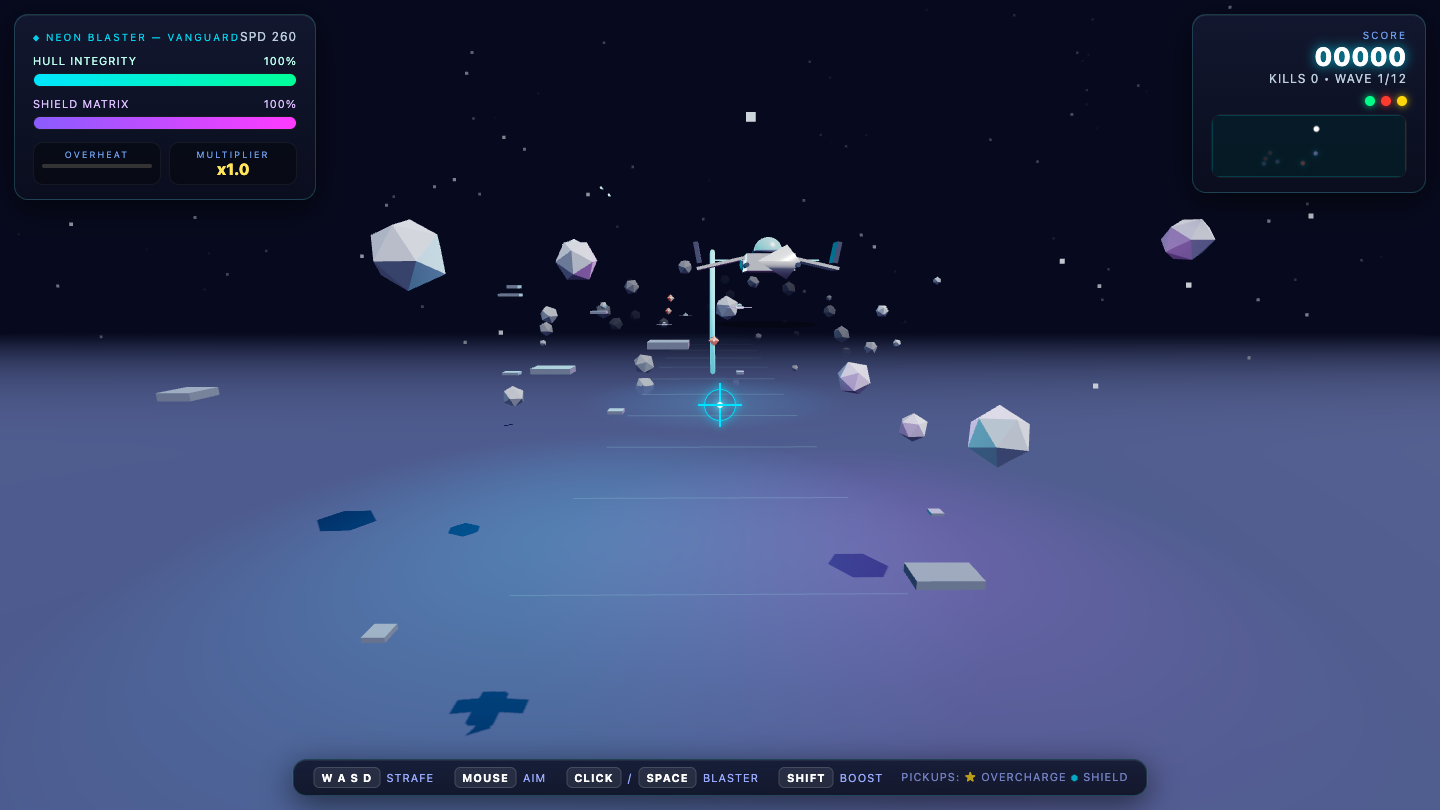
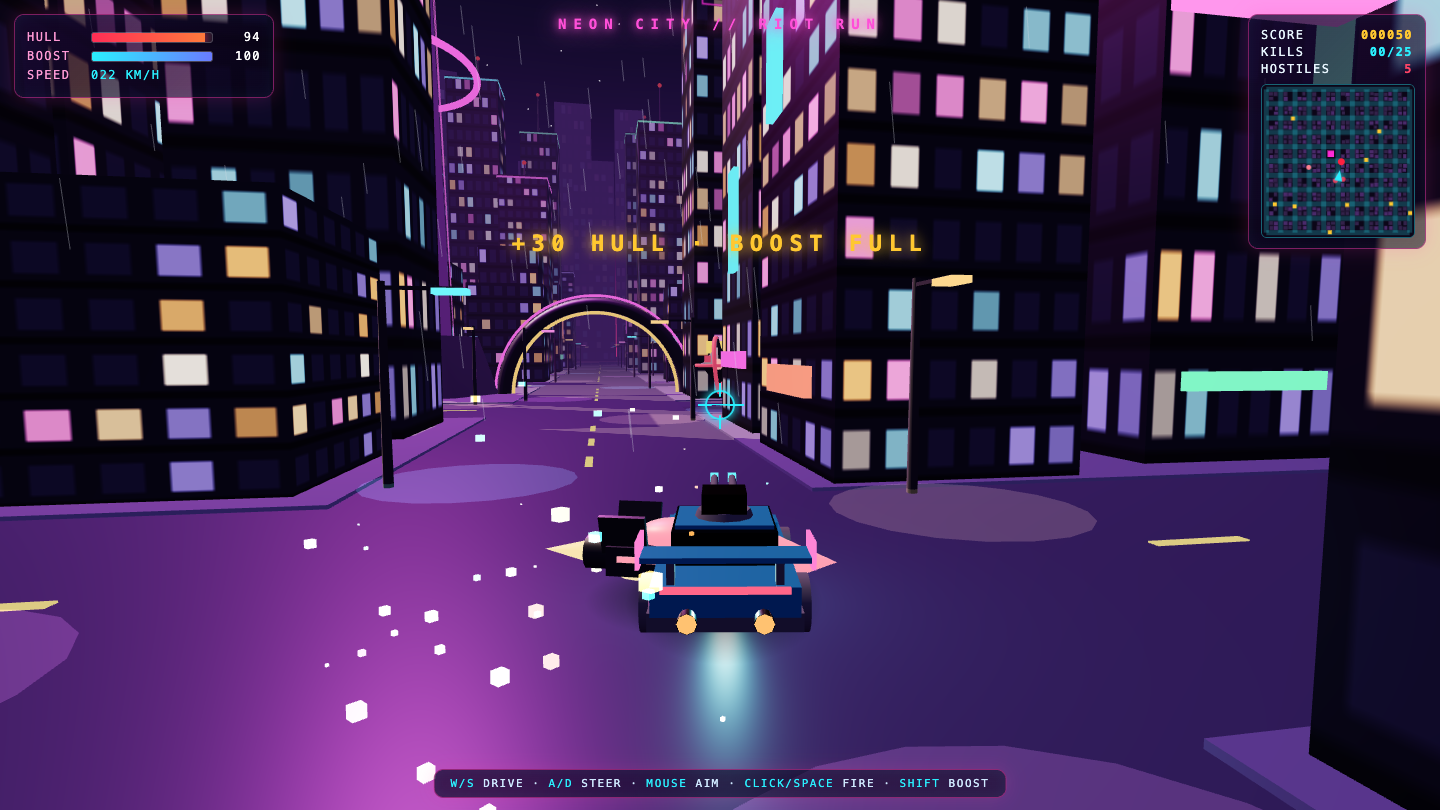
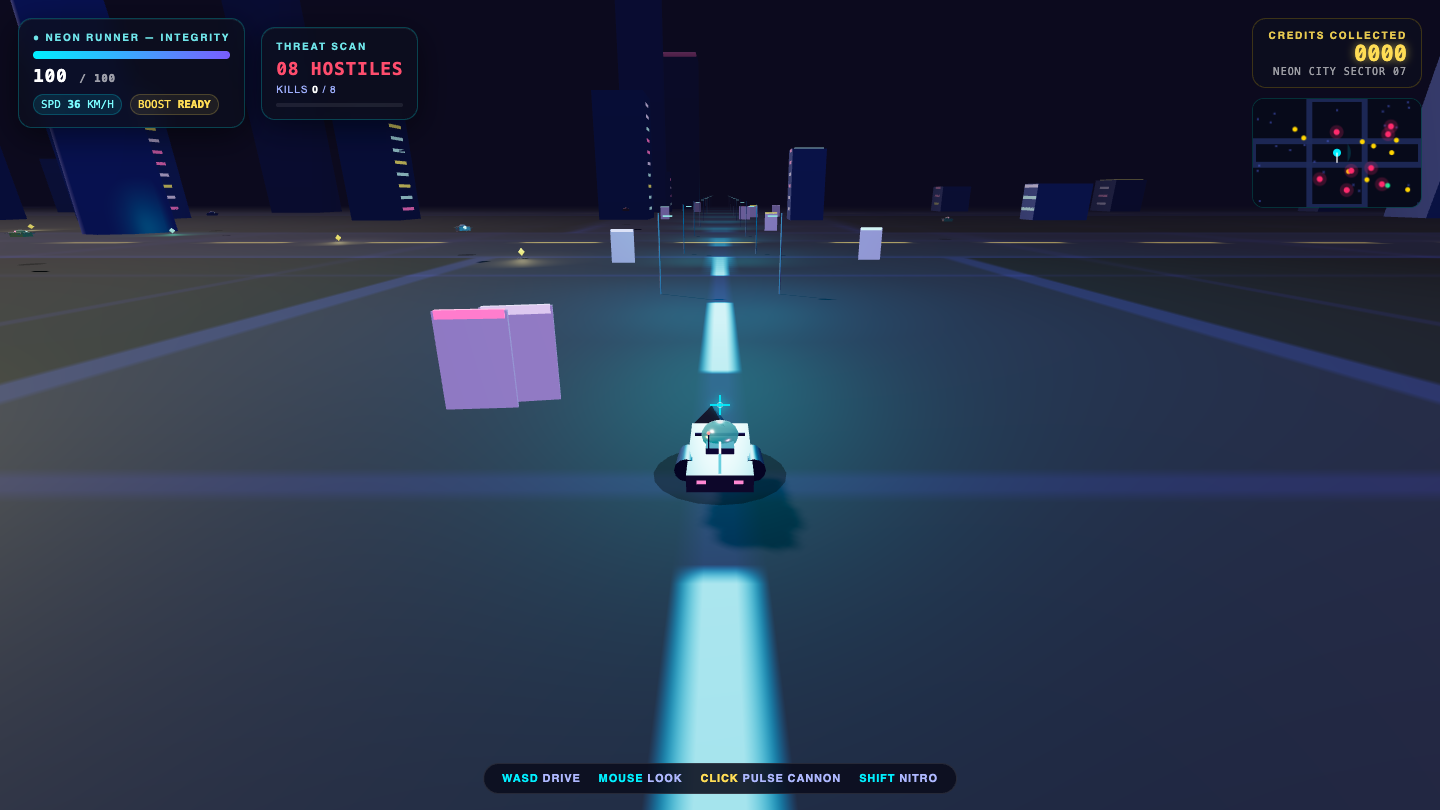
Neonblaster
Game
Muse Spark 1.2 7.4
·
Claude Opus 5.5 5.8
(+1.6)
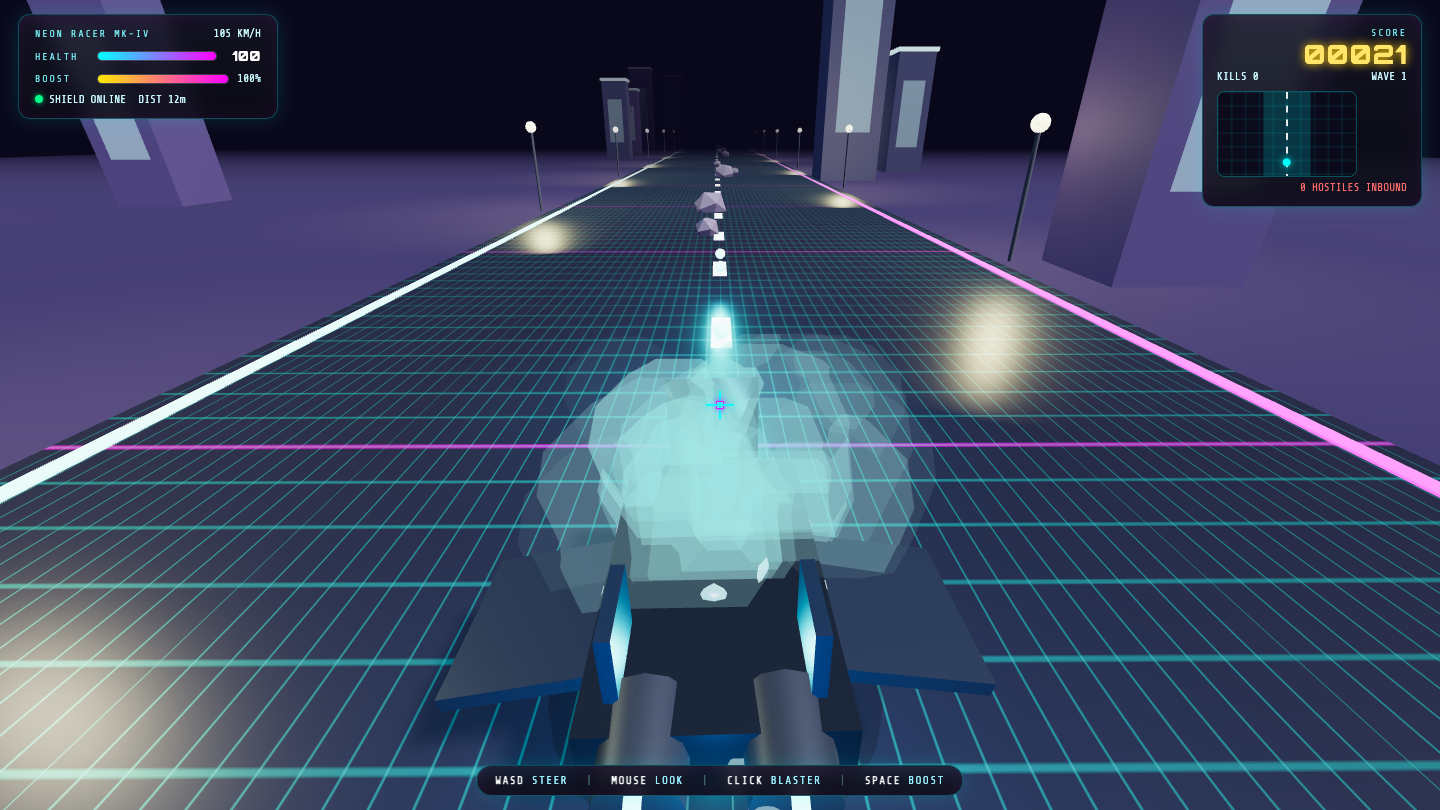
What I saw: Polished 3D HUD with cohesive neon styling, crosshair, radar, and a nicely modeled ship over a starfield/asteroid scene render well; but it reads as a static space scene rather than a juicy arcade shooter — no visible bullets, waves, screen-shake, or combat energy in the frame, s…
Mlx Speedtest
Other
Muse Spark 1.2 7.4
·
Claude Opus 5.5 6.0
(+1.4)
What I saw: Strong polished dashboard shell with clean panels, live metrics, sparklines and a benchmarking task list that reads convincingly on-brief. Weakened by the empty 3D center canvas (just faint ring, no visible model/animation) and blank throughput timeline chart, plus raw unformatte…
Strengths & weaknesses I logged
Claude Opus 5.5
Strengths
- Frontier-class coding + agentic reasoning (Claude 5 family)
- 1M-token context — reads an entire codebase in one call
- All 50 one-shot builds rendered with zero console errors; all 23 games passed the input playtest
Trade-offs
- Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes
- One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts)
Muse Spark 1.2
Strengths
- Generative art & shader-feel scenes (fractal 8.7, aurora/galaxy/matrix/synthwave 8.6)
- Full app chrome one-shot (macOS-clone desktop 8.6)
- Fast one-shots — most builds landed in 45-80s
- 1M context for whole-repo work
Trade-offs
- 3D game worlds often render black/empty (dragonrealm 2.5, dogfight 3.0, doom 3.5)
- Open-world briefs collapse to HUD-only shells
- Reasoning tokens billed as output
Pricing & context — the spec sheet
| Spec | Claude Opus 5.5 | Muse Spark 1.2 |
|---|---|---|
| Vendor | Anthropic | Meta |
| Context window | 1,000,000 tokens | 1,000,000 tokens |
| Price | $4 / $20 per M | $1.25 in / $4.25 out per 1M |
| Pricing detail | Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. | Meta's coding-optimized reasoning model, released 2026-08-05 beside the Muse Code agent. $0.15/1M cached input. Contributor tier is token-rate-limited in a rolling 5-hour window. Benched release-day via OpenRouter (meta/muse-spark-1.2, first-party listing); Opus 4.8 judged every real rendered poster, same rubric as the whole field. |
| Release | 2026-09 | 2026-08-05 |
| Bench coverage | 50/50 scored · avg 7.57/10 | 50/50 scored · avg 7.55/10 |
The verdict — which should you pick?
Across 50 scored shared tasks, the averages are essentially tied — Claude Opus 5.5 7.57 vs Muse Spark 1.2 7.55. This isn't the comparison where one wins; it's the comparison where you pick based on context, pricing, and what you're actually trying to ship.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire Claude Opus 5.5 and Muse Spark 1.2 both into the Agent Operating System and dispatch each from the kanban by task type — hardest agentic builds → Claude Opus 5.5, generative-art visuals → Muse Spark 1.2. That's the same setup I run for the 4,000+ founders inside the AI Profit Boardroom.
FAQ — Claude Opus 5.5 vs Muse Spark 1.2
Which is better, Claude Opus 5.5 or Muse Spark 1.2?
On Goldie Bench, Claude Opus 5.5 averages 7.57/10 across the shared tasks, with 0 gold, 0 silver, 1 bronze overall. Muse Spark 1.2 averages 7.55/10, with 0 gold, 3 silver, 4 bronze. Muse Spark 1.2 wins the head-to-head 30–17.
How much does Claude Opus 5.5 cost vs Muse Spark 1.2?
Claude Opus 5.5: Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. Muse Spark 1.2: Meta's coding-optimized reasoning model, released 2026-08-05 beside the Muse Code agent. $0.15/1M cached input. Contributor tier is token-rate-limited in a rolling 5-hour window. Benched release-day via OpenRouter (meta/muse-spark-1.2, first-party listing); Opus 4.8 judged every real rendered poster, same rubric as the whole field.
What's the context window for Claude Opus 5.5 vs Muse Spark 1.2?
Claude Opus 5.5 has a 1,000,000 tokens context window. Muse Spark 1.2 has a 1,000,000 tokens context window.
When should I pick Claude Opus 5.5 over Muse Spark 1.2?
Pick Claude Opus 5.5 for: Hardest agentic builds; Whole-repo reasoning; Frontier one-shots. The trade-off is the weaknesses we logged on the bench: Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes; One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts).
When should I pick Muse Spark 1.2 over Claude Opus 5.5?
Pick Muse Spark 1.2 for: Generative-art visuals; Dashboard & app-shell one-shots; Long-context refactors (1M window). The trade-off is the weaknesses we logged on the bench: 3D game worlds often render black/empty (dragonrealm 2.5, dogfight 3.0, doom 3.5); Open-world briefs collapse to HUD-only shells; Reasoning tokens billed as output.
How does Goldie Bench score Claude Opus 5.5 vs Muse Spark 1.2?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
Claude Opus 5.5 vs Fusion Muse Spark 1.2 vs Fusion Claude Opus 5.5 vs Claude Opus 5 Muse Spark 1.2 vs Claude Opus 5 Claude Opus 5.5 vs Hermes MoA Muse Spark 1.2 vs Hermes MoA Claude Opus 5.5 vs GPT-5.6 Sol Muse Spark 1.2 vs GPT-5.6 SolFull model pages: Claude Opus 5.5 · Muse Spark 1.2 · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.
4,000+founders
258documented wins
38countries
$59/momonthly