Real head-to-head · same prompt, one shot
Claude Opus 5.5 vs Kimi K2.7 · Quality
Anthropic's Opus 5.5 — benched on all 50 one-shot builds, every game playtested. vs Quality mode — deepest thinking, best output.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to Claude Opus 5.5 and Kimi K2.7 · Quality, side by side, on 47 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
Claude Opus 5.5 · Benched on all 50 GoldieBench tasks via a Claude subscription: one-shot builds, real renders, pixel-diff playtests on every game, then vision-judged.
Kimi K2.7 · Quality · Reserved for one-shot builds where the output is the deliverable — polish over speed.
Side-by-side on 50 shared tasks
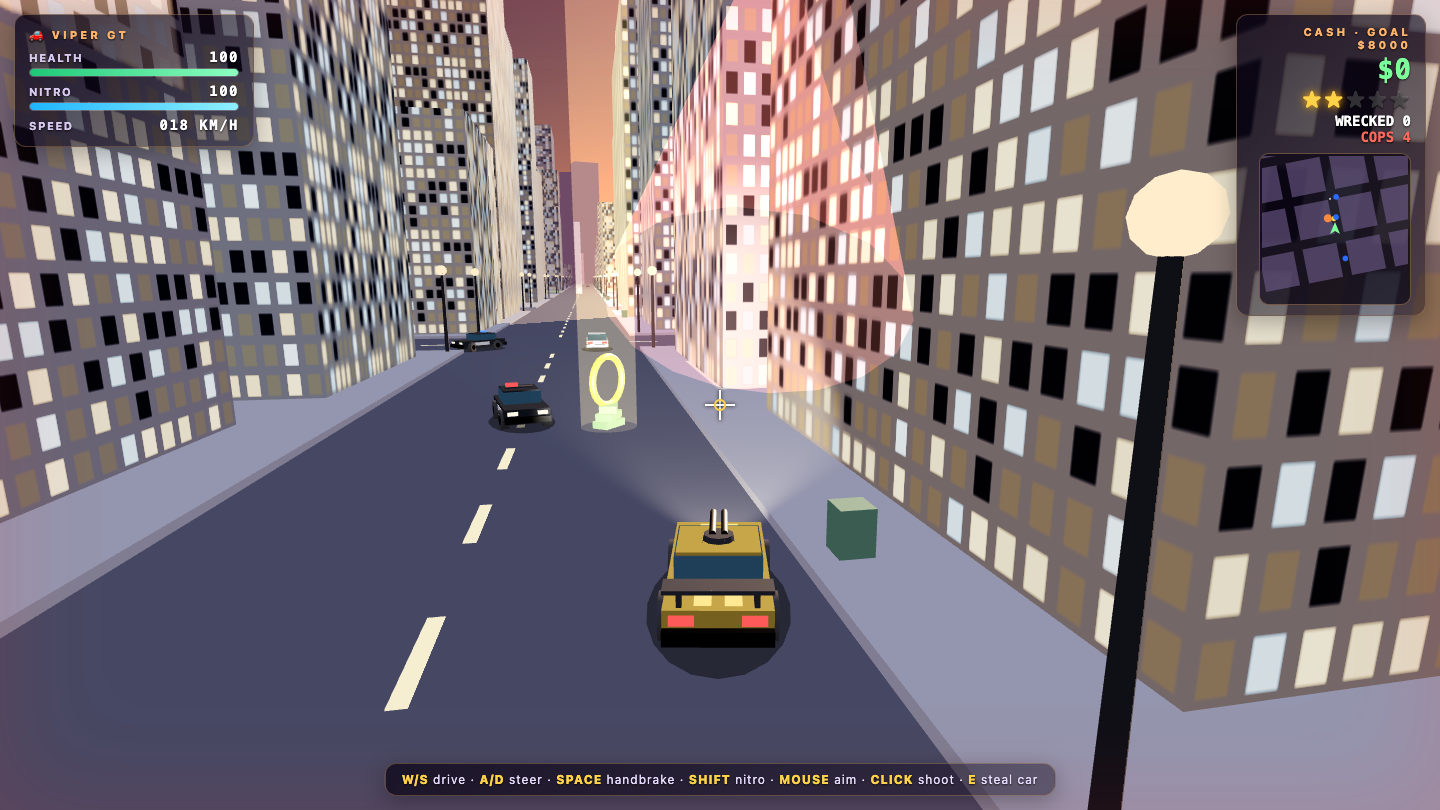
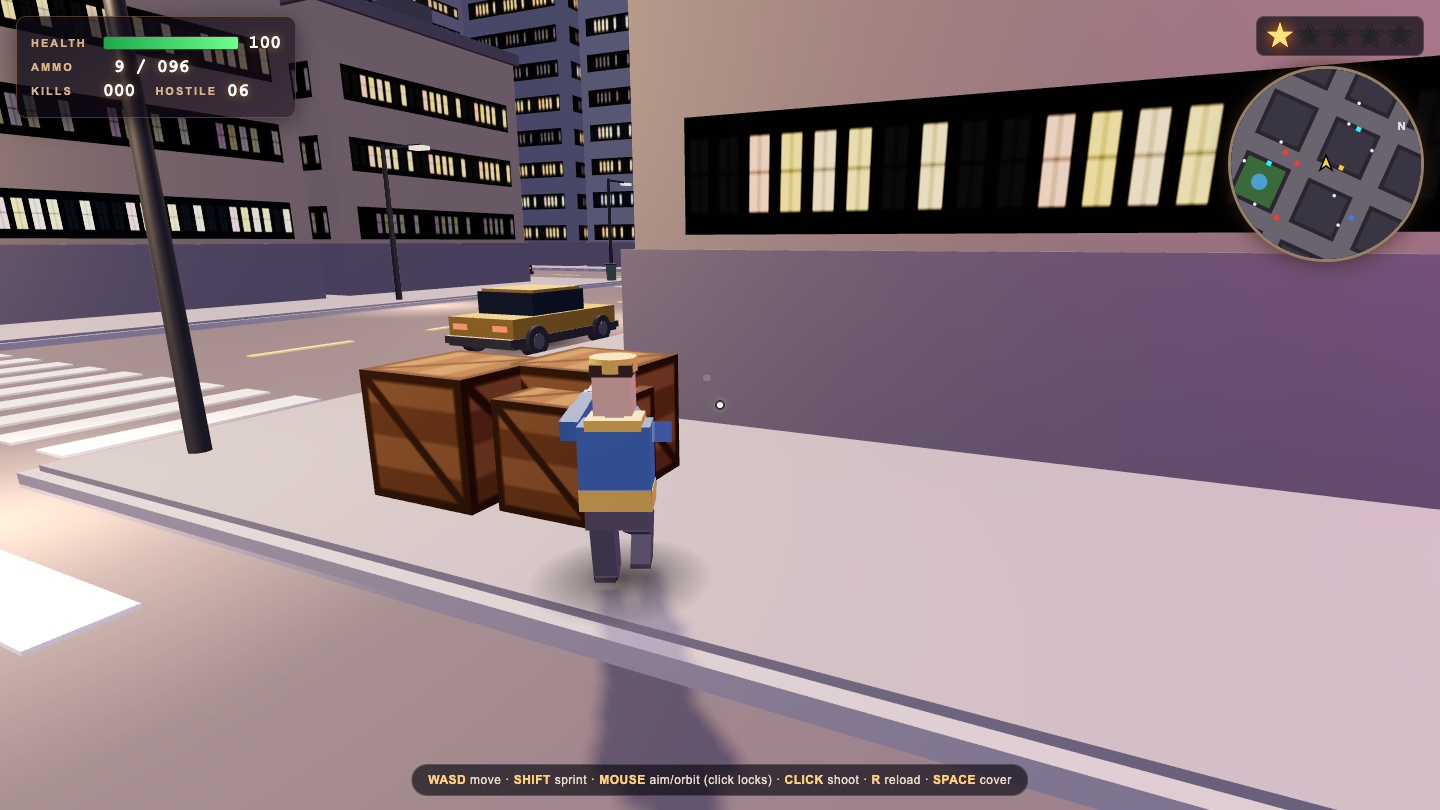
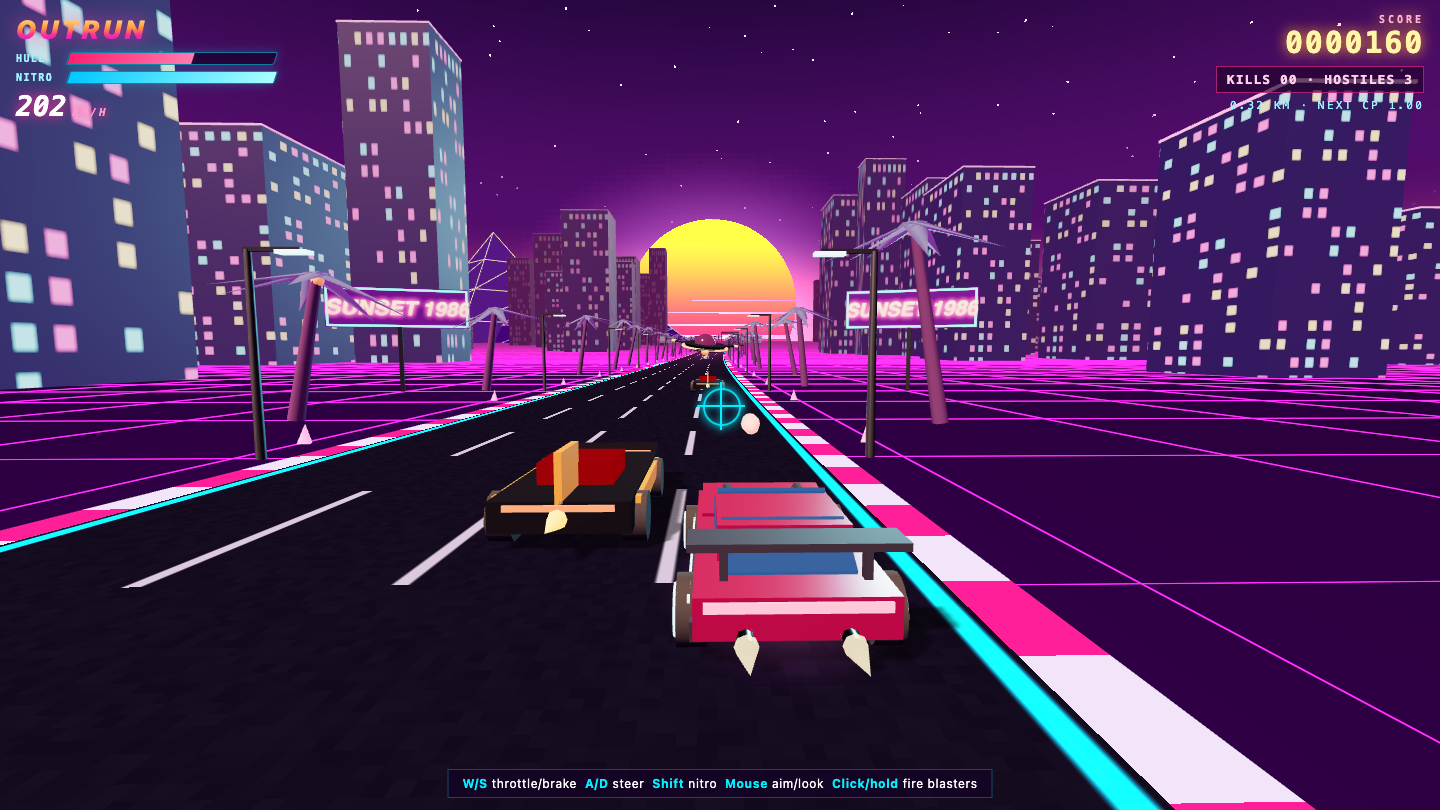
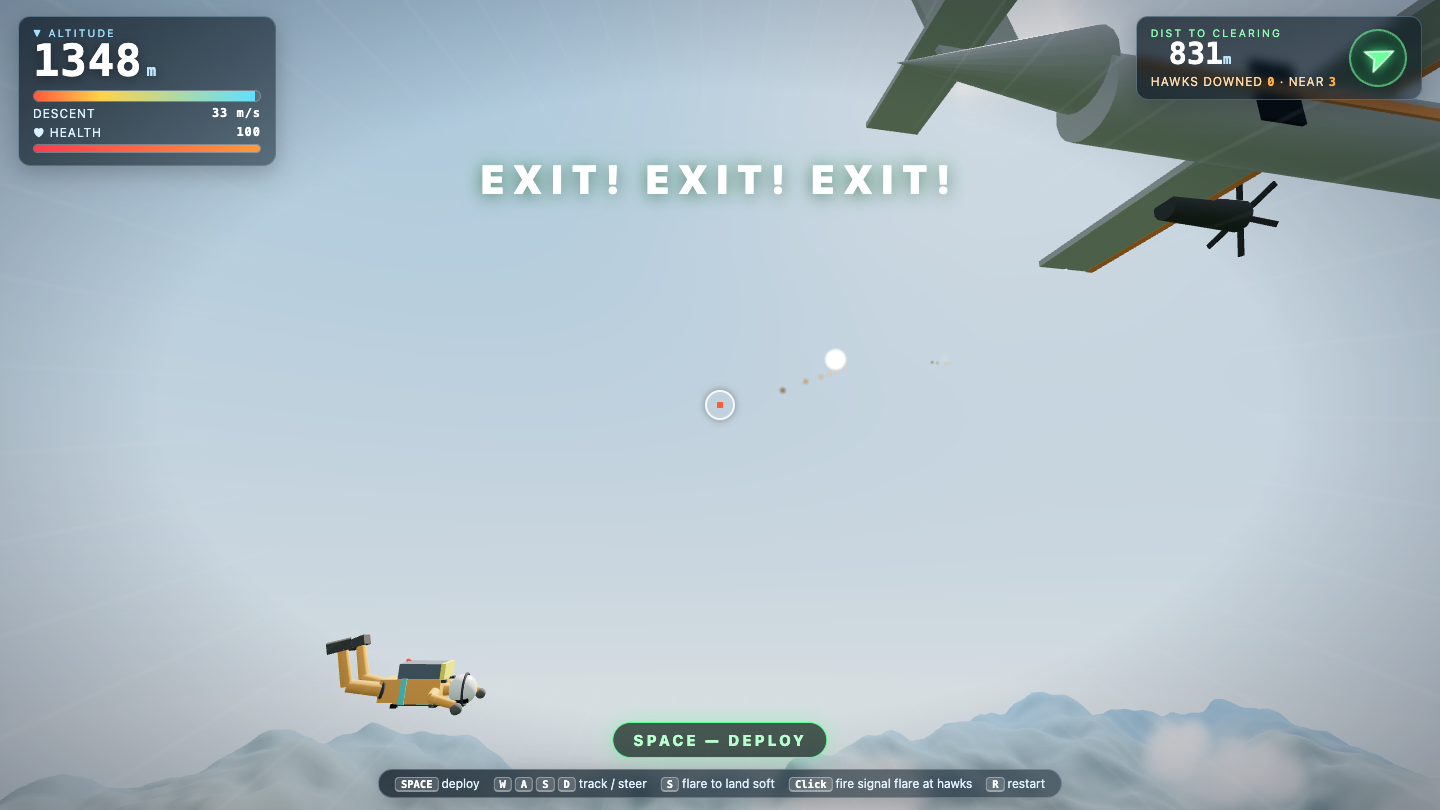
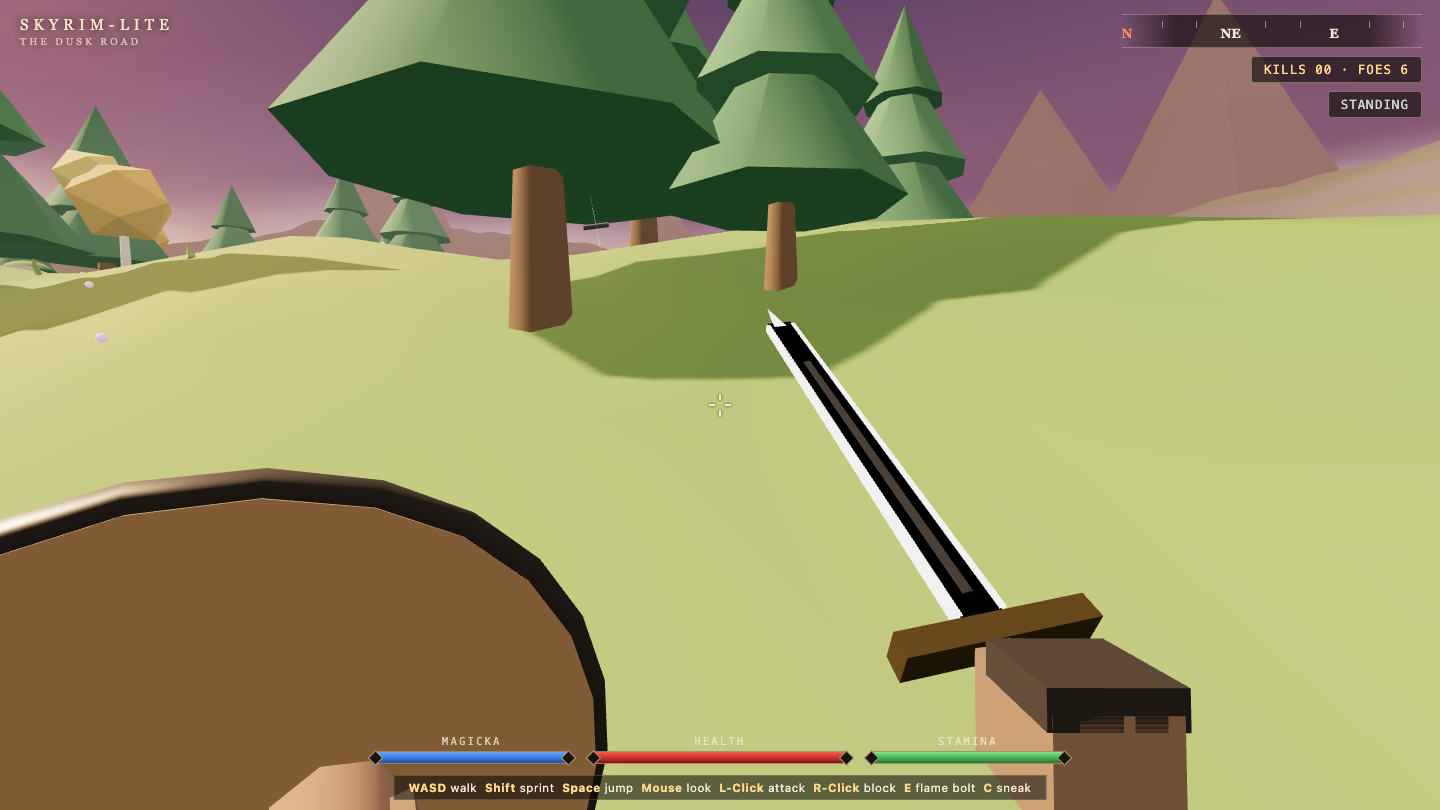
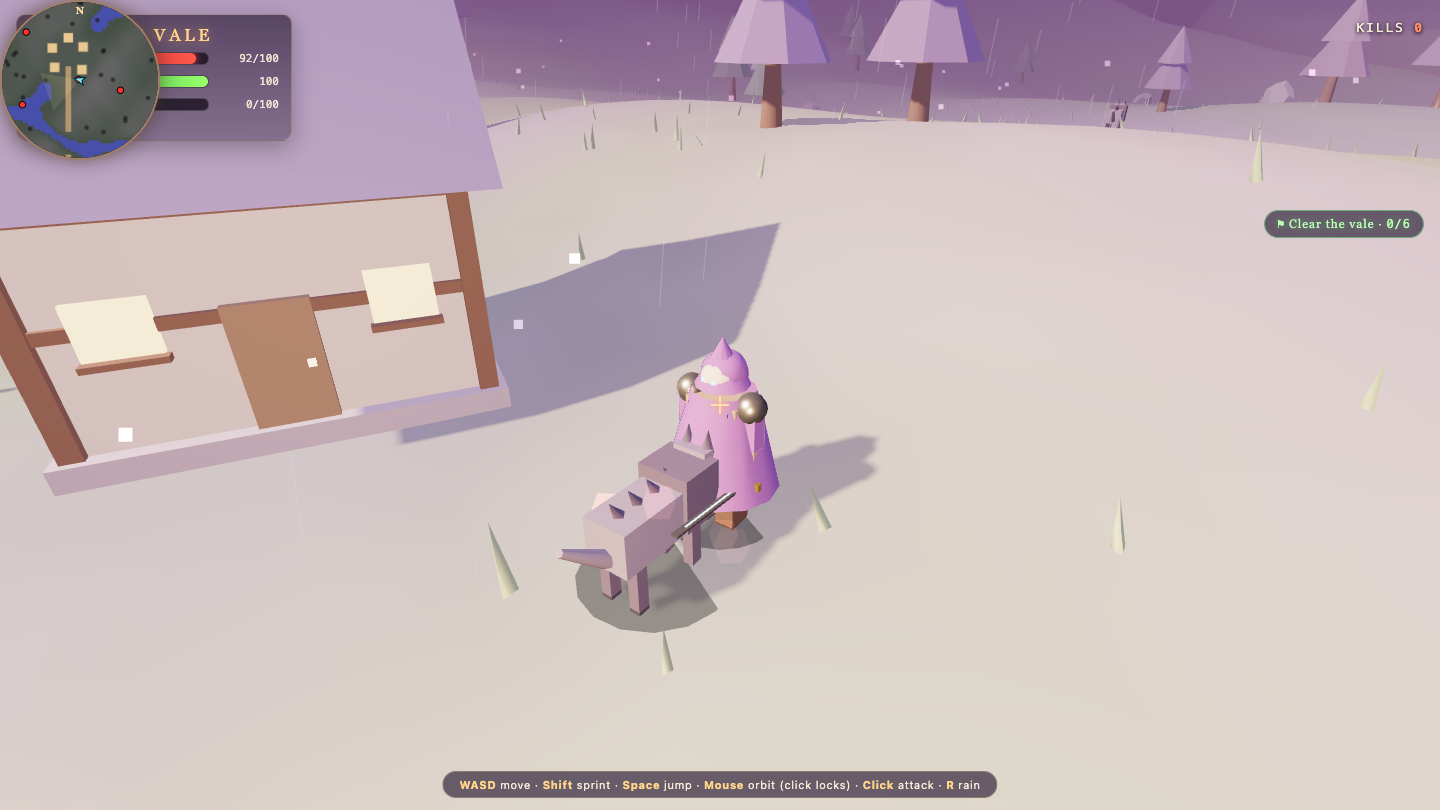
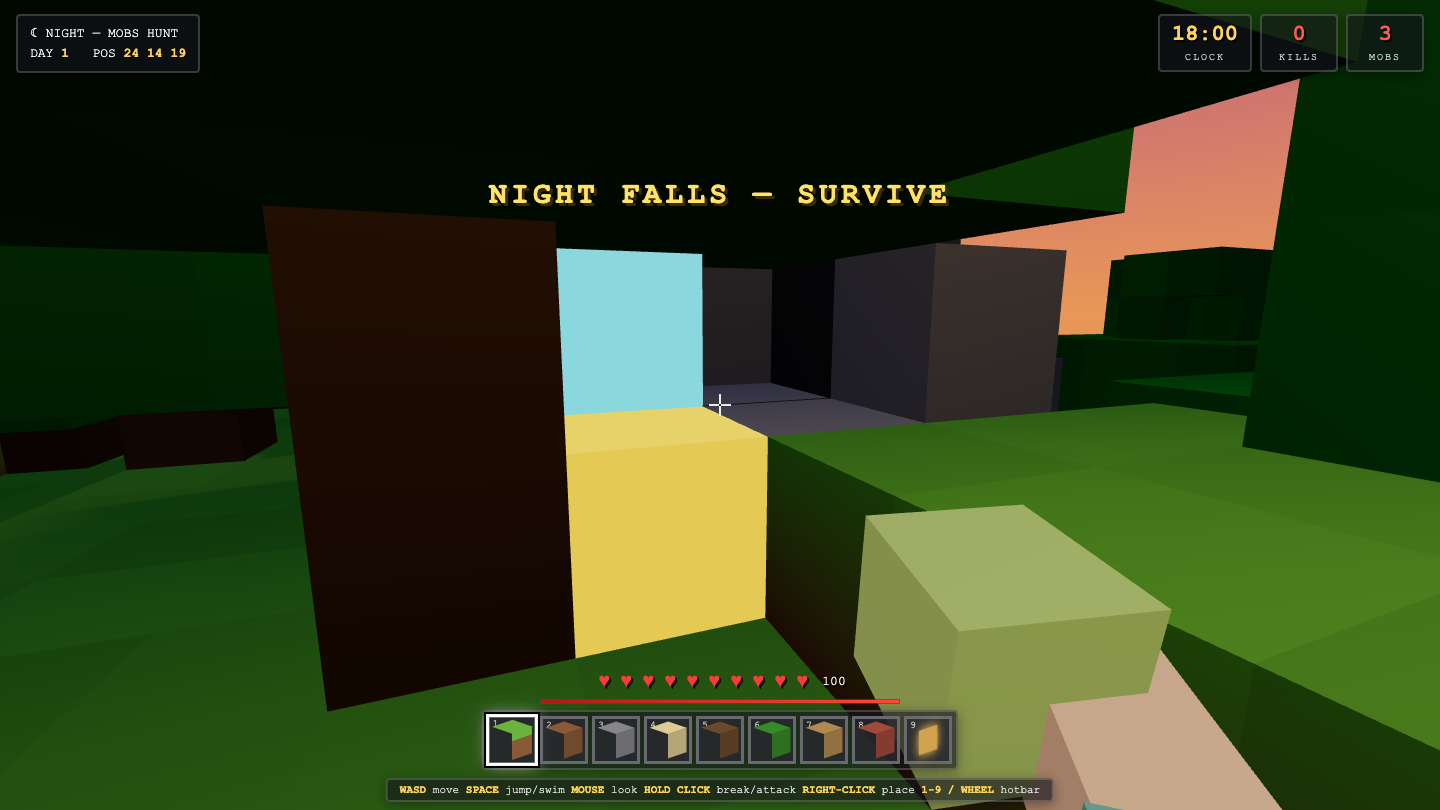
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
Claude Opus 5.5
Kimi K2.7 · Quality
Game
Game
Game
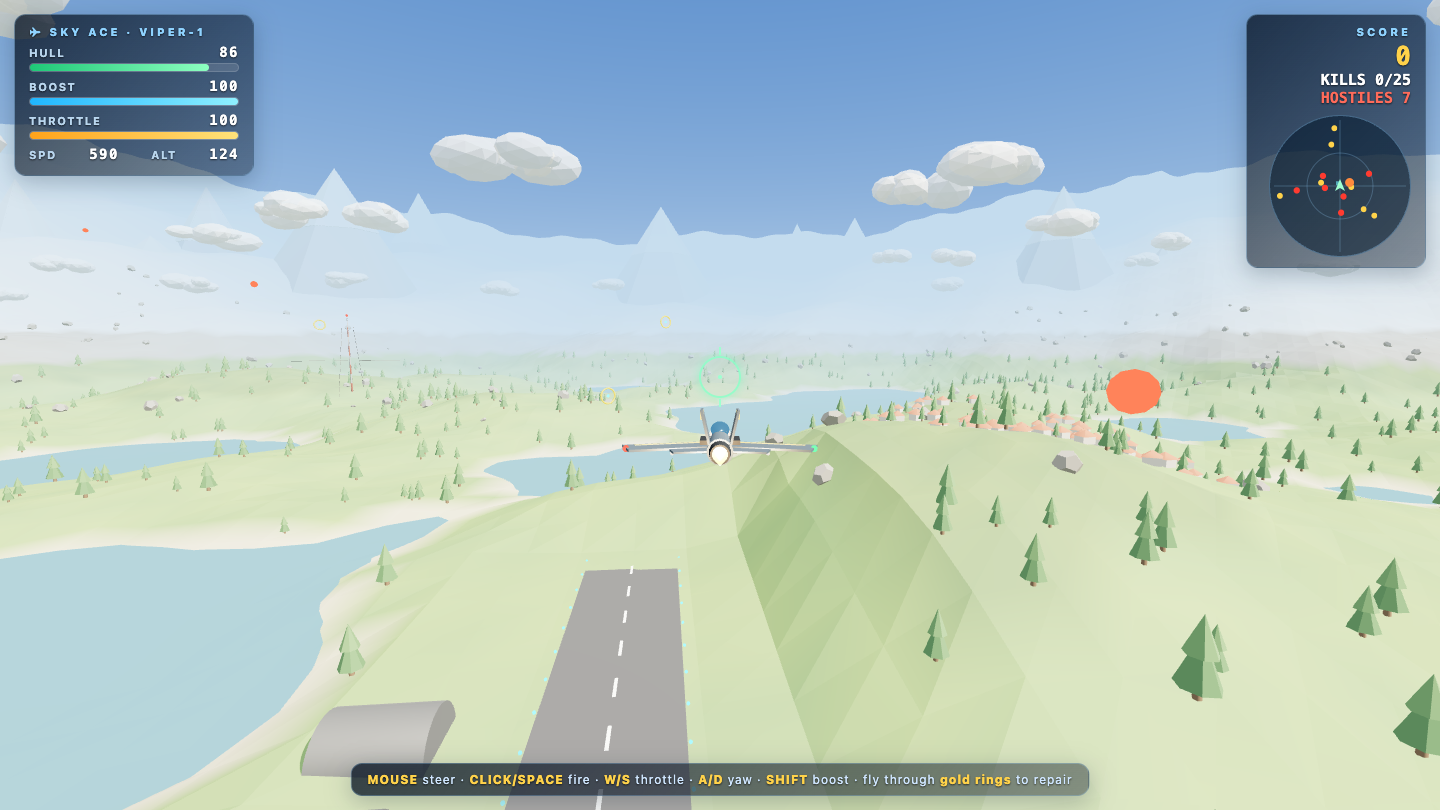
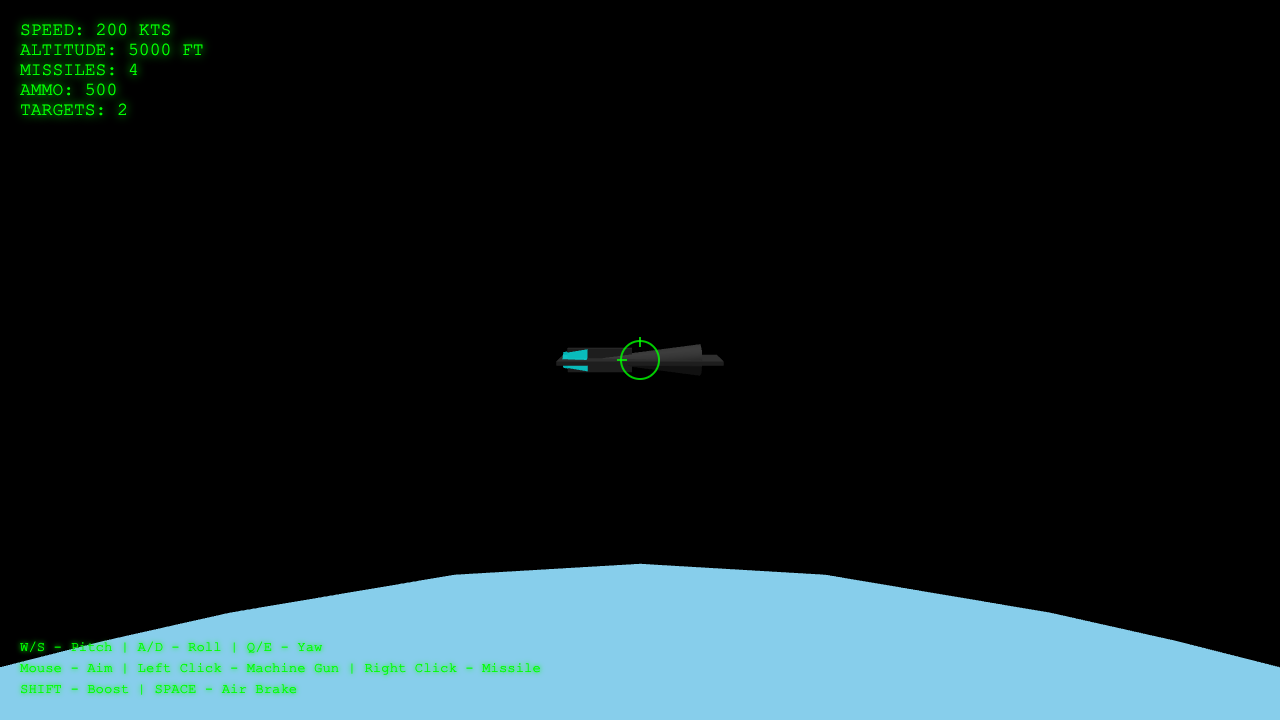
Game
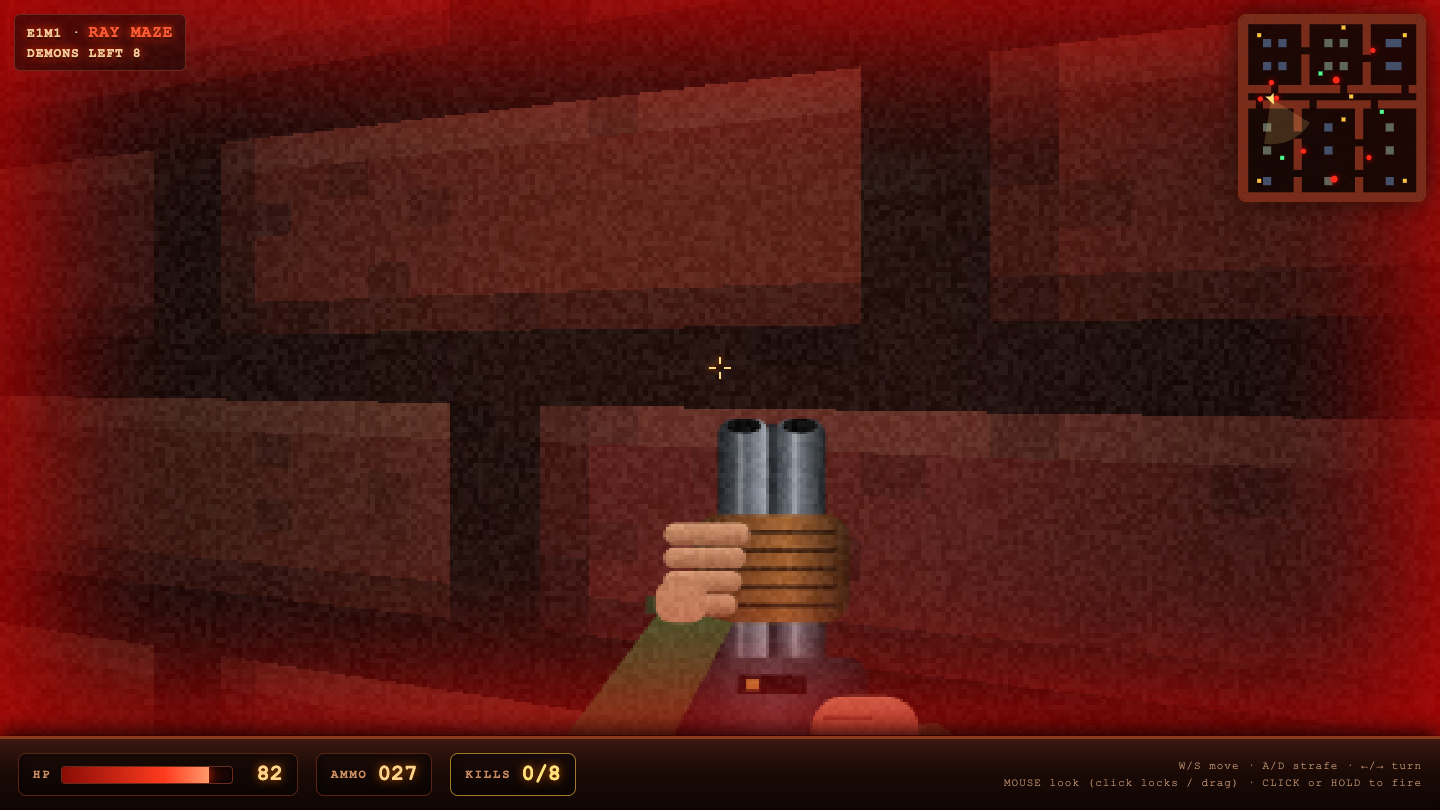
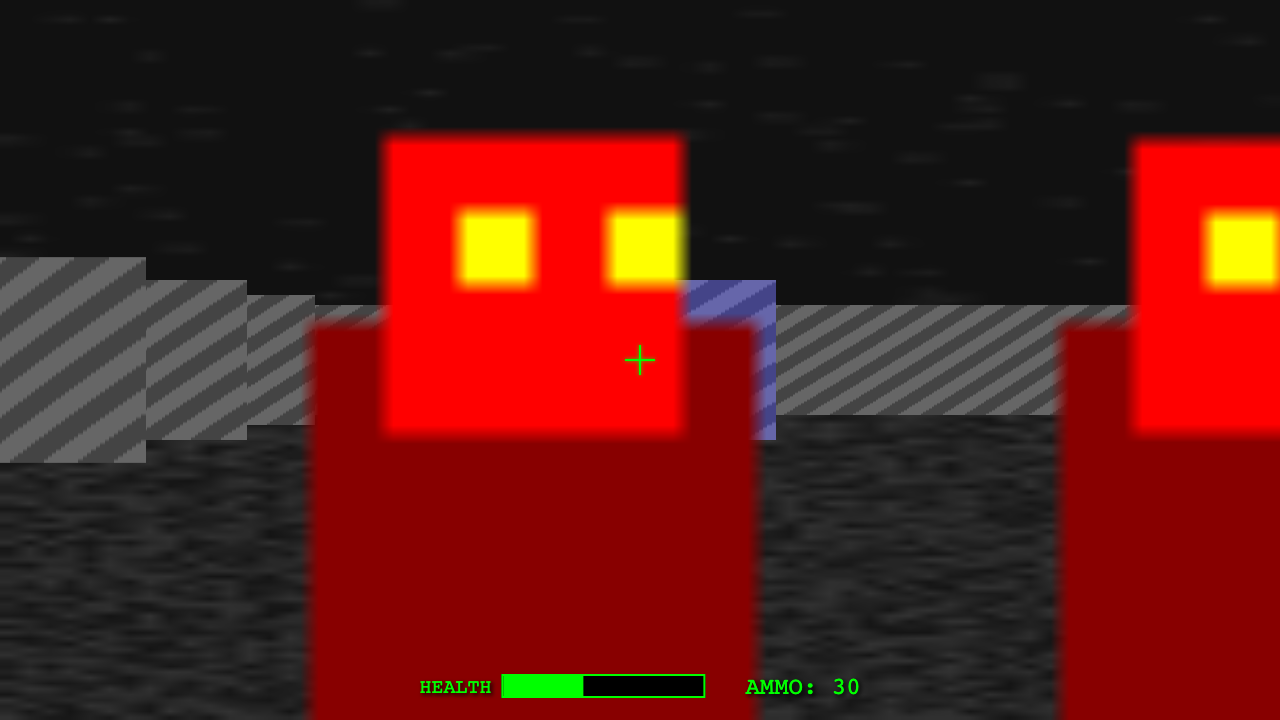
Game
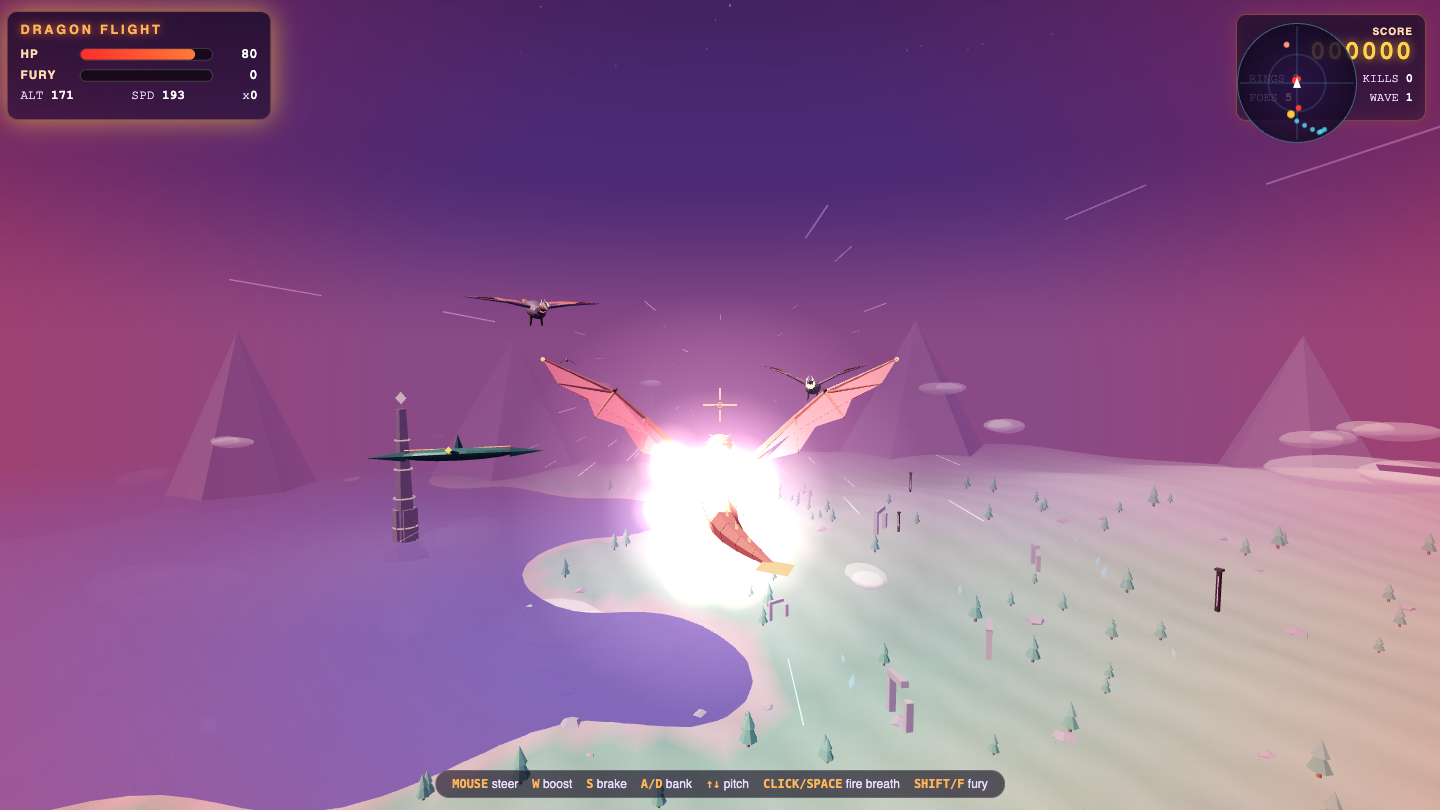
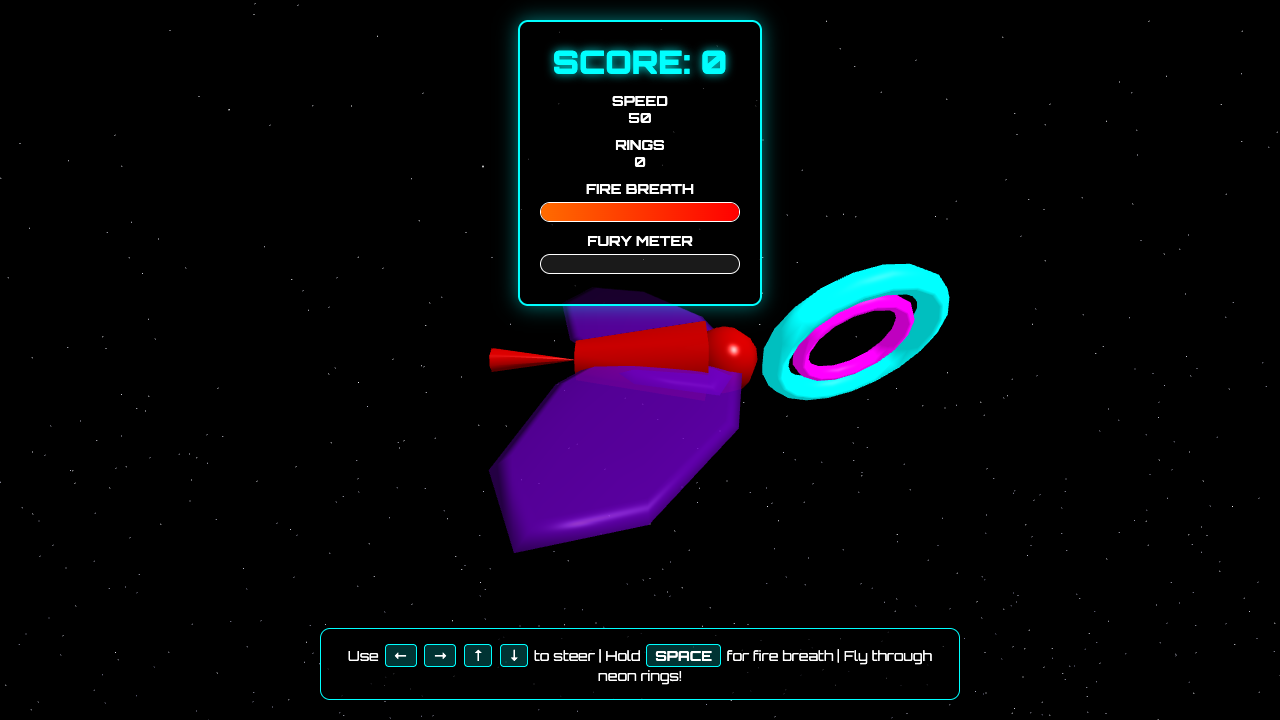
Game
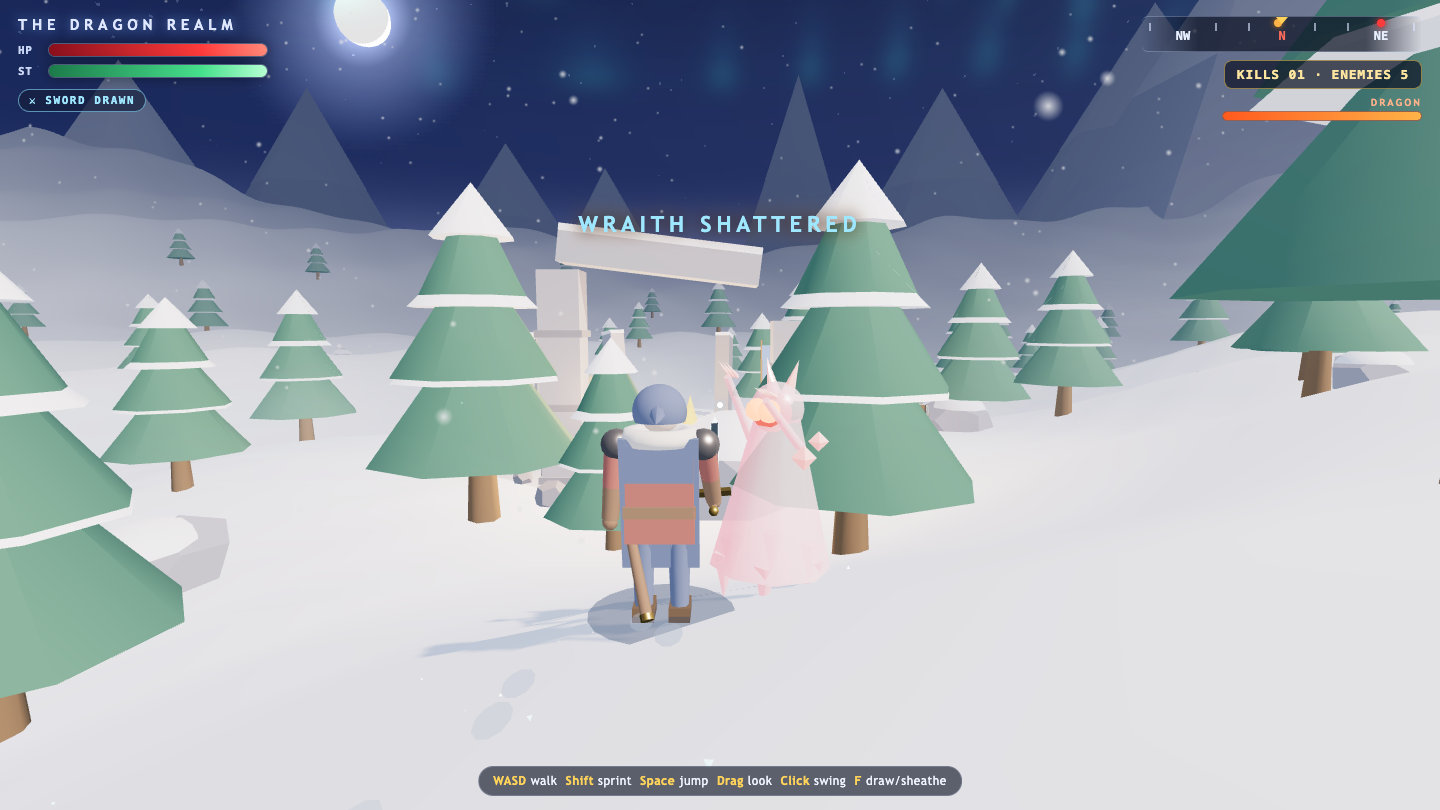
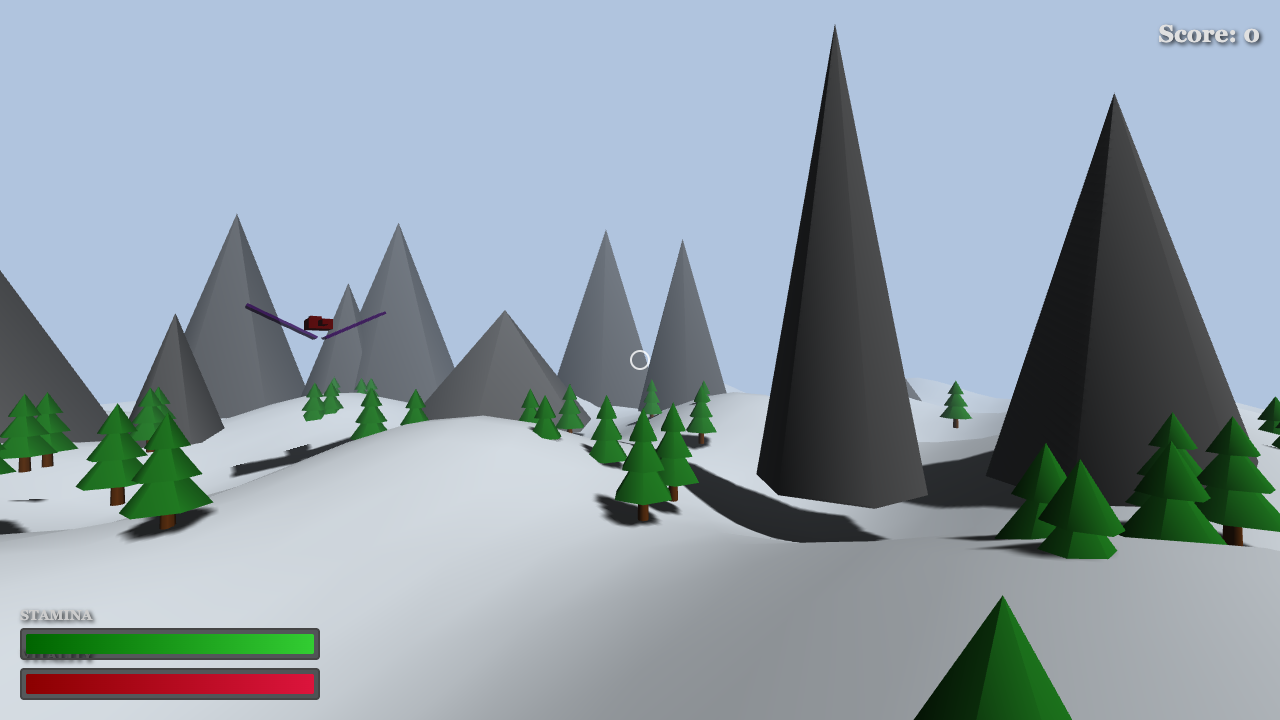
Game
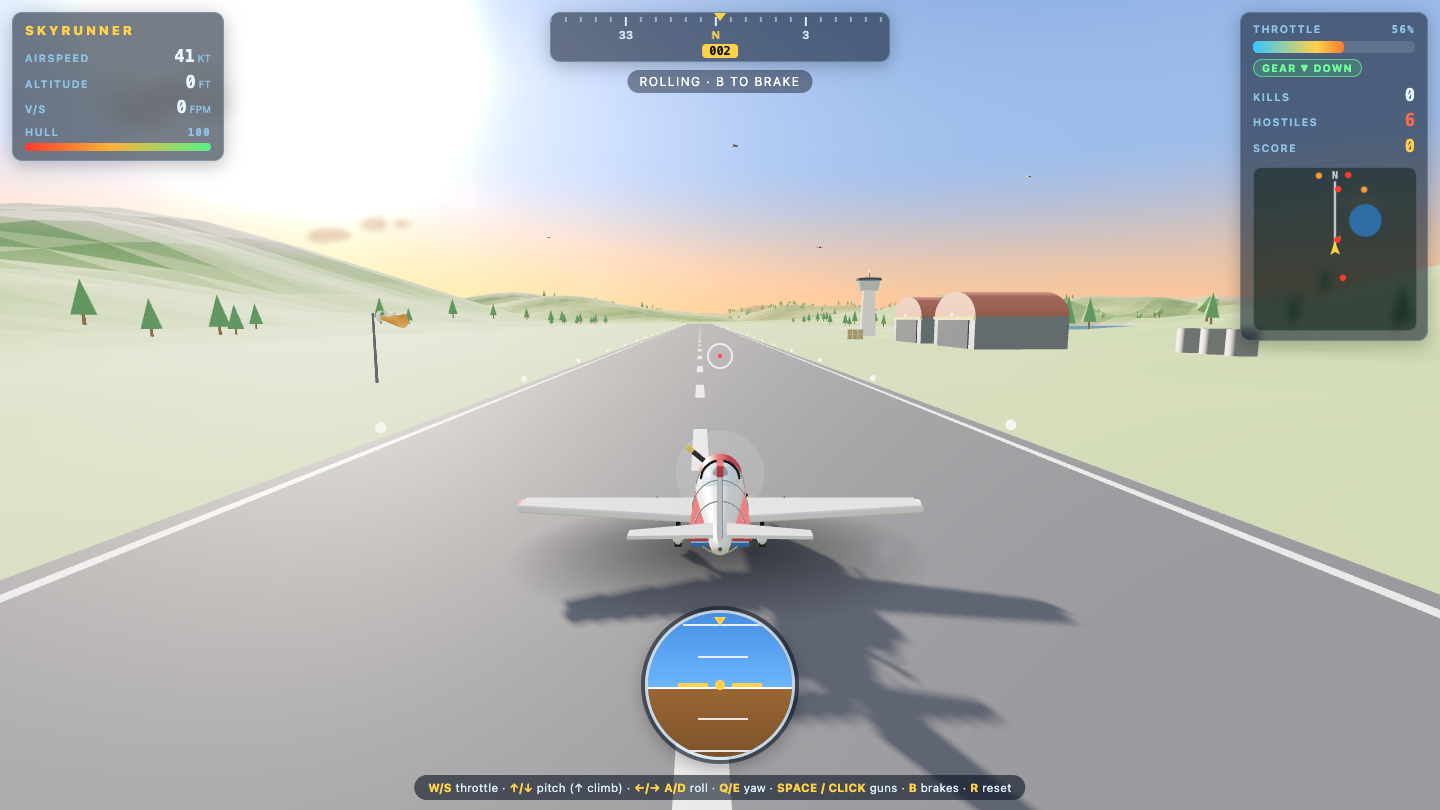
Game
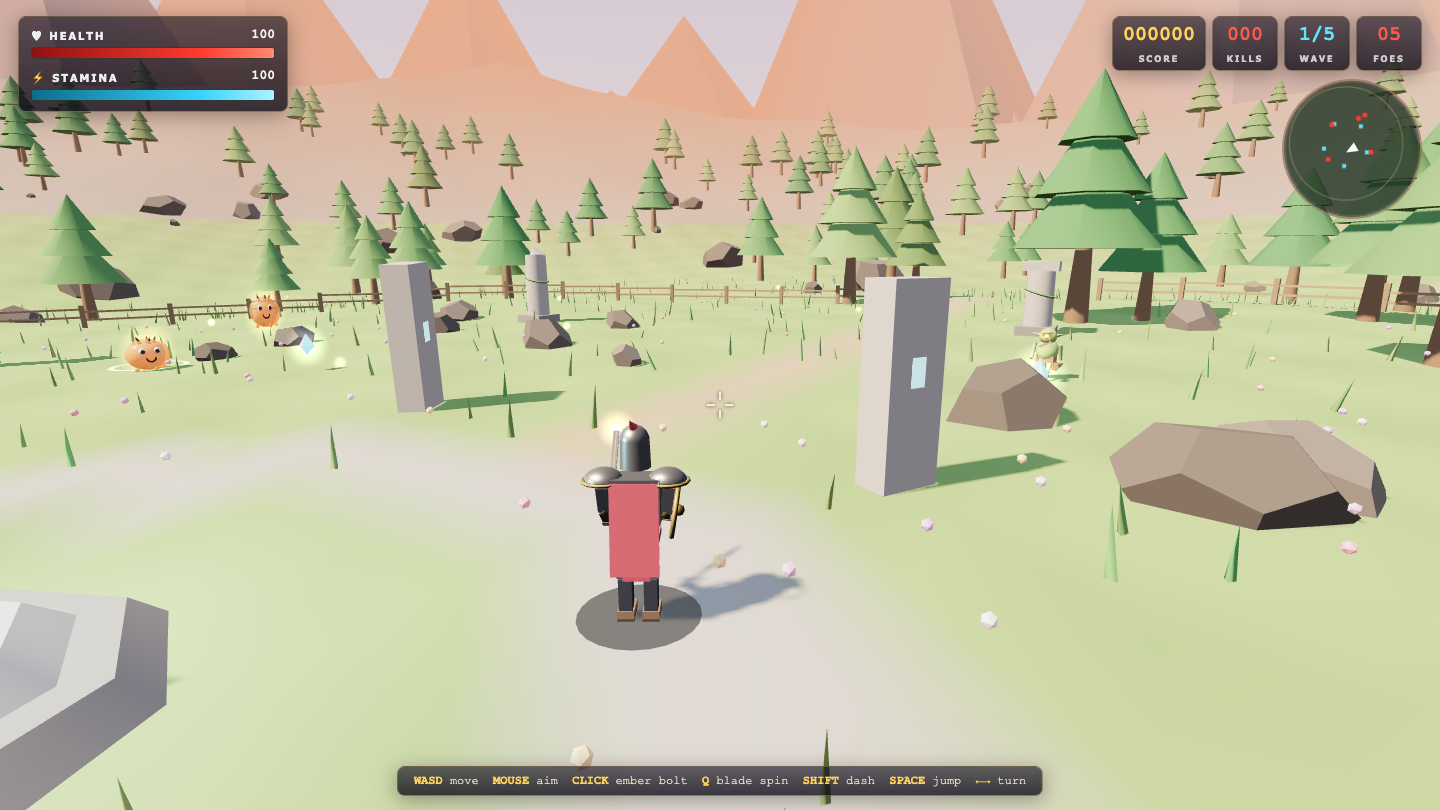
Game
Game
Game
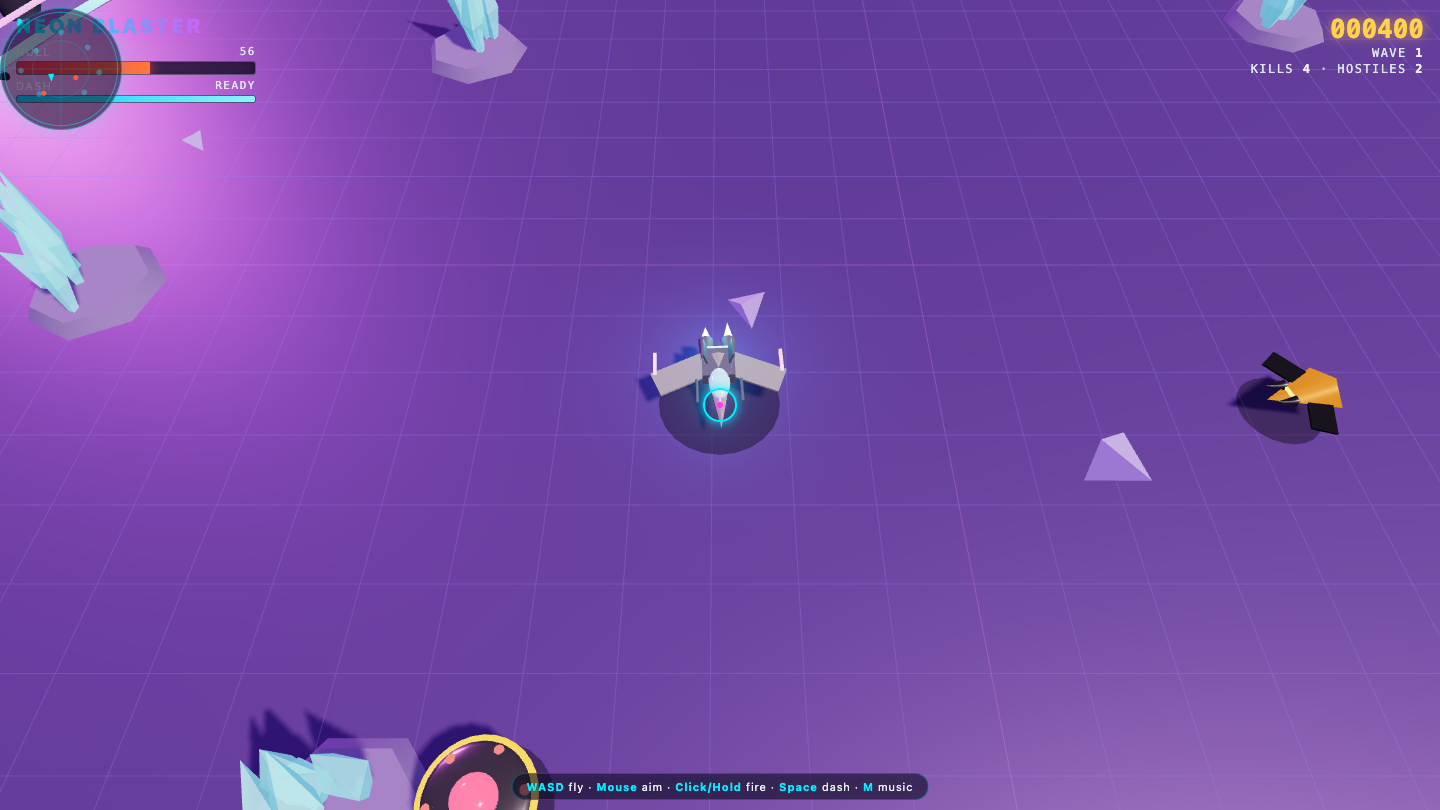
Game
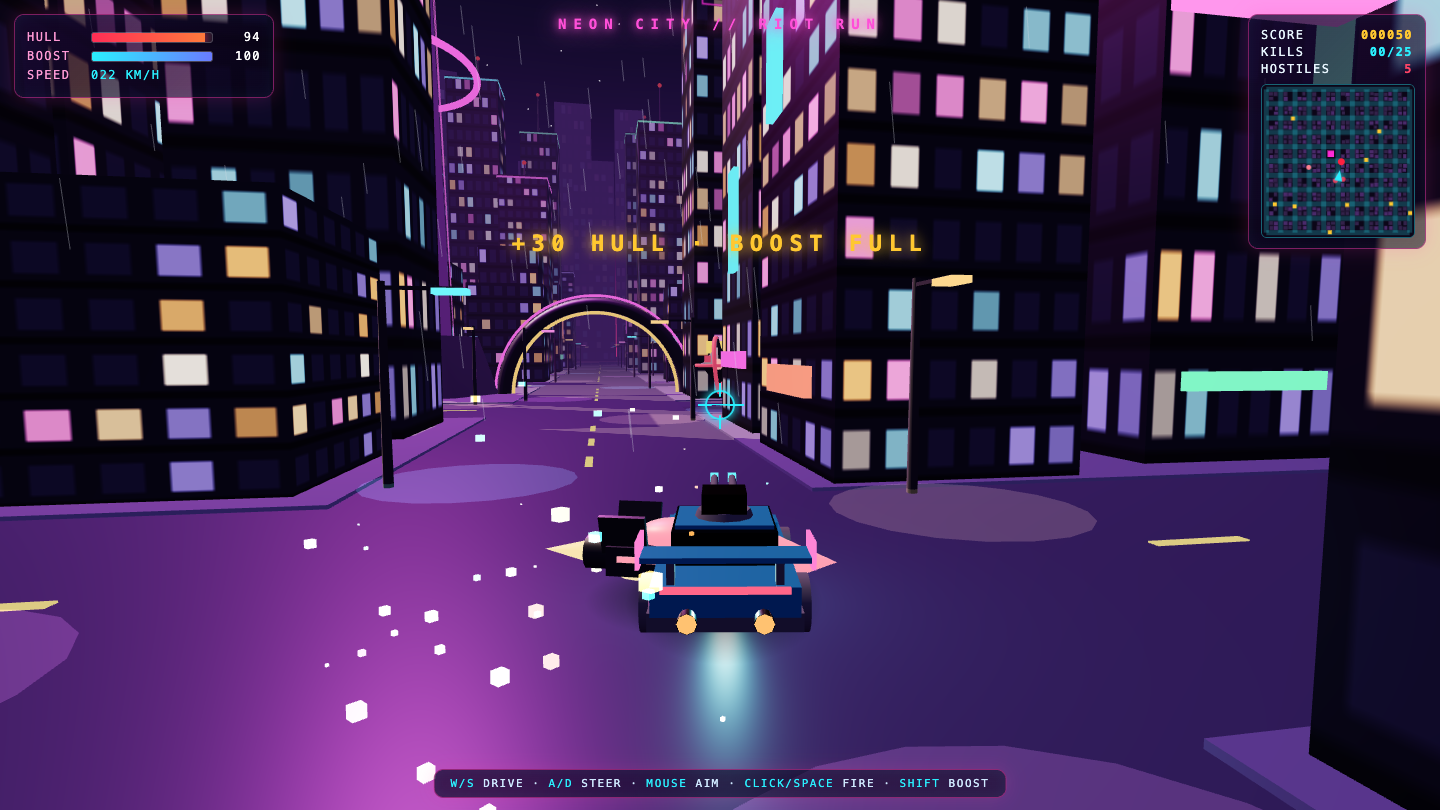
Game
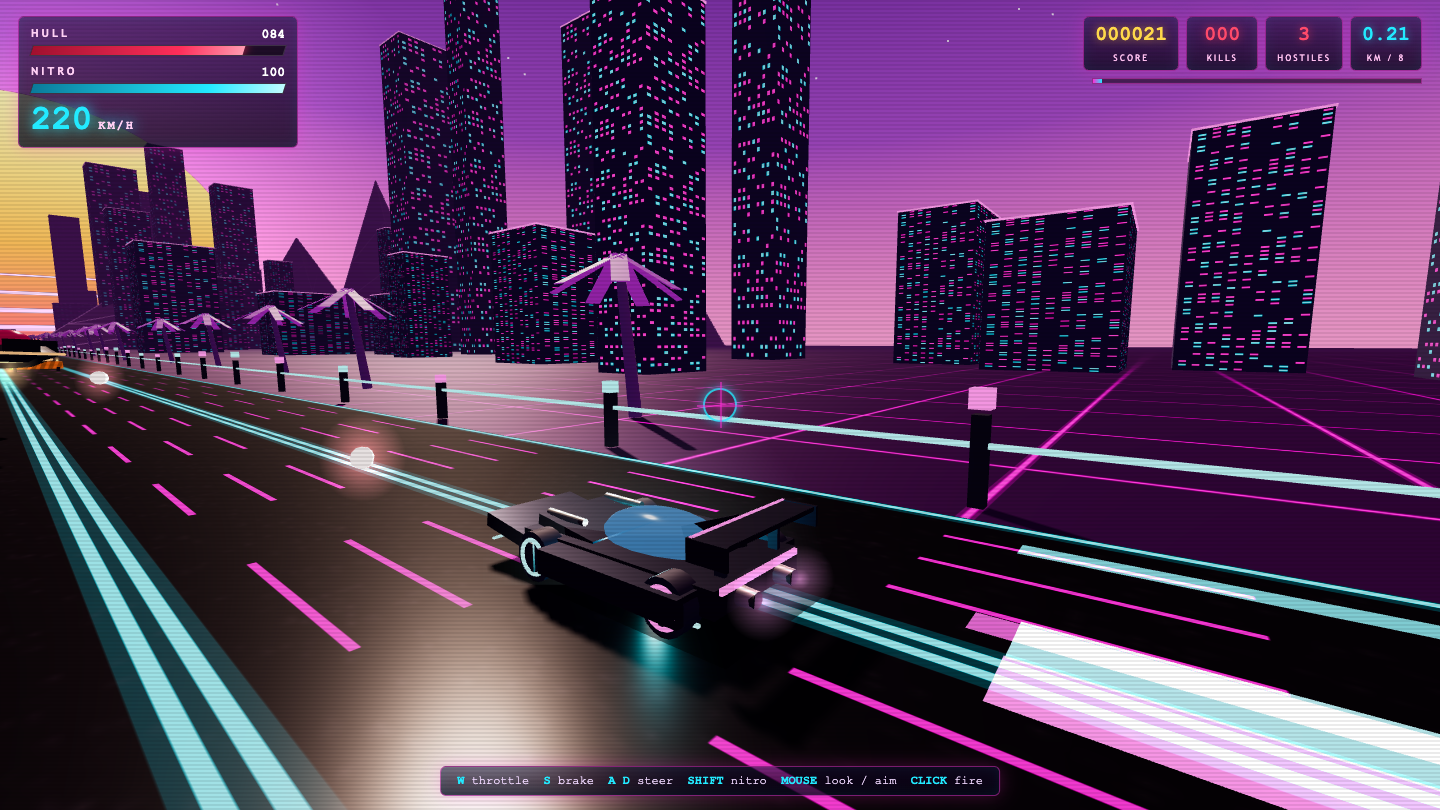
Game
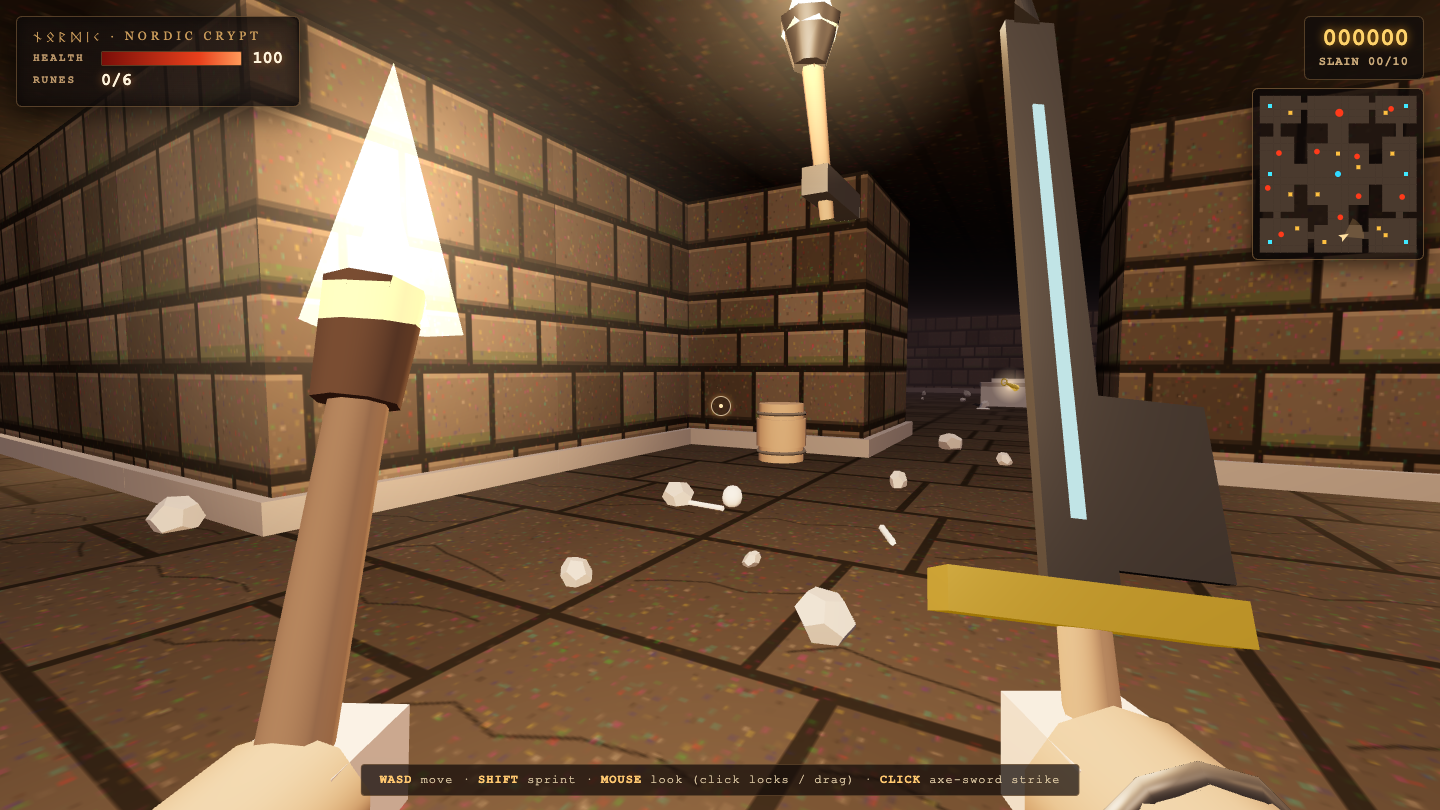
Game
Game
Game
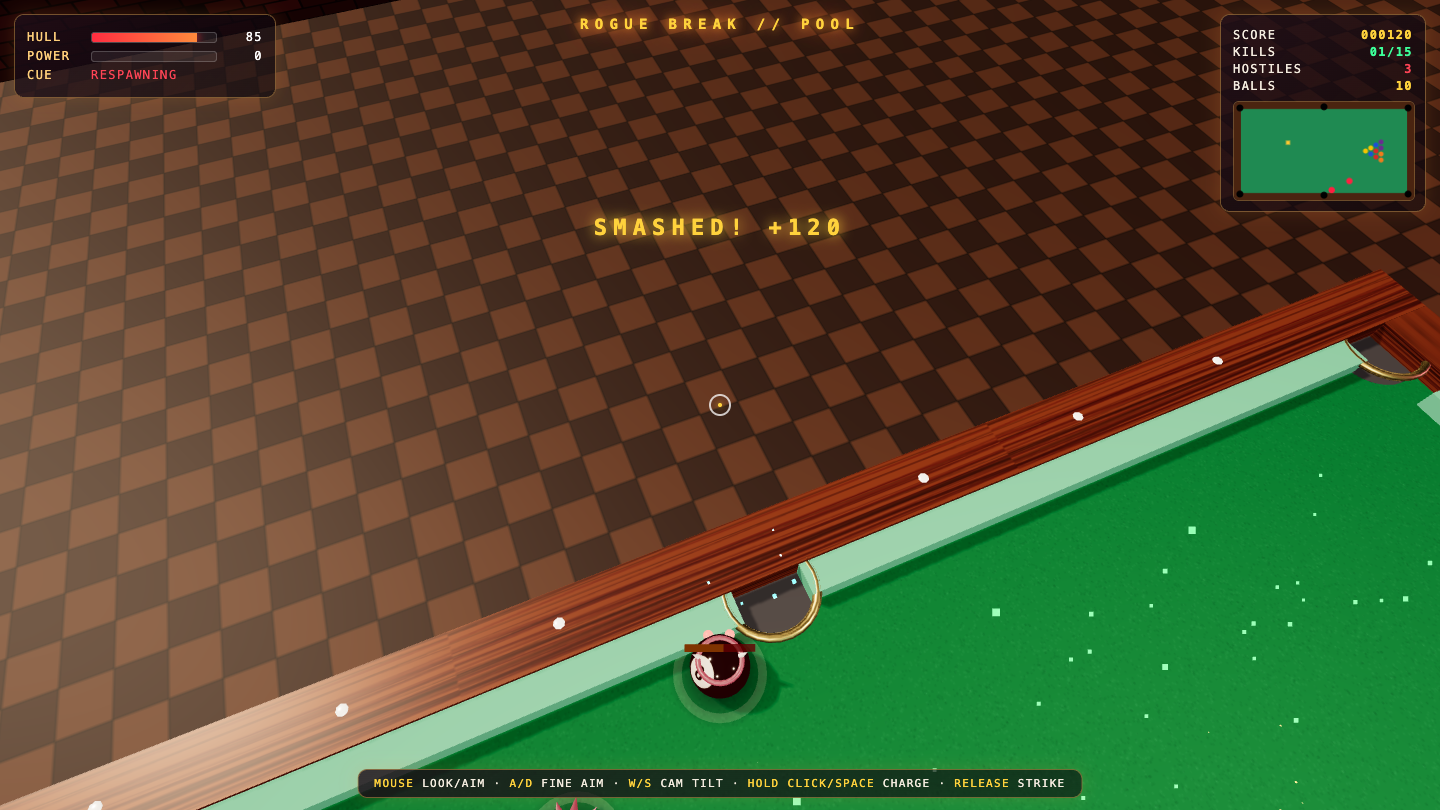
Game
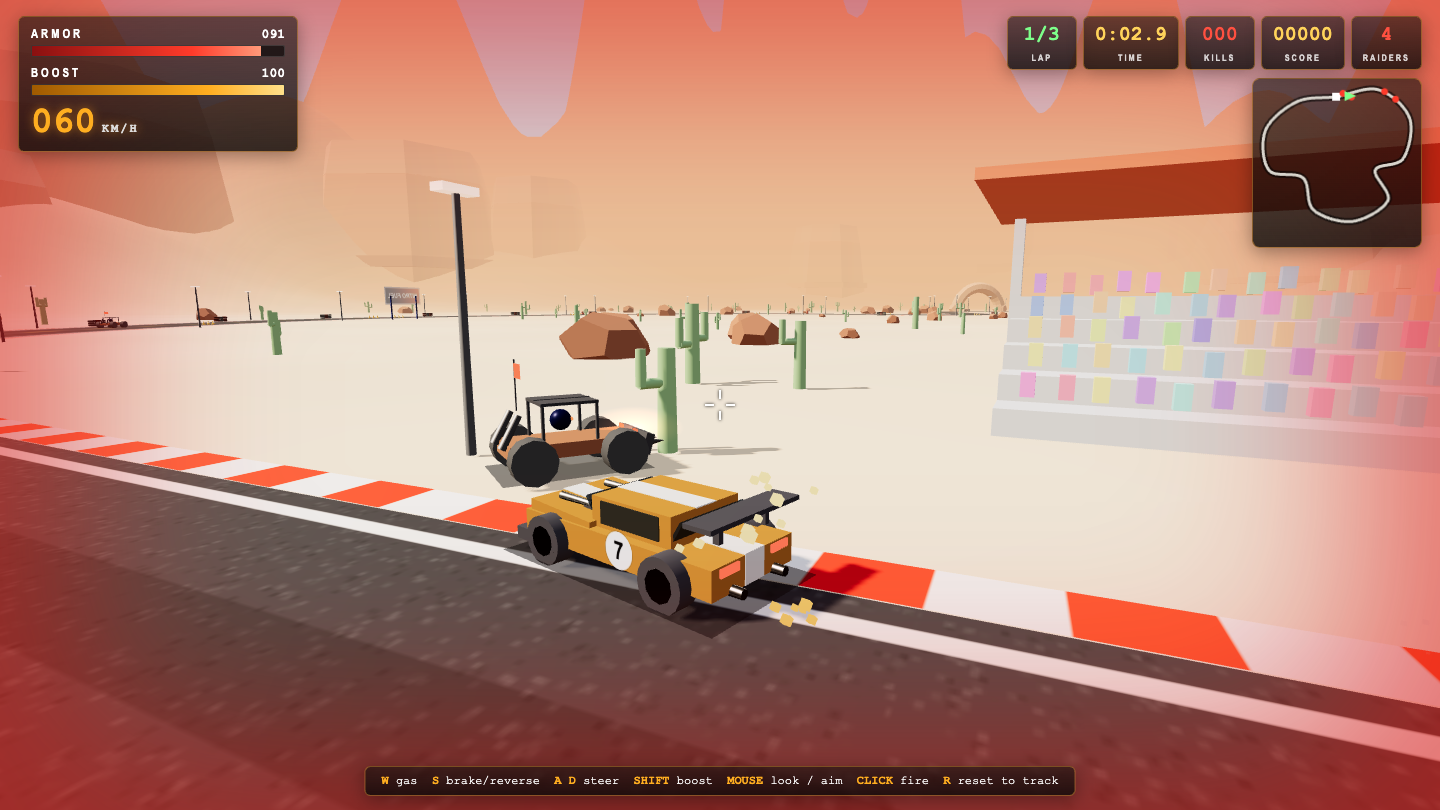
Game
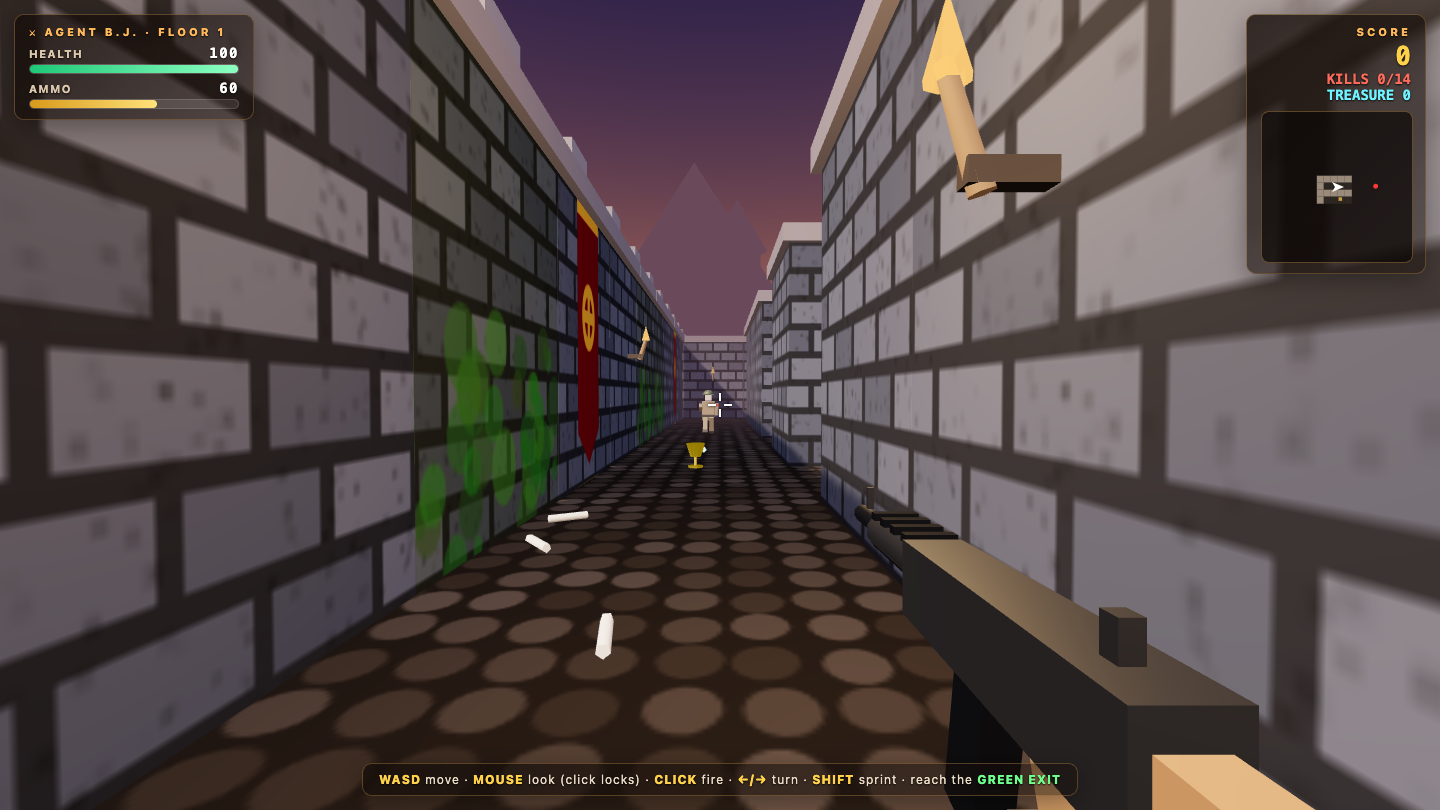
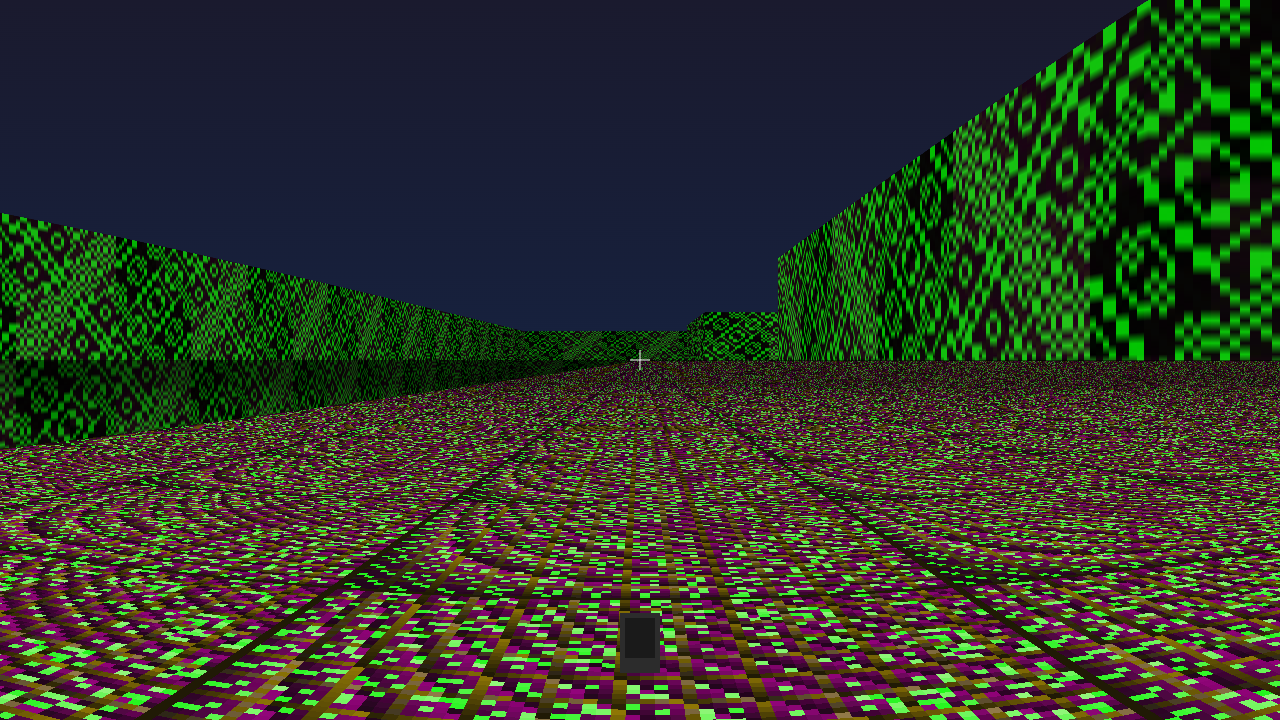
Game
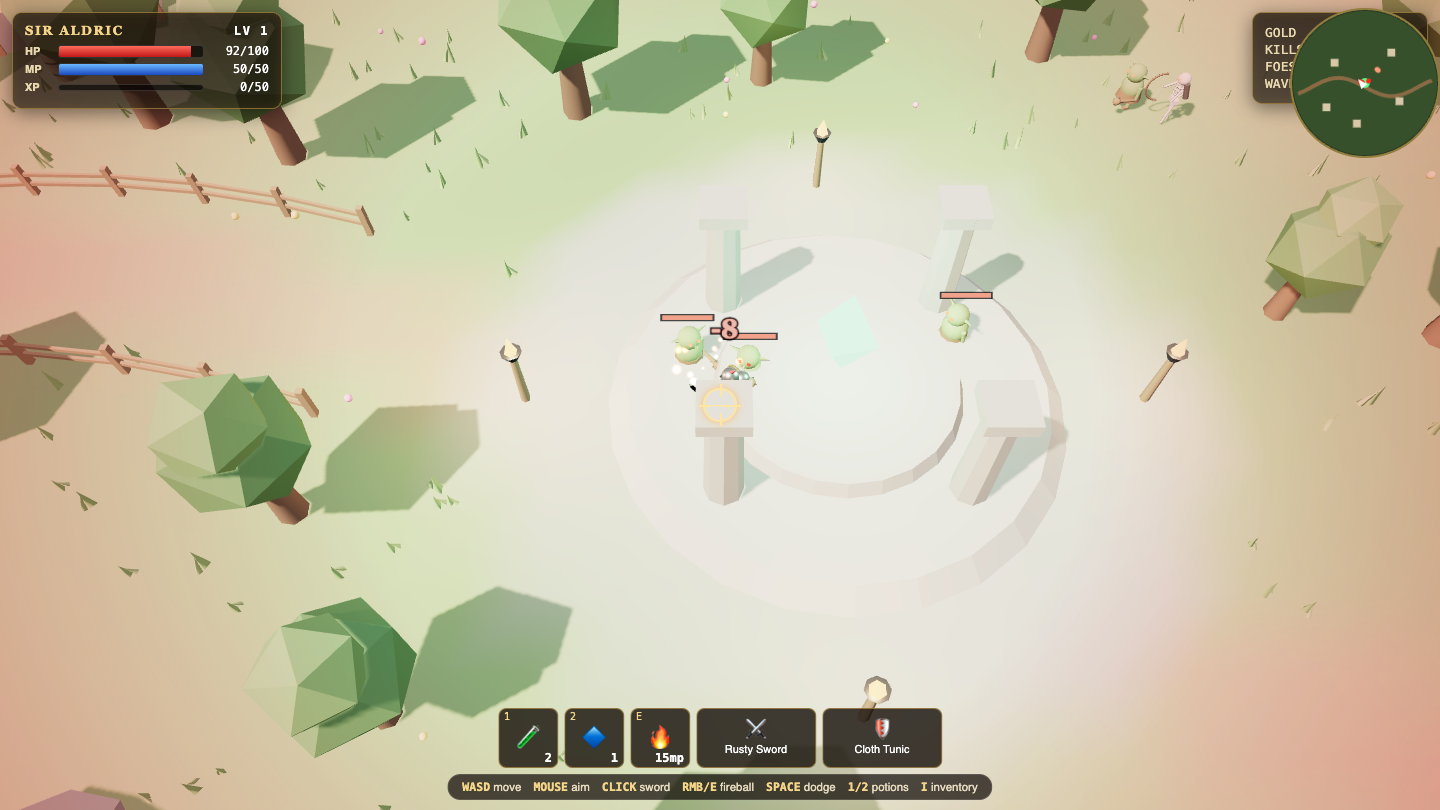
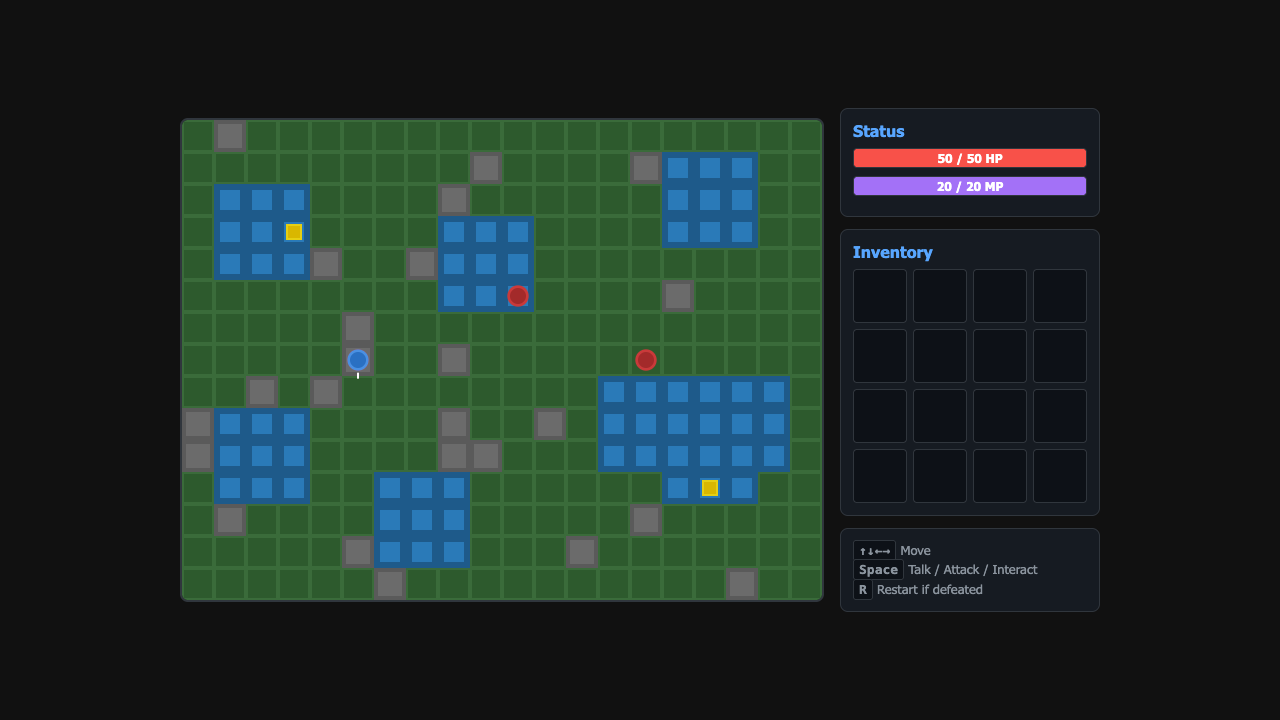
Game
Game
Game
Page
Strengths & weaknesses I logged
Claude Opus 5.5
Strengths
- Frontier-class coding + agentic reasoning (Claude 5 family)
- 1M-token context — reads an entire codebase in one call
- All 50 one-shot builds rendered with zero console errors; all 23 games passed the input playtest
Trade-offs
- Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes
- One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts)
Kimi K2.7 · Quality
Strengths
- Highest-effort reasoning path of the three Kimi modes
- Hand-tuned output polish on creative tasks
- Same flat-rate plan as Fast and No-Think — no premium
Trade-offs
- Slower than Fast and No-Think — not for snappy loops
- Not scored on the standalone bench — see methodology
Pricing & context — the spec sheet
| Spec | Claude Opus 5.5 | Kimi K2.7 · Quality |
|---|---|---|
| Vendor | Anthropic | Moonshot AI |
| Context window | 1,000,000 tokens | 256,000 tokens |
| Price | $4 / $20 per M | Flat plan (no per-token bill) |
| Pricing detail | Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. | Same flat-rate plan as standard Kimi K2.7 — Quality mode runs the deepest reasoning path. Vendor: Moonshot AI (moonshot.ai). |
| Release | 2026-09 | 2026-06 |
| Bench coverage | 50/50 scored · avg 7.57/10 | 0/47 scored · avg — |
The verdict — which should you pick?
Not enough scored shared tasks yet for a head-to-head average. The live demos for both are on the matrix above — play them and form your own opinion.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire Claude Opus 5.5 and Kimi K2.7 · Quality both into the Agent Operating System and dispatch each from the kanban by task type — hardest agentic builds → Claude Opus 5.5, one-shot games and sims where polish matters → Kimi K2.7 · Quality. That's the same setup I run for the 4,000+ founders inside the AI Profit Boardroom.
FAQ — Claude Opus 5.5 vs Kimi K2.7 · Quality
Which is better, Claude Opus 5.5 or Kimi K2.7 · Quality?
On Goldie Bench, Claude Opus 5.5 averages no scored verdicts yet across the shared tasks, with 0 gold, 0 silver, 1 bronze overall. Kimi K2.7 · Quality averages no scored verdicts yet, with 0 gold, 0 silver, 0 bronze. Not enough scored shared tasks yet to call a winner.
How much does Claude Opus 5.5 cost vs Kimi K2.7 · Quality?
Claude Opus 5.5: Anthropic's Opus 5.5 — 1M-token context, listed at $4 input / $20 output per million tokens. Benched through a Claude subscription; game tasks use our skill-infused AAA build prompts. Kimi K2.7 · Quality: Same flat-rate plan as standard Kimi K2.7 — Quality mode runs the deepest reasoning path. Vendor: Moonshot AI (moonshot.ai).
What's the context window for Claude Opus 5.5 vs Kimi K2.7 · Quality?
Claude Opus 5.5 has a 1,000,000 tokens context window. Kimi K2.7 · Quality has a 256,000 tokens context window.
When should I pick Claude Opus 5.5 over Kimi K2.7 · Quality?
Pick Claude Opus 5.5 for: Hardest agentic builds; Whole-repo reasoning; Frontier one-shots. The trade-off is the weaknesses we logged on the bench: Premium pricing ($4/$20 per M) — route the everyday 90% to cheaper lanes; One-shot builds can still ship logic bugs (e.g. a doom kill counter that miscounts).
When should I pick Kimi K2.7 · Quality over Claude Opus 5.5?
Pick Kimi K2.7 · Quality for: One-shot games and sims where polish matters; Creative writing where you want the model to slow down; Final-pass refinement of an earlier draft. The trade-off is the weaknesses we logged on the bench: Slower than Fast and No-Think — not for snappy loops; Not scored on the standalone bench — see methodology.
How does Goldie Bench score Claude Opus 5.5 vs Kimi K2.7 · Quality?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
Claude Opus 5.5 vs Fusion Kimi K2.7 · Quality vs Fusion Claude Opus 5.5 vs Claude Opus 5 Kimi K2.7 · Quality vs Claude Opus 5 Claude Opus 5.5 vs Hermes MoA Kimi K2.7 · Quality vs Hermes MoA Claude Opus 5.5 vs GPT-5.6 Sol Kimi K2.7 · Quality vs GPT-5.6 SolFull model pages: Claude Opus 5.5 · Kimi K2.7 · Quality · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.
4,000+founders
258documented wins
38countries
$59/momonthly