Real head-to-head · same prompt, one shot
Fugu Ultra 1.1 vs MiMo-V2.6 Pro
Sakana's multi-agent orchestrator, v1.1 — routes experts per request. vs Open weights that score level with Opus 5 on agents, for cents.
Head-to-head verdict: Fugu Ultra 1.1 wins 13–8 with 2 ties.
What I tested — same prompt, two models
I run the same fixed prompt set through every new model the day it drops — same string, one shot, single HTML file out — and I score the result 0–10 on whether it ran, how close it hit the brief, and how good it looked. Below is what came out when I gave the exact same prompts to Fugu Ultra 1.1 and MiMo-V2.6 Pro, side by side, on 24 shared tasks inside the Agent Operating System.
Both models were given identical prompts inside the Agent Operating System — no help, no iteration, no "best of N" tricks. I run each prompt once, save the HTML file the model produces, and score it 0–10 on whether it ran, how close it hit the brief, and how good it looked. The scoring is mine. The verdicts below are pulled from my source comparison guides at agentos.guide where I publish every score and the reasoning behind it.
Fugu Ultra 1.1 · Benched on GoldieBench via Sakana's Responses API (fugu-ultra-v1.1, xhigh reasoning). Game tasks use the skill-infused threejs-game-director prompt plus a controls+graphics fix loop with an anti-regression clamp, judged on a real mid-play frame by the same Opus judge as the field.
MiMo-V2.6 Pro · Benched on all 50 GoldieBench tasks through OpenRouter at the model's default reasoning effort: one-shot build, real rendered poster, Opus 4.8 vision judge, game tasks skill-infused. No retries, no hand fixes; the broken builds are scored as they shipped.
Side-by-side on 50 shared tasks
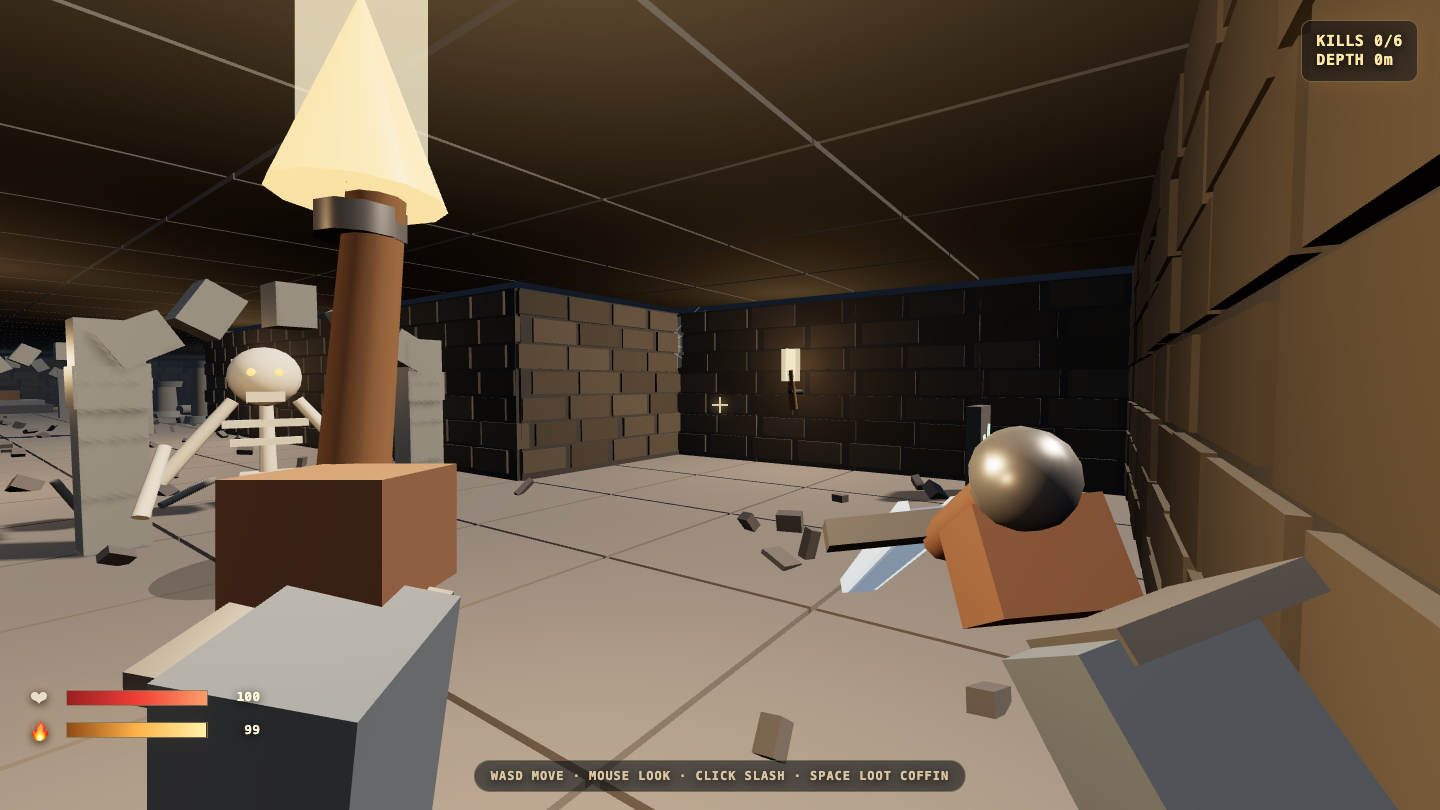
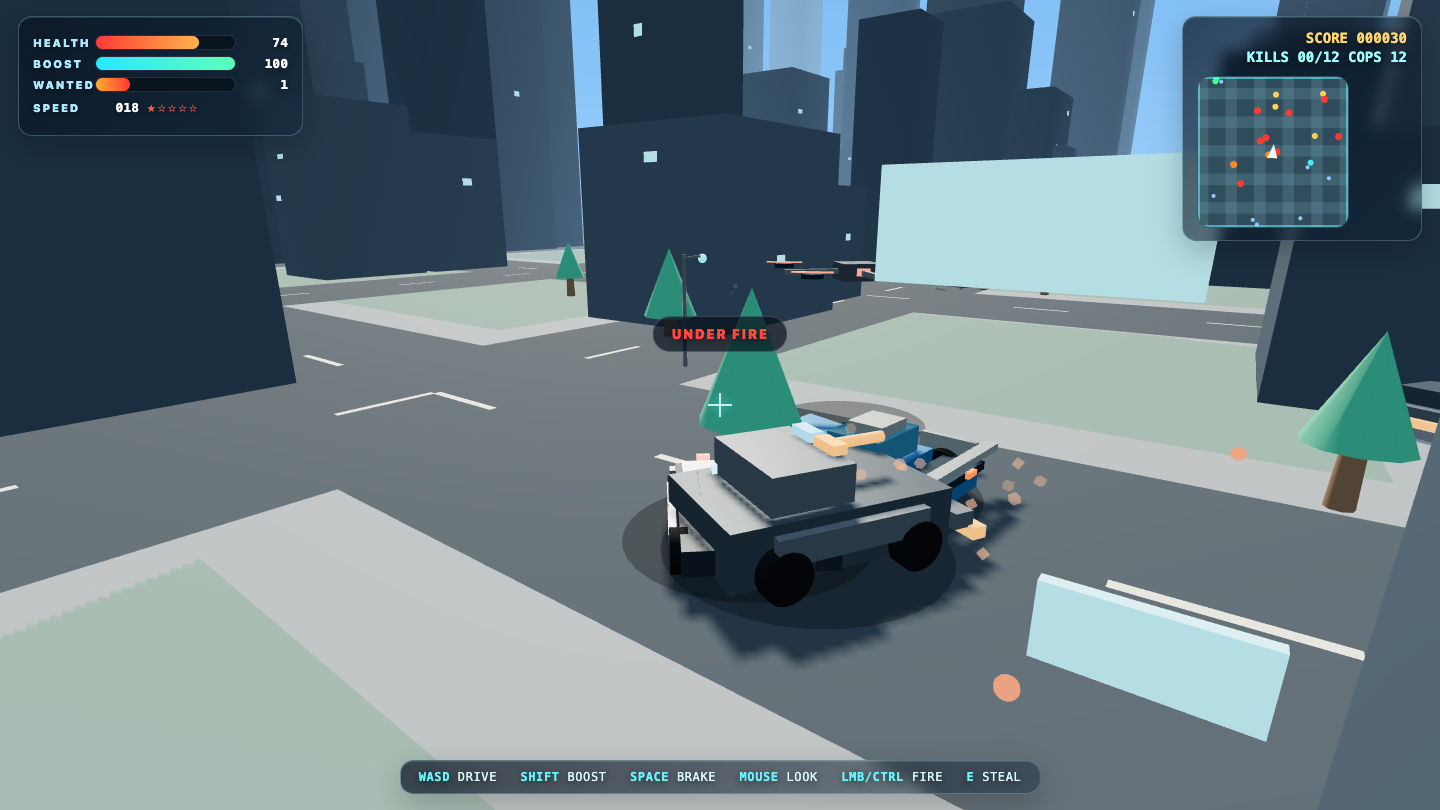
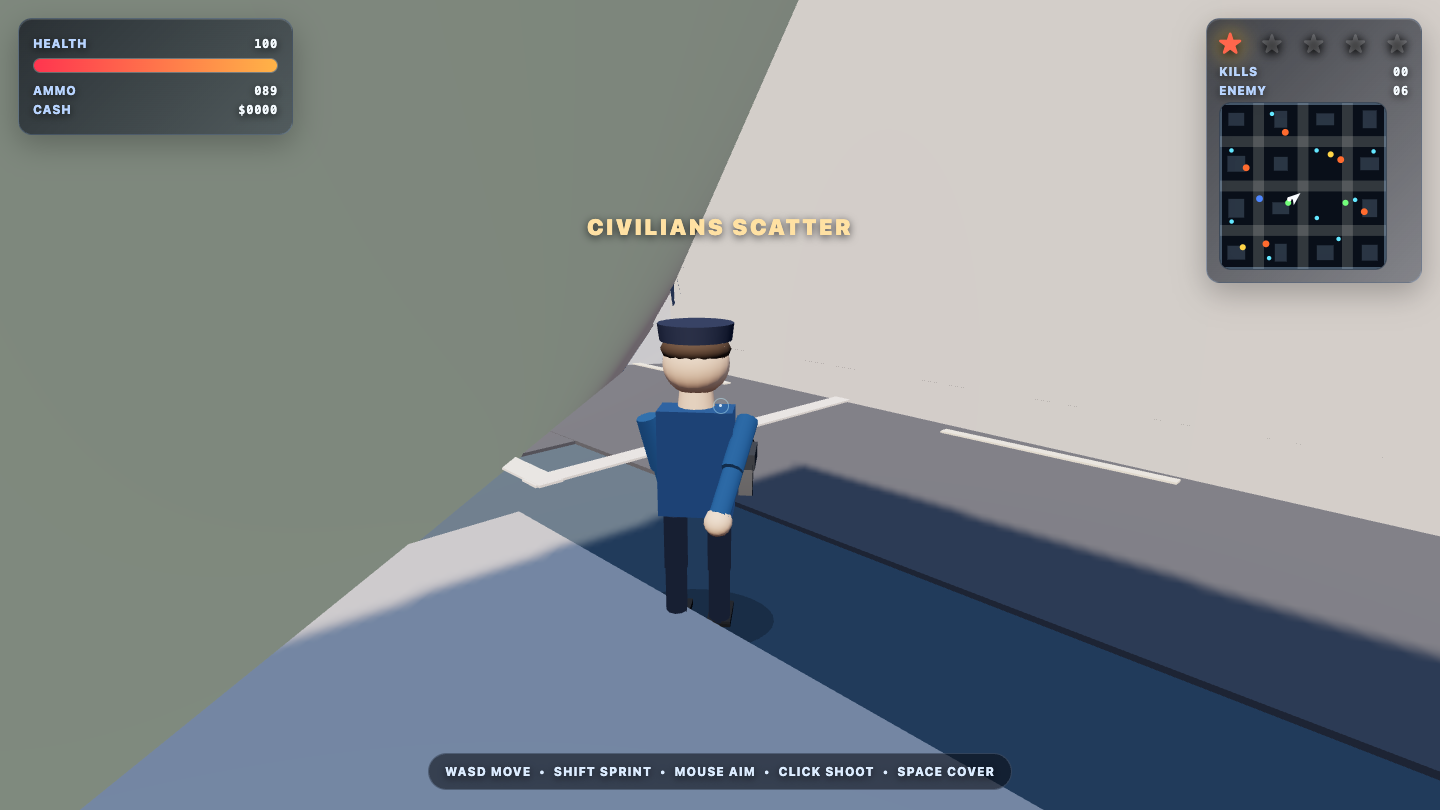
Click any cell to play that model's actual one-shot attempt. Medals are derived from my 0–10 scores per task (highest = 🥇, second = 🥈, third = 🥉).
Task ↓
Fugu Ultra 1.1
MiMo-V2.6 Pro
Game
Game
Game
Game
Game
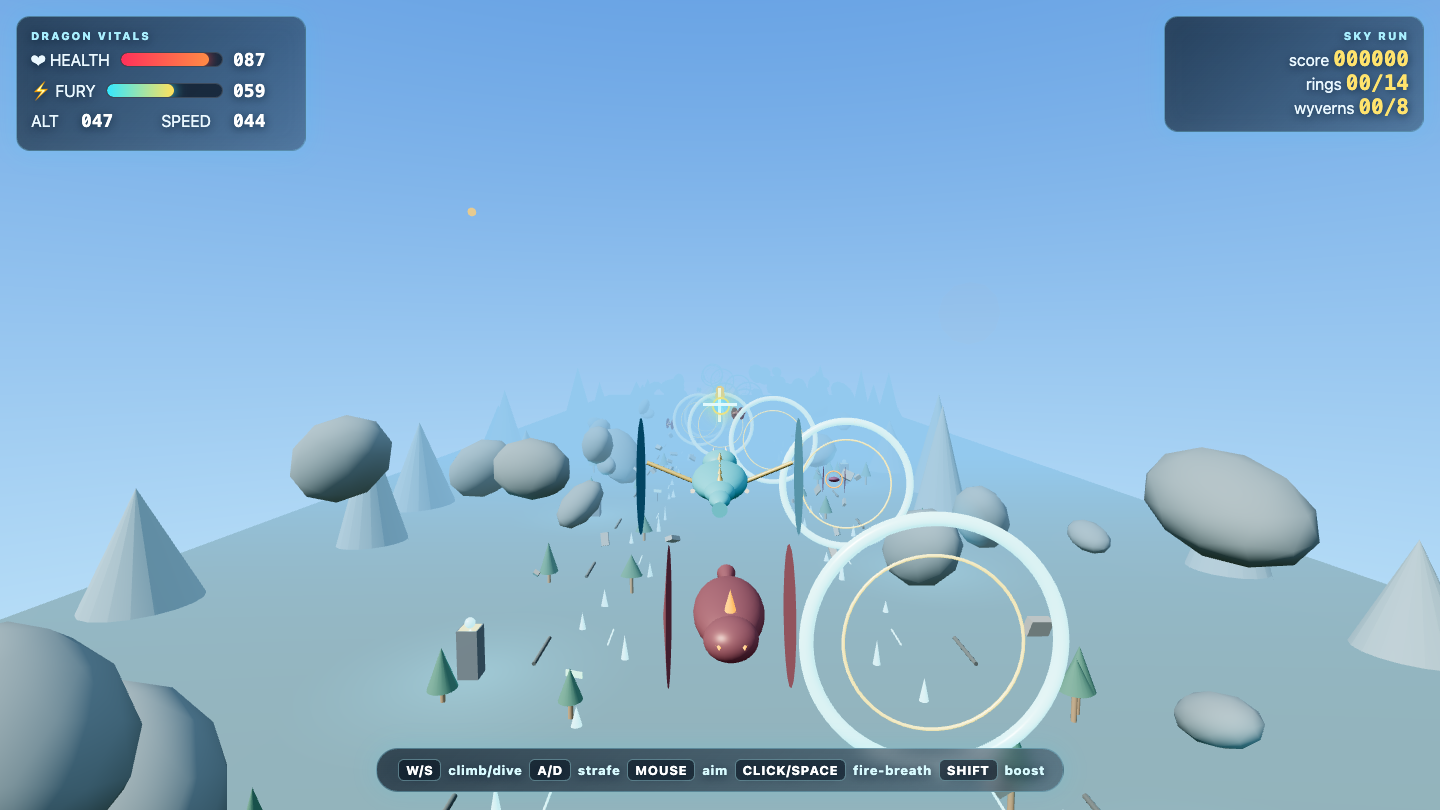
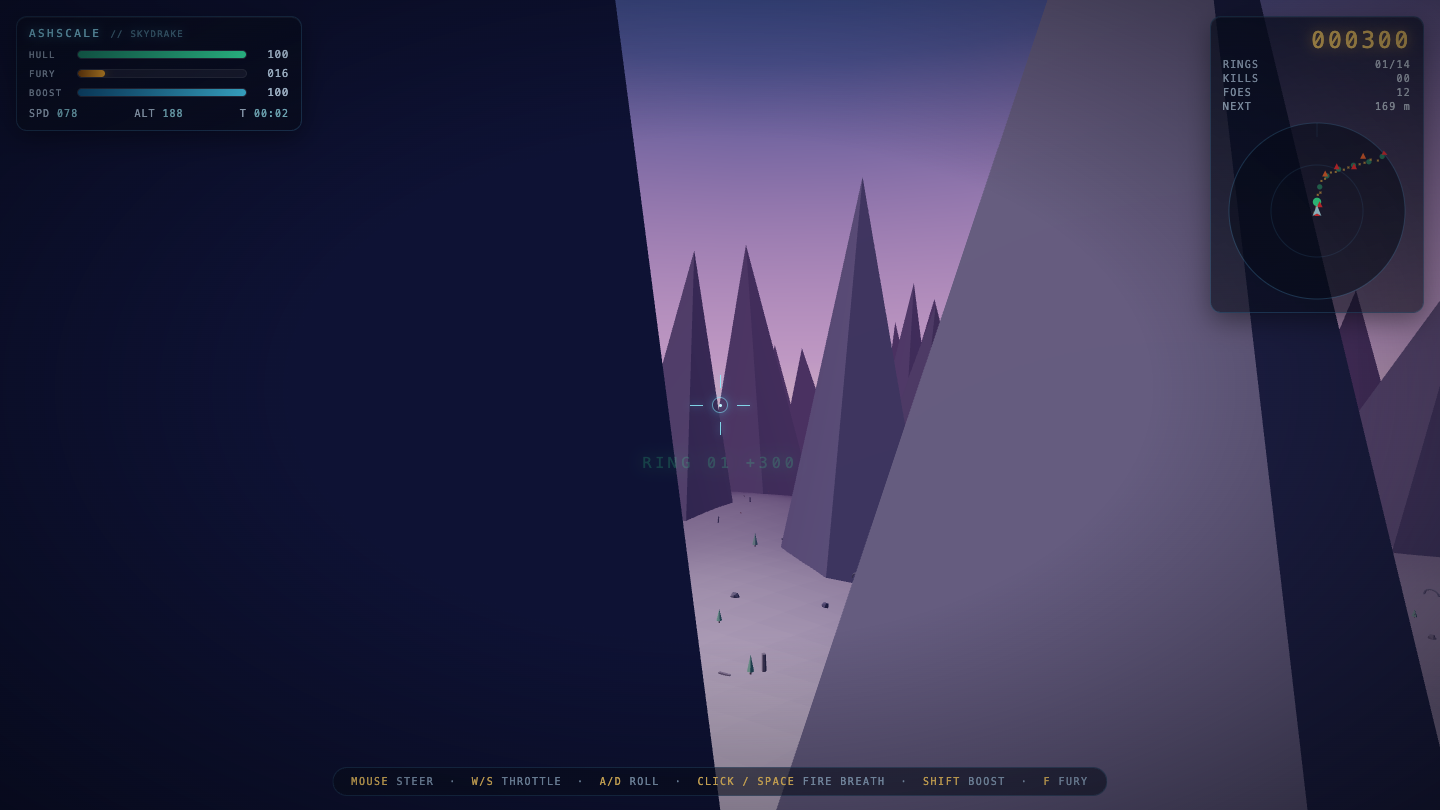
Game
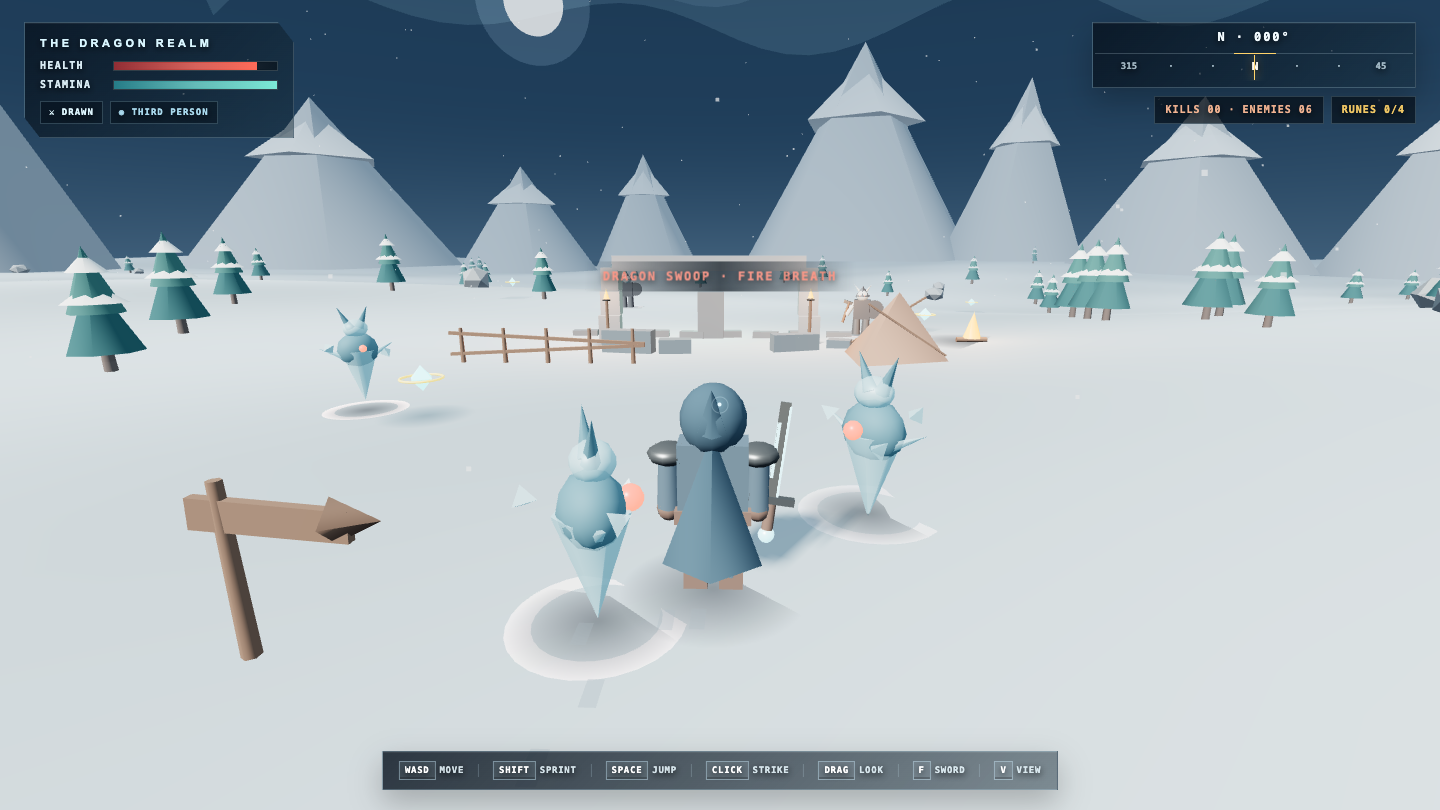
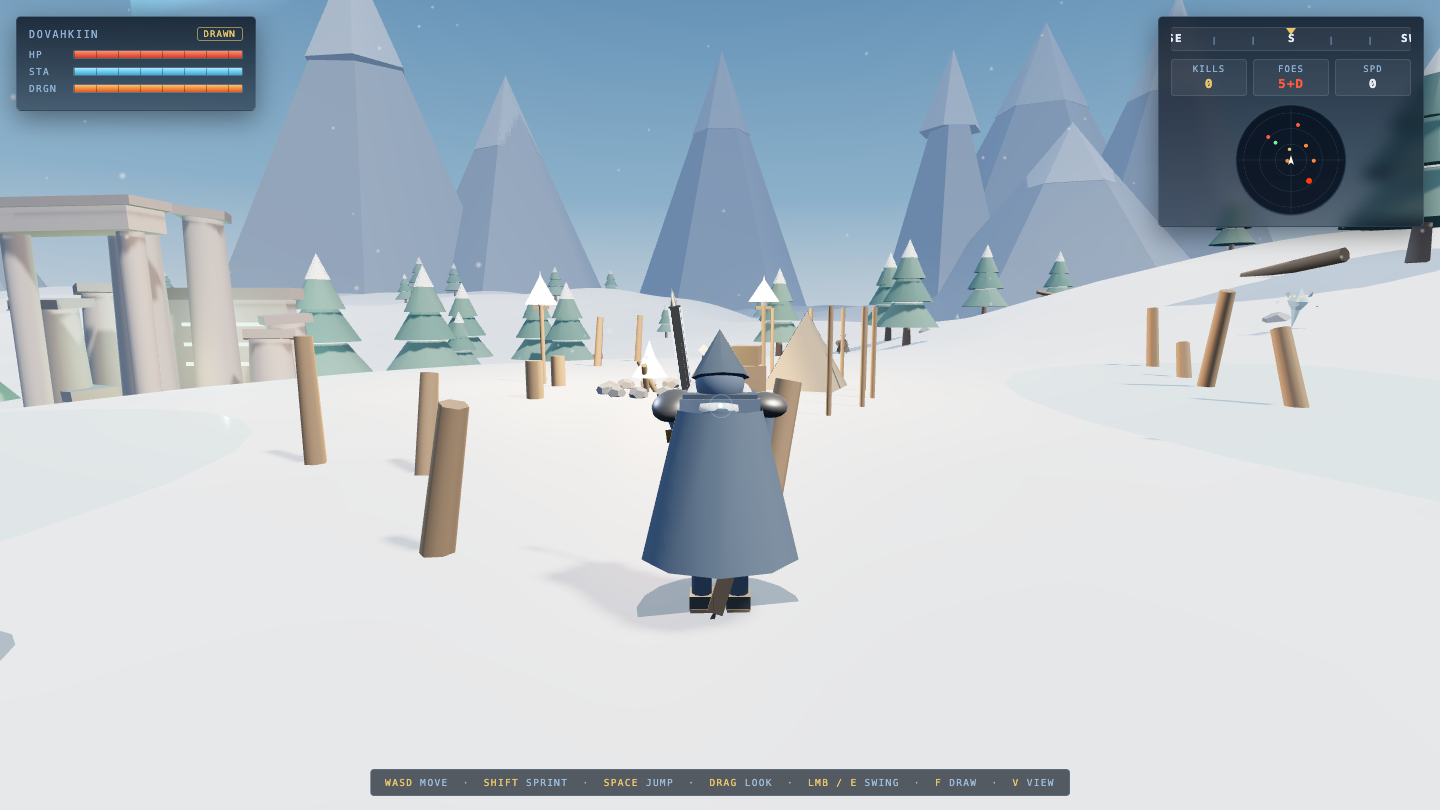
Game
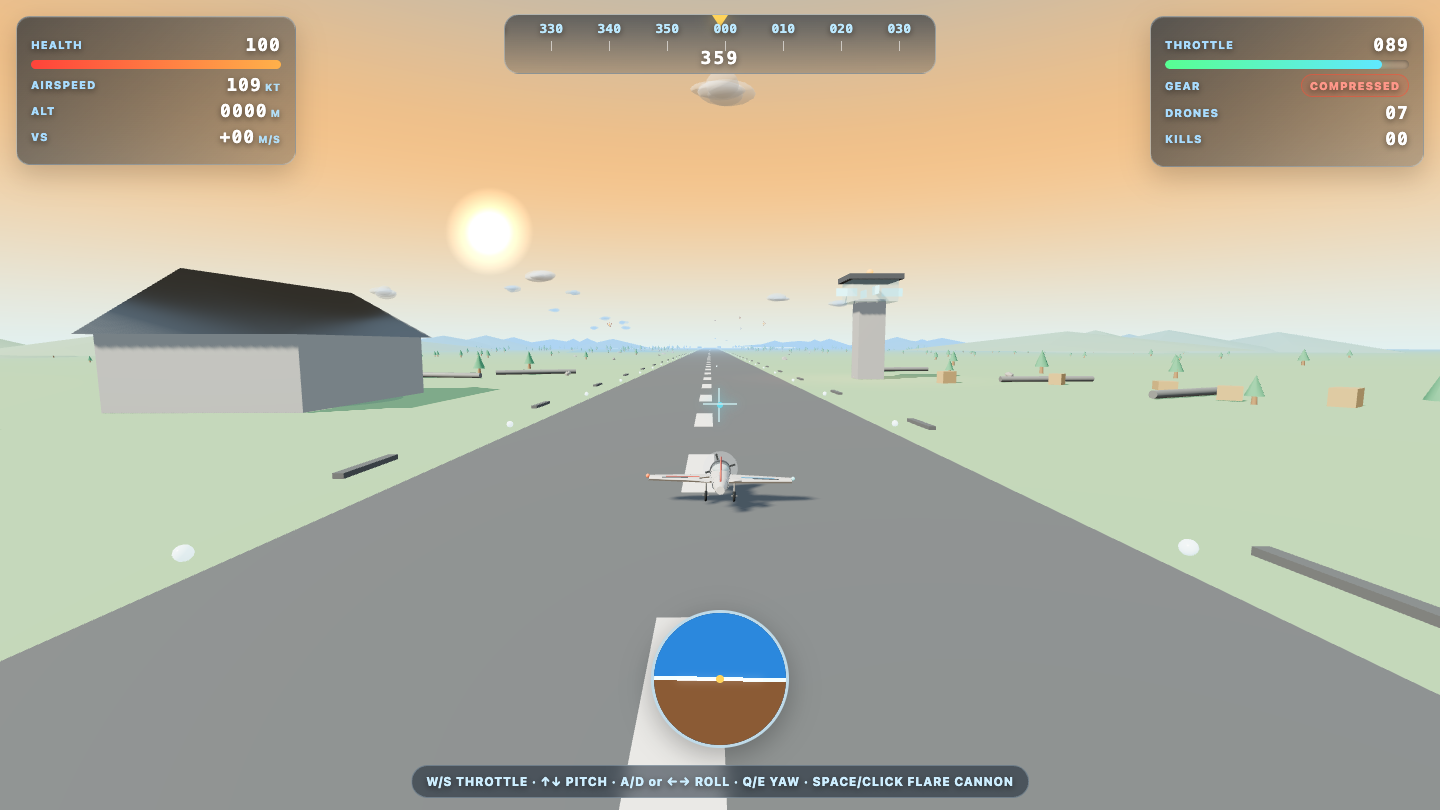
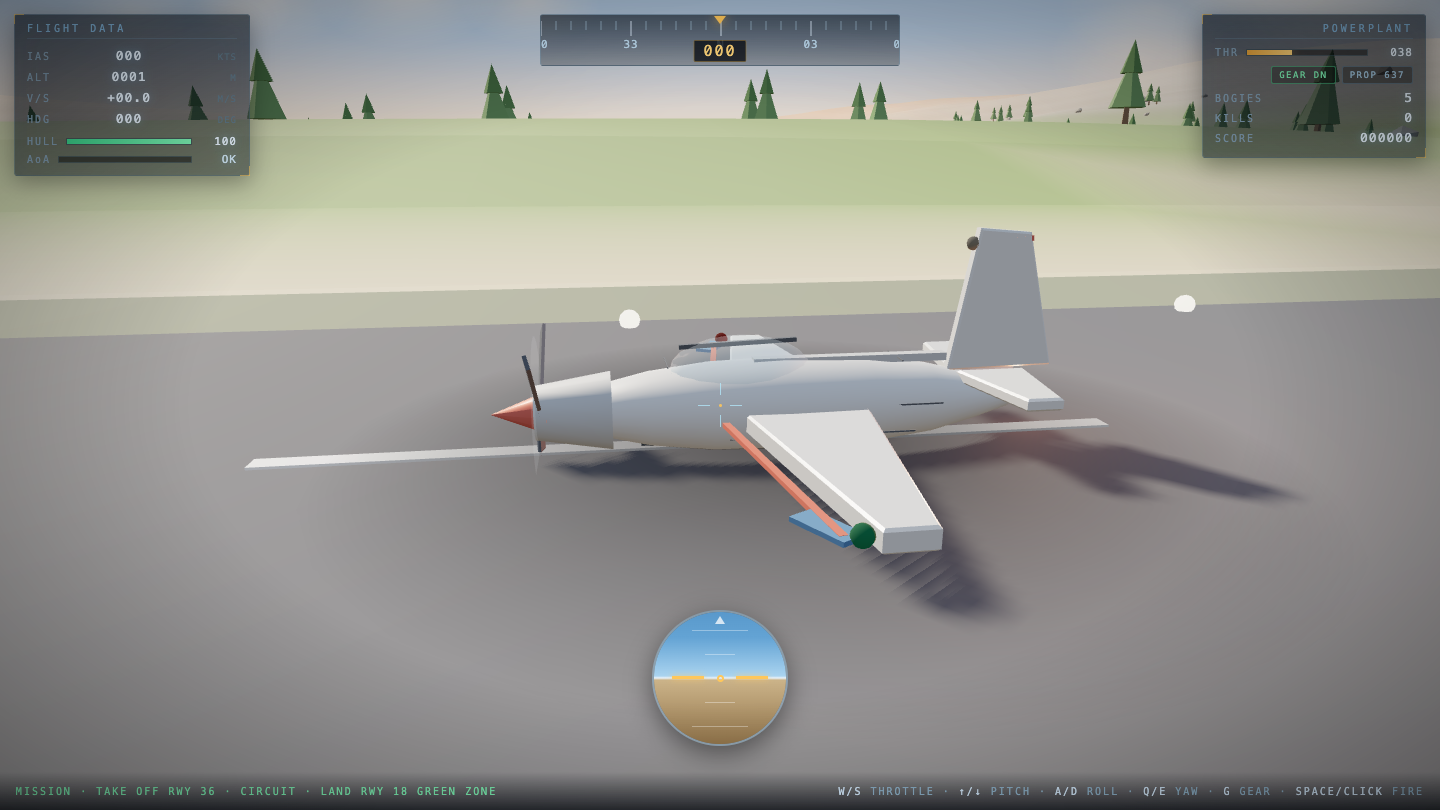
Game
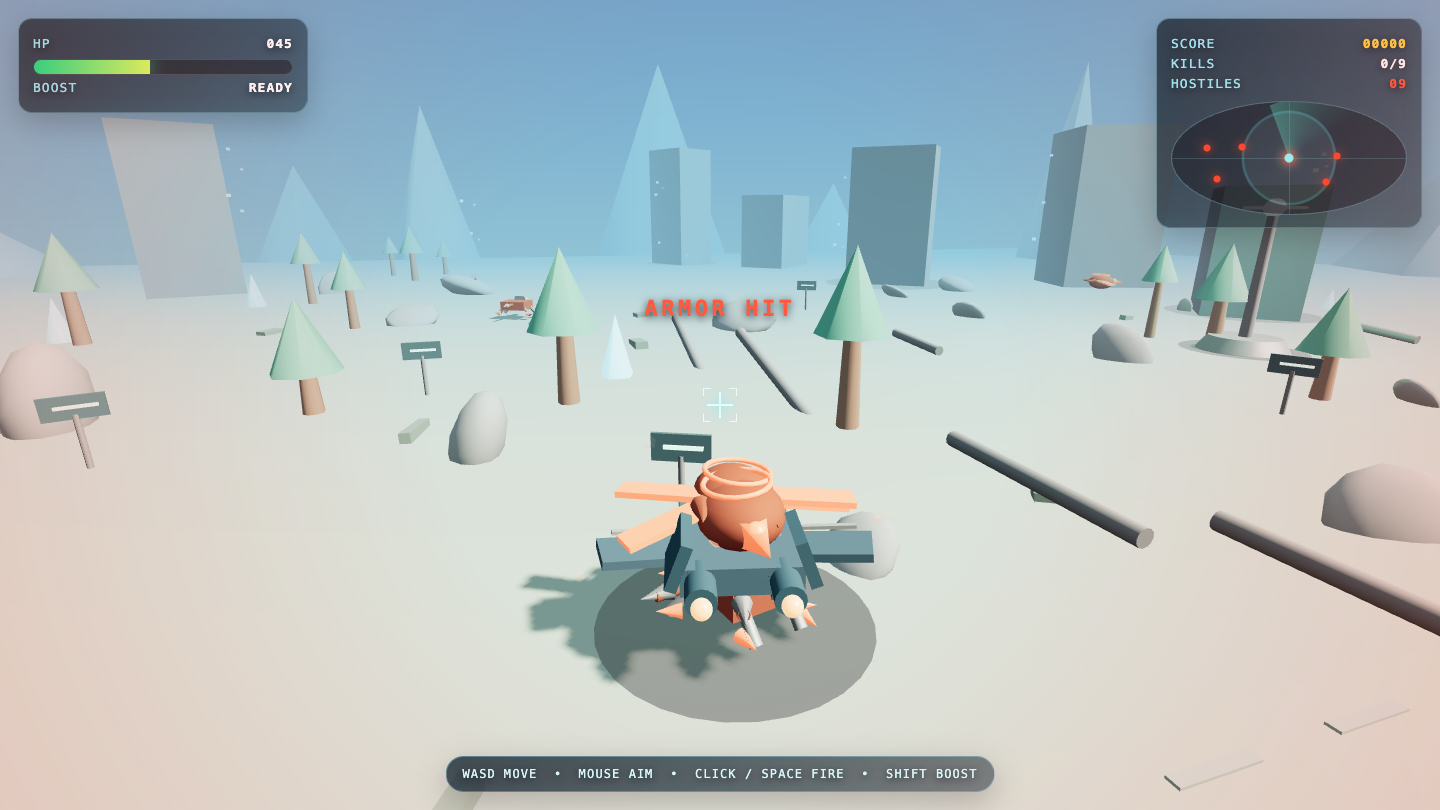
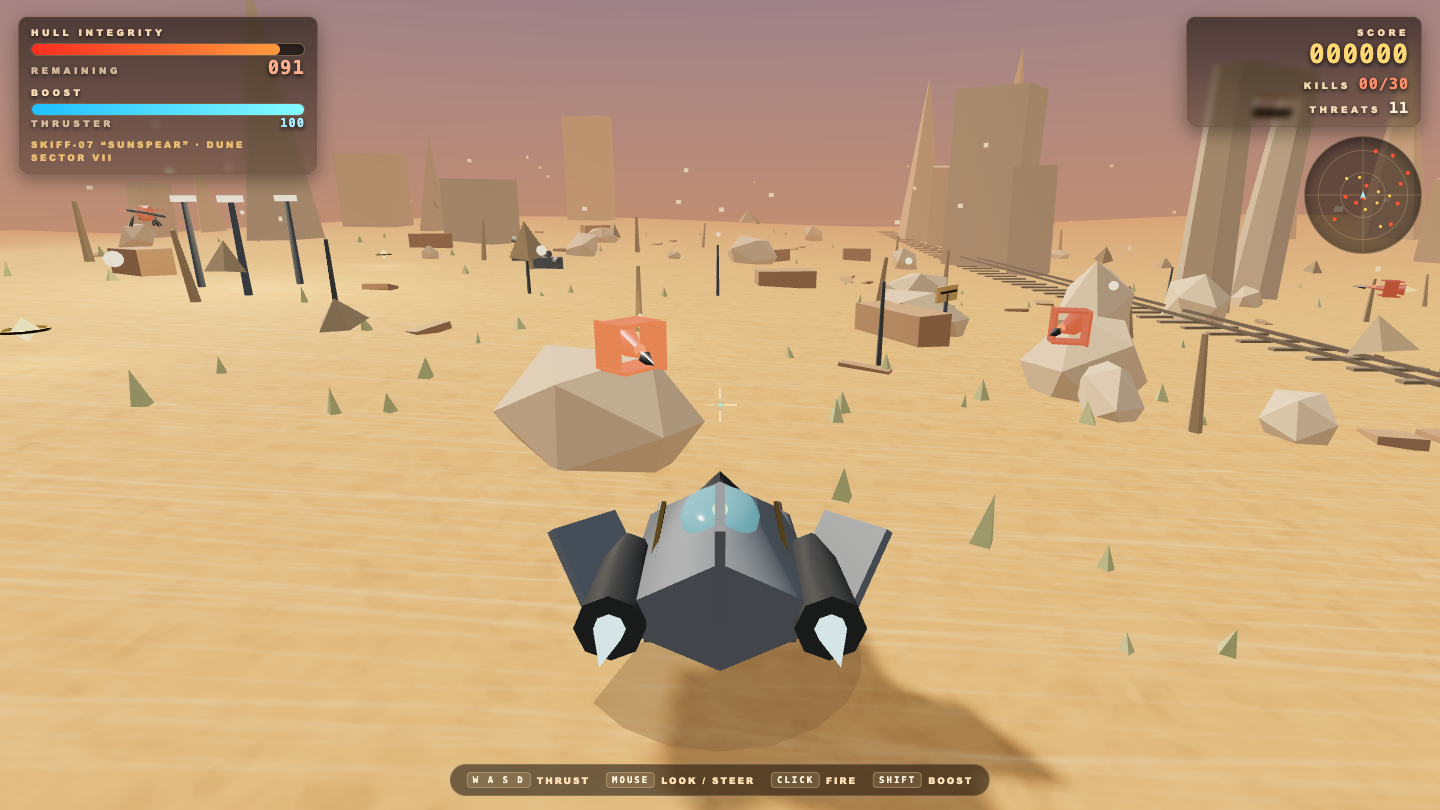
Game
Game
Game
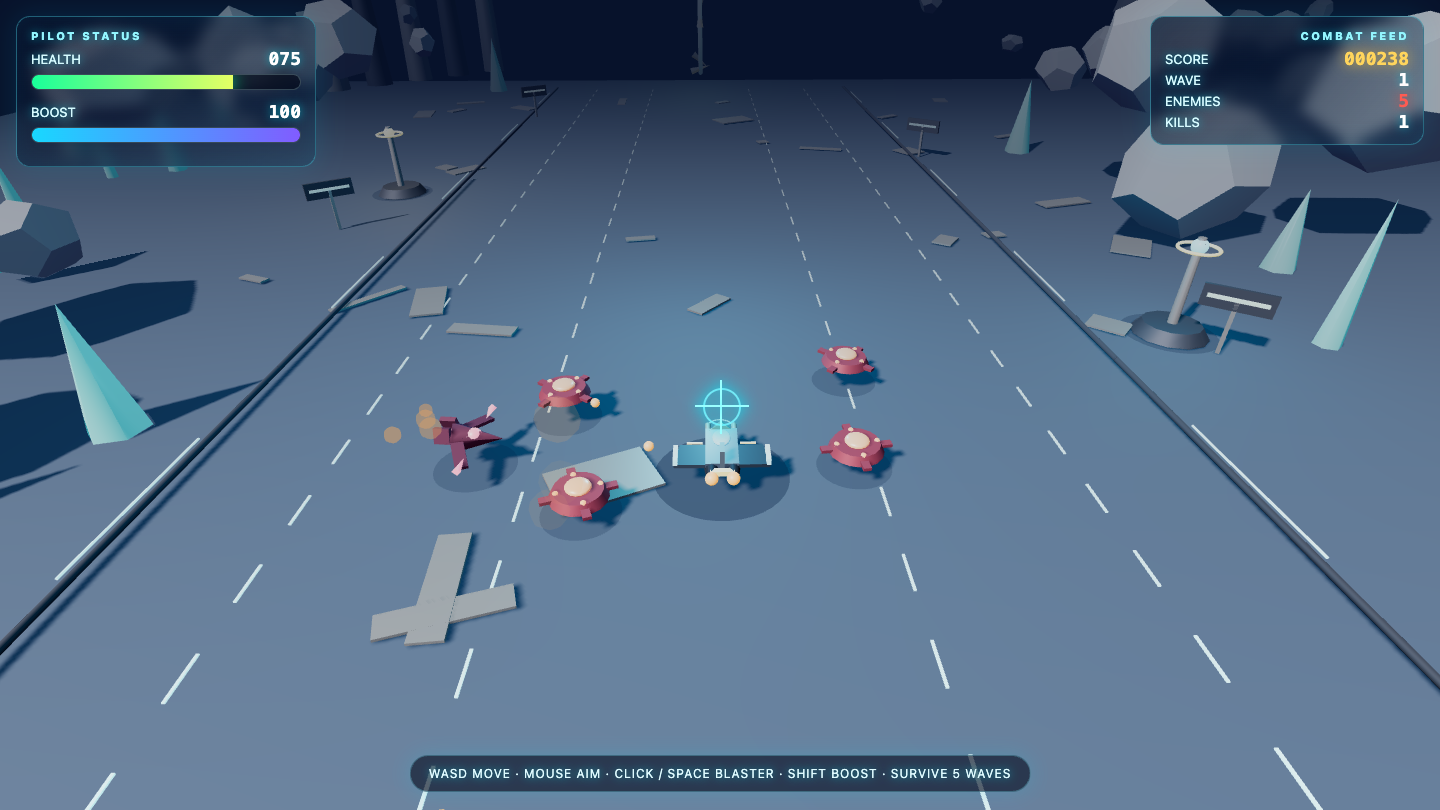
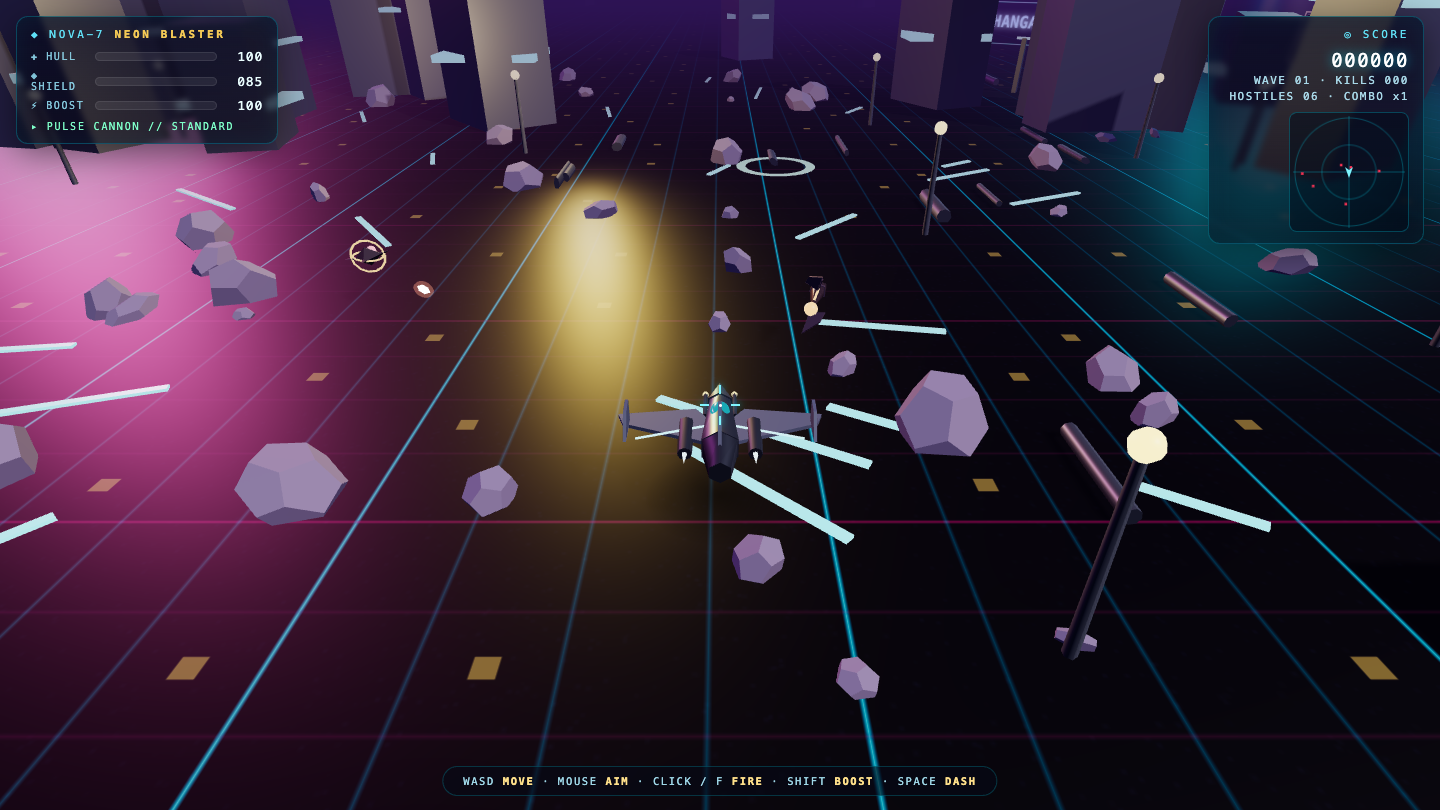
Game
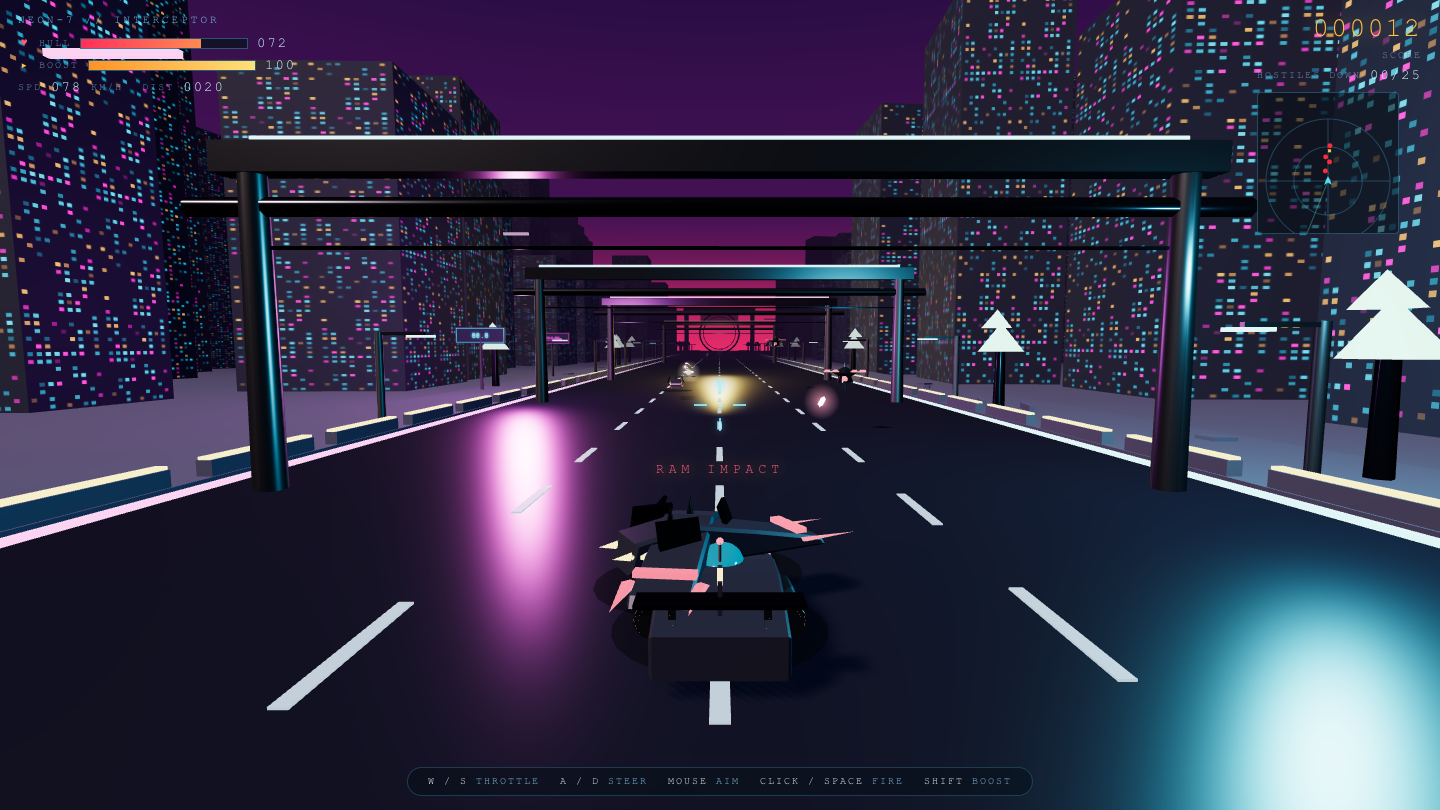
Game
Game
Game
Game
Game
Game
Game
Game
Game
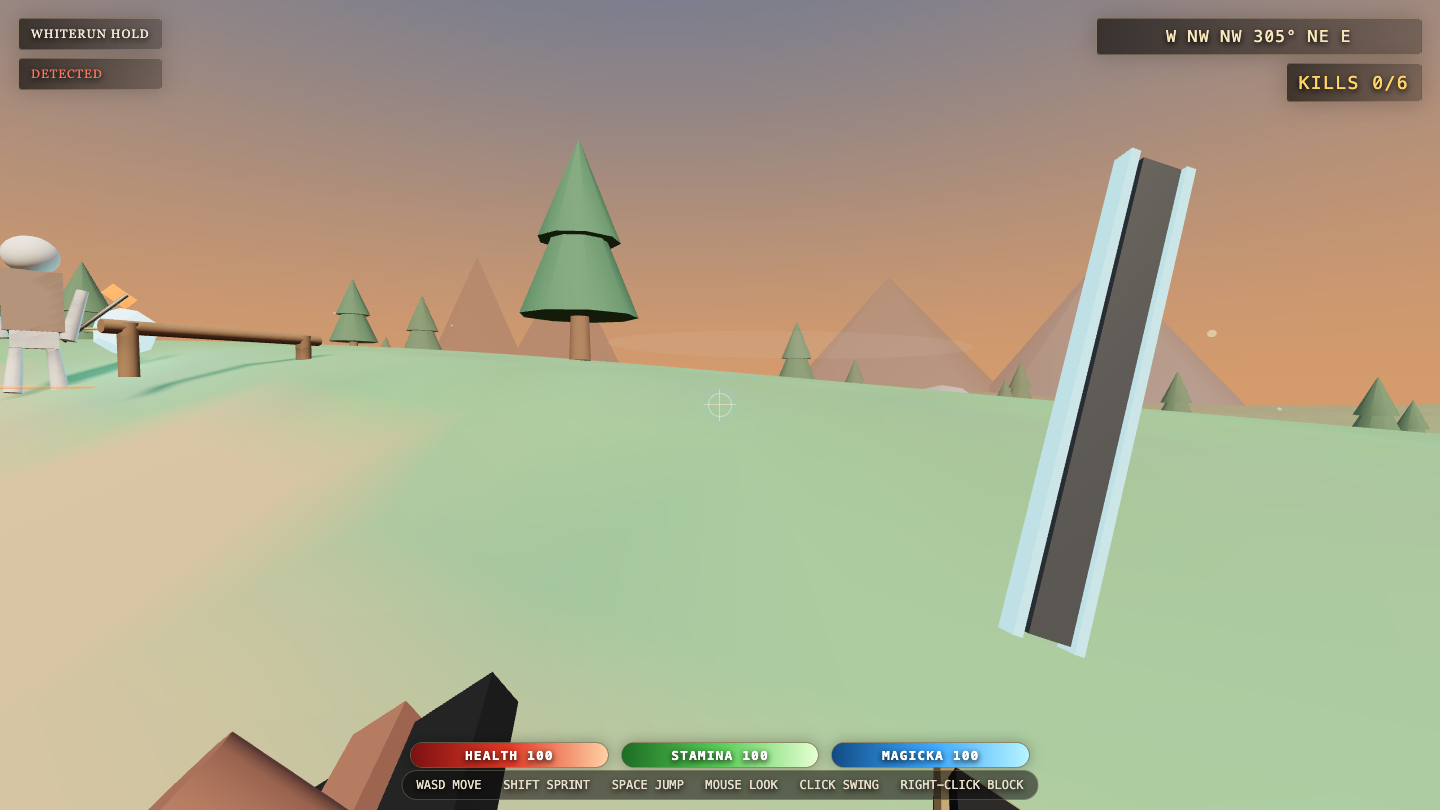
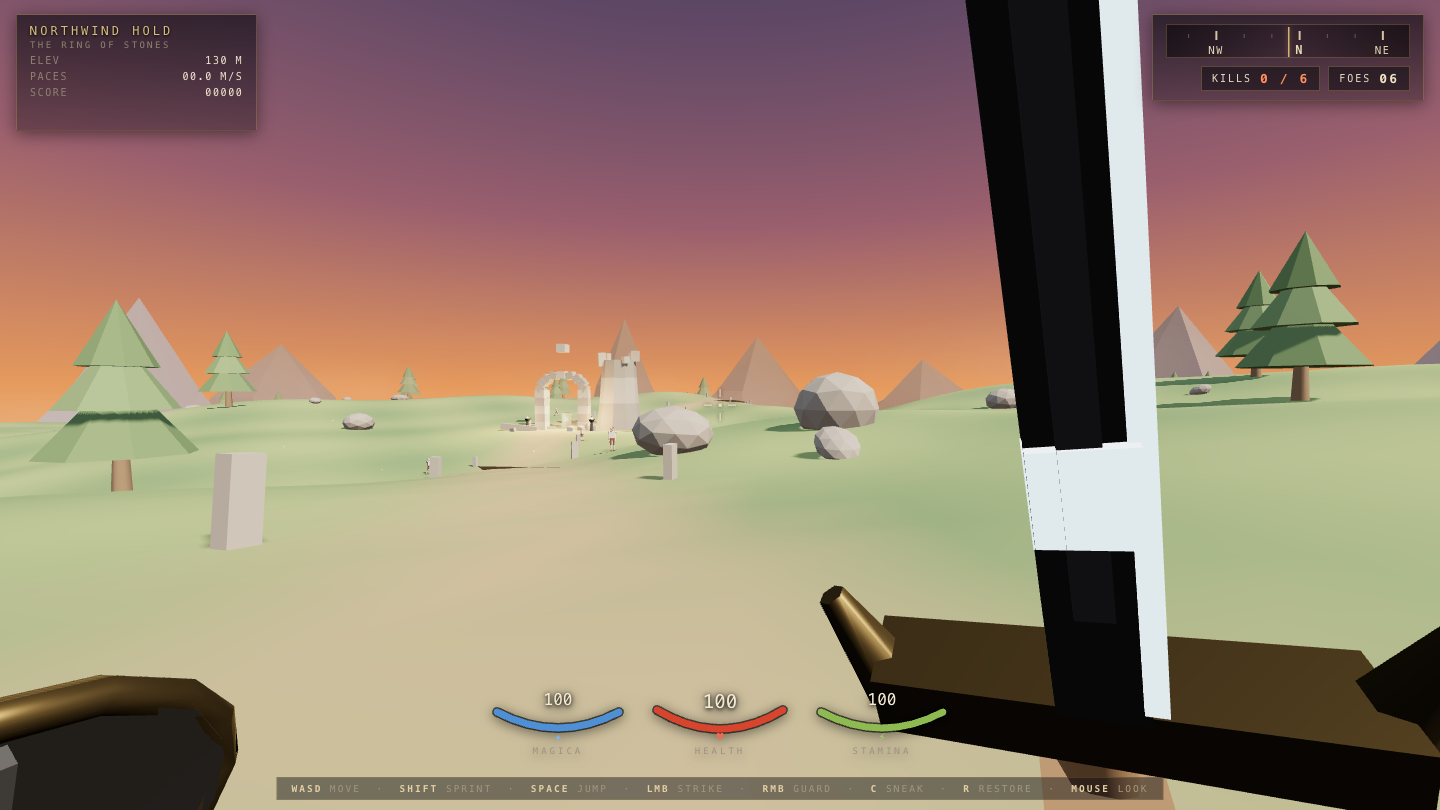
Game
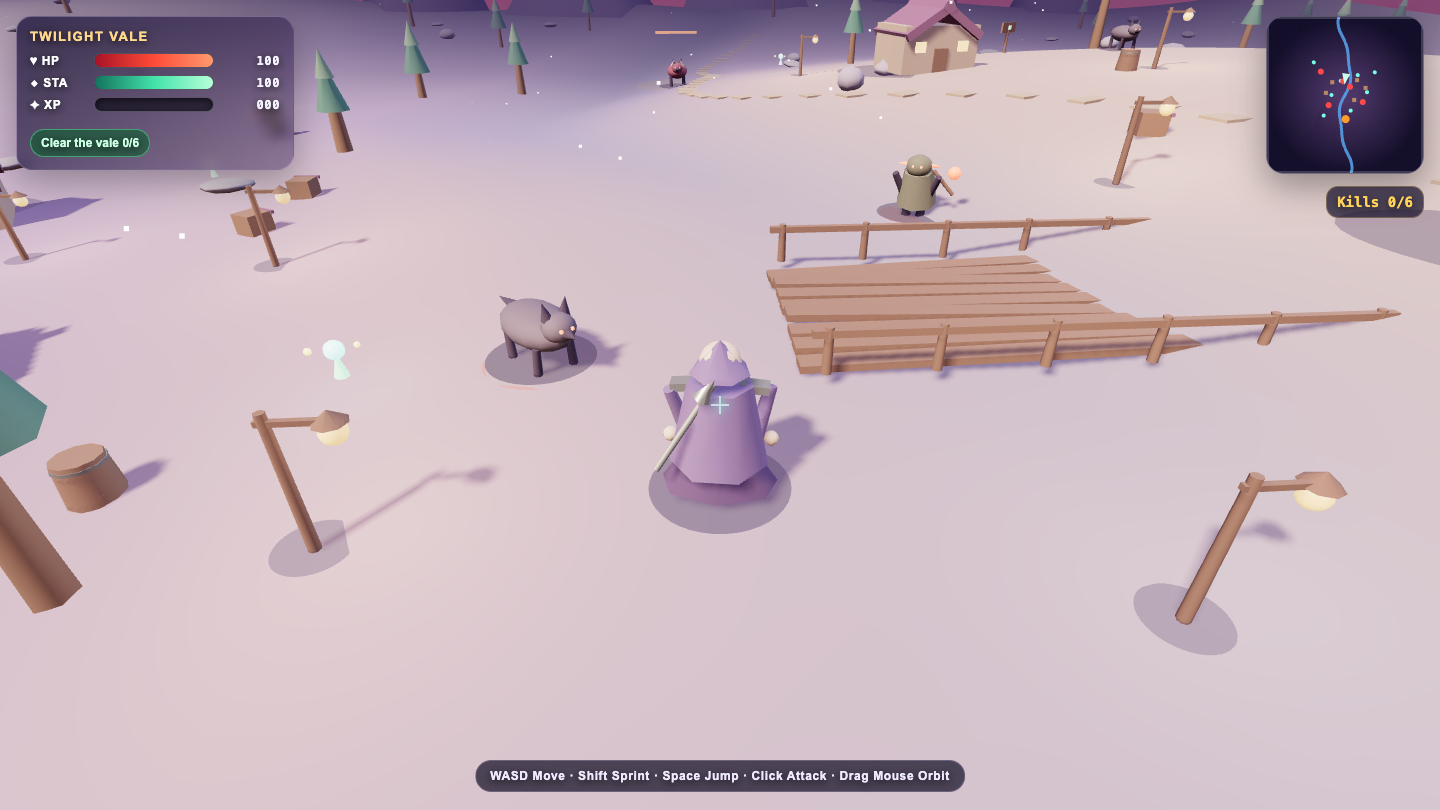
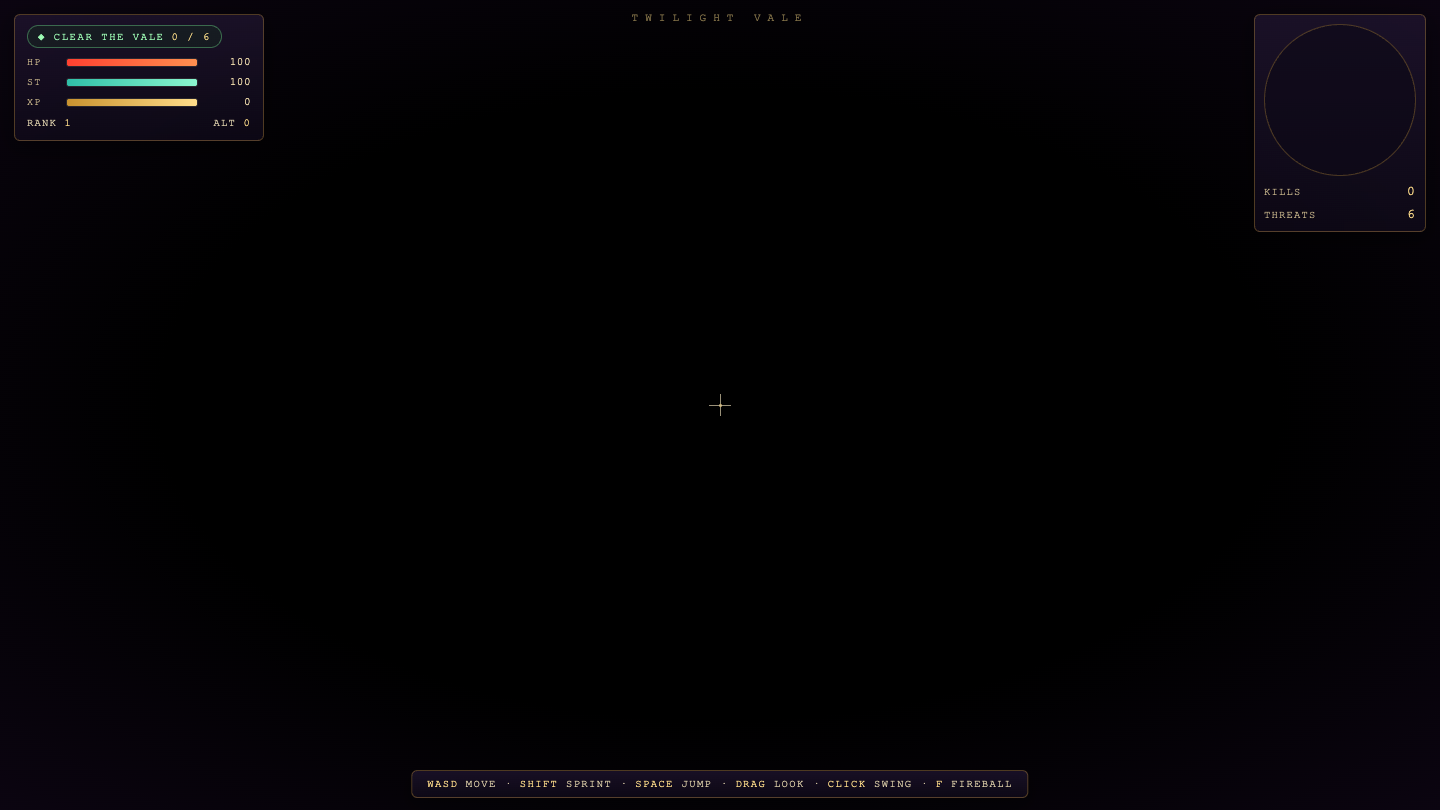
Page
Visual
Where Fugu Ultra 1.1 beat MiMo-V2.6 Pro
The tasks where I gave Fugu Ultra 1.1 a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
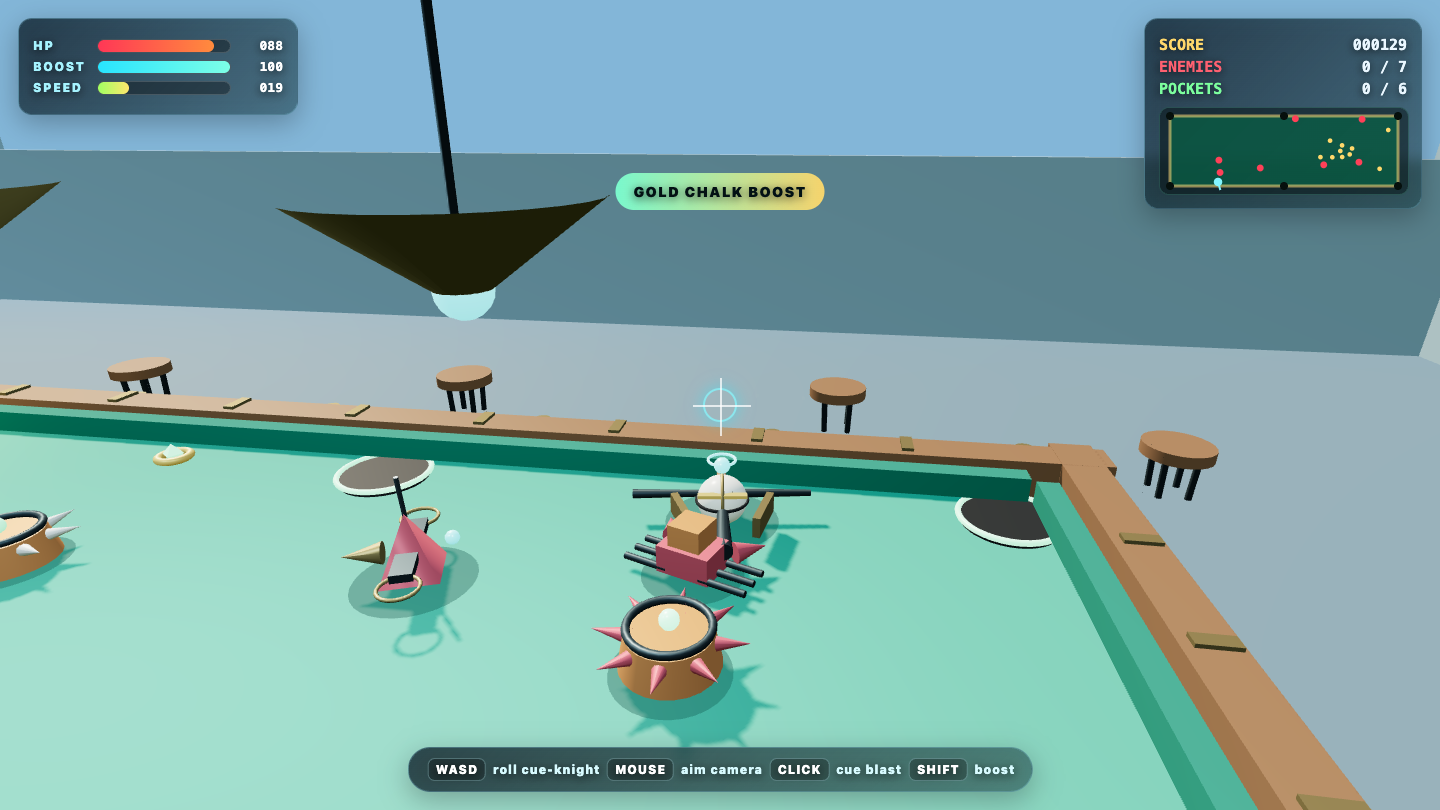
Rpg
Game
Fugu Ultra 1.1 8.4
·
MiMo-V2.6 Pro 1.5
(+6.9)
· Verdant Relic RPG
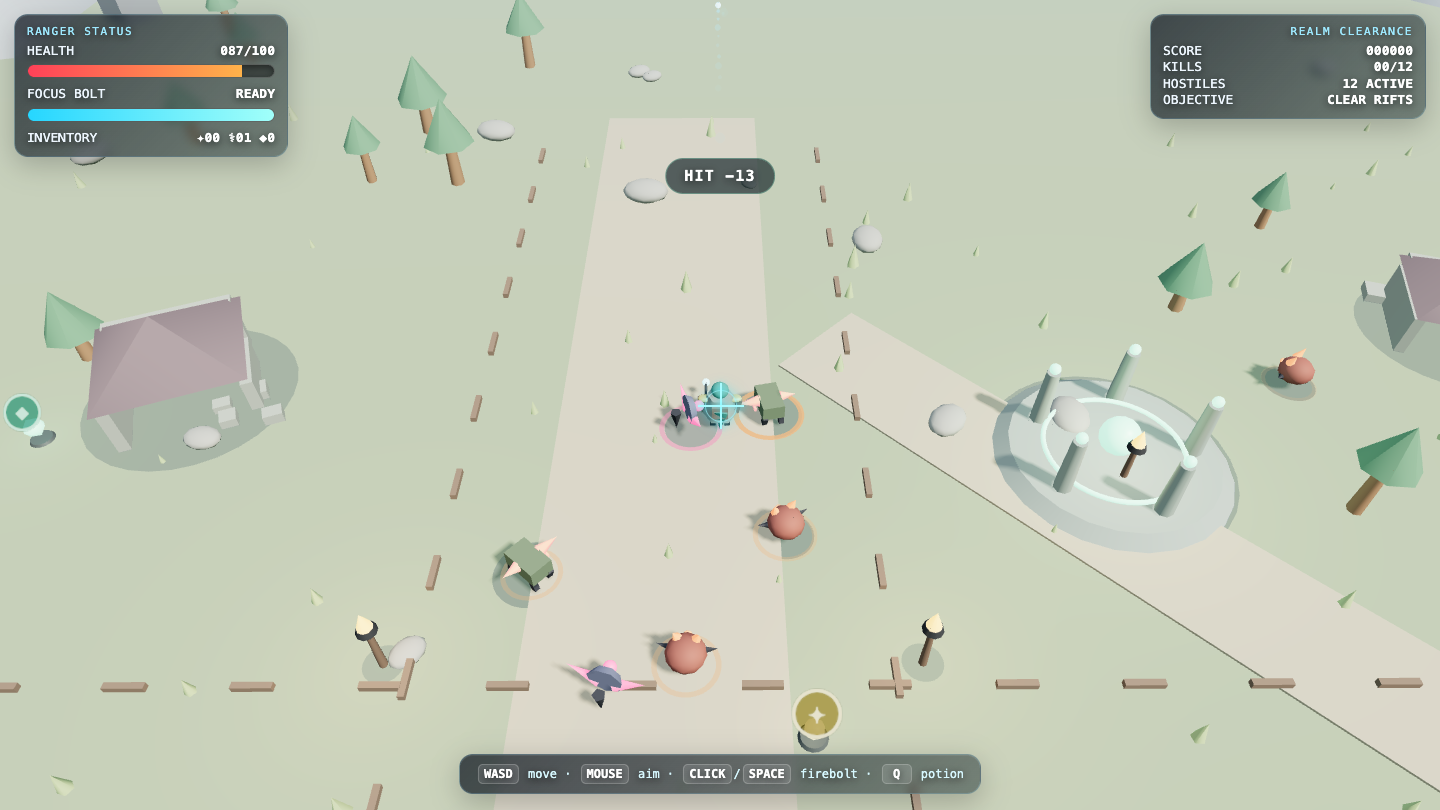
What I saw: Polished top-down 3D RPG with visible enemies in aggro rings, active combat ('HIT -13' damage numbers, health at 87), pickups, a shrine objective, and a clean HUD showing inventory/kills/hostiles; strong shippable build, only slightly held back by the inventory system being minim…
Parachute
Game
Fugu Ultra 1.1 8.6
·
MiMo-V2.6 Pro 3.0
(+5.6)
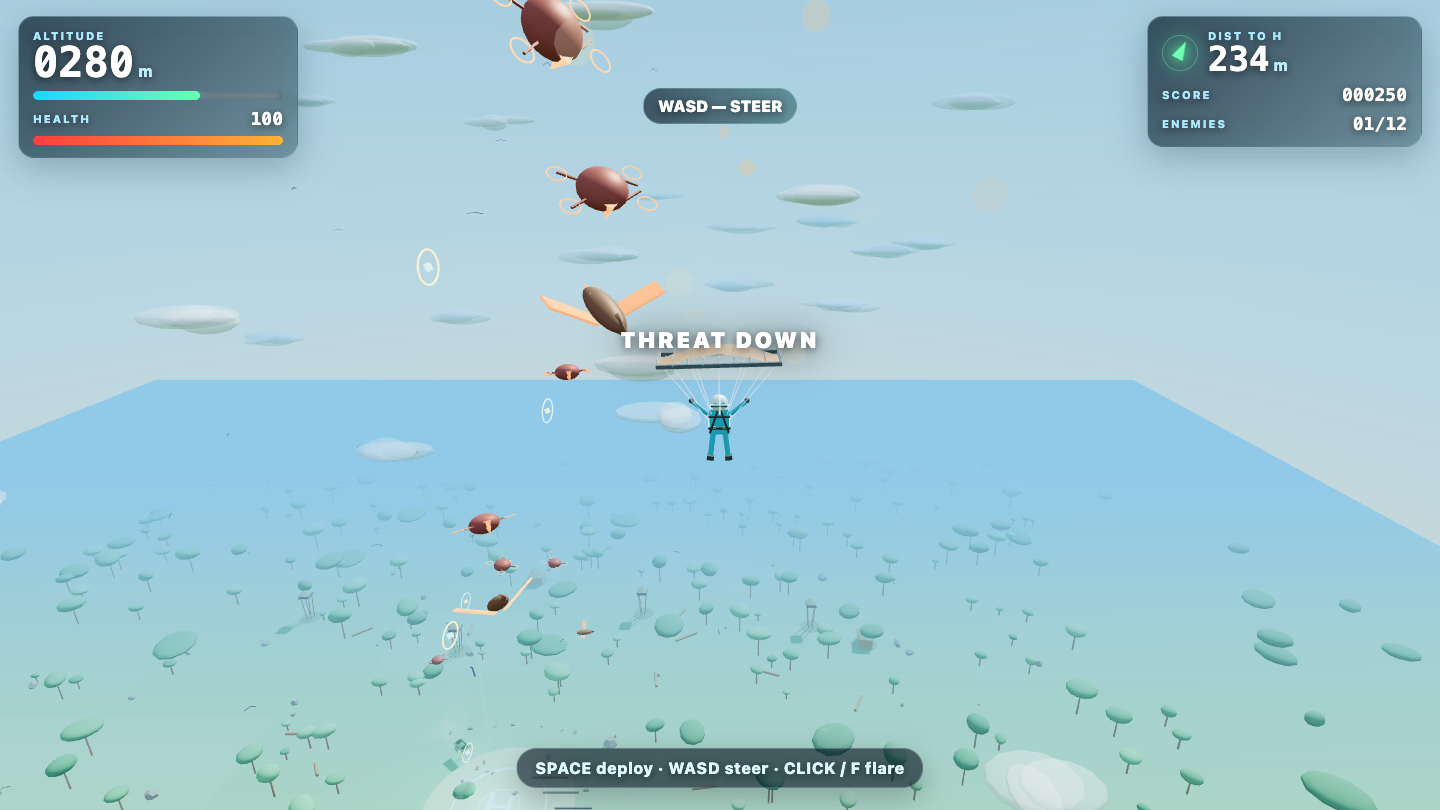
· combat parachute drop
What I saw: Strong deployed-chute skydiver over a jungle canopy with a polished HUD (altitude, dist-to-H, score) plus active drone enemies, flare combat, and 'THREAT DOWN' kill feedback — it delivers the full jump/steer/land loop AND working combat, edging past a bland walking sim.
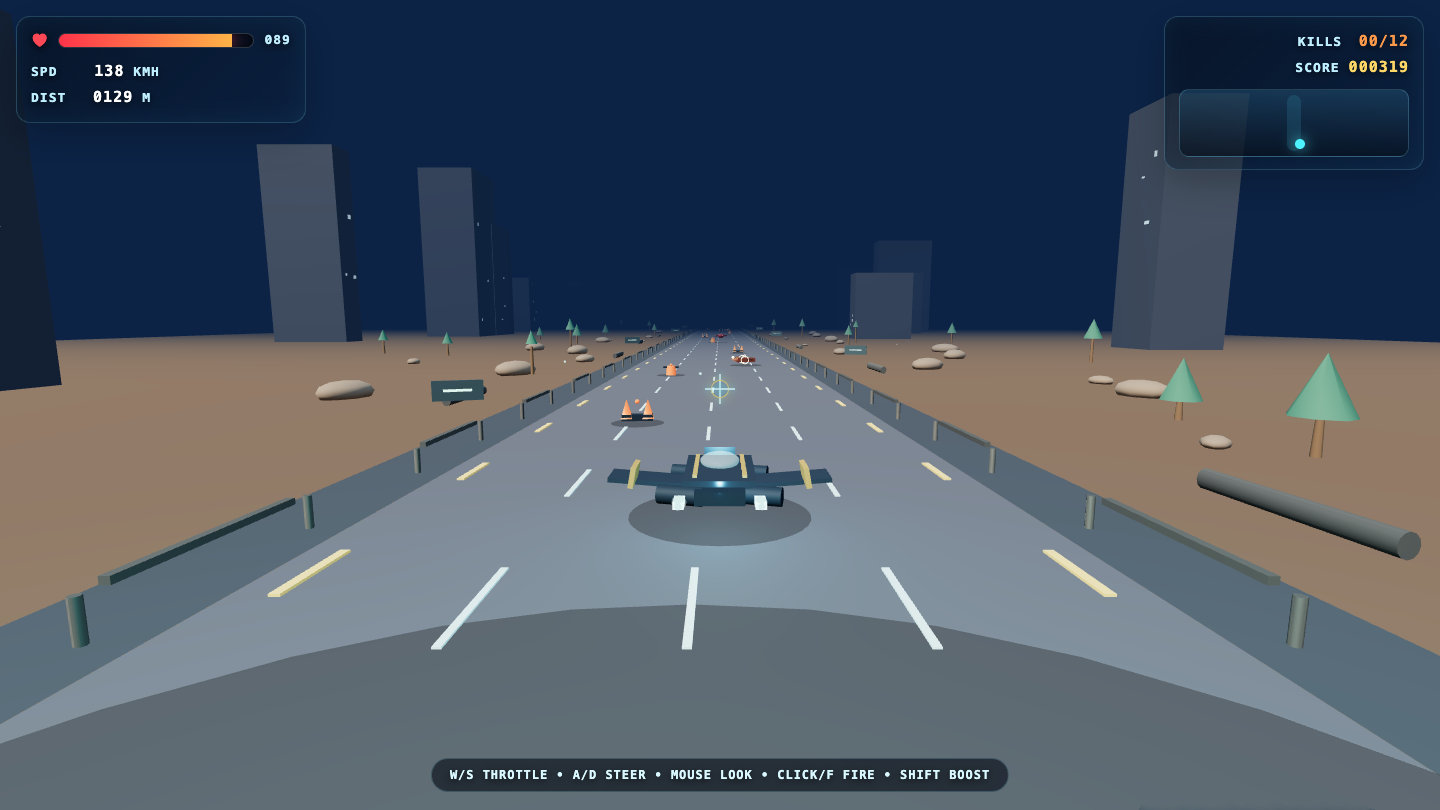
Racing
Game
Fugu Ultra 1.1 8.6
·
MiMo-V2.6 Pro 3.0
(+5.6)
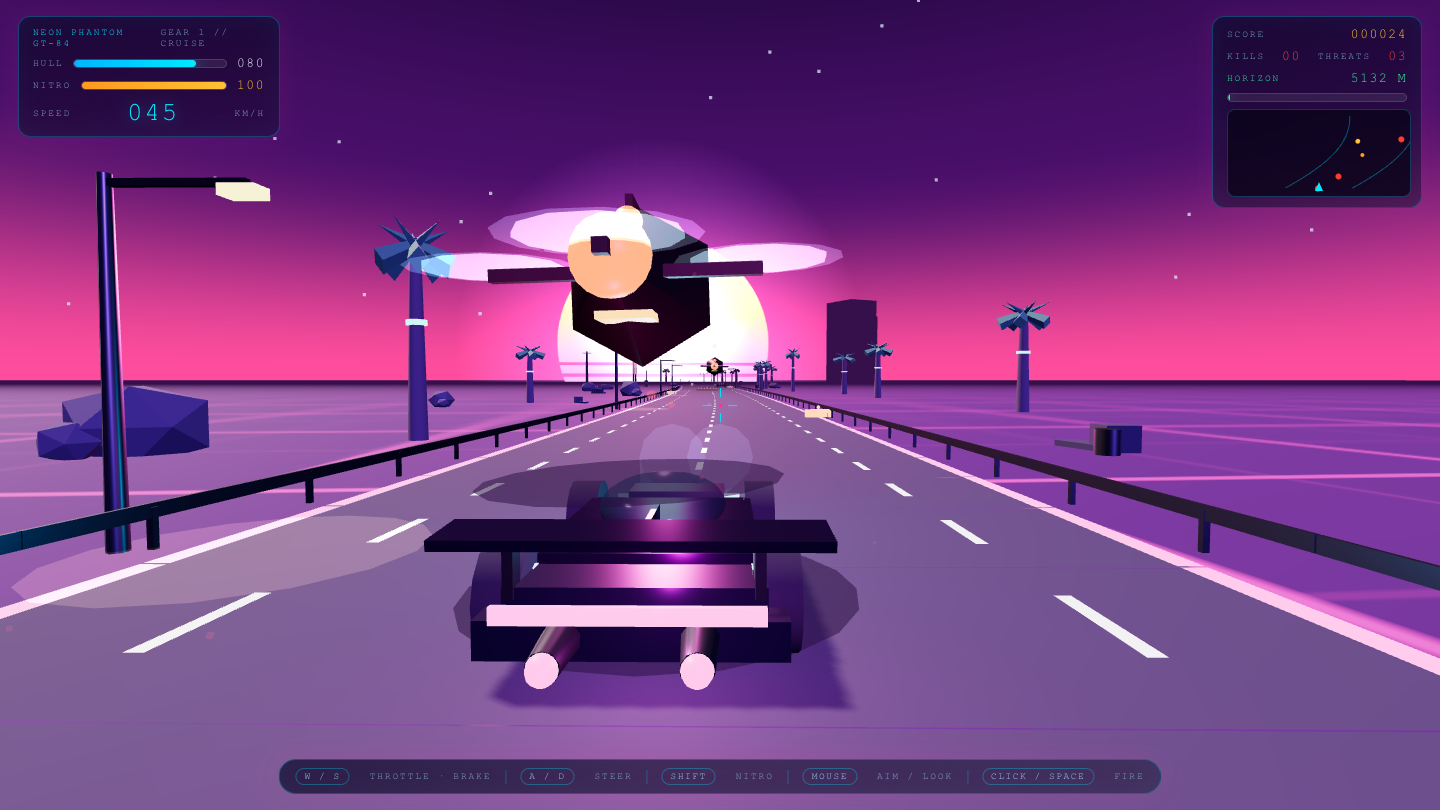
· Neon combat racer
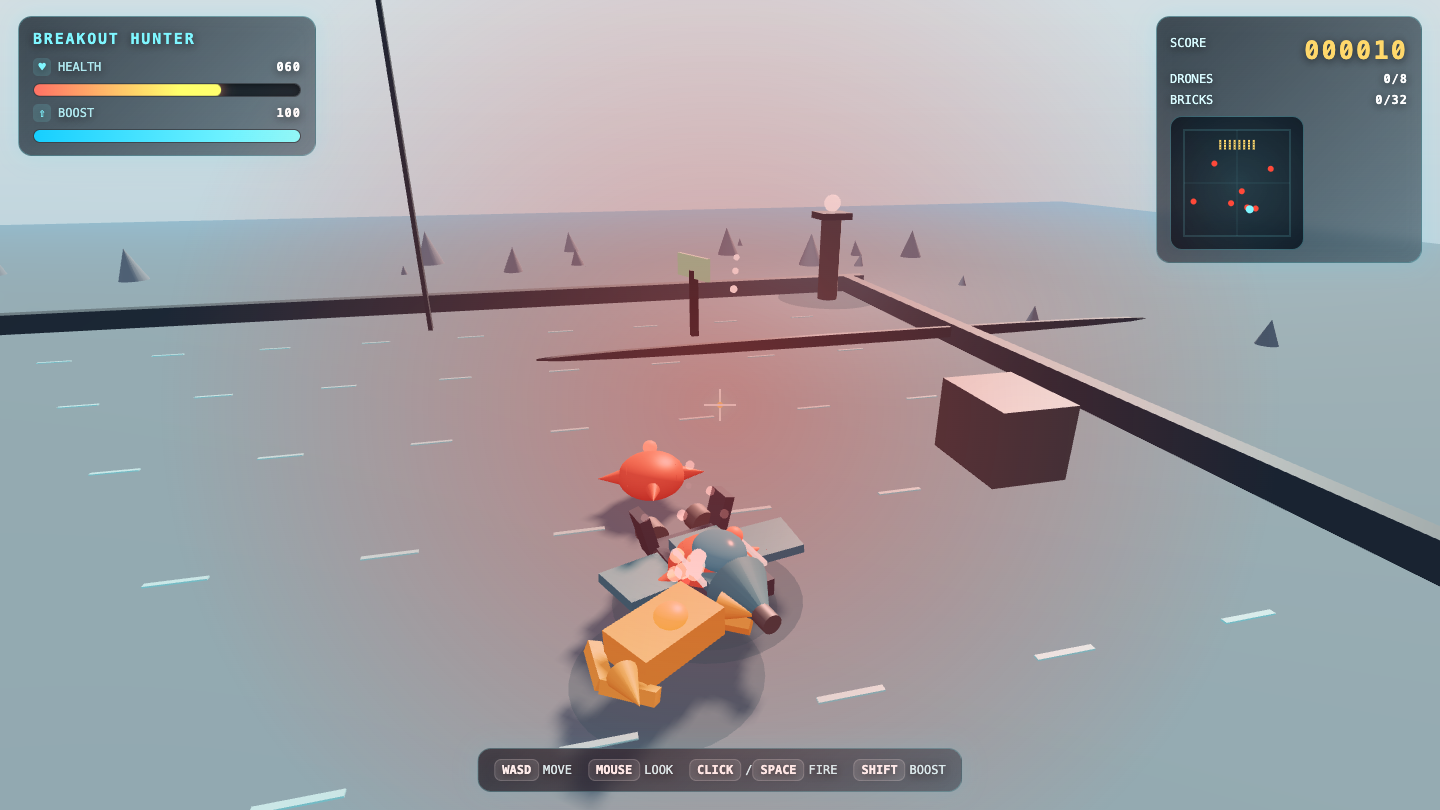
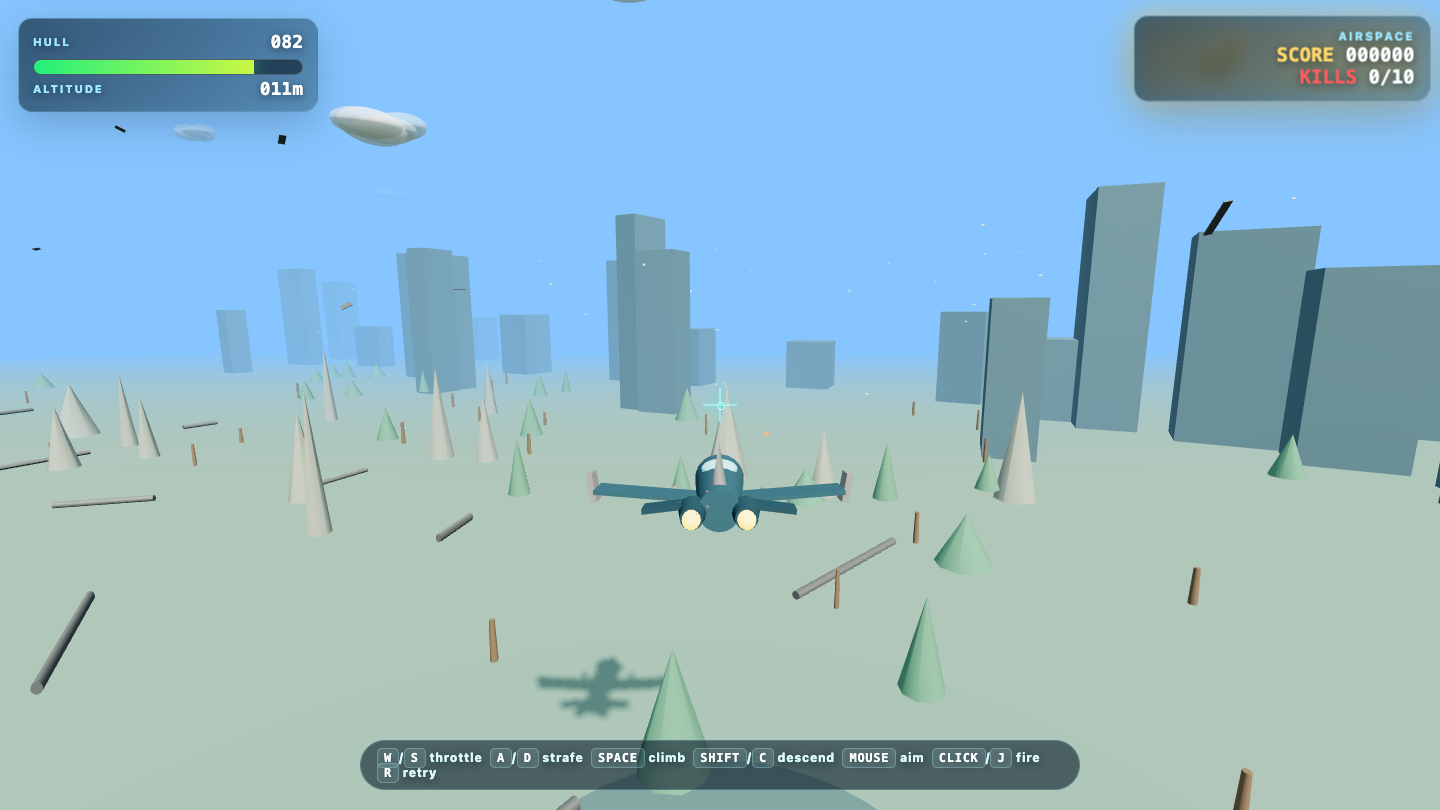
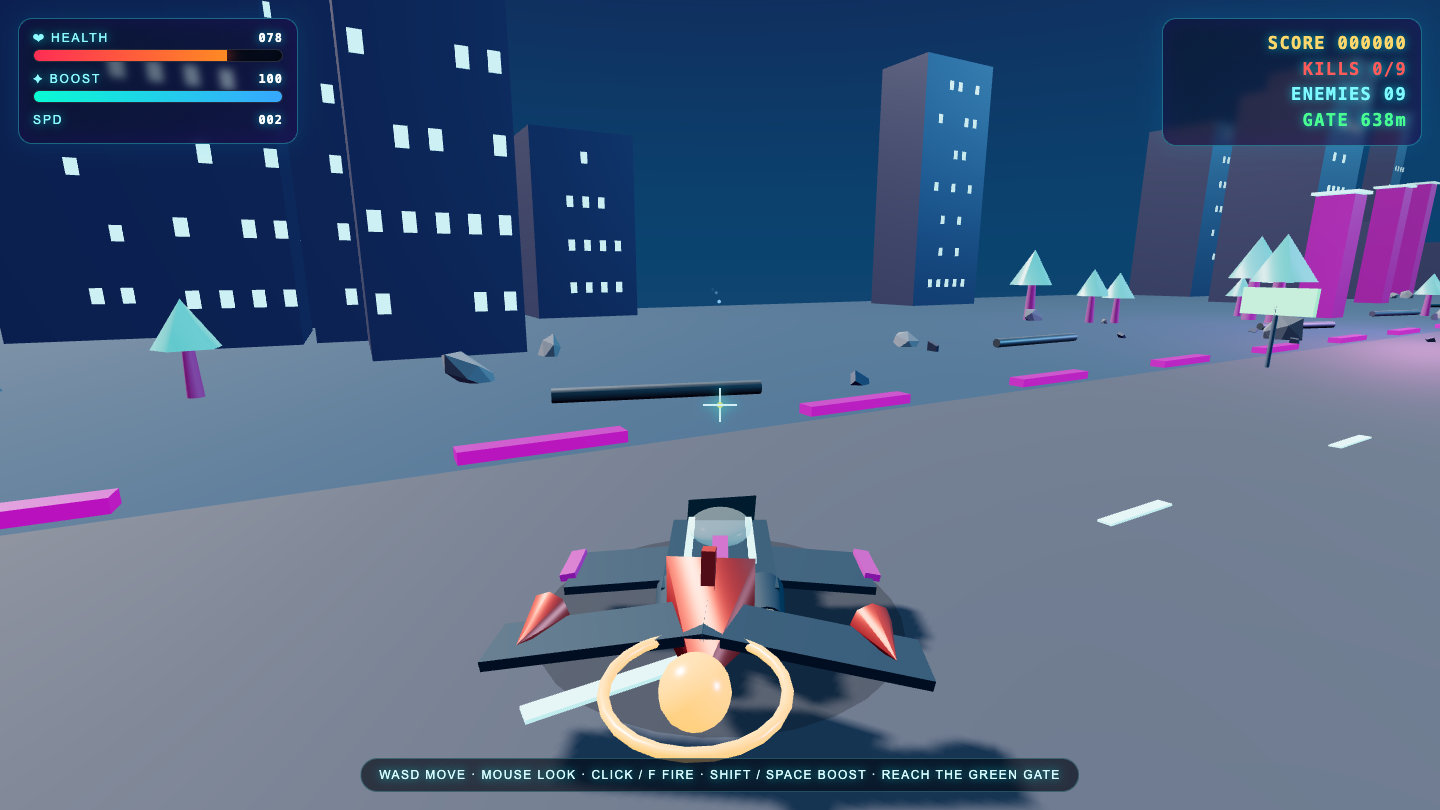
What I saw: Gorgeous polished third-person racer with a clear track, guardrails, trees/rocks/buildings, obstacle cones, a slick craft with ground shadow, and combat layered in (crosshair, KILLS 0/12, visible enemies/targets ahead) plus rich HUD with minimap — strong shippable build; only min…
Twilightvale
Game
Fugu Ultra 1.1 8.6
·
MiMo-V2.6 Pro 3.0
(+5.6)
· Atmospheric RPG World
What I saw: Gorgeous cohesive twilight scene with detailed hero holding a weapon, visible enemies (creature + humanoid), wooden bridge, lampposts, cottage, river, pickups and a working minimap/HUD with quest and kill tracker. Strong art direction and populated world with combat framing; only…
Doom
Game
Fugu Ultra 1.1 8.4
·
MiMo-V2.6 Pro 3.0
(+5.4)
· 3D demon shooter
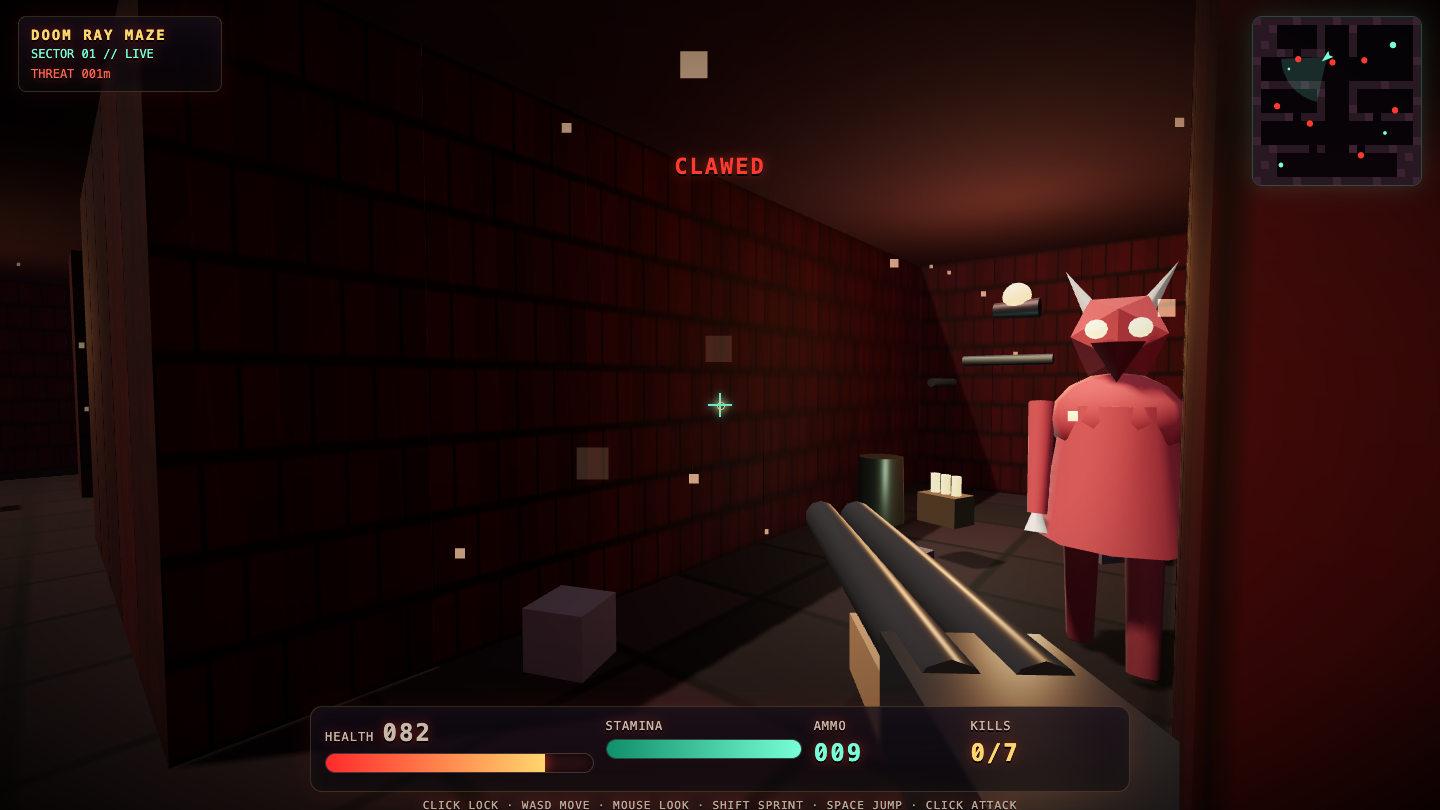
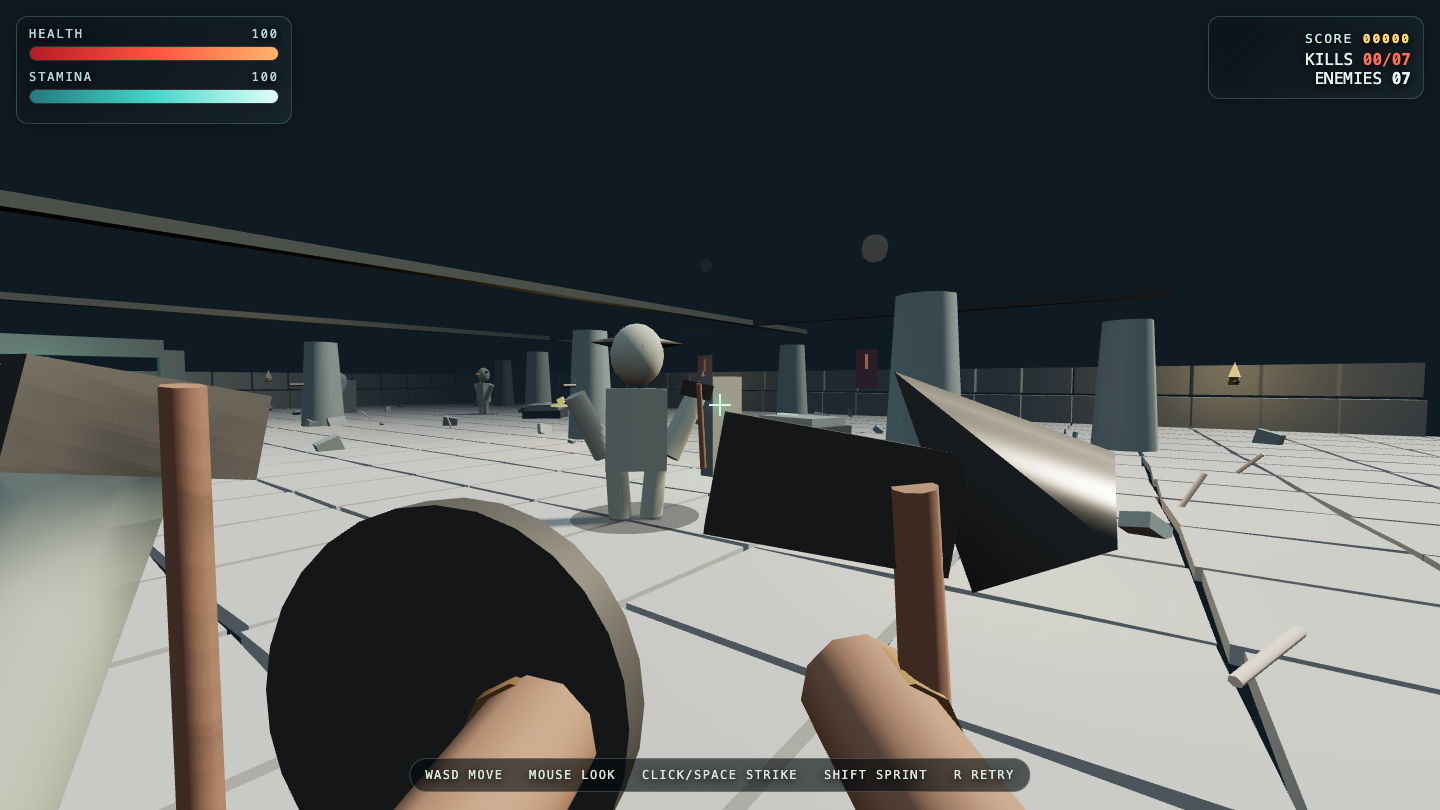
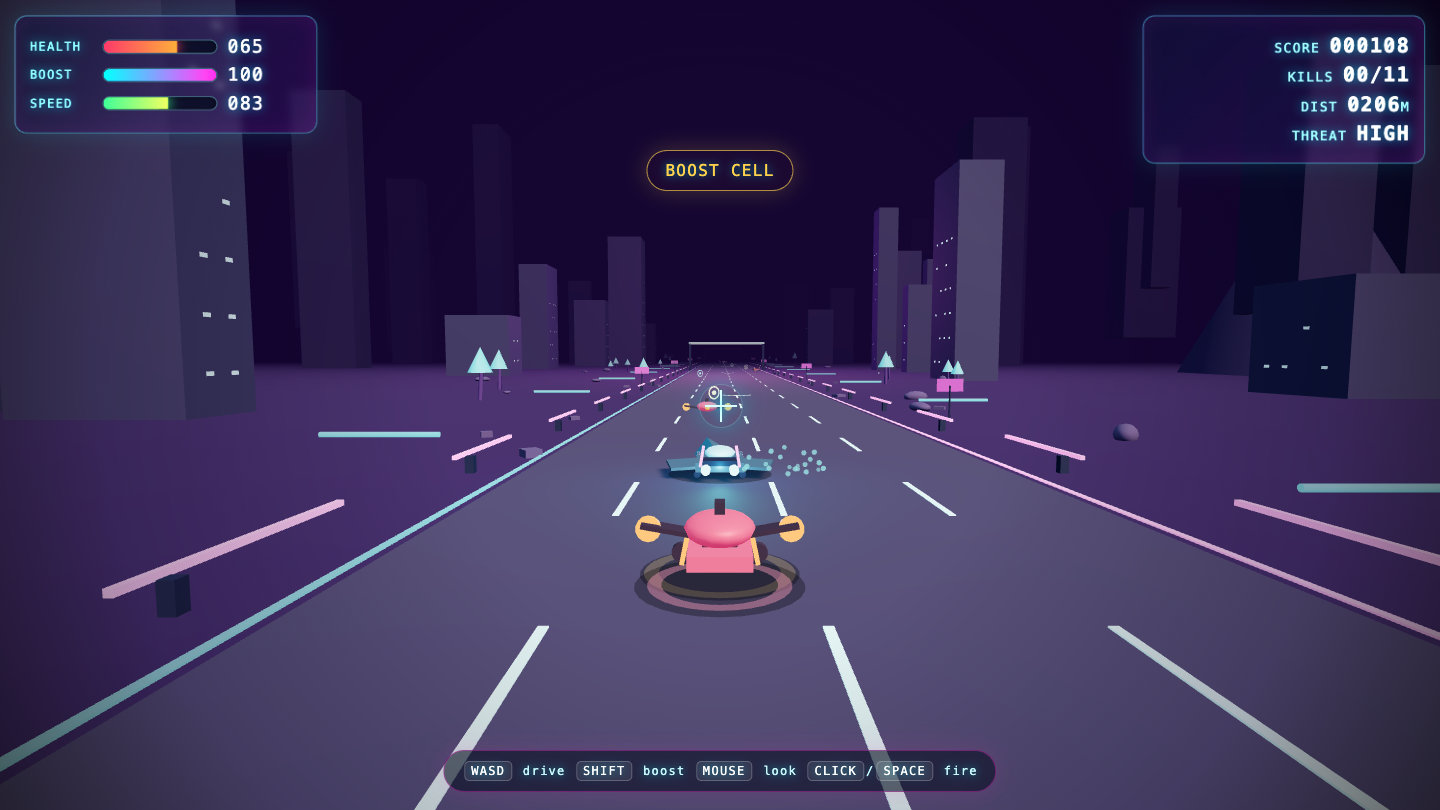
What I saw: Strong atmospheric 3D maze with a visible horned demon enemy, working shotgun, minimap with tracked enemies, and active combat ('CLAWED' hit feedback, HP dropped to 082) — polished HUD and lighting. Falls just shy of the field's best; enemies are more Three.js models than true ra…
Where MiMo-V2.6 Pro beat Fugu Ultra 1.1
The tasks where I gave MiMo-V2.6 Pro a higher 0–10 score on the same prompt — with the actual commentary from my source guides.
Neoncity
Game
MiMo-V2.6 Pro 8.7
·
Fugu Ultra 1.1 2.3
(+6.4)
· Neon Runner Combat
What I saw: Gorgeous rendered scene—gradient cyberpunk sky, dense emissive-window skyscrapers, overpass structures, neon road glow and a detailed player craft with full combat HUD, minimap, bolts and 'RAM IMPACT' feedback all working; the polished driving-shooter loop clearly beats the gener…
Arcade
Game
MiMo-V2.6 Pro 8.6
·
Fugu Ultra 1.1 5.5
(+3.1)
· 3D neon snake
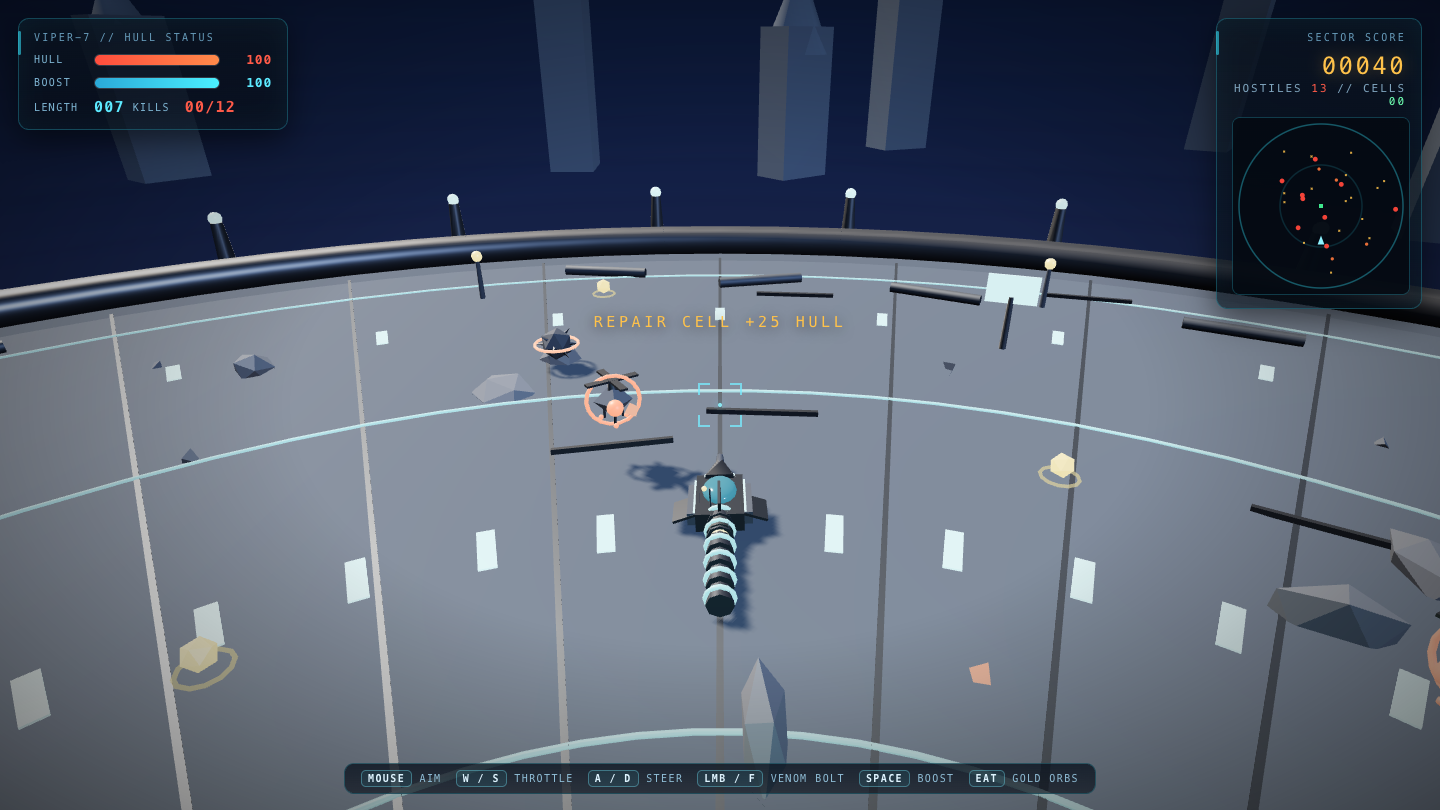
What I saw: Stunning 3D reinterpretation of Snake as a WebGL arena viper — polished lighting, segmented tail, working minimap, pickups, and clean neon HUD all render crisply. Strong on-brief execution that clearly outclasses the flat 2D field; only slight risk is that the elaborate combat fr…
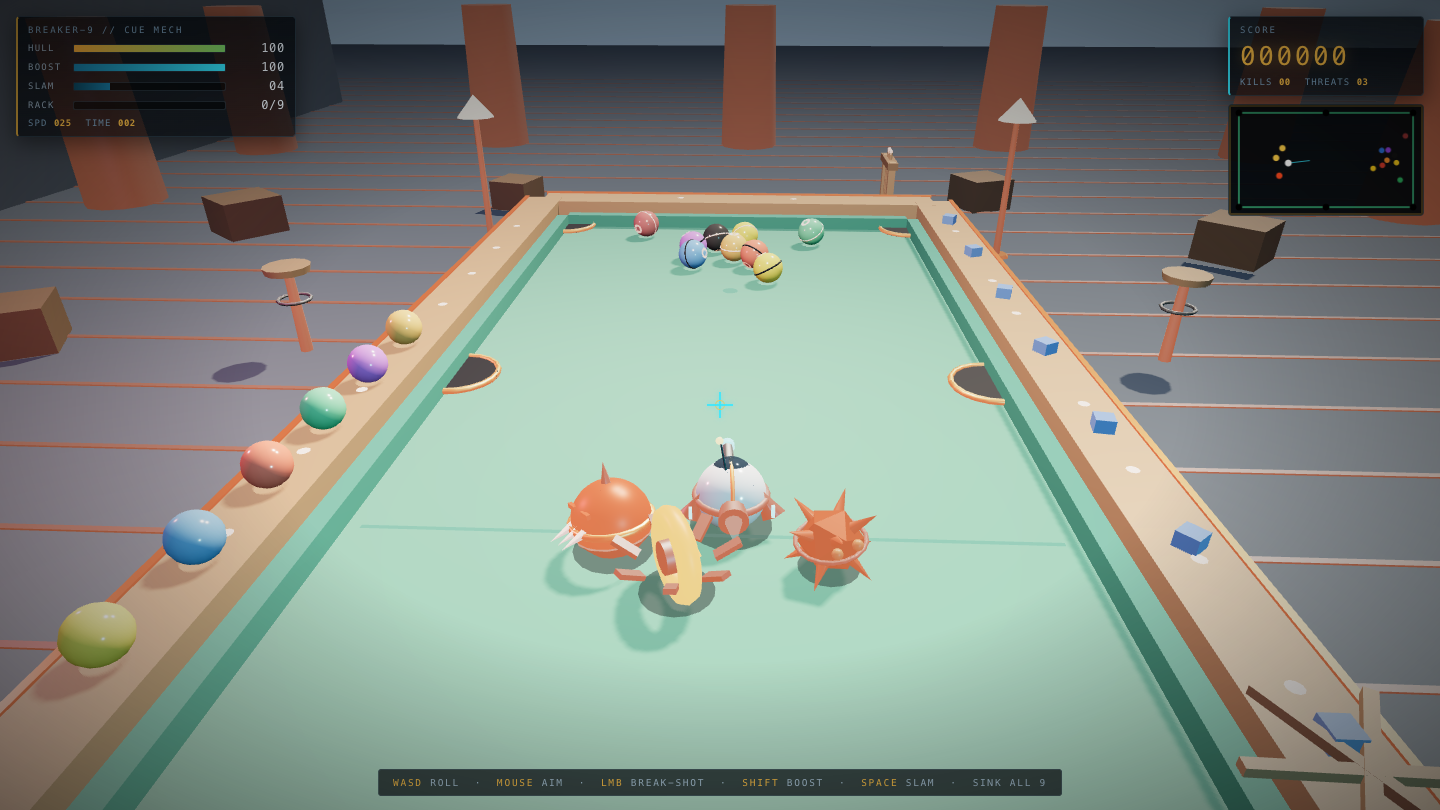
Pool
Game
MiMo-V2.6 Pro 6.0
·
Fugu Ultra 1.1 4.5
(+1.5)
What I saw: Renders a polished, atmospheric 3D pool hall with proper table, racked balls, pockets, cushions and a slick HUD/minimap — visually strong. But it drifts off-brief into a bizarre 'combat mech/threats/kills/SLAM' arena-shooter mashup rather than a clean physically-simulated billiar…
Dogfight
Game
MiMo-V2.6 Pro 8.6
·
Fugu Ultra 1.1 7.2
(+1.4)
· polished 3D dogfight
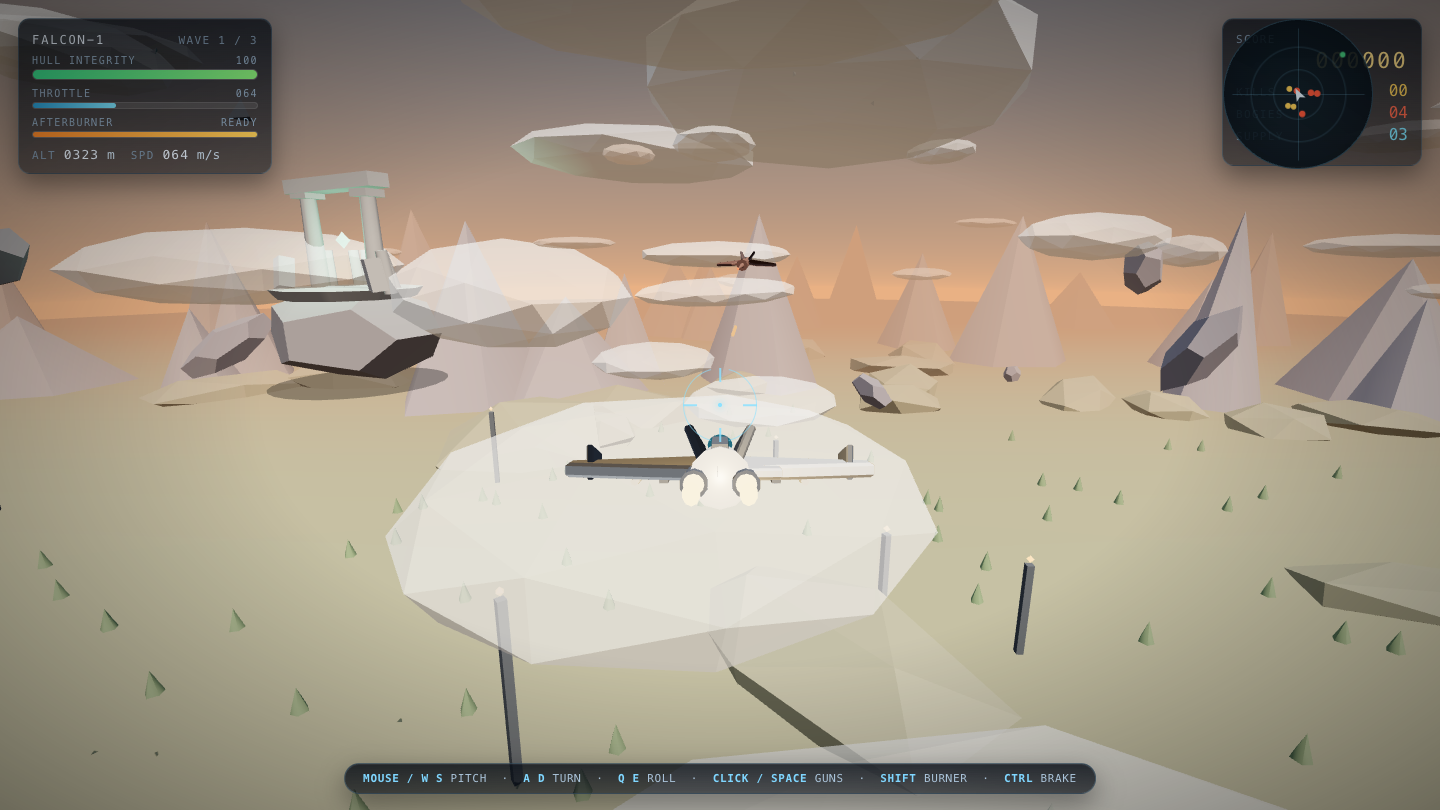
What I saw: Renders a gorgeous low-poly 3D world with detailed player jet, chase cam, floating clouds, terrain props, an enemy bogey in view, and a fully realized HUD (radar, throttle, afterburner, hull). Cohesive military-flight aesthetic and rich mechanics make this a task-topper; only min…
Raycaster
Game
MiMo-V2.6 Pro 3.0
·
Fugu Ultra 1.1 2.0
(+1.0)
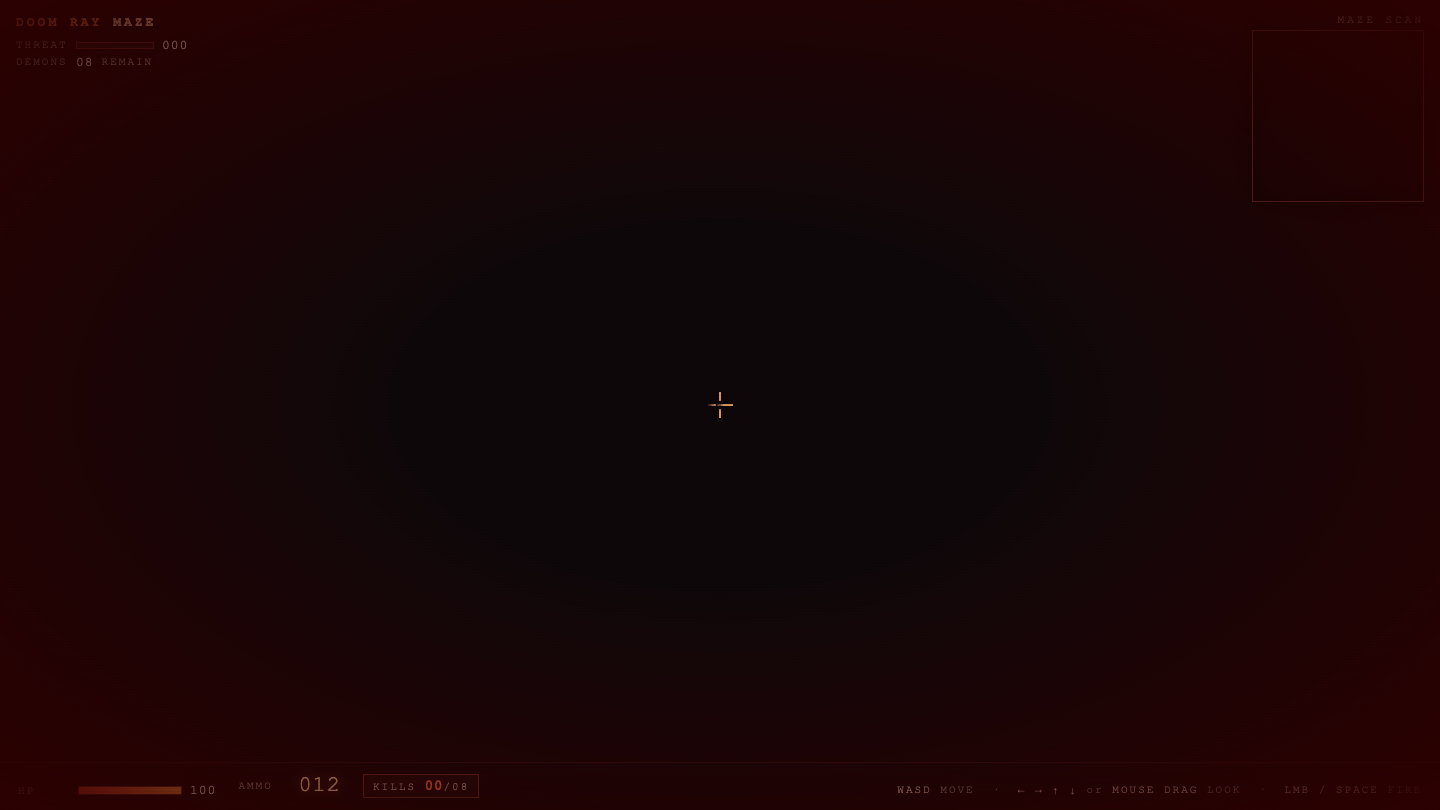
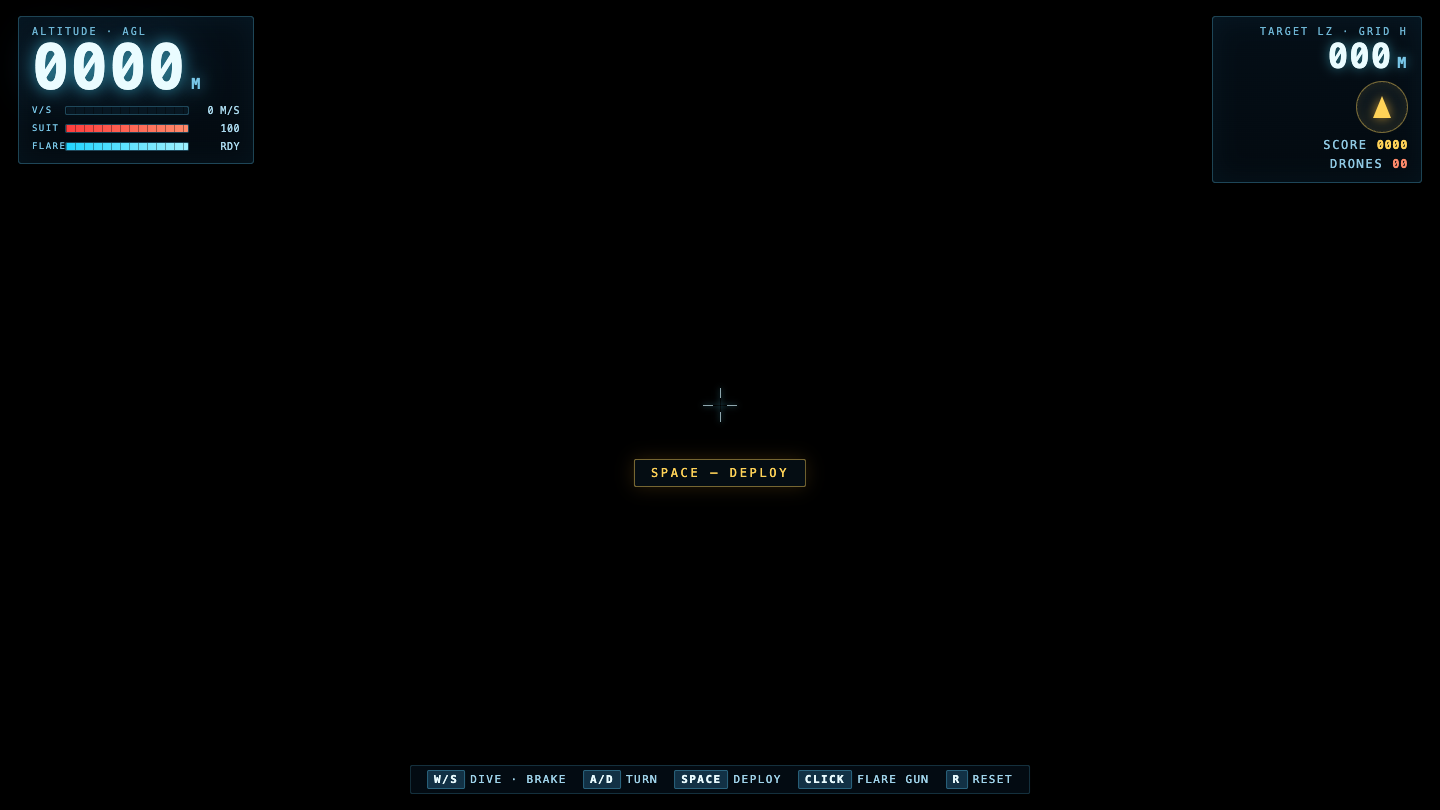
What I saw: The HUD (vitals, score, crosshair, control strip) renders with polish, but the entire 3D raycast scene is blank/dark — no walls, floor, or maze visible, so the core Wolfenstein-style world failed to render. A well-designed shell around a non-functional game.
Strengths & weaknesses I logged
Fugu Ultra 1.1
Strengths
- Orchestrates 1-3 expert agents per request and synthesises their answers
- Reported SWE-Bench Pro 73.7 — above Opus 4.8 and GPT-5.5 on Sakana's table
- OpenAI- and Anthropic-compatible API — drop-in for Codex and Claude Code
Trade-offs
- Benched as a partial run until the full 50-task batch completes
- Region-locked: unavailable across the EU/EEA/UK/CH — access depends on where you are
MiMo-V2.6 Pro
Strengths
- Simulations and visual pieces are top-tier one-shots: the black hole lensing scored 9.0 and the matrix rain, lava lamp, ocean waves, web desktop, boids and galaxy all landed 8.6 or higher
- Strong flight and driving output when the build holds together: a polished 3D dogfight (8.6), a flight sim (8.4) and the synthwave outrun (8.4)
- Big, complete files: builds ran 30 to 70 KB with full HUDs, control hints and settings panels
- The weights are MIT and on Hugging Face, so the same model can run on your own hardware
Trade-offs
- 18 of 50 builds scored under 5: long game files shipped with garbled tokens (a stray 'martin' or 'martial' identifier breaks the whole script), uninitialised references and bad canvas values, so the HUD paints but the 3D scene stays black
- Two hard crashes: the RPG threw an engine fault on load and the solar system rendered nothing at all
- It reasons for a long time at default effort: builds took 5 to 60 minutes each through OpenRouter
Pricing & context — the spec sheet
| Spec | Fugu Ultra 1.1 | MiMo-V2.6 Pro |
|---|---|---|
| Vendor | Sakana AI | Xiaomi |
| Context window | 1,000,000-token context window | 1,000,000 tokens |
| Price | API · orchestration billed | $0.435 in / $0.87 out per M tokens |
| Pricing detail | Sakana's Fugu Ultra v1.1 — a multi-agent system served as a model: an orchestrator routes each request across one to three expert agents and synthesises the answer. Reported (v1.0): SWE-Bench Pro 73.7, LiveCodeBench 93.2, GPQA Diamond 95.5. NOTE: Sakana geo-blocks the EU/EEA/UK/Switzerland pending GDPR compliance — benched from an allowed region. | Xiaomi's September 2026 open-weight flagship (MIT licence, 1.02T total / 42B active parameters). $0.435 per million input tokens and $0.87 per million output on OpenRouter, with cache hits at a fraction of a cent, which is roughly a quarter of Grok 4.7 and a twentieth of the closed frontier models it scores level with on agent benchmarks. |
| Release | 2026-07 | 2026-09 |
| Bench coverage | 23/24 scored · avg 6.94/10 | 50/50 scored · avg 6.35/10 |
The verdict — which should you pick?
Across 23 scored shared tasks, Fugu Ultra 1.1 averaged 6.94/10, beating MiMo-V2.6 Pro's 5.42/10 by 1.52 points. Pick Fugu Ultra 1.1 when the build has to ship on the first prompt and you can afford the trade-offs in the comparison below.
If you only run one of these inside your stack, the head-to-head average above is the call. If you can run both, my honest play is to wire Fugu Ultra 1.1 and MiMo-V2.6 Pro both into the Agent Operating System and dispatch each from the kanban by task type — hard, high-stakes coding and reasoning where answer quality beats latency → Fugu Ultra 1.1, simulations, shaders and visual scenes in one shot, at a fraction of frontier prices → MiMo-V2.6 Pro. That's the same setup I run for the 4,000+ founders inside the AI Profit Boardroom.
FAQ — Fugu Ultra 1.1 vs MiMo-V2.6 Pro
Which is better, Fugu Ultra 1.1 or MiMo-V2.6 Pro?
On Goldie Bench, Fugu Ultra 1.1 averages 6.94/10 across the shared tasks, with 0 gold, 1 silver, 1 bronze overall. MiMo-V2.6 Pro averages 5.42/10, with 5 gold, 8 silver, 4 bronze. Fugu Ultra 1.1 wins the head-to-head 13–8.
How much does Fugu Ultra 1.1 cost vs MiMo-V2.6 Pro?
Fugu Ultra 1.1: Sakana's Fugu Ultra v1.1 — a multi-agent system served as a model: an orchestrator routes each request across one to three expert agents and synthesises the answer. Reported (v1.0): SWE-Bench Pro 73.7, LiveCodeBench 93.2, GPQA Diamond 95.5. NOTE: Sakana geo-blocks the EU/EEA/UK/Switzerland pending GDPR compliance — benched from an allowed region. MiMo-V2.6 Pro: Xiaomi's September 2026 open-weight flagship (MIT licence, 1.02T total / 42B active parameters). $0.435 per million input tokens and $0.87 per million output on OpenRouter, with cache hits at a fraction of a cent, which is roughly a quarter of Grok 4.7 and a twentieth of the closed frontier models it scores level with on agent benchmarks.
What's the context window for Fugu Ultra 1.1 vs MiMo-V2.6 Pro?
Fugu Ultra 1.1 has a 1,000,000-token context window context window. MiMo-V2.6 Pro has a 1,000,000 tokens context window.
When should I pick Fugu Ultra 1.1 over MiMo-V2.6 Pro?
Pick Fugu Ultra 1.1 for: Hard, high-stakes coding and reasoning where answer quality beats latency; Agentic workflows in Codex / Claude Code via the drop-in provider config; One-shot builds you want a panel of experts on, not a single model. The trade-off is the weaknesses we logged on the bench: Benched as a partial run until the full 50-task batch completes; Region-locked: unavailable across the EU/EEA/UK/CH — access depends on where you are.
When should I pick MiMo-V2.6 Pro over Fugu Ultra 1.1?
Pick MiMo-V2.6 Pro for: Simulations, shaders and visual scenes in one shot, at a fraction of frontier prices; High-volume agent work where an open, MIT-licensed model matters; Pair it with a self-fix loop for games: the failures are single broken tokens, not missing ideas. The trade-off is the weaknesses we logged on the bench: 18 of 50 builds scored under 5: long game files shipped with garbled tokens (a stray 'martin' or 'martial' identifier breaks the whole script), uninitialised references and bad canvas values, so the HUD paints but the 3D scene stays black; Two hard crashes: the RPG threw an engine fault on load and the solar system rendered nothing at all; It reasons for a long time at default effort: builds took 5 to 60 minutes each through OpenRouter.
How does Goldie Bench score Fugu Ultra 1.1 vs MiMo-V2.6 Pro?
Every demo on this page was built by Julian Goldie inside the Agent Operating System — same fixed prompt for both models, one shot, single HTML file out. Each result gets a 0–10 score on whether it ran, how close it hit the brief, and how good it looked. The highest score on each task gets gold; second gets silver; third gets bronze. See methodology for full provenance.
Related comparisons
Other head-to-heads using the same scoring system:
Fugu Ultra 1.1 vs Fusion MiMo-V2.6 Pro vs Fusion Fugu Ultra 1.1 vs Claude Opus 5 MiMo-V2.6 Pro vs Claude Opus 5 Fugu Ultra 1.1 vs Hermes MoA MiMo-V2.6 Pro vs Hermes MoA Fugu Ultra 1.1 vs GPT-5.6 Sol MiMo-V2.6 Pro vs GPT-5.6 SolFull model pages: Fugu Ultra 1.1 · MiMo-V2.6 Pro · back to the leaderboard
The same stack Julian uses
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.
4,000+founders
258documented wins
38countries
$59/momonthly