GoldieBench Blog · 6 min read
Hermes vs Cursor: Which AI Models To Run In Each Tool, What The GoldieBench Scores Say, And How To Pair Them
Cursor gives you a picker set by your plan. Hermes takes any provider, per job. Here's what the bench numbers mean for each.
Hermes vs Cursor changes the model question: Cursor hands you a model picker inside a code editor, while Hermes Agent lets you wire any provider into chats, cron jobs and Bots, so each tool needs a different pairing.
This page matches the two tools with the models scored on GoldieBench, using only numbers I read on live goldiebench.com pages on 4 November 2026.
GoldieBench doesn't score Hermes or Cursor themselves.
It scores the models you'd run inside them.
If you'd like my team to pick a model stack with you, book a free SEO strategy session.
Why the two tools pick models so differently
Cursor's Agent runs on the model you pick for the task, and Cursor tunes its instructions and tools for each frontier model it supports, per the Cursor Agent docs.
Your plan decides the list.
The Cursor models page limits Plus to Cursor's own models, Grok 4.7, Grok 4.6, Grok 4.5 and Composer 2.5, and opens third-party models from Premium up.
On Teams and Enterprise, Cursor Router can choose a model per request when you select Auto.
Hermes has no fixed list.
You run hermes model and choose from the providers on its providers page: Anthropic and xAI directly, OpenRouter and Nous Portal as hubs, cloud platforms such as Bedrock and Vertex, or a model on your own hardware.
What a GoldieBench score measures
The methodology page says every model gets the same fixed prompt, one shot, with no retries and no help.
Each result must be a single self-contained HTML file that runs in a browser.
Julian scores each build from 0 to 10, and the leaderboard ranks models by average score across the tasks they were scored on.
That makes it a test of one-shot building, which maps well to a Cursor Agent task and less well to a Hermes cron job that summarizes notes.
The scores, as read on goldiebench.com
| Model | GoldieBench average | Scored tasks | Page read |
|---|---|---|---|
| Claude Opus 5 | 8.27/10 | 50 | /models/opus5 |
| Hermes MoA | 8.17/10 | 47 | /models/moa |
| GPT-5.6 Sol | 8.16/10 | 50 | /models/gpt56 |
| Claude Fable 5 | 8.10/10 | 47 | /models/fable-5 |
| Kimi K3 | 7.89/10 | 50 | /models/kimik3 |
| Claude Opus 5.5 | 7.57/10 | 50 | /models/opus55 |
| Grok 4.7 | 7.15/10 | 20 | /models/grok47 |
The Opus 5 deep dive puts it at rank 2 of 26 ranked frontier models, with data refreshed on 27 October 2026.
Grok 4.7 has 20 scored tasks against 50 for most rows, so read its average with that smaller sample in mind.
Composer 2.5, Cursor's own model, has no GoldieBench page, so I don't score it here.
Pairing for Cursor: the model in the editor
Cursor's model list includes Claude Opus 5, Claude Opus 5.5, Claude Fable 5, GPT-5.6 Sol, Kimi K3 and Grok 4.7, and the docs mark some, such as Opus 5 and Kimi K3, as hidden by default.
On GoldieBench, Claude Opus 5 has the highest average of that group at 8.27/10.
GPT-5.6 Sol sits close behind at 8.16/10, and Claude Fable 5 at 8.10/10.
For one-shot builds such as a new landing page, those three are where I'd start a Cursor Agent run.
On Plus, none of the third-party models are on the list, so Grok 4.7 at 7.15/10 is the benched option you'd have.
Cloud agents and Automations pick models too
Cursor's background work has its own model rules.
The cloud agent docs say cloud agents use a curated selection of models, and you can choose the context window size for supported ones.
Automations let you select the model per automation and always run at that model's largest context window.
So a nightly Automation set to a top scorer runs at full context every time, which is worth knowing before you point it at a big repo.
Members of the AI Profit Boardroom compare which models they leave on these background runs.
Pairing for Hermes: the model behind chats and cron
Hermes runs many small jobs, not one big build.
The cron docs resolve each job's model in this order: a per-job pin, then cron.model in config.yaml, then the main model from hermes model.
hermes config set cron.model <model-name>
hermes cron create "every 1d at 08:00" "Morning brief for the team" --model <model-name> --provider <provider>
That lets you put a top scorer such as Opus 5 on hard work and a lighter model on the morning brief, without one change moving the other.
Kimi K3 is a fair middle pick at 7.89/10 over 50 tasks, and its GoldieBench page says it runs as a Hermes profile in Julian's Agent OS for long unattended runs.
Hermes MoA: a pairing only Hermes offers
GoldieBench lists Hermes MoA at 8.17/10 over 47 tasks.
The MoA page describes it as a panel of models whose drafts a chair model merges into one answer, with a default panel of Claude Opus 4.8 and GPT-5.5 aggregated by Opus 4.8 through OpenRouter.
The Hermes docs mention MoA slots in the auxiliary model settings of the model configuration page.
Cursor has no matching panel setup in its docs, so if you want a mixed panel, that work belongs in the Hermes lane.
Rules and imports don't change the model choice
Hermes reads .cursorrules and .cursor/rules/*.mdc, per the tips page, and hermes import-agent cursor brings over rules, MCP servers and skills.
Neither one carries your Cursor model choice, so set the Hermes model yourself after an import.
I covered which models suit a fresh import in the Hermes Agent Cursor model guide.
Hermes can also run inside VS Code, Zed or JetBrains over ACP with its own model, but the ACP docs don't list Cursor.
Example: a small design studio picking two models
A three-person design studio builds client microsites and sends weekly progress notes.
- In Cursor on Premium, the developer selects Claude Opus 5 for new microsite builds, its best average on GoldieBench at 8.27/10.
- The developer uses Plan Mode, approves the plan, and reviews the diff before the PR goes up.
- In Hermes, the owner sets
cron.modelto a lighter model for the Friday progress-note job. - The owner pins Opus 5 on one monthly cron job that drafts a longer project review.
- Hermes delivers both jobs to the studio's Slack, and the owner sends them on.
Two tools, two model choices, and neither one has to match the other.
What the scores don't tell you
- They don't test Cursor features such as Bugbot, cloud agents or Automations.
- They don't test Hermes features such as the messaging gateway, cron delivery or memory.
- The leaderboard header says 33 models compared while deep dives say 26 ranked, so ranks depend on which list you read.
- Opus 5's tagline says 45 builds while its page counts 50 scored tasks; I use the 50.
The Hermes vs Cursor model call
Put your top GoldieBench scorer in Cursor for one-shot code builds.
Give Hermes a light default for cron and pin a strong model only on the jobs that need it.
The AI Profit Boardroom has the Agent OS these benchmark runs came from.
For help picking your pair, book a free strategy session with my team.
Also On Our Network
- Agent Operatorsthe seven-step order for setting up Hermes and Cursor in separate lanes
- AI Income Deskwhich tool a salon, agency, accountant or shop should set up first
- AI Tool Verdictan eight-row scorecard rating Hermes and Cursor from their own docs
- agentos.guidefive copy-paste prompts that split work between Hermes and Cursor
- aiprofitboardroom.comthe complete Hermes vs Cursor guide on the AI Profit Boardroom blog
Read the GoldieBench pages, set one model per lane, and book a free strategy session if you want help pairing models for hermes vs cursor.
FAQ
Which GoldieBench model scores highest among Cursor's options?
Claude Opus 5, at 8.27/10 over 50 scored tasks on its GoldieBench page. Cursor lists it as hidden by default, so turn it on in the model picker.
Can I use Claude or GPT models on Cursor Plus?
No. Cursor's models page limits Plus to its own models: Grok 4.7, Grok 4.6, Grok 4.5 and Composer 2.5. Third-party models open from Premium up.
Can each Hermes cron job use a different model?
Yes. A per-job pin wins, then cron.model in config.yaml, then the main model from hermes model.
Has GoldieBench scored Composer 2.5?
No. There is no Composer 2.5 page on goldiebench.com, so there is no score to quote.
What is Hermes MoA on GoldieBench?
A panel of models merged by a chair model, listed at 8.17/10 over 47 tasks, with a default panel of Claude Opus 4.8 and GPT-5.5.
Keep reading
 Hermes Agent Cursor + Which AI Models To Run After You Import: Real GoldieBench Scores For Cursor Users
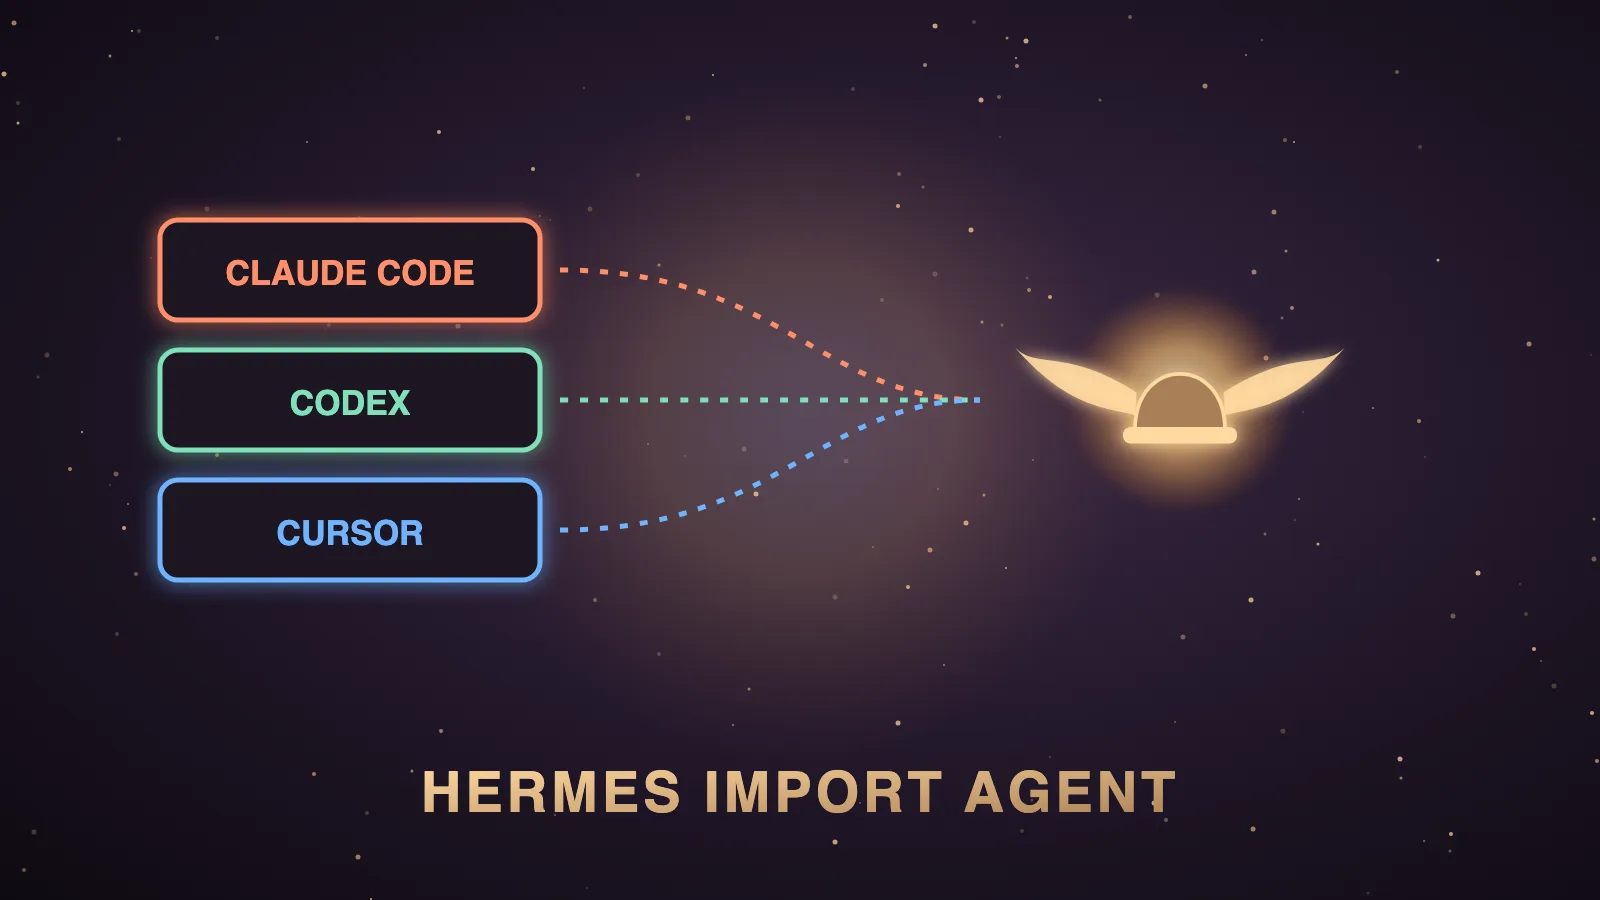 Hermes Import Agent: What It Moves From Claude Code And Codex, How To Use It, And The Model To Run Afterwards
 Hermes Agent For Business + Which AI Models To Run For Each Job: Real GoldieBench Scores For Bots, Boards And Client Pages
🌐 Sister-site take: read this on agentos.guide