Can You Run Jev Locally? The Honest Answer, Plus The Local Stack The Bench Supports
By Julian Goldie · 2026-10-05 · GoldieBench Blog
No, you cannot run Jev locally, because TypeSafe has not released Jev's model weights and it only runs as a hosted service.
What you can run locally is a Jev-shaped decision model, plus a local builder model underneath it.
I benchmark local models on GoldieBench every week, so this post is about the second half that everyone skips.
A local decision layer is pointless if the model doing the actual work is weak.
Why you cannot run Jev locally today
Jev exists only behind TypeSafe's API and the gateways that resell it, such as OpenCode Zen, Vercel AI Gateway and OpenRouter.
The SDKs are open source under the MIT licence, but an SDK is only the code that talks to the hosted model.
So any page offering a Jev download is either selling something else or confusing the SDK with the model.
That saves you an afternoon of hunting.
🔥 Want the exact local decision-model setup I use?
Inside the AI Profit Boardroom I've got the full step-by-step video tutorials, the installable Agent OS, weekly coaching calls and 4,000+ members building real automations.
What runs locally instead
Here is the honest list of Jev-style decision models you can put on your own machine.
| Option | Runs locally? | What I know |
|---|---|---|
| TypeSafe Jev | No, hosted only | Got 54 of 60 right on my email test |
Laya (pip install laya) | Yes, I ran 0.3.4 on my Mac | About 20 ms per English question, but untrained it scored 28 and 36 of 60 on the same emails |
| Cloudflare Clef | Yes, weights on Hugging Face | Released 1 October 2026, Apache 2.0, built on Qwen 3.8-27B, and Cloudflare says it is Jev-API compatible |
| Cloudflare Clef-flash | Yes, weights on Hugging Face | A 9B sibling built on Qwen 3.5-9B, a far easier fit on a laptop |
I have installed and tested Laya myself.
I have not run Clef on my own machine yet, so I am not going to give you a speed number for it.
The accuracy gap you need to know about
Fast is not the same as right.
| Test | Hosted Jev | Laya, untrained |
|---|---|---|
| 60 real-style emails | 54 of 60 | 28 (English model) and 36 (typed-decisions model) |
| 24 contact-form leads | 24 of 24 | 16 of 24 |
| Pick 1 of 5 websites for a brief | 10 of 10 | 8 of 10 |
| 77-category test | 0.870 | 0.425 |
The good news is that Laya did not fake confidence when it was guessing.
None of its 60 email answers came back at 0.85 confidence or higher.
That means a confidence threshold still works with a local model, even when the answers are weaker.
Run Jev locally? Pair the decision model with a local builder
This is where GoldieBench comes in.
A local decision model only decides where work goes.
Something else has to do the work, and on a fully offline stack that something is a local model.
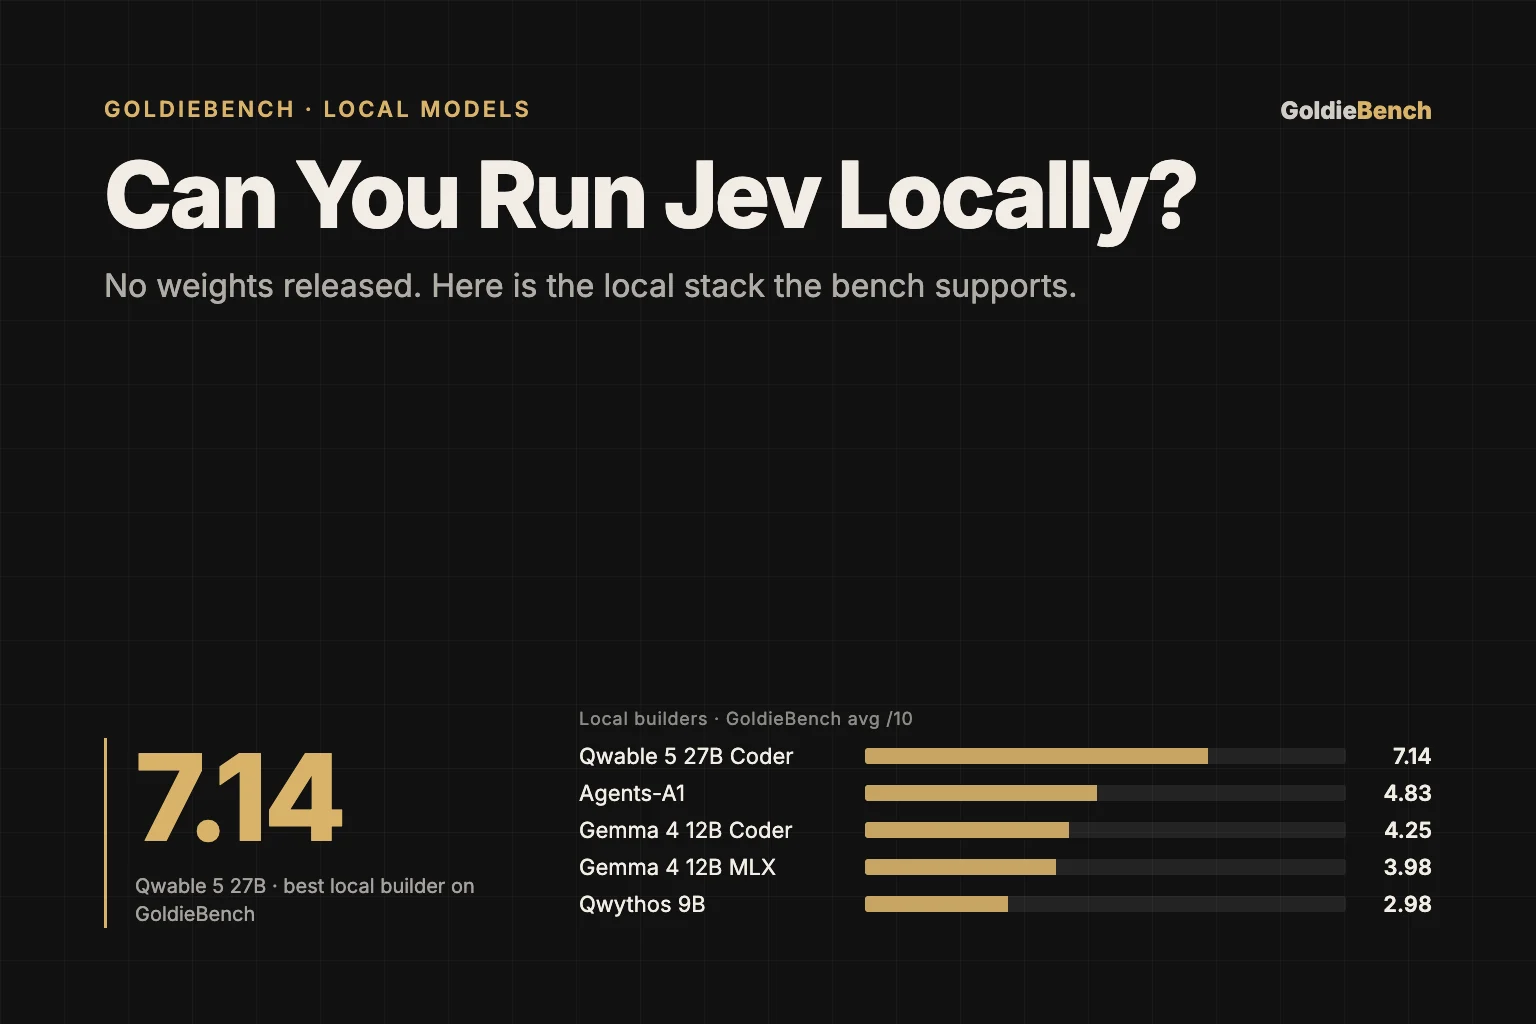
Here is how the local builders score on the same 50-task gauntlet the frontier models run.
| Local model | GoldieBench avg | Notes from the board |
|---|---|---|
| Qwable 5 27B Coder | 7.14 | Best local builder, MLX only, built on Qwen3.6-27B |
| Agents-A1 | 4.83 | Agent-tuned open MoE built for long tool work |
| Gemma 4 12B Coder | 4.25 | Free offline coder |
| Gemma 4 12B MLX | 3.98 | The fast lightweight engine |
| Qwythos 9B | 2.98 | A local writer with a 1M-token context |
For context, the top of the board is Claude Opus 5 at 8.27 and GPT-5.6 Sol at 8.16.
So the best local builder gets you most of the way, and the rest drop off fast.
One honest caveat about Clef: the Qwen 3.8 on our board scores 8.10, but that is Alibaba's hosted flagship benched through Qoder, not the 27B model Clef is built on.
Do not read that 8.10 as a Clef score.
The closest local evidence I have for a 27B Qwen-family model is Qwable at 7.14.
The local stack I would build
Put Laya or Clef in the decision slot, answering typed questions about each job.
Send private, repetitive jobs to Qwable if you have the memory for a 27B model, or to a Gemma 4 build if you do not.
Keep one hosted lane, either Jev or a frontier model, for long option lists and hard reasoning.
That matters because on the 77-category test hosted Jev scored more than double what untrained Laya did.
Use Router(preload=True) with Laya if you see more than one language, because without it each language switch took around 20 seconds on my Mac.
Keep the decision endpoint as one config value, so swapping Laya, Clef and Jev never touches your agents.
Who should actually run Jev-style decisions locally
Run it locally if privacy is the whole point, such as client inboxes, payslips or anything regulated.
Run it locally if you make thousands of small decisions a day and want zero per-call cost.
Stay hosted if accuracy on long category lists matters more than privacy, because that is where the gap is widest.
And if you are not sure, start with the free hosted Jev door and move the private lanes local later.
Also On Our Network
🌐 a step-by-step local Jev setup
🌐 what running Jev locally means for your margins
🌐 the verdict on local Jev alternatives
🌐 how the local decision slot fits an Agent OS
🌐 Julian's hands-on Laya AI test
So the honest answer to "can I run Jev locally" is no, but a local decision model plus a benched local builder gets you the same shape of system today.
FAQ
Can I run Jev locally?
No. TypeSafe has not released Jev's weights, so Jev only runs as a hosted service. Its SDKs are open source, but they only call the hosted model.
What is the best local alternative to Jev?
Laya (pip install laya) is the one Julian installed and tested: about 20 ms per question, but untrained it scored 28 to 36 of 60 on his email test against Jev's 54. Cloudflare's Clef and Clef-flash have open weights and are described by Cloudflare as Jev-API compatible, but Julian has not tested them yet.
Which local model should do the work behind a local decision layer?
On GoldieBench the best local builder is Qwable 5 27B Coder at 7.14, followed by Agents-A1 at 4.83 and Gemma 4 12B Coder at 4.25.
Is Clef as good as Qwen 3.8 on GoldieBench?
There is no Clef score on GoldieBench. The Qwen 3.8 entry (8.10) is Alibaba's hosted flagship benched through Qoder, not the Qwen 3.8-27B model Clef is built on.
Does a local decision model still give confidence scores?
Laya does, and in Julian's test none of its 60 email answers reached 0.85 confidence, so the confidence number stayed honest even when the answers were wrong.
About Julian
I'm Julian Goldie — AI entrepreneur, SEO expert, and founder of the AI Profit Boardroom (4,000+ members).
I help business owners scale with AI agents, automation, and SEO.
400K+ YouTube subscribers. 7-figure AI agency (Goldie Agency). Daily training inside the Boardroom.
Related reading
→ The Best Local Model For Hermes Agent — Decided By 45 Real Builds
→ The Best LLMs For Hermes Agent, Ranked By Real Work
→ The Best Free AI Model For Hermes Agent (All Three $0 Lanes)
🌐 Sister-site take: read this on agentos.guide
Run this stack yourself.
Every demo on this bench was built inside the Agent Operating System — one prompt, one shot, single HTML file out. The Agent OS, the prompts, the templates, the weekly walkthroughs and 4,000+ founders shipping with it every day all live inside the AI Profit Boardroom.
📺 Video notes + links to the tools 👉 AI Profit Boardroom
🆓 Get a FREE AI Course + Community + 1,000 AI Agents 👉 AI Money Lab
🎥 Learn how I make these videos 👉 agentos.guide